
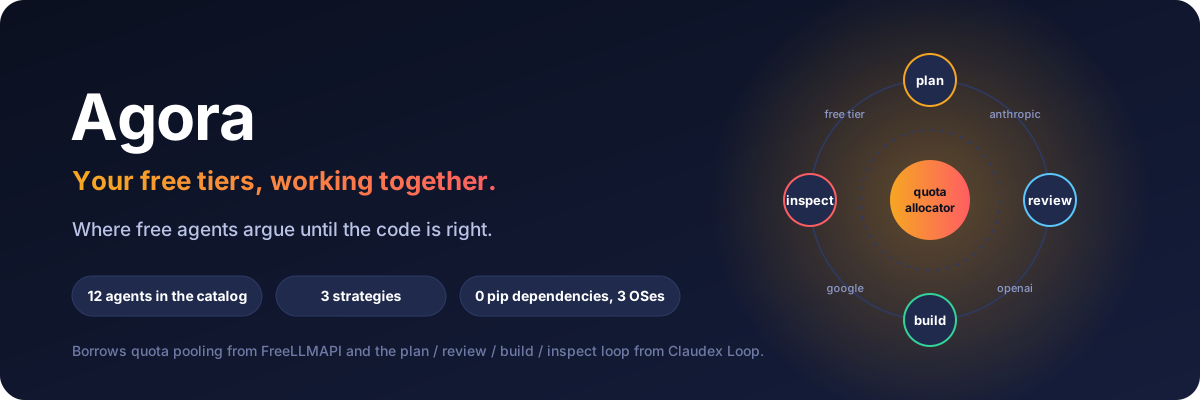
Where free agents argue until the code is right.
N coding agents. One bounded loop. Zero API bills.



Claude Code, Codex, Gemini CLI, Aider, OpenCode, Qwen Code and friends plan, review, build and inspect each other's work, while a quota allocator spends only the free tiers and subscriptions you already have.
Contents
- Why this exists
- What you get in 20 seconds
- Does it actually work?
- Supported agents
- Quick start
- Three use cases, end to end
- Strategies
- Allocation
- Decisions
- What an approval means
- Tests
- Limitations and terms of service
- Contributing
- Credits
Why this exists
Free tiers are toys on their own. Every vendor now ships a coding agent with a free or subscription quota: a few hundred requests per five hours here, a thousand per day there. FreeLLMAPI showed that stacking the free model tiers of dozens of providers (34 at the time of writing, per its README) adds up to real capacity, if a router tracks every cap and fails over the moment one is hit.
Single-agent loops have blind spots. A model reviewing its own plan tends to approve it. Claudex Loop showed that handing the plan to a different provider for review, and the code to a fresh session of yet another provider for inspection, catches what one model misses. But it runs on exactly two providers and stops dead when one runs out of quota.
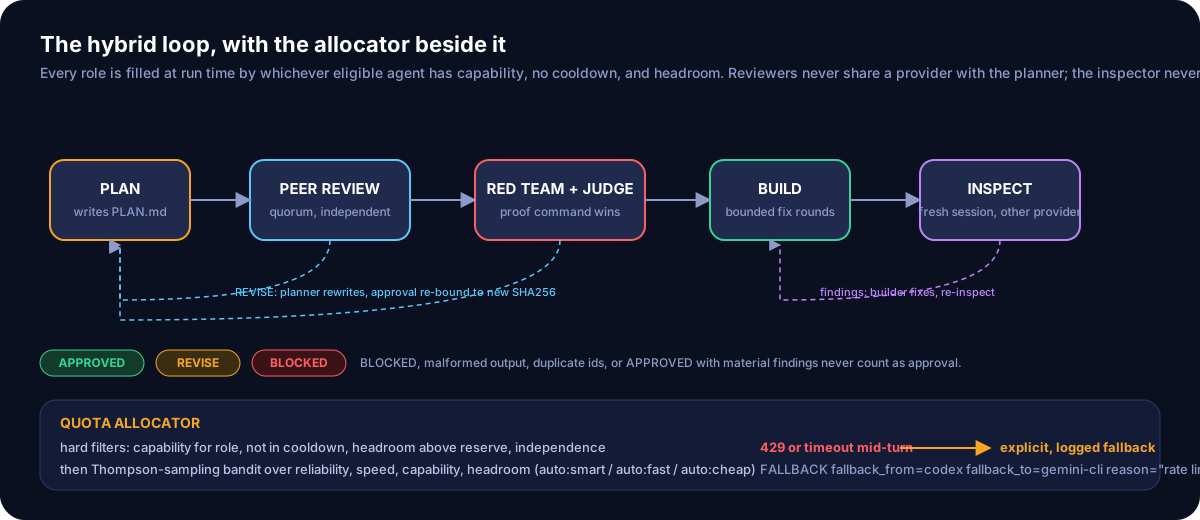
Agora does both. It treats whole agentic systems the way FreeLLMAPI treats models: a catalog with quota shapes, a persistent ledger of what each one has used, cooldowns on 429s, and a bandit that picks the best eligible agent for every role. Then it runs them through a Claudex-style bounded loop under a strategy you choose: collaborative, adversarial, or hybrid. When an agent is rate-limited mid-turn, the loop does not die and does not silently swap models either. It fails over to the next eligible agent and writes that down.
The deliverable does not have to be code. Anything that ends up as files and can be checked by a command works: a module with tests, a decision memo with a structure checker, a data file with a validator, a config with a linter.
What you get in 20 seconds
$ agora run "add CSV import with validation" --strategy hybrid --allocation auto:cheap --proof-cmd "pytest -q"

- [2026-10-29T14:02:11Z] ALLOCATION role=plan agent=gemini-cli provider=google headroom=0.92 reason=auto:cheap bandit: ...
- [2026-10-29T14:03:40Z] REVIEW mode=collaborative round=1 agent=claude-code verdict=REVISE findings=3 material=2
- [2026-10-29T14:05:02Z] REVISION round=1 agent=gemini-cli plan_sha256=9f1c... addressed=2
- [2026-10-29T14:06:30Z] REVIEW mode=collaborative round=2 agent=claude-code verdict=APPROVED findings=1 material=0
- [2026-10-29T14:06:30Z] APPROVAL mode=collaborative round=2 agent=claude-code plan_sha256=4a77...
- [2026-10-29T14:08:12Z] TURN role=review agent=codex ok=false rate_limited=true
- [2026-10-29T14:08:12Z] FALLBACK role=review fallback_from=codex fallback_to=qwen-code reason=rate limited
- [2026-10-29T14:10:45Z] JUDGE by=proof-cmd round=1 passed=true
- [2026-10-29T14:10:45Z] APPROVAL mode=adversarial round=1 agent=qwen-code plan_sha256=4a77...
- [2026-10-29T14:18:03Z] BUILD agent=claude-code pre_build_commit=e3b0c4...
- [2026-10-29T14:18:40Z] PROOF cmd=["pytest","-q"] passed=true exit_code=0
- [2026-10-29T14:21:17Z] INSPECT round=1 agent=gemini-cli verdict=APPROVED findings=1 material=0 fingerprint=71ab...
- [2026-10-29T14:21:17Z] QUOTA agent=claude-code requests=3 failures=0 headroom=0.61 cooldown_s=0
- [2026-10-29T14:21:17Z] SUMMARY status=completed rounds=3 inspections=1 fallbacks=1 open_findings=1
The excerpt is abridged and illustrative (the Gemini and Qwen lines have not run live; the recorded logs under examples/ carry every field). Every line of a real run is appended to AGORA-LOG.md in the target repository. The plan lives in PLAN.md. Per-turn diagnostics (prompt, exact argv, stdout, stderr, result) go to a directory outside the checkout.
Does it actually work?
Yes, on two levels.
Live, with real agents. On 2026-10-29 a collaborative loop ran on a throwaway repo whose five tests fail until slugify is implemented. Claude Code planned and built; Codex reviewed and inspected in its read-only sandbox, on a different provider by construction.
| Role | Agent | Wall time | Result |
|---|---|---|---|
| plan | Claude Code 2.1.306 | 102 s | wrote PLAN.md with a per-test acceptance table |
| review | Codex CLI 0.153.4 (gpt-6-astra, read-only) | 38 s | APPROVED, 1 low finding: a wrong intermediate value in the plan's prose |
| build | Claude Code | 197 s | implemented slugify, one tracked file changed |
| proof | python -m unittest -q |
2 s | Ran 5 tests, OK |
| inspect | Codex CLI, fresh session | 43 s | APPROVED, 0 findings, diff checked against the pre-build commit |
Codex executed the tests against the proposed algorithm in memory during review, without write access, and verified the imports were standard library only. The unedited log, plan, built code and both verdicts with token usage are in examples/live-run-2026-10-29/. The first attempt that day failed because Codex's default model is rejected on ChatGPT accounts: the loop logged a fallback to Claude for planning, then refused to let Claude review its own plan and stopped with the reason. That is the designed behaviour, and it is recorded too. Details in VALIDATION.md. Later the same day the three bundled use cases ran live as well, and two of them found real bugs in Agora: an inspector that could end up checking code its own provider had written after a timed-out build, and a rate-limit detector that matched Agora's own log line when a reviewer echoed it. Both are fixed, tested, and left in the record.
Automatically, without spending quota. 135 tests run on fake agent processes and disposable git repositories on every push, across Ubuntu, Windows and macOS. They cover the ledger, the allocator's hard filters across 1,000 randomised draws, the verdict schema, timeouts and process-tree kills, SHA-bound approvals, all three strategies, explicit fallback, and three end-to-end loops with a real proof command. See Tests.
And it was reviewed before it was announced. Two independent adversarial review passes over the code and the docs, run before the first release, returned 27 code findings and 29 documentation findings. Five were release-blocking: on Windows a quoted proof command could pass vacuously, "read-only" roles were a request to the CLI rather than a verified fact, a planner could be chosen to review its own revision, npm .cmd shims would have put the prompt through cmd.exe, and the example catalog was missing from the package. Every one is fixed and pinned by tests/test_hardening.py; the full list and what was done about each item is in VALIDATION.md.
Supported agents
Any CLI with a headless mode, plus any OpenAI-compatible HTTP endpoint. The example catalog ships these:
 Claude Code subscription |
 Codex CLI subscription |
 Gemini CLI free |
 Qwen Code free |
 OpenCode free |
 Aider free |
 Goose free |
 Crush free |
 Kilo Code free |
 Cline CLI free |
plus FreeLLMAPI (hundreds of free endpoints behind one URL: 34 providers, 635 endpoints per its README in October 2026) and a local Ollama as HTTP tiers
Decision models typed answers that steer the loop and never approve anything
 BeatAPI JEV free, 1 req/min |
 APINex free, 5 req/min |
 Cloudflare Clef free daily allowance |
 OpenRouter Mercury your credit |
 FreeLLMAPI gateway fails over for you |
| Agent | Kind | Status | Notes |
|---|---|---|---|
| Claude Code, Codex CLI | cli | tested live, four completed loops with each tool in the plan, review, build and inspect roles; the LLM judge has not run live yet (see use cases and VALIDATION.md) |
read-only roles get exec -s read-only / disallowed edit tools, builders exec -s workspace-write / acceptEdits, as in Claudex Loop |
| Gemini CLI, Qwen Code, OpenCode, Aider, Goose, Crush, Kilo Code, Cline | cli | declared | headless argv from each tool's docs; send a PR with a VALIDATION.md entry once you have run one |
| FreeLLMAPI, Ollama, vLLM, LM Studio | http | tested (fake server in CI) | any /v1/chat/completions endpoint |
BeatAPI JEV, APINex, Cloudflare Clef, OpenRouter Mercury Decide, FreeLLMAPI /v1/decisions |
decision | tested (fake server in CI); live check pending a free key | typed choice / yes-no / score answers that steer choices and never approve anything (see Decisions) |
Adding an agent is one TOML table. See agents.example.toml.
Quick start
pipx install git+https://github.com/dgiunchi/agora               # PyPI: `pipx install agora-loop` once v0.1.0 is published
agora agents init                                                # writes agents.toml; keep the agents you actually have
agora agents doctor                                              # on PATH? which version? what exactly would run?
agora quota                                                      # what has each agent used, what is left
agora run "add CSV import" --strategy hybrid --dry-run           # who fills which role, spends nothing
agora run "add CSV import" --strategy hybrid --proof-cmd "pytest -q"  # the real thing
Requirements: Python 3.11+, git, and at least two agents from different providers (the loop refuses to let a provider review itself). No pip dependencies at runtime.
Three use cases, end to end
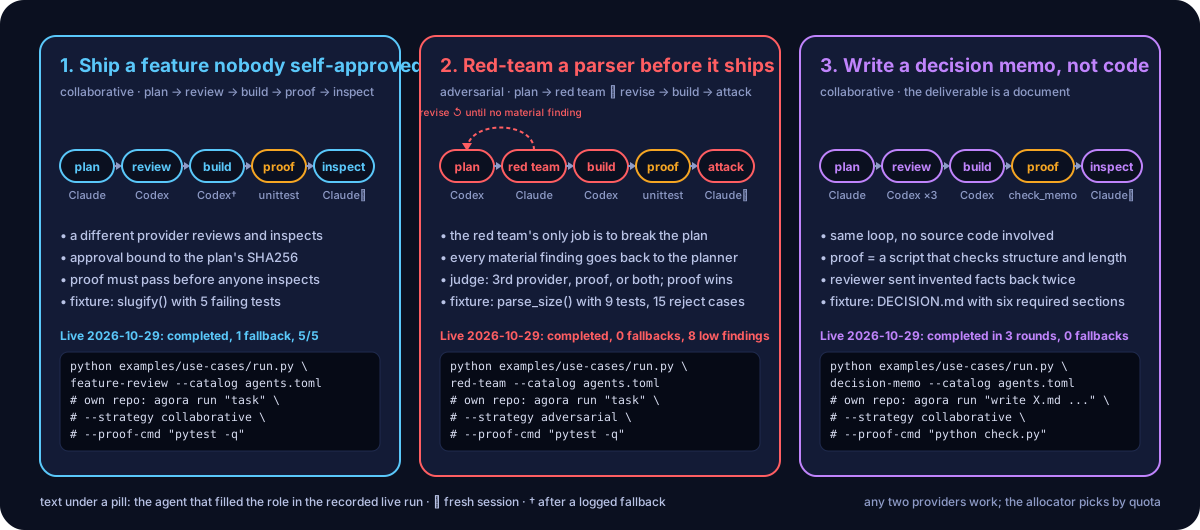
Each use case is a tiny fixture under examples/use-cases/: a stub or a checker, a proof that fails until the task is done, and a usecase.json holding the task text, the flags and the proof command. One script copies the fixture into a temporary git repository and runs the loop there, so your own code is never touched:
git clone https://github.com/dgiunchi/agora && cd agora
agora agents init                                  # keep two agents from different providers
agora agents doctor                                # on PATH? which version?
python examples/use-cases/run.py feature-review --catalog agents.toml --dry-run   # who does what, spends nothing
python examples/use-cases/run.py feature-review --catalog agents.toml             # 1. collaborative
python examples/use-cases/run.py red-team       --catalog agents.toml             # 2. adversarial
python examples/use-cases/run.py decision-memo  --catalog agents.toml             # 3. a document, not code
--workdir DIR chooses the checkout location, --seed N makes the allocation reproducible, --ledger PATH keeps the quota separate, and everything after -- goes to agora run (for example -- --timeout 900). When a run ends you get the status on stdout and AGORA-LOG.md, PLAN.md and the deliverable in the fixture directory. All three were run live to completion on 2026-10-29 with Claude Code 2.1.306 and Codex CLI 0.153.4 (gpt-6-astra); the logs, plans, deliverables and the verdict JSON of every turn are under each use case's result/run-1/ folder, paths redacted, nothing edited.
1. Ship a feature nobody self-approved
Use it for features, refactors and migrations: anything with a test you can name. One provider plans, a different one reviews the plan with evidence, the builder implements, the proof runs, and a fresh session of a provider that did not build inspects the diff against the pre-build commit.
agora run "add CSV import with validation" --strategy collaborative --proof-cmd "pytest -q"
The bundled fixture is slugify() with five failing tests. Live, first run:
| Role | Agent | Wall time | Result |
|---|---|---|---|
| plan | Claude Code | 309 s | PLAN.md with acceptance criteria and a verification table |
| review | Codex, read-only | 116 s | APPROVED, 1 low (the plan's expected git status output omitted untracked files); ran the proposed function against all five tests in memory |
| build | Claude Code | 600 s | timed out, process tree killed |
| fallback | → Codex, workspace-write | 59 s | found slugger.py already written, verified it, changed nothing |
| proof | python -m unittest -q |
1 s | Ran 5 tests, OK |
| inspect | Claude Code, fresh session | 208 s | APPROVED, 2 low (NFKD drops ß/æ/ø; __pycache__ untracked) |
That run completed, and it also exposed a gap. The killed Claude turn had already written the implementation; Codex only verified it; and the inspector was chosen to be independent of the recorded builder, Codex, so Claude inspected code Claude wrote. The loop now treats any agent whose failed write turn changed the working tree as an author: the FALLBACK line carries tree_changed=true, the INSPECT line lists also_touched, and the inspector must be independent of every author. With two providers that first run would now stop with no eligible agent for role 'inspect', which is the honest outcome. Three fake-agent tests pin the rule. A second run under the hardened rules completed cleanly: Codex planned, Claude approved with two low findings (297 s), Claude's build turn timed out at 900 s without touching the tree (the host's hooks again), Codex built on fallback in 65 s, the proof passed 5/5, and a fresh Claude session inspected and approved with three low findings (339 s). One fallback, every author accounted for, the inspector independent of all of them. The record is in result/run-2. The attempt before it was stopped by the new read-only rule on a false positive, a host plugin writing a session file into the fixture during a clean review; that is fixed and both attempts are in VALIDATION.md.
2. Red-team a parser before it ships
Use it for parsers, input validation, security-sensitive paths: anything where the interesting question is "what input breaks this?". The red team's only job is to break the plan; every material finding goes back to the planner until none is left; after the build a fresh red-team session attacks the code rather than the plan.
agora run "harden parse_size against malformed input" --strategy adversarial --proof-cmd "pytest -q"
The bundled fixture is parse_size() with eight tests, three of which drive fifteen reject-cases. Live:
| Role | Agent | Wall time | Result |
|---|---|---|---|
| plan | Codex | 90 s | PLAN.md with an explicit ASCII grammar and exact integer arithmetic |
| red team | Claude Code, read-only | 354 s | APPROVED, 4 low: re.IGNORECASE would case-fold Unicode, non-ASCII digits absent from the rejection list, Python's int digit limit, leading zeros unspecified |
| build | Codex, workspace-write | 139 s | implemented the plan; 8 test methods, 29 assertions |
| proof | python -m unittest -q |
1 s | OK |
| attack | Claude Code, fresh session | 576 s | APPROVED, 4 low: str.strip() accepts Unicode whitespace, no magnitude cap, unit table rebuilt per call, __pycache__ untracked |
Zero fallbacks, eight low findings left open for a human, none material. Because no finding was material the judge was never consulted; with a material finding and only two providers the log shows JUDGE by=llm round=1 skipped=true and the planner must answer it in a revision. Add a third provider and --judge both arbitrates instead.
3. Write a decision memo, not code
Use it for documents, data files, configuration: any deliverable that lands in files and can be checked mechanically. The proof here is check_memo.py, which checks that DECISION.md exists, has six level-2 sections in the required order, lists at least three options, scores them in a markdown table with at least four criteria, states a recommendation, stays between 250 and 700 words, and contains no code block. The reviewer hunts for wrong facts and unmet criteria instead of failing inputs.
agora run "write DECISION.md: a one-page memo on adopting a monorepo ..." --strategy collaborative --proof-cmd "python check_memo.py"
Live, this was the only run that needed more than one round, and the pushback was about facts, not formatting:
| Role | Agent | Wall time | Result |
|---|---|---|---|
| plan | Claude Code | 276 s | plan with section budgets, invented scenario details and a verification table |
| review 1 | Codex, read-only | 96 s | REVISE, 2 medium: the scenario's pains are invented and drive the recommendation; "drift disappears" and "half the migration effort" are unsupported claims |
| revise 1 | Claude Code | 142 s | labelled assumptions, qualified the claims |
| review 2 | Codex | 76 s | REVISE, 2 medium: outline still recommends two options conditionally; "no team boundary worth mirroring" is asserted from nothing |
| revise 2 | Claude Code | 135 s | one recommendation, ownership stated as an assumption to validate |
| review 3 | Codex | 75 s | APPROVED, 2 low (word budget arithmetic, git status expectation) |
| build | Codex, workspace-write | 77 s | wrote DECISION.md, 548 words |
| proof | python check_memo.py |
1 s | OK, six sections in order |
| inspect | Claude Code, fresh session | 280 s | APPROVED, 2 low: one clumsy sentence, a weighting claim the table does not back |
Three rounds, zero fallbacks, four low findings left open. The memo and every verdict are in examples/use-cases/decision-memo/result/run-1/. This run also found Agora's second bug: on an earlier attempt Codex had read the fixture's AGORA-LOG.md, echoed it, and the rate-limit detector matched Agora's own rate_limited=false field, so a clean turn was recorded as a 429 and a cap of nine requests was learned. Fixed: a clean exit is never rate-limited by keyword, and agora quota --forget <agent> drops a learned cap.
A note on the wall times. Claude Code turns were slow in these runs because the host machine's Claude Code had plugin hooks installed that blocked or delayed its read tools; both Claude reviewers said so in their limitations. That is the host's configuration rather than Agora, but it is why every turn has a --timeout, why a timeout is a logged fallback rather than a hang, and why the per-turn artifacts outside the checkout matter when you want to know what an agent actually saw.
Strategies
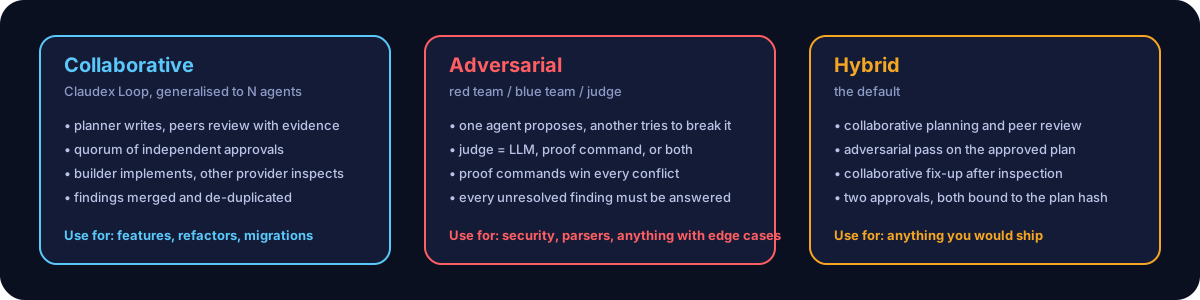
| Strategy | Shape | When |
|---|---|---|
collaborative |
plan → peer review (quorum) → build → independent inspect | features, refactors, migrations |
adversarial |
plan → red team + judge → build → red-team inspect | parsers, security, anything with nasty edge cases |
hybrid (default) |
plan → peer review → red team + judge → build → inspect | anything you would ship |
Tunables: --rounds (plan-review cap, default 5), --quorum (independent approvals needed), --judge llm|proof-cmd|both|decision (before the build the proof command is evidence for the judge, since it is expected to fail while the deliverable does not exist; after the build a failing proof stops the loop whatever any judge said; --judge proof-cmd alone clears every finding on a pass), --max-fix-rounds, --max-inspection-rounds, --builder <id>, --no-fallback.
The LLM judge must be independent of both the planner and the red team, so it needs a third provider. With only two providers the default --judge both skips the judge, logs JUDGE by=llm round=N skipped=true, and sends every red-team finding back to the planner; --dry-run tells you in advance. --judge llm fails loudly instead.
Allocation
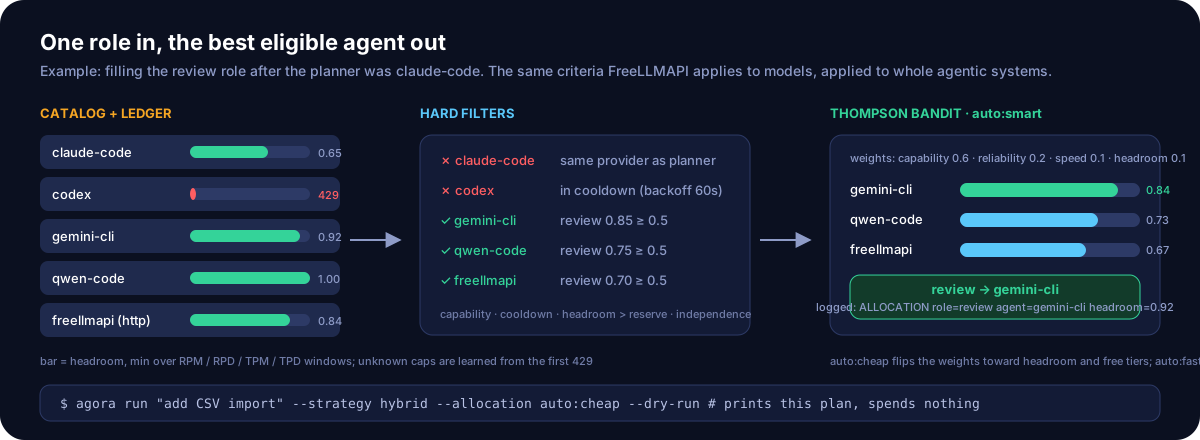
The allocator never spends quota and never bends a hard rule:
- Hard filters: capability for the role above threshold, not in cooldown, headroom above the reserve, and independence (a reviewer cannot share a provider with the planner; an inspector cannot share one with the builder).
- Thompson-sampling bandit over reliability (observed successes and failures), speed (observed latency), capability (catalog prior) and headroom (the ledger's min over every RPM / RPD / TPM / TPD window).
auto:smartweights capability,auto:fastweights speed,auto:cheapweights headroom and free tiers.profile:<name>walks the order declared in a[profiles]table of the catalog (agora agents initshows the syntax). - Explicit fallback: a 429, a timeout or a crash mid-turn moves to the next eligible agent unless you pass
--no-fallback, and the log recordsfallback_from,fallback_toand the reason. Claudex Loop's "no silent fallback" rule stays intact; FreeLLMAPI's fail-over becomes a visible event.
The ledger is SQLite. Unknown caps start optimistic and are learned from the first rate limit; declared caps always win. Windows reset at UTC midnight or roll, per agent.
Decisions
A decision model does not write text. It answers typed questions about a piece of state, choice, noul (yes or no) or score, with probabilities and a confidence, in well under a second, and the free ones cost nothing: BeatAPI's JEV models (jev-1.14-free, one request a minute), APINex's free decision route, Cloudflare Workers AI's Clef, OpenRouter's Mercury Decide, or a running FreeLLMAPI that fails over across all of them. In the catalog they are entries with kind = "decision", tried in declared order (free first), counted by the ledger like any agent, and cached for 30 minutes so a retried turn never spends a one-per-minute quota twice.
Agora asks them only where it would otherwise choose by rule, and a decision is never an approval:
| You pass | The question | Default when no model answers confidently |
|---|---|---|
--strategy auto |
which strategy fits this task | hybrid |
--allocation auto |
which allocation preset fits this task | auto:smart |
--judge decision |
does this red-team finding still stand; a decision model is a third provider, so two coding agents are enough for an arbitrated red team | the finding stands and goes back to the planner |
| nothing, always | is each material finding specific and how severe is it, as evidence in the log | nothing changes |
Every answer is logged with the model that answered, the value and the confidence (DECISION decision=judge model=jev-1.14-free answers={"status": {"value": "addressed", "confidence": 0.81}}), every fallback too (DECISION decision=strategy fallback=no decision model ready (beatapi-jev: BEATAPI_API_KEY not set)), --dry-run says which model would answer, and --no-decisions switches it all off. The integration is verified against a fake decision server in the test suite; a live check against a free JEV model needs a key and is recorded in VALIDATION.md once run.
Using them
All five are already in the catalog that agora agents init writes. Keep the ones you have a key for, delete the rest, and export the key in the shell that runs Agora. Agora reads keys from the environment only, never from a file, and never prints them.
| Provider | Get a key | Export | Catalog entry | Free terms as recorded in October 2026 |
|---|---|---|---|---|
| BeatAPI JEV | free account at beatapi.io, create an API key | BEATAPI_API_KEY |
beatapi-jev (jev-1.14-free; jev-1.13-free also answers) |
temporary free offer, one successful request per minute per account before any top-up; no card |
| APINex | account at apinex.bond, create an API key; a $0 wallet is valid on Free | APINEX_API_KEY |
apinex-decisions (confirm the model id on apinex.bond/developers/models/decisions) |
10,000,000 units per day shared with chat, 5 requests per minute |
| Cloudflare Workers AI | dash.cloudflare.com: an API token with Workers AI access; put your account id in the entry's endpoint | CLOUDFLARE_API_TOKEN |
cloudflare-clef (@cf/cloudflare/clef-flash; clef, nimble, tev1 exist too) |
the Workers AI free daily allowance of any account |
| OpenRouter | openrouter.ai, an API key | OPENROUTER_API_KEY |
openrouter-mercury (mercury-decide) |
rides on whatever credit the key has |
| FreeLLMAPI gateway | your own FreeLLMAPI instance that exposes /v1/decisions, with its client key |
FREELLMAPI_API_KEY |
freellmapi-decisions (auto) |
every decision model the instance holds a key for, with its own failover and cooldowns |
Then, in order:
agora agents init                       # writes agents.toml with the five entries; delete the ones you will not use
export BEATAPI_API_KEY=...              # Windows: set BEATAPI_API_KEY=...
agora agents doctor                     # the decision rows must say key_env=set
agora decide --state "harden parse_size against malformed input" \
  --choice strategy=collaborative,adversarial,hybrid --noul risky   # one request; answers with model and confidence
agora run "harden parse_size" --strategy auto --judge decision --proof-cmd "pytest -q" --dry-run   # who answers, who does what
agora run "harden parse_size" --strategy auto --judge decision --proof-cmd "pytest -q"
What to expect in AGORA-LOG.md: a DECISION decision=strategy line with the model and the confidence, a CHOICE decision=strategy value=... source=decision line (or source=default with the reason), a DECISION decision=triage line per material finding, and with --judge decision a DECISION decision=judge finding=R1 line per finding followed by JUDGE by=decision unresolved=[...] cleared=[...]. Tunables: --decision-min-confidence (default 0.5, below it the default applies), --decision-timeout (default 5 s; BeatAPI's free route can be slow), --no-decisions. Declared order is the order tried, so put the free model you trust first; a 429 puts that model in cooldown and the next one answers; identical questions are served from the 30-minute cache, so a retried turn never spends a one-per-minute quota twice. Decision models never fill a loop role and never approve: with --judge decision a finding is cleared only when the model answers addressed or out_of_scope above the confidence floor, and the model's provider must differ from the planner's and the red team's.
What an approval means
- An approval is bound to the plan path and its SHA256. Change one byte and the loop refuses to build.
- An inspection records the pre-build commit and a fingerprint of the working tree including untracked files. Later edits need another inspection.
- Reviewers and inspectors get the CLI's read-only flags when it has them (Claude Code, Codex, Gemini CLI and Aider in the example catalog); builders get bounded write permission. Flags are a request, so every turn is also bracketed by a working-tree fingerprint: a read-only turn that changes the tree fails, is logged with
tree_changed=true, and that agent counts as an author who may never inspect.--dry-runwarns about catalog entries that have no read-only flags. - The approved plan is re-checked after every build and fix turn and before every inspection. A builder that rewrites
PLAN.mdends the run withPLAN_TAMPERED. - Everyone who wrote or revised the plan is excluded from reviewing it, and quorum peers come from distinct providers. In the hybrid strategy a plan the red team forced to be revised goes back to the peers once.
- On Windows, npm's
.cmdshims are never launched throughcmd.exe, which would re-parse the prompt as a command line; Agora resolves them tonode <entry.js>or refuses to run them. - Agent output never forges a log line: control characters are stripped from every logged value.
BLOCKED, malformed output, duplicate finding ids,APPROVEDwith high or medium findings, an exhausted round budget, or a rate-limited reviewer with fallback disabled are all surfaced. None of them is ever converted into approval.- Zero findings is a valid outcome. A pile of findings is not a quality score. A quorum is evidence, not truth.
Tests
Everything runs on fake agent processes and disposable git repositories. The default suite spends no quota and needs no credentials.
python scripts/validate.py agents.example.toml
python -m unittest discover -s tests -t . -v
| Group | What it proves |
|---|---|
| ledger | windows roll, UTC-midnight and rolling resets, cooldown backoff and cap, caps learned from a 429, headroom math, persistence |
| allocator | hard filters hold across 1,000 randomised draws, auto:cheap prefers free tiers, seeded bandit is deterministic, dry-run spends nothing, independence via role references |
| review | schema validation: duplicate ids, bad severity, APPROVED with material findings, missing coverage, JSON wrapped in prose or in claude -p output |
| runner | five artifact files, stderr preserved, timeout kills the process tree, rate-limit detection (never on a clean exit, never on a killed turn, never on rate_limited= echoed from a log or a line 429 in a traceback), Windows Node launch path, HTTP agents including 429 |
| approval | one byte invalidates an approval, untracked files change the inspection fingerprint |
| strategies | all three reach a terminal state inside the round cap; BLOCKED, malformed, duplicate ids and APPROVED-with-material are rejected; quorum; judge rules; tampered plan refused; fix rounds |
| fallback | logged with fallback_from, fallback_to, reason; --no-fallback fails loudly; independence survives fallback; budget |
| hardening | Windows proof-command quoting; a read-only turn that changes the tree fails and becomes an author; a builder rewriting the approved plan is refused; the reviser never reviews its own revision; quorum peers from distinct providers; hybrid re-reviews a red-team revision; [profiles] validated and unknown profiles refused; agents without an executable are skipped; npm shims resolved and unknown .cmd files refused; a killed turn is never rate-limited by keyword; learned caps exclude the rejected request; token usage reaches the ledger; agent text cannot forge a log line; a missing proof command is logged and reported; agents init; mistakes exit 2 without a traceback |
| decisions | typed answers parsed for the three response shapes; wrong model, malformed and out-of-criteria answers rejected; 429 enters cooldown and the next model is tried; cache stops a second request; missing key and independence reported, never raised; --strategy auto follows a confident decision and defaults to hybrid otherwise; --allocation auto switches the preset; --judge decision clears only a confident addressed/out_of_scope, needs a third provider, and treats a pre-build proof as evidence; triage logged; dry-run notes; agora decide and doctor |
| two providers | judge skipped and logged with --judge both, loop still converges; --judge llm fails loudly; dry-run drops the judge with a note |
| end to end | three fake agents, a toy repo, a real proof command, all three strategies, log and per-agent quota asserted |
CI runs the suite on Ubuntu, Windows and macOS with Python 3.11 and 3.13, then installs the package and smokes the CLI. Live runs against real CLIs are opt-in and recorded in VALIDATION.md.
Limitations and terms of service
- No frontier guarantee: the agent that has quota left late in the day may not be the smartest one. The log always says who did what.
- Independence is by provider, not by model family. Two agents backed by the same upstream model are not independent even if their providers differ.
- Use only quotas you are entitled to. Several vendors forbid proxying or resale of free tiers; FreeLLMAPI's architecture docs keep an honest per-provider table. Agora never shares a credential between agents and never routes one agent's traffic through another's account.
- The loop needs headless CLIs. Editor-only agents (Cursor, Cline VS Code, Roo Code, Continue, Zed, JetBrains AI) are not in the catalog until they expose one.
- This is not a chat proxy. Point raw clients at FreeLLMAPI instead and list it here as an HTTP tier.
Contributing
Good first PRs:
- Validate an agent you have installed: run
agora agents doctor, then a--dry-runand one real loop, and add a row toVALIDATION.md. - Add an agent: one
[[agents]]table inagents.example.tomlwith its headless argv and documented quota, plus a test intests/test_validate_and_cli.pyif it needs special parsing. - Improve the bandit: latency-weighted priors, per-role reliability, regional pinning.
- Strategy ideas: tournament (N proposals, one judge), debate with a moderator, mixed authorship with cross-inspection.
Run the suite before opening a PR. See CONTRIBUTING.md.
Credits
- FreeLLMAPI (MIT) for the quota ledger, the bandit scoring, the fallback chain and the agent logos in
assets/agents/. - Claudex Loop (MIT) by Chase AI for the plan / review / build / inspect loop, the structured verdict contract, SHA-bound approvals, fake-CLI testing and the read-only reviewer flags. Claudex Loop itself credits Matt Pocock and Peter Steinberger.
MIT licensed. Agent logos belong to their respective projects.
1 maintainer

Metadata
1 maintainer
Release files for agora-loop 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| agora_loop-0.1.0.tar.gz | 102.9 kB | With provenance | Details for agora_loop-0.1.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| agora_loop-0.1.0-py3-none-any.whl | Python 3 | none | any | Details for agora_loop-0.1.0-py3-none-any.whl |
Total release size: 163.2 kB
Release files / agora_loop-0.1.0.tar.gz
| Download URL | agora_loop-0.1.0.tar.gz |
|---|---|
| Size | 102.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
837339a6c9b9dc19395d1c1afe73f080234681517eb31f13cdef843c542b5131
|
|
BLAKE2b-256 checksum How to use checksums |
05364c68c6fe84557e5d25fbce53c4e862d367933ed7d3c6bd111aa7cdaaf1c3
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 30, 2026.
Transparency logRelease files / agora_loop-0.1.0-py3-none-any.whl
| Download URL | agora_loop-0.1.0-py3-none-any.whl |
|---|---|
| Size | 60.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
c48051869173b1d02cd9946b0773ae3e458abac0b1ec6db014818f7c6dec00ee
|
|
BLAKE2b-256 checksum How to use checksums |
73c963d9976263552ad30aed509d78c3f83fdf53bdda9a19d232e55742926080
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 30, 2026.
Transparency logSecurity for agora-loop 0.1.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for agora_loop-0.1.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 30, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.













