
AI-Driven E2E Test Self-Healing Engine


Using LLM APIs? This project optionally supports OrcaRouter: one API for 200+ models with zero markup and cost-aware routing. Using this referral link supports the project with a 5% commission at no additional cost to you.
OrcaRouter is an optional LLM provider for this project. See Using OrcaRouter for the configuration.
A self-healing engine that automatically repairs broken Playwright E2E tests with an AI agent built on LangGraph. When a UI change renames or restructures an element and a test's selector breaks, the engine diagnoses the failure, patches the broken selector/wait, verifies the new selector against the live DOM, then re-runs the test until it passes (or a retry cap is hit) and writes the fix back — as a local CLI or a CI GitHub Action that opens a patch PR.
Scope guardrail: the engine only fixes failing locators and wait conditions. It never touches assertions or test logic, and every patch stays human-reviewable.
Two modes: heal and review
Auto-healing patches the test. That is fast, but on its own it can look like papering over a real problem — the source that broke the selector. So the engine offers a second mode:
heal(default) — patch the broken selector/wait and re-run until green. Best when the UI change is intentional and the test simply needs to catch up.review— diagnose why the selector broke and post source-level suggestions as inline PR comments (e.g. "thisclassNamerename broke#cta; add a stabledata-testidor usegetByRole"). It never edits the test — it advises the fix at the source and pushes teams toward resilient, accessibility-first selectors.
Same diagnosis engine, two outputs: a patch, or a review. Pick per-project or per-PR.
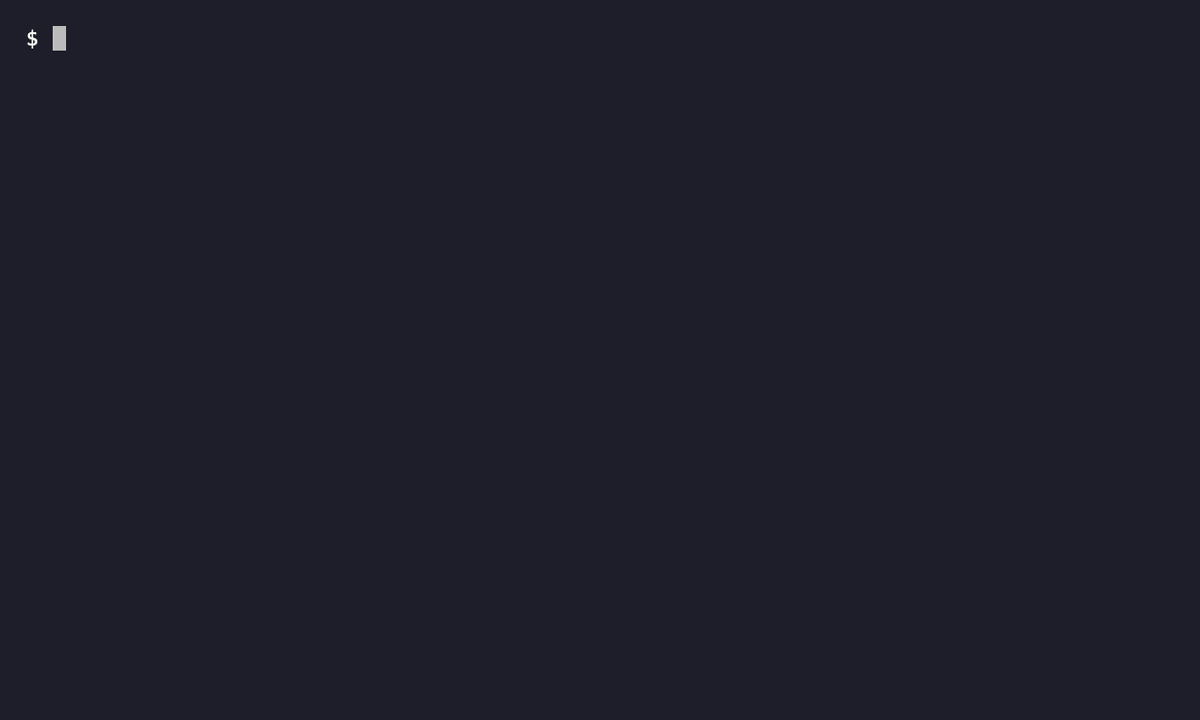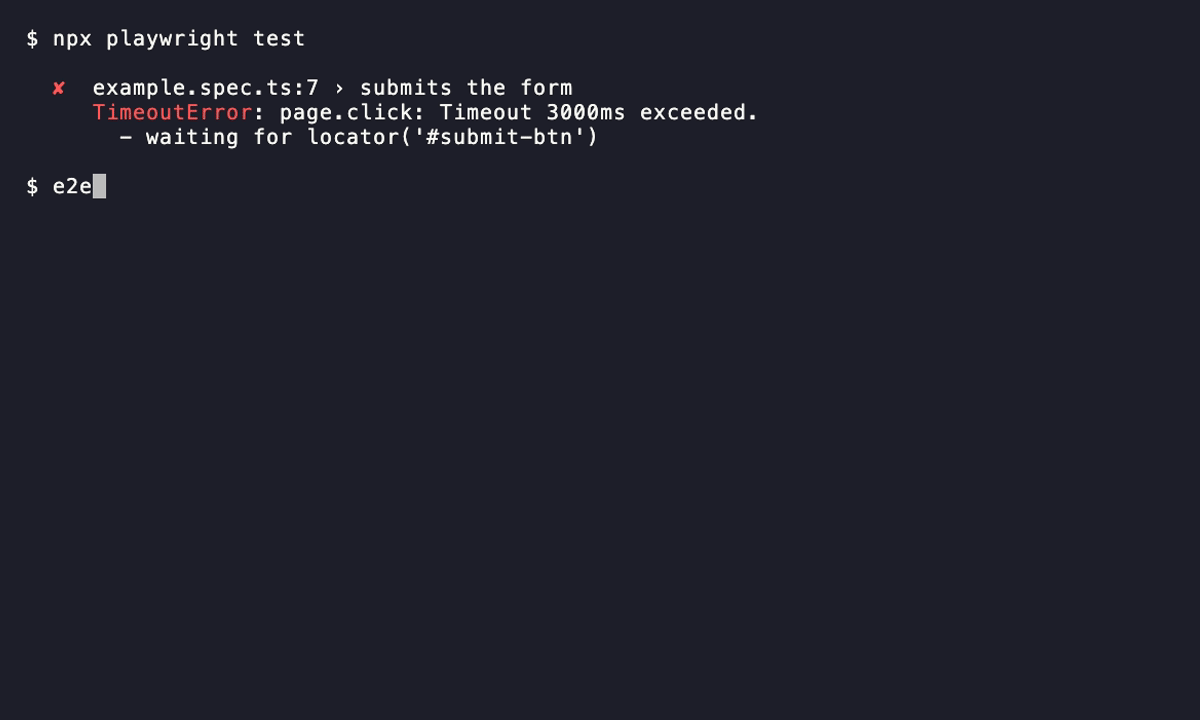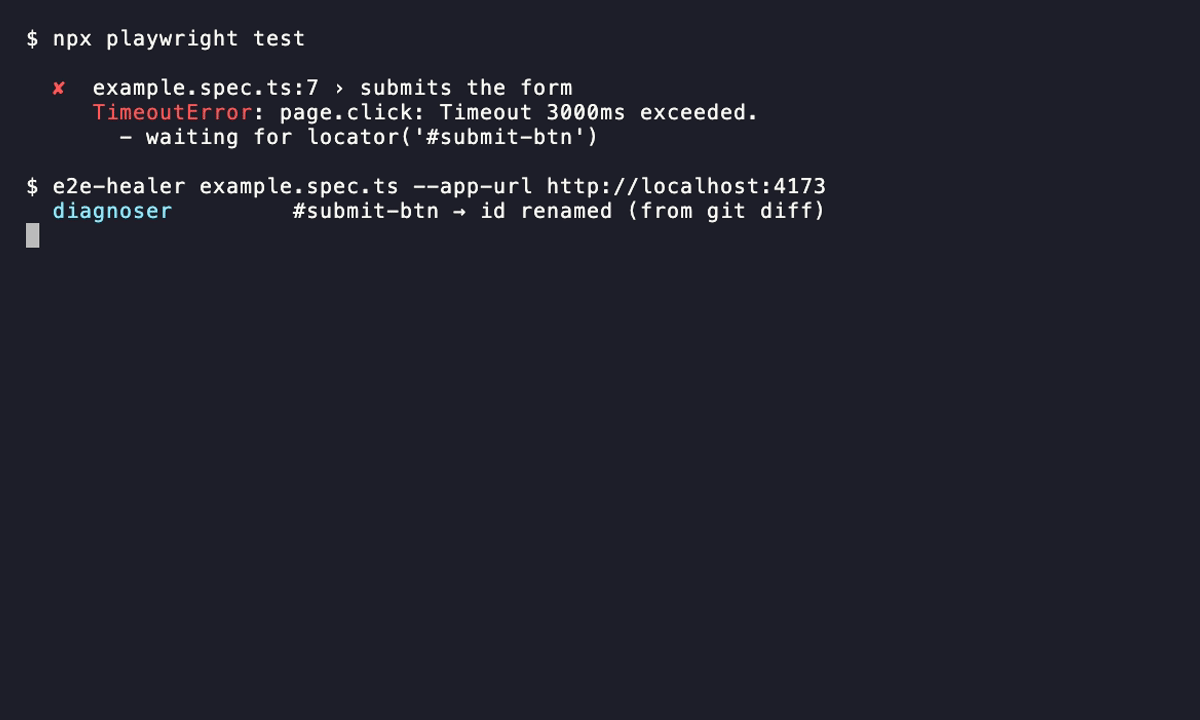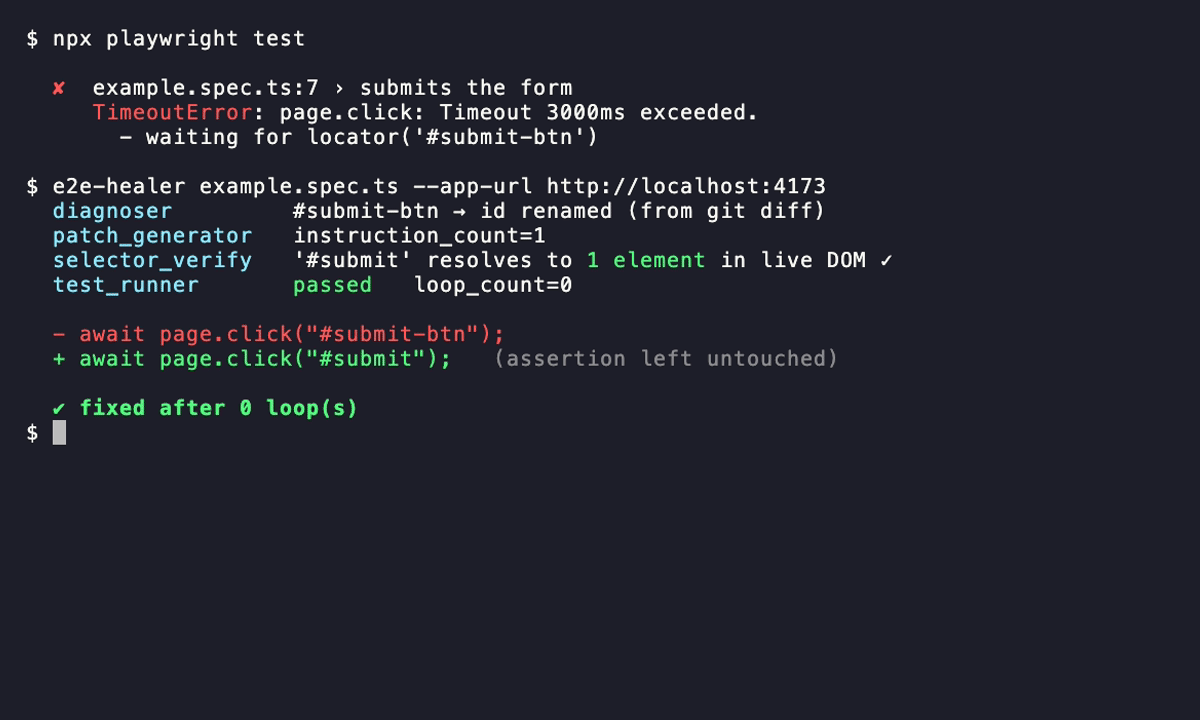
How it works
Four layers drive a LangGraph repair loop:
- CLI core — the single entry point (
e2e-healer); everything, including CI, calls it. - Data Preprocessor — abstracts the raw Playwright log and the
git diffinto compact, hallucination-resistant context (the failing selector + the DOM attribute that changed). - LangGraph agent —
Diagnoser → Patch Generator → Selector Verifier → Test Runner, looping via a conditional Router until the test passes ormax_loopsis reached. - Selector Verifier — checks each patched selector against the real page DOM so it resolves to exactly one element (Node/Playwright helper). Hallucinated (0 matches) or ambiguous (>1) selectors are reverted and re-patched before a full test run.
- Test Runner — runs
npx playwright testvia subprocess to validate each attempt.
   ┌──────────┐    ┌─────────────────┐    ┌───────────────────┐    ┌─────────────┐
──▶│ Diagnoser│──▶ │ Patch Generator │──▶ │ Selector Verifier │─┬─▶│ Test Runner │──┐
   └──────────┘    └─────────────────┘    └───────────────────┘ │  └─────────────┘  │
        ▲                   ▲  verify fail (0/2+ match) → repatch ┘                   │
        │                   └───────────────────────────────────────────────────────┘│
        │                          fail & loop_count < max                            │
        └───────────────────────────────  Router  ◀───────────────────────────────────┘
                                            │ pass or loop cap
                                            ▼
                                          [End]
The Selector Verifier skips gracefully (loop proceeds unverified) when
E2E_HEALER_APP_URLis empty or the page is unreachable (e.g. Node/Playwright not installed) — tooling problems never block a heal.
See docs/design.md for the full design, and
docs/shadow-testing.md for the planned Shadow Testing pipeline.
Usage (CI / GitHub Action)
The flagship workflow: run your suite and auto-heal on failure, opening a patch PR for review:
- name: E2E self-heal
  id: heal
  uses: Lee-Dongwook/E2E-Self-Heal@v0.4.0
  with:
      test-path: tests/example.spec.ts
      nvidia-api-key: ${{ secrets.NVIDIA_API_KEY }}
      diff-base: ${{ github.event.pull_request.base.sha }}
      app-url: http://localhost:4173 # optional: enables live selector verification

- name: Open patch PR
  if: steps.heal.outputs.outcome == 'healed'
  uses: peter-evans/create-pull-request@v6
  with:
      body-path: ${{ steps.heal.outputs.summary-path }}
      branch: e2e-self-heal/${{ github.run_id }}
The action's outcome output is passed | healed | unhealed (heal mode) or reviewed
(review mode). For a Playwright suite in a subdirectory, pass working-directory:. A
runnable self-demo that heals this repo's own examples/ project lives in
ci/github-workflow.example.yml.
To run as a PR review bot instead, pass mode: review and post the findings as inline PR
comments — a ready-to-copy workflow lives in
ci/github-review-bot.example.yml:
- name: E2E review
  id: review
  uses: Lee-Dongwook/E2E-Self-Heal@v0.4.0
  with:
      mode: review
      test-path: tests/example.spec.ts
      nvidia-api-key: ${{ secrets.NVIDIA_API_KEY }}
      diff-base: ${{ github.event.pull_request.base.sha }}
# then read steps.review.outputs.review-path and post inline comments (see the example)
Demo (verified end-to-end)
The examples/ project is a runnable React + Vite app the engine heals
end to end. It ships green — on a clean checkout every spec passes against the real app.
Applying a scenario's real git diff breaks it: the
id-rename scenario renames the button id
submit-btn → submit, so scenarios/id-rename/spec.ts times out on #submit-btn.
Running the healer against it (with a live NVIDIA key) produces:
diagnoser_finished
patch_generator_finished        instruction_count=1
selector_verify_started         selector_count=1 url=http://localhost:4173
selector_verify_passed          counts={'#submit': 1}
test_runner_passed              loop_count=0
fixed after 0 loop(s)
- await page.click("#submit-btn");
+ await page.click("#submit");        # assertion on "Thanks!" left untouched
Reproduce it yourself (the demo uses pnpm): see
examples/README.md.
In practice
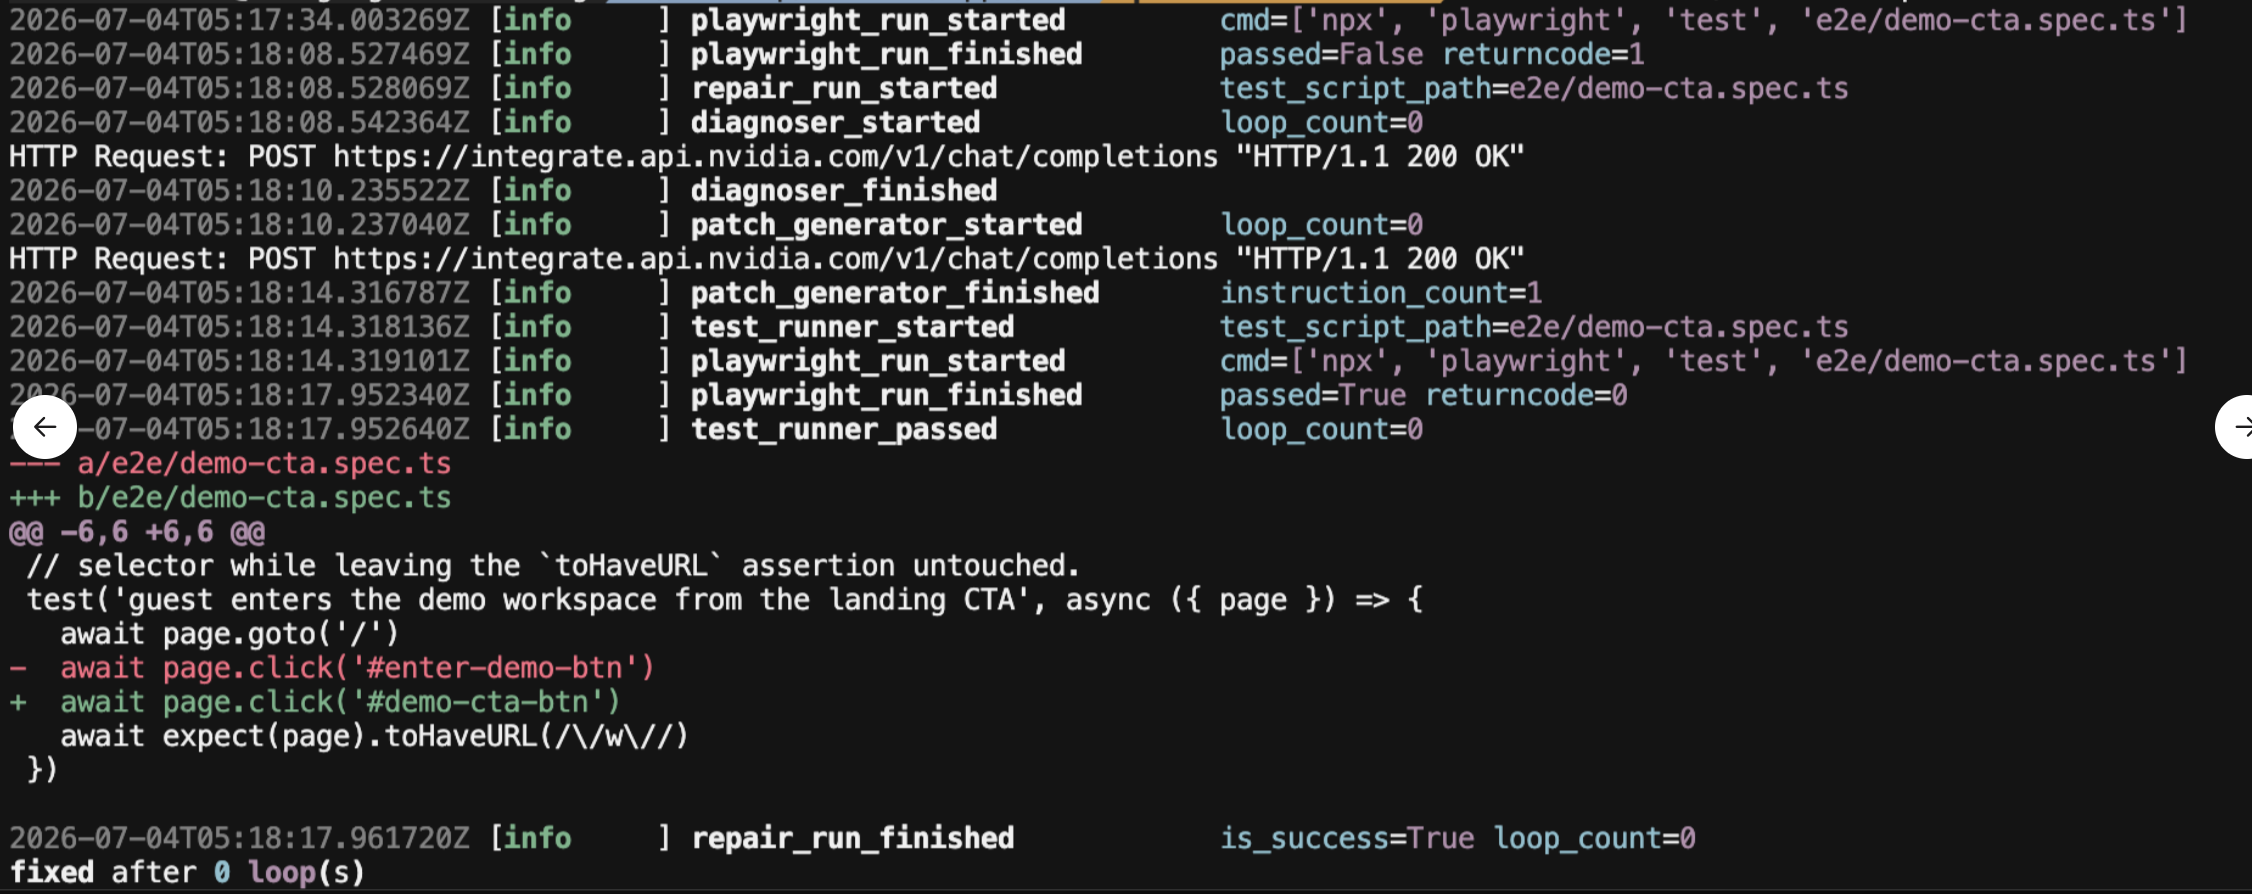
A real run against a landing-page CTA test. A UI refactor renamed the button id
#enter-demo-btn → #demo-cta-btn, so demo-cta.spec.ts started failing on
locator.click. Pointed at the file, the engine diagnosed the break against the git diff,
patched only the broken selector (leaving the toHaveURL assertion untouched), re-ran
the suite, and passed on the first attempt — end to end on NVIDIA NIM
(integrate.api.nvidia.com, openai/gpt-oss-120b):
playwright_run_finished     passed=False                    # original selector times out
diagnoser_started           loop_count=0
diagnoser_finished
patch_generator_finished    instruction_count=1
test_runner_started
playwright_run_finished     passed=True
repair_run_finished         is_success=True loop_count=0
fixed after 0 loop(s)
  test('guest enters the demo workspace from the landing CTA', async ({ page }) => {
    await page.goto('/')
-   await page.click('#enter-demo-btn')
+   await page.click('#demo-cta-btn')
    await expect(page).toHaveURL(/\/w\//)   // assertion left untouched
  })
Install
Requires Python 3.13+ and a Playwright project (Node) in your repo.
Recommended — one-line global install:
pipx install ai-driven-e2e
# or, before PyPI release:
uv tool install git+https://github.com/Lee-Dongwook/E2E-Self-Heal.git
Then in any Playwright project:
cp .env.example .env    # set E2E_HEALER_LLM_API_KEY (or your provider's key)
e2e-healer tests/login.spec.ts
Works with NVIDIA NIM (default), OpenAI, Anthropic (Claude), DeepSeek, OrcaRouter, or a local Ollama model —
see Configuration to pick one. For the default, get a free NVIDIA NIM API
key at build.nvidia.com (default model openai/gpt-oss-120b).
Development install from a local clone
git clone https://github.com/Lee-Dongwook/E2E-Self-Heal.git
cd E2E-Self-Heal
uv sync --extra dev
uv tool install --force .    # global `e2e-healer` from this checkout
Re-run uv tool install --force . after pulling changes.
Usage (CLI)
# Heal the WHOLE suite — run every test, then repair each failing file (aggregate summary):
uv run e2e-healer

# Heal a single failing test (with no --log, the tool runs it to capture the failure):
uv run e2e-healer tests/example.spec.ts

# Preview only — run the loop but write nothing:
uv run e2e-healer tests/example.spec.ts --dry-run

# Disable local healing-history lookup and storage for this run:
uv run e2e-healer tests/example.spec.ts --no-memory

# Feed a pre-captured log and a PR-scoped diff (the CI path):
uv run e2e-healer tests/example.spec.ts --log playwright.log --diff-base origin/main --json

# Enable live-DOM selector verification against a running app:
uv run e2e-healer tests/example.spec.ts --app-url http://localhost:4173

# Review mode — suggest source-level fixes instead of patching (never edits the test):
uv run e2e-healer review tests/example.spec.ts --log playwright.log --diff-base origin/main --json

# Compare the Diagnoser's full-file and semantic-context prompt-token estimates for shipped examples:
uv run e2e-healer benchmark
Pass --root <dir> to anchor all relative paths (the spec, --diff, test-results/, and the
git diff/Playwright subprocess cwd) to a project root — useful when invoking the CLI from a
directory other than the project root (e.g. from a Playwright Reporter).
Exit code is 0 when the test is healed, non-zero otherwise. --json prints a
machine-readable summary to stdout (human output goes to stderr) so CI can branch on it:
a RepairSummary for a successful single-file heal, a RefusalReport when it declines a
single-file repair, a SuiteSummary for suite mode, and a ReviewReport in review mode.
Every emitted summary is self-describing: it carries a schema_version (currently "2.0")
and a kind discriminator ("repair" / "refusal" / "suite" / "review") so the CI
wrapper can dispatch without guessing on keys. e2e-healer <path>
is shorthand for e2e-healer heal <path>; review is a separate subcommand that emits a
ReviewReport (findings anchored to the changed source line) and always exits 0 — the
CI wrapper branches on has_findings.
Healing history is enabled by default. Pass --no-memory to fully bypass local history lookup
and verified-repair storage for a run; pass --memory explicitly to enable the default behavior.
Benchmark semantic-context token usage
Run uv run e2e-healer benchmark to render a rich table comparing the full-file and
semantic-context Diagnoser prompt sizes for each checked-in breakage scenario. It needs neither
provider credentials nor a running Playwright app. Counts include the Diagnoser system and user
prompt content, estimated with the fixed cl100k_base tokenizer; they are a stable comparison
metric, not a provider-billed-token statement. tiktoken may download this tokenizer on first
use, then serves it from its local cache. A scenario that cannot yield an enclosing JSX node is
labeled whole-file fallback and correctly reports zero savings.
Configuration
All settings use the E2E_HEALER_ prefix (see .env.example). LLM
configuration is provider-neutral: pick a backend with E2E_HEALER_LLM_PROVIDER and
configure it via the generic LLM_* vars. The legacy NVIDIA_* vars still work — when
the provider is nvidia they are folded into the generic ones, so existing setups need no
changes.
Provider matrix
| Provider | Install | Required env | Structured outputs | Notes |
|---|---|---|---|---|
nvidia |
built-in (default) | E2E_HEALER_LLM_API_KEY (or legacy NVIDIA_API_KEY) |
strict json_schema |
OpenAI-compatible NIM endpoint; default openai/gpt-oss-120b. |
openai |
built-in | E2E_HEALER_LLM_API_KEY or OPENAI_API_KEY |
strict json_schema (native) |
Set LLM_BASE_URL for Azure / OpenAI-compatible endpoints. |
anthropic |
ai-driven-e2e[anthropic] |
E2E_HEALER_LLM_API_KEY or ANTHROPIC_API_KEY |
tool-use | No OpenAI response_format; schema enforced via Claude tool-use. |
ollama |
ai-driven-e2e[ollama] |
none (local) | native JSON-schema format |
Fully offline; smaller models are less reliable at strict JSON. |
deepseek |
built-in | E2E_HEALER_LLM_API_KEY or DEEPSEEK_API_KEY |
Responses API json_schema |
Stateless Responses API; default deepseek-v4-flash. |
orcarouter |
built-in | E2E_HEALER_LLM_API_KEY or ORCAROUTER_API_KEY |
LangChain default | OpenAI-compatible endpoint; default base URL is https://api.orcarouter.ai/v1. |
All providers read the generic E2E_HEALER_LLM_MODEL / E2E_HEALER_LLM_MAX_TOKENS /
E2E_HEALER_LLM_BASE_URL. On a structured-output parse failure the engine retries
(tenacity) and then falls back to the Patch Generator feedback loop, so a flaky JSON
response never crashes the run.
Using OpenAI
Set the provider to openai and supply a key — either the generic E2E_HEALER_LLM_API_KEY
or an existing standard OPENAI_API_KEY (used as a fallback). Patch/review use OpenAI's
native strict Structured Outputs. Point E2E_HEALER_LLM_BASE_URL at an Azure or
OpenAI-compatible endpoint to override the default.
E2E_HEALER_LLM_PROVIDER=openai
OPENAI_API_KEY=sk-...            # or E2E_HEALER_LLM_API_KEY=sk-...
E2E_HEALER_LLM_MODEL=gpt-4o-mini
Using OrcaRouter
OrcaRouter is an optional OpenAI-compatible provider. Select it explicitly; it never
changes the default NVIDIA configuration. Supply either the generic
E2E_HEALER_LLM_API_KEY or ORCAROUTER_API_KEY. ORCAROUTER_BASE_URL defaults to
https://api.orcarouter.ai/v1, and can be overridden without changing application code.
E2E_HEALER_LLM_PROVIDER=orcarouter
ORCAROUTER_API_KEY=your_orcarouter_api_key_here
E2E_HEALER_LLM_MODEL=your_structured_output_model
# ORCAROUTER_BASE_URL=https://api.orcarouter.ai/v1
Using Anthropic (Claude)
Anthropic is an optional dependency — install the extra so non-Anthropic users don't pull it in:
pip install "ai-driven-e2e[anthropic]" # or: uv sync --extra anthropic
Then set the provider and a key — either E2E_HEALER_LLM_API_KEY or an existing standard
ANTHROPIC_API_KEY (fallback). Claude has no OpenAI-style response_format, so
PatchOutput/ReviewOutput are enforced via tool-use.
E2E_HEALER_LLM_PROVIDER=anthropic
ANTHROPIC_API_KEY=sk-ant-...     # or E2E_HEALER_LLM_API_KEY=sk-ant-...
E2E_HEALER_LLM_MODEL=claude-sonnet-4-6
Using Ollama (local, offline)
Run fully offline with no API key. Ollama is an optional dependency:
pip install "ai-driven-e2e[ollama]" # or: uv sync --extra ollama
Start Ollama and pull a model, then point the provider at it. Structured outputs use
Ollama's native JSON-schema format, so pick a model that handles structured output
well — recommended: llama3.1, qwen2.5-coder, or mistral-nemo. Smaller/older models are
less reliable at strict JSON; on a parse failure the engine retries and falls back to the
Patch Generator feedback loop.
E2E_HEALER_LLM_PROVIDER=ollama
E2E_HEALER_LLM_MODEL=llama3.1
# E2E_HEALER_LLM_BASE_URL=http://localhost:11434   # default; override for a remote host
Using DeepSeek (Responses API)
DeepSeek is exposed through its Responses API (client.responses.create() at
https://api.deepseek.com) rather than the LangChain chat path, so the provider is a small
built-in adapter that speaks that API directly. Supply a key — either
E2E_HEALER_LLM_API_KEY or an existing standard DEEPSEEK_API_KEY (fallback). The default
model is deepseek-v4-flash (the Responses API currently supports only this model;
deepseek-v4-pro is pending). Setting E2E_HEALER_LLM_MODEL to any other model is
rejected unless E2E_HEALER_LLM_BASE_URL points at a custom OpenAI-compatible endpoint
that may serve it. Structured output is requested with the Responses API text.format
json_schema parameter, and the returned JSON is validated against
PatchOutput/ReviewOutput, so schema enforcement holds without LangChain.
E2E_HEALER_LLM_PROVIDER=deepseek
DEEPSEEK_API_KEY=sk-...          # or E2E_HEALER_LLM_API_KEY=sk-...
# E2E_HEALER_LLM_MODEL=deepseek-v4-flash   # default; set only to override
Try it live against the API (set DEEPSEEK_API_KEY first):
uv run e2e-healer --help >/dev/null  # import smoke check
E2E_HEALER_LLM_PROVIDER=deepseek uv run python - <<'PY'
from app.llm import generate_diagnosis
print(generate_diagnosis("You are a terse assistant.", "Say OK"))
PY
| Variable | Default | Purpose |
|---|---|---|
E2E_HEALER_LLM_PROVIDER |
nvidia |
LLM backend: nvidia, openai, anthropic, ollama, deepseek, orcarouter |
E2E_HEALER_LLM_API_KEY |
— | API key for the selected provider |
E2E_HEALER_LLM_BASE_URL |
— | OpenAI-compatible endpoint (empty = SDK default) |
E2E_HEALER_LLM_MODEL |
— | Structured-Outputs-capable model |
E2E_HEALER_LLM_MAX_TOKENS |
4096 |
Completion token cap (headroom for reasoning) |
E2E_HEALER_NVIDIA_API_KEY |
— | NVIDIA NIM API key (legacy; maps to LLM_API_KEY) |
E2E_HEALER_NVIDIA_BASE_URL |
https://integrate.api.nvidia.com/v1 |
OpenAI-compatible endpoint (legacy) |
E2E_HEALER_NVIDIA_MODEL |
openai/gpt-oss-120b |
Structured-Outputs-capable model (legacy) |
E2E_HEALER_NVIDIA_MAX_TOKENS |
4096 |
Completion token cap (legacy) |
ORCAROUTER_API_KEY |
— | OrcaRouter API key (used when provider is orcarouter) |
ORCAROUTER_BASE_URL |
https://api.orcarouter.ai/v1 |
OrcaRouter OpenAI-compatible endpoint |
E2E_HEALER_MAX_LOOPS |
3 |
Repair loop cap |
E2E_HEALER_PLAYWRIGHT_CMD |
npx playwright test |
Playwright invocation |
E2E_HEALER_VERIFY_SELECTORS |
true |
Toggle live-DOM selector verification |
E2E_HEALER_APP_URL |
— | URL the Selector Verifier loads (empty = skip) |
E2E_HEALER_NODE_CMD |
node |
Node executable for the verifier |
E2E_HEALER_SANDBOX_MODE |
relaxed |
strict, relaxed, or off |
E2E_HEALER_WORKSPACE_ROOT |
. |
Root for strict path checks |
E2E_HEALER_WRITE_GLOBS |
*.spec.js,... |
Writable test-file globs |
E2E_HEALER_DENY_GLOBS |
.env,.git/**,... |
Paths blocked by the sandbox |
E2E_HEALER_ALLOW_TEMP_HELPER |
true |
Permit selector verifier helper file |
The
--app-urlCLI flag overridesE2E_HEALER_APP_URL. To actually run selector verification locally, the Playwright project needs browsers installed (npm install && npx playwright install).
Development
make install    # uv sync --extra dev
make check      # ruff lint + format check + pyright
make coverage   # pytest with a 90% coverage floor
make test       # pytest
See CONTRIBUTING.md.
Documentation site
The docs-site/ directory contains our Docusaurus documentation site — this is where frontend contributors can help.
To run it locally:
cd docs-site
npm install
npm run start      # dev server with hot reload
npm run build       # production build
Picking up a docs-site component issue? Read docs-site/DESIGN.md first — it's the locked design spec (tokens, layout, dark-mode rules) all components must follow.
Contributing
Contributions of every size are welcome — bug reports, docs, tests, or code. Start with
CONTRIBUTING.md, then browse
good first issues
and help wanted.
Limitations
- Fixes selectors and waits only — never assertions or control flow.
- The Selector Verifier checks the entry-page state at
APP_URLin v1. Elements that only appear after clicks/navigation aren't verified here; the Test Runner remains the final arbiter (failure-time snapshot capture is planned). - Healing quality depends on the LLM and the clarity of the
git diff.
License
1 maintainer

Metadata
1 maintainer
Release files for ai-driven-e2e 0.5.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| ai_driven_e2e-0.5.0.tar.gz | 1.5 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| ai_driven_e2e-0.5.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.6 MB
Release files / ai_driven_e2e-0.5.0.tar.gz
| Download URL | ai_driven_e2e-0.5.0.tar.gz |
|---|---|
| Size | 1.5 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
2d22ca86d7c38727619ce1228c5f90fcb237382369d739bb709369df2ee38216
|
|
BLAKE2b-256 checksum How to use checksums |
73a285d523b383918f3776fd49afc05609584f8f8a2bff10dbe177ddd83f7dae
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 22, 2026.
Transparency logRelease files / ai_driven_e2e-0.5.0-py3-none-any.whl
| Download URL | ai_driven_e2e-0.5.0-py3-none-any.whl |
|---|---|
| Size | 129.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
df016be784fec91200aeaa5e76c5122c12e50e426f3a107b3775b67df76974f8
|
|
BLAKE2b-256 checksum How to use checksums |
ea3cc643120527563b19ae48671fd98643d4beeeb0e8dc2e0ad31100185f6d10
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 22, 2026.
Transparency log













