
 ai-jury
Convene a cross-vendor multi-agent review jury: coding-agent CLIs, hosted model APIs and local models review the same diff, PR or issue, cross-examine each other, verify the findings, and reach one verdict — a chair's synthesis or a panel vote.



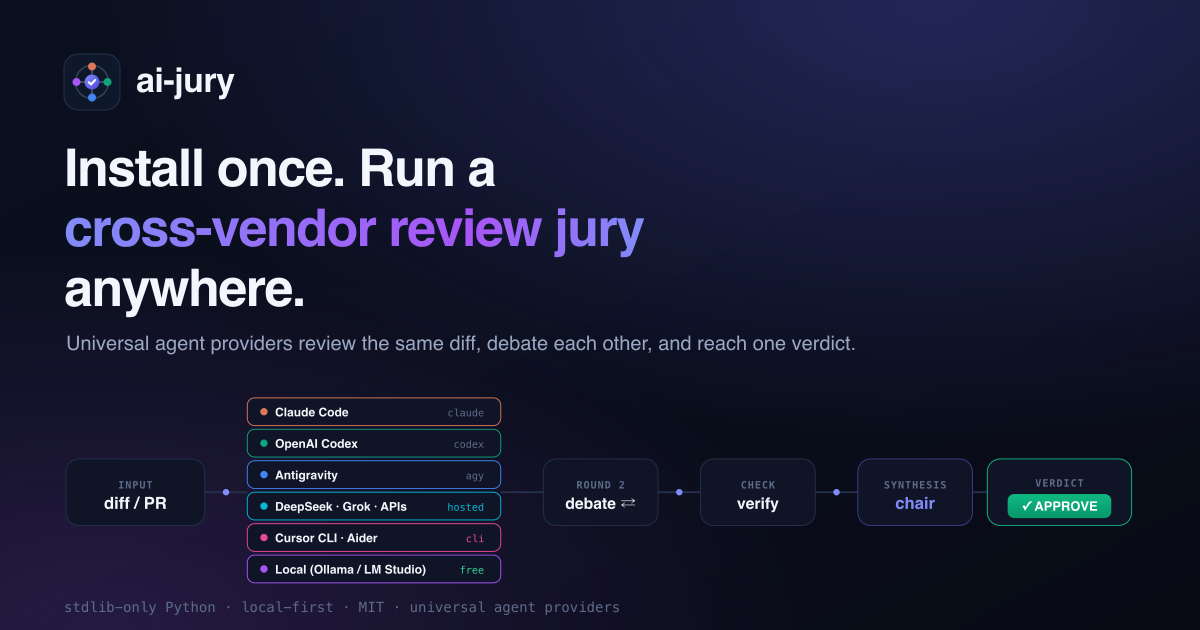
Install once. Run a cross-vendor review jury anywhere.
Most "multi-model review" tools call models at the API level. This one drives any AI agent provider: vendor native CLI agents (claude, codex, agy), hosted API providers (Anthropic, OpenAI, Gemini, xAI Grok, OpenRouter, DeepSeek, Groq, and any other OpenAI-compatible API such as Mistral), free local open-weight models (Ollama, llama.cpp, vLLM, LM Studio), and arbitrary coding-agent CLIs (vendor = "cli" like Aider, Goose, OpenHands) — and hands every seat the diff in its prompt, so no reviewer needs access to your repository. Each agent runs headless; the orchestrator owns the round structure.
        ┌──────── round 1 ────────┐   ┌─ round 2 (adaptive) ─┐   ┌─ verify + synthesis ─┐
diff ──▶ claude codex deepseek qwen ▶ each rebuts the      ▶ chair verifies, then   ▶ verdict
         (parallel, independent)           others' findings       consolidates             + report
Highlights: universal agent provider support (cloud CLIs, hosted APIs, local models, arbitrary CLI agents) · free/offline local reviews · secure by default (reviewers run sandboxed/read-only) · jury init setup · debate + verification · chair verdict or a panel vote · review a PR, a diff, or an issue · live / full-transcript output · CI gating · incremental review · suggested patches · large-diff chunking. Configure once in jury.toml; mix cloud CLIs, hosted APIs, and local models however you like.
Why
Different models miss different things. Running them as an adversarial panel — each
seeing the others' findings and arguing — surfaces more real issues and filters more
false positives than any single reviewer. The research-backed lever is vendor
heterogeneity, not more rounds — and universal provider support lets you mix frontier cloud CLIs, hosted APIs (OpenRouter, DeepSeek, Groq), custom CLI agents (Aider), and free local models at zero marginal cost. See docs/architecture.md and docs/feasibility.md.
Install
# macOS & Linux (Homebrew — recommended):
brew install berkayturanci/ai-jury/ai-jury

# Or standalone curl installer:
curl -fsSL https://ai-jury.dev/install.sh | sh

# Or via pipx / pip:
pipx install ai-jury
Requires Python 3.11+. Try it instantly, no config: jury --mock runs the full
offline deliberation on a diff bundled with the package (add --theater to watch the
panel animate). Then scaffold a config with jury init (it detects your
installed agents, and seats a local reviewer on a model your local server lists). You need at least one reviewer: an agent CLI
(claude or codex, the built-in panel; agy and a bring-your-own CLI such as aider only
when a jury.toml seats them by name, and agy is opt-in because it cannot be confined), a free
local model via Ollama, or a hosted-API reviewer
(Anthropic, OpenAI, Gemini, xAI Grok, OpenRouter, DeepSeek, Groq — or Moonshot Kimi, Mistral or any other
OpenAI-compatible API through vendor = "openai-compatible") — no CLI install or interactive login needed,
useful for CI and containers; missing/unreachable/unkeyed reviewers are skipped. gh is
needed for --pr / --post.
Install into an agent
The above installs the CLI. Installing ai-jury as a plugin — so its skill is available inside an agent session — is a separate step, and the CLI is still required either way. Jump to the agent you use:


Each badge jumps to that agent's box; open it for the commands. (A browser scrolls
to a collapsed <details>; it does not expand one.)
The agent names elsewhere in this README are reviewers the jury convenes. Here the same agents are hosts you install ai-jury into — a different role.
Claude Code — marketplace plugin
Install
claude plugin marketplace add https://github.com/berkayturanci/ai-jury
claude plugin install ai-jury@ai-jury
Update
claude plugin marketplace update ai-jury
claude plugin update ai-jury@ai-jury
claude plugin install is a no-op on an already-installed plugin, so it is
not an upgrade path. plugin update needs the qualified name@marketplace: the
bare name exits 1 with Plugin "ai-jury" not found.
Codex — marketplace plugin
Install
codex plugin marketplace add https://github.com/berkayturanci/ai-jury
codex plugin add ai-jury@ai-jury
Adding the marketplace does not install the plugin; both steps are needed.
Update
codex plugin marketplace upgrade
codex plugin add ai-jury@ai-jury
Antigravity (agy) — git install
Install
agy plugin install https://github.com/berkayturanci/ai-jury
agy plugin enable ai-jury
install alone leaves it disabled.
Update
agy plugin install https://github.com/berkayturanci/ai-jury
Overwrites in place and keeps the enabled flag. It lands in
~/.gemini/config/plugins/ai-jury/, not the ~/.gemini/antigravity-cli/plugins/
path Antigravity's own docs suggest.
Cursor — local checkout
Cursor has no CLI install command — cursor-agent plugin exposes only
marketplace. The local checkout is the route with a straightforward update.
Install
git clone --depth 1 https://github.com/berkayturanci/ai-jury ~/.cursor/plugins/local/ai-jury
Then restart Cursor. It is reported to list as ai-jury (Local) under
Settings → Plugins — a GUI claim, not confirmed from a CLI session.
Update
git -C ~/.cursor/plugins/local/ai-jury pull
A locally installed Cursor plugin registers skills only — no commands,
subagents or MCP servers. The marketplace route
(cursor-agent plugin marketplace add <url>, then install from /plugins)
registers more.
Full detail, including what each route actually registers and where files land:
docs/install.md.
Windows
CI runs two Windows jobs in ci.yml, both on
windows-latest with Python 3.13. The test leg installs the package with pip, runs
the offline unit suite, and runs a --mock review under Git Bash. The Action
self-test runs the GitHub Action itself (uses: ./action) on a --mock review, after
pip install ./action. That is all that is tested on Windows:
- The test leg's install is
pip install -e .from the checkout, and the Action self-test's ispip install ./actionfrom the checkout, which the Action's own pinned install then finds with the package index switched off. No installer is tested on Windows: not pipx, not the PyPI wheel, not Homebrew orcurl | sh.pipx install ai-juryorpip install ai-juryis the route that matches it. - No agent CLI runs in CI on any OS. Whether
claude,codex,agyorghworks on Windows is up to its vendor. A CLI that is missing is skipped, as on any OS. jury run-agentchecks a detached run's process on POSIX only, so on Windows a run that crashed staysrunninginstead oflost.
Usage
Set up — detect your agents and write a jury.toml:
jury init                     # scaffold (detects agents + local models)
jury init --wizard            # guided setup: numbered, skippable questions
jury init --preset balanced   # from a preset: offline | fast | balanced | thorough
Review a pull request:
jury --pr 123                  # review a GitHub PR
jury --pr 123 --auto           # auto-depth: scale rounds/verify to the diff
jury --pr 123 --decision vote  # verdict by panel vote instead of a single chair
jury --pr 123 --post           # post the verdict back as a PR comment
Review an issue — completeness & clarity (READY / NEEDS-INFO / UNCLEAR):
jury --issue 42
jury --issue 42 --decision vote   # tie-break order: NEEDS-INFO > UNCLEAR > READY
jury --issue 42 --live --post     # stream + post each step to the issue thread
Watch it happen — live in your terminal:
jury --pr 123 --live                            # stream each step as it lands
jury --pr 123 --transcript                      # full play-by-play (reviews, debate, reasoning)
jury --pr 123 --theater                         # animated "deliberation" view
jury --pr 123 --theater --theater-style pixel   # …as a pixel-art room (truecolor terminal)
Post to the PR:
jury --pr 123 --post-progress             # one sticky comment, updated each round/chunk
jury --pr 123 --post --post-mode phased   # Round 1 / debate / decision as separate comments
jury --pr 123 --suggest-patches           # also emit inspectable patches for verified findings
jury --pr 123 --incremental               # review only changes since the last run
Local diffs & offline:
git diff origin/HEAD... | jury --diff-file -   # review the current branch
jury --diff-file changes.diff                  # review a diff file
jury --mock                                     # offline demo on a bundled sample, no live CLIs
jury --mock --rounds 1                          # offline: independent review only (no debate)
Inspect:
jury config show   # the effective resolved config + its source
jury --doctor      # readiness check + actionable next steps
Drive one agent from an orchestrator — jury run-agent runs a single
configured agent for one role and prints an ai-jury.run-agent.v1 JSON result
with attribution, using the same adapters, read-only flags and error taxonomy as
a panel run. review/gate/chair are always read-only; implement/fix
need an explicit --allow-write. See
cookbook §21.
jury run-agent --agent claude --role review --prompt-file gate.md
jury run-agent --agent codex:gpt-6-sol --role implement --allow-write --prompt-file task.md
Pre-commit hook (.pre-commit-config.yaml):
- repo: https://github.com/berkayturanci/ai-jury
  rev: v1.24.0
  hooks:
    - id: ai-jury
GitHub Action — two files, both committed. The workflow
(.github/workflows/ai-jury.yml):
name: ai-jury
on: [pull_request]
jobs:
  review:
    runs-on: ubuntu-latest
    permissions:
      contents: read
      pull-requests: write   # the default args (--post) write the review to the PR
    steps:
      - uses: actions/checkout@3d3c42e5aac5ba805825da76410c181273ba90b1  # v7.0.1
      - uses: berkayturanci/ai-jury@v1
        with:
          anthropic-api-key: ${{ secrets.ANTHROPIC_API_KEY }}
          openai-api-key: ${{ secrets.OPENAI_API_KEY }}
…and a jury.toml at the repository root that seats a hosted-API reviewer for each key:
# jury.toml
[jury]
chair = "claude-api"

[[agent]]
name = "claude-api"
vendor = "anthropic-api"     # reads ANTHROPIC_API_KEY
model = "claude-opus-5-5"   # any model your key can call

[[agent]]
name = "codex-api"
vendor = "openai-api"        # reads OPENAI_API_KEY
model = "gpt-6-sol"
The keys alone do not form a panel: without a jury.toml the jury seats its built-in
agent CLIs, which a runner does not have, and the run exits with no usable agents.
Two vendors is also what the Action's min-vendors guard asks for by default. A
gemini-api-key (vendor = "google-api") or xai-api-key (vendor = "xai-api") seat
is added the same way. jury init --agents claude-api,codex-api scaffolds the file
without the model lines, which you fill in.
@v1 installs the ai-jury release that v1 points at, and @vX.Y.Z installs X.Y.Z;
version: overrides it (latest for the newest on PyPI). A branch or SHA ref installs
the version its own tree declares, and fails until that release is on PyPI; pass
version: latest or a released number instead.
A sample report is in docs/example-run.md. For a real
four-vendor run where the jury reviews its own repository (with honest notes on
false positives and the local model's contribution), see
docs/example-live-review.md.
Theater mode — --theater
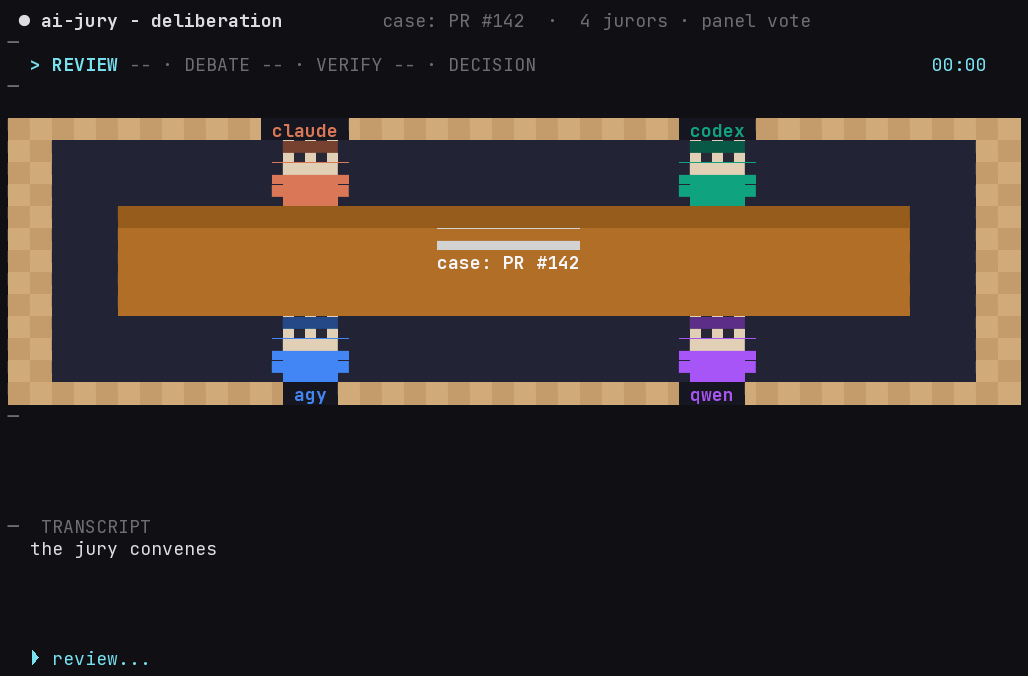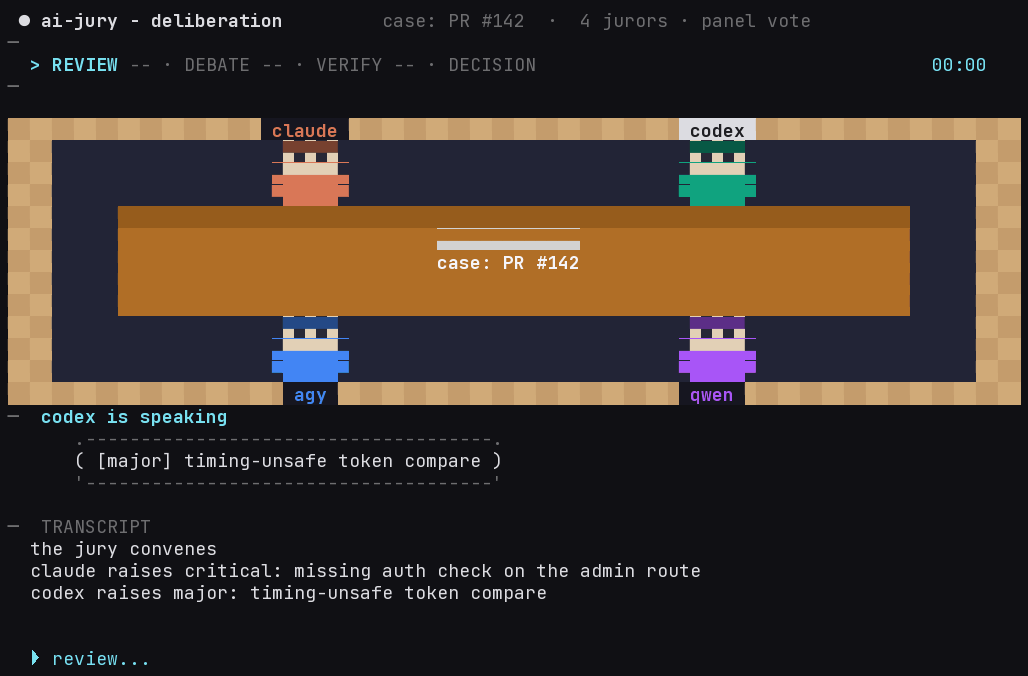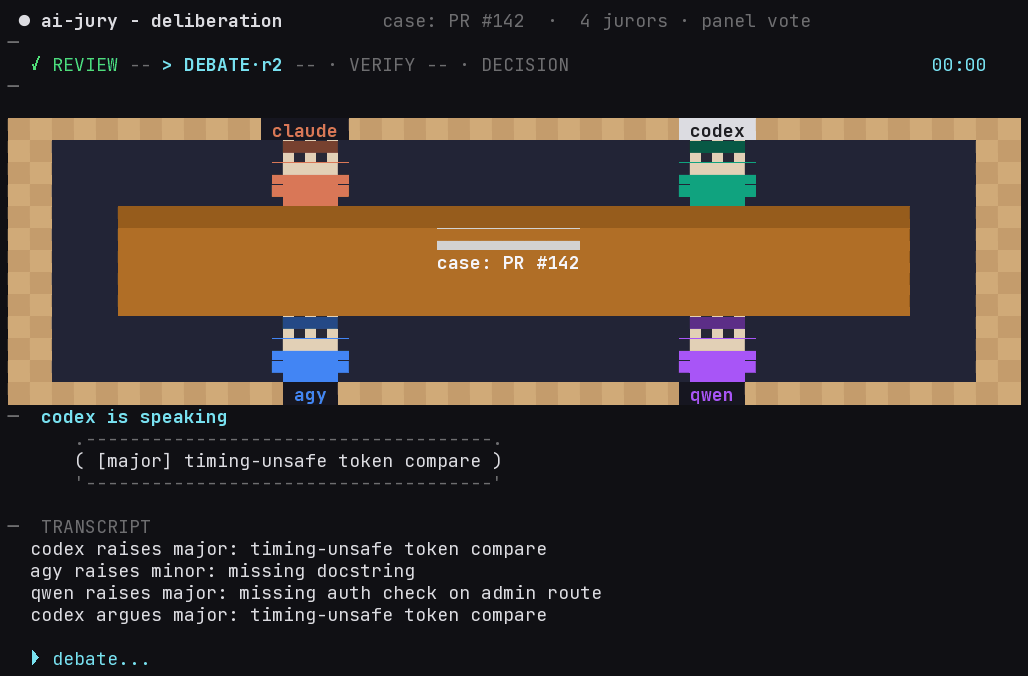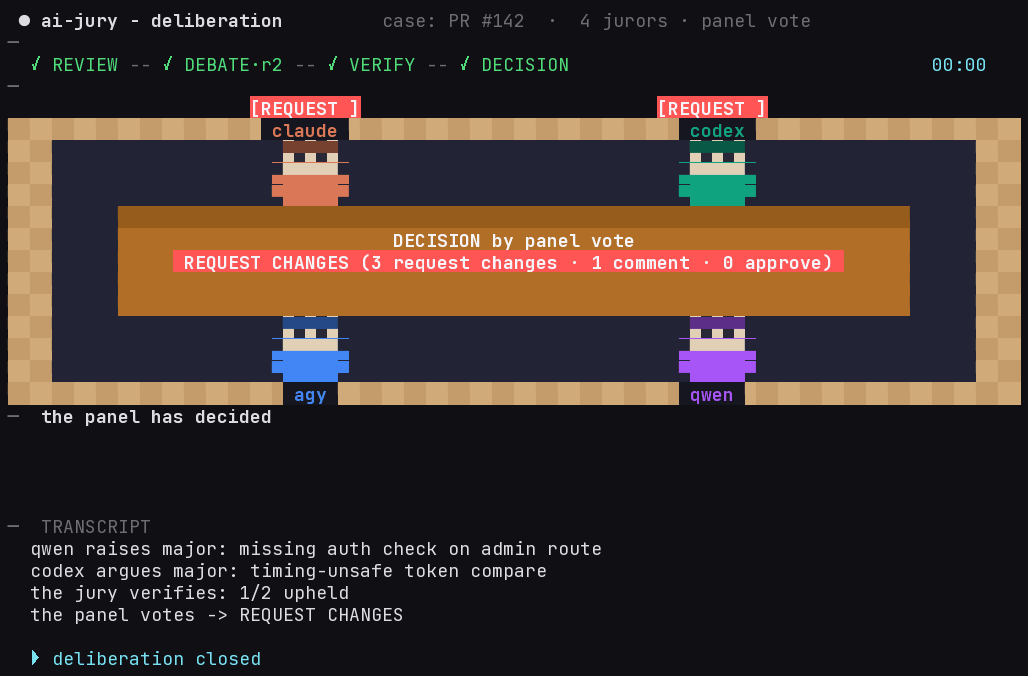
An opt-in, animated deliberation view of a live run: the models sit around a table and take turns speaking as the run moves through review → debate → verify → decision, then reach a decision together — by panel vote, or recorded by the chair. There is no judge; the jurors deliberate with each other.
It renders in two styles, both live in your terminal. An opt-in pixel-art
room (--theater-style pixel; needs a truecolor + unicode terminal):
…and the default flat ANSI scene (--theater):
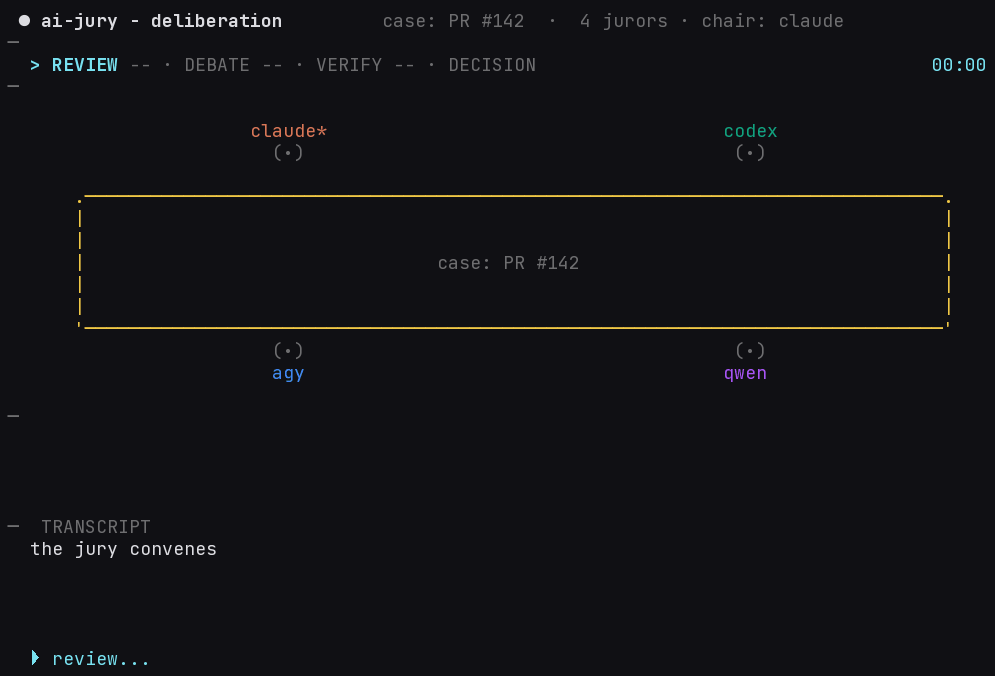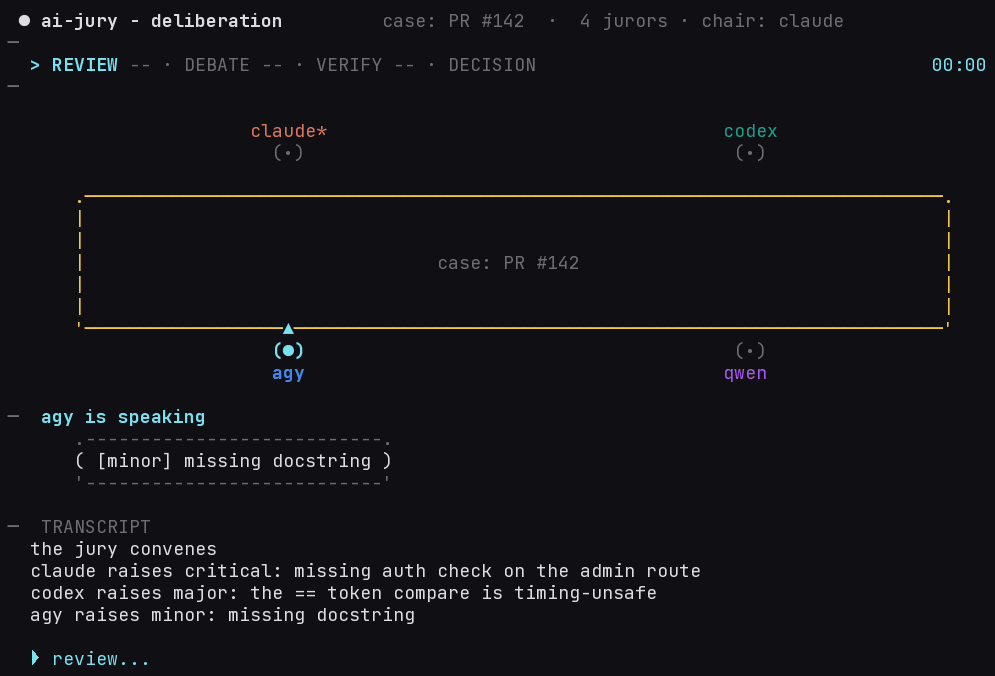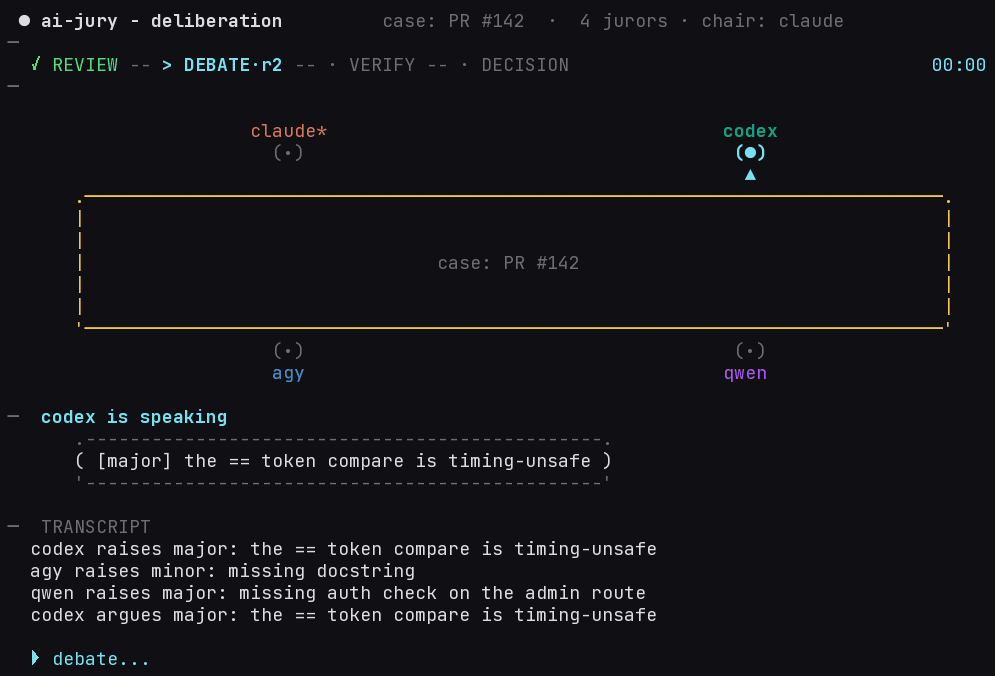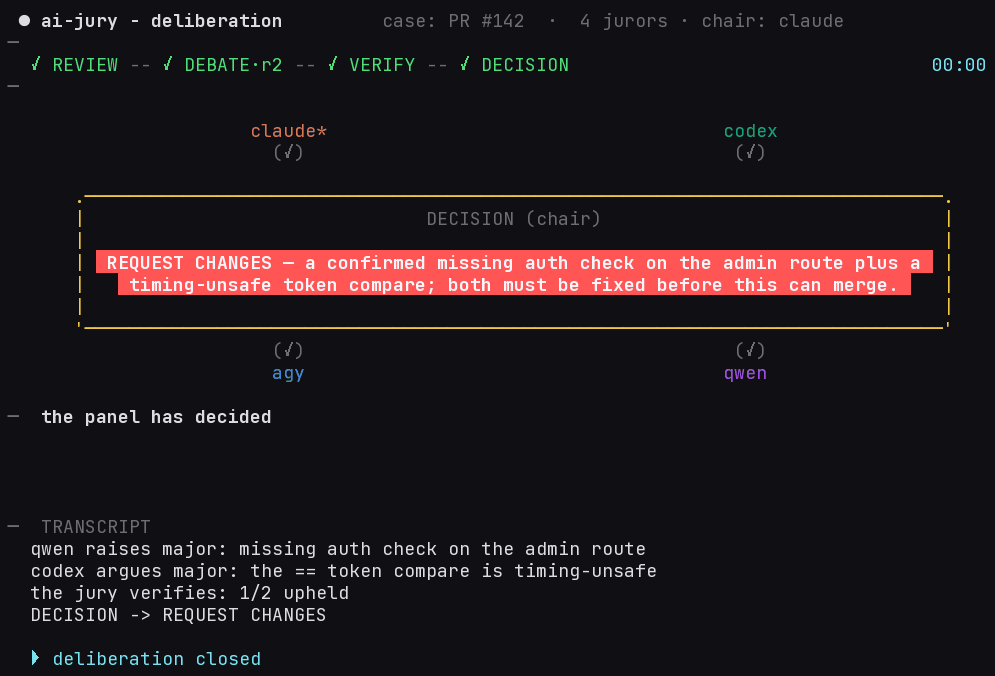
It is presentation-only — it reads the same per-phase on_event stream the
report does, so it mirrors the real run (jury --mock --theater gives a
deterministic, offline demo). It adapts to PR vs issue and chair vs vote, shows
debate rounds / early-stop / disputes, seats many jurors (with a compact roster
fallback), and degrades to the plain --live step stream on a non-interactive
terminal (or, for pixel, to the flat scene without truecolor/unicode).
Details: docs/theater-design.md.
Watch runs inside Claude Code — jury-progress
The optional jury-progress mod shows every live jury run above
the Claude Code prompt (target, phase, each seat's ✓/…/✗) and in a /jury-progress pane, from the
metadata-only events jury writes. It leaves a .watched marker in jury's cache, so every jury on the
machine writes its events there with no flag or variable (or set $JURY_EVENTS_DIR yourself). Install
it with claude plugin install jury-progress@ai-jury; the CLI and the other hosts are unaffected.
Replay a saved run — jury replay
Re-watch a finished run without re-spending a single token. The file to replay is
the result-cache entry a --cache run stores:
jury --pr 123 --cache                          # stores ~/.cache/ai-jury/<key>.json
jury replay ~/.cache/ai-jury/<key>.json --theater   # replay in the deliberation theater
jury replay ~/.cache/ai-jury/<key>.json --theater --theater-style pixel
jury replay ~/.cache/ai-jury/<key>.json --decision vote --mode issue   # re-tally the panel-vote finale
replay loads a serialized outcome — a result-cache entry (via its outcome key) or a
bare outcome_to_dict dump, which the CLI itself never writes — and re-drives the theater with the exact per-phase event
sequence the live run emitted (review → debate → verify → synthesis, then the vote/chair
finale). No orchestration, no network, no agents. Off a tty (or without --theater) it
degrades to the plain --live step stream. The serialized outcome does not record the run
mode, so --mode code|issue selects the vote vocabulary when you replay with
--decision vote. A report cannot be replayed: -o run.json writes the report in the
--format chosen (markdown by default, so replay answers not valid JSON), and a
jury --format json report does not carry the per-agent deliberation stream, so it is
rejected with a pointed message. --cache-dir (or $JURY_CACHE_DIR) moves the cache
entries.
Output formats
Use --format {markdown,json,sarif,keel-reviews} (default markdown) to control
what is written to stdout or --output. --metadata-json is independent and always
writes the metadata block to its own file, and the --ci exit code is computed
the same way regardless of format.
jury --diff-file changes.diff --format json         -o report.json
jury --diff-file changes.diff --format sarif        -o report.sarif
jury --diff-file changes.diff --format keel-reviews -o reviews.json
JSON
A structured report with these top-level keys:
| Key | Description |
|---|---|
schema_version |
Version of this JSON schema (currently 1.5). |
metadata |
Run metadata (agents, rounds, context mode, redaction stats, wall-clock proxy). |
classification |
The deterministic PR-level classification: review_effort, risk_level, security_sensitive, needs_human_attention (what --label applies). |
findings |
All raw findings; each carries severity, file, line, claim, evidence, suggested_fix, confidence, reviewer. |
consensus |
Per consensus group: representative finding, agreement count, reviewers, bucket, verification_status. |
reviewers |
One ballot per seat that ran — who said what, what they read (scope), what they ran (testing), whether it counts as a review (counts_as_review), with vendor/model provenance — plus the chair. See the report-format contract. |
verdicts |
Verification verdicts (file, line, claim, status, reasoning). |
verdict |
The chair synthesis text, if any. |
The output is deterministic for a deterministic run (e.g. --mock) and contains
only legitimate finding fields — never raw diff or prompt text.
This JSON drives the "Load a real run" panel on the
website: drag it on to play the real reviewers, findings,
and verdict through the in-browser theater (fully client-side — nothing is uploaded).
For the terminal jury replay (above), replay the result-cache entry a --cache run
stores instead — the --format json report omits the per-agent deliberation stream, so
jury replay rejects it, as noted above.
keel-reviews
A JSON array of per-reviewer review records — one per seat that ran, plus the
chair as reviewer: "chair" — in the shape a consumer of head-pinned per-reviewer
verdicts accepts (keel's keel review --reviews <file>). The chairing agent
sits on the panel: it reviews in round 1 like anyone else, so a three-agent
bench yields three ballots — the chairing agent's among them — and a fourth
record, the chair's synthesis. Each record says which agent chaired and what
became of its ballot, so a chair that reviewed is not indistinguishable from one
that only synthesised. --min-reviews N requires a review count: the ceiling is
checked before the panel runs, the number actually supplied afterwards.
Every record names what it read, and the name has to exist: scope carries
the reviewer's own Checked: line — resolved against the change, so only tokens
naming a path or a symbol actually in the diff count — the files it attached to
its findings, or, under --issue, where a finding has no file to name, the claims
it raised; testing carries what it ran or says plainly that nothing was. A
reviewer whose reply names nothing checkable is recorded as an ABSTAIN whose
scope says why, never as an APPROVE with a placeholder — an agent that named
nothing did not review, and neither did one whose Checked: nothing merely had
the shape of naming something.
A ballot is not automatically a review. counts_as_review on each record is
the one definition (ai_jury.panel.is_review): a panelist entry, with a scope
naming something checkable, and a verdict that is not ABSTAIN. The chair's
synthesis, a seat that returned nothing, and a seat that answered without naming
anything are all in the bundle — the report has to be able to say which agent
produced what — and none of them is counted, because the consumer would refuse
it. --min-reviews counts the same thing the consumer does.
And a ballot that did not review says why. In a bundle record the reason is in
its scope text; the structured field is on the --format json report's reviewers[]
ballots, not in this bundle: abstention_cause carries one of
five — silent, named_nothing, not_in_change, refused, adapter_failed —
and every count of the seats that supplied no review is that field tallied, in the
report line, the --min-reviews failure and --metadata-json's panel block
alike. A seat that named a file and then refused is reported as a refusal, not
as one that named nothing; a seat that named src/made/up.py is reported as
having named something this change does not contain, which is a different failure
again.
[
  {
    "reviewer": "claude",
    "verdict": "REQUEST_CHANGES",
    "scope": "Checked, as stated by the reviewer: `src/example.py`. Named 1 file(s): `src/example.py`.",
    "findings": [
      {"severity": "major", "path": "src/example.py", "line": 42, "message": "..."}
    ],
    "testing": "Tested, as stated by the reviewer: python -m pytest tests/test_example.py — 12 passed",
    "vendor": "anthropic",
    "model": "claude-opus-5-5",
    "model_source": "requested",
    "counts_as_review": true
  }
]
See the report-format contract for how each field is derived.
SARIF
Valid SARIF 2.1.0
suitable for GitHub code scanning. Results are drawn from consensus group
representatives (falling back to raw findings). Each result maps to a
physicalLocation (artifactLocation.uri = file, region.startLine = line when
known), message.text = the claim, and a stable ruleId of jury/<severity>.
Severity maps to the SARIF level as:
| Severity | SARIF level |
|---|---|
critical, major |
error |
minor |
warning |
nit, info |
note |
Upload to GitHub code scanning:
The standard way is the github/codeql-action/upload-sarif GitHub Action.
Results then show up in the PR's Code scanning view and the repo's
Security tab. The job needs security-events: write (to upload) and
contents: read:
name: Jury code scanning

on:
  pull_request:

permissions:
  contents: read
  security-events: write   # required by upload-sarif

jobs:
  jury:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@3d3c42e5aac5ba805825da76410c181273ba90b1  # v7.0.1
        with:
          fetch-depth: 0   # need the base commit to diff against

      - uses: actions/setup-python@5fda3b95a4ea91299a34e894583c3862153e4b97  # v7.0.0
        with:
          python-version: "3.13"

      - name: Install jury
        run: pip install ai-jury   # or: pip install .

      - name: Produce SARIF from the PR diff
        env:   # the hosted-API seats of the jury.toml above read these
          ANTHROPIC_API_KEY: ${{ secrets.ANTHROPIC_API_KEY }}
          OPENAI_API_KEY: ${{ secrets.OPENAI_API_KEY }}
        run: |
          git diff "origin/${{ github.base_ref }}...HEAD" > pr.diff
          jury --diff-file pr.diff --format sarif -o jury.sarif

      - name: Upload to code scanning
        uses: github/codeql-action/upload-sarif@7211b7c8077ea37d8641b6271f6a365a22a5fbfa # v4.36.0
        with:
          sarif_file: jury.sarif
This uses a diff file, so no gh token is required to generate the SARIF. It still
needs reviewers: a runner has no agent CLIs, so without a jury.toml the step exits
2 with error: no usable agents. Commit the hosted-API jury.toml shown with the
GitHub Action example and pass its keys as above. To review the PR via
--pr instead (which shells out to gh), set GH_TOKEN: ${{ github.token }} on that
step.
As a manual alternative, upload an existing SARIF file with gh:
gh api -X POST repos/OWNER/REPO/code-scanning/sarifs \
  -f commit_sha="$SHA" -f ref="$REF" \
  -f sarif="$(gzip -c report.sarif | base64 -w0)"
Configuration — jury.toml
Don't hand-write it the first time — scaffold one with jury init, which
detects your installed agents and writes a valid config:
jury init                              # interactive: pick agents, rounds, chair
jury init --wizard                     # guided: numbered questions for the most-used settings (skippable)
jury init --preset balanced            # one-command preset: offline | fast | balanced | thorough
jury init --list-agents                # show known agents + availability
jury init --list-models                # list local (Ollama) models you can pick
jury init --agents claude,codex,qwen --rounds 2   # non-interactive / scriptable
It detects which agent CLIs are installed and, for a local agent, discovers the
models on your Ollama/OpenAI-compatible server so you can pick one in the
interactive prompt (e.g. gemma:2b, deepseek-coder:6.7b). It uses the
secure-by-default agent templates and refuses to overwrite an existing file
without --force. jury init --agents claude,codex writes exactly this:
# Generated by `jury init`. Edit freely — see docs/configuration.md
# for the full schema (rounds, ci gate, context policy, diff handling).

[jury]
rounds = 2
chair = "claude"
verify = true

[jury.ci]
# Distinct vendors that must have contributed a review before the run can
# stand as cross-vendor consensus (exit 3 otherwise). Defaults to 2 and only
# applies when 2+ vendors are enabled HERE — including when one of their CLIs
# is not installed; set 0 (or pass --no-min-vendors) to accept a panel that
# collapsed to one vendor, or --strict to fail at startup on a missing CLI.
# min_vendors = 2

[[agent]]
name = "claude"
vendor = "anthropic"
command = "claude"
extra_args = ["--output-format", "text", "--tools", "", "--disallowed-tools", "Edit,Write,NotebookEdit,Bash,Read,Grep,Glob,WebFetch,WebSearch,Task,Agent", "--strict-mcp-config", "--safe-mode", "--no-session-persistence", "--permission-mode", "dontAsk"]

[[agent]]
name = "codex"
vendor = "openai"
command = "codex"
extra_args = ["-s", "read-only"]
The claude seat gets no tools (no file reads, shell, network or MCP servers), loads
no CLAUDE.md, hooks, skills or plugins, and keeps no transcript of the diff; the
codex seat runs in codex's read-only sandbox. A key the file leaves out keeps its
default: timeout = 600 per-agent wall-clock seconds (a hung CLI is killed at this
bound) and parallel = true, among others. vendor takes any of the
vendors the parameter reference lists. A seat with no model runs its CLI's own
default model; pin one by adding it to the seat:
[[agent]]
name = "claude"
vendor = "anthropic"
command = "claude"
model = "claude-opus-5-5"
extra_args = ["--output-format", "text", "--tools", "", "--disallowed-tools", "Edit,Write,NotebookEdit,Bash,Read,Grep,Glob,WebFetch,WebSearch,Task,Agent", "--strict-mcp-config", "--safe-mode", "--no-session-persistence", "--permission-mode", "dontAsk"]
Override per run with --rounds, --chair, --config.
Fail-soft is not a multi-vendor guarantee. A missing or failing agent is skipped and the run continues — which is right for one reviewer having a bad day, and wrong as a silent default, because a panel that collapsed to one vendor produces a report shaped exactly like a healthy one. Two guards keep them apart: an agent that exits 0 with a refusal or its own usage banner is recorded as a typed failure rather than a review, and a run that claimed cross-vendor consensus and did not form one exits 3 (
--min-vendors, default2). The claim is what your config NAMES, so ajury.tomlnaming three vendors fails on a machine carrying one installed CLI — a missing CLI is not an exemption. Opt out with--no-min-vendors([jury.ci] min_vendors = 0), or use--strictto catch the missing CLI at startup instead.jury --doctorreports reachable vendors, but never contribution — only a run can prove that. See docs/parameters.md.
The config is validated on every run. Check it without running a review with jury --config-validate (exit 0 valid, 2 invalid); add --strict-config to turn warnings into errors. See the parameter reference for every field, allowed value, and default (CLI flags + jury.toml), and docs/configuration.md for the validation behaviour (hard errors vs. warnings) and other config semantics.
Local / open-weight reviewer (free, offline)
A panelist can run on a local open-weight model via any OpenAI-compatible
server (Ollama, llama.cpp llama-server, vLLM, LM
Studio). Use vendor = "local" with an endpoint and a model — it talks plain
HTTP (stdlib only, no extra deps) and participates in every round and the
consensus exactly like a CLI agent:
[[agent]]
name = "qwen"
vendor = "local"
model = "qwen2.5-coder:7b"
endpoint = "http://localhost:11434/v1"   # default; Ollama's OpenAI-compatible API
# One-time: install Ollama and pull a coding model.
ollama pull qwen2.5-coder:7b
# Review with zero cloud cost, fully offline:
jury --diff-file changes.diff --config local-only.toml
Trade-off (be honest): a small local model is a weaker reviewer than a
frontier CLI — its value is added diversity (the load-bearing advantage for a
jury) and zero marginal cost, not parity. The sweet spot is mixing one
local panelist with one or two cloud CLIs: more vendor heterogeneity, lower spend.
An unreachable server fails fast with a typed connection_error (the run
continues with the other agents). See the
benchmark note for the
measured diversity contribution.
A local seat decodes greedily (temperature = 0) by default. Some reasoning
models loop at 0 and never answer; gpt-oss is one of them. Give such a seat
temperature = 1.0, which is what OpenAI recommends for gpt-oss. See
sampling temperature.
What a run costs
ai-jury itself is free (MIT) and has no server. A run costs the model calls its seats make, and each call is billed by whoever serves that seat:
| Seat | vendor |
Who bills the call |
|---|---|---|
| Hosted API | anthropic-api, openai-api, google-api, xai-api, openai-compatible (OpenRouter, DeepSeek, Groq, …) |
The provider, at its API prices, on the key you give it |
| Agent CLI | anthropic (claude), openai (codex), google (agy), and cli or xai for a CLI you bring (Aider, Cursor, …) |
The account the CLI is logged in with: its plan or its API billing |
| Local model | local |
Nobody: it runs on your hardware |
jury --mock makes no model calls.
Calls per run. With the defaults (rounds = 2, verify = true), a run with N
seats makes these calls for each diff, or for each chunk when --chunk splits one:
- N round-1 reviews;
- one debate reply per review that came back, when at least two did;
- one verification call and one synthesis call, both by the chair.
When every review comes back, that is 2N + 2 calls. For a CLI seat a "call" is one run of its CLI, which may make several model requests inside the vendor's tool. These change the count:
--rounds 1skips the debate, and--no-verifyskips the verification call.--early-stopskips the debate when the round-1 reviews agree, and otherwise runs up to--max-rounds− 1 debate rounds, each with the same debaters.--autosets the rounds and verification from the diff's risk: alow-risk diff gets one round and no verification.--tieredseats fewer frontier seats in round 1 on alowormedium-risk diff: the economical seats plus one frontier anchor. Acriticalormajorfinding brings the benched seats into the debate.--retries Krepeats a call that failed transiently, up to K more times.--cachereuses the stored result for an unchanged diff and config, with no calls.--total-timeoutcaps the run: once it is spent, the debate, verification and synthesis that have not started are skipped.
Repository review policy (optional)
A repository under review may ship an optional, separate review policy that
tells the jury what to care about for that project (high-risk paths, focus
areas, forbidden output, severity overrides, a checklist, and doc links). This is
distinct from the runtime jury.toml: it configures what reviewers should
care about, not how the agent runs.
It is auto-discovered from .jury/policy.toml or jury-policy.toml, or
pointed at explicitly:
jury --mock --diff-file examples/sample.diff --policy .jury/policy.toml
The policy is maintainer-authored, so it is injected into the review prompts as a
clearly separated, trusted section (distinct from the untrusted diff/context
fences). Missing policy files are allowed (no-op); a malformed one is a clear
error. See examples/policy.toml for a generic example
and the architecture docs for the
schema.
Data flow / privacy
What gets sent to each agent is governed by [jury.context] in
jury.toml (and overridable per run on the CLI):
[jury.context]
mode = "diff-only"      # "diff-only" (default) or "expanded"
redact_secrets = true   # scrub recognized secrets before sending (default on)
Context modes — what leaves your machine for each reviewer:
diff-only(default): agents receive only the diff. Any surrounding PR context (title/body) is dropped. This is the smallest data surface.expanded: agents additionally receive the PR title/body context (when reviewing with--pr) to improve review quality. Use this only when you trust the configured agent endpoints.
Either way, the jury itself reads and sends no source files outside the diff, no
repository history, and no environment variables. What an agent CLI can reach on
its own, once started, depends on the seat: the shipped claude seat has no tools
at all, the shipped codex seat can read any file your user can read by absolute
path but not write or reach the network from its shell (and it loads the MCP
servers in your ~/.codex/config.toml), an agy seat — opt-in only, never in
the default panel — can read and write files and reach the network, and a
bring-your-own cli seat has whatever its own flags give it — see
Security & the Codex sandbox.
There is no ai-jury server; your diff goes only to the model endpoints you configure — vendor CLIs and APIs, or your own model server for local seats.
Secret redaction — before anything is sent to an agent, the diff (and any
context) is passed through a redactor (src/ai_jury/redaction.py)
that masks recognized secrets, including PEM private keys, AWS access keys, GitHub/OpenAI
tokens, Bearer tokens, and generic api_key/secret/token assignments
(including base64-style values); the full list of shapes is _PATTERNS in that module. Each hit becomes [REDACTED:<kind>]. Redaction
is on by default.
Controls:
jury.toml:[jury.context] mode = "diff-only"|"expanded"andredact_secrets = true|false.- CLI (override config for a single run):
--context-mode diff-only|expanded, and--redact/--no-redact.
Posting to GitHub (--post-summary, --post-inline) sends the rendered report
/ comments to the GitHub API; use --dry-run with --post-inline to preview the
inline payload without any network call. See SECURITY.md for the
full data-flow and redaction reference.
No telemetry (by default and always) — this project collects and sends no telemetry and no analytics, not now and not behind any opt-in flag. The tool never phones home. Network traffic goes to:
- the agent CLIs you configure, each of which talks to its own vendor;
- the hosted-API endpoints you configure (Anthropic, OpenAI, Google, xAI, or any OpenAI-compatible URL), which the jury calls itself with the prompt, diff included;
- the local model endpoints you configure, which the jury calls itself the same way;
gh, for--prand--issue(fetching, posting, labelling);- with the opt-in
--hints, the linters it runs in the working directory:ruff, andnpx eslintwhen apackage.jsonis present —npxmay downloadeslintfrom the npm registry when the project does not have it installed; - and the default local model server on loopback (
http://localhost:11434/v1), to offer a free offline reviewer: everyjury initchecks whether it is reachable (a status-only request), exceptjury init --list-models, which lists its models instead;--list-agentsand seating a local reviewer list them after that check;jury --doctorlists them when no reviewer is available, and so does a run with nojury.toml, no--config, not--mock, and no usable agent CLI.jury init --local-endpoint URLasksURL/modelsfor those listings instead (--list-models,--list-agents, and seating a local reviewer: interactive,--wizard,--agents qwen,--preset offline); a URL that is not loopback is asked only withJURY_ALLOW_REMOTE_ENDPOINT=1set.
Diagnostics — jury --doctor
Run a local readiness check that surfaces common configuration problems:
jury --doctor                          # print a readable report
jury --doctor --json                   # per-agent readiness as one JSON document (ai-jury.doctor.v1)
jury --doctor --write diagnostics.json # also write the full diagnostics as JSON
The report covers the tool version, Python version, OS, a config summary
(rounds, chair, context mode, enabled agents), which agent CLIs are available on
your PATH, and any detected config warnings. The output is safe to share:
secret-like config values are redacted via the same redactor used for prompts,
and the report never includes the diff under review or any agent output.
Diagnostics are built locally and only written to disk when you pass
--write PATH.
--doctor --json prints one JSON document on stdout and nothing else, for
wizards and orchestrators. It is not the --write file: --write saves the readable
report's diagnostics (config summary, warnings, recommendations), while --json is a
provider export — per agent: transport
(cli / api / local), availability and the reason when unavailable, the
command or endpoint, resolved binary, version, capabilities, discovered models,
and effort support. The schema is ai-jury.doctor.v1, documented in
docs/configuration.md:
jury --doctor --json | jq '.agents[] | select(.available) | .name'
Use it from another project (skill)
A Claude Code skill ships in skills/ai-jury/.
Install it as a plugin from this repo (it doubles as a single-plugin marketplace):
/plugin marketplace add berkayturanci/ai-jury
/plugin install ai-jury@ai-jury
That is Claude Code's short form; docs/install.md has the
CLI commands, the other three agents, and the update path — which is not a
re-install, since plugin install is a no-op on an installed plugin.
Or drop skills/ai-jury/ into a project's
.claude/skills/ manually. Either way the agent can convene the jury on demand, and
it composes with existing review workflows: run the jury for a cross-vendor pass,
then act on the consensus findings. For support status per platform, see the
platform support matrix.
For a concrete consumer: keel can run
ai-jury as a review gate. A project turns it on by adding jury to its gates:
list, or by naming jury as a tier's reviewers under knobs.team.review.
keel ship also enables the jury for a change in the project's tier-3 risk class
(paths matching its tier3_globs) unless the run passes --no-jury. The jury
gate is fail-soft — a no-op when ai-jury isn't installed. A tier whose reviewers
are the jury is different: keel checks first that the panel can sit, and when it
cannot (no jury binary counts) it seats host reviewers by default, or refuses the
run if the project set knobs.team.jury.on_unavailable: block. keel's optional
keel-visual run
visualizer surfaces the jury on the review step when a run used it.
How it works
| Module | Responsibility |
|---|---|
config.py |
Load jury.toml (or built-in default) |
adapters.py |
One adapter per vendor: a headless subprocess for an agent CLI, an HTTP call for a hosted-API or local seat |
orchestrator.py |
Round structure: review → debate → verify → synthesis (agents run in parallel) |
prompts.py |
The prompt templates: review, debate, verify and synthesis, each for a code review and for an issue review |
report.py |
Render the run as one markdown report |
github.py |
gh-based PR diff in / comment out |
Report format contract
The markdown report is the tool's user-facing output and a contract for
downstream skill/workflow consumers, so it changes only deliberately.
tests/test_report_golden.py renders the report for several scenarios (full
jury run, single-round, verified-finding, failed-agent, missing-agent) and
compares each against a committed snapshot in tests/golden/*.md. Unintended
formatting drift fails CI; an intentional change shows up as a reviewable
fixture diff. Durations (the only non-deterministic token) are normalized to
0s before comparison. Regenerate fixtures after an intentional change with
UPDATE_GOLDEN=1 PYTHONPATH=src python3 -m unittest tests.test_report_golden.
See docs/report-format.md for details.
Prior art & how this differs
This is a known pattern, not a new invention. The closest project is
Magpie (multi-vendor CLI review + debate, with a
benchmark
showing debate lifts bug detection to ~80%); see also
agent-council,
the-council, and Mozilla.ai's
Star Chamber.
The jury/courtroom metaphor shows up in research too — e.g.
VulTrial (ICSE 2026), which casts
prosecutor / defense / judge / jury LLM agents at vulnerability detection.
ai-jury aims to be the smallest drop-in version: stdlib-only Python, a
single jury.toml, and a Claude Code skill that snaps into an existing repo's review
workflow. See the ecosystem comparison & capability matrix for how
it differs from hosted, API-level, and other native-CLI tools, and
docs/feasibility.md for the supporting research.
Status
Active (v1.24.0). The full pipeline runs end-to-end with the real CLIs and the offline
--mock path is covered by tests. Shipped: structured findings + tiered consensus
(consensus / majority / single-reviewer), a verification pass that drops false positives,
universal agent provider support (cloud CLIs, hosted APIs, arbitrary coding-agent CLIs, local models),
chair verdict or panel vote (--decision vote), PR / diff / issue / commit review
(--pr, --diff-file, --issue, --commit, --commits), abstention accounting in the panel,
live play-by-play (--live) and full-transcript / verbose output, animated deliberation theater
(--theater, --theater-style pixel), anonymized debate, adaptive early-stop,
severity-gated CI exit codes, secure-by-default sandboxing, run budget/retries, large-diff
filtering + semantic chunking, an optional result cache, incremental review, interactive patch applier (jury apply),
static analysis hint injection (--hints), frugal model tiering (--tiered),
official GitHub Action and pre-commit hooks,
comment-command triggering, a local / open-weight adapter (free, offline), and
jury init scaffolding (with an opt-in --wizard). See
docs/architecture.md and the
milestones.
The phased plan and how to pick up a session's worth of work is in ROADMAP.md;
issues are tracked under milestones.
Security & the Codex sandbox
The panel performs read-only review orchestration — it sends a diff to each seat and collects their feedback; it applies no edits. Writing is left to separate commands you run: jury apply on a patch you pick, and jury run-agent's implement/fix roles with --allow-write.
The Codex adapter pipes the prompt on stdin (codex exec with no positional prompt) so non-interactive runs never hang waiting for input, and defaults extra_args to ["-s", "read-only"] — a secure-by-default sandbox. The diff is fetched by the jury (gh), not by codex, so the reviewer only needs to read its prompt and print findings; a prompt injection in the diff can't make it write files, and its shell has no network. The read-only sandbox does not stop it reading any file your user can read, by absolute path, and the MCP servers enabled in your own ~/.codex/config.toml still load (they run outside its sandbox).
What each seat can reach while it reads an attacker-controlled diff. The default panel — what runs with no jury.toml — is claude + codex; agy is opt-in only:
| Seat | Shipped flags | Writes / shell | Reads files outside the diff | Network |
|---|---|---|---|---|
claude |
--tools "", a deny list naming every write, shell, read, network and subagent tool, --strict-mcp-config, --safe-mode (no CLAUDE.md, hooks, skills or plugins), --no-session-persistence, --permission-mode dontAsk |
no | no — and with --safe-mode not even your own ~/.claude/CLAUDE.md is loaded into its context |
no |
codex |
-s read-only (the adapter adds --skip-git-repo-check --ephemeral) |
no writes; read-only shell | yes, by absolute path | not from its shell; user MCP servers from ~/.codex/config.toml still load |
agy (opt-in) |
--sandbox --dangerously-skip-permissions |
yes — --sandbox did not stop it writing files |
yes | yes |
cli / xai |
yours | whatever your flags give it | whatever your flags give it | whatever your flags give it |
Each row was measured with the shipped flags against Claude Code 2.1.236, codex-cli 0.155.0 and agy 1.2.9. agy is not in the default panel because it cannot be confined for untrusted diffs: agy has no flag that removes its tools, and --sandbox did not stop it. Seat it only by name (jury init --agents agy, or an [[agent]] in jury.toml) and only for diffs you trust; every run with an agy seat prints a least-privilege warning, and --strict fails on it. claude, codex and agy start every read-only call — each panel call, and jury run-agent's review/gate/chair roles — in a fresh, empty temporary directory rather than the repository under review, so the instruction files, project settings (a .claude/settings.json hook ran from one before) and .env a checkout carries are not picked up; a bring-your-own seat runs where jury was started, with whatever permissions its own flags give it. Details in docs/security.md.
Need codex to write or reach the network for your flow? Widen extra_args for the codex agent in jury.toml (e.g. -s workspace-write). See docs/security.md for details.
CLI compatibility contract
The jury command is this project's public API. The surfaces below are
stable and are locked by tests/test_cli_contract.py (including a
width/color-pinned snapshot of jury --help under tests/golden/) so
accidental changes are caught in review.
Stable flags (names, short aliases, and semantics), grouped by intent:
- Input:
--pr,--issue,--repo,--diff-file,--commit,--commits - Depth:
--rounds,--max-rounds,--early-stop/--no-early-stop,--auto/--no-auto,--verify/--no-verify,--effort {low,medium,high},--tiered - Budget / reliability:
--total-timeout,--phase-timeout,--retries - Large diffs:
--max-diff-bytes,--chunk/--no-chunk,--exclude,--include - Context & privacy:
--context-mode {diff-only,expanded},--redact/--no-redact,--hints/--no-hints - Config / policy:
--config,--policy,--chair,--seed,--mock,--strict,--config-validate,--strict-config - Output:
-o/--output,--write,--metadata-json,--events-file,--format {markdown,json,sarif,keel-reviews},--decision {chair,vote},--transcript/--no-transcript,--verbose,--live,--theater/--no-theater,--theater-style {flat,pixel},-q/--quiet - GitHub posting:
--post-summary/--post,--post-inline,--post-progress,--post-mode {single,phased},--dry-run,--label,--no-attribution - CI gating:
--ci,--fail-on,--min-vendors,--no-min-vendors,--min-reviews - Cache & incremental:
--cache,--clear-cache,--cache-dir,--incremental - Patches:
--suggest-patches,--patches-out - Misc:
--doctor,--json(with--doctor),--version,-h/--help
A version-independent test (test_readme_stable_flags_match_the_parser) reads
this list out of the README and compares it with the long options of the real
argparse parser, in both directions, so a new flag can't be added without being
listed here and a listed flag can't silently disappear. A second test holds the
flag tables of docs/parameters.md to the same parser.
Stable error messages and exit codes:
| Condition | Behavior |
|---|---|
| No input source given | exits non-zero with error: provide one of --pr, --issue, --diff-file, --commit, --commits (or --diff-file - for stdin) |
| More than one input source | exits non-zero with error: choose one input source, got …, naming each one given |
| Empty diff | exits non-zero with error: empty diff — nothing to review |
--post-summary with no postable target (e.g. --diff-file; it works with --pr or --issue) |
exits non-zero with error: --post-summary requires --pr, before any reviewer runs |
--post-inline without --pr (PR-only; also --post-progress, --label, --incremental) |
exits non-zero with error: --post-inline requires --pr, before any reviewer runs; with --issue instead, error: --post-inline is not supported with --issue (it is a PR/diff concept) |
A config that exists but cannot be read (--config names a directory, or ./jury.toml is unreadable) |
exits 2 with error: cannot read config <path>: <reason> |
jury init --wizard with no terminal on stdin (CI, a pipe) |
exits 2 with error: the wizard needs a terminal; use `jury init --preset <name>` |
jury init --interactive with no terminal on stdin (CI, a pipe, no stdin at all), and no --agents or --preset |
exits 2 with error: --interactive needs a terminal; use `jury init --preset <name>` or `jury init --agents <list>` |
| Unknown flag / bad arguments | argparse exits with code 2 |
No configured seat can run (no agent CLI on PATH, no reachable local model, no hosted-API key) |
exits 2 with error: no usable agents — …, before any review |
--strict and a configured agent CLI is missing, or a seat draws a least-privilege warning (an agy or bring-your-own cli seat) |
exits 2 with error: agent '<name>' CLI not available: <command> or error: least-privilege check failed (--strict): …, before any review |
--version |
prints jury <version> and exits 0 |
Successful review (no --ci) |
exits 0 |
--ci with blocking findings remaining |
exits 1 (see ci.evaluate_ci) |
Fewer than min_vendors distinct vendors contributed a review |
exits 3 — the cross-vendor guard, not a findings failure. Checked on every run, with or without --ci, and it outranks the --ci severity gate. Default 2 ([jury.ci] min_vendors); the default is scoped to runs that claimed cross-vendor consensus, so a config with fewer distinct vendors enabled than the threshold is never failed by it — nor is the zero-config offline run (no jury.toml, no agent CLI, a local model server), whose panel is its one local seat. An explicit --min-vendors N is enforced as asked. Opt out with --no-min-vendors (or min_vendors = 0); to fail at startup on a missing CLI instead, use --strict. |
| Every seat that ran failed to return a result — a CLI that crashed or timed out, an API error, a local model that is not pulled | exits 3 — nothing was reviewed, so the run is not a pass and not a findings failure. Checked on every run and it outranks the --ci severity gate; --no-min-vendors does not waive it. A seat that answered in prose with no findings is an abstention, not a failure, so a clean single-seat run still exits 0. jury --doctor names the usual cause (#849). |
Fewer reviews than min_reviews — a review is a panel ballot that named what it read and voted; neither the chair's synthesis record nor an abstaining ballot is one |
exits 3 — the panel-size guard, not a findings failure, and it outranks the --ci severity gate. Off by default ([jury.ci] min_reviews = 0, --min-reviews N). When the available bench cannot reach even the ceiling, the run refuses before the panel runs and exits 2 with error: panel too small before the panel runs: …. |
Stable report headings (substrings other tooling may parse):
AI Jury, Chair verdict, Round 1 (and subsequent Round N).
Policy: Any breaking change to the surfaces above — renaming or removing a
flag, changing an error message or exit code, or altering a report heading —
requires a CHANGELOG.md entry describing the break. When the change is
intentional, regenerate the help snapshot with
UPDATE_GOLDEN=1 PYTHONPATH=src python3 -m unittest tests.test_cli_contract.
The help-snapshot exact match is pinned to Python 3.13 argparse formatting; the
flag-presence checks run on all supported versions (3.11–3.14).
Uninstall
Remove the CLI the way you installed it:
brew uninstall ai-jury && brew untap berkayturanci/ai-jury   # Homebrew
pipx uninstall ai-jury                                       # pipx
uv tool uninstall ai-jury                                    # uv
pip uninstall ai-jury                                        # pip
The curl | sh installer uses the first of Homebrew, pipx and uv it finds, so one
of those lines undoes it. When it finds none, it creates a virtual environment and
a link to it. Remove both (these are the default paths; AI_JURY_HOME and
AI_JURY_BIN_DIR move them):
rm -rf ~/.local/share/ai-jury
rm ~/.local/bin/jury
The GitHub Action installs ai-jury on the runner for each job, and a
GitHub-hosted runner is discarded after the job. Delete the
uses: berkayturanci/ai-jury@… step, and the API-key secrets you added for it if
nothing else uses them.
An agent plugin is removed by its agent. These commands come from the --help
of Claude Code 2.1.236, codex-cli 0.155.0 and agy 1.2.12:
claude plugin uninstall ai-jury@ai-jury && claude plugin marketplace remove ai-jury
codex plugin remove ai-jury@ai-jury && codex plugin marketplace remove ai-jury
agy plugin uninstall ai-jury
rm -rf ~/.cursor/plugins/local/ai-jury   # Cursor's local checkout
The second command on each of the first two lines removes the marketplace the install added.
Files left behind. Uninstalling does not remove the two directories the tool writes to. Delete them if you want them gone:
~/.config/ai-jury/($XDG_CONFIG_HOME/ai-jury/when that is set), which holdstrusted-configs: the discoveredjury.tomlfiles you allowed to run commands.~/.cache/ai-jury/($XDG_CACHE_HOME/ai-jury/, or$JURY_CACHE_DIR), which holds the--cacheresults and the state ofjury run-agentruns.
Development
Working on ai-jury itself. None of this is needed to use it.
Install the dev extras (linting, build, and coverage tooling):
pip install -e ".[dev]" # or: make install
That resolves ruff, build and coverage fresh. To get the exact versions CI
uses — the ones pinned in the tracked uv.lock, with hashes — install from the
lock instead. It is also the ruff the ruff-format pre-commit hook runs:
uv sync --locked --extra dev
Coverage
Test coverage is measured with coverage.py
— a dev-only dependency. The runtime stays standard-library-only.
Measure it locally with one command:
make coverage          # run the suite under coverage, print the report, write htmlcov/
# or, without make:
./scripts/coverage.sh
Either entry point runs:
python3 -m coverage run -m unittest discover -s tests
python3 -m coverage report
Threshold. The enforced minimum total coverage is 98% — one number,
fail_under in pyproject.toml under [tool.coverage.report], enforced by a
dedicated coverage job in CI (.github/workflows/ci.yml, Ubuntu / Python
3.13). CI fails if total coverage drops below that floor. The gate runs in a
single job rather than across the whole test matrix to keep CI cheap and free of
cross-OS path noise. tests/test_docs_coverage_gate.py asserts the percentage in
this paragraph is still the one pyproject.toml sets, because the two were out
of step for several releases.
The floor is not the measurement. The gate is deliberately set below what the
suite actually reaches, so that an unrelated refactor moving the total by a
fraction of a point is caught in review rather than by a red CI job, and it is
raised on purpose as coverage improves. For the current measured total see the
live coverage badge, rebuilt from main on every
push, or your own make coverage run. Neither this paragraph nor pyproject.toml
records it, because a written figure goes stale.
Measurement method. Branch coverage is enabled (branch = true) and the
package is measured by import name (source = ["ai_jury"]).
Exclusions. Intentionally-untested paths are excluded so the number stays honest:
src/ai_jury/__main__.pyis omitted (a thinpython -mentry shim).- Lines matching these patterns are excluded from the count:
pragma: no cover,if __name__ == "__main__":,raise NotImplementedError,if TYPE_CHECKING:, and abstract-method decorators.
Add # pragma: no cover to any new line that is genuinely not worth testing.
Live smoke tests
The default test suite uses mock adapters only, so the real native CLIs
are never invoked — a breakage in argv format, stdin handling, or output
capture in the concrete adapters would go unnoticed until a live run. The
optional live smoke tests close that gap: they run a tiny, cheap review
prompt (a two-line diff) through each installed real adapter and assert the
run succeeds (ok, non-empty output, error_code is None).
They are opt-in and skipped entirely unless JURY_LIVE=1 is set, so
they never run in make test or in CI.
Requirements for a meaningful live run:
- The agent CLIs of the built-in panel must be installed and on your
PATH(claude,codex) and authenticated for non-interactive use.agyis opt-in and not in that panel, so these tests do not run it. - Any agent whose CLI is not installed is skipped individually, so a
machine with only
claudestill exercises that one adapter.
Run them:
make live-smoke
# equivalent to:
JURY_LIVE=1 PYTHONPATH=src python3 -m unittest discover -s tests -v
They are intentionally excluded from the CI matrix (no CLIs, auth, or secrets are available there) and are meant to be run locally before a release or when touching the adapter layer.
Review-quality benchmark
A small, directional benchmark (benchmark/) measures whether a jury's
findings line up with hand-authored expectations for a handful of fixture diffs
(obvious logic bug, subtle boolean-guard bug, missing error handling, a
false-positive trap, and a docs-only change).
It is not a universal quality claim. The default offline mode is deterministic and runs with no live CLIs: it scores each fixture's recorded sample findings against an expected spec, which validates the scorer and the recorded baselines — it does not measure live review quality. (
--mockis deliberately not used per fixture: the mock adapter emits a fixed finding regardless of the diff, so it would be fake signal.) Only the opt-in live mode (JURY_BENCH_LIVE=1) runs real agents and measures quality.
make benchmark                                          # offline, deterministic
JURY_BENCH_LIVE=1 PYTHONPATH=src python3 -m ai_jury.benchmark  # live (opt-in)
The lift, measured. A config-sweep (benchmark/sweep.py) runs the same
labeled fixtures with each model solo vs the panel vs the full jury —
isolating what the panel adds, without the result hinging on which single model
you'd pick. On one live four-vendor run (v1.1.0, 2026-06-05; 5 fixtures, 3 seeded
bugs, cloud models not pinned), the four-vendor panel caught 3/3 seeded bugs vs
2/3 for the best single model (Claude, Qwen; Codex and Agy 1/3), at lower
precision: 0.75, and 0.60 for the full jury, against 1.00 for every model run
alone. More reviewers found more bugs and raised more false alarms. Whether the
verification round wins the precision back is within noise at N=5 and not claimed.
The run predates the current release and has not been repeated on it. Full table
and method in docs/benchmark-results.md.
See benchmark/README.md for the fixture list, the
expected/recorded schema, and the match/scoring rules.
Documentation
- Parameter reference — every CLI flag and
jury.tomlkey with allowed values and defaults. - Configuration behaviour & validation — validation, budgets, adaptive rounds, large-diff handling, and the cache.
- Positioning — mission, what makes it different, principles, and non-goals.
- Cookbook — copy-paste recipes for local, PR, advisory-comment, CI, mock, and assistant workflows.
- Architecture — components, round structure, adapters, supported platforms.
- Ecosystem comparison — capability matrix vs hosted / API-level / native-CLI tools.
- Feasibility & prior art — research grounding and verified CLI invocations.
- Installing into an agent — per-agent plugin install and update, for Claude Code, Codex, Antigravity and Cursor.
- Platform support matrix — where you can install/run the jury and how.
- Skill packaging & install — install/version the review jury as a reusable skill artifact.
- Release readiness checklist — the bar before a public release.
- The Homebrew release chain — how a release reaches
brew install, every guard on the way, and what has already gone wrong. - Report format contract — the golden-file snapshot tests and how to regenerate them.
- SECURITY.md — data-flow and secret-redaction reference.
- Agent-readable:
llms.txt(concise) andllms-full.txt(full reference).
License
MIT — see LICENSE.
1 maintainer

Metadata
1 maintainer
Release files for ai-jury 1.24.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| ai_jury-1.24.0.tar.gz | 1.0 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| ai_jury-1.24.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.4 MB
Release files / ai_jury-1.24.0.tar.gz
| Download URL | ai_jury-1.24.0.tar.gz |
|---|---|
| Size | 1.0 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
d6c5ff965a7610614cb4a2fb10563c1937cf21aaeecbe41c9e94da30119b3d1e
|
|
BLAKE2b-256 checksum How to use checksums |
fa48fd16c4c63a2ae39882f5d68b2f9ce92785803d058b3ebbada40f6a94eeea
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 3, 2026.
Transparency logRelease files / ai_jury-1.24.0-py3-none-any.whl
| Download URL | ai_jury-1.24.0-py3-none-any.whl |
|---|---|
| Size | 375.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
f682a93d610dc44c49e399e8b6524935618cde7fc013fdec33c6918c24887279
|
|
BLAKE2b-256 checksum How to use checksums |
ecb94ed4ee05f5d9b4c90bdac55942f6b0df85e6ded1727fb57f5b9f459751cd
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 3, 2026.
Transparency log













