



Jiamu Zhang1 Tianze Yang1 Yucheng Shi2 Liang Wu1
1 Nokia, Sunnyvale, CA 2 Tencent Hunyuan
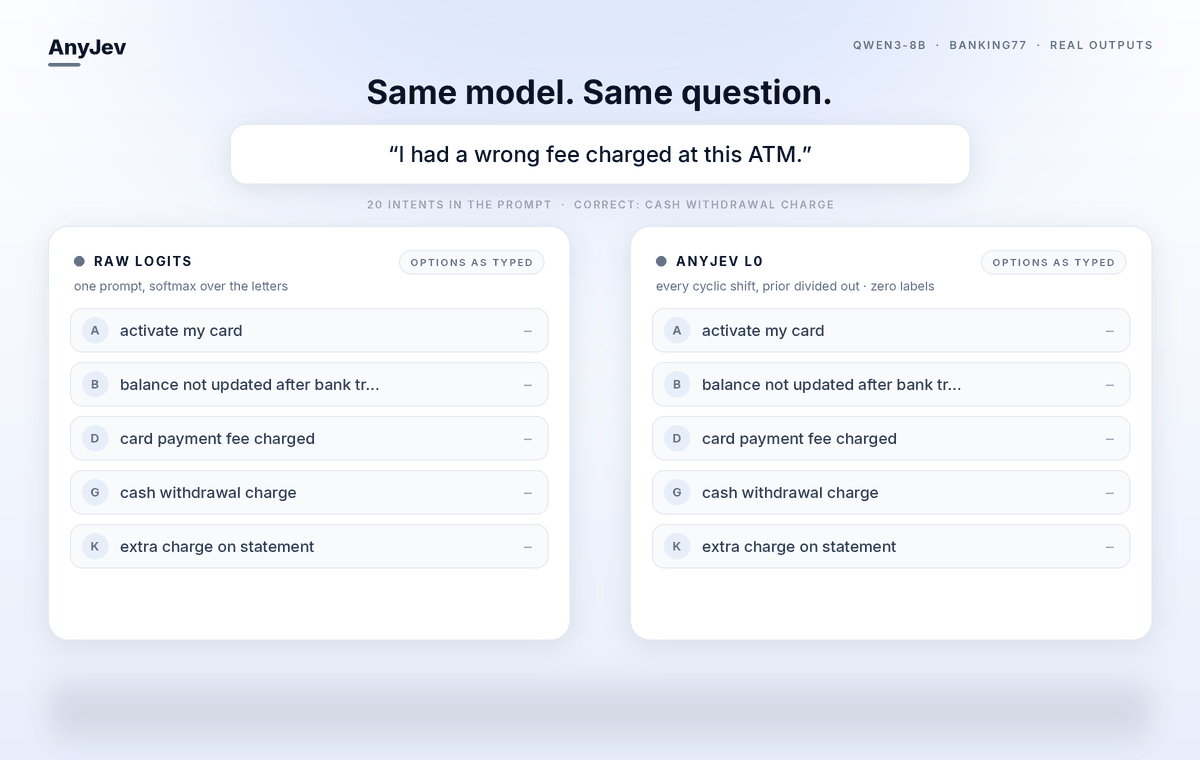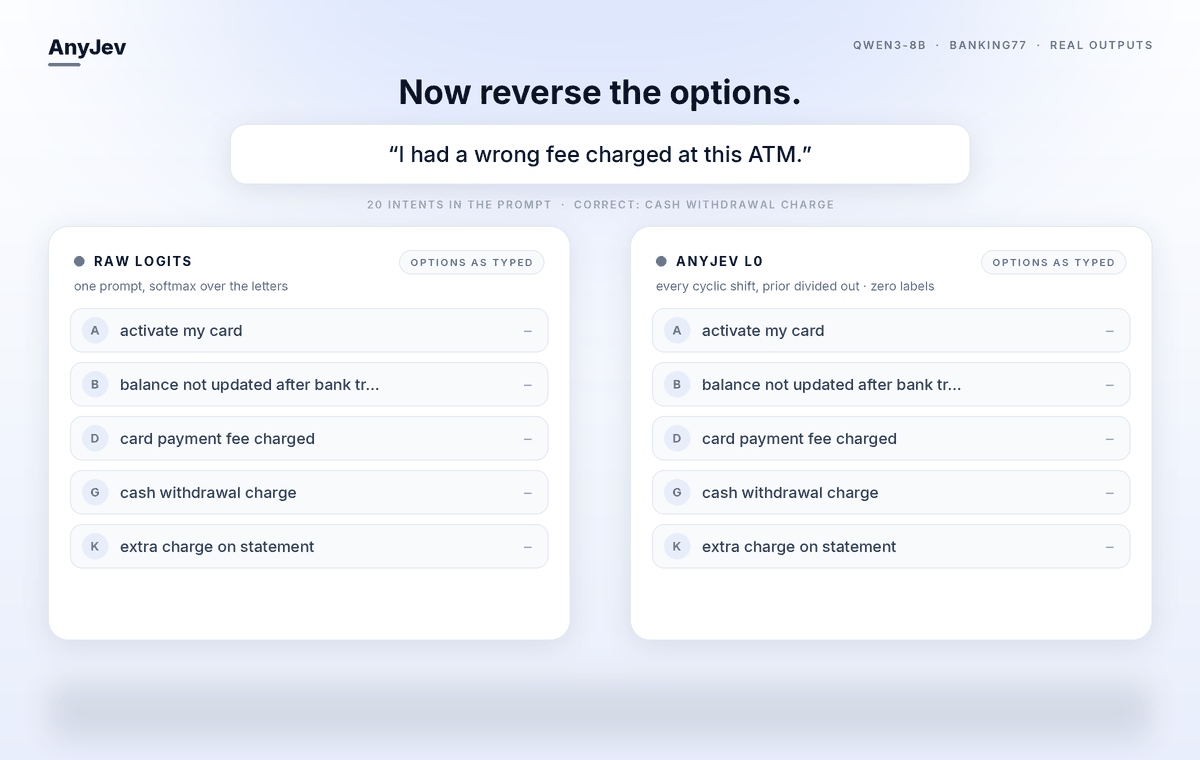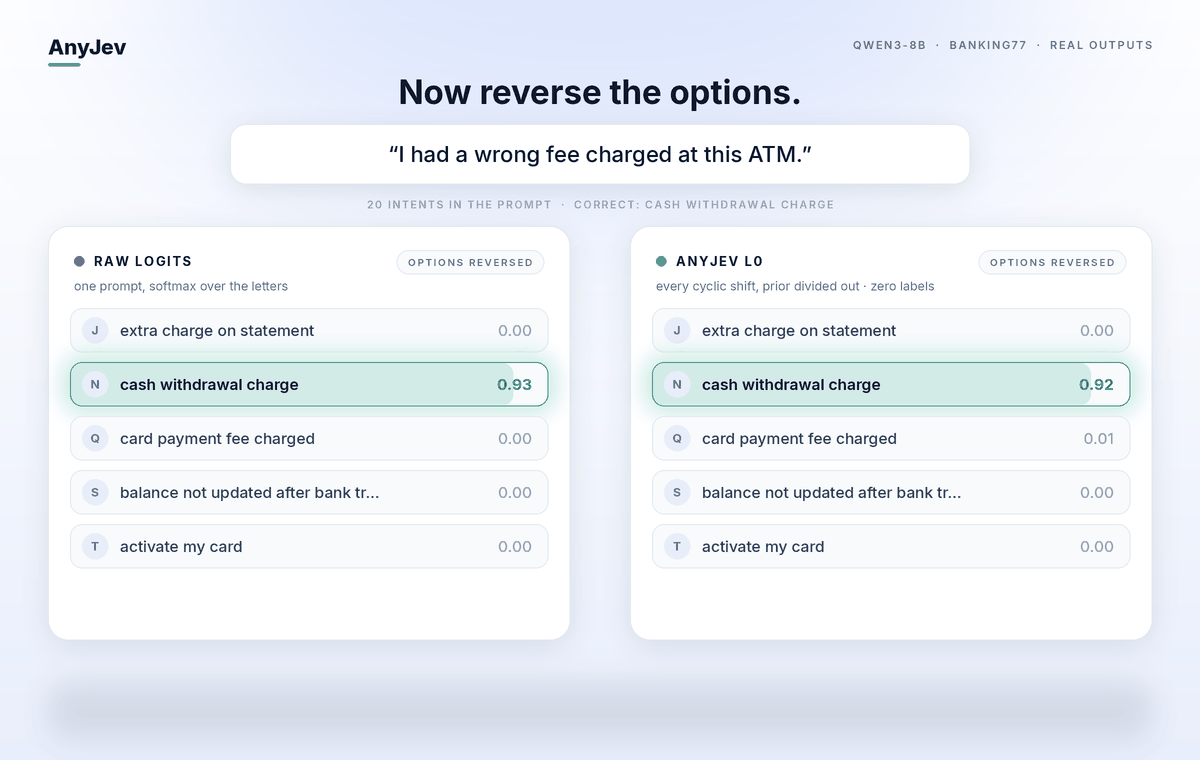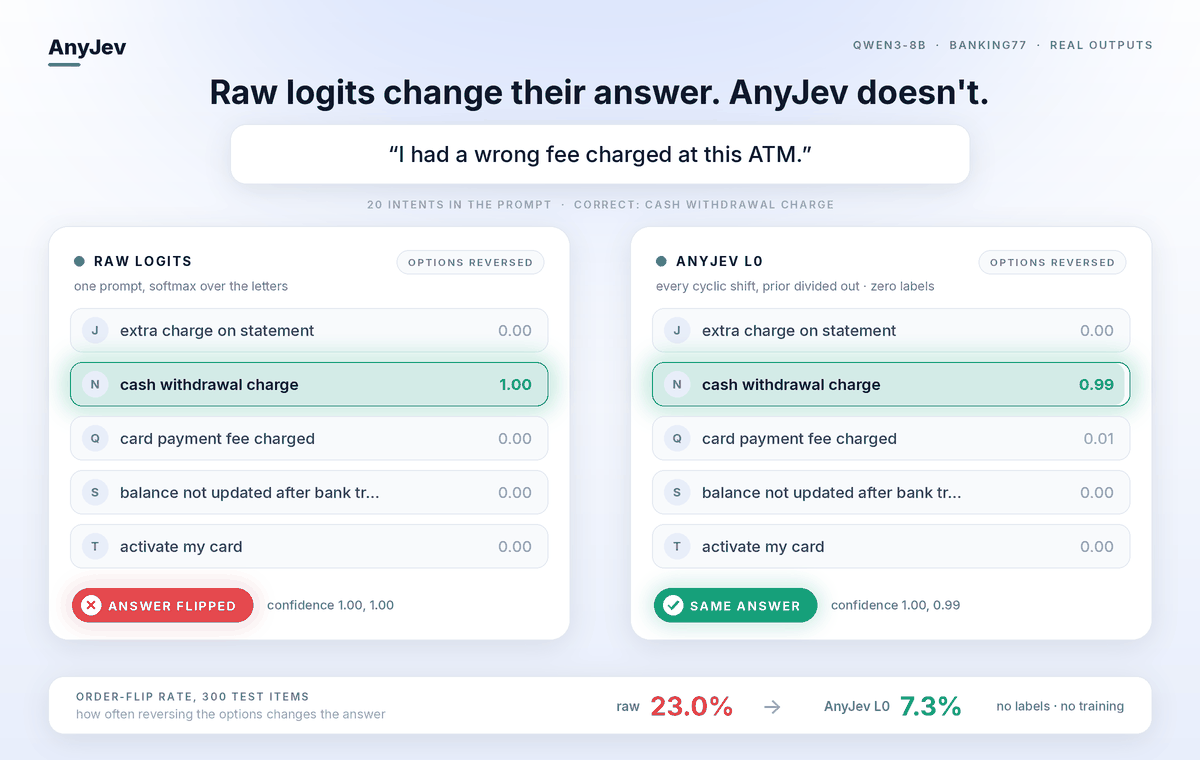
Qwen3-8B on a real BANKING77 item. Every number is a model output.
⚡ Serve it
Three commands take a model off the Hub and put a calibrated decision endpoint in front of it.
pip install "anyjev[hf]"

# 1. keep the blocks a decision needs — usually about two thirds
python -m anyjev.truncate Qwen/Qwen2.5-7B-Instruct 18 ./qwen-b18

# 2. serve it. L2 reads a hidden state, so the pooler hands one back untouched
vllm serve ./qwen-b18 --task embed \
  --override-pooler-config '{"pooling_type":"LAST","normalize":false,"softmax":false}'
from anyjev import Decider, Question
from anyjev.backends.vllm import VLLMBackend

d = Decider(VLLMBackend("http://localhost:8000", "./qwen-b18"), level="L2")
route = Question.choice("Which team should handle this?",
                        ["billing", "technical", "sales", "other"], name="route")

d.fit_head(route, states, labels, layers=[-1])   # 100–300 labels, one closed-form solve
d.decide(ticket, [route])["route"].distribution  # {"billing": 0.81, "technical": 0.07, ...}
An L2 deployment is a pooling server plus a few kilobytes of head. No logits, no parsing, no
patched engine, and nothing generated. raw / L0 / L1 run the same way against a --task generate
server. A head fit through transformers and served by vLLM answers the same as one fit and
served on either alone — 99.0% identical answers, mean |dp| 0.0011 on BANKING77-20.
Measure it on your own box instead of trusting ours:
python -m anyjev.pipeline Qwen/Qwen2.5-7B-Instruct --labels-from banking20
That truncates, serves, fits a head, measures accuracy, ECE and ms per decision on held-out
states, shuts the server down, and repeats at full depth so there is something to compare
against. Timings are a median over --repeats passes with the spread printed next to them,
because on a shared machine a single pass can report the same configuration as both faster and
slower than the baseline.
Depth is usually a gain, not a trade. Cutting Qwen2.5-7B from 28 blocks to 18 left accuracy slightly higher and calibration better, and was faster: a middle block is a better feature space for a linear head than the last one, where the remaining blocks are busy turning the answer into tokens.
--quantization fp8is available and not recommended — it buys single-question latency and costs accuracy.
✨ What it is
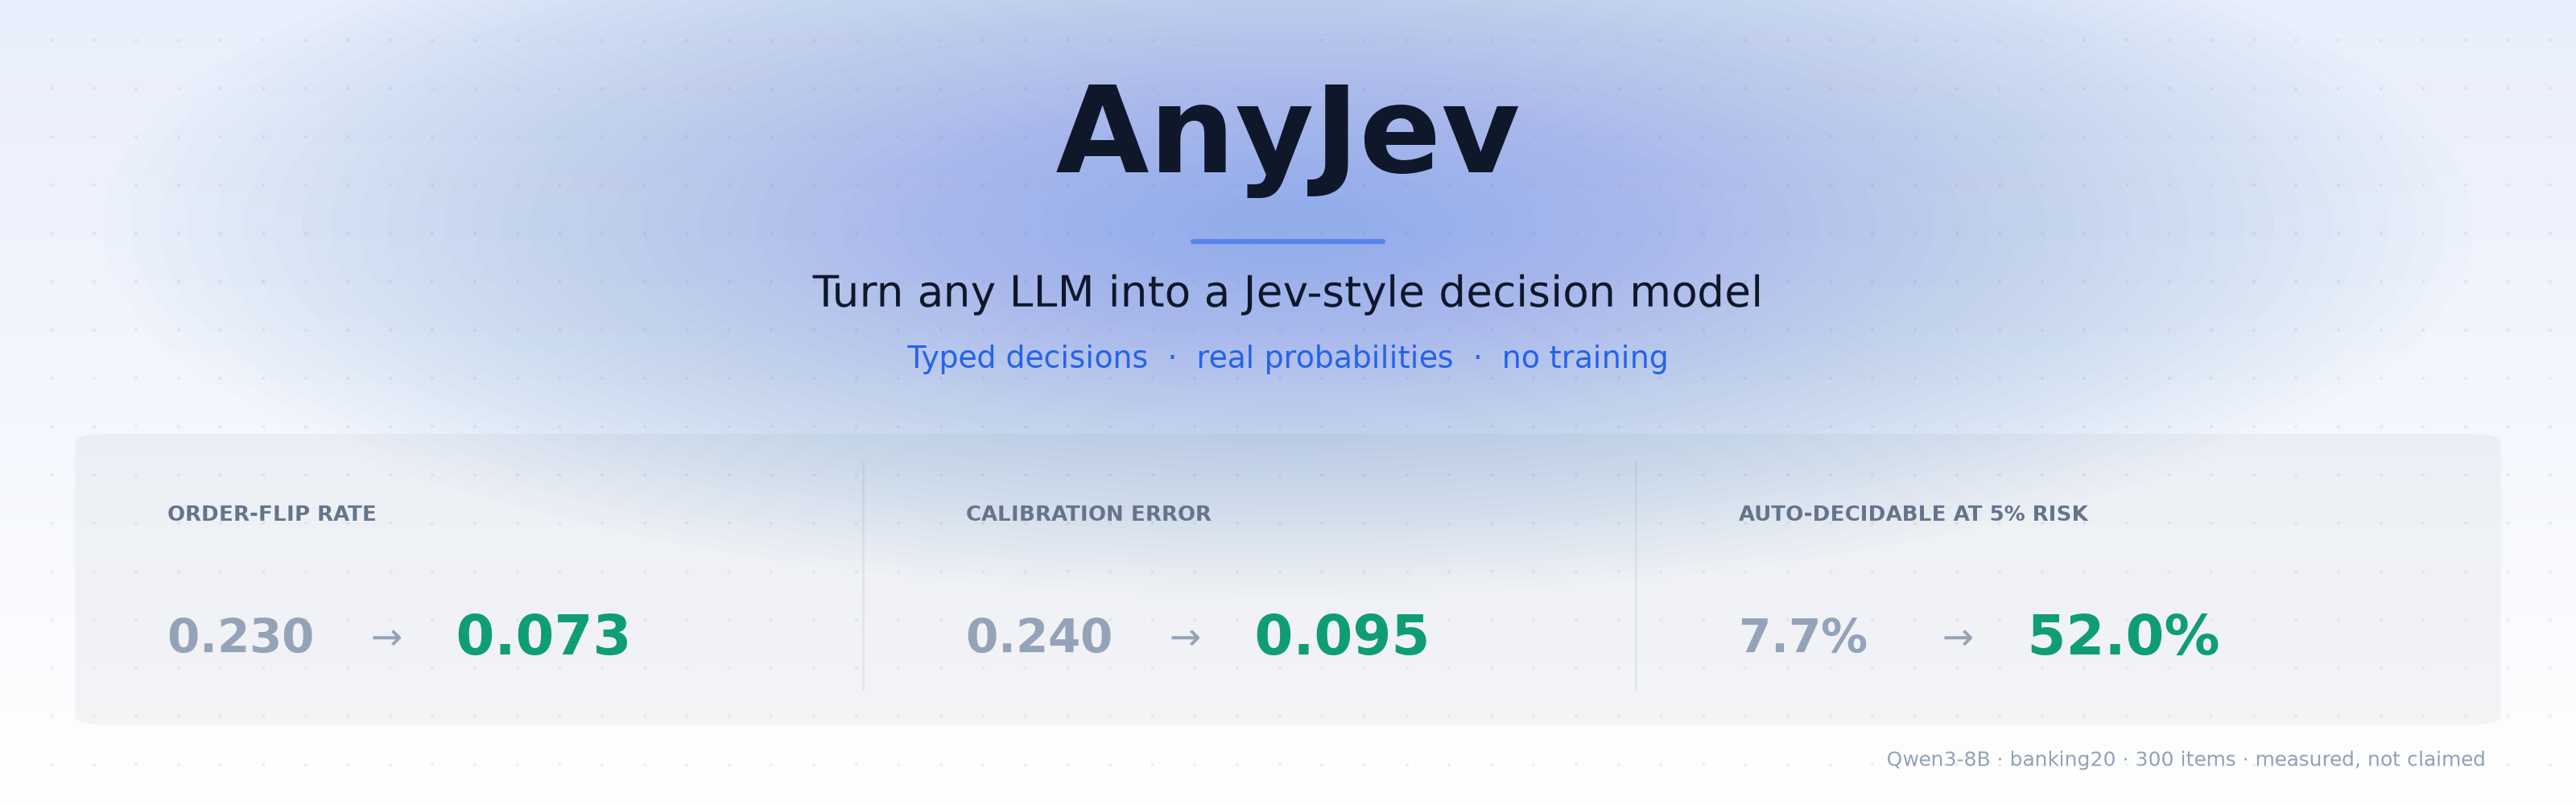
Ask any open LLM a typed question — a choice, a yes/no, a score — and get a decision with a probability you can threshold, read from one prefill of its next-token distribution. Nothing is generated and nothing is parsed. Raw logits change their answer when you reorder the options and their confidence cannot be trusted; AnyJev fixes the first with zero labels and the second with a few hundred.
| ⚪ raw logits | 🔵 L0 zero labels |
🟢 L1 + temperature |
|
|---|---|---|---|
| Labels required | none | none | 100–500 |
| Answer flips when options are reversed | 0.230 | 0.073 | 0.077 |
| Accuracy | 0.747 | 0.803 | 0.807 |
| Calibration error (ECE) | 0.240 | 0.184 | 0.095 |
| Auto-decidable at ≤5% error | 7.7% | 46.3% | 52.0% |
Qwen3-8B, BANKING77 20-way, 300 test items · every ablation
The last row is the point: accuracy moves six points, but the share of traffic you can safely automate goes 7.7% → 52.0%. With raw logits a "0.9" is not trustworthy enough to act on, so everything goes to a human. Once the probability means what it says, you can set a threshold.
📊 With labels: L2
A closed-form head per question, solved on 100–300 labels in seconds — no gradients, the model's weights untouched — and read from one prompt stopped partway down.
| model | L0, zero labels | L2 | block | cost vs one forward |
|---|---|---|---|---|
| Qwen3-1.7B | 0.494 | 0.730 | 18 / 28 | 0.70× |
| Qwen3-4B | 0.564 | 0.786 | 24 / 36 | 0.69× |
| Qwen3-8B | 0.647 | 0.771 | 24 / 36 | 0.68× |
| Qwen3-30B-A3B | 0.630 | 0.799 | 40 / 48 | — |
| Qwen3-32B | 0.700 | 0.798 | 52 / 64 | 0.84× |
LocalLLaMA/typed-decisions, 20 questions × 300 labels, 2,000 held-out decisions. Pooled ECE 0.03–0.05. Jev 0.727 and fine-tuned Laya 0.768 on the same set, as published by their authors · every cell
A 1.7B at 64% of its depth reaches the number Jev publishes; a 4B ties the fine-tuned 421M Laya.
100 labels already put the 8B head at 0.740. Heads for five Qwen3 models ship in
anyjev-heads/, 23 heads per model in one 1.8–4.4 MB file.
A head maintains itself. Only its feature mean and scale move afterwards, re-estimated from unlabelled traffic, so it follows its question across rewordings and option orders on its own — a reworded question drops the Qwen3-8B head from 0.77 to 0.65–0.70 and 30 unlabelled requests bring it back to 0.74–0.75, against 0.77 for a full relabelled refit. New labels are needed only for a new question. How the routing works →
🧠 The levels
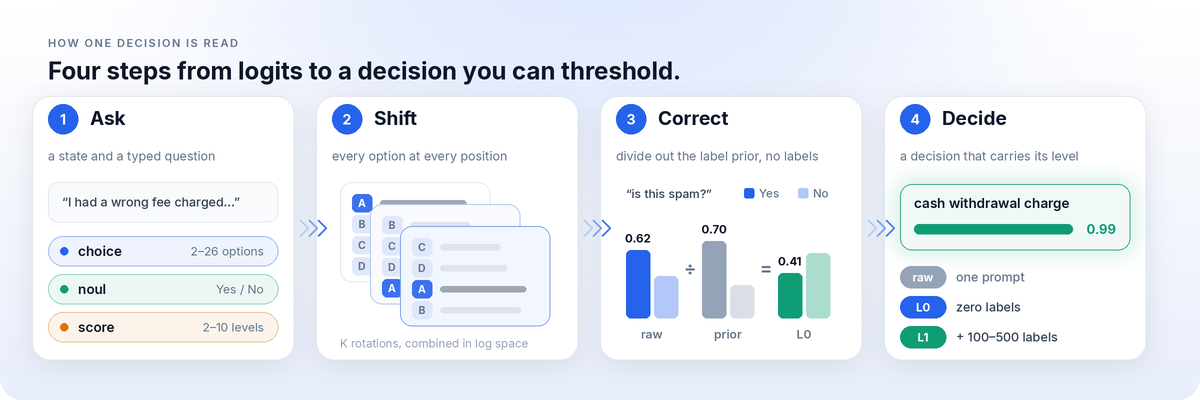
| Level | Needs | Does | Does not |
|---|---|---|---|
raw |
nothing | restricted softmax over label tokens | anything about bias or calibration |
L0 |
nothing | averages position bias out over the K rotations, divides out the label prior | calibrate the uncertainty |
L1 |
100–500 labels per question | temperature scaling on top of L0 | change the ranking |
L2 |
100–300 labels per question | a closed-form head on the hidden state partway down, one prompt per state | transfer to another question or model |
Every Decision carries its level, and require="L1" makes downstream code refuse to act on a
weaker one. L0 costs K prefills for a K-option choice; L2 costs less than one plain forward.
d.observe(q, state, label) collects labels as they arrive and solves the head by itself at 30,
re-solving at 60, 120, … so day 0 runs at L0 with nothing and L2 arrives when the loop has fed it.
The contract in full → · the method →
No GPU handy? python -m demo.jev_mode --backend fake runs the whole thing on a synthetic
model in under a second.
Jev mode · 2048 and Minesweeper · NanoJev maze · when L0 helps · small models · research log, negative results included
Every number is regenerated from committed JSON (bash scripts/regen_docs.sh); a second run
from a clean checkout reproduced every zero-label number bit for bit. Not affiliated with TypeSafe
AI or Jev; rows published by their authors were not rerun here.
🧭 Roadmap
-
choice,noulandscorefrom one prefill; L0 with zero labels; L1 artifacts - L2: a closed-form head per question, routing, label-free adaptation,
observe - Shipped heads for five Qwen3 models; a packaged demo
- 🚧 Speed optimization (ongoing): making every decision cheaper
- L2 on served engines: vLLM, through an embed server's pooler or a truncated checkpoint (
anyjev.pipeline,anyjev.truncate); SGLang not yet - Agent-loop evaluation: the same decisions inside a real agent, against the LLM they replace
- Heads on the Hugging Face Hub, an interactive Space, a technical report
- More models (Llama, Gemma, Mistral, DeepSeek), span readout beyond 26 options, conformal abstention
Dated plan and help-wanted files: ROADMAP.md.
🔍 Limitations
- On typed-decisions, "accuracy" is agreement with a teacher LLM. The gold is the mean of three samples of one model; a fresh sample of that teacher agrees with it 0.735 of the time.
- L2 is per question and per model. Heads fit on other questions do not help a new one, and only Qwen3 heads ship. It needs hidden states, which transformers and a vLLM embed server both provide; other engines do not yet.
- Calibration cannot fix a model that cannot answer. On maze edges and Minesweeper no readout beats the trivial baseline.
- L0 is not a free win everywhere. The batch prior costs accuracy when one label dominates (when L0 helps).
Also: at most 26 options in the letter readout (a span readout is on the roadmap, not in the code); coverage at 5% risk is a high-variance estimate at n = 300; the headline tables are Qwen models; every decision here is scored in isolation, not inside an agent loop.
🤝 Contributing and citation
Backends and bench providers are one file each; several are help wanted (ROADMAP.md, CONTRIBUTING.md). Changes: CHANGELOG.md. Credits: CREDITS.md.
@software{anyjev2026,
  title  = {AnyJev: Turn any LLM into a Jev-style decision model},
  author = {Zhang, Jiamu and Yang, Tianze and Shi, Yucheng and Wu, Liang},
  year   = {2026},
  url    = {https://github.com/nokia-applied-research/AnyJev}
}
Apache-2.0, see LICENSE. Datasets keep their own licenses, see THIRD_PARTY.md.
1 maintainer

Release files for anyjev 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| anyjev-0.1.0.tar.gz | 82.3 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| anyjev-0.1.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 145.1 kB
Release files / anyjev-0.1.0.tar.gz
| Download URL | anyjev-0.1.0.tar.gz |
|---|---|
| Size | 82.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
3dc0a887b59d6faa501c6cc456373fd3dc1dbd1728c5f63fd531e7c564e0e9b7
|
|
BLAKE2b-256 checksum How to use checksums |
0408f8cee8cb2403bb7cf62ede30a343deedfdfdb383ea44eb38cdadcea9c0b4
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 26, 2026.
Transparency logRelease files / anyjev-0.1.0-py3-none-any.whl
| Download URL | anyjev-0.1.0-py3-none-any.whl |
|---|---|
| Size | 62.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
36afbed4101defbc25c5a8fc69153accec8d8b21e5d1bc853e81de77c71a9aa4
|
|
BLAKE2b-256 checksum How to use checksums |
edd3c8752d859f42f2ad52d862c90dedced36610caf53dca9ed82c3caf47c74e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 26, 2026.
Transparency log













