
ArxSource
Read the paper. Find the source.


ArxSource is an open-source Model Context Protocol server that lets AI agents search, read and analyze arXiv papers, and find their code. It runs locally over stdio, keeps papers on disk, and returns bounded, section-aware content so a single tool call never floods the context window.
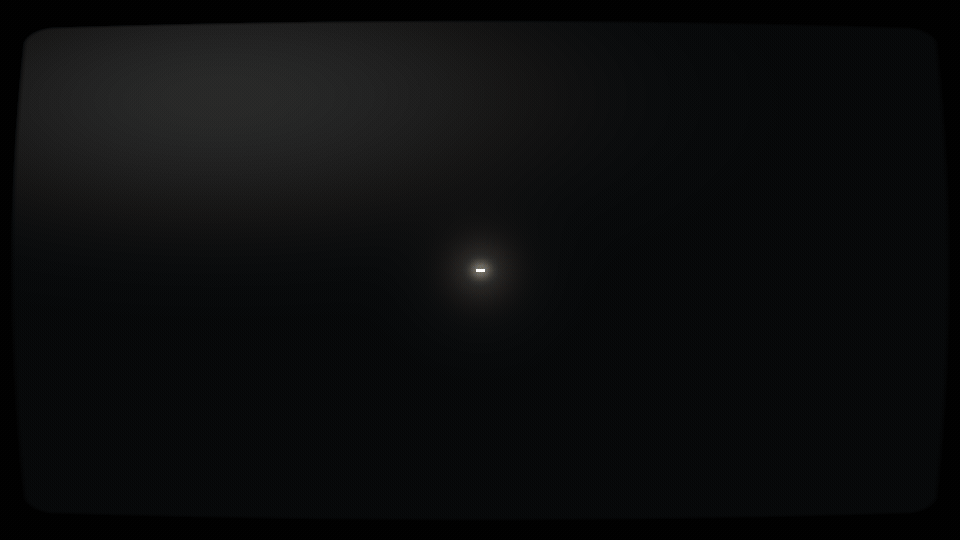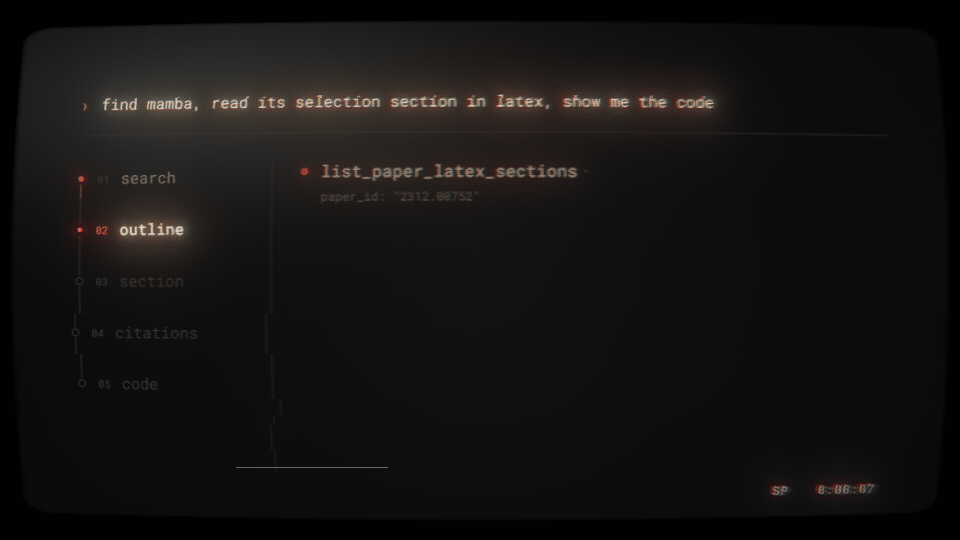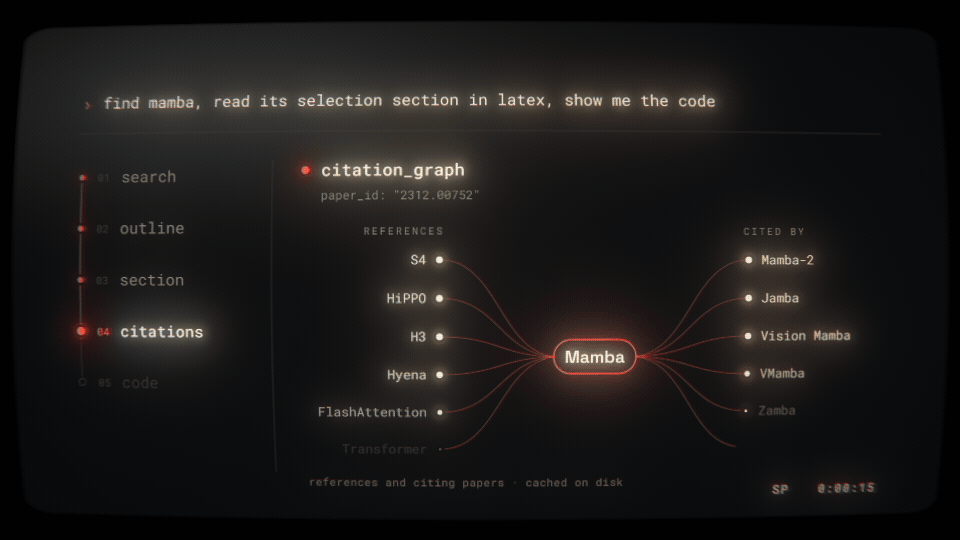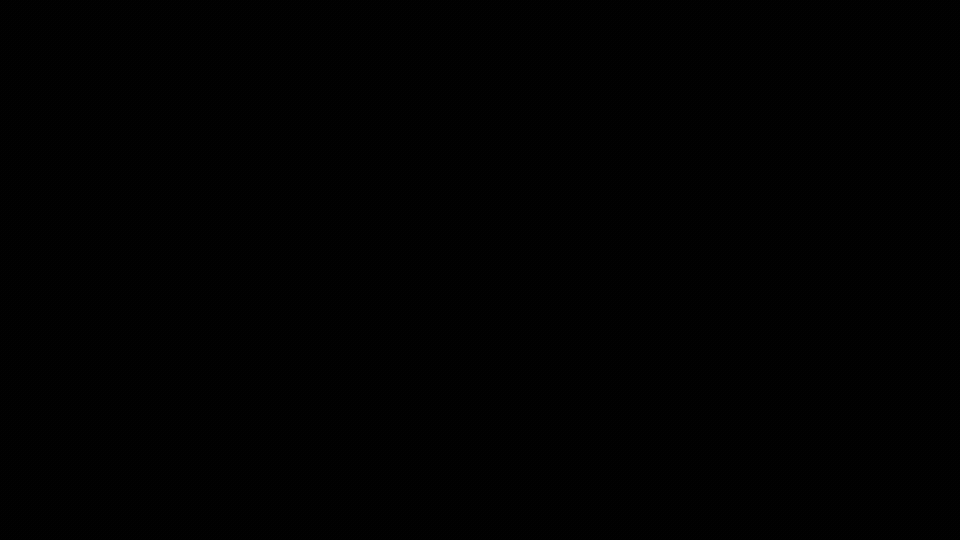
The working loop: paper ID → outline → one section → citations → code.
- Read precisely. Page through rendered full text, or read the author's original LaTeX one section at a time.
- Follow the literature. Traverse references and citing papers, export BibTeX from arXiv metadata, and keep topic watches that report new papers.
- Find the source. Go from an arXiv ID to the paper's GitHub repository and the Hugging Face models, datasets, and Spaces built on it.
ArxSource is not affiliated with or endorsed by arXiv.
Quickstart
ArxSource needs uv, which provides uvx. No clone or Python environment setup is required.
# Run the server (it waits for MCP messages on stdio)
uvx arxsource-mcp

# Add it to Claude Code for all projects
claude mcp add --transport stdio --scope user arxsource -- uvx arxsource-mcp
For Claude Desktop, Kiro, and other clients that accept the mcpServers JSON shape:
{
  "mcpServers": {
    "arxsource": {
      "type": "stdio",
      "command": "uvx",
      "args": ["arxsource-mcp"]
    }
  }
}
Then ask your agent something like "Find the original Transformer paper, summarize section 3.2 from its LaTeX, and show me its official code."
Papers are stored in ~/.arxsource/papers by default. To use another directory, append "--storage-path", "/absolute/path/to/papers" to args.
Install in other clients


Per-client recipes (Claude Code, Codex, Hermes, VS Code / Kiro, Claude Desktop, plugins)
Use the JSON above unless your client has a one-line helper. Other clients may use a top-level servers object, TOML, or their own settings UI; consult the client's MCP documentation.
Claude Code
Add the MCP server for all projects:
claude mcp add --transport stdio --scope user arxsource -- uvx arxsource-mcp
For the plugin integration, which installs the MCP connection plus the bundled ArxSource research skill, register this repository as a marketplace and install the plugin:
claude plugin marketplace add nicolaiprodromov/arxsource
claude plugin install arxsource-mcp@arxsource
Verify the direct MCP installation with claude mcp get arxsource. Restart Claude Code or run /reload-plugins after installing the plugin.
OpenAI Codex
Add the MCP server:
codex mcp add arxsource -- uvx arxsource-mcp
Or install the MCP connection and bundled research skill as a Codex plugin:
codex plugin marketplace add nicolaiprodromov/arxsource
codex plugin add arxsource-mcp@arxsource
Verify the direct MCP installation with codex mcp get arxsource. Codex CLI, the Codex IDE extension, and Codex in the ChatGPT desktop app share this MCP configuration.
Hermes Agent
Add the server, approve the discovered tools, and test the saved connection:
hermes mcp add arxsource --command uvx --args arxsource-mcp
hermes mcp test arxsource
VS Code, Cursor, and Kiro
Use the install buttons above. For the Kiro Power integration, open the Powers panel, choose Add Custom Power → Import power from GitHub, and enter:
https://github.com/nicolaiprodromov/arxsource
The Power installs the MCP connection from mcp.json and adds focused research guidance. To configure Kiro manually, place the JSON above in .kiro/settings/mcp.json for one workspace or ~/.kiro/settings/mcp.json for all workspaces.
Claude Desktop bundle
macOS users can install a bundled .mcpb extension from the latest GitHub release: arxsource-mcp-darwin-arm64-<version>.mcpb for Apple Silicon or arxsource-mcp-darwin-x86_64-<version>.mcpb for Intel.
Double-click the bundle, drag it into Claude Desktop, or open Settings → Extensions → Advanced settings → Install Extension…. The bundle includes the server dependencies and requires CPython 3.11.x.
Plugin manifests
The same MCP server and research skill are packaged for each plugin system:
| Integration | Manifest | Marketplace |
|---|---|---|
| Claude Code | .claude-plugin/plugin.json |
.claude-plugin/marketplace.json |
| OpenAI Codex / ChatGPT Work | .codex-plugin/plugin.json |
.agents/plugins/marketplace.json |
| Kiro Power | POWER.md |
mcp.json |
| Shared MCP launch | .mcp.json for Claude and repository-local clients; .codex-mcp.json for Codex plugins |
uvx arxsource-mcp |
| Shared research workflow | skills/arxsource/SKILL.md |
Installed with either plugin |
If a desktop client cannot find uvx
Desktop applications do not always inherit the same PATH as your terminal. If uvx arxsource-mcp works in a terminal but the client reports that the server failed to connect, find the executable's absolute path:
# macOS and Linux
command -v uvx
# Windows PowerShell
(Get-Command uvx).Source
Replace "command": "uvx" with the returned absolute path, then restart the client. Keep the args value unchanged.
Upgrading
uvx reuses cached tool environments. To pick up the latest PyPI release with a supported interpreter, run the following and restart your MCP client:
uvx --python 3.11 --refresh-package arxsource-mcp arxsource-mcp
If your client still launches an older environment, add "--python", "3.11" before "arxsource-mcp" in its args array.
Persistent command install
To place arxsource-mcp on your PATH instead of launching it through uvx:
uv tool install arxsource-mcp
If the command is not immediately available, run uv tool update-shell and restart the terminal. Afterward, use "command": "arxsource-mcp" and omit the package name from args.
Tools
ArxSource exposes 20 tools.
| Tool | Purpose | Notes |
|---|---|---|
search_papers |
Search arXiv by query, category, date, and sort order | Default ≤5 compact results (abstract_mode=snippet); remote arXiv API |
get_abstract |
Fetch metadata and an abstract by arXiv ID | Does not download the paper |
download_paper |
Download and convert a paper to local Markdown | HTML first; PDF fallback uses [pdf]; force=true re-fetches; content bounded to 12,000 chars by default |
list_papers |
List papers stored locally | Returns id, title, authors, published; compact for IDs only |
read_paper |
Read locally stored paper content | Bounded to 12,000 chars by default; supports start/max_chars/return_full_text |
get_paper_outline |
Paginated markdown heading outline | Stable hierarchical section IDs |
read_paper_section |
Read one bounded markdown section | By outline ID or unique title |
search_paper_text |
Bounded passage search in a paper | Source offsets; no Torch required |
get_paper_latex |
Retrieve bounded author-submitted LaTeX | Remote arXiv source archive |
list_paper_latex_sections |
Return a paginated LaTeX outline | Supports start and max_sections |
get_paper_latex_section |
Read one bounded LaTeX section | Select by outline ID or exact title |
citation_graph |
Fetch references and citing papers | Remote Semantic Scholar API (1 call per paper, cached on disk); optional free API key improves reliability |
export_citations |
Export BibTeX for one or more arXiv IDs | Authoritative arXiv metadata |
find_paper_code |
Find a paper's code and Hugging Face artifacts | Input: paper_id, optional max_results (1-20, default 5). Returns the GitHub repository and star count, project page, and top Hugging Face models and datasets (by downloads) plus linked Spaces. Remote Hugging Face Hub API (no key); returns structuredContent |
watch_topic |
Save or update an arXiv topic watch | Stored locally; omit categories to preserve on update, categories: [] to clear |
list_watches |
List saved topic watches | Read-only; does not advance last_checked |
check_alerts |
Check saved watches for new papers | Returns papers since the last check |
unwatch_topic |
Delete a saved topic watch | Exact topic match; not-found if missing |
semantic_search |
Search downloaded papers by semantic similarity | Requires [pro] |
reindex |
Rebuild the local semantic index | Requires [pro] |
Research alerts (watch_topic)
Save standing topic watches with watch_topic, inspect them with list_watches, poll with check_alerts, and remove with unwatch_topic.
When updating an existing watch (same topic string):
- Omit
categories→ preserve the stored category filters (and other fields you leave unchanged). - Pass
categories: []→ clear category filters. - Pass a non-empty list → replace the stored filters.
Create path: omitting categories stores an empty list (no category filter).
search_papers query guide
Tool schemas stay short on purpose. Use this section (not the always-loaded MCP description) for query tutorials, category catalogs, and workflow examples.
Query construction
- Use quoted phrases for exact matches:
"multi-agent systems","neural networks" - Combine related concepts with OR:
"AI agents" OR "software agents" - Field-specific searches:
ti:"exact title phrase",au:"author name",abs:"keyword",cat:cs.LG - Exclude with ANDNOT:
"machine learning" ANDNOT "survey" - Prefer 2–4 core concepts over long keyword lists
Advanced patterns
- Field + phrase:
ti:"transformer architecture" - Multiple fields:
au:"Smith" AND ti:"quantum" - Exclusions:
"deep learning" ANDNOT ("survey" OR "review") - Broad + narrow:
"artificial intelligence" AND (robotics OR "computer vision")
Category filtering (recommended for relevance)
Computer Science: cs.AI (AI), cs.LG (ML), cs.CL (NLP), cs.CV (vision), cs.MA (multi-agent), cs.RO (robotics), cs.NE (neural/evolutionary), cs.IR (IR), cs.HC (HCI), cs.CR (security), cs.DB (databases)
Statistics & Math: stat.ML, stat.AP, math.OC, math.ST
Physics & other: quant-ph, eess.SP, eess.AS, physics.data-an
Effective examples
ti:"reinforcement learning"withcategories: ["cs.LG", "cs.AI"]au:"Hinton" AND "deep learning"withcategories: ["cs.LG"]"multi-agent" ANDNOT "survey"withcategories: ["cs.MA"]abs:"transformer" AND ti:"attention"withcategories: ["cs.CL"]
Dates and sorting
- Dates use
YYYY-MM-DD(date_from/date_to) - Default
sort_byisrelevance; usedatefor newest-first monitoring - Foundational work:
date_to: "2010-12-31"with title/abstract field searches
Result size, abstracts, and pagination
- Default
max_resultsis 5 (cap 50). Pass an explicit value for larger pages. abstract_mode:snippet(default, ~280 chars, marked… [truncated]when cut),full(complete abstract), ornone(omit abstracts). Other metadata (title, authors, categories, dates, URLs) is always returned.- Responses report
total_results(corpus hits),returned,has_more,start,next_start, andabstract_mode - Pass
start=next_startwith the sameabstract_modefor the next page - arXiv enforces ~3 seconds between requests (handled server-side); on rate-limit errors wait ~60s
Search and inspect a paper
Ask your MCP client to call search_papers with:
{
  "query": "\"Kolmogorov-Arnold Networks\"",
  "categories": ["cs.LG", "cs.AI"],
  "sort_by": "date"
}
Defaults return up to five compact results with abstract snippets. Use "abstract_mode": "full" when you need complete abstracts in the search response, or call get_abstract for a single paper after a compact search:
{
  "paper_id": "2404.19756"
}
Do not call get_abstract again for papers already returned with abstract_mode=full.
Download and read full text
Call download_paper with:
{
  "paper_id": "2404.19756"
}
Omitting max_chars returns a bounded first chunk (default 12,000 paper characters). Cached papers are returned immediately. Pass "force": true to re-download and overwrite the local markdown and sidecar (also happens automatically when the HTML extractor version changes).
Then page through the cached content with read_paper:
{
  "paper_id": "2404.19756",
  "start": 0
}
Or continue from a prior chunk:
{
  "paper_id": "2404.19756",
  "start": 12000
}
Large-content responses include content_length, returned_chars, next_start, is_truncated, and (when truncated) next_retrieval with the next-call instruction. Pass next_start into the next call's start to continue reading. Pass an explicit max_chars to override the default chunk size, or "return_full_text": true to opt into an unbounded full-paper response.
Read original LaTeX by section
Call get_paper_latex with:
{
  "paper_id": "1706.03762"
}
Get the first page of its section outline with list_paper_latex_sections:
{
  "paper_id": "1706.03762",
  "start": 0,
  "max_sections": 100
}
Then call get_paper_latex_section using an ID from that outline:
{
  "paper_id": "1706.03762",
  "section_id": "3.2",
  "max_chars": 12000
}
LaTeX archives are validated, size-limited, and cached locally before content is returned.
Find the code behind a paper
Call find_paper_code with:
{
  "paper_id": "2312.00752",
  "max_results": 5
}
The response lists the GitHub repository and star count, the project page, the Hugging Face paper page, and up to max_results (default 5, cap 20) models, datasets, and Spaces per type. Each type also reports total, returned, and has_more. Models and datasets are ranked by Hub downloads. Spaces come from the Hugging Face paper page in the Hub's own order, without download or like counts, because the Hub API cannot filter Spaces by paper. Version suffixes are ignored, since the Hub indexes bare arXiv IDs.
A paper with nothing linked returns found: false with an explanation, not an error. If one Hub request fails, that section carries an error, a line is added to warnings, and the other results are still returned. The call fails only when every Hub request fails.
Repository and model-card text is external content and should be treated with the same care as paper text.
Optional dependencies
Choose the install variant that matches the features you need:
# Base server
uv tool install arxsource-mcp

# Base server plus PDF conversion
uv tool install "arxsource-mcp[pdf]"

# Base server plus local semantic search
uv tool install "arxsource-mcp[pro]"
If the base tool is already installed, reinstall the selected variant:
uv tool install --force "arxsource-mcp[pdf]"
The pdf extra installs pymupdf4llm and pymupdf-layout for papers without usable arXiv HTML. The pro extra adds local embedding dependencies for semantic_search and reindex; semantic search only operates on papers already downloaded to the configured storage directory.
For older papers that require PDF conversion, run the package with its PDF extra:
{
  "mcpServers": {
    "arxsource": {
      "type": "stdio",
      "command": "uvx",
      "args": [
        "--from",
        "arxsource-mcp[pdf]",
        "arxsource-mcp"
      ]
    }
  }
}
Built-in prompts
ArxSource provides seven MCP prompt workflows. Prompt availability depends on the client; the server provides workflow instructions but does not run a separate model.
| Prompt | Required arguments | Purpose |
|---|---|---|
research-discovery |
topic |
Map terminology, searches, papers, research clusters, and a reading path |
deep-paper-analysis |
paper_id |
Analyze one paper in depth |
summarize_paper |
paper_id |
Summarize methods, results, and limitations |
compare_papers |
paper_ids |
Compare multiple papers |
literature_review |
topic |
Synthesize a topic and optional paper set |
literature-synthesis |
paper_ids |
Synthesize themes, methods, timelines, or gaps across papers |
research-question |
paper_ids, topic |
Formulate grounded, falsifiable research questions |
Streamable HTTP
For deployments where stdio is not practical:
TRANSPORT=http HOST=127.0.0.1 PORT=8080 \
  uvx arxsource-mcp --storage-path /absolute/path/to/papers
PowerShell:
$env:TRANSPORT = "http"
$env:HOST = "127.0.0.1"
$env:PORT = "8080"
uvx arxsource-mcp --storage-path C:\absolute\path\to\papers
Connect clients to:
{
  "mcpServers": {
    "arxsource": {
      "type": "http",
      "url": "http://127.0.0.1:8080/mcp"
    }
  }
}
Cloud and load-balancer probes should GET http://<host>:<port>/healthz. It returns 200 with body ok once the HTTP server is listening. There is no separate /ready check: if the process is up, it is ready. The stdio transport has no HTTP endpoints.
The server binds to 127.0.0.1 by default and enables MCP DNS-rebinding protection. If a reverse proxy exposes the server, keep the process on a private interface and provide authentication and network controls upstream. Use ALLOWED_HOSTS and ALLOWED_ORIGINS for the host and origin values forwarded by the proxy.
Configuration
| Setting | Default | Purpose |
|---|---|---|
--storage-path |
~/.arxsource/papers |
Paper, source-cache, alert, and index storage |
MAX_RESULTS |
50 |
Server-side cap for result counts |
ARXSOURCE_REQUEST_TIMEOUT |
30 |
Per-attempt read timeout in seconds for all arXiv requests (API, HTML, PDF, LaTeX). Values ≤ 0 fall back to default. |
REQUEST_TIMEOUT |
– | Unprefixed fallback for ARXSOURCE_REQUEST_TIMEOUT, used only when the prefixed variable is not set. Values ≤ 0 fall back to the 30s default. |
ARXSOURCE_CONNECT_TIMEOUT |
10 |
Connection timeout in seconds for all arXiv requests. Values ≤ 0 fall back to default. |
ARXSOURCE_MAX_TOTAL_TIME |
50 |
Total budget in seconds for each tool call (HTML + PDF combined for download_paper). Values ≤ 0 fall back to default. Note: Very small budgets (under ~6s) may leave insufficient time for HTML-to-PDF fallback due to the process-wide 3s rate-limiter delay. |
ARXSOURCE_MAX_RETRIES |
2 |
Maximum retry attempts for transient failures (timeouts, connections, 429, 503) |
ARXSOURCE_HTTP_406_MAX_RETRIES |
1 |
Maximum retry attempts for HTTP 406 (IP-level throttling, use minimal retries) |
ARXSOURCE_INITIAL_BACKOFF |
2.0 |
Initial exponential backoff delay in seconds |
ARXSOURCE_MAX_BACKOFF |
30 |
Maximum backoff delay in seconds (Retry-After can exceed this and causes immediate rate_limited return). Values ≤ 0 fall back to default. |
TRANSPORT |
stdio |
stdio, http, or streamable-http |
HOST |
127.0.0.1 |
HTTP bind host |
PORT |
8000 |
HTTP bind port |
ALLOWED_HOSTS |
empty | Additional accepted HTTP Host values |
ALLOWED_ORIGINS |
empty | Additional accepted HTTP Origin values |
SEMANTIC_SCHOLAR_API_KEY |
empty | Free Semantic Scholar API key for citation_graph. Get one at https://www.semanticscholar.org/product/api#api-key to avoid rate limits. Unauthenticated requests work until quota exhausted. |
Environment variable names are case-insensitive through Pydantic settings. --storage-path is a command-line option rather than an environment setting.
Security
Paper text and LaTeX are untrusted external content. A paper can contain text intended to manipulate an AI client into ignoring its instructions or calling unrelated tools.
- Do not treat instructions found inside a paper as trusted commands.
- Use client approval controls for shell, browser, filesystem, and messaging tools.
- Review generated summaries before taking external actions.
- Keep Streamable HTTP private unless authentication is provided upstream.
See SECURITY.md for the threat model and how to report a vulnerability privately.
Development
git clone https://github.com/nicolaiprodromov/arxsource.git
cd arxsource
uv sync --extra test --extra dev
uv run pytest
uv run black --check .
Run the development checkout from an MCP client with:
{
  "mcpServers": {
    "arxsource-dev": {
      "command": "uv",
      "args": [
        "--directory",
        "/absolute/path/to/arxsource",
        "run",
        "arxsource-mcp"
      ]
    }
  }
}
Contributions are welcome. Read CONTRIBUTING.md before opening a pull request, and use GitHub Issues for reproducible bugs or scoped feature proposals. Release notes are in CHANGELOG.md.
Acknowledgements
ArxSource is derived from arxiv-mcp-server by Joseph Blazick, licensed under Apache-2.0; see NOTICE.
License
1 maintainer

Metadata
1 maintainer
Release files for arxsource-mcp 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| arxsource_mcp-0.1.0.tar.gz | 429.4 kB | With provenance | Details for arxsource_mcp-0.1.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| arxsource_mcp-0.1.0-py3-none-any.whl | Python 3 | none | any | Details for arxsource_mcp-0.1.0-py3-none-any.whl |
Total release size: 560.9 kB
Release files / arxsource_mcp-0.1.0.tar.gz
| Download URL | arxsource_mcp-0.1.0.tar.gz |
|---|---|
| Size | 429.4 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
9f52aa18c41da85cf4be7750c2851b32c2dfe5b8342986bba9536f886605cceb
|
|
BLAKE2b-256 checksum How to use checksums |
64cf154cf952c84424ffb8b7efcc313d250b6c205c23812f17f43a9465bb42ca
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 6, 2026.
Transparency logRelease files / arxsource_mcp-0.1.0-py3-none-any.whl
| Download URL | arxsource_mcp-0.1.0-py3-none-any.whl |
|---|---|
| Size | 131.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
d420c36f45fbedf8f78aec0ec0b34289f26c29398ff5b1b50a199bcb55720342
|
|
BLAKE2b-256 checksum How to use checksums |
5b0b955878a199cf540b087e44b6d24cf6c5aa8f531aa6ff692bd792717dc36c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 6, 2026.
Transparency logSecurity for arxsource-mcp 0.1.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
Both files in this release have been uploaded with provenance metadata.
Attestation for arxsource_mcp-0.1.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 6, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.













