
AudioSR: Versatile Audio Super-resolution at Scale


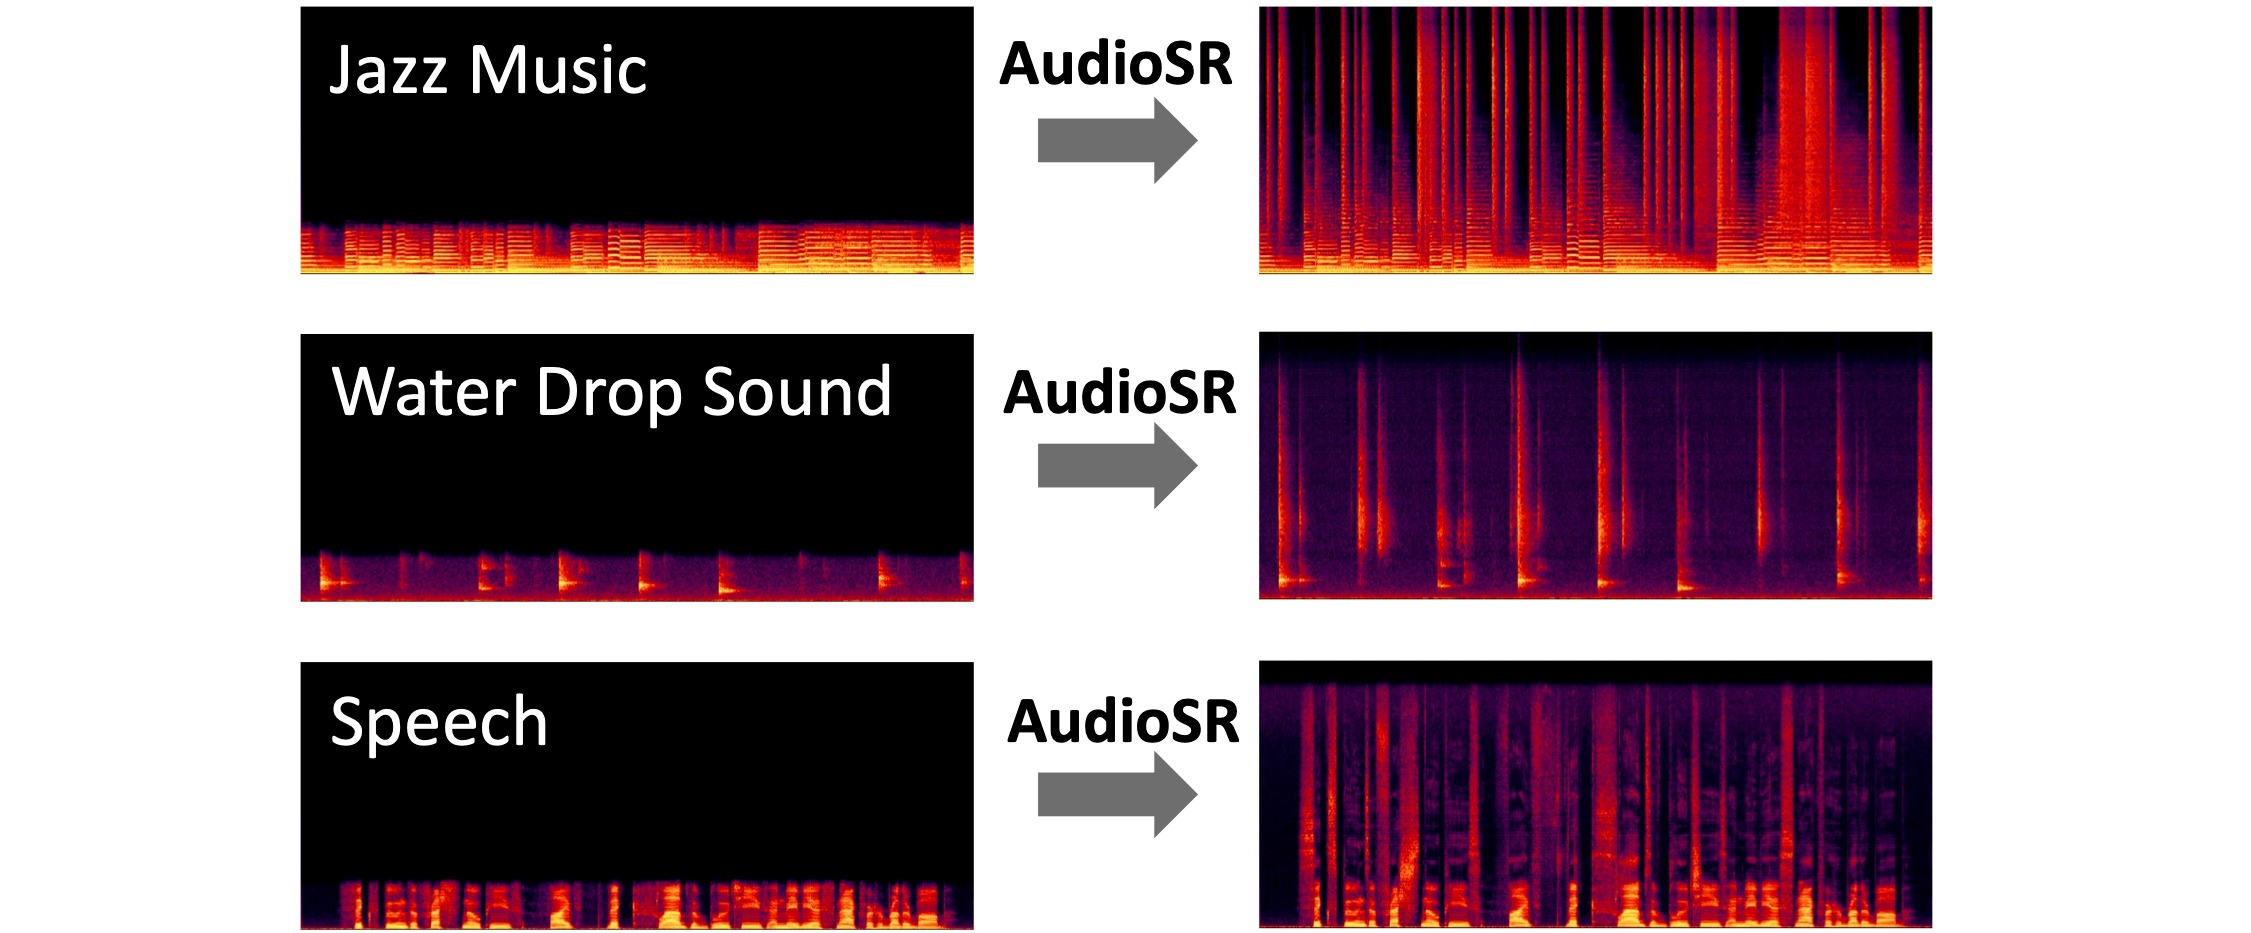
Pass your audio in, AudioSR will make it high fidelity!
Work on all types of audio (e.g., music, speech, dog, raining, ...) & all sampling rates.
Share your thoughts/samples/issues in our discord channel: https://discord.gg/HWeBsJryaf
Change Log
- 2023-09-24: Add replicate demo (@nateraw); Fix error on windows, librosa warning etc (@ORI-Muchim).
- 2023-09-16: Fix DC shift issue. Fix duration padding bug. Update default DDIM steps to 50.
Commandline Usage
Installation
# Optional
conda create -n audiosr python=3.9; conda activate audiosr
# Install AudioLDM
pip3 install audiosr==0.0.7
Usage
Process a list of files. The result will be saved at ./output by default.
audiosr -il batch.lst
Process a single audio file.
audiosr -i example/music.wav
Full usage instruction
> audiosr -h

> usage: audiosr [-h] -i INPUT_AUDIO_FILE [-il INPUT_FILE_LIST] [-s SAVE_PATH] [--model_name {basic,speech}] [-d DEVICE] [--ddim_steps DDIM_STEPS] [-gs GUIDANCE_SCALE] [--seed SEED]

optional arguments:
  -h, --help            show this help message and exit
  -i INPUT_AUDIO_FILE, --input_audio_file INPUT_AUDIO_FILE
                        Input audio file for audio super resolution
  -il INPUT_FILE_LIST, --input_file_list INPUT_FILE_LIST
                        A file that contains all audio files that need to perform audio super resolution
  -s SAVE_PATH, --save_path SAVE_PATH
                        The path to save model output
  --model_name {basic,speech}
                        The checkpoint you gonna use
  -d DEVICE, --device DEVICE
                        The device for computation. If not specified, the script will automatically choose the device based on your environment.
  --ddim_steps DDIM_STEPS
                        The sampling step for DDIM
  -gs GUIDANCE_SCALE, --guidance_scale GUIDANCE_SCALE
                        Guidance scale (Large => better quality and relavancy to text; Small => better diversity)
  --seed SEED           Change this value (any integer number) will lead to a different generation result.
  --suffix SUFFIX       Suffix for the output file
TODO
- Add gradio demo.
- Optimize the inference speed.
Cite our work
If you find this repo useful, please consider citing:
@article{liu2023audiosr,
  title={{AudioSR}: Versatile Audio Super-resolution at Scale},
  author={Liu, Haohe and Chen, Ke and Tian, Qiao and Wang, Wenwu and Plumbley, Mark D},
  journal={arXiv preprint arXiv:2309.07314},
  year={2023}
}
1 maintainer

Metadata
1 maintainer
Release files for audiosr 0.0.7
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| audiosr-0.0.7.tar.gz | 2.9 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| audiosr-0.0.7-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 5.8 MB
Release files / audiosr-0.0.7.tar.gz
| Download URL | audiosr-0.0.7.tar.gz |
|---|---|
| Size | 2.9 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
6e272a00f6dfbb4ae7b749b8cc6c90f58e0f4aaf2f96ae7b1e5f58ddb8c75803
|
|
BLAKE2b-256 checksum How to use checksums |
64e578b6385ae7156697a3d04cf7e8fbb894f11ab8a95ebf6dd70bd4f49307ee
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.2 CPython/3.9.18
|
Release files / audiosr-0.0.7-py3-none-any.whl
| Download URL | audiosr-0.0.7-py3-none-any.whl |
|---|---|
| Size | 2.9 MB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
05794f995ab42458216eb302dd9768c1c1e535091ee54e9e09f69a60eaad96e2
|
|
BLAKE2b-256 checksum How to use checksums |
7e12e53ffbe19d52d544ab7bcc4f1e0a691fd6ed5e4dc342ebc5a30fcbe519bf
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.2 CPython/3.9.18
|














