
Bare Agent
Own the loop, not the framework.
A framework-free agent runtime you can read, run, and leave — a small library you
import and call, plus a visual studio that ejects to plain Python with zero dependency on us.


Why stateless? • Features • Quickstart • Studio • How it works • Eject • Configuration • Development
Most agent frameworks own your main(), hide control flow behind metaclasses and DAG executors, and obscure the actual prompts. bare-agent is the opposite: a small library — the agent loop, a tool registry, a 3-axis budget, and a LiteLLM gateway, ~600 readable lines — that you import and call. You own the loop. Every prompt is in plain sight. You can always eject to plain Python and run it with zero bare_agent dependency.
On top of the library sits an optional visual studio: wire agents into a chain on a canvas, attach tools, Run and watch tokens stream live, then eject the whole flow to a self-contained agent.py. Local-first — it runs at zero cost on Ollama; OpenAI, Anthropic, and Gemini are optional drop-ins through the same loop.
Built on Python 3.12 · LiteLLM · FastAPI · Next.js 16 — with no agent framework (no LangChain/LangGraph).
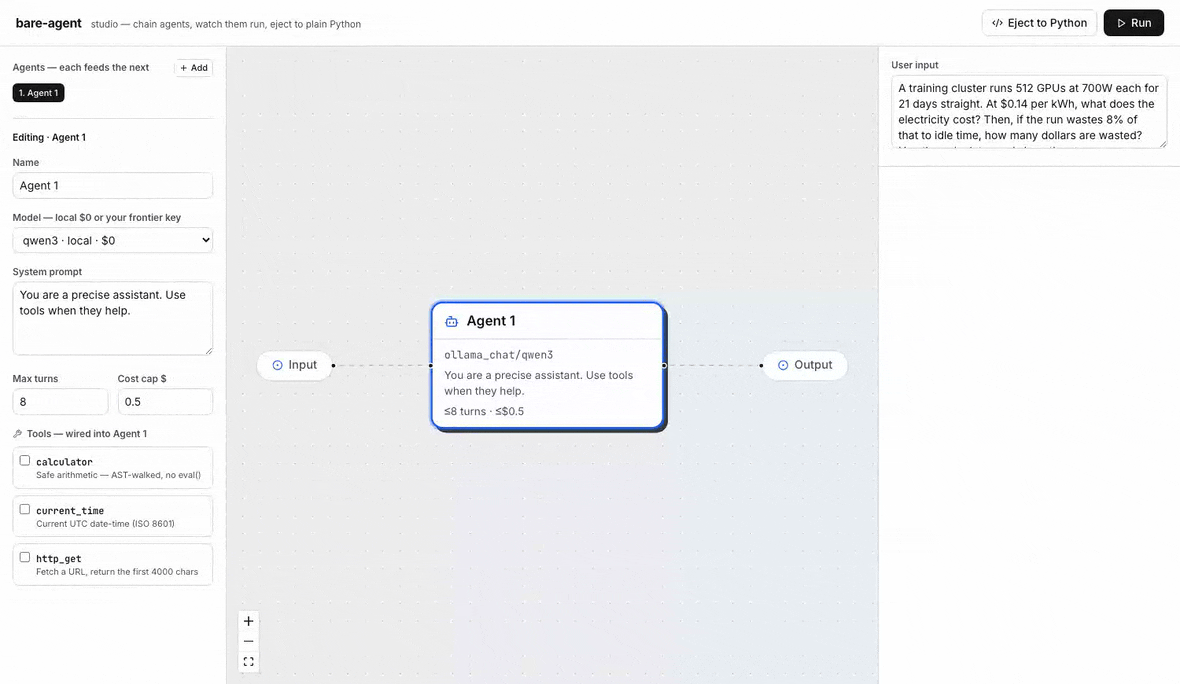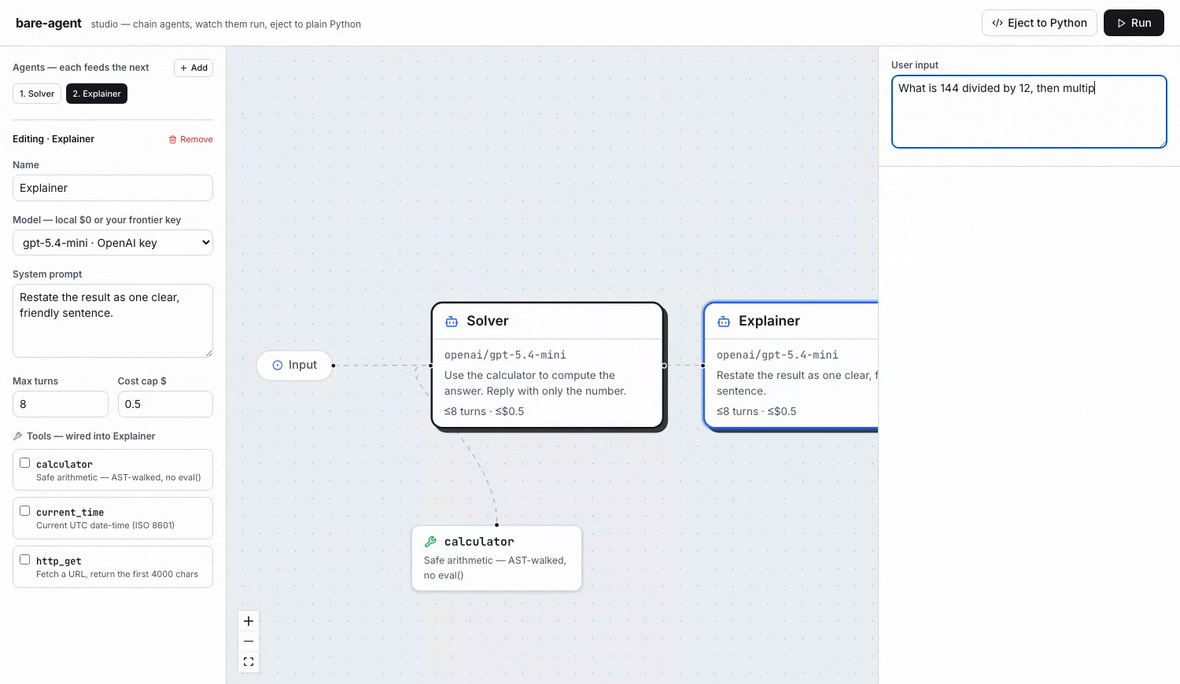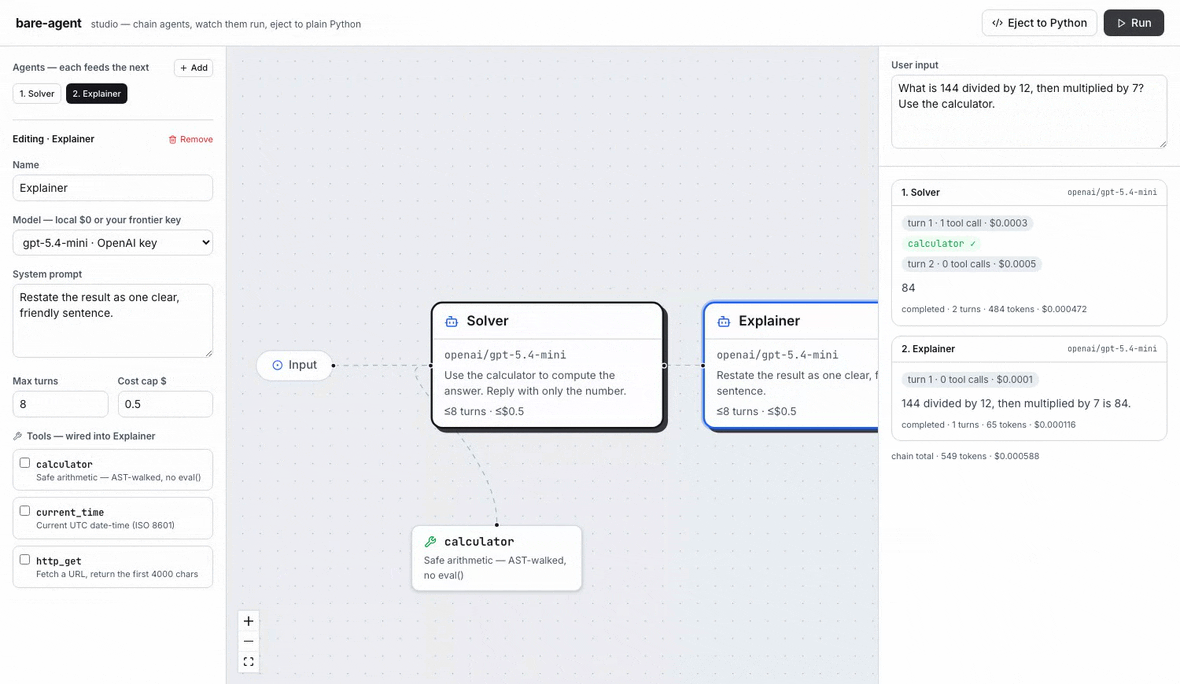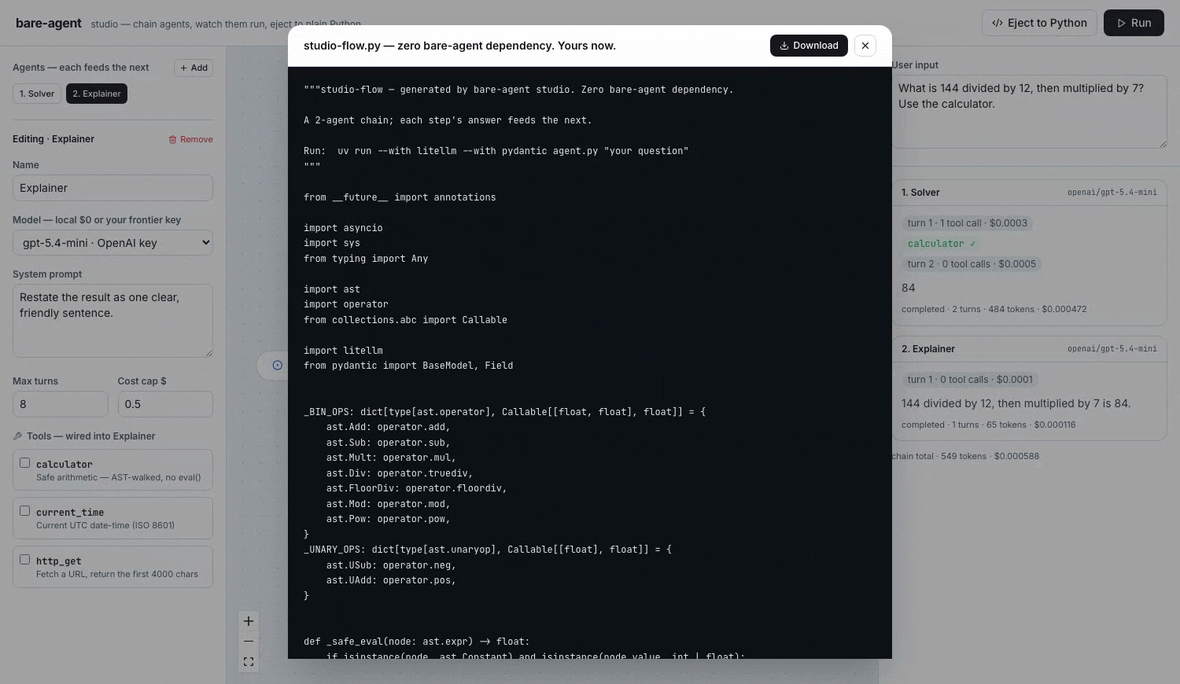
The studio, end to end: chain a Solver and an Explainer, attach the calculator, Run and watch each agent stream its turns, tool calls, and tokens live — with real per-call cost attribution (here on gpt-5.4-mini, ~$0.0006 for the whole chain) — then Eject to Python, a self-contained agent.py with zero bare_agent dependency. The same loop runs local-first on Ollama at $0.
Why stateless?
The agent loop is a stateless reducer over an explicit messages: list[dict]. This is the most important design decision in the library, and it was made deliberately. Here is what it costs (nothing) and what it pays (three things):
The cost: you pass the messages list explicitly. There is no magic session object accumulating state behind the scenes.
What you get for free:
1. Testability without a live LLM
Feed a canned messages list and a fake CompletionClient — assert on the result. Every one of the 29 tests runs hermetically: no Ollama daemon, no Redis, no LLM API key required. The test suite is a CI gate, not a flaky integration smoke.
# How the test suite works — no real LLM
agent = AgentLoop(
    registry=registry,
    llm=FakeCompletionClient(responses=["The answer is 42."]),
    budget=Budget(max_turns=3),
    system_prompt="You are a test agent.",
)
result = await agent.run("What is 6 × 7?")
assert result.answer == "The answer is 42."
assert result.stop_reason == "completed"
2. Durability for free
The messages list is a plain Python list of dicts — JSON-serializable by construction. Checkpoint it to Postgres (or a file) after each turn. If the process crashes, deserialize and resume from the last checkpointed step. No workflow engine required. This is the same pattern that Argus uses for DBOS durable execution.
3. Eject-to-code is honest
"Eject to plain Python" works because the list is the program — there was never a framework underneath to lift out. The compiled agent.py is not a snapshot of framework state; it is a literal transcription of the loop, with tool sources inlined verbatim. You can read it, diff it, and run it after you stop using bare-agent entirely. That is the point.
What this means in practice: no metaclass magic, no hidden DAG executor, no god-object to subclass, no state trapped in a session. Extensibility is composition — AgentLoop(llm=..., approver=..., registry=...) — not inheritance.
Features
| Capability | Detail |
|---|---|
| Framework-free agent loop | A hand-written tool-use loop over LiteLLM with a 4-axis budget (turns / tokens / wall-clock / cost) plus a configurable cycle guard, a retry/fallback ladder, and a self-registering, permission-gated tool registry. |
| Local-first, $0 — or BYO frontier key | Every call goes through LiteLLM, so the model id picks the provider. ollama_chat/qwen3 runs free and offline; anthropic/…, openai/…, gemini/… are drop-ins. No lock-in. |
| Multi-agent chains | Wire agents agent→agent; the runtime topologically orders them and feeds each answer into the next. Inline runs, queued runs, and ejected code all execute the same chain. |
| Visual studio | A React Flow canvas (Next.js 16 / React 19) to build chains, attach tools, and watch turns / tool calls / tokens stream live over SSE — one readable section per agent. |
| Eject to plain Python | Compile any graph to a standalone agent.py (litellm + pydantic only) — tool sources inlined, zero bare_agent import. Machine-checked to compile. |
| HITL / permissions | An Approver gates tool calls allow / ask / deny; successful tool output is wrapped <untrusted_tool_output> for prompt-injection containment. |
| Horizontal scale | An optional Redis-list job queue + worker pool; Kubernetes + KEDA scale workers 0→N→0 on queue depth — the same infrastructure pattern as Argus's searcher fan-out. |
| Composition, not configuration | Four seams, all Python Protocols — swap the model, the tools, the message format, or the event sink by passing a different object. No god-object to subclass. |
| Any provider's message shape | A Transcript decides how a turn is written into history. The default speaks Chat Completions; swap it for one that speaks the OpenAI Responses API, or anything else. |
| Tools that live behind a protocol | registry.register() takes a JSON Schema that arrived at runtime — MCP, OpenAPI, another agent — and lets the server that owns the tool do its own validation. |
The 8 primitives
Each is independently usable — not a god-object:
| # | Primitive | File |
|---|---|---|
| ① | Tool registry — @registry.tool() for local tools, register() for protocol-backed ones → permission-gated dispatch |
registry.py |
| ② | Prompt assembly — the explicit, serializable messages: list[dict], shaped by a Transcript |
transcript.py |
| ③ | Agent loop — AsyncExitStack + 4-axis budget + termination + cycle-stop |
loop.py |
| ④ | Retry / fallback over LiteLLM (local Ollama or any frontier model) | llm.py |
| ⑤ | State / memory — checkpoint the messages list (durability for free) |
loop.py |
| ⑥ | HITL / permissions — allow / ask / deny, an Approver on ask |
registry.py |
| ⑦ | Observability — structlog + an optional EventSink (SSE-ready) |
events.py |
| ⑧ | Eval gate — golden replay (roadmap) | — |
The four seams
Extensibility here is composition: you pass a different object, never set a flag on a
closed framework. Each seam is a duck-typed Protocol, so anything with the right methods
works — no base class to inherit.
| Seam | Protocol | Default | Swap it when |
|---|---|---|---|
| Model | CompletionClient |
LLMClient (LiteLLM) |
you need a provider LiteLLM doesn't cover, or its raw response |
| Tools | ToolRegistry |
@registry.tool() |
the tool lives behind a protocol → register() with the wire schema |
| Messages | Transcript |
ChatCompletionsTranscript |
the provider isn't Chat-Completions-shaped |
| Events | EventSink |
none | you want turns, reasoning, or tool calls on a UI |
Tools that live somewhere else
The decorator derives a tool's schema and its validation from a Python class, which only works for a tool defined in your own process. A tool reached over MCP, OpenAPI, or another agent is described by a schema that arrives at runtime and is validated by whoever owns it:
registry.register(
    name="get_dish_info",
    description="Look up one dish by exact name.",
    parameters=mcp_tool.input_schema,        # the schema as it came off the wire
    func=lambda arguments: session.call_tool("get_dish_info", arguments),
)
Such a tool publishes its schema verbatim and receives the raw argument dict — the registry does not re-validate it. That is deliberate: a local check would duplicate the remote's own validation and, worse, swallow the remote's error response, which is usually the thing the caller actually needs to see.
Providers that shape a turn differently
Chat Completions writes one assistant message carrying a tool_calls array. The OpenAI
Responses API writes the same turn as N+1 separate items. A Transcript owns that
difference, so the loop never has to know:
class ResponsesTranscript:
    def seed(self, system_prompt: str, user_input: str) -> list[dict]:
        return [{"role": "user", "content": user_input}]   # system travels out of band

    def assistant_message(self, response: LLMResponse) -> list[dict]:
        ...   # one message item + one function_call item per call

    def tool_message(self, call: ToolCallRequest, result: ToolResult) -> dict:
        ...   # {"type": "function_call_output", "call_id": ..., "output": ...}

agent = AgentLoop(..., transcript=ResponsesTranscript())
The loop decides when to append; the transcript decides what is appended — including
the <untrusted_tool_output> fence, so a transcript can choose a different containment
strategy.
Governing the run
Budget is the one thing that is a value rather than a seam:
Budget(
    max_turns=4,
    max_tokens=1_000_000,
    max_wallclock_s=120.0,
    max_cost_usd=1.0,
    max_identical_calls=0,   # 0 disables the cycle guard; the other axes still terminate
)
max_identical_calls stops a run that keeps making the same call with the same arguments.
It defaults to 3. Set it to 0 when you want termination to depend only on turn count —
a demo that must stop after a predictable number of rounds, say.
Seeing what the model thought
LLMResponse.reasoning carries a reasoning model's summary when the provider returns one.
It is kept out of answer — it exists to be shown to a human, never replayed to the model
as though it were part of the conversation. The loop emits it as a reasoning event:
async def sink(event):
    if event.kind == "reasoning":
        print(event.data["text"])

await agent.run("...", on_event=sink)
Quickstart
pip install bare-agent # or: uv add bare-agent
A complete agent in ~30 lines — the docstring becomes the LLM's tool description:
import asyncio
from pydantic import BaseModel, Field
from bare_agent import AgentLoop, Budget, LLMClient, ToolRegistry, get_settings

registry = ToolRegistry()

class AddArgs(BaseModel):
    a: int = Field(description="first addend")
    b: int = Field(description="second addend")

@registry.tool()
async def add(args: AddArgs) -> int:
    """Add two integers and return their sum."""
    return args.a + args.b

async def main() -> None:
    settings = get_settings()          # local Ollama by default; set BARE_AGENT_MODEL for frontier
    agent = AgentLoop(
        registry=registry,
        llm=LLMClient.from_settings(settings),
        budget=Budget.from_settings(settings),
        system_prompt="You are a precise assistant. Use tools for arithmetic.",
    )
    result = await agent.run("What is 17 + 25, then add 100 to that?")
    print(result.answer)               # -> "142"
    print(result.stop_reason, result.turns, f"${result.cost_usd}")  # -> completed 3 $0.0

asyncio.run(main())
Run it locally for free:
ollama pull qwen3        # one-time
make demo                # or: uv run python examples/quickstart.py
The studio
make web # FastAPI on :8000 + Next.js studio on :3000 → http://localhost:3000/studio
Open http://localhost:3000/studio: Add agents and wire them into a chain, attach catalog tools, pick a model (local qwen3 at $0 or your frontier key), and Run — each agent streams its turns, tool calls, and tokens live over SSE in its own section. The backend is standalone: make api runs the control plane alone, and the library works with no UI at all.
How it works
user input
   │
   ▼
┌──────────────┐   answer feeds   ┌──────────────┐
│   Agent 1    │ ───────────────► │   Agent 2    │ ──────────►  final answer
│  + tools     │   the next       │  + tools     │
└──────────────┘                  └──────────────┘
   each agent = ONE hand-written loop:
   explicit messages list · 4-axis budget + cycle guard · permission-gated tool dispatch

   run it:   inline over SSE      ·  or  queue → worker pool → KEDA scales 0→N→0
   keep it:  Eject ──► agent.py   (litellm + pydantic only — ZERO bare_agent dependency)
Eject
Any flow — single agent or a chain — compiles to a standalone script that imports only litellm and pydantic. Tool sources are inlined verbatim; there is no bare_agent import:
uv run --with litellm --with pydantic agent.py "your question"
In the studio, Eject to Python shows the generated code and downloads it. The generated file is machine-checked to compile. You can read it, diff it, vendor it, and run it after you stop using bare-agent entirely.
Configuration
Settings are read by Pydantic Settings from the environment (BARE_AGENT_ prefix) or .env.
| Variable | Default | Purpose |
|---|---|---|
BARE_AGENT_MODEL |
ollama_chat/qwen3 |
LiteLLM model id. Local Ollama by default; anthropic/…, openai/…, gemini/… for hosted. |
BARE_AGENT_OLLAMA_BASE_URL |
http://localhost:11434 |
Ollama server, passed as api_base for ollama_chat/ models. |
BARE_AGENT_FALLBACK_MODELS |
[] |
Ordered fallback model ids (JSON list) for the retry ladder. |
BARE_AGENT_MAX_TURNS / …_TOKENS / …_WALLCLOCK_S / …_COST_USD |
8 / 120000 / 180 / 0.50 |
The 4-axis budget; the loop stops on the first to trip. |
BARE_AGENT_USE_QUEUE |
false |
Route runs through the Redis queue + worker pool (KEDA-autoscalable) instead of inline. |
BARE_AGENT_REDIS_URL |
redis://localhost:6379/0 |
Redis DSN for the run queue + event pub/sub (queue mode). |
For a hosted model, set BARE_AGENT_MODEL=anthropic/… and export that provider's key (ANTHROPIC_API_KEY, OPENAI_API_KEY, GEMINI_API_KEY).
Development
make ci          # lock-check + format-check + lint (ruff) + compile + typecheck (ty) + tests (pytest)
make test        # the 29-test suite — hermetic (LLM and Redis are faked; no daemon needed)
make web         # backend + studio together for local hacking
make up / down   # the Docker stack (api + studio; Ollama stays on the host)
make queue-up    # the Docker stack WITH the KEDA-shaped worker plane (+ redis + worker)
make help        # all targets
Kubernetes manifests live in k8s/ — an inline deploy (api + studio) and the KEDA worker plane (redis + worker). The studio has its own toolchain (apps/studio/AGENTS.md); the canonical agent rules for the whole repo are in AGENTS.md.
License
MIT © 2026 Subrata Mondal — see LICENSE. Built as the clean, reusable extraction of Argus's agent runtime.
1 maintainer

Metadata
1 maintainer
Release files for bare-agent 0.0.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| bare_agent-0.0.2.tar.gz | 18.0 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| bare_agent-0.0.2-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 38.8 kB
Release files / bare_agent-0.0.2.tar.gz
| Download URL | bare_agent-0.0.2.tar.gz |
|---|---|
| Size | 18.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
e206cbfb25467677ef16cc86dc56edd2f9d44fc793136a7b14d770709ec1a6f7
|
|
BLAKE2b-256 checksum How to use checksums |
e6255980bef0d48c4802fa27450cb27258de9b5b1f4136ee603db6c781c16c3c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
uv/0.12.13 {"installer":{"name":"uv","version":"0.12.13","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":true}
|
Release files / bare_agent-0.0.2-py3-none-any.whl
| Download URL | bare_agent-0.0.2-py3-none-any.whl |
|---|---|
| Size | 20.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
8578f43798bcc877be68d00e2077c155f1af95b2cb1ee2a13850743da24326c6
|
|
BLAKE2b-256 checksum How to use checksums |
0321e28515b5d3f0bf666875522d712800d9b0f06b5d7cb0dfa3d3df91d52acb
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
uv/0.12.13 {"installer":{"name":"uv","version":"0.12.13","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":true}
|














