
barem


Real-world Linux command examples, right in your terminal.
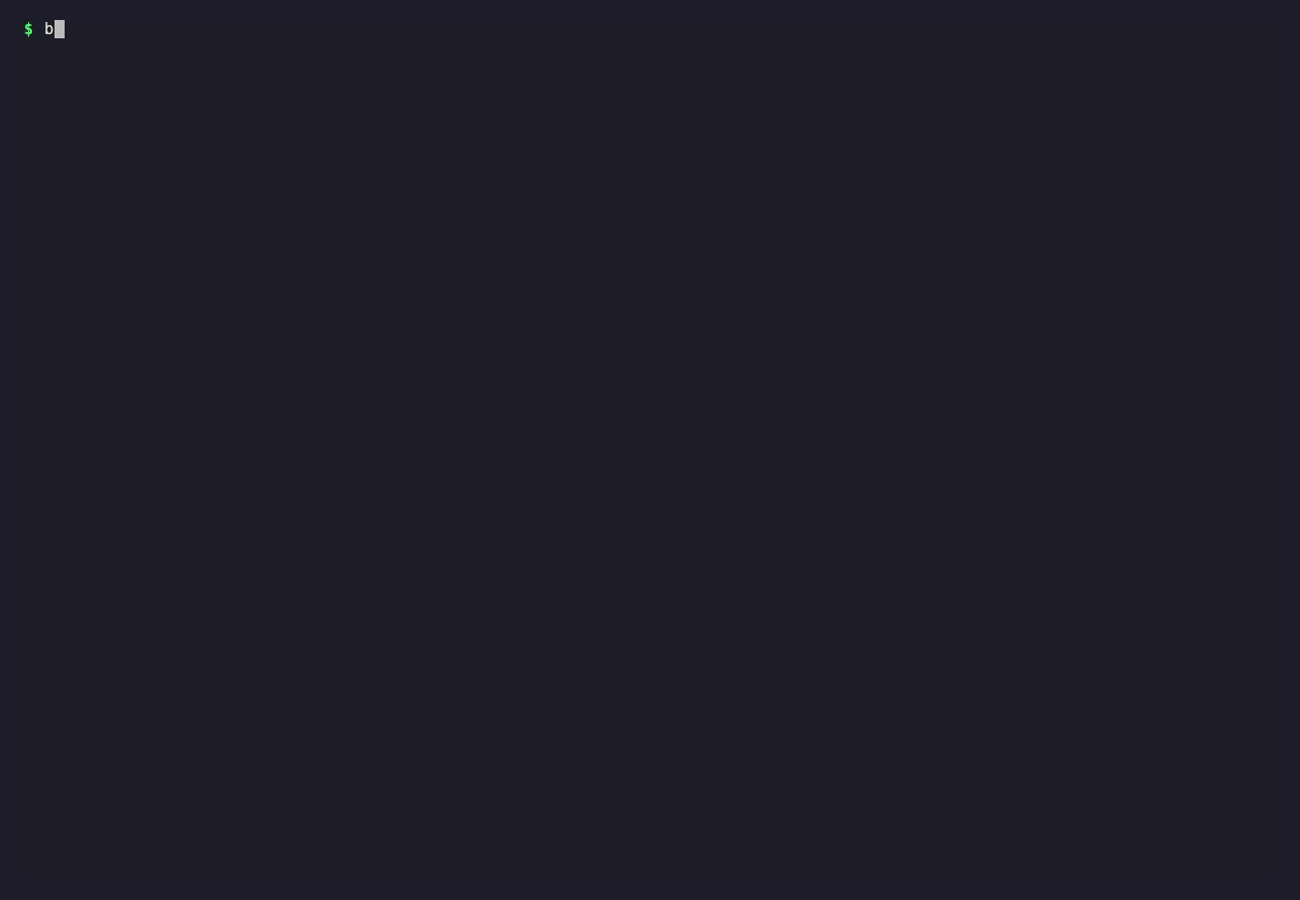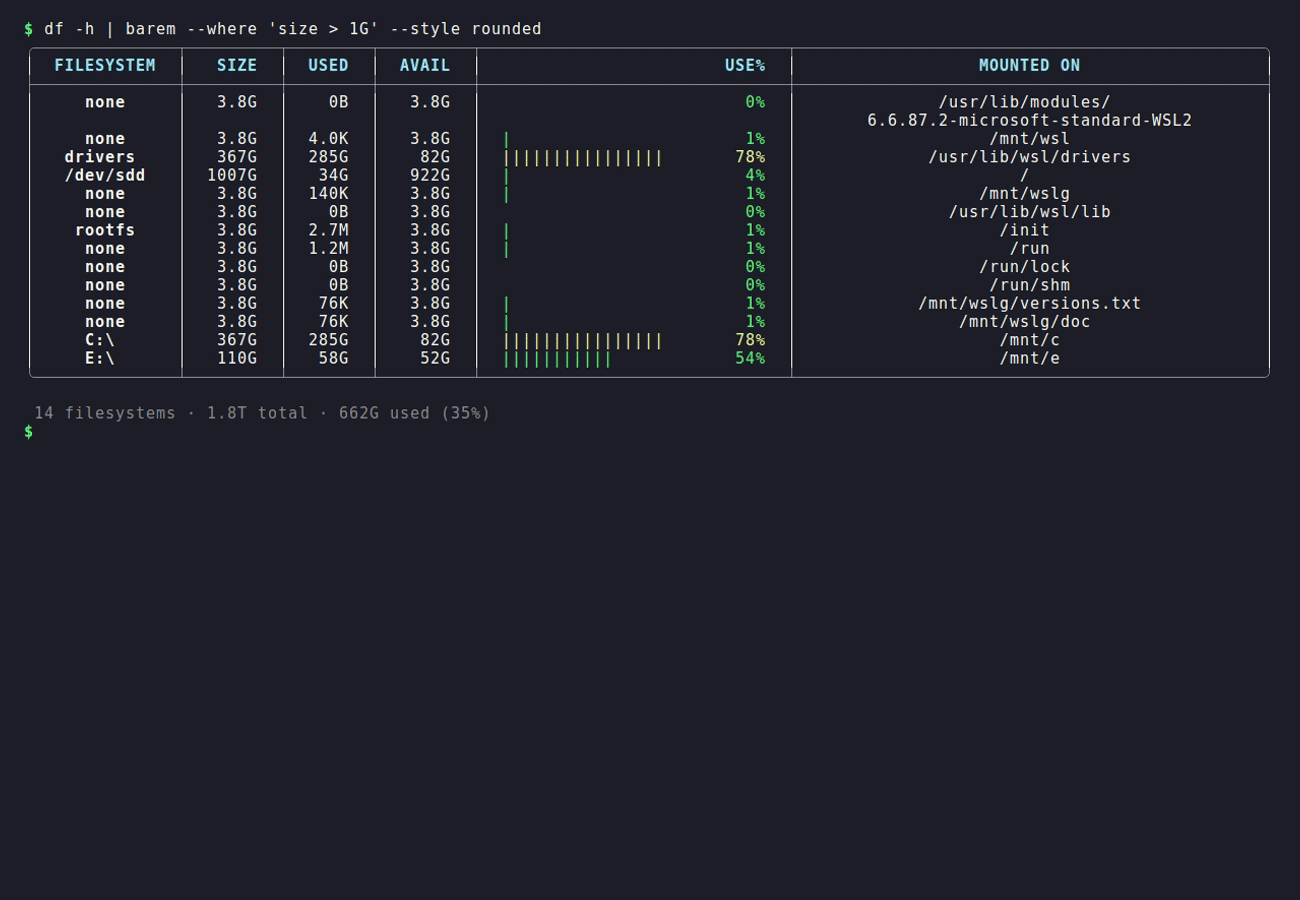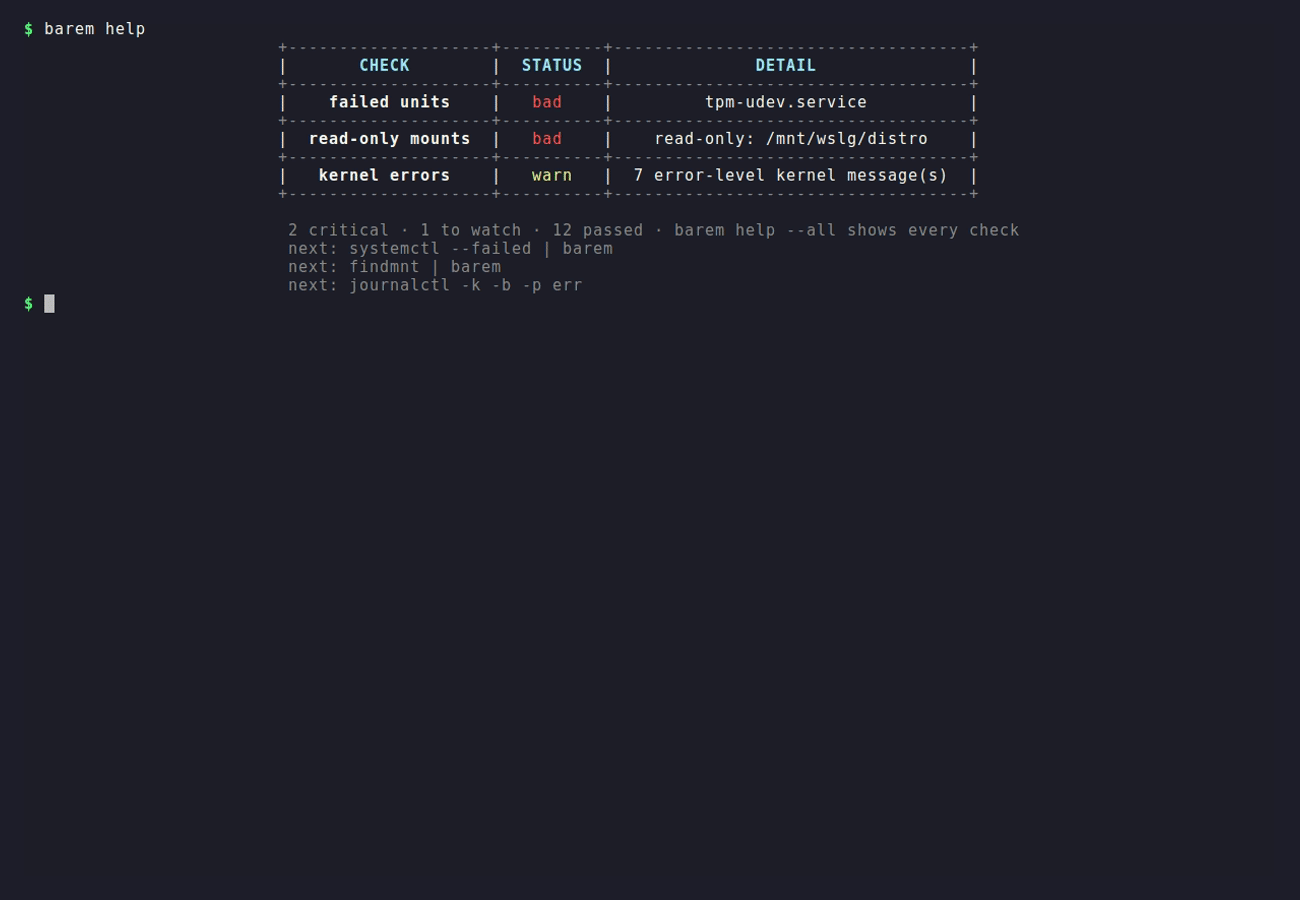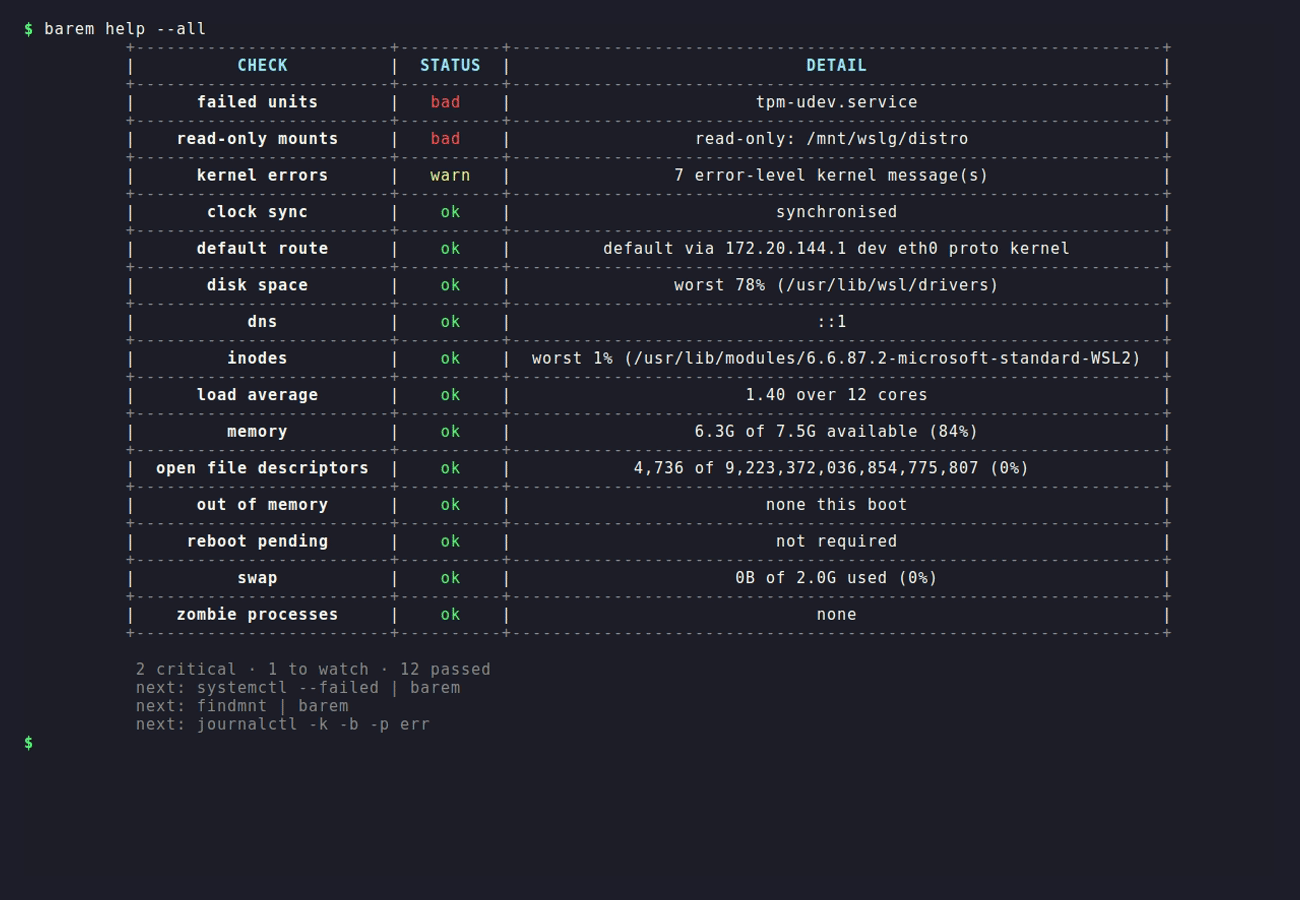
barem prints practical, copy-paste-ready examples for everyday Linux, networking and DevOps commands. Instead of scrolling through a long man page to remember how to exclude a folder in find, follow a service log in journalctl or forward a port with ssh, you ask:
$ barem find size
find - Search for files and directories by name, type, size, time and permissions

# Files bigger than 100 MB anywhere, hide permission errors
find / -type f -size +100M 2>/dev/null

# Files between 10 MB and 50 MB
find . -type f -size +10M -size -50M

# Stay on one filesystem (skip /proc, mounted disks)
find / -xdev -type f -size +500M 2>/dev/null
It currently ships 157 commands and 5,314 examples — about 30 per command, covering the options and flags you actually use at work.
Features
- Real-world examples: realistic file names, paths and hosts instead of
<placeholder>soup, ordered from the most common to the more advanced. - Description first, command second: every example is a
# descriptionline followed by the command, so it reads like a well-commented script. - Keyword filtering:
barem tar extractshows only the examples that mention "extract". - Search everything:
barem -s portsearches the examples of every command at once. - Tab completion: bash and zsh completion for command names, keywords and options, built from the example files that are installed.
- Table mode: pipe a command into
baremand it formats the output — bordered, aligned columns, usage bars, and a layout that adapts to your terminal width.df -h | barem - One-command triage:
barem helpruns the diagnostics you reach for first when something is off, and reports only what is actually wrong. - Grep-friendly:
--onelineprintscommand # descriptionon one line, and colors switch off automatically when output goes to a pipe or file. - Zero dependencies: standard library only, Python 3.9+.
- Easy to extend: adding a command means adding one plain text file.
Installation
You need Python 3.9+ and pipx. On Ubuntu/Debian:
sudo apt install pipx
pipx ensurepath        # then open a new terminal
Then:
pipx install barem
pipx creates an isolated virtual environment for the tool and puts the barem command on your
PATH, so it cannot collide with anything else you have installed.
pipx upgrade barem             # update
pipx install barem==1.0.0     # a specific version
pipx uninstall barem           # remove
pip install barem works too, inside a virtual environment.
From the repository
To run the unreleased main, or to try a change of your own:
pipx install git+https://github.com/Merab25/Barem.git
Note that pipx upgrade does not re-fetch a git install, so to move such an install forward
you reinstall it:
pipx uninstall barem && pipx install git+https://github.com/Merab25/Barem.git
Usage
| Command | What it does |
|---|---|
barem --help |
How the tool works, usage examples and all available commands |
barem find |
All examples for find |
barem find size |
Only find examples that mention "size" |
barem tar extract gz |
Several keywords: an example must match all of them |
barem -s port |
Search the examples of every command |
barem -l |
List commands with a summary and the number of examples |
barem grep -1 |
One example per line: command # description |
barem find --no-color |
Plain output (also NO_COLOR=1) |
barem -V |
Show the version |
barem --completion bash |
Print a completion script (also zsh) |
python -m barem find |
Same as barem find |
df -h | barem |
Format piped output as a table (see Table mode) |
barem --styles |
Show every border and percentage style with a sample |
barem run df -h |
Run the command, then format it |
barem help |
Run the diagnostics and report what is off (see barem help) |
Keywords are case-insensitive and match the start of a word: port finds "port", "ports" and --port, but not "export" or "report".
Using it with grep
The built-in keyword filter covers most cases, but the output is designed to work with standard tools too:
barem find -1 | grep perm          # one line per example, grep sees command + description
barem find | grep -A1 -i "delete"  # match a description, also print the command below it
barem find | grep -B1 "exec"       # match a command, also print its description above it
barem -s docker -1 | less          # page through a search
barem curl json -1 > curl-json.sh  # save examples as a commented script
Exit codes make it usable in scripts: 0 when examples were printed, 1 for an unknown command or no matches.
barem help
When something is off on a machine, the first few minutes are always the same handful of
commands: is the disk full, has memory gone, did a unit fail, is there a default route,
does DNS answer. barem help runs that list and reports only what is actually wrong.
$ barem help
+----------------+------+------+-------+-------------------------+------------+
|   FILESYSTEM   | SIZE | USED | AVAIL |                   USE%  | MOUNTED ON |
+----------------+------+------+-------+-------------------------+------------+
| /dev/nvme0n1p2 | 468G | 112G |  332G | ||||               25%  |     /      |
+----------------+------+------+-------+-------------------------+------------+
|   /dev/sdb1    | 1.8T | 1.7T |   43G | |||||||||||||||    95%! |   /data    |
+----------------+------+------+-------+-------------------------+------------+
| /dev/nvme0n1p1 | 512M |  62M |  450M | ||                 12%  | /boot/efi  |
+----------------+------+------+-------+-------------------------+------------+
|     tmpfs      |  16G | 2.1M |   16G | |                   1%  |    /run    |
+----------------+------+------+-------+-------------------------+------------+

 4 filesystems · 2.3T total · 1.8T used (80%)
On a healthy machine it says so in one line and shows nothing else:
$ barem help
 nothing wrong found · 15 passed · barem help --all shows every check
barem check and barem doctor do the same thing. Note that barem --help still prints
the usage text — the diagnosis is the bare word, the usage is the flag.
What it checks
Disk space and inodes, memory and swap, load against the core count, failed systemd units, read-only filesystems, OOM kills, kernel I/O errors, the default route, DNS, clock synchronisation, a pending reboot, zombie processes and open file descriptors.
Each one also carries the command worth running next, and the worst three are printed under the table.
Using it in a script
The exit code says what was found, so it drops into a cron job or a CI step:
| Code | Meaning |
|---|---|
0 |
nothing wrong |
1 |
warnings only |
2 |
something critical |
barem help || echo "check the machine"
barem help --all --format json          # every result, machine-readable
What it will not do
Every check is read-only, needs no root, and is given a four-second timeout, so running it
can never make a bad situation worse — a hung NFS mount cannot hang the diagnosis. A check
whose command is missing reports skipped rather than failing, which is what you get on a
container without systemctl or a system without journalctl.
Table mode
Pipe a command into barem and it formats the output instead of looking anything up:
$ df -h | barem
+----------------+------+------+-------+-------------------------+------------+
|   FILESYSTEM   | SIZE | USED | AVAIL |                   USE%  | MOUNTED ON |
+----------------+------+------+-------+-------------------------+------------+
| /dev/nvme0n1p2 | 468G | 112G |  332G | ||||               25%  |     /      |
+----------------+------+------+-------+-------------------------+------------+
|   /dev/sdb1    | 1.8T | 1.7T |   43G | |||||||||||||||    95%! |   /data    |
+----------------+------+------+-------+-------------------------+------------+
| /dev/nvme0n1p1 | 512M |  62M |  450M | ||                 12%  | /boot/efi  |
+----------------+------+------+-------+-------------------------+------------+
|     tmpfs      |  16G | 2.1M |   16G | |                   1%  |    /run    |
+----------------+------+------+-------+-------------------------+------------+

 4 filesystems · 2.3T total · 1.8T used (80%)
It works out which command produced the text, splits it into columns, decides what each column means — a size, a percentage, a status, a path — and lays it out to the width of your terminal. The commands stay the source of truth; this is only a nicer view of them.
df -i | barem                            # inode usage, with bars
ps aux | barem --sort -%mem --top 10     # replaces an awk and sort pipeline
ss -tlnp | barem                         # listening sockets, aligned
docker ps | barem --symbols              # ● up, ✖ exited
kubectl get pods | barem --where 'status ~ Crash'
free -h | barem --style rounded          # pick a border style
df -h | barem --pct dots --pad 2         # pick a percentage style and more spacing
mount | barem --format md                # a Markdown table
barem run --watch 2 df -h                # re-run and redraw every 2 seconds
Options
| Flag | Effect |
|---|---|
--as df |
Force a profile; --profiles lists them |
--sort use% / --sort -size |
Sort by a column, - for descending, by real value not by text |
--top 10 |
Keep the first N rows after sorting |
--cols fs,use%,target |
Choose and order columns |
--where 'use% > 80' |
Keep matching rows; also < >= <= == != ~ (regex) |
--format md|csv|tsv|json |
Export instead of rendering |
--style NAME |
Border style; barem --styles shows all nine with a sample |
--pct NAME |
How percentages are drawn; barem --styles shows all seven |
--pad N |
Spaces inside each cell, either side (default 1) |
--no-wrap |
Cut a value that does not fit instead of wrapping it |
--clean / --cards / --ascii |
Shorthand for --style clean, --style cards, no Unicode |
--width N / --max-width N |
Assume a width, or cap it (BAREM_WIDTH also works) |
--no-bars / --bar-width N |
Numbers without bars, or a different bar size |
--warn 80 --crit 95 |
Move the thresholds; 90% is critical for a disk, normal for a CPU |
--symbols |
Add ●, ◐, ✖ to status cells |
--relative |
Durations as "3 min ago" rather than "3m" |
--input csv |
Force the input format instead of detecting it |
--no-summary / --raw |
Drop the line under the table / print the input untouched |
barem run CMD |
Run the command, so its name is known for certain |
--watch 2 |
With run, re-run and redraw in place |
Picking a look
barem --styles renders the same table in every style so you can choose by eye. Nine
border styles:
--style |
What it draws |
|---|---|
box |
square corners, a line under the header |
rounded |
as box, with rounded corners |
double |
double lines, the heaviest look |
grid |
a line between every row, for tables you read across |
dashes |
plain +---+ and |, works on any terminal |
dashes-grid |
as dashes, with a line between every row — the default |
simple |
column lines and a header rule, no frame |
clean |
no lines but a rule under the header |
minimal |
nothing but aligned columns |
And eight ways to draw a percentage:
--pct pipes    |||||                  25%      upright pipes with nothing behind them   (the default)
--pct blocks   █████░░░░░░░░░░░░░░░   25%      solid blocks, accurate to an eighth of a cell
--pct shade    ▓▓▓▓▓░░░░░░░░░░░░░░░   25%      a shaded track, quieter than solid blocks
--pct bracket  [#####...............]   25%    a bracketed meter, [####....]
--pct dots     ●●●●●○○○○○○○○○○○○○○○   25%      filled and hollow dots
--pct line     ━━━━━┄┄┄┄┄┄┄┄┄┄┄┄┄┄┄   25%      a simple rule, drawn and undrawn
--pct ticks    |||||...............   25%      as pipes, on a dotted track
--pct number   25%                             the number on its own, no bar
A percentage is drawn as 20 upright pipes by default, with nothing behind them, so a
glance down the column shows which rows are full. --pct picks another of the eight
looks. The bar is 20 cells long; --bar-width N changes it, --pad N the spacing inside
every cell, --row-gap N blank lines between rows, and --left turns off the centring.
A long bar and a roomy cell are the first things given up when the window is narrow: at 80 columns the bar shortens and the padding tightens by itself rather than a column being dropped, so you still see everything.
How it adapts
Nothing in the output is fixed to 80 columns, and nothing is thrown away. As the window
narrows the table gives things up in the order that keeps the most useful information
longest: text columns shrink (wrapping, never cutting), then the bars go, then whole
columns are dropped — and dropped ones are named under the table so you know to ask for
them with --cols. Below about 50 columns a table cannot work at all, so each row
becomes a small block instead:
 /dev/sdb1
   Size        1.8T
   Used        1.7T
   Avail       43G
   Use%        95%!  █████████▌
   Mounted On  /data
The column that names the row is never dropped, and it keeps its full width until the
layout has run out of columns it could drop instead — giving up a column you can ask
back with --cols beats wrapping every name across two lines. Numbers are never
wrapped or cut either.
Reading the output
- Borders by default, because they make the columns unmissable: a
+---+frame with a rule between every row, padded so the rows have room to breathe, and the whole table sits in the middle of the window.--stylepicks another of the nine looks,--stylesshows them all,--pad Nand--row-gap Nchange the spacing, and--leftputs the table back on the margin. - Column names are bold and bright while the frame stays dim, so the names and the numbers are what your eye lands on rather than the grid around them.
- Nothing is cropped. A value too wide for its column is wrapped onto as many lines as it
needs, breaking at spaces first and then after
/ , ; : =so a path still reads as a path.--no-wrapgoes back to cutting with an…. - The row's name stands out: the identifying column is emphasised, and it is the last thing the layout narrows, so a name is not wrapped to save a cell somewhere less important.
- Text is centred, numbers right-aligned, so digits still line up where the eye expects them.
- Colour is never the only signal. A critical value is also marked
!whenever colour is off, so the output reads the same in a log file, underNO_COLOR, and for a colourblind reader. - Values above 100% keep their real number (
psreports 340% for a multi-threaded process) while the bar clamps at full. - If anything cannot be parsed, the input is printed unchanged. A formatting tool must never be the reason you cannot read your disk usage.
Known commands
Profiles give correct column types without --as: df, df -i, lsblk, lsblk -f,
findmnt, ps aux, ps -ef, free, ss, netstat, ip -br a, docker ps,
docker images, kubectl get pods, kubectl get nodes, systemctl list-units,
systemctl list-unit-files and systemctl list-timers.
Anything else still works: column types are inferred from the data, which is the path
that runs for every command nobody wrote a profile for. JSON, JSON lines, CSV, TSV and
key=value input are detected automatically, so ip -j addr | barem and
cat /etc/os-release | barem both do something sensible.
Add your own profiles as small Python modules in ~/.config/barem/profiles/,
each exposing a PROFILE.
Shell completion
barem --completion bash and barem --completion zsh print a completion script. Install it once:
# bash
mkdir -p ~/.local/share/bash-completion/completions
barem --completion bash > ~/.local/share/bash-completion/completions/barem

# zsh, into any directory on your $fpath
barem --completion zsh > "${fpath[1]}/_barem"
rm -f ~/.zcompdump && compinit
Open a new terminal, and TAB completes command names, keywords and options:
$ barem doc<TAB>        # docker
$ barem git reb<TAB>    # rebase
$ barem tar extr<TAB>   # extract  extracting
$ barem --no<TAB>       # --no-color
Candidates come from the example files that are installed rather than from a list baked into the script, so a command or keyword you add is completed without regenerating anything. A keyword already on the line is not offered again.
To try it in the current shell only, without installing:
source <(barem --completion bash)
Available commands
Files and directories
| Command | Examples | What it covers |
|---|---|---|
ls |
32 | List directory contents with details, sorting and filtering |
cp |
30 | Copy files and directories, with backups, preserving attributes |
mv |
29 | Move and rename files and directories |
rm |
29 | Delete files and directories, by name, pattern or age |
ln |
30 | Create hard links and symbolic links |
mkdir |
29 | Create directories, including whole paths at once |
touch |
31 | Create empty files and update timestamps |
find |
37 | Search for files and directories by name, type, size, time and permissions |
tree |
34 | Show a directory as an indented tree |
stat |
29 | Show detailed file metadata: size, permissions, owner and timestamps |
file |
32 | Identify what a file actually is, whatever its name says |
realpath |
32 | Resolve paths, and split them into directory and file name |
du |
30 | Show disk usage of files and directories |
df |
32 | Show free and used disk space per filesystem |
chmod |
30 | Change file and directory permissions |
chown |
31 | Change file ownership and group |
chattr |
33 | Set filesystem attributes, including making a file immutable |
tar |
31 | Create, list and extract archives (.tar, .tar.gz, .tar.bz2, .tar.xz, .tar.zst) |
Text processing
| Command | Examples | What it covers |
|---|---|---|
cat |
32 | Print files, join them together and create small files |
less |
32 | Page through files and command output without loading it all |
grep |
32 | Search text for lines matching patterns |
rg |
38 | ripgrep: fast recursive search that respects .gitignore |
sed |
33 | Stream editor: find and replace, delete, insert and transform text |
awk |
31 | Process text column by column: filter, sum, count and reformat |
sort |
32 | Sort lines of text by alphabet, numbers, columns, versions and more |
uniq |
30 | Report or filter repeated lines in sorted input |
cut |
31 | Extract columns and character ranges from each line |
tr |
31 | Translate, squeeze and delete characters |
head |
29 | Show the first lines or bytes of a file |
tail |
30 | Show the last lines of a file, and follow a growing log |
wc |
31 | Count lines, words, characters and bytes |
diff |
33 | Compare files and directories line by line |
comm |
32 | Compare two sorted files line by line |
join |
31 | Join two files on a shared key column, like an SQL join |
column |
32 | Line up text into readable columns |
paste |
31 | Merge lines from files side by side, or fold a list into one line |
nl |
33 | Number the lines of a file |
split |
31 | Split a large file into smaller pieces |
iconv |
32 | Convert text between character encodings |
strings |
33 | Pull readable text out of binary files |
xxd |
33 | Dump and patch files in hexadecimal |
tee |
30 | Write standard input to a file and pass it on |
xargs |
30 | Build and run commands from standard input |
jq |
35 | Query, filter and transform JSON on the command line |
yq |
35 | Query and edit YAML, JSON and TOML on the command line |
base64 |
32 | Encode and decode base64 |
Archives and compression
| Command | Examples | What it covers |
|---|---|---|
zip |
31 | Create and update .zip archives |
unzip |
32 | List, test and extract .zip archives |
gzip |
32 | Compress and decompress single files with gzip |
xz |
33 | Compress and decompress with xz, for the smallest archives |
Processes and system
| Command | Examples | What it covers |
|---|---|---|
ps |
32 | Show running processes with CPU, memory, owner and command |
top |
32 | Watch processes, CPU and memory in real time |
kill |
32 | Send signals to processes by PID |
pkill |
32 | Find and signal processes by name, user, age or command line |
htop |
34 | Interactive process viewer with sorting, filtering and tree view |
lsof |
30 | List open files, network sockets and the processes that use them |
strace |
33 | Trace system calls and signals to see what a process really does |
nohup |
31 | Keep a command running after you log out |
nice |
32 | Run work at lower or higher priority, for CPU and for disk |
free |
33 | Show memory and swap usage |
vmstat |
32 | Sample CPU, memory, swap and IO activity over time |
iostat |
33 | Measure disk throughput, latency and utilisation |
sar |
36 | Read historical and live system activity from sysstat |
uname |
36 | Show kernel, architecture and system information |
lscpu |
35 | Show CPU architecture, cores, cache and flags |
lsmod |
35 | List and manage kernel modules |
sysctl |
36 | Read and set kernel parameters at runtime and at boot |
mount |
32 | Mount and unmount filesystems, and inspect what is mounted |
dmesg |
33 | Read the kernel ring buffer: boot, hardware and driver messages |
watch |
31 | Re-run a command periodically and watch the output change |
systemctl |
33 | Control systemd services, boot targets and timers |
journalctl |
33 | Read and filter systemd journal logs |
logrotate |
30 | Rotate, compress and expire log files |
hostnamectl |
34 | Read and change the system hostname and machine metadata |
timedatectl |
34 | Set the time, timezone and clock synchronisation |
crontab |
32 | Schedule recurring jobs with cron (fields: minute hour day month weekday) |
at |
35 | Schedule a command to run once, at a given time |
date |
33 | Show, format and calculate dates and times |
tmux |
35 | Terminal multiplexer: sessions that survive disconnects, windows and panes |
screen |
34 | Terminal sessions that survive a dropped connection |
Shell and environment
| Command | Examples | What it covers |
|---|---|---|
echo |
33 | Print text, and the pitfalls worth knowing |
printf |
35 | Print formatted text, portably and predictably |
seq |
34 | Generate sequences of numbers |
shuf |
32 | Shuffle lines and pick random samples |
env |
34 | Show and set environment variables for a command |
which |
34 | Find out which command will run, and where it lives |
time |
31 | Measure how long a command takes |
timeout |
32 | Put a time limit on a command |
Users and permissions
| Command | Examples | What it covers |
|---|---|---|
useradd |
36 | Create user accounts, home directories and groups |
passwd |
33 | Set and manage user passwords and account locking |
sudo |
33 | Run commands as another user, and inspect sudo rights |
id |
33 | Show who you are, your groups, and who else is logged in |
Packages
| Command | Examples | What it covers |
|---|---|---|
apt |
37 | Install, update and manage packages on Debian and Ubuntu |
dpkg |
35 | Query and manage Debian packages directly |
dnf |
39 | Install, update and query packages on Fedora, RHEL and Rocky |
snap |
38 | Install and manage snap packages on Ubuntu |
Editors
| Command | Examples | What it covers |
|---|---|---|
vim |
35 | Open, find and edit files with vim from the command line |
nano |
37 | Edit files with nano, the editor that tells you its own shortcuts |
Disks and filesystems
| Command | Examples | What it covers |
|---|---|---|
dd |
32 | Copy and convert data block by block, for disks and images |
lsblk |
33 | List block devices, partitions and what they hold |
fdisk |
33 | Inspect and edit partition tables |
parted |
34 | Partition disks, including those larger than 2 TB |
mkfs |
33 | Create filesystems on partitions and images |
fsck |
35 | Check and repair filesystems |
blkid |
34 | Find filesystem UUIDs, labels and types |
ncdu |
33 | Explore disk usage interactively and find what is filling a disk |
smartctl |
34 | Read disk health and run self-tests with SMART |
Networking
| Command | Examples | What it covers |
|---|---|---|
ip |
32 | Show and manage network interfaces, IP addresses, routes and ARP |
nmcli |
38 | Manage network connections with NetworkManager |
ss |
31 | Inspect network sockets and connections (modern netstat) |
netstat |
35 | Inspect sockets, routes and interface counters (legacy; prefer ss) |
ping |
31 | Test whether a host answers, and measure round-trip time |
traceroute |
32 | Show the network path packets take to a host |
mtr |
34 | Trace the route to a host and watch latency and loss per hop |
dig |
30 | DNS lookups: records, resolvers, propagation and debugging |
host |
35 | Quick DNS lookups: names, addresses and mail servers |
whois |
33 | Look up domain and IP registration details |
nc |
30 | Netcat: test ports, send raw TCP/UDP data, move files (OpenBSD netcat) |
socat |
34 | Relay data between almost any two endpoints |
curl |
35 | Transfer data with URLs: HTTP requests, REST APIs and downloads |
wget |
31 | Non-interactive downloader: files, resumable downloads, website mirrors |
ssh |
34 | Secure shell: remote login, remote commands, keys and tunnels |
scp |
31 | Copy files to and from remote hosts over SSH |
sftp |
33 | Transfer files interactively over SSH |
rsync |
31 | Fast incremental sync of files, locally or over SSH |
nmap |
30 | Network scanner: hosts, ports, services (scan only networks you own or may test) |
tcpdump |
32 | Capture and inspect network packets |
iptables |
34 | Configure the Linux firewall (netfilter) for IPv4 |
Security
| Command | Examples | What it covers |
|---|---|---|
openssl |
34 | TLS certificates, keys, CSRs, hashing, random data and encryption |
ssh-keygen |
34 | Create, inspect and manage SSH keys |
gpg |
35 | Encrypt, decrypt, sign and verify with GnuPG |
sha256sum |
31 | Compute and verify checksums |
certbot |
33 | Get and renew Let's Encrypt TLS certificates |
setfacl |
33 | Grant fine-grained permissions with access control lists |
ufw |
36 | Manage the uncomplicated firewall on Ubuntu and Debian |
nft |
41 | Configure the nftables firewall, the successor to iptables |
firewall-cmd |
39 | Manage firewalld on Fedora, RHEL and Rocky |
fail2ban-client |
37 | Inspect and control fail2ban bans |
DevOps and cloud
| Command | Examples | What it covers |
|---|---|---|
git |
44 | Version control: commits, branches, history, remotes and undo |
gh |
43 | GitHub from the terminal: repos, pull requests, issues and runs |
make |
36 | Build targets and run project tasks from a Makefile |
docker |
42 | Build, run and manage containers, images, volumes and Compose stacks |
podman |
46 | Run containers without a daemon, rootless by default |
kubectl |
42 | Manage Kubernetes clusters: pods, deployments, services, logs and rollouts |
helm |
41 | Install and manage Kubernetes applications with charts |
terraform |
38 | Infrastructure as code: plan, apply and manage cloud resources |
ansible |
37 | Run ad-hoc tasks and playbooks against your inventory |
aws |
38 | AWS CLI: S3, EC2, IAM, CloudWatch Logs, ECR, EKS and more |
gcloud |
46 | Manage Google Cloud from the terminal |
nginx |
34 | Test, reload and inspect the nginx web server |
Languages and package tools
| Command | Examples | What it covers |
|---|---|---|
python |
35 | Run Python, manage virtual environments and use its handy modules |
pip |
36 | Install and manage Python packages |
npm |
41 | Install and manage Node.js packages and run project scripts |
Databases
| Command | Examples | What it covers |
|---|---|---|
psql |
44 | Query and administer PostgreSQL from the terminal |
mysql |
41 | Query and administer MySQL and MariaDB from the terminal |
redis-cli |
50 | Inspect and operate a Redis server from the terminal |
sqlite3 |
42 | Query and manage SQLite database files |
Run barem -l for the live list.
Example file format
Each command is one text file in src/barem/examples/, named after the command (find.txt, docker.txt, ...):
## Search for files and directories by name, type, size, time and permissions

# Find files by exact name in the current directory tree
find . -name "config.yaml"

# Web permissions: 755 for directories, 644 for files
find /var/www -type d -exec chmod 755 {} +
find /var/www -type f -exec chmod 644 {} +
## ...on the first line is the one-line summary shown bybarem -l.# ...starts a new example with its description.- The following line(s) are the command. Several lines under one description belong to the same example.
- Blank lines are ignored.
Adding a command
- Create
src/barem/examples/<command>.txtusing the format above. - Aim for about 30 examples: the most common use first, then the important options, then advanced and combined usage.
- Use realistic values (
/var/log/nginx/access.log,user@server,192.168.1.10) instead of<file>placeholders, so examples can be copied and edited quickly. - Keep each command on one line.
- Run the tests. They check that every file has a summary, at least 20 examples, and that every command is valid shell syntax (
bash -n).
pytest
The new command shows up automatically in --list, --help, --search and tab completion; no code changes are needed.
Project structure
barem/
├── .github/
│   ├── workflows/ci.yml       # CI: lint, then build + install the wheel and test on 3.9-3.13
│   └── dependabot.yml         # keeps the pinned GitHub Actions current
├── src/barem/
│   ├── __init__.py            # package version (single source of truth)
│   ├── __main__.py            # enables `python -m barem`
│   ├── cli.py                 # argument parsing, file parsing, filtering, output, completion
│   ├── diagnose.py            # `barem help`: the first-try checks and how they are judged
│   ├── completions/           # the bash and zsh completion scripts, shipped too
│   ├── examples/              # one .txt file per command, shipped inside the package
│   └── table/                 # table mode, described in table-mode.md
│       ├── __init__.py        # format_text(text, options), the only public entry point
│       ├── width.py           # display_width, truncation, sanitizing: no other imports
│       ├── model.py           # Column, Kind, Align, Table, Profile
│       ├── humanize.py        # sizes, durations, and the parsers that let them sort
│       ├── styles.py          # the border and percentage style registries
│       ├── theme.py           # colours, thresholds, bars, the ASCII fallback
│       ├── detect.py          # input format detection and profile fingerprinting
│       ├── parse/             # columnar (by position), structured (json/csv), infer
│       ├── layout.py          # the fit / shrink / drop / cards algorithm
│       ├── render.py          # one bordered engine, plus cards, markdown, csv, json
│       ├── runner.py          # `barem run` and --watch
│       └── profiles/          # df, ps, ss, docker, kubectl, systemctl, ...
├── tests/
│   ├── test_cli.py            # parser, example files, CLI behaviour and completion
│   ├── test_docs.py           # the README's tables must match the example files
│   ├── test_table_*.py        # width, parsing, layout, rendering, CLI and golden files
│   ├── test_diagnose.py       # every check judged against real command output
│   ├── fixtures/              # real command output, so tests never run df or ps
│   └── golden/                # each fixture rendered at 40, 60, 80 and 120 columns
├── pyproject.toml             # package metadata, build backend, entry point, ruff config
├── .gitattributes             # keep the tree LF: the examples are read on Linux
├── .editorconfig
├── CHANGELOG.md
├── CONTRIBUTING.md
├── LICENSE
└── README.md
How it works
- Entry point:
pyproject.tomldeclaresbarem = "barem.cli:main"under[project.scripts]. When the package is installed, pip/pipx generate a smallbaremexecutable that callsmain(). - Bundled data: the example files live inside the package, so they are included in the wheel. At runtime
importlib.resourcesfinds them wherever the package was installed, instead of relying on hard-coded paths. - Parsing: each file is read line by line into
Example(description, commands)objects; filtering is a case-insensitive word-start match against the description and the commands. - Output: colors are ANSI escape codes, enabled only when stdout is a terminal (
sys.stdout.isatty()), so pipes, files and grep always get plain text. - Completion: the script printed by
--completionis a real file in the package, not a string built in Python. On every TAB it calls the hiddenbarem --complete <words>, which prints one candidate per line. That call is handled beforeargparseruns, because the words arrive half-typed (--no-c,-) andargparsewould try to read them as options. - Table mode: a command name always means the example lookup, so table mode starts only when standard input is a pipe, or when a table flag says so. Columns are found by character position rather than by
split(), because real output defeats splitting —dfhas aMounted onheader,ps auxholds a whole command line in one column, anddocker pshas both. Everything is measured in terminal cells, never characters, and colour is applied last so padding is never wrong by the length of an escape sequence. The design is written up in table-mode.md. - Isolation: pipx installs the tool in its own virtual environment, so it never conflicts with system Python packages.
- Versioning: the version is defined once in
src/barem/__init__.pyand read by the build backend (hatchling). A test checks thatCHANGELOG.mdhas a section for it and that the README's install line names the matching tag.
Development
git clone https://github.com/Merab25/Barem.git
cd Barem
python3 -m venv .venv
source .venv/bin/activate
pip install -e ".[dev]"    # editable install: code and example changes apply immediately

barem find             # try it
pytest                     # run the tests
ruff check .               # lint
ruff format .              # format
python -m build            # build the wheel and sdist into dist/
CI runs those same checks on Python 3.9 through 3.13, then installs the built wheel and smoke-tests the CLI and the generated bash completion script.
To use your local copy as your everyday command, install it with pipx in editable mode:
pipx install -e . --force
See CONTRIBUTING.md before opening a pull request, and CHANGELOG.md for what changed in each release.
Roadmap
- Publish to PyPI (
pipx install barem) - More commands:
go,cargo,node,gdb,lvm,iperf3,ethtool,az - Table profiles for the headerless commands:
du -sh *,last,lsof - Table mode: highlight cells that changed since the last
--watchrefresh - Georgian descriptions
Safety note
Some examples change or delete things (rm, find -delete, iptables -F, docker system prune, terraform destroy). Read a command before you run it. Only scan or capture traffic (nmap, tcpdump) on networks you own or have permission to test.
License
1 maintainer

Metadata
1 maintainer
Release files for barem 1.0.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| barem-1.0.0.tar.gz | 265.1 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| barem-1.0.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 535.9 kB
Release files / barem-1.0.0.tar.gz
| Download URL | barem-1.0.0.tar.gz |
|---|---|
| Size | 265.1 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
3be492ec58ca00dccb39855b64944ca0f5a4b778b665a2d0077a5fc49f9fe858
|
|
BLAKE2b-256 checksum How to use checksums |
fe21761545b9b8f9d0c26ee7af8020364b8f3299d68abce6f7c5be33221179da
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 7, 2026.
Transparency logRelease files / barem-1.0.0-py3-none-any.whl
| Download URL | barem-1.0.0-py3-none-any.whl |
|---|---|
| Size | 270.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
62acf4b7788d9665cf91b3719388dd150e9248acd7048caee117d32d3f4243a4
|
|
BLAKE2b-256 checksum How to use checksums |
2854fa595ef74fbe10dfc9418f09dab7b80531885da5a64948bbef2541dff391
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 7, 2026.
Transparency log













