
BASTION


A single-GPU safety broker for Ollama -- not a serving engine.
BASTION sits as a transparent HTTP proxy in front of Ollama on the standard port. It serializes model loads, enforces a VRAM budget, and queues requests by model affinity so a single GPU shared by several clients does not thrash. On my single RTX 5090 (32 GB) workstation this eliminated the hard reboots I was hitting under rapid model cycling -- a single-machine (n=1) result whose mechanism is hypothesized, not proven. See Crash Mitigation for the full caveat.
Name disambiguation. This is not Supergiant Games' Bastion (the 2011 action RPG), not
bastion-rs(the Rust actor framework), and not an SSH bastion host. It is a GPU inference broker. Installed from PyPI asbastion-broker; the command and module are bothbastion.
Only BASTION is published. It is a personal project by a single developer, MIT-licensed, run in the open. No SLA, no third-party audit -- see Support & status.
Scope and non-goals
BASTION is a scheduling and safety layer for one Ollama instance on one NVIDIA GPU: request queueing, model-swap serialization, VRAM budgeting, a crash-mitigation default, an admin/observability surface, and an optional A2A agent interface.
BASTION is not a serving engine. It deliberately does not implement the throughput primitives a production inference server has. If you need those, BASTION is the wrong tool -- use one below and stop reading:
| You need | Use instead |
|---|---|
| Continuous/dynamic batching, PagedAttention KV cache | vLLM |
| Tensor / pipeline parallelism across GPUs | vLLM, TGI |
| Multi-node GPU clusters, autoscaling | GPUStack, Ray Serve |
| A hosted, multi-tenant inference API | a managed provider |
BASTION optimizes for stability on a single shared GPU, not tokens/sec.
Where BASTION fits
| raw Ollama | BASTION | vLLM | GPUStack | |
|---|---|---|---|---|
| Drop-in on the Ollama port | -- | ✅ | -- | -- |
| Model-swap serialization + cooldown | -- | ✅ | n/a | -- |
| VRAM budget / overcommit guard | -- | ✅ | ✅ | ✅ |
| Affinity queue across many clients | -- | ✅ | ✅ (batching) | ✅ |
| High-throughput batching / PagedAttention | -- | -- | ✅ | ✅ |
| Multi-GPU / multi-node | -- | -- | ✅ | ✅ |
| Target | one model | one shared GPU | one big model, max throughput | a cluster |
The honest one-liner: BASTION is what you put in front of Ollama when several agents share one GPU and you want it to stay up, not to go faster.
Why I built it
I ran several Claude Code agents and Python pipelines against one Ollama instance on an RTX 5090. Under rapid model cycling -- many clients requesting different models in quick succession -- the machine would hard-reboot after a few dozen swaps. Ollama has no queue, no VRAM budget, and no cooldown between model transitions, so nothing upstream throttled the thrash.
I could reproduce the reboot reliably and stop it by (a) disabling memory-mapped loading on scheduled requests, (b) serializing model swaps behind a budget, and (c) rate-limiting swaps with a cooldown. That is what BASTION does. What I cannot do is prove the mechanism: this is one machine, no controlled A/B, and the documented Blackwell reboot causes (power delivery, GSP/driver Xid faults) are exactly the kind of thing I had no instrument to rule in or out. The Crash Mitigation doc states this plainly, and an instrumented before/after benchmark is the planned way to actually test it.
Hardware
| Tier | Hardware | Behavior |
|---|---|---|
| Tested (n=1) | RTX 5090, 32 GB | Primary development box; every measurement here comes from it |
| Minimum | Any CUDA NVIDIA GPU where nvidia-smi responds, ~8 GB |
Runs; expect heavy queueing and single-model use on small cards |
| Recommended | 24 GB+ NVIDIA (RTX 3090/4090, A6000, L40) | Comfortable multi-model co-residency |
| Small cards | < ~12 GB | Budget refuses co-loads that would exceed VRAM -- BASTION queues rather than OOMs |
| CPU / no GPU | no CUDA device | BASTION starts and proxies, but GPU safety features (crash mitigation, thermal gating) are inert -- it is a plain affinity queue |
Not supported: AMD/ROCm, Apple Silicon, Intel Arc (GPU monitoring is nvidia-smi-specific). Full matrix and per-size config in the Hardware Guide.
Quick Start
1. Install
pip install bastion-broker
Or from a source checkout, for development:
git clone https://github.com/cypwin/bastion.git
cd bastion
pip install -e ".[dev]"
No real data ships or is required -- BASTION runs against your own local Ollama models. There is no bundled corpus and nothing phones home.
2. Move Ollama to port 11435
sudo mkdir -p /etc/systemd/system/ollama.service.d/
sudo tee /etc/systemd/system/ollama.service.d/override.conf > /dev/null << 'EOF'
[Service]
Environment="OLLAMA_HOST=127.0.0.1:11435"
EOF
sudo systemctl daemon-reload
sudo systemctl restart ollama
Or manually: OLLAMA_HOST=127.0.0.1:11435 ollama serve
3. Configure and validate
bastion --init-config       # Generate ~/.config/bastion/broker.yaml
bastion --detect-models     # Discover installed models
bastion --validate          # Check the setup before starting
4. Start and verify
bastion                                    # bind loopback (default)
curl http://localhost:11434                # "Ollama is running"
curl http://localhost:11434/broker/status  # broker status
ollama run llama3.1:8b "Hello, world!"     # transparent proxy
Demo
bastion-dashboard against a live broker on a single RTX 5090, under synthetic
load from scripts/demo/generate_load.py --
four simulated agents (an interactive CLI session, a research agent, a batch
ingest, a nightly reindex) contending for one card across three models. Every
still below is a real capture; nothing here is mocked up.
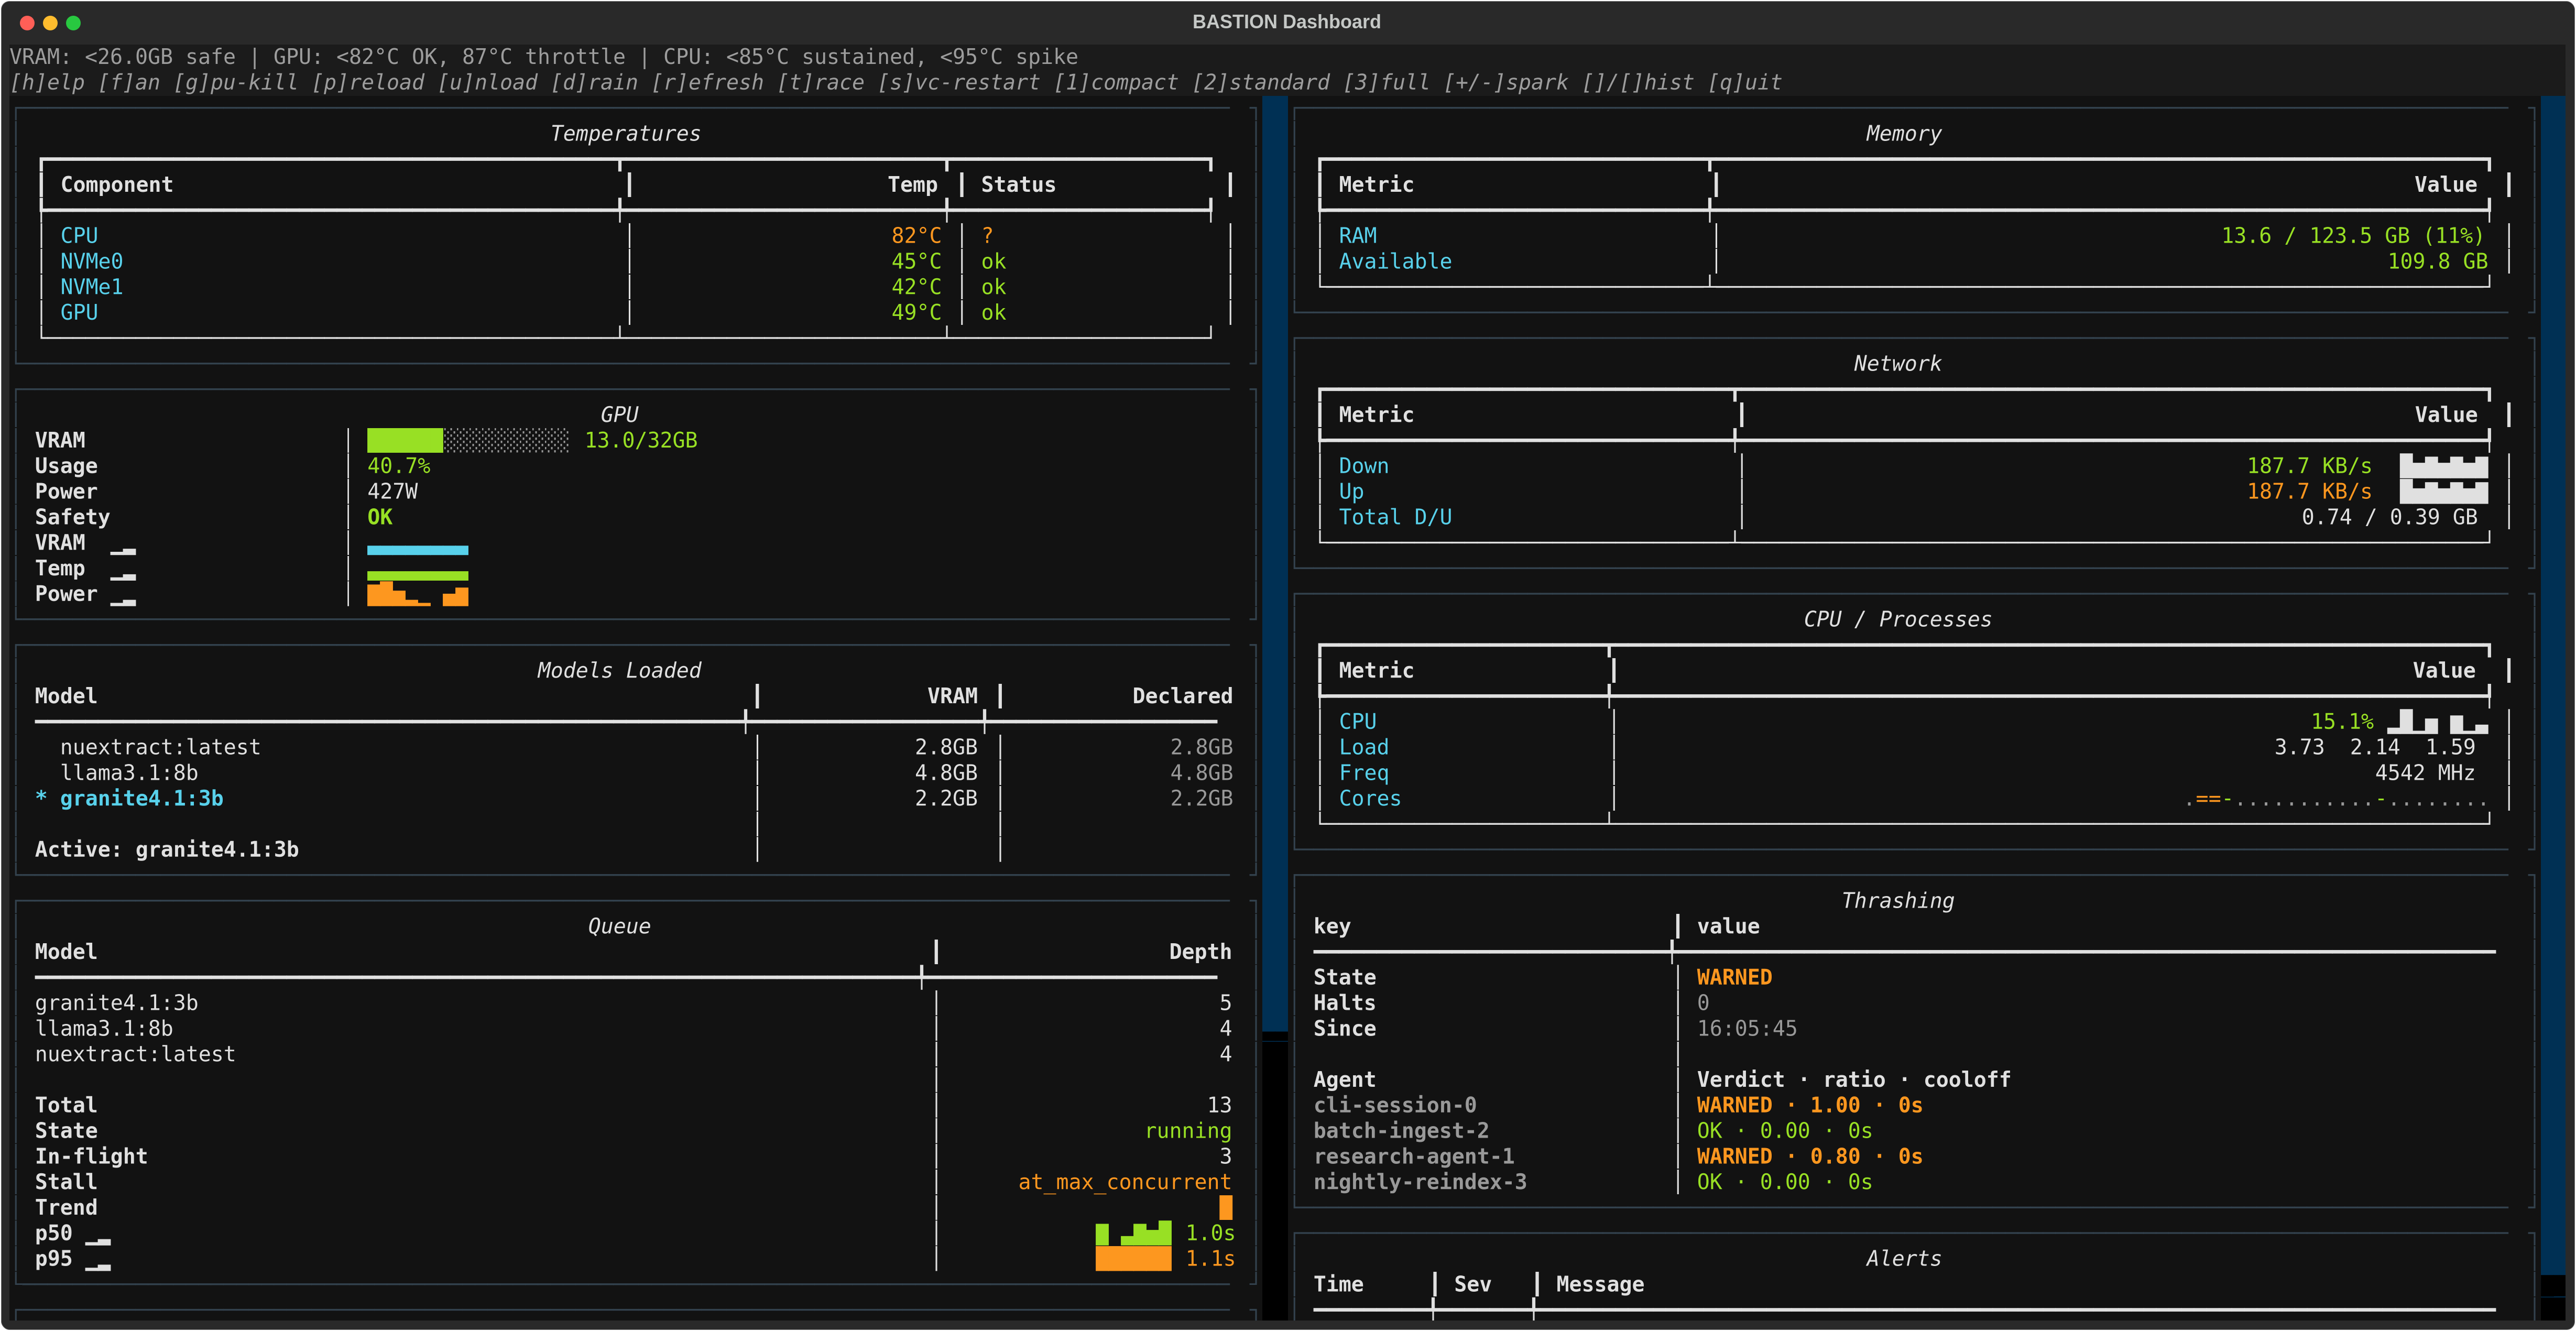
Three models are resident at 2.2 + 2.8 + 4.8 GB, and each matches the size
declared for it in config -- so the Declared column stays dim. A loud signed
figure there is the thing to look for: it means admission is approving loads
against a number the card will not honour.
The queue is 13 deep and stalled at at_max_concurrent; the thrashing detector
has WARNED two of the four agents on their swap ratio -- how often consecutive
requests from that caller ask for a different model.
The VRAM ledger keeps its two error terms apart rather than netting them out.
Δ booking compares what the ledger booked against what Ollama reports
resident; Δ outside compares the hardware total against that same figure. The
+3.6 GB outside is CUDA contexts, cuBLAS workspaces and the desktop compositor
-- bytes Ollama's size_vram never counts. Budgeting as if they were zero is
how a logical ledger talks itself past a physical limit, which is what
gpu.non_ollama_reserve_gb exists to prevent.
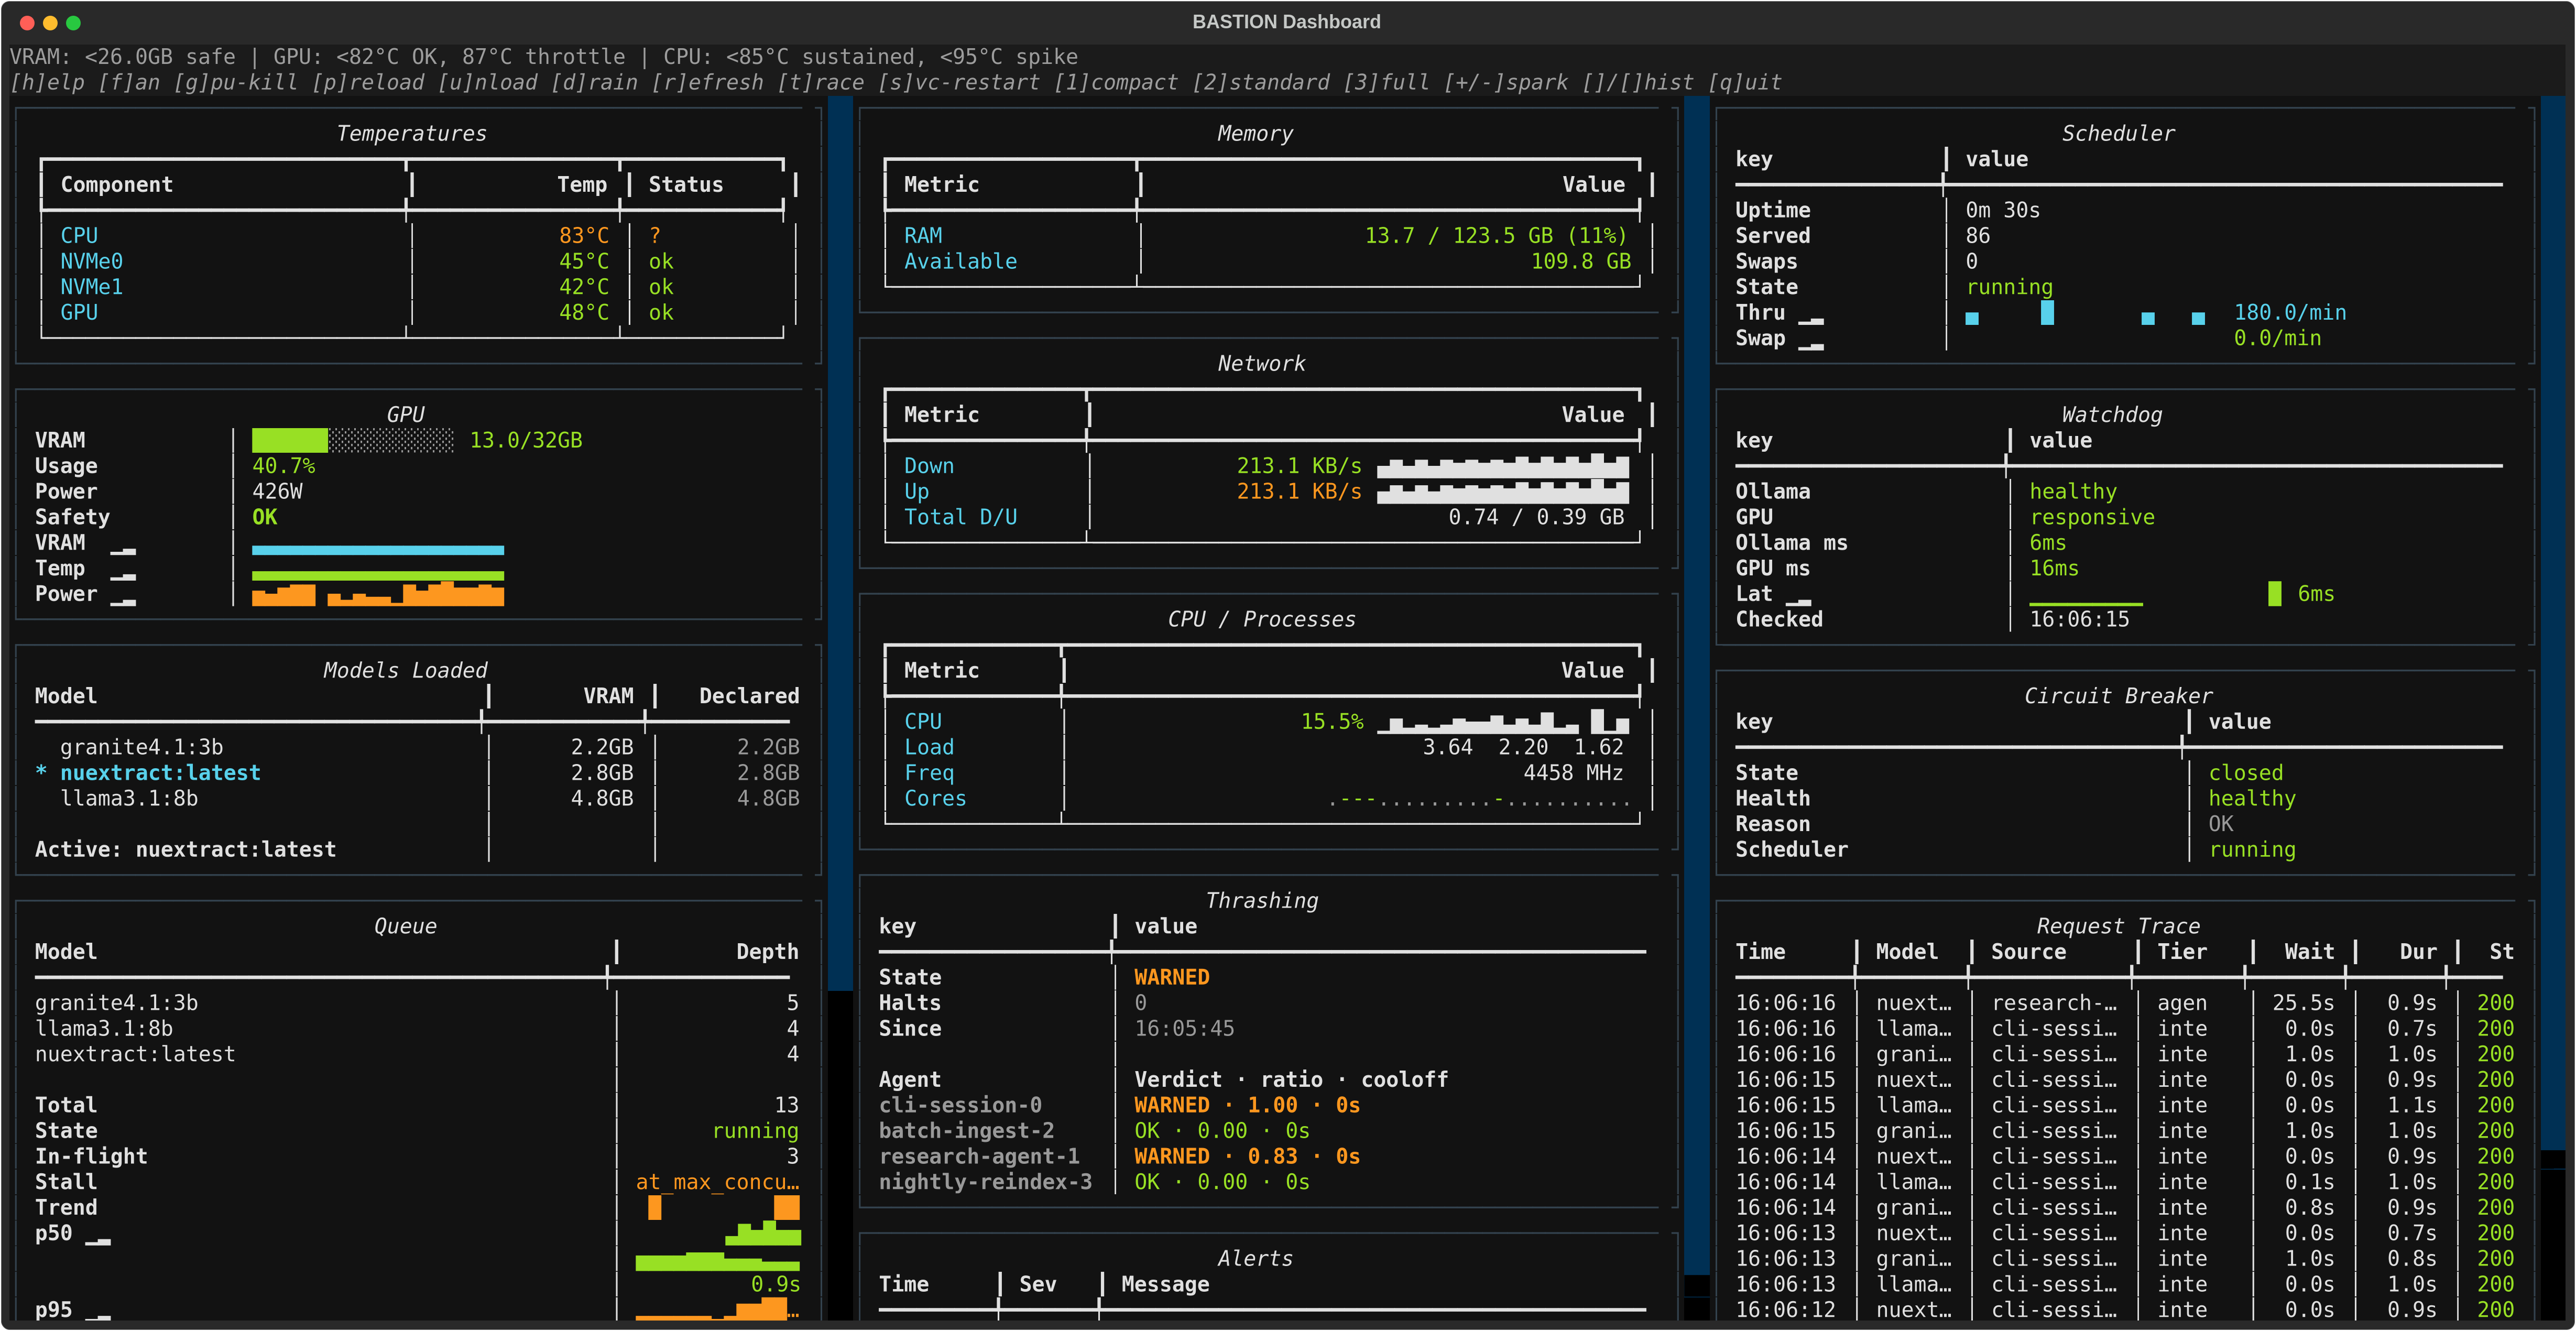
Other layouts -- [1] compact, [3] full, [h] help
[3] full -- adds the scheduler, watchdog, circuit breaker and a live request
trace with per-request source and priority tier:
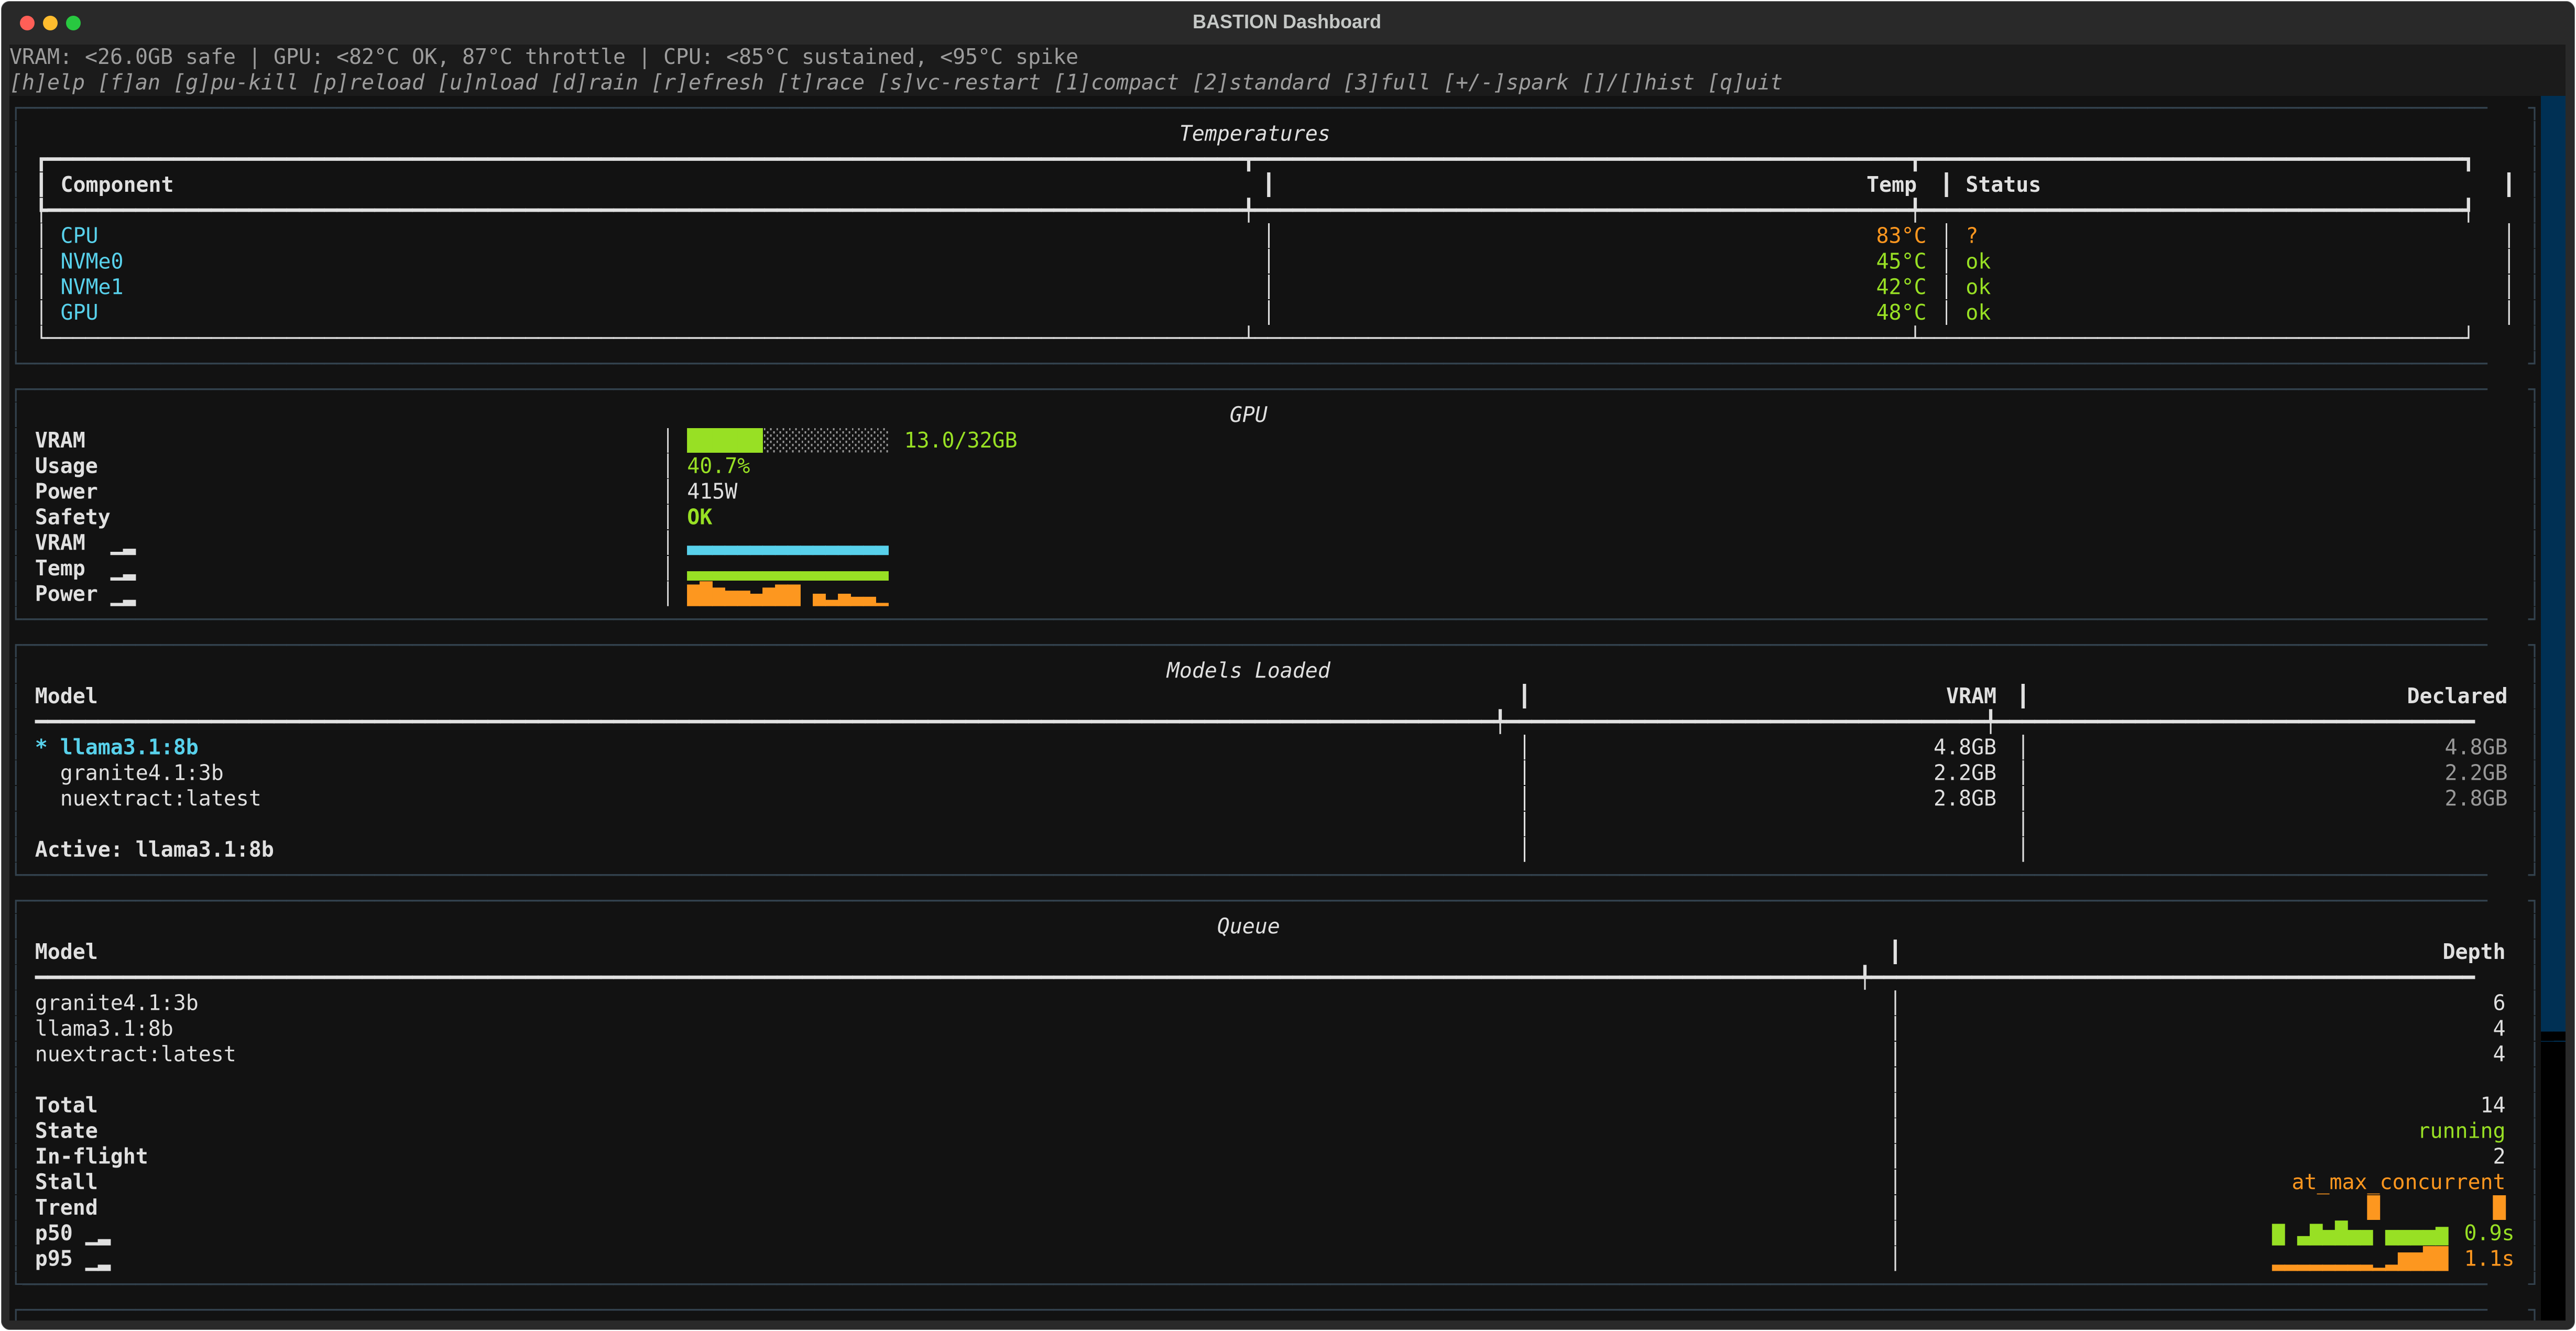
[1] compact -- one column (temps, GPU, models, queue, ledger) for a narrow
pane:
[h] help -- the full key map, including fan control, GPU process kill,
preload/unload and drain:
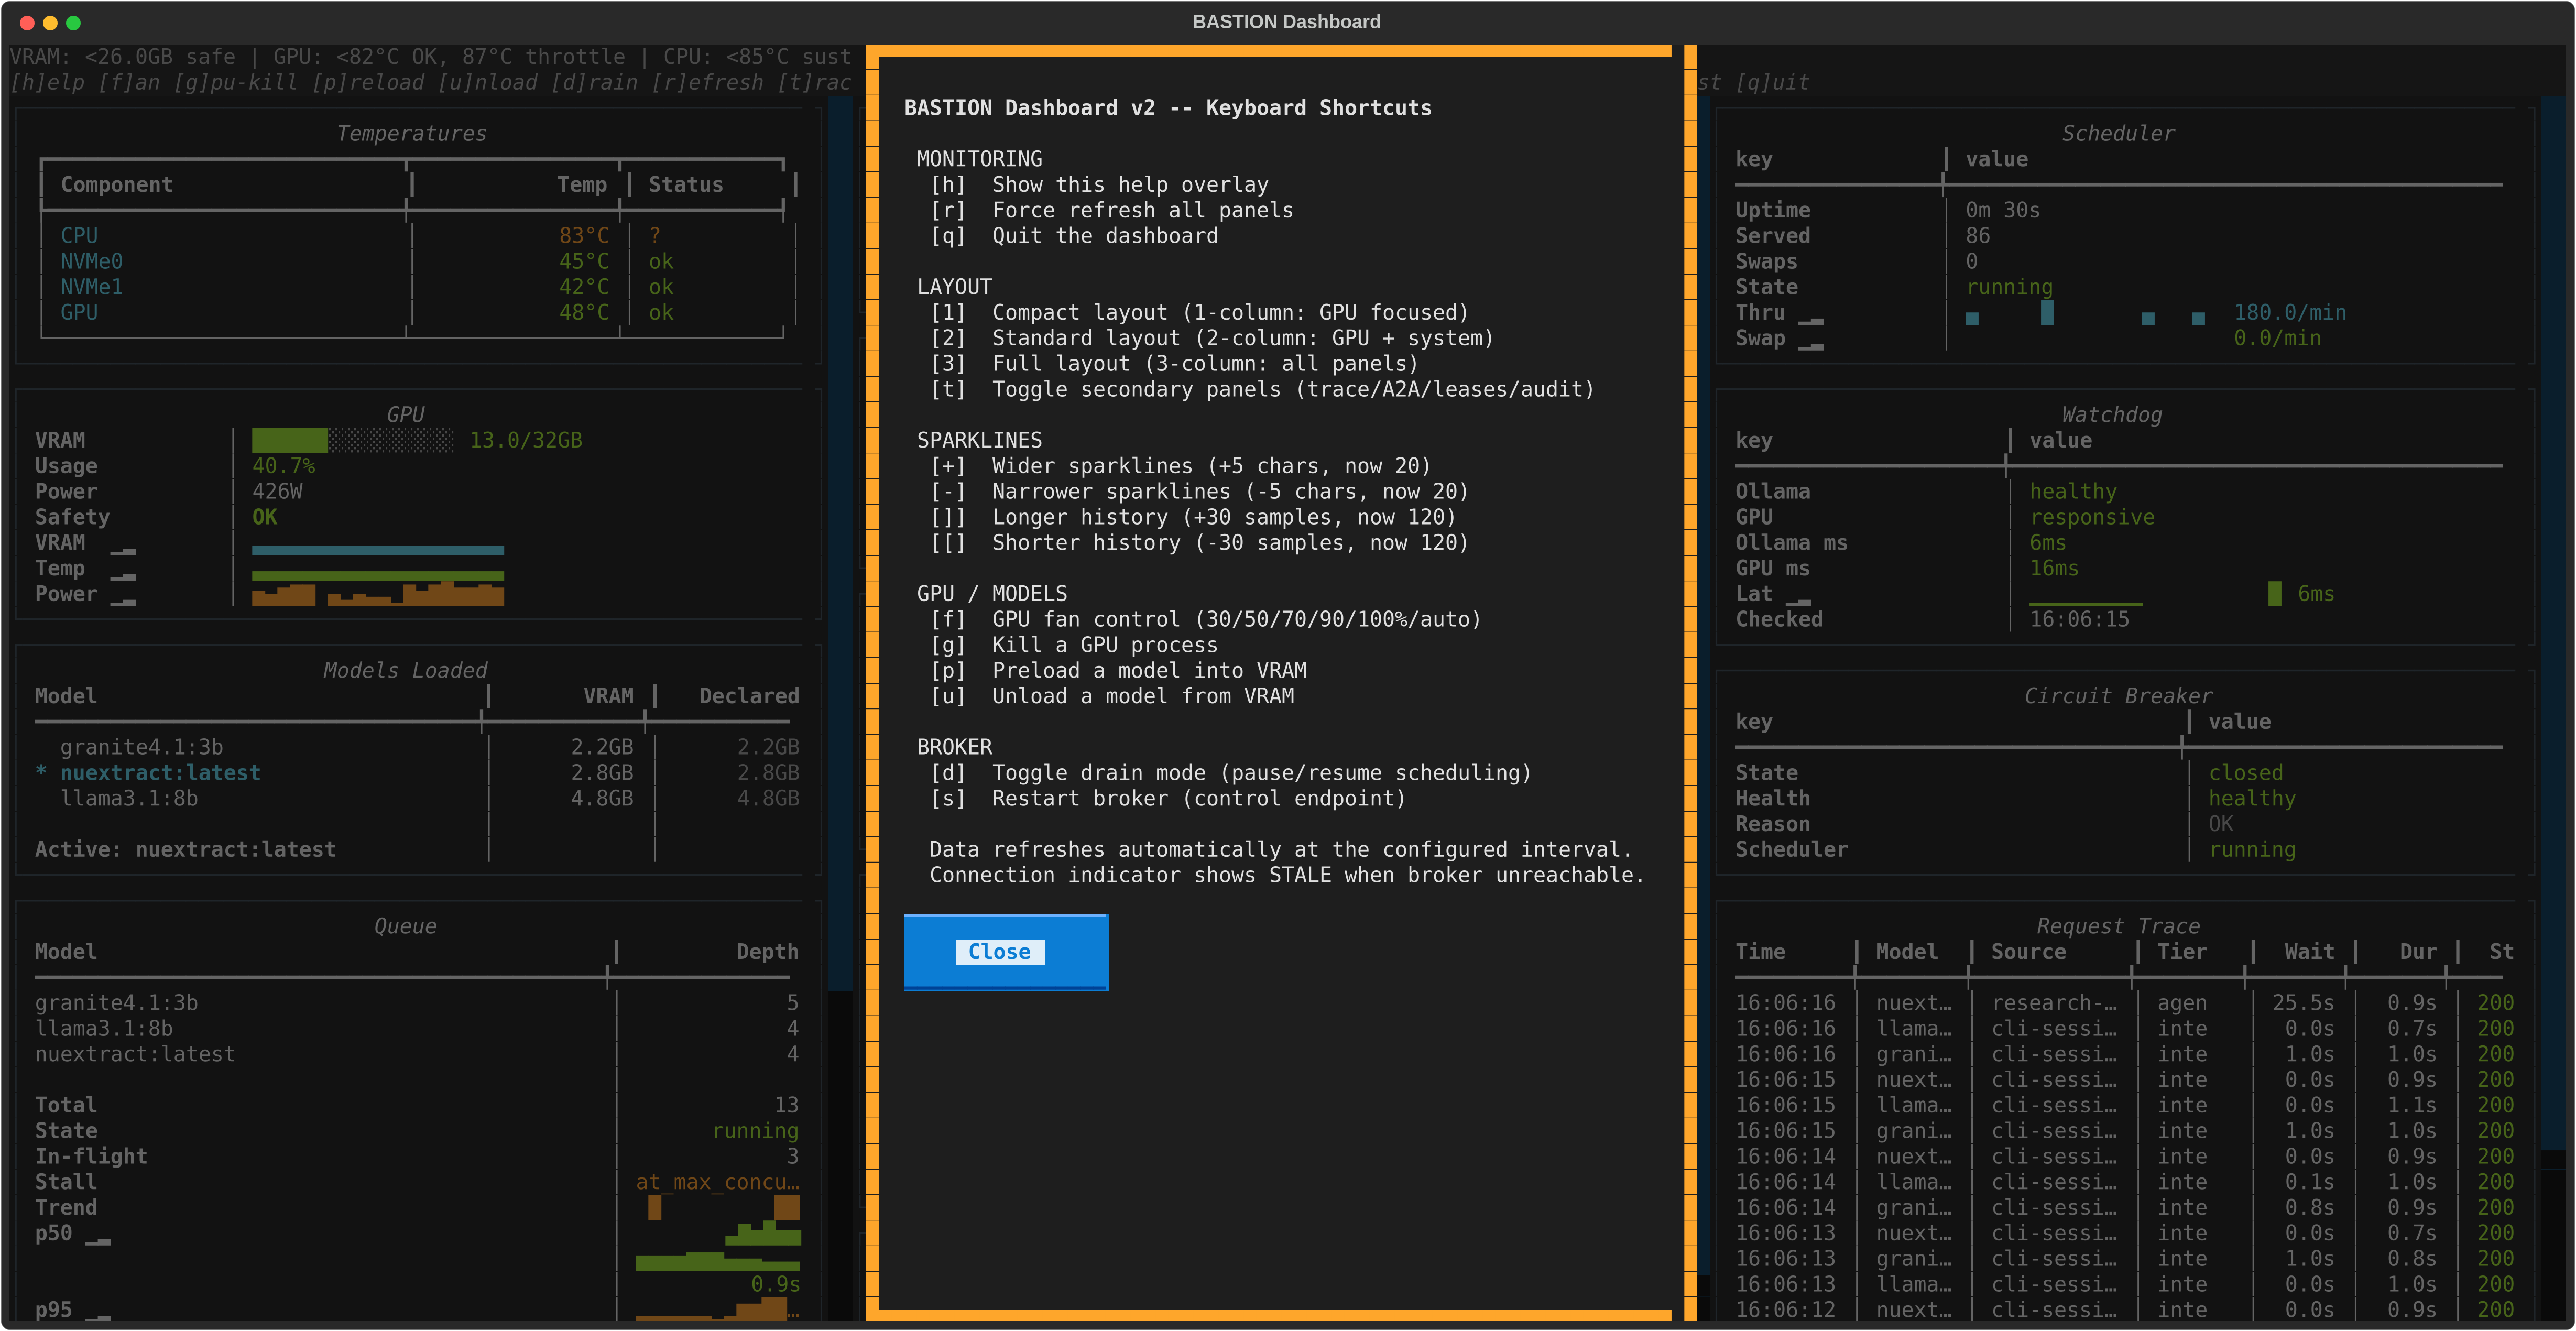
Reproduce the stills on your own broker with
scripts/demo/capture_screenshots.py -- it refuses to
run when nothing answers on the proxy port, by design.
Key Features
- Transparent HTTP proxy -- drop-in on port 11434; existing clients work
unchanged. Streams NDJSON faithfully so
ollama runstays responsive. - Affinity-based scheduling -- per-model sub-queues drain all pending requests for the loaded model before swapping, cutting GPU model transitions.
- Priority aging -- four tiers (interactive, agent, pipeline, background) with time-based aging to prevent starvation.
- VRAM budget enforcement -- tracks GPU memory via Ollama
/api/psfused withnvidia-smi; blocks loads that would exceed the budget. - Crash mitigation -- injects
use_mmap: falseinto scheduled inference requests when the client hasn't set it, plus swap cooldown and rate limiting. Targets the rapid-swap pattern that can destabilize the GPU driver (single-config testing; mechanism hypothesized -- see Crash Mitigation). - TUI dashboard -- real-time Textual dashboard: GPU thermals, VRAM, queue depth, scheduler state, A2A tasks, leases, audit events.
- A2A protocol support -- agent card discovery, task lifecycle, batch inference, model reservation leases (optional extra).
- Prometheus metrics + OpenTelemetry tracing -- optional, with no-op fallbacks when the extras are absent.
- Circuit breaker + per-IP rate limiting + tiered audit logging.
Architecture
                          Clients
    (ollama run, Claude Code, Python scripts, A2A agents, curl)
                             |
                             | :11434 (standard Ollama port)
                             v
    +------------------------------------------------------------+
    |                        BASTION                              |
    |  +----------------+  +-----------------+  +--------------+  |
    |  | Ollama Proxy   |  | Admin API       |  | A2A Agent    |  |
    |  | /api/*         |  | /broker/*       |  | /a2a/*       |  |
    |  | - use_mmap     |  | - status/queue  |  | - tasks      |  |
    |  |   injection    |  | - health/vram   |  | - streaming  |  |
    |  | - NDJSON       |  | - preload       |  | - leases     |  |
    |  |   streaming    |  | - unload/drain  |  | - agent card |  |
    |  | - priority     |  | - metrics       |  | - batch      |  |
    |  +-------+--------+  +-----------------+  +--------------+  |
    |          |                                                  |
    |  +-------v-------------------------------------------------+ |
    |  |          Affinity Queue + Scheduler                     | |
    |  |  - Per-model sub-queues (minimize GPU model swaps)      | |
    |  |  - Priority tiers: INTERACTIVE > AGENT > PIPELINE > BG  | |
    |  |  - Cooldown: 2s (escalates with swap rate)              | |
    |  |  - VRAM ledger (assume/confirm/forget pattern)          | |
    |  |  - GPU health gating (temp, power, utilization)         | |
    |  +-------+------------------------------------------------+ |
    +----------|--------------------------------------------------+
               | :11435
    +----------v--------------------------------------------------+
    |                     Ollama (backend)                        |
    |              OLLAMA_HOST=127.0.0.1:11435                     |
    +-------------------------------------------------------------+
The VRAM ledger is the load-bearing safety primitive: it reserves estimated VRAM atomically before an async load (assume), marks it on success (confirm), and returns it on failure or TTL expiry (forget), so concurrent loads can never overcommit the budget.
Dashboard
bastion-dashboard
bastion-dashboard --url http://localhost:11434 --interval 2.0
For a clickable app entry, scripts/install-desktop.sh (or the Desktop-icon
variant scripts/install-desktop-icon.sh) -- see
Deployment → Desktop Launcher.
Keyboard shortcuts: p preload, u unload, d drain toggle, r refresh,
h help, q quit.
Security
BASTION is built for a single machine or a trusted LAN, not public internet exposure. Under the default auth model (ADR-006):
- Binds to
127.0.0.1(loopback) on 11434 by default. - A non-loopback bind refuses to start unless
auth.enabled: true-- exposure is always a deliberate, auth-gated choice, never a default. - An on-disk bearer token (constant-time compared) gates admin surfaces; a
DNS-rebinding guard rejects foreign
Hostheaders and cross-origin browser requests. The loopback exemption is a convenience for local CLI tools, not a security boundary. - No TLS in-process -- terminate at a reverse proxy for remote access.
mTLS and OIDC are deferred, not rejected (ADR-006-B). They are revisited when any of: (1) a second operator is added to the host, (2) the MCP adapter is hosted on a non-loopback bind in production, or (3) the token model is shown compromised in an incident. For the single-operator workstation target, mTLS is provisioning friction that buys nothing.
Report vulnerabilities via GitHub Private Security Advisory -- see SECURITY.md. Full model in the Security Guide.
Known Limitations
- n=1. Every stability claim comes from one RTX 5090. No controlled A/B, no second machine, mechanism hypothesized. Treat swap-rate numbers as observed, not validated.
- Not a serving engine. No batching, PagedAttention, tensor/pipeline parallel, multi-node, or autoscaling. See Scope and non-goals.
- NVIDIA/Linux only. GPU safety features depend on
nvidia-smi. AMD, Apple Silicon, Intel Arc, and CPU-only run degraded or unsupported. - Single developer. No SLA, no third-party security audit, best-effort
support. First stable release (
0.6.0) -- breaking changes to the config schema and admin API will come with a major-version bump, but that policy is new and untested. - No published benchmark yet. Throughput and the before/after stability A/B are planned, not shipped -- do not read performance claims into this repo.
Documentation
| Guide | Description |
|---|---|
| Getting Started | Full installation walkthrough |
| Configuration | Every config option explained |
| Hardware Guide | GPU compatibility and VRAM requirements |
| Troubleshooting | Common issues and fixes |
| Operations | Monitoring, restart, day-2 ops |
| Security | Auth, TLS, network isolation, threat model |
| Crash Mitigation | The n=1 reboot observation and what BASTION does about it |
| API Reference | All endpoints with examples |
| Deployment | Systemd, Docker, desktop launcher |
| Releasing | One-time PyPI/OIDC setup and release cut procedure |
Optional Extras
pip install "bastion-broker[dashboard]"   # TUI dashboard (Textual)
pip install "bastion-broker[metrics]"     # Prometheus metrics export
pip install "bastion-broker[a2a]"         # A2A agent interface
pip install "bastion-broker[persistence]" # SQLite task persistence
From a source checkout use the editable form -- e.g. pip install -e ".[dashboard]"
(and pip install -e ".[dev]" for testing + linting tools).
Testing
pip install -e ".[dev,dashboard,a2a,metrics,persistence]"
python -m pytest tests/ -m "not e2e" -v
Install all extras for the full suite -- optional-dependency routes (metrics, A2A, persistence) are only registered when their extra is present.
Support & status
- Status: Active, alpha. Single-developer personal project, MIT-licensed.
- Support: best-effort via GitHub Issues; no SLA. Please include your
version (
pip show bastion-broker), GPU/driver, and repro steps. - Contributing: small, focused PRs welcome. There is no CLA and no bug bounty. Security issues go through the private advisory flow above, never a public issue.
- AI disclosure: parts of this project were developed with AI assistance and human review.
License
MIT License. See LICENSE for details.
1 maintainer

Metadata
1 maintainer
Release files for bastion-broker 0.6.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| bastion_broker-0.6.0.tar.gz | 629.0 kB | With provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| bastion_broker-0.6.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 932.7 kB
Release files / bastion_broker-0.6.0.tar.gz
| Download URL | bastion_broker-0.6.0.tar.gz |
|---|---|
| Size | 629.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
a3b22c2feb7f7ee67fb67e47dfa0389e8dc576c27f15a6101ca4e866a1d7fe06
|
|
BLAKE2b-256 checksum How to use checksums |
d35d3c2e239286983d35fe777f6d3cbea9afeff4b2d29d4c29423fe1c7f2ba73
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 28, 2026.
Transparency logRelease files / bastion_broker-0.6.0-py3-none-any.whl
| Download URL | bastion_broker-0.6.0-py3-none-any.whl |
|---|---|
| Size | 303.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
226fdf402c5804f8c0feaebe14372474b4c9d8e6b4c063c2af52beb2dbf04e08
|
|
BLAKE2b-256 checksum How to use checksums |
88b2c646b3905e79816dd5bea9f7bcd8bf1b881a3b34fb2ef63e04c5d9438b33
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 28, 2026.
Transparency logSecurity for bastion-broker 0.6.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for bastion_broker-0.6.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 28, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














