
beamfeat




Beam-search feature construction with false-discovery-rate (FDR) controlled selection, packaged as scikit-learn estimators.
Paper: TMLR 2026
beamfeat builds interpretable mathematical expressions from your columns —
(x0 / x2) * x1, log(a) * log(b) — searches for the ones that explain the
target, and then screens them with a selection procedure whose statistical
guarantee is stated, tested, and honestly reported when it cannot be given.
from beamfeat import BeamFeatRegressor

model = BeamFeatRegressor(max_depth=2, beam_width=30).fit(X, y)

model.formulas()        # ['((x0 / x2) * x1)', ...]
model.equation()        # 'y = 0.9847*((x0 / x2) * x1) + ...'
model.fdr_controlled_   # True: the features carry the stated FDR guarantee
model.predict(X_new)
Install
pip install beamfeat            # core: numpy + scikit-learn only
pip install "beamfeat[units]"   # + pint, for unit-aware search (units as
                                #   strings like "kg" or as pint quantities)
pip install "beamfeat[all]"     # + sympy display support and test deps
Python ≥ 3.10. There are no upper version pins: the 456 tests pass on
Python 3.10 to 3.15, from scikit-learn 1.6.1 with numpy 1.26 through
scikit-learn 1.9.1 with numpy 2.5. Running the test suite or reproducing
the benchmarks needs a little more setup, described in
docs/installation.md.
What it does
- Search. A beam search over an expression DAG proposes and scores
compositions of unary (
log,sqrt,reciprocal,square,abs) and binary (*,/,+,-) operators, with structural deduplication, redundancy pruning, and cost O(depth × beam²) rather than the exhaustive O(operators^depth). - Selection. Candidates are tested for association with the target under procedures that control the false discovery rate (details below), on a held-out split of the training rows that the search never saw.
- Fit. A parsimony step (greedy forward selection within the screened
set, on by default) keeps the compact subset the equation uses, and
.equation()marks how many of the certified terms it printed — the full screened set with per-candidate p- and q-values stays auditable inselection_report_.parsimony=Nonefits that whole set instead, so the printed equation is itself the certified object.
Numerical failures (overflow, domain errors) are recorded and excluded, never
silently masked. Optional unit propagation — units given as pint quantities,
as plain strings like "kg" or "m / s**2", or as a sequence with one entry
per column — rejects dimensionally invalid expressions at construction time,
and a units specification that matches no column raises rather than being
ignored. On a kg/m/s mechanics example this cuts the number of candidates
ever evaluated by roughly two-thirds before any data work; the exact fraction
depends on how many distinct dimensions the columns carry.
The guarantees, stated precisely
- Permutation selector (default). Tests marginal association with a permutation test whose p-values are valid in finite samples: the statistic (|Pearson r| for regression, eta-squared for classification) is a fixed function of the data, and p-values use the add-one estimator of Phipson & Smyth (2010). Multiplicity is corrected with Benjamini–Yekutieli by default (valid under arbitrary dependence); Benjamini–Hochberg is available and is valid under positive dependence (PRDS).
- Knockoff selector. Fixed-X knockoffs (Barber & Candès, 2015) when
n > 2p: no distributional assumption on the features — engineered columns are fine — with the guarantee requiring Gaussian noise in the linear model. Model-X Gaussian knockoffs (Candès et al., 2018) only as ann ≤ 2pfallback, with a warning, since engineered features violate its Gaussianity assumption. - Selective inference. Search retains candidates because they correlate
with the target in its sample, so testing them on the same rows would bias
p-values optimistically. By default the estimators search on one half of
the training rows and select on the other (
selection_holdout=0.5). - Association ≠ generalisation. A post-fit check on the selection
holdout raises a visible
DegenerateFitWarningif the assembled model fails to generalise (negative held-out R², or accuracy below the majority class) — FDR certifies the features' association, and this check covers the separate claim that the equation built on them is sound. - Scope, not just a flag.
fdr_controlled_says whether the returned features carry the guarantee;fdr_scope_says what it is over —"screened set"when the parsimony step pruned the equation down from a larger certified set,"printed equation"when the two coincide..equation()prints the same distinction for a human reader. - Honest failure. If nothing passes selection, the default
(
on_no_discoveries="empty") keeps no constructed features: the model degrades to an intercept-only fit and raises a visibleNoDiscoveriesWarning."fallback"(keep the unfiltered search output, flaggedfdr_controlled_ = False) and"raise"are available. It never silently claims a guarantee it does not have.
Three readings of these guarantees matter. FDR is an expectation over repetitions, not a per-run bound. The marginal null counts a near-duplicate of a real signal as a true discovery — de-duplication is the redundancy threshold's job, not the error-control procedure's. And every number below carries Monte Carlo error from finite trials.
Measured, not assumed
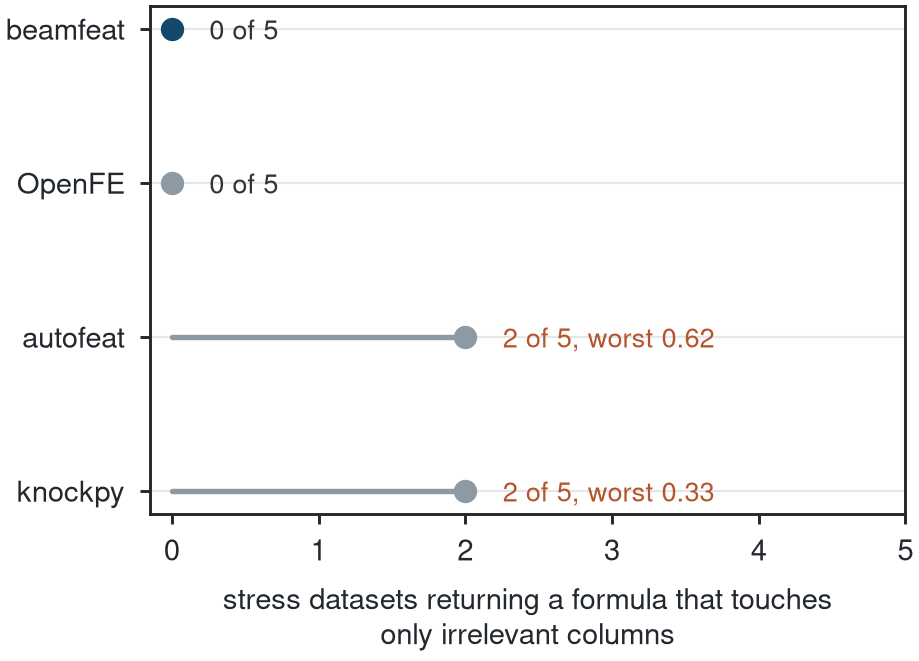
Signal hidden among ten distractor columns. A false feature is a returned
formula touching only irrelevant ones; the count is over the five stress
datasets that declare which columns their formula uses. Regenerate with
python benchmarks/make_figures.py, which writes six other figures alongside
it.
All of the following are measured by the test suite or the committed benchmark scripts, not asserted:
- Selector calibration (Gaussian designs, 100 trials,
benchmarks/selector_calibration.py): BH realised 0.046 ± 0.008, 0.084 ± 0.012 and 0.161 ± 0.016 at nominal 0.05/0.10/0.20, against its ceiling ofq·m₀/m= 0.040/0.080/0.160; BY, stricter by a harmonic factor, realised 0.013 ± 0.005, 0.018 ± 0.005 and 0.046 ± 0.008. Power 1.00 throughout. The bounds are computed from the design and the script fails if a bound falls below a realised rate's whole 95% interval. - End-to-end pipeline (search + holdout selection) at nominal FDR 0.10,
500 rows and 6 input columns of which 2 carry signal through their product,
noise at 5% of the signal's standard deviation
(
benchmarks/calibration_study.py): no false discovery in 200 replicates, a 95% upper bound of 0.015 on the true rate, power 1.000, zero fallbacks; zero selections over 60 global-null replicates. - Feynman-equation panel (12 physics laws, 0.1% noise): 10/12 solved at the SRBench criterion and 8/12 in exact symbolic form, ~0.9 s per equation; the misses are named boundaries (a depth-3 rational, a literal constant, depth-4 nesting, the Gaussian's exponential).
- Pure-noise stress (
benchmarks/selector_calibration.py): over 100 global-null pipelines, where every selection is false by construction, BH returned features in 6 trials and BY in 1 — false discovery proportions of 0.06 and 0.01, both under the nominal 0.10. The gap is not significant at this trial count: both corrections saw the same 100 datasets, the one trial on which BY selected is among BH's six, and the exact paired test gives p = 0.06. BY is the estimator default because it is valid under arbitrary dependence, and this is the consistency check. - Stress suite (signal among ten distractor columns): beamfeat's false-feature rate — returned formulas touching only irrelevant columns — is 0.000 at noise levels from 5% to 50% of the signal scale and at n as small as 120, with recovery and the guarantee intact throughout; autofeat recovers the formula equally often but returns distractor-only features on 2 of the 5 scoreable datasets. Reported as a count rather than a mean: with five datasets the mean carries a standard error of about 0.15, and autofeat's output varies between processes in any case.
- Real data (seven datasets, numeric columns): best on mpg (0.864 vs LightGBM 0.853) and tips — where gradient boosting overfits below ridge while the FDR gate holds beamfeat at the ceiling — tied with ridge on diamonds from one interpretable feature, behind LightGBM on penguins and breast cancer, and behind ridge on diabetes (0.376): no nonlinear structure exists there to find, and beamfeat does not invent any.
- OpenFE on the same stress suite (its features + LightGBM, after shimming a removed sklearn parameter): false-feature rate also 0.000, but 0/5 formulas recovered and lower R² throughout — it optimises tree-model lift, not equations.
- Heavy-tailed noise (Student t(2), infinite variance): exact formula recovered at R² 0.956 vs LightGBM 0.866 — the permutation test is distribution-free, so heavy tails cost it nothing.
- Known boundaries, measured: on piecewise targets trees win outright (LightGBM 0.998 vs 0.808 — if a tree model beats beamfeat by a wide margin, the signal is likely piecewise, not algebraic; OpenFE records 0.998 there too, but bit-identically to raw LightGBM and from a feature touching only an irrelevant column, so the credit is its tree consumer's), and on Friedman #1 the shortfall splits, over six draws, into a representation oracle of 0.960 ± 0.003, a screening-admissible ceiling of 0.874 ± 0.006 (the marginally-quiet quadratic is priced by the guarantee itself) and an achieved 0.780 ± 0.013: about 0.086 lost to what marginal screening cannot see, 0.094 to the search — stated rather than hidden.
- Test suite: 456 tests at 95% statement coverage (a 90% floor is enforced in CI), including scikit-learn's full estimator-conformance checks.
- Selection-only baseline (knockpy on raw columns, modified-FDR offset — the only satisfiable configuration at these dimensionalities): 0/15 formulas recovered, core-suite R² at the ridge level (0.845), and distractor-only features on 2 of the 5 scoreable stress datasets — the construction step and the holdout are the delta.
- Independent 360-fit study across nine datasets and eight methods
(
benchmarks/independent/): mean R² 0.803 against random forest 0.810, LightGBM 0.798, OpenFE 0.736, ridge 0.704, autofeat −1.561 and featuretools −2.478 — and a worst single fit of 0.355, none below zero, where autofeat reached −103.2 and featuretools −57.3, at ~60× autofeat's speed, with the FDR flag delivered on 45/45 fits. - Benchmarks (70/30 splits): mean R² over the ten core-suite problems, and recovery of the generating columns over the ten synthetic problems that declare them — the two sets differ by one dataset each. beamfeat mean R² 0.9989, ~0.2 s fits, 10/10 recovered; autofeat 0.9968, ~12 s, 8/10; LightGBM 0.9798; ridge 0.8442. On the purely linear problem — where feature construction should not win — ridge ties beamfeat.
Relationship to autofeat
beamfeat's design began from a code review of autofeat (Horn et al., 2019) and keeps its best idea — compact symbolic features feeding a linear model — while replacing exhaustive expansion with beam search, heuristic noise-threshold selection with FDR-controlled procedures, and upper-pinned dependencies with tested floors. The generate-then-FDR-filter design has a direct precedent in tsfresh (Christ et al., 2018), which filters mass-generated time-series features under Benjamini–Yekutieli control; beamfeat applies that design to symbolic expressions on tabular columns.
Independent comparison
benchmarks/independent/ holds a 360-fit study (nine datasets, eight
methods, five splits, average ranks plus a Friedman test) with its harness,
pinned environment, data, and a notebook that reproduces the analysis. Mean
held-out R²: beamfeat 0.803, random forest 0.810, LightGBM 0.798, OpenFE
0.736, ridge 0.704, autofeat −1.561, featuretools −2.478 — and worst single
fit of 45: beamfeat 0.355, autofeat −103.2, featuretools −57.3, with the FDR
guarantee delivered on 45/45. Read PROVENANCE.md first: it records what is
reproducible (beamfeat: selections bit-identically; the fitted model's
cross-validated penalty can flip on marginal problems) and what is not (autofeat seeds
no random_state and drawing its decoy features from the global NumPy
generator, swung from +0.952 to −109.8 across six runs on one identical split).
Documentation
Tutorial notebooks live in notebooks/ (getting started; search and scoring;
selection and units). The statistical guarantees are documented in detail in
docs/guarantees.md and in the module docstrings of beamfeat.selection. Users coming
from autofeat will find a full API mapping and version-compatibility notes
in docs/migrating-from-autofeat.md.
Citing
If you use beamfeat, please cite the paper:
@article{
daramola2026symbolic,
title={Symbolic feature construction with false discovery rate control},
author={Olanrewaju M. Daramola},
journal={Transactions on Machine Learning Research},
issn={2835-8856},
year={2026},
url={https://openreview.net/forum?id=UibXoy4h3u},
note={}
}
The paper describes 0.4.2, archived at
10.5281/zenodo.23417132; every release is
archived under 10.5281/zenodo.21619567. See also
CITATION.cff. If you use the selection procedures, please also cite the
underlying statistics: Benjamini & Hochberg (1995),
Benjamini & Yekutieli (2001), Barber & Candès (2015),
Candès et al. (2018), and Phipson & Smyth (2010).
License
MIT.
1 maintainer

Metadata
1 maintainer
Release files for beamfeat 0.4.4
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| beamfeat-0.4.4.tar.gz | 446.2 kB | With provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| beamfeat-0.4.4-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 512.2 kB
Release files / beamfeat-0.4.4.tar.gz
| Download URL | beamfeat-0.4.4.tar.gz |
|---|---|
| Size | 446.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
f9f3343c153c44fae555404505c161b94998627a0e2798d99e672273ce973626
|
|
BLAKE2b-256 checksum How to use checksums |
5d4caacfc008a81aaaaecb6d1f394ee11bd7cdede8ae269e637ed758a53ebcdf
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 19, 2026.
Transparency logRelease files / beamfeat-0.4.4-py3-none-any.whl
| Download URL | beamfeat-0.4.4-py3-none-any.whl |
|---|---|
| Size | 66.0 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
b335e004e6af91a0e5eb76eb18d08a89cf1744c2788ed6738a2c985912c62312
|
|
BLAKE2b-256 checksum How to use checksums |
656102829019eb55d453eee4c02131db5f3ebe3d027da503a69e4aa2178e7ac5
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 19, 2026.
Transparency logSecurity for beamfeat 0.4.4
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for beamfeat-0.4.4.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 19, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.














