
behave-hive



Run behave 1.3.x scenarios in parallel, read Examples: from CSV files and get Allure, Cucumber JSON and HTML reports in one run.
- Examples from CSV: point an
Examples:table at a file with its path,| data/users.csv |, or the equivalent| read('data/users.csv') |. CSV and hand-written tables can live in the same outline. - Sequential or parallel runs: set in the
[behave_hive]section ofbehave.ini, or with--parallel/--no-parallel. - Consolidated reports: Allure results, standard Cucumber JSON and a self-contained HTML report with filters, metrics and screenshots.
Your steps, your environment.py and the way you write features stay the same. A .feature without CSV cells runs exactly as it does with behave. behave-hive complements behave; if you only need a parallel runner with its own report, BehaveX is another option.
Contents: Installation · Quick start · Examples from CSV · Running · Configuration · Reports · Examples · Limitations · Roadmap · Contributing · Releasing
Installation
Install behave-hive in the same environment as your behave project, with uv:
uv add behave-hive                      # in a uv project; or: uv pip install behave-hive
uv add "behave-hive[allure]"            # adds allure-behave 2.16.2 for the Allure format
uv add "behave-hive[playwright]"        # only needed to run the example
pip works too: pip install behave-hive, pip install "behave-hive[allure]".
Requires Python 3.11 or newer. macOS and Linux are supported; Windows is not (see Limitations). Run the commands in this guide with uv run (for example uv run behave-hive run), or activate the environment first.
Quick start
features/login.feature:
Feature: Login

  Scenario Outline: Login as <user>
    Given I open the login page
    When I sign in with user "<user>" and password "<password>"
    Then I see the message "<message>"

    Examples:
      | data/login.csv |
features/data/login.csv:
user,password,message
admin,1234,Welcome
admin,wrong,Invalid credentials
uv run behave-hive run --parallel -w 2
Examples: 0 inline, 1 from CSV
  - features/data/login.csv
Mode: parallel (2 workers, scheme scenario)
batch 1 · worker 1 · 1 scenario · passed · 1.6s
batch 2 · worker 2 · 1 scenario · passed · 1.6s
1 feature · 2 scenarios (2 passed) · 6 steps (6 passed) · 1.7s
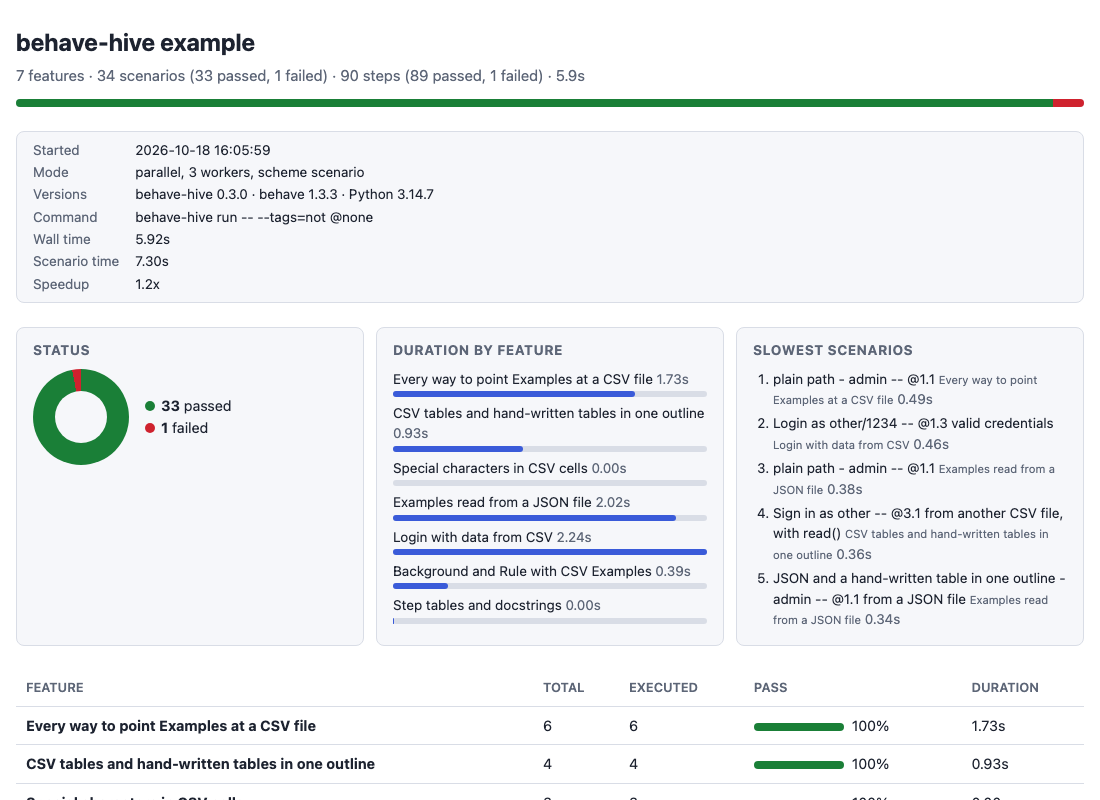
Open report.html (project root by default) for the result; the Cucumber JSON, Allure results and logs are in reports/. The steps used here are in example/, which runs as is.
Examples from CSV
Feature: Login

  Scenario Outline: Login as <user>
    Given I open the login page
    When I sign in with user "<user>" and password "<password>"
    Then I see the message "<message>"

    Examples: valid credentials
      | data/login.csv |
data/login.csv:
user,password,message
admin,1234,Welcome
admin,wrong,Invalid credentials
A table is read from CSV when its first row has one cell that is a path ending in .csv. That plain path is the default form:
    Examples:
      | data/login.csv |
read('path.csv') and read("path.csv") mean exactly the same; use them if you prefer the explicit spelling:
    Examples:
      | read('data/login.csv') |
Any other table is a regular, hand-written one. Both kinds can live in the same outline, each under its own Examples:, and each keeps its own tags:
    @smoke
    Examples: from a file
      | data/login.csv |

    Examples: written by hand
      | user  | password | message             |
      | guest | guest    | Invalid credentials |
The CSV path is relative to the directory of the .feature file (subdirectories and .. are fine). The Examples: keyword follows the language of the feature (# language: directive or lang in [behave]).
CSV contract
- UTF-8, with or without a BOM. The first row is the header; its names are the
<placeholders>. - Physically empty lines are ignored. Empty cells are kept.
- Spaces around a cell are lost, as in any Gherkin table. A
|inside a cell is written as\|for you, and the step receives it intact. - Rejected, with exit code 2 and a message naming the
.feature, the line, the CSV and the CSV row: no data rows, empty or duplicated headers (after stripping spaces), rows whose width differs from the header, cells with a line break, a missing file and invalid UTF-8. - Text inside
"""or'''docstrings is never interpreted asExamples:.
What behave-hive writes
When a CSV table is present, the whole features root is copied to a working directory: .feature files are written expanded and every other file is a symlink to the original. uris in the reports are the original ones; the HTML report shows path.csv:row next to each scenario. To see the result:
behave-hive expand features /tmp/expanded
expand refuses, without deleting anything, a destination that is the source or one of its ancestors, a symlink, or a non-empty directory not created by a previous expansion.
Running
behave-hive run                         # uses [behave_hive] from behave.ini
behave-hive run --parallel -w 4         # 4 processes
behave-hive run --no-parallel           # one process per features root
behave-hive run features/login.feature   # a directory or a single .feature file
behave-hive run -- --tags=@smoke -D env=qa   # everything after -- goes to behave
Every path belongs to a features root: the closest directory, walking up, that contains steps/. Inputs with the same root share one expansion, and a scenario reachable through two inputs runs once.
| Option | Meaning |
|---|---|
--parallel / --no-parallel |
Override parallel. |
-w, --workers N |
Number of processes. |
--scheme scenario|feature |
Distribute scenarios (and outline rows) or whole features. |
--chunk N |
Units per process; 0 splits the units of a root evenly among the workers. |
--results-dir DIR |
Where JSON, Allure results and logs go; HTML uses report_path. |
--formats LIST |
Any of allure, cucumber, html. |
--config FILE |
Read [behave_hive] from this file only. |
--keep-tmp |
Keep results_dir/tmp/ (partial results, locations files). |
Parallel by scenario or by feature
With parallel = true, behave-hive splits the suite into units and gives them to up to workers processes. scheme decides what a unit is:
scheme |
A unit is | Use it when |
|---|---|---|
scenario (default) |
One scenario, or one row of a Scenario Outline (from CSV or written by hand). | Scenarios are independent. A file with 4 data rows runs as 4 units, in parallel. |
feature |
One whole .feature file; its scenarios run in order in the same process. |
Scenarios of a feature depend on each other, share an expensive before_feature, or use @setup/@teardown. The same 4-row file is 1 unit. |
behave-hive run --parallel --scheme scenario -w 4    # rows and scenarios spread over 4 processes
behave-hive run --parallel --scheme feature -w 2     # one process per feature, 2 at a time
The same keys work in the configuration file (parallel, workers, scheme, chunk); example/configs/ has a ready-made file for each case. A scenario's own steps never run in parallel. chunk sets how many units each process receives (0 shares them evenly). before_all and after_all in environment.py run once per process, so use BEHAVE_HIVE_WORKER to keep ports or users apart.
Exit codes: 0 all good, 1 a failed, undefined or pending scenario or a batch error, 2 usage, configuration or CSV error, 130 interrupted with Ctrl+C. When nothing matches, No scenarios found is printed and the exit code is 0.
Configuration
Put a [behave_hive] section next to [behave] in behave.ini, .behaverc, setup.cfg or tox.ini, or a [tool.behave_hive] table in pyproject.toml. Files are looked up in the working directory in that order and the first one with the section wins. behave ignores the section.
[behave]
default_tags = not @expected_fail

[behave_hive]
parallel = true
workers = 3
scheme = scenario
formats = allure, cucumber, html
report_name = My QA project
report_path = reports/report.html
| Key | Default | Notes |
|---|---|---|
parallel |
false |
true/false, yes/no, on/off, 1/0. Sequential mode ignores workers, scheme and chunk. |
workers |
number of CPUs | At least 1. |
scheme |
scenario |
scenario or feature. |
chunk |
0 |
At least 0. |
results_dir |
reports |
|
report_name |
project name | HTML title and heading only; blank also uses the fallback. |
report_path |
<project-root>/report.html |
Full HTML filename; relative to the project root, or absolute. Parents are created. |
formats |
cucumber, html |
Comma or space separated; TOML arrays work too. |
work_dir |
.behave-hive |
Each run uses its own subdirectory. |
behave_args |
empty | Shell-style string (--tags="@a and not @b" -D env=qa) or a TOML array. % is literal. |
paths |
features |
What to run when no path is given. |
Precedence, lowest to highest: default, file, command line. Arguments after -- are appended after behave_args. An unknown key is an error. behave's own settings (default_tags, tags, lang, ...) keep their meaning; --tags on the command line overrides default_tags, as in behave.
The project root is the selected configuration file's directory, or the working
directory when no configuration section is selected. An omitted/blank HTML name
uses [project].name from that root's pyproject.toml, then the folder name.
HTML is now written at the project root by default. Set
report_path = reports/report.html to retain the earlier destination.
These settings do not change the generated Allure report's name.
Arguments behave-hive controls
These are rejected, in behave_args and after --, with exit code 2:
- positional arguments and
@files (paths go before--); -f/--format,-o/--outfile,-r/--runner,--junit,--junit-directory;-d/--dry-run,--stop,-i/--include,-e/--exclude,-n/--name,-w/--wip.
The same applies to the effective behave configuration: stop, dry_run, steps_catalog, junit, wip, name filters, include/exclude, stage and a custom runner in [behave] are rejected, and so are --version, --tags-help, --lang-list and --lang-help. format and outfiles from [behave] are ignored.
Worker identification
Each behave process receives BEHAVE_HIVE_WORKER (the slot, 1..workers; always 1 in sequential mode) and BEHAVE_HIVE_BATCH (the 1-based batch index). Two active processes never share a slot, so they can pick ports, users or databases:
import os
port = 9000 + int(os.environ.get("BEHAVE_HIVE_WORKER", "1"))
@setup and @teardown
behave runs scenarios tagged @setup or @teardown even when they are not selected. With parallel = true and scheme = scenario, a feature containing them is rejected; use scheme = feature or sequential mode.
Reports
JSON, Allure and logs are written to results_dir (default reports/). The HTML
file uses report_path independently (default <project-root>/report.html):
| Path | Format |
|---|---|
cucumber.json |
Standard Cucumber JSON, scenarios in line order, each preceded by its background. |
allure-results/ |
One Allure result per scenario that behave selected, including scenarios inside a Rule, with context.attach(...) data as attachments of their step and an environment.properties file. Open it with the Allure CLI: npx allure@3 generate reports/allure-results. |
report_path |
Self-contained HTML with inline filters, no external requests, light and dark mode; project name in title and heading. |
logs/batch-<n>.log |
Output of each behave process. |
Every generated HTML carries a behave-hive-report-4f9c2e7a generator marker in its head. At the start of a run behave-hive deletes the previous file at report_path only when it is a regular file with that marker, so an aborted run never leaves an old report that looks current, and any other file at report_path is never touched.
At the start of a run behave-hive deletes only what it manages (cucumber.json, report.html, allure-results/, logs/, tmp/); anything else in results_dir is kept. A second run on the same results_dir exits with code 2.
Scenario and feature ids are stable: they do not depend on workers, chunk or input order. Hook failures and failed context.add_cleanup functions count as failed (broken in Allure). A pending step counts as pending, except inside a @wip scenario.
Allure attachments and environment
Data attached with context.attach(mime_type, data) (for example a screenshot in
after_step) is stored in allure-results/ and attached to the step that made it;
data attached after the last step goes to the last step, and data attached before any
step is ignored. environment.properties lists behave-hive, behave and python
versions, mode (parallel or sequential), workers and scheme.
The HTML report
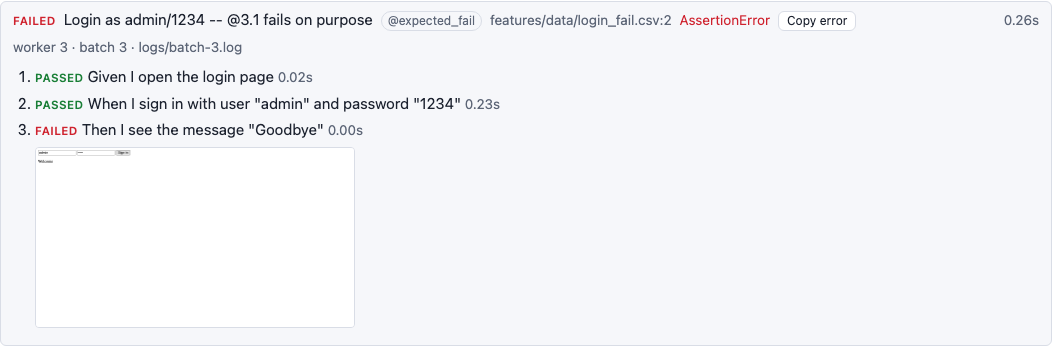
- Failures first: inside each feature, failed, undefined and pending scenarios come
first and are open; each shows the first line of its error (the last line when the
first one is only a prefix such as
ASSERT FAILED:) and a Copy error button. - Run context: start time, mode, workers, scheme, versions, the command without your home or project path, the wall-clock time, the sum of scenario times and, in parallel mode, the speedup between them.
- Worker and batch: each scenario names its worker, its batch and
logs/batch-<n>.log. - Outline groups: the rows of a Scenario Outline are grouped under the outline, with the row count and the number of rows that did not pass.
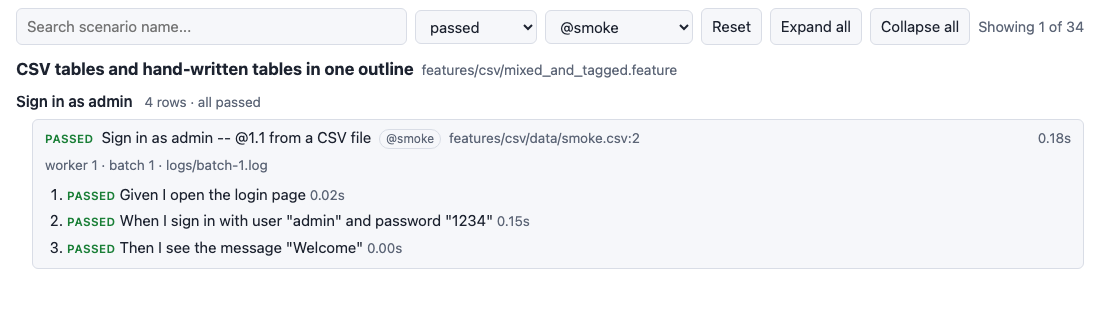
- Shareable filters: the search text, status and tag filters are kept in the address
as
#search=...&status=...&tag=..., for examplereport.html#status=failed&tag=@smoke. Unknown values are ignored.
A failed scenario opens with its error headline, a Copy error button, the worker and batch that ran it, and the screenshot taken by your after_step hook (the traceback below the steps is hidden in this picture):
Filters live in the address, so a filtered view can be shared; #status=passed&tag=@smoke shows this:
Privacy and security of the HTML
The HTML carries a default-deny Content-Security-Policy with the hash of its exact
inline script, inline styles and data: images. Paths in error messages and in the
command are rewritten as described under Limitations: the run directory
becomes the original path, the project directory becomes relative and your home becomes
~. Screenshots and error texts are reported as they are.
CucumberJSONFormatter also works without behave-hive:
behave features -f behave_hive.formatters.cucumber:CucumberJSONFormatter -o out.json
Examples
example/ is a runnable project (Playwright and a local login page) with one example for each feature. Its README lists them with the command to run each one.
| Example | Shows |
|---|---|
features/login.feature |
CSV table, hand-written table and a table that fails on purpose (screenshot as evidence). |
features/csv/forms.feature |
The plain path (the default form), read('...') with single and double quotes, and a shared file through ... |
features/csv/mixed_and_tagged.feature |
CSV (plain path and read()) and hand-written tables in one outline, each with its own tags. |
features/csv/special_characters.feature |
Pipes, commas and percent signs inside cells. |
features/structure/background_and_rule.feature |
Background and Rule with CSV Examples:. |
features/structure/step_data.feature |
Step tables and docstrings, never read as Examples:. |
configs/ |
Sequential, scheme = feature and TOML configurations. |
git clone https://github.com/albertor03/behave-hive && cd behave-hive/example
uv venv && uv pip install "behave-hive[allure,playwright]"
uv run python -m playwright install chromium
uv run behave-hive run                               # as configured in behave.ini
uv run behave-hive run --config configs/sequential.ini
uv run behave-hive run -- --tags=@smoke              # only the @smoke Examples table
Gherkin in other languages works too: the Examples: keyword follows the feature's language, as shown in tests/fixtures/i18n/.
Limitations
- Lines in expanded features: rows generated from a CSV, and everything after them in the file, report the lines of the expanded file. The
uriis the original one and the HTML showscsv:row; files without CSV keep their lines. Path(__file__)in steps: steps run through symlinks in the expanded tree. UsePath(__file__).resolve()to reach files next to the original step.- Unbalanced batches: units are split into consecutive chunks. Use
chunk = 1for dynamic balancing, at the cost of one process per unit. allure-behaveis pinned to 2.16.2, because the Allure formatter relies on its internals.- POSIX only (macOS and Linux): the run lock uses
fcntl.flock, interruption signals whole process groups (os.killpg) so browsers started by a step do not survive Ctrl+C, and the expanded copy of your features links every non-feature file with symlinks. None of these exist, or work without special privileges, on Windows. CI covers Linux and macOS only. WSL runs Linux and should work, but it is not tested. - Not supported:
--stop,--dry-run,--include,--exclude,--name,--wip, retries, and data sources other than CSV (JSON files are planned, see the Roadmap). - CSV access is not sandboxed: a feature may reference any CSV readable by the
current user, including paths with
..; its rows can appear in reports. - Retained run configuration:
--keep-tmppreserves private plans and locations, including-D key=valuearguments. These files are owner-only (0600, inside a0700temporary directory); remove retained runs when no longer needed. The results lock is also owner-only. - Report privacy: behave-hive rewrites expanded roots, the working directory
and the home prefix in error messages to original relative paths or
~. The directly used Cucumber formatter (behave -f) has no run path map and does not perform this rewriting. Screenshots and attached data are not scrubbed and may contain sensitive application data; scenario inputs can also appear. - Expansion race window: destination checks are repeated before deletion and marker creation. This narrows, but does not eliminate, filesystem races.
Roadmap
Next on the list:
- Windows support: replace the POSIX-only pieces described under Limitations (file lock, process groups and symlinks) and add Windows to CI.
- JSON data files: read
Examples:from a.jsonfile, next to CSV, with the same plain-path form.
Contributing
Pull requests are welcome. CONTRIBUTING.md explains how to set up the project, the checks that must pass and how CI works. AGENTS.md describes the layout and the conventions.
Releasing
Releases are tagged and published to PyPI by a workflow; the maintainer's checklist is in docs/RELEASING.md.
License
MIT, see LICENSE.
1 maintainer

Metadata
1 maintainer
Release files for behave-hive 0.1.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| behave_hive-0.1.1.tar.gz | 53.1 kB | With provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| behave_hive-0.1.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 104.7 kB
Release files / behave_hive-0.1.1.tar.gz
| Download URL | behave_hive-0.1.1.tar.gz |
|---|---|
| Size | 53.1 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
bd6315332e986f0b4966f46440481a17ee8cd9b749f9e54c53cfbfb480c23843
|
|
BLAKE2b-256 checksum How to use checksums |
98879570a9cc192b82dcbd135aefa932e4e64c5730b73c583f544b459dbab784
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 18, 2026.
Transparency logRelease files / behave_hive-0.1.1-py3-none-any.whl
| Download URL | behave_hive-0.1.1-py3-none-any.whl |
|---|---|
| Size | 51.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
fe3711848e2dd5cd6458870fe3bb81e1c242675c723ffdeb9296ad9acd37ed5b
|
|
BLAKE2b-256 checksum How to use checksums |
a7cec3488e458a5ac3514cf7bbf9528fe5b8d9228d5fc95b18c1fc731f5abb82
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 18, 2026.
Transparency logSecurity for behave-hive 0.1.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for behave_hive-0.1.1.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 18, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














