
BehaviorGPT
The foundation model for behavior.
BehaviorGPT is Unbox AI's Large Behavioral Model. It is trained on long sequences of things people actually did (viewed this, added that, bought the other) and predicts what comes next, so search, recommendations and personalization are the same call with different histories. BehaviorGPT-v4 is a single 12.5B-parameter model pretrained on 150 billion user actions across retail, engagement and payments, and it ranks catalogs it has never seen with no training.
Website · Live demo · Research · Notebook
This repository holds the Python SDK for the Unbox AI API and a notebook that walks through the model step by step.
Three apps built on this SDK: two that recommend, on a store's catalog and a museum's, and one that reads the same rankings as a fraud detector. More on each in Demo and examples.
 |
 |
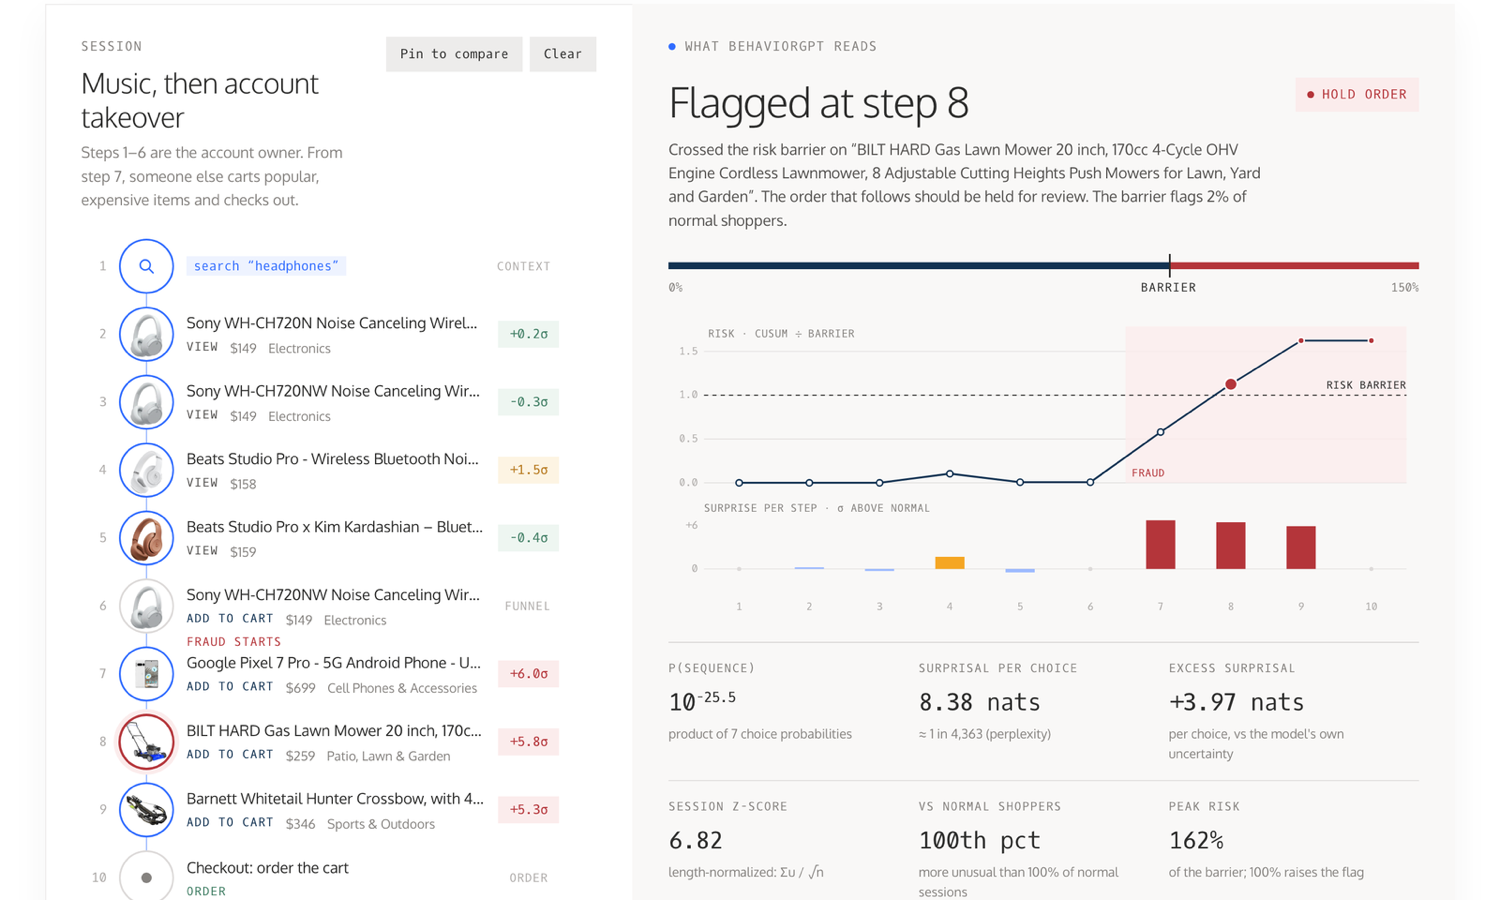 |
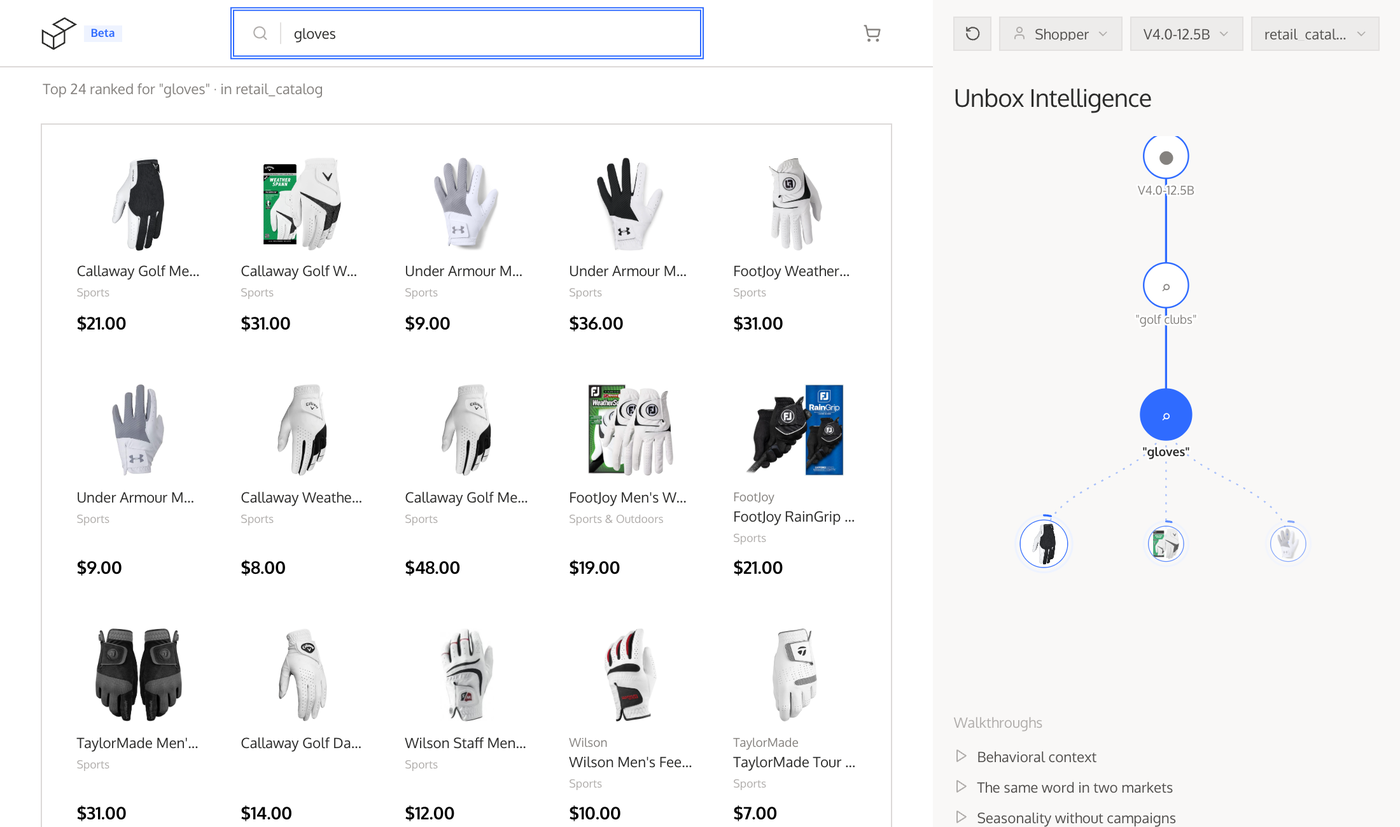
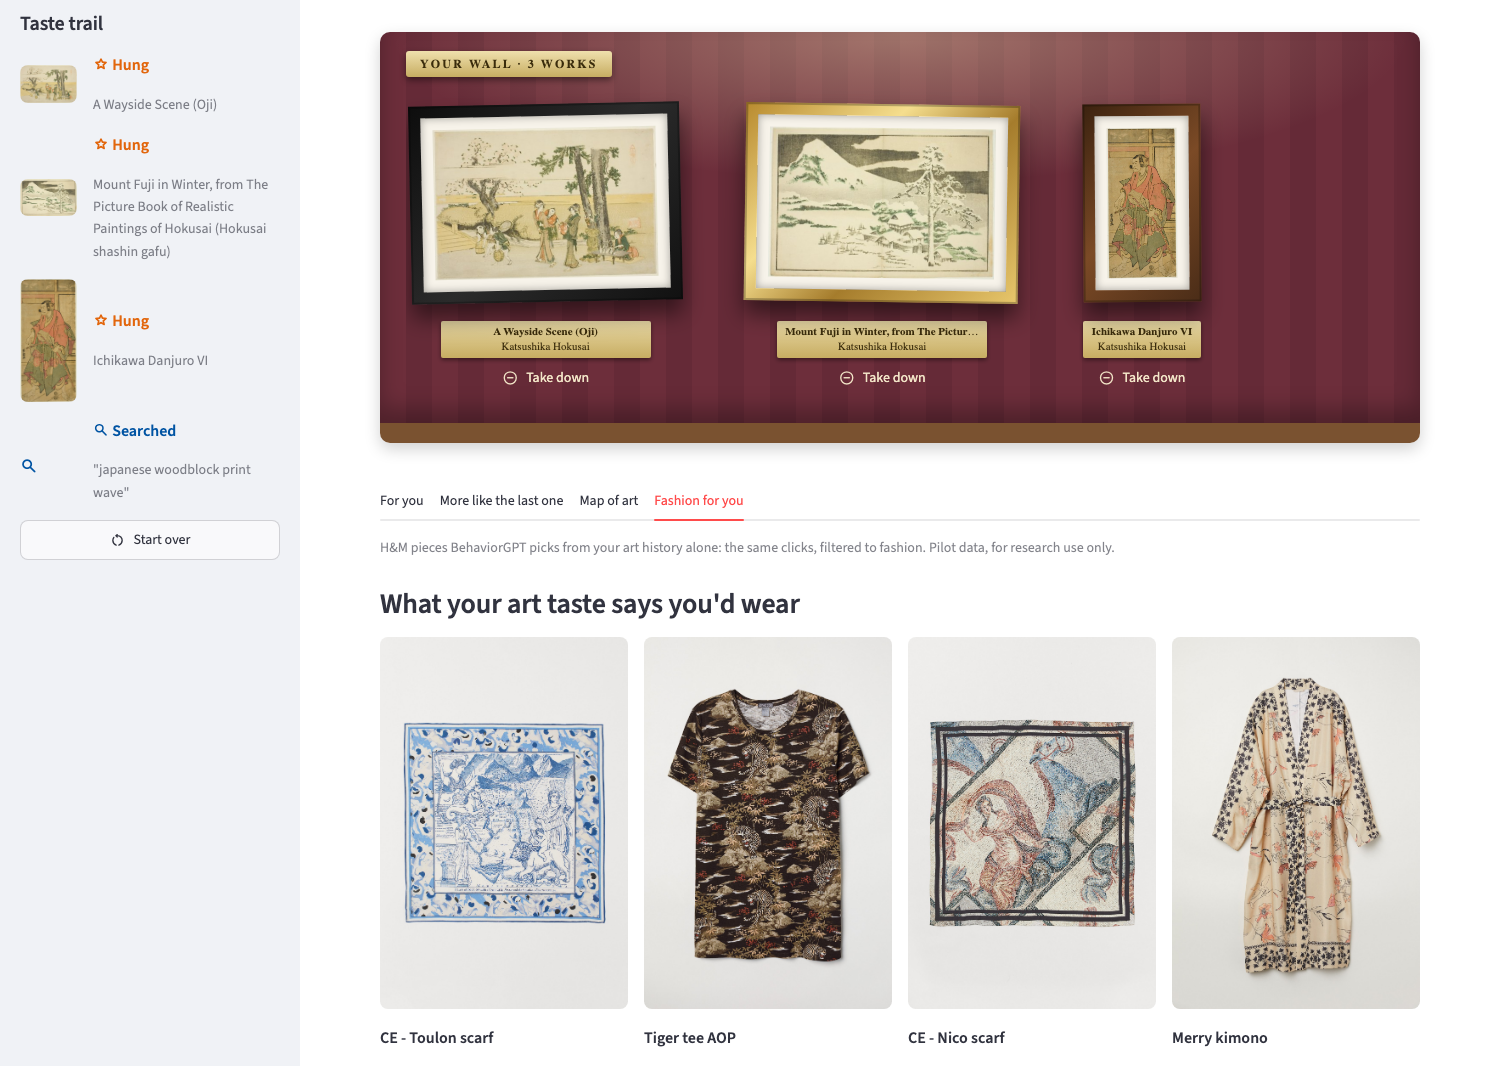
| Storefront (live demo). Search results and recommendations change with what the shopper did before, and a panel shows the history the model read. | Curate my wall (live app, source). Hang three Hokusai prints, and the "Fashion for you" tab suggests scarves and kimonos from those art clicks alone. | Anomaly detection (source). An account takeover: after the owner's headphone views, someone carts a phone and then a lawn mower, and the session is flagged at the mower, the step where its risk crosses the barrier. |
Requirements
- An Unbox AI API key. Create and copy the key at unboxai.com/behaviorgpt; the key also arrives by email.
- Python 3.11 or newer.
Quick start
pip install behaviorgpt
export UNBOXAI_API_KEY=...   # or pass api_key= to UnboxAIClient
from behaviorgpt import Search, UnboxAIClient, View

client = UnboxAIClient(market="us")

# a history of one search
res = client.complete([Search("running shoes")], limit=5)
print(res.names)

# the same call, personalized: a viewed item (Nike pants), then a query
res = client.complete([View("paB08NYK61PJ"), Search("shoes")], limit=5)
print(res.names)

# items close to one another in the model's space
print(client.similar_items(res.items[0].id).names)
complete takes the history and returns the items most likely to come next. Each result in res.items has an id, a score and the catalog row in data; res.to_pandas() gives a DataFrame if pandas is installed.
Async
In asyncio code, such as a FastAPI or aiohttp server, use AsyncUnboxAIClient. It takes the same arguments and has the same methods, awaited, so a call never blocks the event loop and many calls can run at once:
import asyncio

from behaviorgpt import AsyncUnboxAIClient, Search

async def main():
    async with AsyncUnboxAIClient(market="us") as client:
        shoes, gloves = await asyncio.gather(
            client.complete([Search("running shoes")], limit=5),
            client.complete([Search("gloves")], limit=5),
        )
        print(shoes.names, gloves.names)

asyncio.run(main())
Create one client and reuse it, for example for the lifetime of your server: async with closes its connections at the end, or call await client.aclose(). embed(..., wait=True) waits for the job without blocking other requests.
How it works
- One call, many features. Every request asks the same question: given what this person did, which items are they most likely to act on next? The history picks the feature. End it with a
Searchfor search results, with aViewfor "more like this", with anOrderfor what is bought next; leave it empty for a cold start. - The whole sequence counts. The model reads the history in order, so the same query means different things after different actions: "gloves" after "golf clubs" returns golf gloves.
marketon the client says where the user is, which helps most when the history is short. - Items are read from their content, not their ids. Each item is embedded from its name, brand, categories, image and price. That is why the model can rank a catalog it has never seen as soon as it is uploaded, with no interaction data and no training, and why those columns decide how well it does (catalog format).
- One pass per request. Item vectors are computed once when the catalog is embedded, so ranking the whole catalog costs one forward pass over the history rather than one per item: the model itself takes under a millisecond per query, and most of an API call's time is the network.
The notebook
notebooks/showcase.ipynb covers the model in eight steps: setup, a first query, one call for many features, how context changes the answer, then embedding your own catalog, inspecting the embedding space, querying it, and trying it in the demo.
Needs uv. Clone, install, add your key, register the kernel, start JupyterLab:
git clone https://github.com/Unbox-AI/behaviorgpt.git
cd behaviorgpt
uv sync
cp .env.example .env   # paste your key as UNBOXAI_API_KEY
uv run ipython kernel install --user --env VIRTUAL_ENV $(pwd)/.venv --name=behaviorgpt-env
uv run jupyter lab
JupyterLab opens in your browser. Open the notebook and pick the behaviorgpt-env kernel.
Your own catalog
The model can only return items it knows about. Out of the box the client uses retail_catalog, a sample retail catalog. To use the model on your own data, upload your catalog as a parquet file. A catalog doesn't have to be products for sale: artworks, articles, listings or anything else people browse and pick from work the same way.
docs/catalog-format.mdlists the required columns and types.- A catalog can hold at most 100,000 items.
- Each API key can hold 2 catalogs. The file name is the catalog's name: uploading a file with the same name again refreshes that catalog and keeps its
catalog_id, and a new name takes one of the 2 slots. A failed upload does not use up a slot. Once both slots are in use, an upload under a new name is refused; to remove a catalog or raise the limit, contact alexander@unboxai.com. examples/sample_catalog.csvis an example only, showing what each column should contain. Your own file will look different depending on your catalog, and it has to be converted to the parquet structure described in the format doc before upload.
job = client.embed("my_catalog.parquet", wait=True, timeout=1800.0)
client.complete([Search("...")], catalog_id=job.catalog_id)
Adding or updating items
To add items to an embedded catalog, or change some of its items, upload just those items in the same format. Only they are embedded, so the job takes about as long as the file is big, and the catalog keeps answering queries while it runs:
client.add_items("new_items.parquet", catalog_id=job.catalog_id, wait=True)
- An item whose
idis already in the catalog is replaced with the new row; any other item is added. Nothing is removed. - The new items are embedded at the catalog's own reference time, so their ages and sales are measured the same way as the rest of the catalog's.
- The 100,000-item limit counts the whole catalog: the items it holds plus the new ones.
- One
add_itemsjob runs per catalog at a time, and the catalog cannot be refreshed or deleted while it runs. - Uploading the catalog's file again with
embedreplaces the whole catalog, added items included. Put them in that file too to keep them. - A catalog embedded before
add_itemsexisted needs one more full upload before items can be added to it.
If mapping your data to the format is hard, open a coding agent in this directory and ask it to embed your catalog. The repo ships a skill at .claude/skills/embed-catalog/SKILL.md that walks the agent through mapping your columns, building and validating the parquet, checking image URLs, and uploading. Claude Code picks it up automatically; for other agents, point them at that file.
Events
A history is a list of Search, View, AddToCart, RemoveFromCart and Order events. The names come from a store because that is what the API accepts, but they work for any catalog: map your users' actions by meaning. Curate my wall sends "look closer" as View, "hang it on the wall" as AddToCart and "take it down" as RemoveFromCart.
Demo and examples
More on the three apps shown at the top of this page:
- behaviorgpt.unboxai.com: a storefront, with recommendations, personalized search and a cart driven by the shopper's clicks. To try it on your catalog once it is embedded, select the BehaviorGPT V4.0-12.5B model, choose Bring your own catalog and enter your API key. Images must be publicly reachable for the demo to display them.
- Curate my wall (live app): an art recommender over 19,000 public-domain artworks from the Art Institute of Chicago. It shows the whole path for a catalog that isn't products: turning an open dataset into a catalog, embedding it, and driving recommendations, search, similar items and the embedding map from a visitor's clicks.
- Art to fashion. Its fashion pilot puts H&M clothing in the same catalog as the art, and the "Fashion for you" tab ranks it from the visitor's art clicks alone: kimonos for Japanese prints, beaded bracelets for ancient Egypt, statement earrings for portraits. No event in the history involves clothing. It works because the art and the clothing share one catalog; a
filtersquery keeps the art grids art-only.
- Art to fashion. Its fashion pilot puts H&M clothing in the same catalog as the art, and the "Fashion for you" tab ranks it from the visitor's art clicks alone: kimonos for Japanese prints, beaded bracelets for ancient Egypt, statement earrings for portraits. No event in the history involves clothing. It works because the art and the clothing share one catalog; a
- Anomaly detection: scores every step of a shopping session by how likely the model finds it given the history so far, and flags the step where a session crosses a calibrated risk barrier, naming the items that pushed it there. It needs no fraud labels, rules or training. It runs on the public
retail_catalog, and its bundled examples work without an API key.
1 maintainer

Metadata
1 maintainer
Release files for behaviorgpt 0.2.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| behaviorgpt-0.2.2.tar.gz | 19.6 kB | With provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| behaviorgpt-0.2.2-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 43.7 kB
Release files / behaviorgpt-0.2.2.tar.gz
| Download URL | behaviorgpt-0.2.2.tar.gz |
|---|---|
| Size | 19.6 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
4983e07cfa181571bb09eb2742d594d279eca140ef0303382f5c0402e495b4a9
|
|
BLAKE2b-256 checksum How to use checksums |
fd36b99dd5917e43f6bb0938396f886731218fe8b6fc249e9c595da3b01840ef
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 18, 2026.
Transparency logRelease files / behaviorgpt-0.2.2-py3-none-any.whl
| Download URL | behaviorgpt-0.2.2-py3-none-any.whl |
|---|---|
| Size | 24.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
b853181409c652e264cb19b8ea820e6f0706f3971918bfe141be02ac0fb80f16
|
|
BLAKE2b-256 checksum How to use checksums |
265666ec64f5bf5bf41a40a85a8859bc80a71dfe853b9917270737484842407e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 18, 2026.
Transparency logSecurity for behaviorgpt 0.2.2
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for behaviorgpt-0.2.2.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 18, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.














