


Compare Python performance across implementations and inputs with fewer false alarms.
benchmatrix adds benchmark matrices, repeated-run collection, paired experiments, and regression checks to pytest-benchmark. Define your implementations and input cases once; benchmatrix measures every combination and compares a baseline with a candidate.
Before reporting a regression, it checks that both sides ran in compatible environments, measured the same matrix, and collected enough independent runs. It then calculates a run-level confidence interval and separates meaningful changes, practical equivalence, and inconclusive results.
uv run benchmatrix measure --runs 5 --output baseline tests/test_benchmarks.py
# Make a change, then measure again.
uv run benchmatrix measure --runs 5 --output candidate tests/test_benchmarks.py
uv run benchmatrix compare baseline candidate --fail-on-regression
Results are available as readable terminal output, versioned JSON, Markdown, and GitHub Actions summaries.
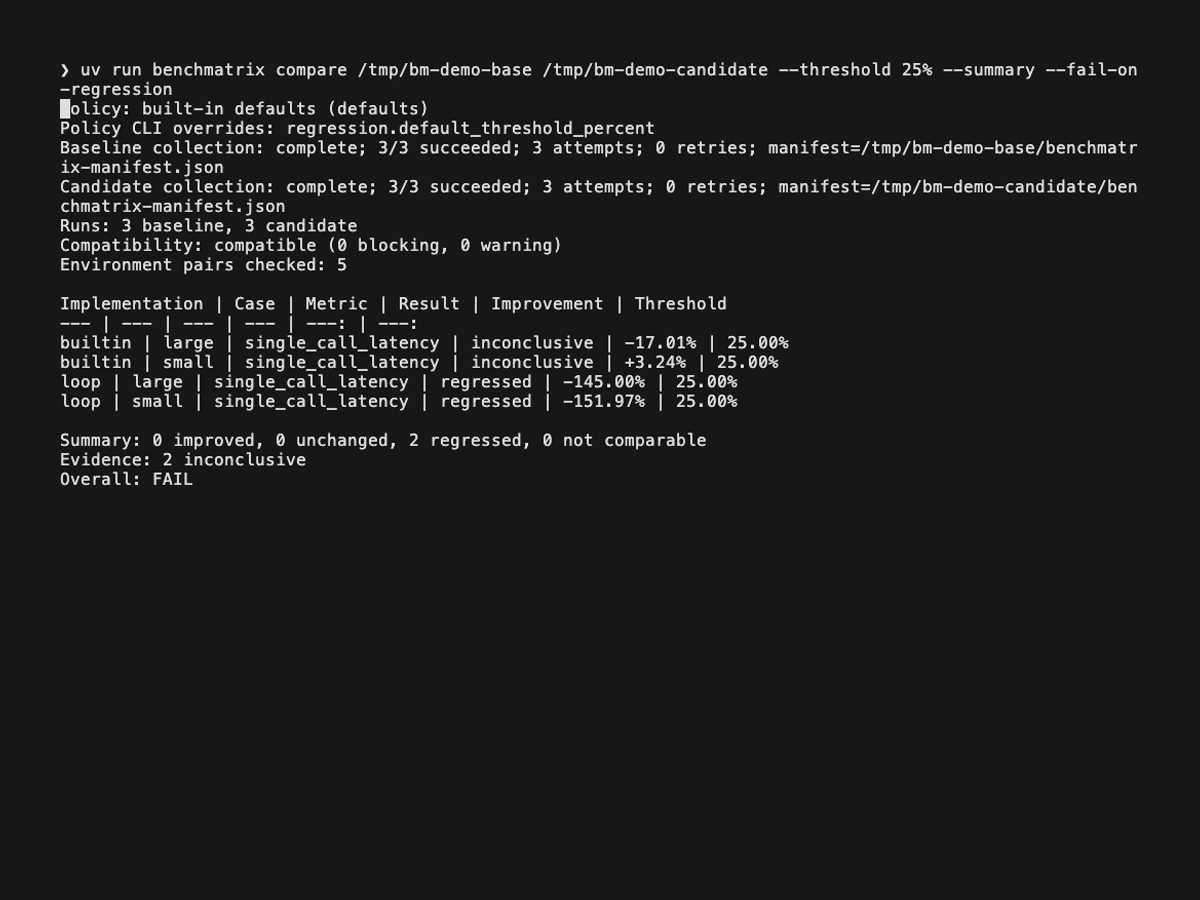
Watch benchmatrix catch an intentional regression (1 minute)
[!TIP] Read the benchmatrix documentation for the quickstart, usage guides, and API reference.
Install
uv add --dev benchmatrix
or:
python -m pip install benchmatrix
Quickstart
Create a benchmark matrix from callables in a pytest file:
from benchmatrix import BenchmarkCase, make_benchmark_test

implementations = {
    "builtin": sum,
    "loop": lambda vs: sum(v for v in vs),
}

cases = [
    BenchmarkCase.from_values(
        "small",
        list(range(100)),
        work_units=100,
        work_unit_name="items",
    ),
]

test_sum_matrix = make_benchmark_test(implementations, cases)
Keep ordinary correctness tests alongside the generated benchmark; timing a wrong answer does not make it useful evidence.
Collect a baseline, make your change, and collect a candidate on the same machine:
uv run benchmatrix measure --runs 5 --output baseline tests/test_sum_benchmark.py
# Make the change you want to evaluate.
uv run benchmatrix measure --runs 5 --output candidate tests/test_sum_benchmark.py
Compare the repeated runs and fail the command when the evidence shows a regression:
uv run benchmatrix compare baseline candidate --threshold 5% --fail-on-regression
Each output directory contains the individual pytest-benchmark JSON files and a manifest recording the command, matrix, environment, and collection lifecycle. Resume an interrupted collection without overwriting earlier runs:
uv run benchmatrix measure --resume --output candidate
uv run benchmatrix measure --retry-failed --output candidate
The same run and comparison model is available from Python:
from benchmatrix import load_benchmark_run_group

baseline = load_benchmark_run_group("baseline")
candidate = load_benchmark_run_group("candidate")
comparison = baseline.compare_to(candidate)

for cell in comparison.regressed:
    print(cell.implementation_name, cell.case_name, cell.metric_name)
For a drift-resistant experiment, collect adjacent matched blocks with
collect-paired. Baseline-first (AB) and candidate-first (BA) blocks
alternate, and both members of a pair use the same balanced matrix-cell order.
Separate the two commands with ::: after the usual -- delimiter:
uv run benchmatrix collect-paired \
    --random-seed 20260801 \
    --output paired-runs \
    --baseline-cwd ../project-baseline \
    --candidate-cwd . \
    -- \
    uv run pytest --benchmark-only tests/test_sum_benchmark.py \
    ::: \
    uv run pytest --benchmark-only tests/test_sum_benchmark.py

uv run benchmatrix compare paired-runs --paired --precision-target 2%
The equivalent Python API is:
from benchmatrix import collect_paired_benchmark_runs

pytest_command = (
    "uv",
    "run",
    "pytest",
    "--benchmark-only",
    "tests/test_sum_benchmark.py",
)
paired = collect_paired_benchmark_runs(
    pytest_command,
    pytest_command,
    "paired-runs",
    random_seed=20260801,
    baseline_cwd="../project-baseline",
    candidate_cwd=".",
)
comparison = paired.compare()
A pair contributes to inference only when both adjacent commands succeed in
the same block attempt. Resume and retry preserve every earlier record but
replace an incomplete block with a fresh two-command attempt. Use
collect-paired --resume after an interruption and
collect-paired --retry-failed for one new full-block attempt per incomplete
pair. Ordinary measure, collect, and two-source compare workflows remain
independent; compare PAIRED_DIR --paired is the explicit paired path.
When --pairs/pair_count is omitted, benchmatrix learns the matrix from the
first accepted command and chooses the smallest target of at least five pairs
that completes the joint AB/BA-by-cell-order supercycle. An explicit target is
useful for exploratory pilots, but manifest-backed formal comparison requires
a complete joint supercycle.
Metrics
benchmatrix supports three ways to measure each benchmark:
| Metric | Meaning | Better result |
|---|---|---|
| Single-call latency | Time required to complete one function call | Lower |
| Batch throughput | Number of declared work units completed per second | Higher |
| Tail latency | The slower end of the timing distribution (e.g., 95th percentile) | Lower |
Comparison policy
Keep project-wide comparison rules in pyproject.toml:
[tool.benchmatrix.evidence]
minimum_runs = 5

[tool.benchmatrix.inference]
method = "bca_bootstrap"
confidence_level = 0.95
resamples = 50000
random_seed = 0
multiplicity = "bonferroni"

[tool.benchmatrix.regression]
default_threshold_percent = 5.0

[tool.benchmatrix.regression.by_metric]
tail_latency = 8.0
Thresholds can also target an implementation, case, or exact matrix cell. A CLI option overrides only the corresponding setting; it does not discard the more specific rules.
Inspect or validate the effective policy without running a benchmark:
uv run benchmatrix policy show
uv run benchmatrix policy validate --quiet
See Configuration and automation for the full schema and precedence rules.
Reports and CI
benchmatrix's text output is intended for human readers. Complementary machine- readable, versioned JSON reports can be generated and loaded later programmatically:
uv run benchmatrix compare baseline candidate --format json > comparison.json
from benchmatrix import load_comparison_report

report = load_comparison_report("comparison.json")
print(report.schema_version, report.passed, len(report.regressed))
The same decision can be rendered as Markdown or appended to a GitHub Actions step summary:
uv run benchmatrix compare baseline candidate --format markdown
uv run benchmatrix compare baseline candidate --github-summary
Comparison checks
Before classifying a change, benchmatrix checks that both sides contain compatible environments, matching matrix cells, and five independent process runs by default. Raw pytest-benchmark rounds are nested observations used for each run's statistic and diagnostics; they are not counted as independent replicates of a code change.
The formal estimand is the direction-aware percentage ratio between the median per-run statistic on each side. benchmatrix resamples complete process-run statistics, calculates a deterministic BCa bootstrap interval, and falls back to a clearly reported percentile-bootstrap interval when the BCa adjustment is degenerate. Bonferroni adjustment controls the family-wise error rate across the structurally comparable cells in the matrix by default.
Independent comparisons resample each side separately. Explicit paired comparisons resample matched baseline/candidate tuples, preserving within-pair dependence while leaving the estimand unchanged. Pairing is never guessed from filenames, timestamps, or collection proximity. Manifest-backed paired comparisons stratify resampling by the recorded AB/BA orientation, so every bootstrap sample preserves the fixed orientation counts. The bootstrap does not force each resample to preserve its exact matrix-order-row composition; the collected supercycle crosses every row with both orientations before formal comparison is allowed.
An optional PrecisionPolicy uses paired pilot log-ratio variability to
estimate the pair count for a fresh, fixed-size future collection at a
requested multiplicative log-ratio width proxy. This planning approximation is not
power analysis or a sequential stopping rule. It applies Student-t scaling to
a within-orientation mean signed paired-log-ratio proxy; that proxy is not the formal
ratio-of-marginal-medians estimand used by paired BCa inference, so the planned
count does not guarantee the requested BCa interval width. Plans never recommend
fewer pairs than the active evidence policy permits and round up to the paired
collection's complete design supercycle. Their
additional_pairs value is only the arithmetic difference from the pilot
size; it is not permission to append runs to the pilot and reuse those outcomes
as confirmatory evidence.
A cell is regressed or improved only when its complete adjusted interval is
beyond the configured practical threshold. It is unchanged only when the
complete interval is inside the practical-equivalence region. An interval that
crosses either boundary is inconclusive; failure to prove a regression is not
treated as proof of equivalence.
Evidence output includes per-run rounds, iterations, observation counts, IQR, coefficient of variation, and outlier diagnostics. Tail-latency inference requires 100 round-duration observations and one target iteration per round by default.
A single run remains useful for descriptive comparison, but cannot produce the
default run-level interval and is therefore inconclusive. The explicit
legacy_consistency inference method preserves the earlier observed pairwise
range rule for migration and exploratory use; it is non-inferential.
benchmatrix's positioning
When using benchmatrix, pytest-benchmark still handles timing, calibration, statistics, terminal output, and JSON export. benchmatrix adds the matrix, collection, and comparison layer.
If you only need to time one function or inspect one run, pytest-benchmark may already be enough. benchmatrix is useful when you repeatedly compare the same operation across implementations and inputs, need auditable regression rules, or want portable reports without adopting a hosted benchmarking service.
benchmatrix supports synchronous Python callables; it is not a load-testing tool or a production latency monitor.
Contributing and community
Questions, bug reports, and feature ideas are welcome in GitHub Issues. See the contributing guide to make a change, and use private vulnerability reporting for security concerns. Published changes are listed in the release history.
License
benchmatrix is distributed under the MIT License.
1 maintainer

Metadata
1 maintainer
Release files for benchmatrix 1.2.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| benchmatrix-1.2.1.tar.gz | 648.5 kB | With provenance | Details for benchmatrix-1.2.1.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| benchmatrix-1.2.1-py3-none-any.whl | Python 3 | none | any | Details for benchmatrix-1.2.1-py3-none-any.whl |
Total release size: 764.8 kB
Release files / benchmatrix-1.2.1.tar.gz
| Download URL | benchmatrix-1.2.1.tar.gz |
|---|---|
| Size | 648.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
1bfa6805ef56e054d9911f3c2772ba05e6e5d5f93d3d8086b1f10e551e15aedc
|
|
BLAKE2b-256 checksum How to use checksums |
33e038e4f458429dfe9a60eef58ca7f2e5ff11b33e02eb265ff09158af12d721
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 2, 2026.
Transparency logRelease files / benchmatrix-1.2.1-py3-none-any.whl
| Download URL | benchmatrix-1.2.1-py3-none-any.whl |
|---|---|
| Size | 116.3 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
aa61517007e9c1df7f7db3480a1fd63d6f6fabd387c9e521438a76621c298f92
|
|
BLAKE2b-256 checksum How to use checksums |
cd116feef582b46f942dd46e41d465139f134829a87727e682b0e402447439b7
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 2, 2026.
Transparency logSecurity for benchmatrix 1.2.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for benchmatrix-1.2.1.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 2, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














