
Bev
System One decision models with open weights. Typed yes/no, choice and score decisions over any text, with a calibrated probability for every option, without generating text, on your own machines.


Give Bev a document (text, email, ticket, log or JSON) and typed questions. It returns typed answers: yes/no (noul),
one of the options you describe (choice), or a level on a scale you define (score), each with calibrated
probabilities. It never generates text, so there is nothing to parse and nothing to hallucinate, and it runs locally:
your documents never leave your machines.
| Model | Size | Runs on | Best for | Status |
|---|---|---|---|---|
| Bev-Large-C | 0.4B (ModernBERT-large base) | laptop CPU/GPU, edge boxes, any GPU | operations documents, logs and alerts, counting, amounts and limits, ticket routing, request safety | available |
| Bev-Pro-C | 26B (Gemma 4 26B-A4B base) | one GPU with about 60 GB | knowledge-heavy decisions: contracts, finance topics, large intent sets, dates and payment status | available |
Installation
python -m pip install bev-decisions            # Bev-Large-C: laptop CPU or any GPU
python -m pip install "bev-decisions[pro]"     # adds Bev-Pro-C: one GPU with about 60 GB
Python 3.10 or newer. The first bev.load() downloads the model from Hugging Face and caches it; after that it works
offline. Optional extras:
| Extra | Adds |
|---|---|
bev-decisions[pro] |
Bev-Pro models (GPU) |
bev-decisions[serve] |
the self-hosted HTTP server |
bev-decisions[mcp] |
the MCP server for AI assistants and agents |
bev-decisions[structured] |
schema-driven decisions with Pydantic |
bev-decisions[all] |
everything above |
Quickstart
import bev

model = bev.load()   # Bev-Large-C (laptop or GPU); bev.load(bev.PRO_MODEL) for Bev-Pro-C (large GPU)

answers = model.decide(
    "Subject: Charged twice for order 88412. I was billed $49.99 twice on 3 October. Please refund one payment today, it's urgent.",
    {
        "team":   {"type": "choice", "instructions": "Which department should handle this message?",
                   "criteria": {"billing": "billing team", "refunds": "refunds team", "technical": "technical team"}},
        "urgent": {"type": "noul",   "instructions": "Does the customer explicitly ask for urgent or same-day handling?"},
        "severity": {"type": "score", "instructions": "How severe is the problem for the customer?",
                     "criteria": ["low", "medium", "high"]},
    },
)
answers["team"]      # {"choice": ..., "confidence": ..., "probabilities": {...}}
answers["urgent"]    # {"noul": P(yes), "probabilities": {"true": ..., "false": ...}}
answers["severity"]  # {"label": ..., "score": expected level, "confidence": ..., "probabilities": {...}}
More in examples/: thirteen short scripts, from a first yes/no question to complete automations.
Run with or without a GPU
bev.load() picks the best device it finds: an NVIDIA GPU (cuda), an Apple Silicon GPU (mps), otherwise the CPU.
Choose one yourself with device=:
model = bev.load(device="cpu")                    # Bev-Large-C, no GPU needed
model = bev.load(device="cuda")                   # Bev-Large-C on an NVIDIA GPU
model = bev.load(device="mps")                    # Bev-Large-C on an Apple Silicon GPU
pro = bev.load(bev.PRO_MODEL, device="cuda")      # Bev-Pro-C: NVIDIA GPU with about 60 GB
bev "I was charged twice, please refund" --noul "Does the customer ask for a refund?" --device cpu
| Measured, one document with 3 questions | First load | Time |
|---|---|---|
| Bev-Large-C, Apple M4 Pro laptop, CPU only | about 25 s | about 0.18 s |
Bev-Large-C, Apple M4 Pro laptop, GPU (mps) |
about 22 s | about 0.05 s |
| Bev-Large-C, one NVIDIA H200 GPU | about 32 s | about 0.015 s |
| Bev-Pro-C, one NVIDIA H200 GPU | about 54 s (after the 52 GB download) | about 0.07 s |
Bev-Pro-C needs a GPU with about 60 GB; without one, use Bev-Large-C, or route mode (below) to send only the unsure answers to a GPU machine.
Use cases
| Use case | Example questions | Where the evidence is |
|---|---|---|
| Support inbox triage | which team (choice), urgent? (yes/no), customer sentiment (score) | Bev-Bench ticket questions; support intents |
| Request safety and guardrails | is this request harmful? is it a jailbreak attempt? | Aegis 2.0 and JailbreakBench |
| AI agents: tool dispatch and checks | does this need a tool? which tool? does the action move money or delete data? (MCP: bev mcp) |
typed decisions |
| Model routing | which handler: rules, a small model, a large LLM or a person? | typed decisions |
| Security and operations logs | attack category, failed logins above a number, severity, outage root cause | Bev-Bench security and alert questions |
| Back office documents | invoice total over the approval limit? | Bev-Bench invoice questions |
| Contract and policy review | does this clause look unfair to the customer? which policy rule applies? | unfair contract terms; Rules-Bench |
| Reviews and content moderation | review sentiment, toxic comment? | product reviews; toxic comments |
Automation examples
Complete scripts you can run and adapt (they use Bev-Large-C, so a laptop is enough):
| Script | What it automates |
|---|---|
| 11_automation_support_inbox.py | reads a folder of emails, routes each to a team when confident, flags urgent ones, writes routing.csv; the rest go to a person |
| 12_automation_invoice_approval.py | approves invoices clearly under the limit automatically; anything over the limit or unsure goes to a manager |
| 13_automation_agent_guard.py | checks an AI agent's proposed action: harmful requests are refused, actions that move money, delete data or contact people wait for a person |
# the pattern behind all three: ask, gate on confidence, let your code decide
answers = model.decide(email_text, bev.presets.get("ticket_triage"))
sure, review = bev.gate(answers, threshold=0.8)
if "department" in sure:
    route_to(sure["department"])
else:
    send_to_person(email_text)
Decision primitives
| Type | Use it for | Answer |
|---|---|---|
noul |
yes or no | noul: probability of yes |
choice |
one of a set you define (criteria: key → description, up to 300) |
choice, confidence, probabilities |
score |
ordered levels (criteria: list or key → description, lowest first) |
label, score (expected level: Σ index × probability), confidence, probabilities |
Up to 16 questions per call. Bev-Large-C reads the document once for all of them; Bev-Pro-C answers each question in its own scoring pass (questions with more than 26 options take a second round). Keep each question narrow and combine the answers in your code. Describe options in a few words that tell them apart, add an "other" option when nothing may fit, and keep the option order stable between calls.
Confidence gating
sure, review = bev.gate(answers, threshold=0.8)   # sure: {name: value}; review: answers below the threshold
if "team" in sure:
    route(ticket, sure["team"])
else:
    send_to_person(ticket)
Choose the threshold on a few hundred labelled examples of your own (see Evaluate on your data).
Route mode
router = bev.Router(load_strong=True, threshold=0.8)    # Bev-Large-C first, unsure answers asked again on Bev-Pro-C
result = router.decide(text, questions)
result["answers"], result["routing"]                    # routing: {"team": "fast", "urgent": "strong"}
Modes: "cascade" (default), "fast", "strong".
Schema-driven decisions
from typing import Literal
from pydantic import BaseModel, Field

class Ticket(BaseModel):
    urgent: bool = Field(description="Does the customer explicitly ask for urgent or same-day handling?")
    team: Literal["billing", "technical", "shipping"] = Field(description="Which department should handle this message?")

ticket = bev.decide_as(model, text, Ticket)     # Ticket(urgent=True, team='billing')
Workflow presets
bev.presets.names()   # ['request_safety', 'review_sentiment', 'security_log', 'service_alert', 'ticket_triage']
model.decide(text, bev.presets.get("security_log"))
model.decide(invoice, {"over_limit": bev.presets.over_limit("$8,900"), "big": bev.presets.count_above("$250.00")})
Batch processing
results = model.decide_batch([(text, questions) for text in texts], batch_size=8)
Command line
bev "I was charged twice, please refund" --noul "Does the customer ask for a refund?" --model sathiskumarjothi0/Bev-Pro-C
bev --file ticket.txt --preset ticket_triage --min-confidence 0.8
bev --file alert.txt --score "How severe is this?" --levels low medium high
bev --batch tickets.txt --preset ticket_triage
bev presets
Self-hosting
pip install "bev-decisions[serve]"
bev serve --model sathiskumarjothi0/Bev-Pro-C --port 8000     # POST /v1/decide, /v1/batch; GET /v1/presets, /health
docker compose -f compose.cuda.yaml up                         # the same server in a GPU container
pip install "bev-decisions[mcp]"
bev mcp --model sathiskumarjothi0/Bev-Pro-C                    # MCP tools: decide, decide_preset, list_presets
| Method and path | Body | Response |
|---|---|---|
POST /v1/decide |
{"state": ..., "questions": {...}} or {"state": ..., "preset": "ticket_triage"} |
{"answers": {...}} |
POST /v1/batch |
{"requests": [{"state": ..., "questions": ...}, ...]} |
{"results": [{"answers": ...}, ...]} |
GET /v1/presets, GET /health |
preset names; {"ok": true} |
MCP client configuration: {"mcpServers": {"bev": {"command": "bev", "args": ["mcp", "--model", "sathiskumarjothi0/Bev-Pro-C"]}}}.
The server listens on 127.0.0.1 and has no authentication; put it behind your own gateway (TLS, authentication, rate
limits) before exposing it.
Benchmarks
Accuracy (%) = correct answers ÷ questions on held-out test sets; the same cases for every system (October 2026). Bold = best in the row; – = not run. * = an area Bev was not built for. Question-by-question results are on the Hugging Face model card.
How much of the work can you automate?
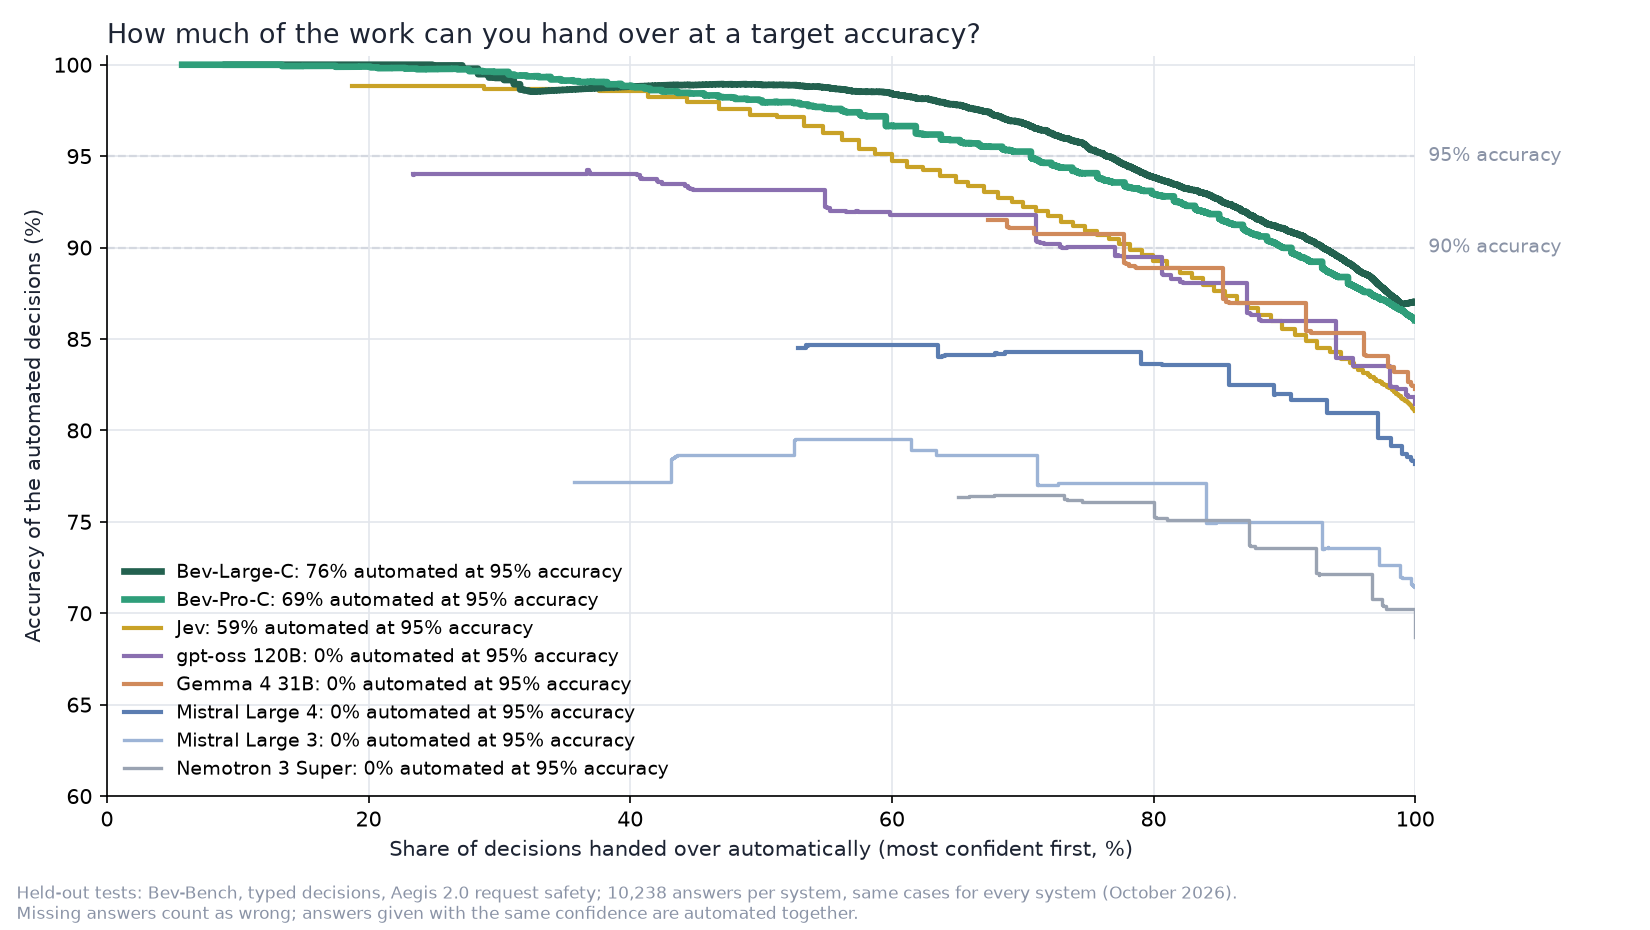
Hand over the most confident answers first: the share you can automate while those decisions stay at least 95% correct. Example: "76% at 95%" means 3 of every 4 decisions are taken automatically and at least 95% of them are right; the rest go to a person. Answers given with the same confidence are handed over together, so a system whose "100% sure" answers are only 94% right reaches 0% at the 95% target. Bev-Bench, typed decisions and Aegis 2.0, 10,238 answers per system.
| System | Automated at 95% accuracy | at 90% | Accuracy on all answers |
|---|---|---|---|
| Bev-Large-C | 76% | 93% | 87.0% |
| Bev-Pro-C | 69% | 90% | 86.0% |
| Jev | 59% | 77% | 81.1% |
| gpt-oss 120B | 0% | 74% | 81.4% |
| Gemma 4 31B | 0% | 71% | 82.2% |
| Mistral Large 4 | 0% | 0% | 78.1% |
| Mistral Large 3 | 0% | 0% | 71.4% |
| Nemotron 3 Super | 0% | 0% | 68.7% |
Size and speed
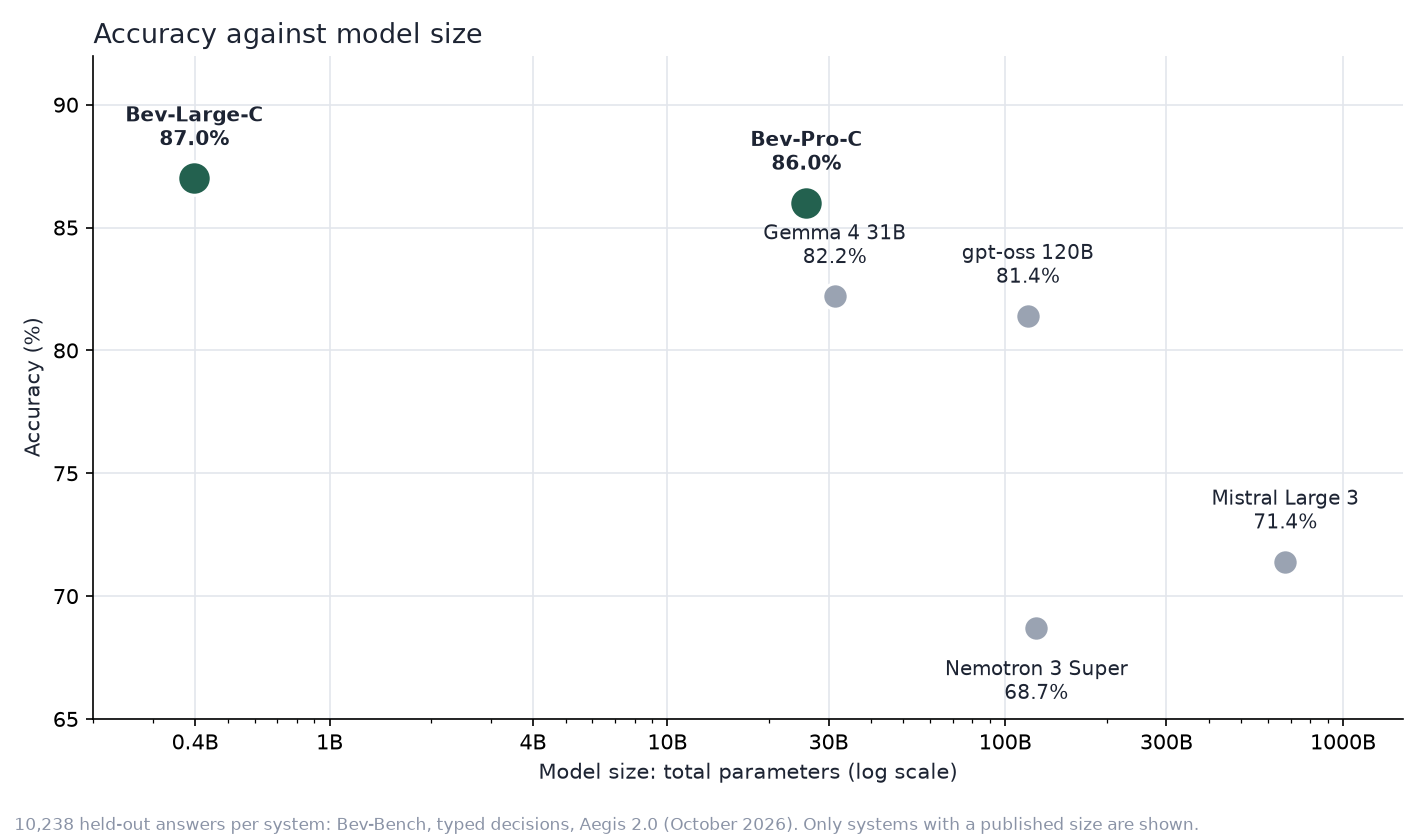
Accuracy on the same 10,238 answers against total parameters (log scale), for every system with a published size: Bev-Large-C (0.4B) and Bev-Pro-C (25.8B) are more accurate than LLMs of 31B to 675B.
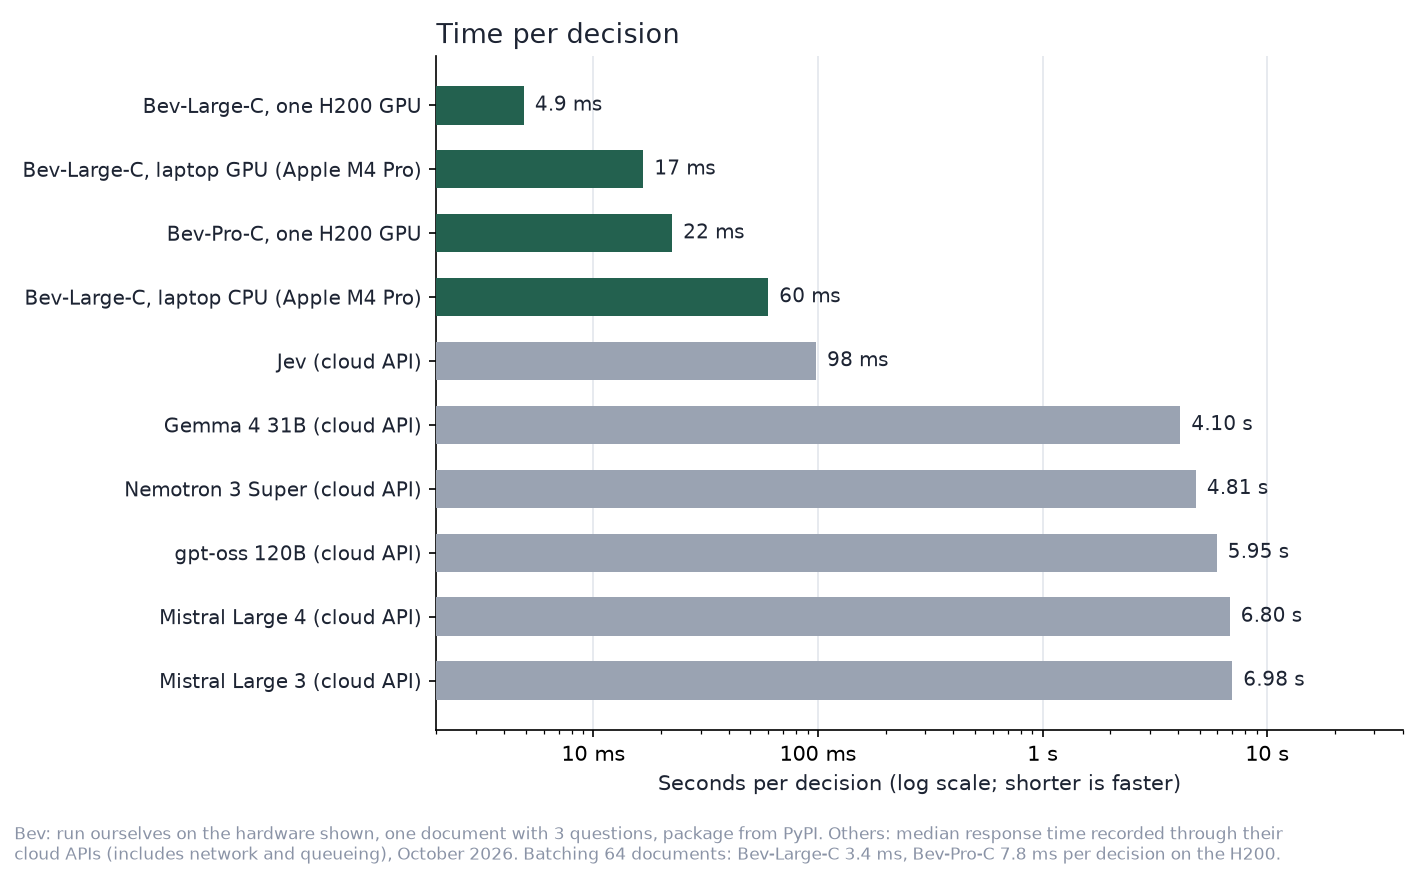
Bev, one document with 3 questions, package from PyPI: Bev-Large-C 4.9 ms per decision on one NVIDIA H200, 17 ms on an Apple M4 Pro laptop GPU, 60 ms on its CPU; Bev-Pro-C 22 ms on one H200. Jev and the LLMs were measured through their cloud APIs (median per decision, including network and queueing): Jev 98 ms, the five LLMs 4.1 to 7.0 s.
Decisions on documents
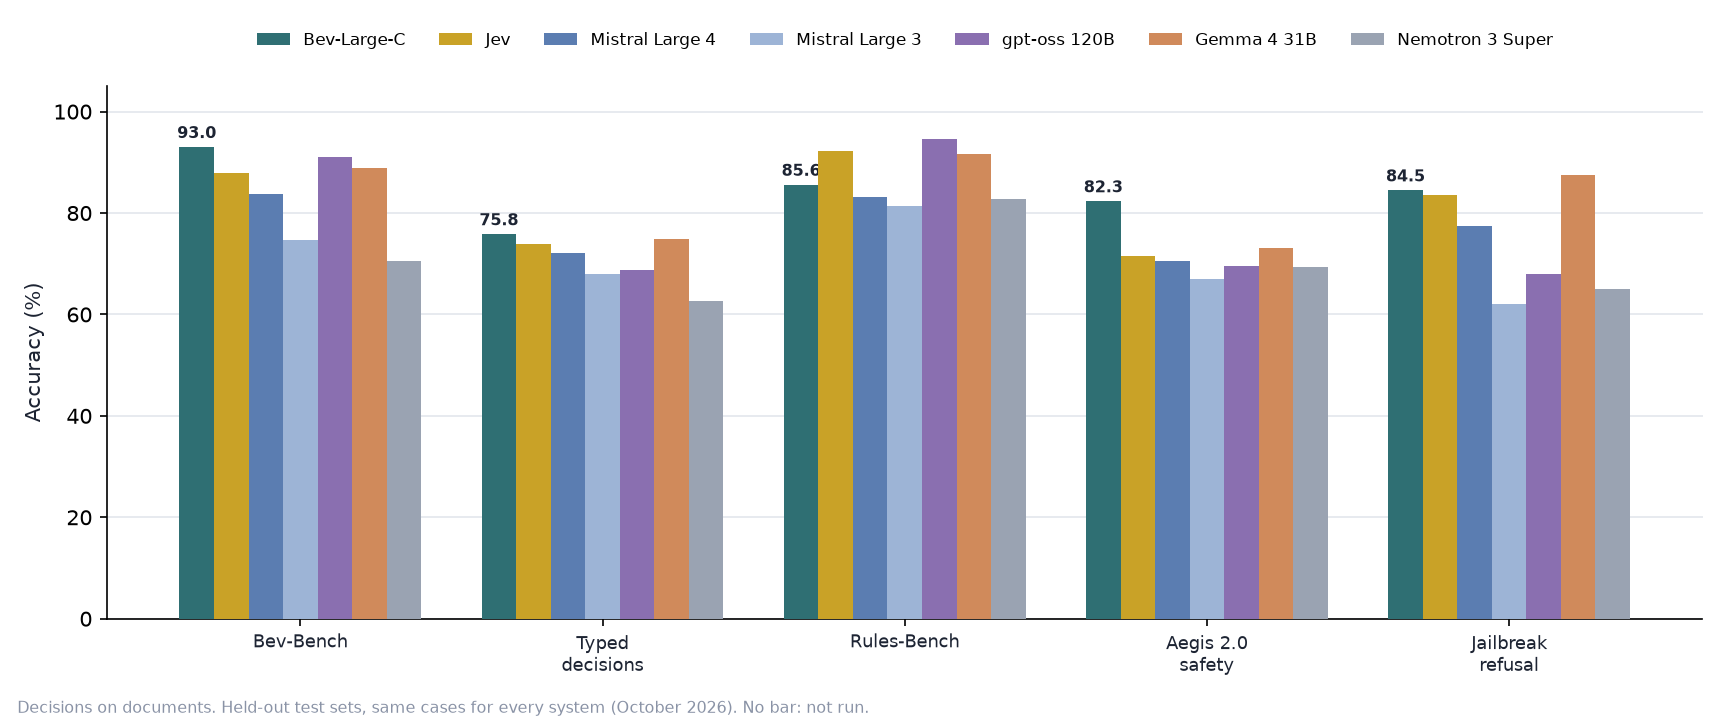
| Test | Bev-Large-C | Bev-Pro-C | Jev | Mistral Large 4 | Mistral Large 3 | gpt-oss 120B | Gemma 4 31B | Nemotron 3 Super |
|---|---|---|---|---|---|---|---|---|
| Bev-Bench (operations documents) | 93.0 | 91.9 | 87.9 | 83.7 | 74.6 | 91.1 | 88.9 | 70.6 |
| Typed decisions | 75.8 | 79.2 | 73.8 | 72.0 | 68.0 | 68.8 | 75.0 | 62.7 |
| Rules-Bench (rules shown) | 85.6 | 92.0 | 92.3 | 83.1 | 81.4 | 94.5 | 91.6 | 82.7 |
| Aegis 2.0 request safety | 82.3 | 78.2 | 71.5 | 70.5 | 66.9 | 69.5 | 73.1 | 69.3 |
| JailbreakBench refusal | 84.5 | 84.0 | 83.5 | 77.5 | 62.0 | 68.0 | 87.5 | 65.0 |
Public classification tests
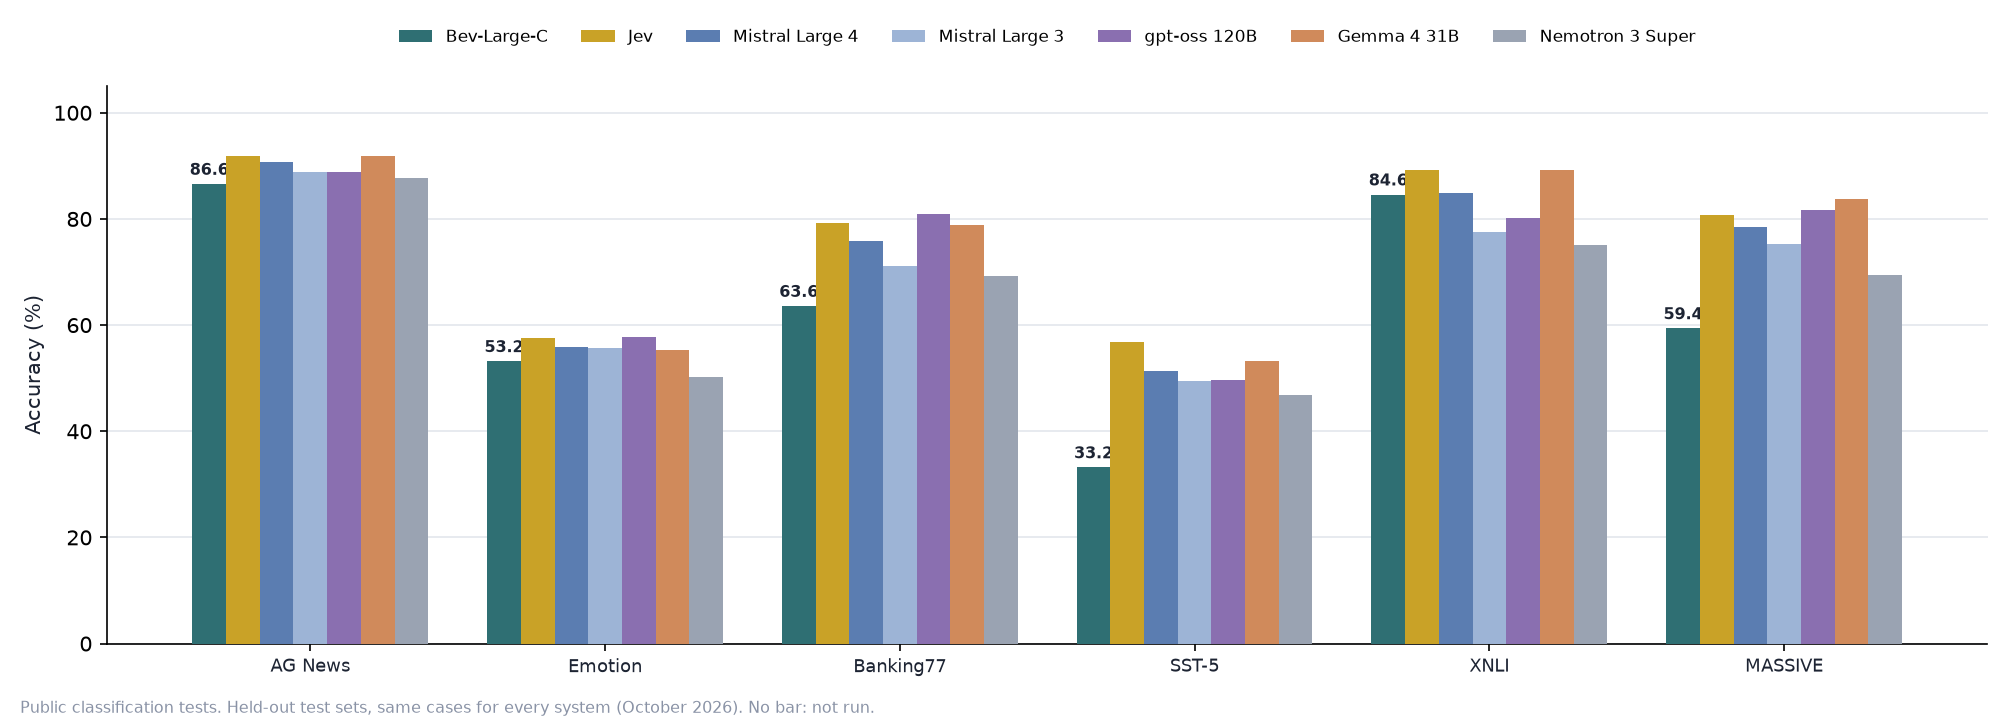
| Test | Bev-Large-C | Bev-Pro-C | Jev | Mistral Large 4 | Mistral Large 3 | gpt-oss 120B | Gemma 4 31B | Nemotron 3 Super |
|---|---|---|---|---|---|---|---|---|
| AG News | 86.6 | 90.6 | 91.8 | 90.8 | 88.8 | 88.8 | 91.8 | 87.8 |
| Emotion | 53.2 | 56.2 | 57.6 | 55.8 | 55.6 | 57.8 | 55.4 | 50.2 |
| Banking77 (77 intents) | 63.6 | 70.6 | 79.2 | 75.8 | 71.2 | 81.0 | 78.8 | 69.2 |
| SST-5 (5-level sentiment) | 33.2 | 51.8 | 56.8 | 51.4 | 49.4 | 49.6 | 53.2 | 46.8 |
| XNLI (English) | 84.6 | 86.4 | 89.2 | 84.8 | 77.6 | 80.2 | 89.2 | 75.0 |
| MASSIVE intents | 59.4 | 74.8 | 80.8 | 78.4 | 75.2 | 81.6 | 83.8 | 69.4 |
Areas Bev was not built for
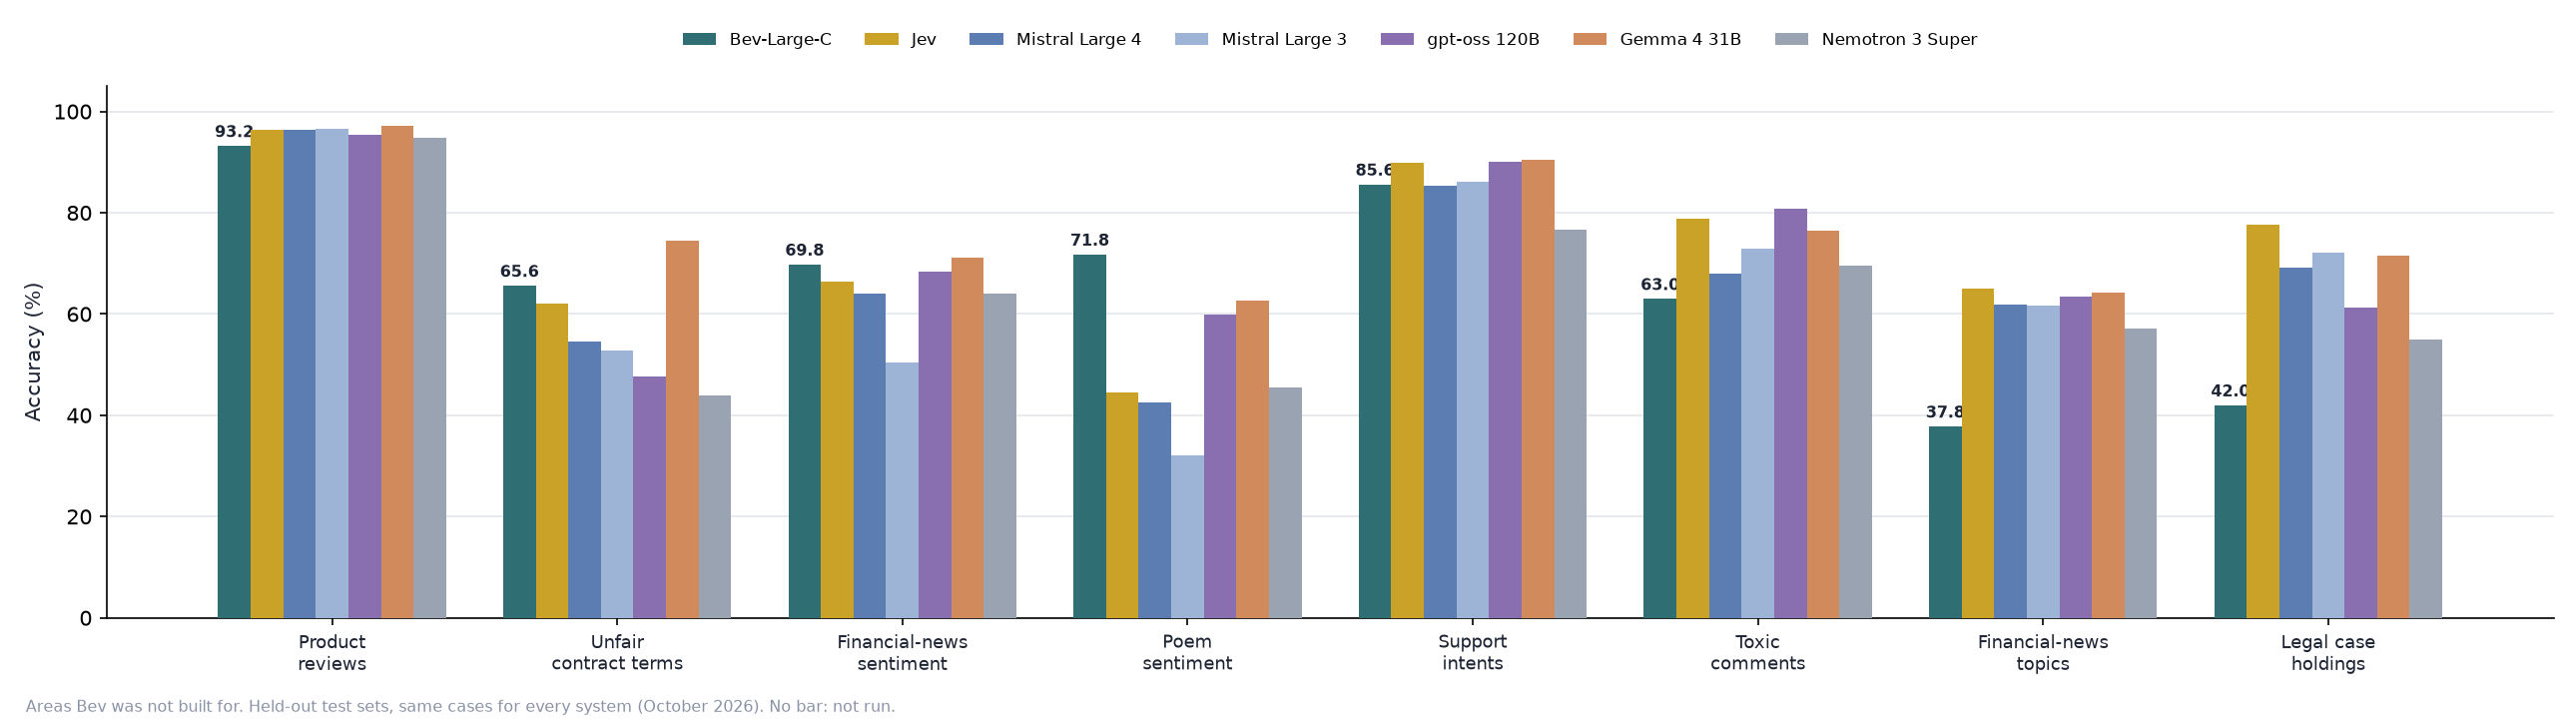
| Test | Bev-Large-C | Bev-Pro-C | Jev | Mistral Large 4 | Mistral Large 3 | gpt-oss 120B | Gemma 4 31B | Nemotron 3 Super |
|---|---|---|---|---|---|---|---|---|
| Product reviews* | 93.2 | 96.4 | 96.4 | 96.4 | 96.6 | 95.4 | 97.2 | 94.8 |
| Unfair contract terms* | 65.6 | 76.0 | 62.0 | 54.6 | 52.8 | 47.6 | 74.4 | 44.0 |
| Financial-news sentiment* | 69.8 | 59.2 | 66.4 | 64.0 | 50.4 | 68.4 | 71.2 | 64.0 |
| Poem sentiment* | 71.8 | 65.1 | 44.5 | 42.6 | 32.1 | 59.8 | 62.7 | 45.5 |
| Support intents* | 85.6 | 88.0 | 89.8 | 85.4 | 86.2 | 90.0 | 90.4 | 76.6 |
| Toxic comments* | 63.0 | 79.2 | 78.8 | 68.0 | 73.0 | 80.8 | 76.4 | 69.6 |
| Financial-news topics* | 37.8 | 69.8 | 65.0 | 61.8 | 61.6 | 63.4 | 64.2 | 57.2 |
| Legal case holdings* | 42.0 | 71.2 | 77.6 | 69.2 | 72.2 | 61.2 | 71.6 | 55.0 |
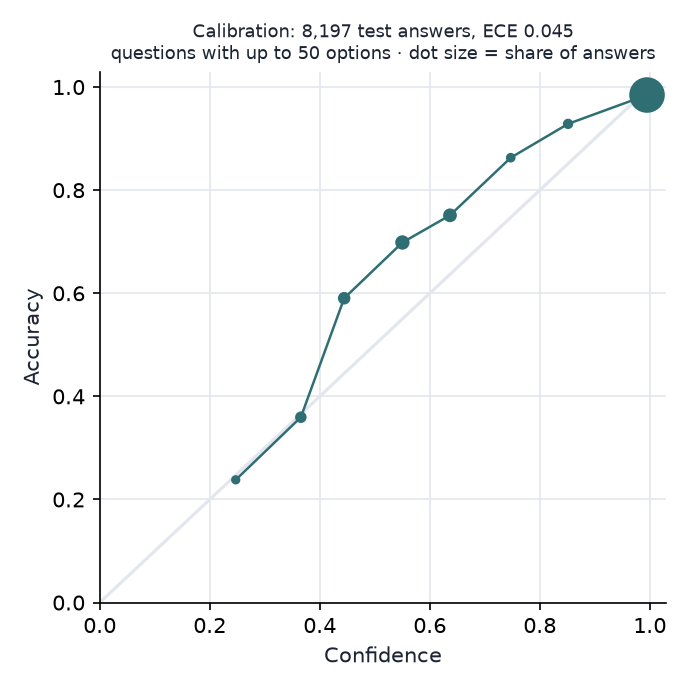
Calibration of Bev-Large-C (confidence = the probability of the answer given; ECE 0 is perfect):
| Test | Accuracy | Answered at confidence ≥ 0.8 | Accuracy of those | ECE |
|---|---|---|---|---|
| Bev-Bench (operations documents) | 93.0% | 86.9% | 98.9% | 0.029 |
| Typed decisions | 75.8% | 14.0% | 97.1% | 0.170 |
| Rules-Bench (rules shown) | 85.6% | 76.8% | 94.7% | 0.034 |
| Aegis 2.0 request safety | 82.3% | 57.0% | 94.2% | 0.034 |
| Product reviews | 93.2% | 84.2% | 96.9% | 0.024 |
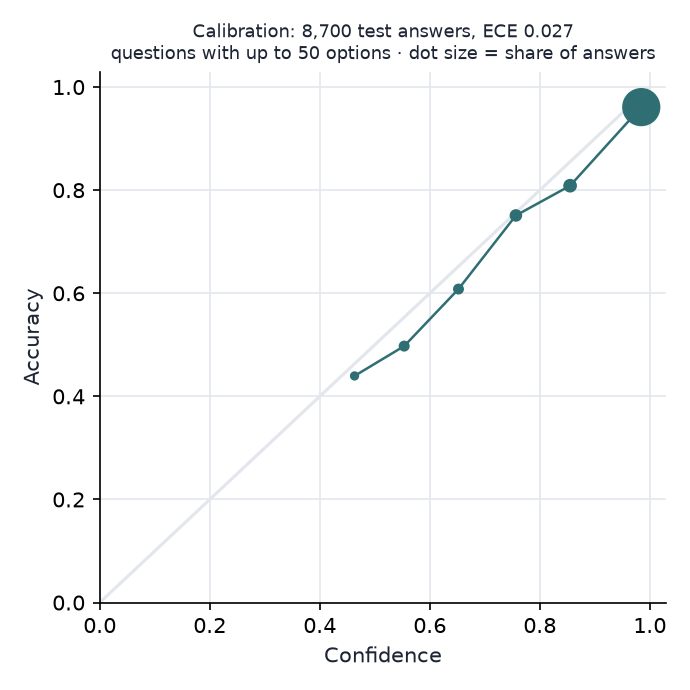
Calibration of Bev-Pro-C (confidence = the probability of the answer given; ECE 0 is perfect):
| Test | Accuracy | Answered at confidence ≥ 0.8 | Accuracy of those | ECE |
|---|---|---|---|---|
| Bev-Bench (operations documents) | 91.9% | 89.7% | 95.0% | 0.032 |
| Typed decisions | 79.2% | 61.7% | 91.5% | 0.040 |
| Rules-Bench (rules shown) | 92.0% | 87.2% | 97.0% | 0.011 |
| Aegis 2.0 request safety | 78.2% | 51.1% | 92.6% | 0.024 |
| Product reviews | 96.4% | 93.0% | 97.9% | 0.014 |
Evaluate on your data
bev eval my_cases.jsonl --threshold 0.8
Each line: {"state": "...", "questions": {...}, "labels": {"name": answer}}. Reports, per question type: accuracy
(correct ÷ questions), ECE (Σ over 10 confidence bins of share of answers × |accuracy − mean confidence|; 0 is perfect;
example: a bin with 40% of the answers at mean confidence 0.95 and 90% right adds 0.4 × 0.05 = 0.02) and, at the
threshold, the share of answers and their accuracy.
Limits
- English only; 4,096 tokens per call (longer text is cut at the end); no images.
- Knowledge-heavy decisions (case law, finance topic labels) are the weakest area; check them on your own data.
- Answers can change when the options are shuffled for a small share of questions; keep option order stable.
- For decisions with serious consequences, validate on your own data and keep a person in the loop.
- Questions with more than 26 options run as a tournament on Bev-Pro-C: lower accuracy, less calibrated confidence.
Contributing and security
Issues and pull requests are welcome; run pip install -e ".[all,dev]", ruff check src tests examples and pytest
(the tests need no model download). Report security problems privately through GitHub: Security → Report a
vulnerability.
Support
If Bev is useful to you, you can support its development: buymeacoffee.com/sjothi
Licence
Apache-2.0, © 2026 Dr. Sathiskumar JOTHI: the package and the models, commercial use allowed. Bev-Pro-C is built on Gemma 4 (Apache-2.0) by Google; Bev-Large-C on ModernBERT-large (Apache-2.0) by Answer.AI and LightOn.
1 maintainer

Metadata
1 maintainer
Release files for bev-decisions 0.2.3
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| bev_decisions-0.2.3.tar.gz | 43.5 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| bev_decisions-0.2.3-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 83.0 kB
Release files / bev_decisions-0.2.3.tar.gz
| Download URL | bev_decisions-0.2.3.tar.gz |
|---|---|
| Size | 43.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
6d77b6299b75eb36421b1fcbc52dc5bd5ebbbc09ecaf350e5fc1bf5951feb6fd
|
|
BLAKE2b-256 checksum How to use checksums |
378457f31fb5f93f9cbc6c257c8900496df7f22c5498083b9d8183049145280b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 13, 2026.
Transparency logRelease files / bev_decisions-0.2.3-py3-none-any.whl
| Download URL | bev_decisions-0.2.3-py3-none-any.whl |
|---|---|
| Size | 39.5 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
65eae51c81190c29dbd8884c3e4b8f6719c0249a43f07922c88dca2a7f1f52cf
|
|
BLAKE2b-256 checksum How to use checksums |
b7a44c042f02167d45e14996250bcb1ec5715e17b29d366e7805fa441f1909df
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 13, 2026.
Transparency log













