


⚠️ Important: Bewer is pre-1.0 and under active development. The API may change. Breaking changes are signalled by a minor version bump (e.g. 0.2.x → 0.3.0); patch releases contain only fixes and backwards-compatible additions. Pin with bewer~=0.Y.0 (pip) or ^0.Y.0 (Poetry).
Bewer is an evaluation and analysis framework for automatic speech recognition in Python. It defines a flexible approach for configuring and customizing speech recognition evaluation. The hierarchical structure, going from the dataset level down to individual tokens, makes it easy to inspect individual examples and understand evaluation results. The built-in preprocessing pipeline and metrics collection are designed to cover all conventional use cases and then some, while still being fully extensible.
Contents | Installation | Quickstart | Core Concepts | Metrics Catalog |
Installation
pip install bewer
Quickstart
from bewer import Dataset

# Create an evaluation dataset
dataset = Dataset(language="en")

# Load data
dataset.load_csv(
    "data.csv",
    ref_col="reference",
    hyp_col="hypothesis",
)

# Compute a metric
wer = dataset.metrics.wer()
print(f"{wer.short_name_base}: {wer.value:.2%}")
WER: 12.34%
Core Concepts
Hierarchy
In bewer, evaluation is centered around the Dataset object, which implements a hierarchical structure, from a collection of reference-hypothesis pairs to individual tokens.
dataset = Dataset(language="en")            # Create a dataset ...
dataset.add(ref="one two", hyp="want to")   # ... and populate it

# Climb down the hierarchy:
for example in dataset:                     # Dataset -> Example
    print(example)
    text = example.ref                      # Example -> Text
    print(text)
    for token in text.tokens:               # Text -> Token
        print(token)
Example(ref="one two", hyp="want to")
Text("one two")
Token("one")
Token("two")
Preprocessing
Text preprocessing is a central part of speech recognition evaluation, and typically requires specific considerations for different languages, domains, or tasks. The bewer preprocessing pipeline runs in three stages:
- Standardization runs on the whole string, before tokenization. It irons out inconsistencies that would otherwise affect how the text is split. The default standardizer applies Unicode NFC and unifies apostrophe, hyphen, and slash variants.
- Tokenization is regex-based, to track token boundaries in the standardized text. While not essential for metric computation, it supports richer post-hoc analysis.
- Normalization runs per token, after tokenization. At this point, token boundaries are fixed. It typically handles lowercasing, removing diacritics, and other language-specific adjustments.
The result of each stage is accessible from the corresponding objects.
text.raw                      # str: the original input
text.standardized             # str: after the standardizer
text.tokens.standardized      # list[str]: the tokens after standardization
text.tokens.normalized        # list[str]: the tokens after normalization
Pre-defined pipeline components can be found under dataset.pipelines.
print(dataset.pipelines)
Pipelines(
    standardizers: default
    tokenizers:    default, with_punctuation, key_term, orthographically_complex_term
    normalizers:   default, cased
)
Each component is named and defined as part of the dataset's configuration. Typically, it is sufficient to just choose the language, and the configuration for that language is applied automatically, but you can adapt and extend the pipeline as needed.
# TODO: Example of customizing the pipeline for a dataset
Any component can be switched with the set_pipeline context manager. The English key_term tokenizer, for instance, splits on apostrophes as well as hyphens and slashes, so that a term is still matched when it appears in the possessive form. In contrast, the default tokenizer does not.
from bewer import set_pipeline

dataset = Dataset(language="en")
dataset.add(ref="Jane Doe's", hyp="Jane Doe's")
text = dataset[0].ref

print(text.tokens.standardized)

with set_pipeline(tokenizer="key_term"):
    print(text.tokens.standardized)
['Jane', "Doe's"]
['Jane', 'Doe', 's']
In practice you will rarely need to adjust the pipeline manually. As we will see next, metrics carry the pipeline they run under, so a key-term metric is already defined to use the key_term tokenizer.
Metrics
Every metric in bewer is registered under one or more names, which makes it accessible from a dataset's metrics collection.
wer = dataset.metrics.wer()
All metrics accept the preprocessing components standardizer, tokenizer and normalizer as keyword arguments, allowing you to override the defaults they were registered with. Some metrics also accept arguments specific to their computation.
# Override the pipeline components a metric runs under (see Vocabularies below
# for how to define a key-term vocabulary):
ktf = dataset.metrics.ktf(
    tokenizer="key_term",
    vocab="medical",
)
Call dataset.metrics.list_metrics() to get an overview of available metrics and their parameters or see the metrics catalog below.
You can also register new variants of existing metrics or your own custom metrics.
from bewer.metrics import METRIC_REGISTRY, WER

# Register a custom metric in the global registry
METRIC_REGISTRY.register_metric(WER, name="my_wer", tokenizer="key_term")

# Access it from the dataset's metrics collection
my_wer = dataset.metrics.my_wer()
Every metric exposes a main value alongside the constituents it was computed from. By convention, the main value is simply value for numeric metrics and alignment for alignments.
print(wer.metric_values())
print(f"{wer.value:.2%} = {wer.num_edits}/{wer.ref_length}")
{'main': 'value', 'other': ['num_edits', 'ref_length']}
12.50% = 1/8
Most metrics are defined by aggregating over example-level values. This structure is reflected in bewer, which also exposes example-level metrics accessible through the example objects or directly from the metric object itself.
wer = dataset.metrics.wer()

assert wer[0] is dataset[0].metrics.wer()
assert wer.num_edits == sum(ex_wer.num_edits for ex_wer in wer)
Vocabularies
Key-term metrics measure performance on a pre-defined subset of terms (medical, financial, acronyms, etc.). To use them, build a Vocabulary and attach it to the dataset.
from bewer import Vocabulary

dataset = Dataset(language="en")
dataset.add(
    ref="the patient has diabetes and high blood sugar",
    hyp="the patient has diabetis and high blood sugar",
)

# Add key terms from a Python list
vocab = Vocabulary(name="medical")
vocab.add_terms(["diabetes", "blood sugar"])
dataset.add_vocabulary(vocab)

# Compute key-term recall by referencing the vocabulary name
ktr = dataset.metrics.ktr(vocab="medical")
print(f"{ktr.long_name_base}: {ktr.value:.2%}")
Key-Term Recall: 50.00%
You can also load line-separated key terms directly from a file (add_file) or write a custom function (Dataset -> Iterable[str]) to extract key terms from the dataset (add_extractor).
Alignments
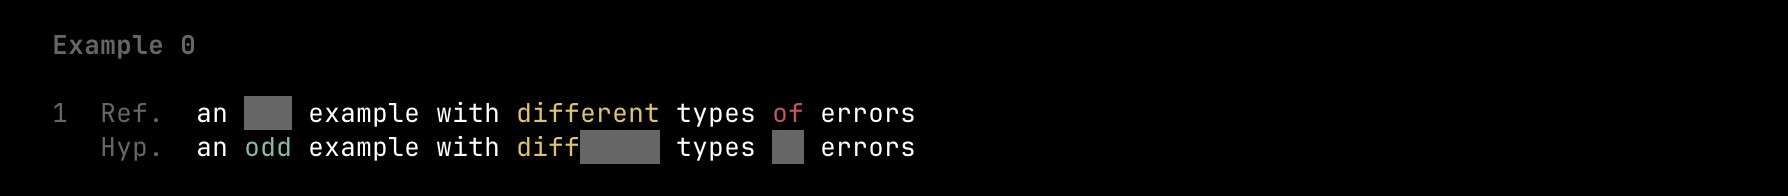
Alignments produce an example-level text-to-text alignment as their primary output, rather than a dataset-level numeric score. An Alignment is a sequence of Op objects, each representing a match, substitution, insertion, or deletion between hypothesis and reference. Edit counts are available as supportive values.
dataset = Dataset(language="en")
dataset.add(
    ref="an example with different types of errors",
    hyp="an odd example with diff types errors",
)

# Access alignments at the example level
example = dataset[0]
alignment = example.metrics.levenshtein().alignment

# Access pre-computed edit operation counts
assert alignment.num_edits + alignment.num_matches == len(alignment)
assert alignment.num_edits >= alignment.num_substitutions

# Print a color-coded two-row alignment in the console
alignment.display()
Lazy Computation and Caching
Metric values and pipeline attributes are computed lazily. The dependencies between the pipeline stages are tracked to make sure that the full pipeline is considered when deciding which computations are necessary. Once a metric is requested from the metrics collection, it is cached and reused for subsequent requests with matching parameters or by other metrics that depend on it.
wer = dataset.metrics.wer() # already uses the "default" normalizer
assert wer is dataset.metrics.wer(normalizer="default")
Metrics Catalog
| Type | Accessor | ||
|---|---|---|---|
| General purpose | |||
| Word Error Rate | General | wer |
> |
| Character Error Rate | General | cer |
> |
| Punctuation Error Rate | General | per |
> |
| Hallucination metrics | |||
| Insertion Rate | Hallucination | insertion_rate |
> |
| Key-term metrics | |||
| Key-Term Recall | Key-term | ktr |
> |
| Key-Term Precision | Key-term | ktp |
> |
| Key-Term F-Score | Key-term | ktf |
> |
| Key-Term Error Rate | Key-term | kter |
> |
| Key-Term False-Positive Rate | Key-term | ktfpr |
> |
| Key-Term Character Error Rate | Key-term | ktcer |
> |
| Relaxed Key-Term Recall | Key-term | rktr |
> |
| Orthographically complex terms | |||
| Orthographically Complex Term Recall | Key-term | orthographically_complex_term_recall |
> |
| Orthographically Complex Term Precision | Key-term | orthographically_complex_term_precision |
> |
| Orthographically Complex Term F-Score | Key-term | orthographically_complex_term_fscore |
> |
| Alignments | |||
| Levenshtein Alignment | Alignment | levenshtein |
> |
| Error Alignment | Alignment | error_align |
> |
| Dataset statistics | |||
| Dataset Summary | Summary | summary |
> |
1 maintainer

Metadata
1 maintainer
Release files for bewer 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| bewer-0.1.0.tar.gz | 73.5 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| bewer-0.1.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 176.1 kB
Release files / bewer-0.1.0.tar.gz
| Download URL | bewer-0.1.0.tar.gz |
|---|---|
| Size | 73.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
1950c9bf226e0fa87f910726785681f2236a77487a13e7e7b49cf9ded23fa6d3
|
|
BLAKE2b-256 checksum How to use checksums |
a1b58bb0e00572435359a3ad578df2237f32f02a8a05168bb504a7e67274db3a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Release files / bewer-0.1.0-py3-none-any.whl
| Download URL | bewer-0.1.0-py3-none-any.whl |
|---|---|
| Size | 102.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
96f145efd207152c3a5b76c736488a4e6d8d2f6f1722fefd95ce94d94fb0889b
|
|
BLAKE2b-256 checksum How to use checksums |
d109aa57ba42440506a7578fa242b04f6fd8895a9af2962751bcd5598f3eaf46
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|














