



BigTesty is an integration testing framework for BigQuery, running the tests on a real and short-lived infrastructure.
Documentation: tosun-si.github.io/bigtesty
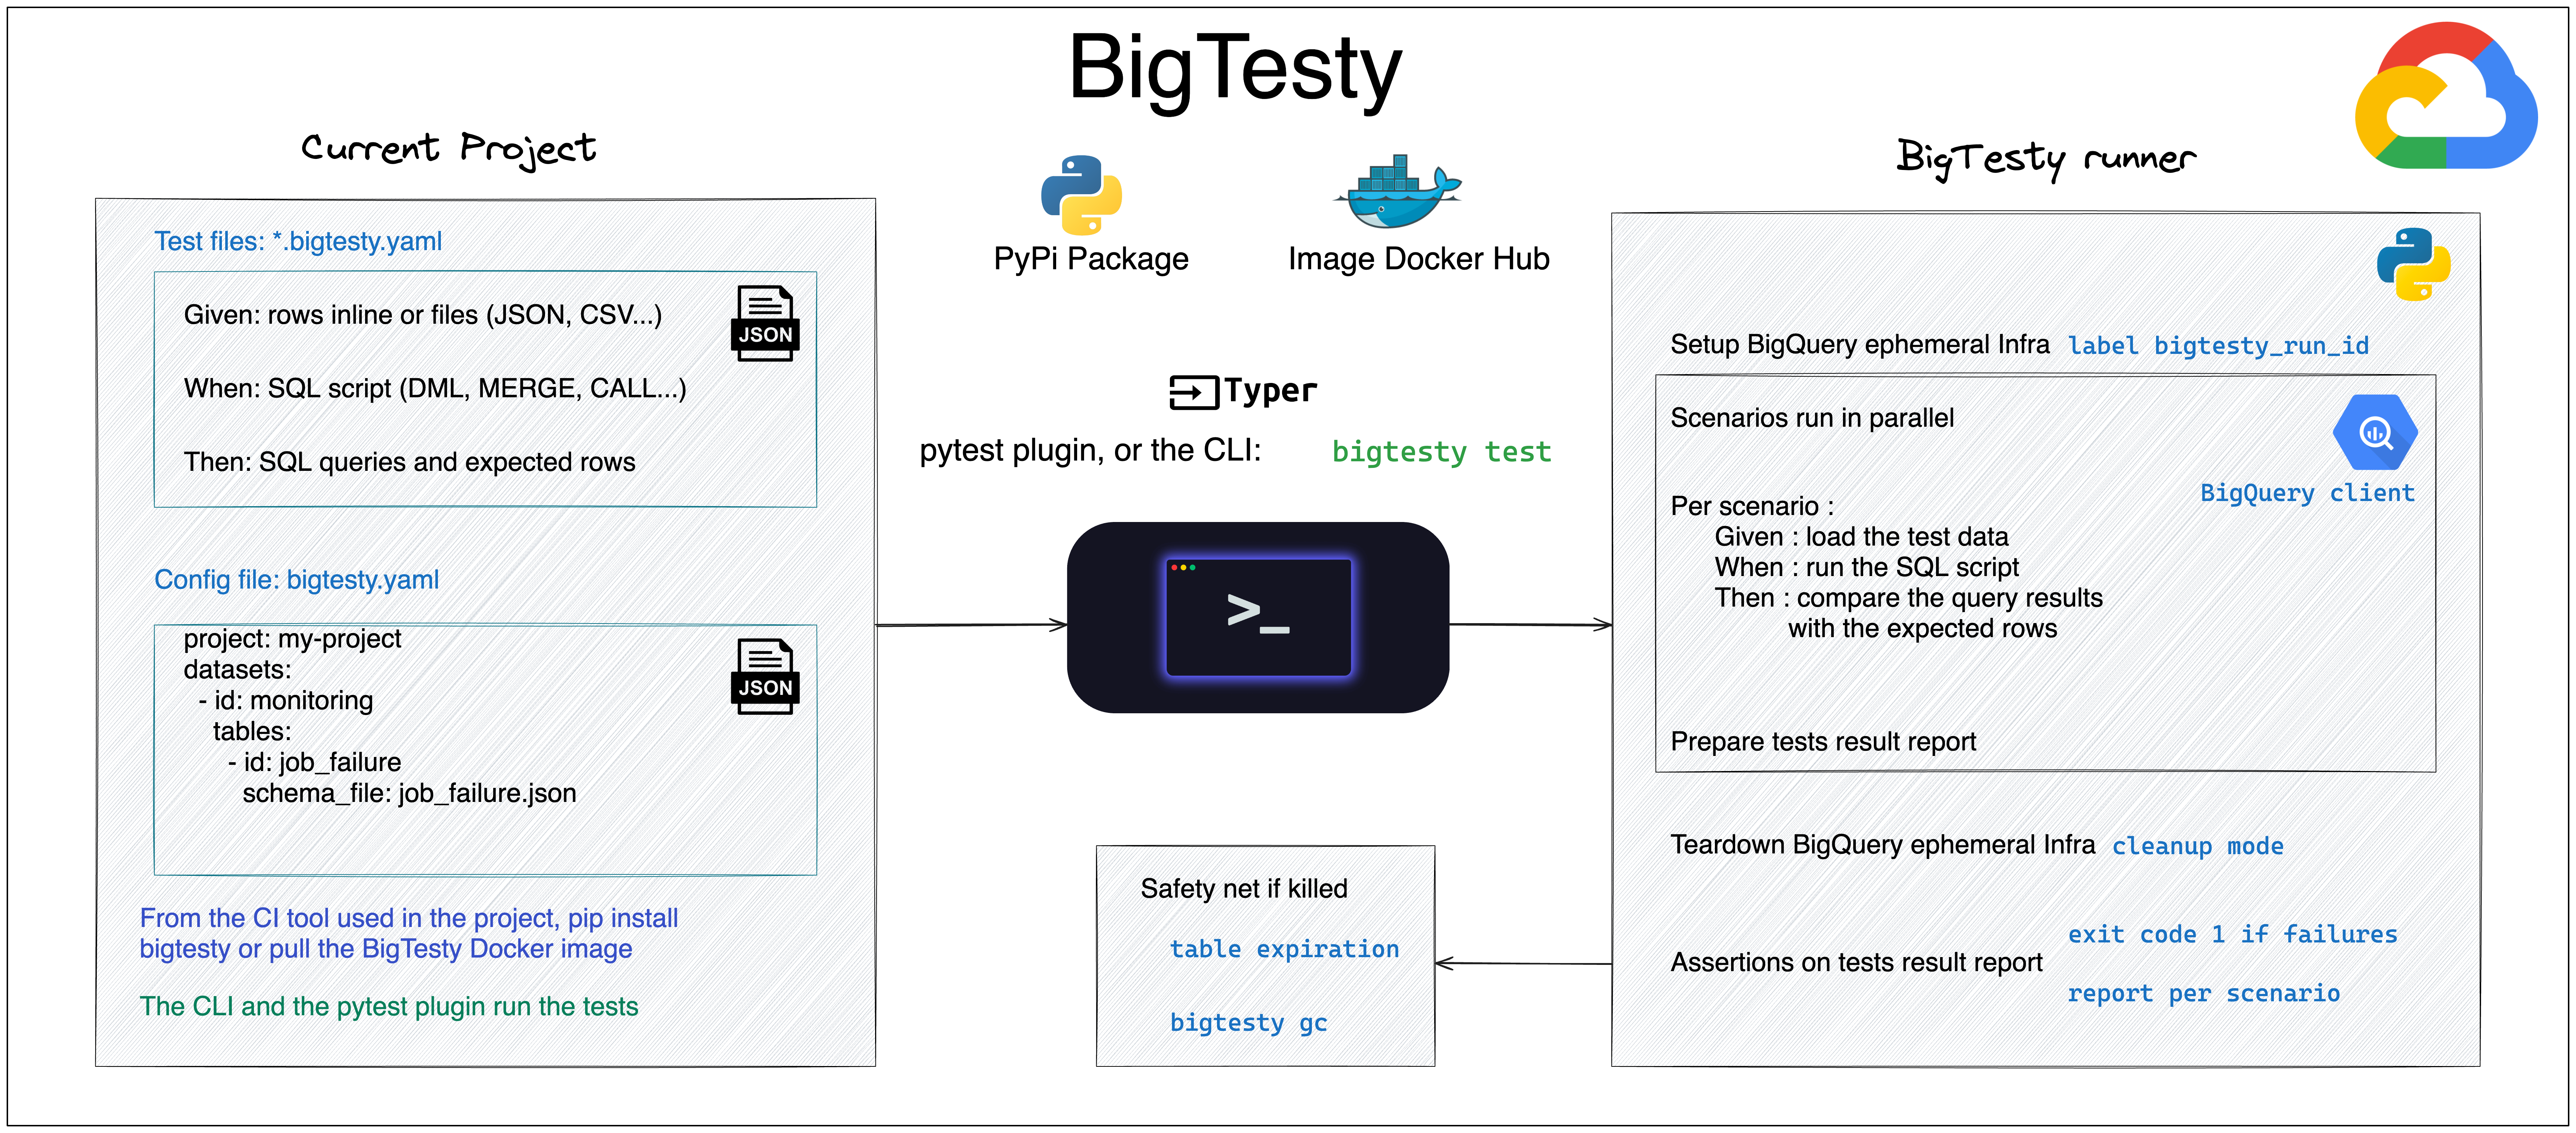
- The real BigQuery engine, no emulator: the SQL behaves exactly as in production.
- Given / When / Then test files in YAML or JSON: load test data, run any SQL (queries, DML,
MERGE, scripts, procedures), then assert on query results or table contents. - Isolated and ephemeral: each scenario of each run gets its own datasets, created and destroyed by BigTesty. Several developers and CI pipelines can run the tests at the same time.
- Production SQL unchanged: the references to your datasets are rewritten to the isolated datasets.
Installation
Python 3.11+ is required.
# as a dev dependency of a uv project, the version is locked in uv.lock
uv add --dev bigtesty
# or as a standalone CLI
uv tool install bigtesty
BigTesty uses Application Default Credentials:
gcloud auth application-default login
Quick start
A BigTesty project is a bigtesty.yaml config file declaring the datasets and tables, and test files named
*.bigtesty.yaml (or .yml / .json):
bigtesty.yaml
schema/monitoring/job_failure.json
ddl/monitoring/v_failures_count_by_feature.sql
tests/monitoring/
├── find_failures.bigtesty.yaml
├── merge_failures_summary.bigtesty.yaml
├── assertion_functions/failures_assertions.py
├── given/input_failures_feature_name.json
├── queries/find_failures_by_feature_name.sql
├── then/expected_failures_feature_name.json
└── when/merge_failures_summary.sql
bigtesty.yaml: the datasets and tables created for each scenario.
project: my-project        # or --project / GOOGLE_CLOUD_PROJECT
location: EU
tests: tests

datasets:
  - id: monitoring
    tables:
      - id: job_failure
        schema_file: schema/monitoring/job_failure.json   # BigQuery JSON schema
        partitioning: { type: DAY, field: dwhCreationDate }
        clustering: [featureName, jobName]
      - id: job_failure_summary
        schema:                                            # or inline
          - { name: featureName, type: STRING }
          - { name: failuresCount, type: INT64 }
          - { name: lastFailureDate, type: TIMESTAMP }
    ddl_files:                                             # views, functions, procedures...
      - ddl/monitoring/*.sql
tests/monitoring/merge_failures_summary.bigtesty.yaml: one or several scenarios.
scenarios:
  - name: merge_updates_existing_and_inserts_new_features
    given:
      - table: monitoring.job_failure
        rows:
          - { featureName: featurePSG, jobName: job1, dwhCreationDate: "2026-01-10 10:00:00" }
          - { featureName: featurePSG, jobName: job2, dwhCreationDate: "2026-01-11 10:00:00" }
          - { featureName: featureOM, jobName: job3, dwhCreationDate: "2026-01-12 10:00:00" }
      - table: monitoring.job_failure_summary
        rows:                                   # or rows_file, a JSON or YAML file
          - { featureName: featurePSG, failuresCount: 5, lastFailureDate: "2025-12-31 23:00:00" }
    when:
      sql_file: when/merge_failures_summary.sql
    then:
      - table: monitoring.job_failure_summary
        expected:
          - { featureName: featurePSG, failuresCount: 7, lastFailureDate: "2026-01-11 10:00:00" }
          - { featureName: featureOM, failuresCount: 1, lastFailureDate: "2026-01-12 10:00:00" }
      - query: SELECT featureName FROM monitoring.job_failure_summary GROUP BY featureName HAVING COUNT(*) > 1
        row_count: 0
Run the tests:
bigtesty test
PASSED  monitoring/find_failures.bigtesty.yaml::find_failures_by_feature_name  (4.7s)
PASSED  monitoring/find_failures.bigtesty.yaml::find_failures_by_feature_name_with_functions  (4.1s)
PASSED  monitoring/find_failures.bigtesty.yaml::find_failures_by_job_name  (3.8s)
FAILED  monitoring/merge_failures_summary.bigtesty.yaml::merge_updates_existing_and_inserts_new_features  (8.2s)

________ monitoring/merge_failures_summary.bigtesty.yaml::merge_updates_existing_and_inserts_new_features ________
then[0] / rows:
    expected 2 rows, got 2, diff from expected to actual:
    Value of root[0]['failuresCount'] changed from 8 to 7.

3 passed, 1 failed (run zivarf)
All the files used in this documentation are in the examples folder.
Test files
A scenario has 3 blocks:
given: the rows loaded into the tables, inline (rows) or from a JSON / YAML file (rows_file). The rows are loaded with load jobs: they are immediately available for DML statements.when(optional): the SQL under test (sqlorsql_file), executed as a BigQuery script: queries, DML,MERGE,CALLof a procedure, multi-statements...then: one or several assertions on aquery, aquery_fileor a wholetable:expected/expected_file: the expected rows,row_count: the expected number of rows,functions: custom Python assertion functions, called with(actual_rows, expected_rows).
Options of the then blocks:
| Option | Default | Description |
|---|---|---|
ignore_order |
true |
Compare the rows in any order. |
compare_columns |
all |
expected_only compares only the columns present in the expected rows. |
ignore_columns |
[] |
Columns excluded from the comparison. |
float_tolerance |
Absolute tolerance for the float comparison. |
The actual and expected values are compared with the types of the query result: a TIMESTAMP written
"2026-01-11 10:00:00", "2026-01-11T10:00:00Z" or "2026-01-11T12:00:00+02:00" is the same value, a NUMERIC
can be written 1.5 or "1.50", a DATE "2026-01-11"...
In YAML, yes / no / on / off and the dates stay strings: only true / false are booleans.
IDE validation
JSON Schemas are published for the config and the test files. With the VS Code YAML extension or JetBrains IDEs:
# yaml-language-server: $schema=https://raw.githubusercontent.com/tosun-si/bigtesty/main/schemas/bigtesty-test.schema.json
Isolation and SQL rewrite
For each run, BigTesty creates one dataset per configured dataset and per scenario, e.g. monitoring_hlnyks_0,
labelled with bigtesty_run_id. The references to the configured datasets in the SQL (DDL files, when and then)
are rewritten to these datasets, the formatting of the SQL is kept:
monitoring.job_failure,`monitoring.job_failure`,`monitoring`.`job_failure`my-project.monitoring.job_failure, whenmy-projectis the test project or listed inproject_aliases(e.g. the production project hardcoded in the SQL).
The comments, string literals and references to other datasets or projects are not touched.
Don't alias a table with the name of a configured dataset (FROM x AS monitoring), it would be rewritten.
The datasets are destroyed at the end of the run (cleanup: always by default, or on_success / never to analyse
the result in BigQuery). As a safety net, their tables expire after table_expiration_hours (6 by default), and
bigtesty gc deletes the datasets left by killed runs.
CLI
bigtesty test                      # run all the scenarios
bigtesty test -k merge             # only the scenarios whose ID contains "merge"
bigtesty test --cleanup never -v   # keep the datasets, show the executed SQL
bigtesty validate                  # validate the config and test files, no call to BigQuery
bigtesty gc --older-than-hours 6   # delete the datasets left by killed runs
bigtesty schema -o schemas         # write the JSON Schemas
| Option | Env var | Description |
|---|---|---|
--config, -c |
BIGTESTY_CONFIG |
Config file, bigtesty.yaml found from the current directory by default. |
--project |
BIGTESTY_PROJECT, GOOGLE_CLOUD_PROJECT |
GCP project, overrides the config. |
--location |
BIGTESTY_LOCATION |
Default location of the datasets, overrides the config. |
The exit code is 0 when all the scenarios pass, 1 when a scenario fails and 2 for an invalid config.
Run with pytest
BigTesty is also a pytest plugin, installed with the package: pytest collects the *.bigtesty.yaml / .json files,
one test per scenario. The pytest features come for free: -k, --lf, JUnit XML reports for the CI, IDE
integration...
pytest tests --bigtesty-project my-project
pytest tests -k merge --junitxml=report.xml
tests/monitoring/find_failures.bigtesty.yaml::find_failures_by_feature_name PASSED              [ 25%]
tests/monitoring/find_failures.bigtesty.yaml::find_failures_by_feature_name_with_functions PASSED [ 50%]
tests/monitoring/find_failures.bigtesty.yaml::find_failures_by_job_name PASSED                  [ 75%]
tests/monitoring/merge_failures_summary.bigtesty.yaml::merge_updates_existing_and_inserts_new_features PASSED [100%]
The ephemeral infra is created once for the selected scenarios, and the scenarios run in parallel on the first BigTesty test executed: this test shows the duration of the whole run. pytest-xdist is not needed.
| Option | Env var | Description |
|---|---|---|
--bigtesty-config |
BIGTESTY_CONFIG |
Config file, bigtesty.yaml found from each test file directory by default. |
--bigtesty-project |
BIGTESTY_PROJECT, GOOGLE_CLOUD_PROJECT |
GCP project, overrides the config. |
--bigtesty-location |
BIGTESTY_LOCATION |
Default location of the datasets, overrides the config. |
--bigtesty-cleanup |
always, on_success or never, overrides the config. |
The plugin does nothing in a project without BigTesty test files.
Run with Docker
docker run -it \
   -e GOOGLE_CLOUD_PROJECT=$PROJECT_ID \
   -v $(pwd)/examples:/usr/local/src/app/project \
   -v $HOME/.config/gcloud:/usr/local/src/app/.config/gcloud \
   groupbees/bigtesty test --config project/bigtesty.yaml
Mounting the local gcloud configuration authenticates the container with your Application Default Credentials,
without a long-lived service account key.
Run in CI
Examples for GitHub Actions, Cloud Build and GitLab CI.
Migrating from 0.x
BigTesty 1.0 replaces Pulumi by the BigQuery client and introduces a new config and test file format:
tables.json becomes a bigtesty.yaml config file, the definition_*.json files become *.bigtesty.yaml /
*.bigtesty.json test files, and the --iac-backend-url and folder options of the CLI are replaced by --config.
Python 3.11+ is required.
The migration guide gives the mapping of every option and field, with before / after examples.
Documentation
The full documentation is on the BigTesty website.
1 maintainer

Metadata
1 maintainer
Release files for bigtesty 1.0.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| bigtesty-1.0.0.tar.gz | 24.7 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| bigtesty-1.0.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 55.2 kB
Release files / bigtesty-1.0.0.tar.gz
| Download URL | bigtesty-1.0.0.tar.gz |
|---|---|
| Size | 24.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
6159ec289b37b8b03f06562ae71f8937d2d4614979d7aed6887f1ed7cf65dc73
|
|
BLAKE2b-256 checksum How to use checksums |
c2c90473cd48c1017b5fce9e0d694784c83d57b396137821b8462cebf486a4cd
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 16, 2026.
Transparency logRelease files / bigtesty-1.0.0-py3-none-any.whl
| Download URL | bigtesty-1.0.0-py3-none-any.whl |
|---|---|
| Size | 30.5 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
020e8332d2d654e5ee16023589ccabbbb8c347d99904fe4b6d194b9ee4d9f9c6
|
|
BLAKE2b-256 checksum How to use checksums |
6800adb7b71f8c41f64d07a798f4d69fec9a28a5bf7757889efbffc8ecc057cb
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 16, 2026.
Transparency log













