
BioAI Evidence Validator


Stop AI-extracted biological claims from entering your knowledge base or training set before their evidence is good enough for that use.
An LLM can turn a paper into a tidy gene → associated_with → phenotype record
that passes every schema check. This toolkit asks the next question: is the
evidence behind it sufficient for the specific use you have in mind? It checks
evidence structure, provenance consistency, scope and human-review requirements,
then returns an auditable admitted / review_required / rejected decision for
each requested use.
pip install bioai-evidence-validator
Or try it in the browser, nothing to install: quickstart notebook on Colab.
30-second example
The two records below are identical except for one field: how the supporting evidence was extracted.
   "evidence_type": "publication_result",
-  "extraction_method": "llm_extraction",
+  "extraction_method": "manual_curation",
$ bioevidence validate examples/literature_claim/llm_only.json --profile literature-claim
{
  "overall_status": "review_required",
  "findings": [
    {
      "rule_id": "BEV008",
      "severity": "review",
      "message": "Required evidence type 'publication_result' comes only from LLM extraction.",
      "blocking_uses": ["research_summary"]
    }
  ],
  "use_decisions": [
    { "use": "research_summary", "admission_status": "review_required", "reason_codes": ["BEV008"] }
  ]
}
The command exits with 2, so a pipeline can route the record to a reviewer.
The manually curated version (examples/literature_claim/curated_association.json)
is admitted with exit code 0. Every full report also records the input,
schema and profile SHA-256 hashes and versions for audit.
Why not just JSON Schema or Pydantic?
A schema tells you a record is well formed. It cannot tell you whether the record is trustworthy enough for a particular purpose.
| Schema validation | This validator | |
|---|---|---|
| Record shape and types | ✅ | ✅ (LinkML) |
| Different evidence rules per intended use (summary vs. KB vs. training) | — | ✅ |
| Quality gate per required evidence type (LLM-only evidence cannot ride on unrelated manual evidence) | — | ✅ |
| Provenance consistency (source hashes, resolved references, scope) | — | ✅ |
| Human adjudications bound to a specific statement and use | — | ✅ |
| Machine-readable audit report with hashes of input, schema and profile | — | ✅ |
On the real-data benchmark below, schema-only checks admitted 160/160 injected faults; the full validator admitted 0/160.
Use it
Write a draft, not a full record
A full record spells out identifiers, evidence lines and hashes. A draft states each fact
once; bioevidence build derives the rest and hashes local source files:
profile: literature-claim
uses: [research_summary]
statement:
  subject: {id: "SYN:GENE_A", label: Synthetic gene A, type: gene}
  predicate: associated_with
  object: {id: "SYN:PHENOTYPE_A", label: Synthetic phenotype A, type: phenotype}
  scope: ["taxon:synthetic"]
sources:
  - {id: paper, title: Synthetic paper, type: publication, version: v1,
     retrieved_at: "2026-09-21T00:00:00Z", file: synthetic_paper.txt}
evidence:
  - {source: paper, locator: Table 2, type: publication_result,
     method: llm_extraction, scope: ["taxon:synthetic"]}
bioevidence build examples/drafts/llm_claim.yaml --output record.json
bioevidence validate record.json --profile literature-claim    # exit 2: review required
Building never fills in scope, extraction method, retrieval time or review decisions for
you. For LLM pipelines, bioevidence draft-schema --profile literature-claim prints a JSON
Schema for structured output. See the draft format.
Command line
bioevidence profiles                                   # list built-in profiles and their use contracts
bioevidence build draft.yaml --output record.json       # expand a compact draft
bioevidence validate record.json --profile literature-claim
bioevidence validate record.json --profile my_profile.yaml --output report.json
bioevidence draft-schema --profile literature-claim     # JSON Schema for drafts (e.g. LLM output)
bioevidence generate-schema --output record.schema.json  # JSON Schema for full records
Exit codes: 0 admitted, 1 rejected, 2 review required, 3 input or configuration error.
Python
from bioevidence_validator import build_record, load_draft, validate_record

record = build_record(load_draft("draft.yaml"), base_dir=".")   # or load a full record JSON
report = validate_record(record, profile="literature-claim")

for decision in report["use_decisions"]:
    print(decision["use"], decision["admission_status"], decision["reason_codes"])
profile accepts a built-in name or a path to your own YAML profile.
Check records in CI
Validate every record or draft in a pull request, with a summary table and inline annotations:
# .github/workflows/evidence.yml
on: pull_request
jobs:
  evidence:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
      - uses: NingyuSUN/bioai-evidence-validator@v0.5.0
        with:
          files: records/**/*.yaml        # whitespace-separated globs
          format: draft                   # or: record (default)
          profile: literature-claim       # built-in name or path to your profile YAML
          fail-on: review                 # or: rejected
With fail-on: review (default) the job fails unless every file is admitted; with
fail-on: rejected it fails only on rejected files or files that cannot be read. The
action's outputs admitted, review_required, rejected and error hold the counts.
How it works
flowchart TD
    A["Structured evidence JSON"] --> B["LinkML structure checks"]
    B --> C["Reference and scope checks"]
    P["Selected YAML profile"] --> C
    C --> D["Evidence and human review requirements"]
    D --> E["Decision for each requested use"]
    E --> F["Audit report: findings, versions and hashes"]
    S["Frozen source evidence + intended use"] --> R["Independent human annotation"]
    R --> J["Resolve disagreements and record uncertainty"]
    J --> G["Freeze gold-standard test set"]
    G --> V["Compare held-out decisions with gold standard"]
    F --> V
    V --> M["False admission, false block and review rates"]
This diagram defines the complete project workflow. Each project supplies its own reviewed reference labels; the validator's decisions are evaluated against them. Gold labels stay separate from runtime evidence and rule development.
Domain rules are YAML profiles: new entity types, relations, evidence types and uses do not require engine edits.
| Example profile | Assertion | Use contract |
|---|---|---|
general |
Any typed entity–relation–entity statement | Provenance, scoped support, optional human review by use |
literature-claim |
Gene/variant associated with phenotype/disease | Publication evidence; human acceptance for knowledge-base admission |
dataset-label |
Sample assigned a label | Curated label plus sample link; human acceptance for training |
| Custom YAML | Compound measured response in an assay | Assay evidence; defined without changing Python code |
See Create a profile.
Run the examples from source
Python 3.11+ and uv, from the repository root:
uv sync --frozen --extra dev
uv run bioevidence profiles
uv run bioevidence validate examples/general/curated_assertion.json
uv run bioevidence validate examples/literature_claim/llm_only.json --profile literature-claim
uv run bioevidence validate examples/custom_profile/assay_record.json --profile examples/custom_profile/assay.yaml
uv run pytest
Build a gold standard for your project
- Define the task: specify the domain, intended uses, label definitions and evidence requirements in a written rubric.
- Select and freeze cases: retain source versions and record hashes; group related entities and aliases into the same development/test split.
- Review independently: domain reviewers label mapping correctness and use-specific admission without seeing validator predictions; record evidence and uncertainty.
- Resolve and version: preserve original reviews, document disagreements and adjudication, then freeze the labels and provenance manifest.
- Evaluate: compare held-out decisions with that reference; report false admissions, false blocks and review rates with counts and denominators.
Use the annotation templates and detailed protocol. Each gold standard is specific to a task, source version and intended use. Document reviewer roles and whether labels are single-reviewed or independently reviewed by multiple people.
Real-data case
VBO canine name mapping uses a frozen public ontology: 72 real-name cases, 160 controlled errors, and 16 separately reported trust-boundary cases. It compares schema-only checks, the previous aggregate quality gate, and per-required-evidence-type validation. Source-derived labels are not expert annotations.
uv run python examples/vbo_canine/run.py --output artifacts/vbo-canine
Benchmark results (v0.4.1)
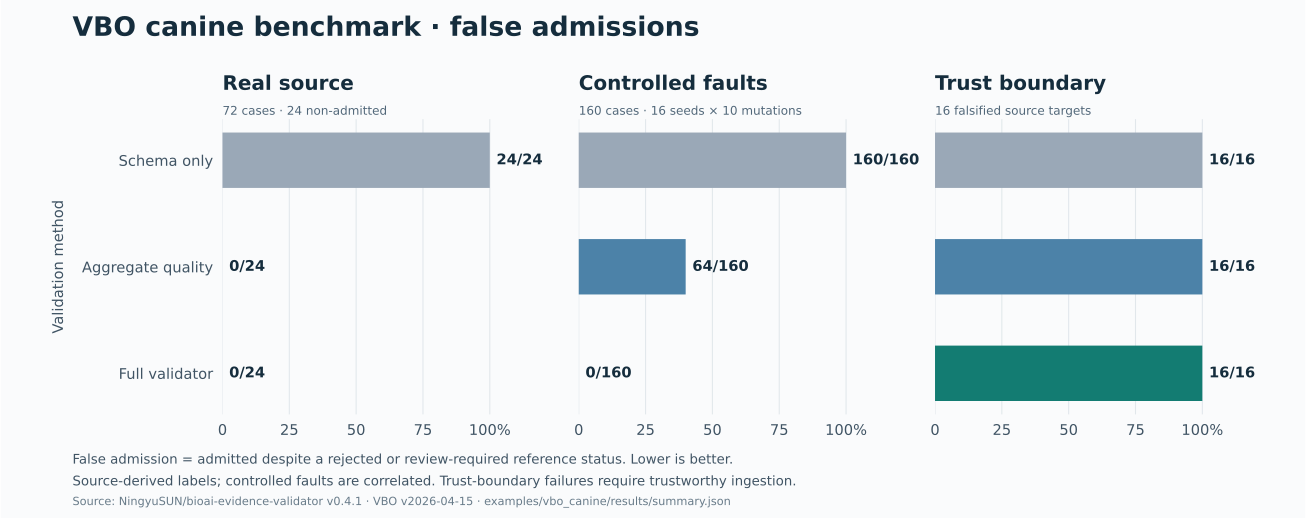
On 72 real-source name mappings, the full validator admitted all 48 unambiguous cases and blocked automatic admission of all 24 ambiguous names (0/48 false blocks; 0/24 false admissions). Across 160 deliberately injected faults, false admissions were 160/160 for schema-only, 64/160 for the aggregate-quality ablation, and 0/160 for the full validator; the full validator sent 80 cases to review and rejected 80. All three methods admitted 16/16 falsified-target trust-boundary cases, showing the need for trustworthy source ingestion and supplied metadata.
Interpretation limits: Reference labels are derived from the pinned VBO source and authored fault specifications, not independent expert annotations. The 160 mutations share 16 seed cases and are correlated. This benchmark tests the mapping contract and controlled fault detection; it does not estimate biological accuracy or production error rates. See the protocol and full results and machine-readable summary.
Scope
The VBO case uses attributed public data; other fixtures are synthetic. Admission means the supplied record meets the selected profile, not that a biological claim is true. The toolkit does not retrieve papers, verify reviewer identities, train models, or measure prediction accuracy. The generic core compares supplied hashes; the VBO importer also hashes its local source projection. External source truth and cohort independence require upstream verification.
Versions and branches
main is the domain-neutral framework (0.5.0). The complete canine implementation
and SQLite adapter from 0.3 live on the
canine-breed branch;
see the 0.4 migration guide and
changelog.
Citing
If you use this toolkit in research, please cite it using the metadata in
CITATION.cff
(GitHub's "Cite this repository" button generates APA and BibTeX).
Create a profile · Draft format · Engineering contract · Design case study · Architecture decision · Apache-2.0
1 maintainer

Release files for bioai-evidence-validator 0.5.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| bioai_evidence_validator-0.5.0.tar.gz | 249.5 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| bioai_evidence_validator-0.5.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 275.7 kB
Release files / bioai_evidence_validator-0.5.0.tar.gz
| Download URL | bioai_evidence_validator-0.5.0.tar.gz |
|---|---|
| Size | 249.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
5cd6630b4a34be13a7192384ca8c647023767a7f89a9e733862343c03e96b45e
|
|
BLAKE2b-256 checksum How to use checksums |
8eda1bea688a01a6d0e1081c38077c9e2fdb8d54dafe9de02785794e8ecfd7a4
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 25, 2026.
Transparency logRelease files / bioai_evidence_validator-0.5.0-py3-none-any.whl
| Download URL | bioai_evidence_validator-0.5.0-py3-none-any.whl |
|---|---|
| Size | 26.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
942810b7b90bde15023afd3883becb985a330880ed816c61a30f1ccc68b02f5d
|
|
BLAKE2b-256 checksum How to use checksums |
9808a59ec88f0f3b8a6f5e558971e9072f7aad967833f9078e86b1d09f641353
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 25, 2026.
Transparency log













