
This release is a pre-release and may not be stable for production use.
BioNeMo Inference Runtime
Easy, fast, and memory-efficient structure prediction inference
GPU-accelerated inference for protein, nucleic-acid, and ligand structure prediction models — from FASTA/MSA to PDB/mmCIF.



About
BioNeMo Inference Runtime (BioIR) is NVIDIA's library for structure-prediction
inference. A five-stage GPU pipeline turns AlphaFold-lineage and all-atom models
into PDB/mmCIF with confidence scores. Models stay ordinary nn.Modules — no
TensorRT engine build.
Disclaimer
BioIR is in a Beta state, may not be fully functional, may contain errors or design flaws, and may be changed at any time without notice. We appreciate your feedback to improve and iterate on our products.
Getting Started
Prerequisites
- Linux, x86_64 or aarch64, with an NVIDIA GPU. The wheels are
manylinux_2_34, so the host needs glibc 2.34 or newer — Ubuntu 22.04, RHEL 9 or later. - Driver 580 or newer. The dev image carries a CUDA 13.2 build of PyTorch. An older driver runs it only through the forward-compatibility shim, which we have measured hanging and crashing part-way through a run rather than merely running slowly — results taken on one are discarded, not corrected.
- Python 3.12. The released wheels are tagged
cp312, so pip finds no matching build on a newer interpreter. - Docker and the NVIDIA Container Toolkit, to build from source in the dev container. Installing the wheel needs neither.
PyTorch and the CUDA math libraries arrive as wheel dependencies, or in
nvcr.io/nvidia/pytorch:26.05-py3 when you use the container. Building the
extension from source outside a container needs a C++17 compiler and CUDA
headers as well — docs/dev.md.
Supported GPUs
BioIR runs on the Ampere, Ada Lovelace, Hopper, and Blackwell GPUs listed in the support matrix. The doc also shows which fused kernels apply to each architecture. Benchmarks page shows detailed speedup, memory, and accuracy for these GPUs: H200, H100, A100, L40S, GB200, and GB300.
Install
BioIR is published on PyPI, one wheel per CPU architecture:
pip install bionemo-ir
The wheel ships the kernels precompiled, so nothing in the install builds CUDA
and running it needs only the driver's libcuda.so.1. That is the whole install
if you are calling BioIR from your own code — the container below is for working
on BioIR itself. docs/install.md covers the environment
setup and the requirements in full.
Build from source
Configure SSH authentication with GitHub, then clone the repository and fetch its submodules and LFS objects.
git lfs install &&
  GIT_LFS_SKIP_SMUDGE=0 \
    git clone --recurse-submodules \
    git@github.com:NVIDIA-BioNeMo/BioNeMo-Inference-Runtime.git &&
  cd BioNeMo-Inference-Runtime
On a host with the required compiler and CUDA headers, uv provisions the pinned Python and exact dependency set, builds the editable extension, and runs tools inside that environment:
uv sync --locked
uv run --locked scripts/fetch_weights.sh --model boltz-2
uv run --locked python examples/folding/run_demo.py --output-dir output
The supported container workflow remains available when the host is not configured:
docker/dev.sh
Then run inside its shell:
uv lock --check
uv pip install --no-deps -e .
scripts/fetch_weights.sh --model boltz-2
python examples/folding/run_demo.py --output-dir output
Checkpoints come from their upstream publishers and need no NVIDIA credentials;
anything that cannot be fetched is skipped, and the tests needing it skip too.
Running uv run --locked scripts/run_tests.sh on the host, or
scripts/run_tests.sh in the container, stages weights and runs the suite the
way CI does.
See docs/dev.md
for the host prerequisites, environment details and wheel build.
docs/ref/docker-images.md covers the images and
what docker/dev.sh mounts.
Documentation
BioIR documentation lives under docs/ and is published with Fern:
- Overview — what BioIR is and how to start
- Installation — requirements and release-wheel installation
- Quickstart — run a serial Boltz-2 prediction
- Ray multi-GPU inference — scale independent requests across visible GPUs
- Accelerate a custom model — swap BioIR modules into your own PyTorch model
- Port a data pipeline — run a new model
family through
build_processor - Validate a ported pipeline — feature equivalence and end-to-end accuracy against upstream
- Developer guide — build, test, stage weights, contribute
- API reference —
build_processor, model constructors, inputs/outputs - Architecture — five-stage pipeline and runtime design
- Config architecture — model
BaseConfigtree and pipeline stage configs - Support matrix — models, GPUs, and fused kernels
- Token padding — what BioIR pads to a multiple of 8 tokens, and why it runs faster
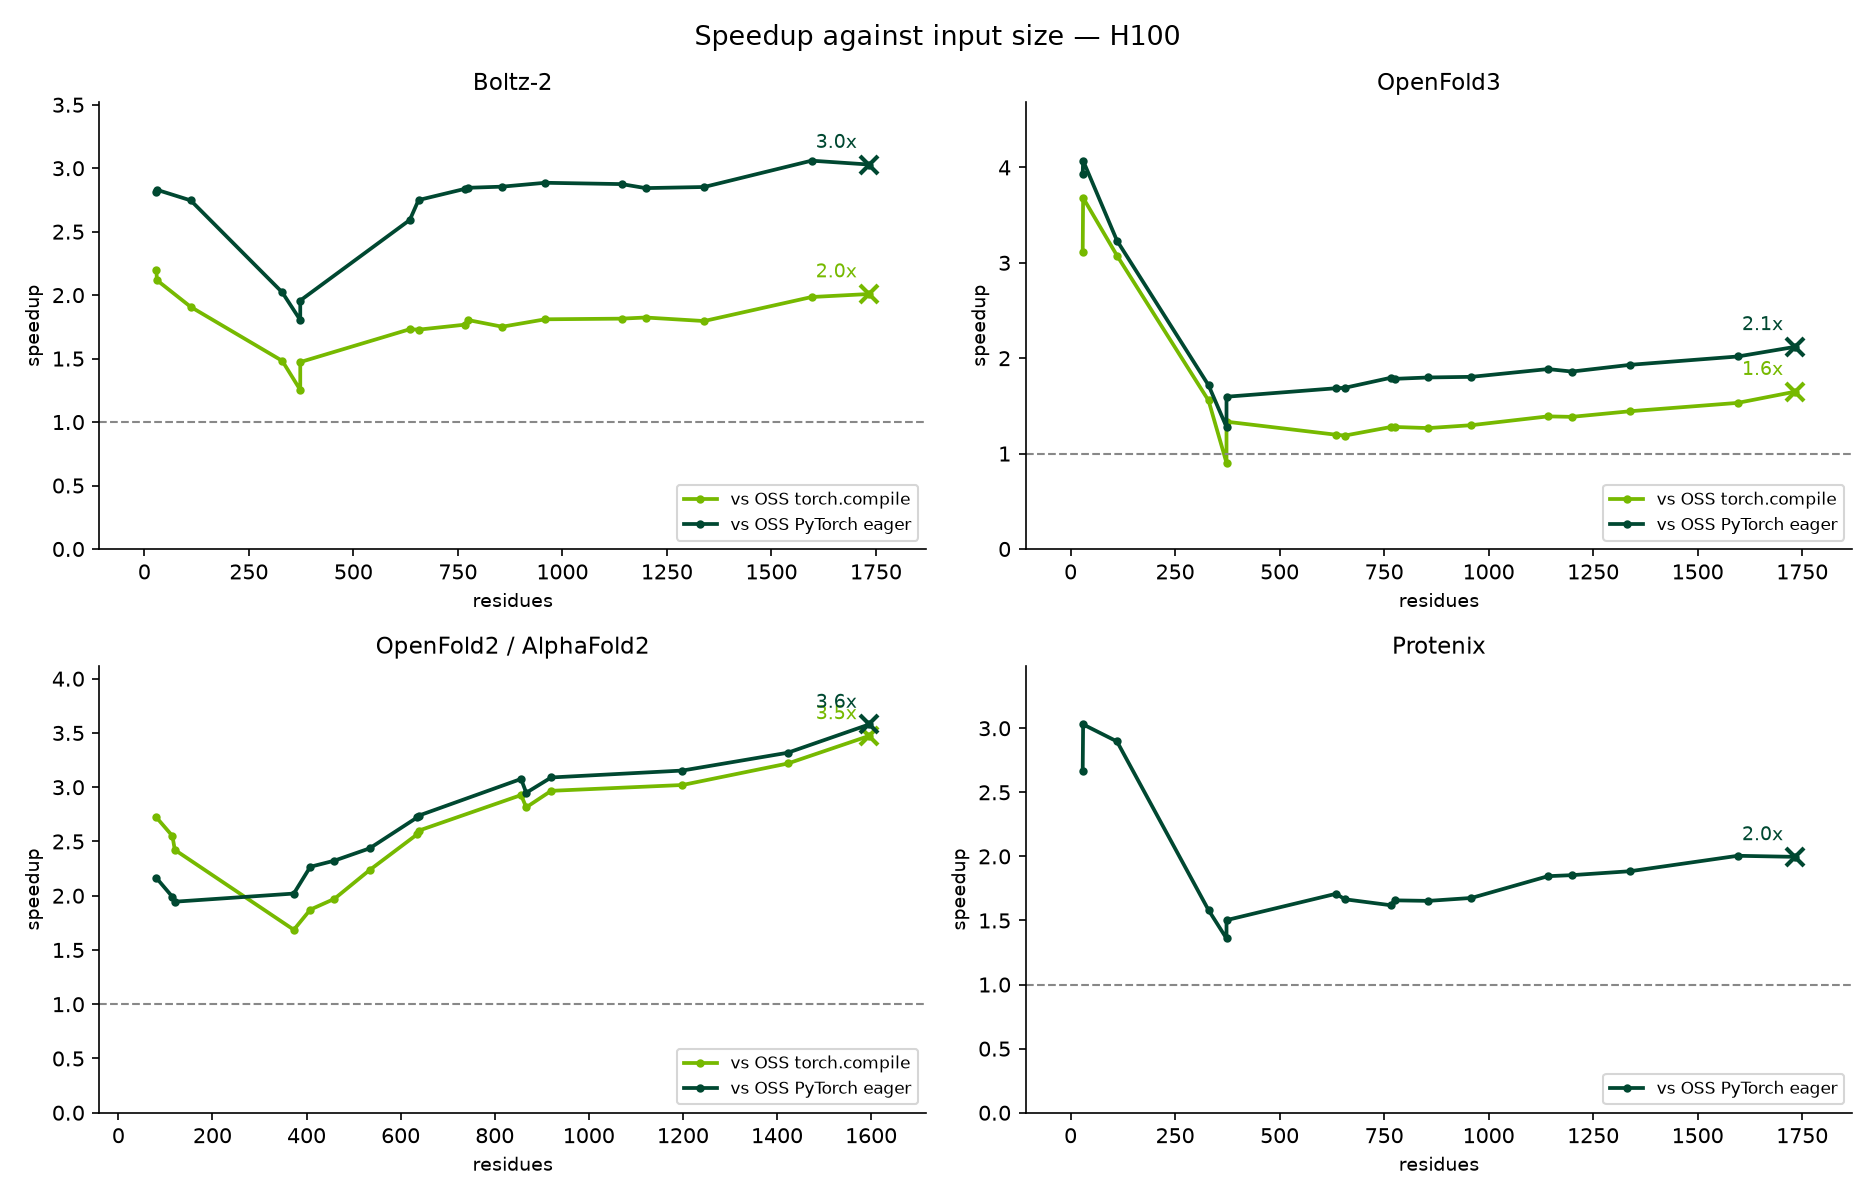
- Benchmarks — measured speedup and memory against OSS PyTorch
- Model weights — checkpoint resolution and staging
- Docker images — development and runtime images
- Coding guidelines — style, naming, and tooling
- Folding example — runnable
build_processordemo
Benchmarks
Methodology
Folding benchmarks over a bench set the shipped
rebuild_dataset.py builds from RCSB
and NVIDIA's MSA Search NIM — there is no dataset release to download.
Template-bearing samples included: both sides load every bundled MSA and attach
every listed template.
- One GPU, serial, one structure per forward call.
- Time only GPU-synchronized
model.forward(). Featurization, transfers, postprocessing, writing, and scoring stay outside the window. - Discard one warmup forward, then report one measured forward per sample.
- BioIR runs its default optimized config, which captures CUDA graphs of each model's trunk recycle, diffusion step, and confidence Pairformer for inputs up to 1024 tokens. The results below, measured 2026-09-08, used a CUDA graph on the diffusion module only.
- OSS runs its own inference script: eager always, plus
torch.compilewhen it passes a dynamic-shape probe. - Runtime knobs match on both sides — 200 sampling steps, 3 or 5 diffusion samples, and per-model recycling.
- Score written structures with OpenStructure lDDT and DockQ. Speedup is
OSS forward / BioIR forward; above 1 favors BioIR. - Future work will add additional Blackwell-optimized kernels.
Results
| Model | H100 | H200 |
|---|---|---|
| Boltz-2 | 1.78x / 2.65x | 1.74x / 2.54x |
| OpenFold3 | 1.55x / 2.02x | 1.54x / 2.03x |
| OpenFold2 / AlphaFold2 monomer | 2.55x / 2.60x | 2.61x / 2.66x |
| OpenFold2 / AlphaFold2 multimer | 2.66x / 2.77x | 2.61x / 2.75x |
| Protenix | — / 1.87x | — / 1.84x |
Geomean speedup, vs OSS torch.compile / vs OSS PyTorch eager; above 1 favours
BioIR. Protenix has no torch.compile path. Fourteen GPUs, per-model accuracy
and peak memory, and how to reproduce any of it:
docs/ref/benchmark.md.
The bench-perf-oss agent skill has
the full gates, environment isolation, result schema, and charting protocol.
Contributing
We welcome contributions. See contributing.md for
policy and docs/dev.md for the development workflow.
Citation
If you use BioIR in your research, please cite it via
CITATION.cff.
Contact / Support
- Bugs and feature requests: GitHub Issues
- Usage questions: GitHub Discussions
- Security vulnerabilities: see
SECURITY.md— do not file a public issue
License
NVIDIA-authored BioIR code is licensed under the Apache License 2.0. Distribution compliance material is available here:
- Third-party notices and attributions
- Full third-party license texts
- Gemmi 0.6.5 corresponding source, licensed under MPL-2.0 or LGPL-3.0-or-later; BioIR distributes it under the MPL-2.0 option
Metadata
Release files for bionemo-ir 0.2.0rc1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Built distributions (wheels)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| bionemo_ir-0.2.0rc1-cp312-cp312-manylinux_2_34_x86_64.whl | CPython 3.12 | CPython 3.12 | Linux glibc 2.34+ x86-64 | Details |
| bionemo_ir-0.2.0rc1-cp312-cp312-manylinux_2_34_aarch64.whl | CPython 3.12 | CPython 3.12 | Linux glibc 2.34+ ARM64 | Details |
Total release size: 74.6 MB
Release files / bionemo_ir-0.2.0rc1-cp312-cp312-manylinux_2_34_x86_64.whl
| Download URL | bionemo_ir-0.2.0rc1-cp312-cp312-manylinux_2_34_x86_64.whl |
|---|---|
| Size | 37.3 MB |
| Tags | CPython 3.12 Linux glibc 2.34+ x86-64 |
|
SHA-256 checksum How to use checksums |
18568809ece3cb7eeab635c42dd7e943e69a22d9eaf25b8492f7e63126701b5b
|
|
BLAKE2b-256 checksum How to use checksums |
90c5b34accb0c4d200f7bec31bdc6880feec02e238a4fe751f932ae657446c5d
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.14.8
|
Release files / bionemo_ir-0.2.0rc1-cp312-cp312-manylinux_2_34_aarch64.whl
| Download URL | bionemo_ir-0.2.0rc1-cp312-cp312-manylinux_2_34_aarch64.whl |
|---|---|
| Size | 37.3 MB |
| Tags | CPython 3.12 Linux glibc 2.34+ ARM64 |
|
SHA-256 checksum How to use checksums |
c166faf0243a0a4ee73424e950de35d03e38729d27946a69934c0d8cbd37443d
|
|
BLAKE2b-256 checksum How to use checksums |
82c66018d641f69c30519d2d68c925c6e2d5e2623378254243130d0734a43fb0
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.14.8
|
Security for bionemo-ir 0.2.0rc1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














