




Distill your LLM classifier into a small, fast model — with a statistical bound on agreement.
Status: alpha (0.1.0). The offline core works, is tested and benchmarked. The API may still change before 1.0.
The problem
Many teams classify text with an LLM pipeline: a prompt, a provider, output parsing. It works, but every call is slow and costs money. A common fix is to train a small classifier on the LLM's own labels and fall back to the LLM only when the small model is unsure.
Training that classifier is easy. Deciding when it is safe to trust it is the hard part. Nobody wants to replace an LLM in production on the basis of "it looked fine on a validation set".
What bounded-distill does
You give it texts and the labels your LLM already produced (for example, from your logs). You state a target, such as "agree with the LLM at least 97% of the time". bounded-distill:
- trains a small classifier (frozen sentence embeddings + logistic regression);
- picks a confidence threshold so that the lower confidence bound of agreement on the texts it answers meets your target — not just the point estimate;
- reports how much traffic the small model can take over (the share of LLM calls saved), per-class agreement and the small model's latency;
- lists suspects: texts where the small model is confident but disagrees with the LLM. These are often LLM labeling mistakes and point to ambiguous class definitions in your prompt;
- checks accuracy against a small human-labeled (gold) set, if you have one.
Texts below the threshold go back to your own LLM pipeline. The library never calls an LLM itself.
Install
pip install bounded-distill
The default embedder uses sentence-transformers, which needs PyTorch. On a machine
without a GPU, install the CPU-only build first to avoid a multi-gigabyte download:
pip install torch --index-url https://download.pytorch.org/whl/cpu
Quickstart
from bounded_distill import distill

# texts and the labels your LLM pipeline gave them, e.g. from your logs
router = distill(texts, llm_labels, target_agreement=0.97)

if (label := router.predict(text)) is None:   # not confident enough
    label = my_llm_pipeline(text)

print(router.report())
for suspect in router.suspects(top_n=20):
    print(suspect)

router.save("router/")                         # later: Router.load("router/")
llm_labels may contain None or empty strings (failed calls, parsing errors): they are
excluded, counted in the report, and a warning tells you how many. Pass
on_invalid="drop" to skip the warning or on_invalid="error" to fail instead. Pass
labels=[...] to fix the label set; then labels outside it are invalid too.
The default embedder is intfloat/multilingual-e5-small (many languages, runs on CPU).
To use your own vectors, pass embed=: any function from a list of texts to an
(n, dim) array.
Reading the report
On synthetic data with 3% wrong LLM labels and a 90% target (made with a fake embedder, so the latency is unrealistically low):
bounded-distill report
  texts:      900 total, 898 used, 2 invalid (1 missing (None), 1 empty)
  target:     agreement >= 90.0% at 95% confidence: reached
  threshold:  0.8218
  coverage:   53.6% (481 of 898 texts answered without the LLM)
  agreement:  92.3% on answered texts, lower bound 90.1%
  latency:    0.02 ms per text (median, student)

  per class  support  coverage  agreement
  billing        299     55.5%      95.8%
  other          297     52.2%      89.0%
  tech           302     53.0%      91.9%

  confident disagreements (LLM label -> student label)
  other -> tech         9
  other -> billing      8
  ...
- coverage is the share of traffic the small model answers, so it is also the share of LLM calls you save.
- lower bound is what the threshold is chosen by: with 95% confidence, agreement on the answered texts is at least this. If no threshold can guarantee the target, the router answers nothing and the report says so — it does not silently lower the bar.
- per class shows what the overall number hides: here
otheris below the target even though the total is above it. - confident disagreements point at class definitions the LLM finds ambiguous —
typically a catch-all class like
other.
All numbers are out-of-fold estimates: each text is scored by a model that did not see
it during training. print(...) is for people; report.to_dict() gives plain JSON.
Suspects list single texts, most confident first. In this example 8 of the top 10 are labels that were deliberately broken, although they are only 18% of all disagreements:
#90  tech -> billing (96.8%): 'billing 90'
#359  other -> tech (96.5%): 'tech 59'
The number is the position in your input, so you can find the row in your own data.
Checking against gold labels
Agreement with the LLM is not accuracy. If you have a few hundred human-labeled texts that were not used for training, compare the LLM, the small model and the cascade:
print(router.evaluate(texts, gold_labels, llm_labels))
The small model only answers texts it is confident about, which tend to be the easier ones, so its accuracy is shown next to the LLM's accuracy on the same texts.
Benchmark: two datasets with real LLM labels
Two intent datasets with human labels: Banking77 (English, 77 fine-grained banking intents, 10,003 train and 3,080 test texts) and MASSIVE in Russian (59 voice assistant intents, 11,510 train and 2,974 test texts). The teacher is Gemma 4 31B, self-hosted on vLLM, prompted zero-shot with the label names and constrained to answer with one of them. Its labels are noisy, as in production: 78.5% (Banking77) and 83.6% (MASSIVE) accuracy on test against the human labels.
distill() is trained on the LLM's train labels only. The human labels are used only to
evaluate, on test texts the router never saw.
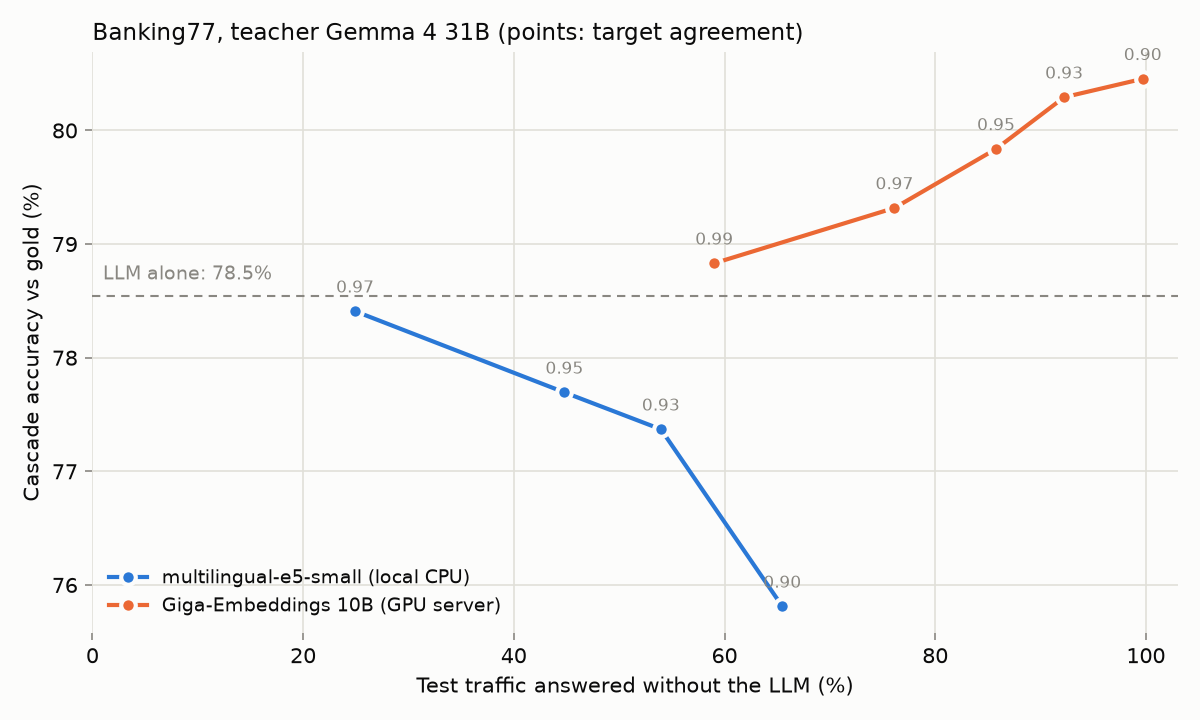
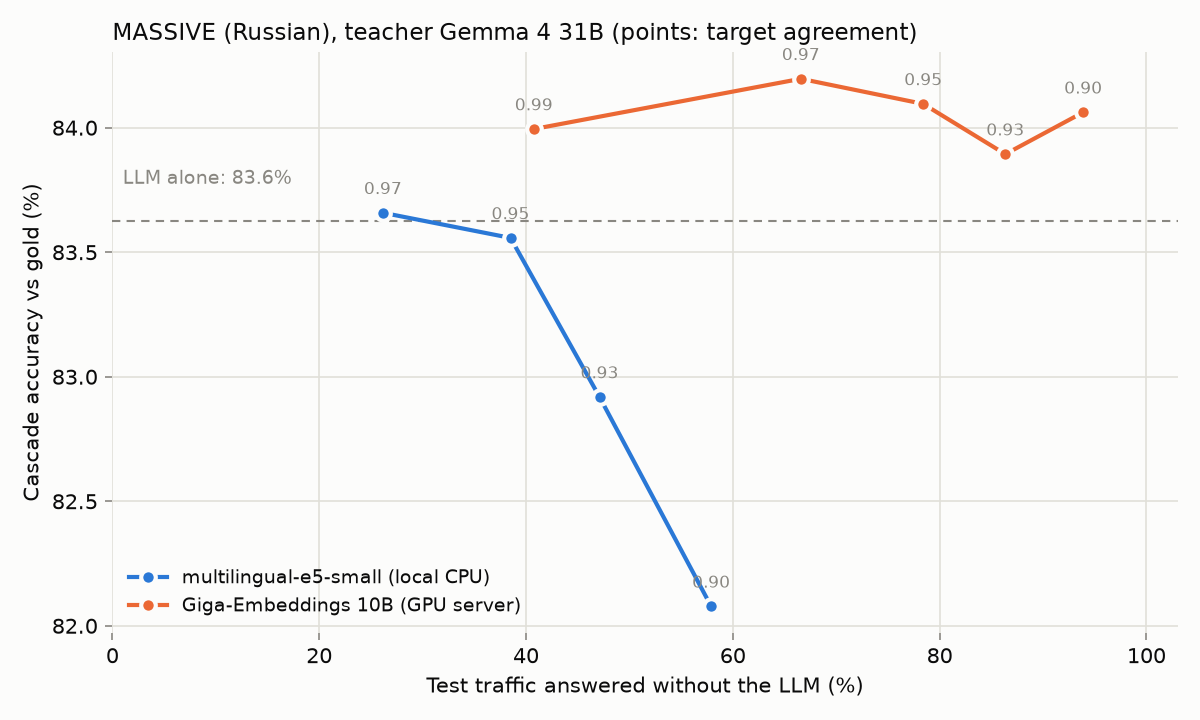
The y-axes are zoomed in: on these test sets a difference of 0.3 points is about ten texts.
At target_agreement=0.97:
| Dataset | Embedder | Test traffic without the LLM | Agreement with the LLM on it | Cascade accuracy | LLM alone |
|---|---|---|---|---|---|
| Banking77 | multilingual-e5-small (default) | 24.9% | 97.3% | 78.4% | 78.5% |
| Banking77 | Giga-Embeddings 10B (via embed=) |
76.1% | 97.7% | 79.3% | 78.5% |
| MASSIVE ru | multilingual-e5-small (default) | 26.2% | 96.9% | 83.7% | 83.6% |
| MASSIVE ru | Giga-Embeddings 10B (via embed=) |
66.6% | 97.3% | 84.2% | 83.6% |
Median latency of one prediction: 13 ms with e5-small on a laptop CPU, 55 ms with Giga-Embeddings on a GPU server (network included), 117 ms for one call to the LLM.
- The report matches new traffic. Coverage on test is within 1.7 points of the out-of-fold estimate in every case. Agreement on test reaches the target in 14 of 18 cases; the four misses (up to 1.1 points, three of them on MASSIVE with e5-small) are all within sampling error: the target stays inside the 95% confidence interval measured on test.
- The embedder decides the coverage. A stronger embedder answers 2.5–3 times more traffic at the same target. At 0.97 the cascade is as accurate as the LLM alone with both embedders; with Giga-Embeddings it is slightly more accurate at every target, because averaging over similar texts smooths the teacher's random errors.
- Suspects find real LLM errors. With Giga-Embeddings, 75 (Banking77) and 87 (MASSIVE) of the top 100 suspects are texts the LLM labeled wrongly, against base rates of 24% and 16%; in most of them the small model suggests the human label. With e5-small the signal is weaker (39 and 55 of 100). Some "LLM errors" are errors in the human labels themselves.
- 40–70% of the LLM's errors are systematic: the small model learns them and agrees, so
no agreement metric can reveal them. Only a gold set can — see
evaluate().
Caveats: one teacher so far. Both datasets are MTEB tasks; embedders are evaluated on them and may have been tuned on their training data. The training data of Giga-Embeddings is not published, so its numbers may be optimistic. Latencies depend on hardware: the LLM server here is fast, so the main saving is GPU compute rather than time. Texts were embedded as they are, without the instruction prefix Giga-Embeddings recommends for classification. How to reproduce: benchmarks/README.md.
How it works
- Embed the texts with a frozen sentence embedder.
- Get out-of-fold class probabilities with k-fold logistic regression.
- For each candidate threshold, count the covered texts and those where the small model agrees with the LLM; compute the one-sided Wilson lower bound of agreement.
- Pick the lowest threshold (the most coverage) whose bound reaches the target.
- Predict with the average of the fold models: the same models the threshold was chosen on, so it means the same on new texts. Prediction is one embedding plus a few small matrix products in numpy.
A saved router is a JSON file and a .npz file — no pickle, and no training texts on
disk. The design is described in HLD/offline_core.md.
How it differs from similar tools
Several projects distill an LLM classifier into a small model with an LLM fallback. bounded-distill focuses on:
- Offline first. Works on labels you already have; it does not run or wrap the LLM.
- A statistical bound, not a hand-picked threshold.
- Auditing the teacher. Confident disagreements surface LLM labeling errors (in the spirit of Confident Learning, Northcutt et al., 2021).
- Small and simple. One function call, strict typing, few dependencies.
Honest limitations
- Agreement with the LLM is not accuracy. If the LLM makes the same mistake consistently, the small model learns it too. Use a gold set to check.
- The threshold is chosen and evaluated on the same out-of-fold data, so the bound is slightly optimistic; in the benchmark, misses on new texts stayed within sampling error.
- Single-label classification with a fixed, known set of labels only.
- When the small model answers, you get only the label, not other fields of your pipeline's structured output.
Roadmap
- Offline core:
distill,Router.predict, save/load - Report: coverage, agreement with lower bound, per-class metrics, latency
- Suspects (confident disagreements)
- Evaluation against gold labels
- Benchmark on Banking77 and MASSIVE (Russian) with real LLM labels
- More teachers in the benchmark
- Release 0.1.0 on PyPI
- Optional online mode (collect pairs from a running pipeline)
License
1 maintainer

Metadata
1 maintainer
Release files for bounded-distill 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| bounded_distill-0.1.0.tar.gz | 23.0 kB | With provenance | Details for bounded_distill-0.1.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| bounded_distill-0.1.0-py3-none-any.whl | Python 3 | none | any | Details for bounded_distill-0.1.0-py3-none-any.whl |
Total release size: 49.7 kB
Release files / bounded_distill-0.1.0.tar.gz
| Download URL | bounded_distill-0.1.0.tar.gz |
|---|---|
| Size | 23.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
455391fb1e0b4a47dc81419d3ff0400b6eb966958387cbdda302c96b193ba6a0
|
|
BLAKE2b-256 checksum How to use checksums |
d9a855773d4ef49bf676b3e3bb25f82b89aad723b4431379f8a2e6d452b4000a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 19, 2026.
Transparency logRelease files / bounded_distill-0.1.0-py3-none-any.whl
| Download URL | bounded_distill-0.1.0-py3-none-any.whl |
|---|---|
| Size | 26.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
4c4d7598787176b286bcd55329aeedd52b66f173e43d189444ee2c0b6ee95831
|
|
BLAKE2b-256 checksum How to use checksums |
cf19f94e915f0e8df7647bd46792648fea9422ba81ceda5541e910e0890e808d
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 19, 2026.
Transparency logSecurity for bounded-distill 0.1.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
Both files in this release have been uploaded with provenance metadata.
Attestation for bounded_distill-0.1.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 19, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














