



Turn an open LLM into a calibrated decision model: choice, yes/no and score questions answered with real probabilities, read straight from the model's next-token logits, without generation or fine-tuning.
Status: alpha (0.1). The API may still change before 1.0. See the roadmap.
Try it: tutorial notebook: a calibrated ticket router from an open model in about 15 minutes, on a free Colab GPU.
Why
Reading an LLM's answer from generated text is slow and needs parsing. Raw next-token probabilities skip that, but they are biased by option order and badly calibrated. brier reads the answer distribution directly and corrects it in levels. Every decision records the level that produced it.
| Level | Labels needed | What it fixes | Forward passes |
|---|---|---|---|
raw |
0 | baseline readout of the label tokens | 1 |
L0 |
0 (optional unlabelled pool) | option-order bias, label prior bias | K for a K-option Choice, else 1 |
L1 |
≥ 50 | over/under-confidence (one temperature) | as L0 |
L2 |
≥ 60, ≥ 5 per answer | accuracy and calibration via a hidden-state head | 1 |
Results
banking20 (20 BANKING77 intents), Qwen3-1.7B, 2,603 test items, 95 % bootstrap CIs.
L1 and L2 use 300 labels. Full tables, protocol and caveats:
docs/results.md.
| raw | L0 | L1 | L2 | |
|---|---|---|---|---|
| Accuracy ↑ | 0.626 | 0.668 | 0.668 | 0.807 [0.793, 0.823] |
| ECE ↓ | 0.357 | 0.299 | 0.094 | 0.035 [0.028, 0.050] |
| NLL ↓ | 6.541 | 3.845 | 1.204 | 0.727 [0.672, 0.781] |
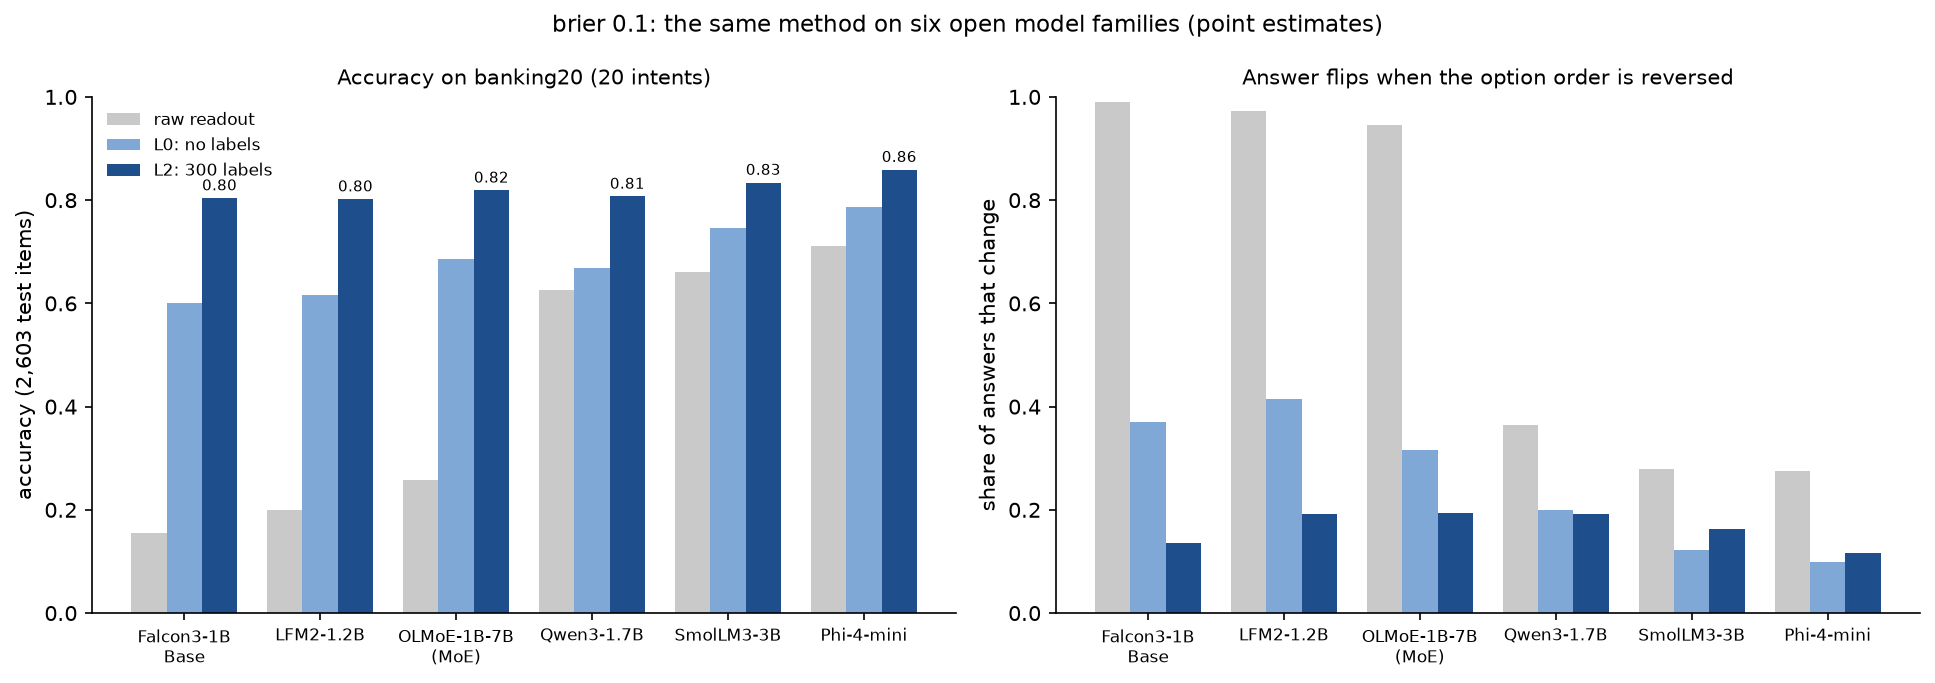
Across six model families (same task and labels; point estimates):
| Model | Accuracy: raw → L0 → L2 | ECE: raw → L1 → L2 | Order flips: raw → L0 |
|---|---|---|---|
| Qwen3-1.7B | 0.626 → 0.668 → 0.807 | 0.357 → 0.094 → 0.035 | 0.364 → 0.201 |
| Falcon3-1B-Base (no chat template) | 0.155 → 0.601 → 0.804 | 0.119 → 0.162 → 0.072 | 0.990 → 0.371 |
| LFM2-1.2B (hybrid convolution) | 0.200 → 0.617 → 0.802 | 0.336 → 0.064 → 0.036 | 0.972 → 0.415 |
| SmolLM3-3B | 0.660 → 0.746 → 0.834 | 0.190 → 0.030 → 0.039 | 0.279 → 0.123 |
| Phi-4-mini (3.8B) | 0.711 → 0.786 → 0.859 | 0.186 → 0.022 → 0.057 | 0.275 → 0.099 |
| OLMoE-1B-7B (mixture of experts) | 0.257 → 0.686 → 0.819 | 0.068 → 0.098 → 0.084 | 0.945 → 0.316 |
Zero labels (L0) raise accuracy and cut order flips on every model; with 300 labels (L2) every
model lands at 0.80–0.86 accuracy. One task so far: evidence that the method works, not a
general claim. Details and caveats in
docs/results.md.
Install
pip install "brier[hf]"
Python ≥ 3.10. The core needs only numpy; the hf extra adds torch and transformers.
Quickstart
from brier import Choice, Decider, Noul
from brier.backends.hf import HFBackend

d = Decider(HFBackend("Qwen/Qwen3-1.7B", revision="<commit-sha>"))
route = Choice("Which team?", ["billing", "technical", "sales"], name="route")
refund = Noul("Is this a refund request?", name="refund")

res = d.decide("My card was charged twice, please fix it now!", [route, refund], level="L0")
print(res["route"].answer, res["route"].probs)  # top option and all option probabilities
print(res["refund"].p_yes, res["refund"].level)  # probability of yes, and "L0"
Calibrate with your own data, save the calibration, and reuse it:
d.fit_prior(unlabelled_states, [route])  # L0 prior, no labels
d.fit_temperature(labelled_states, route, route_labels)  # L1, >= 50 labels
d.fit_head(labelled_states, route, route_labels)  # L2, >= 60 labels, >= 5 per answer
d.decide(state, [route], level="L2")

d.save("calibration/")  # JSON + .npz, never model weights
d = Decider.load("calibration/", HFBackend("Qwen/Qwen3-1.7B", revision="<commit-sha>"))
load refuses a calibration made for another model, revision, precision (dtype) or prompt
template. Pin revision to a commit SHA: a model name alone does not pin weights.
Questions:
Choice(text, options, name=...): one of K options.Noul(text, name=...): yes/no;p_yesis the probability of yes.Score(text, levels, name=...): an integer rating1..levels;expectedis the mean.
Does it work with my model?
Hugging Face causal LMs with safetensors weights: chat models through their chat template, base models through a plain-text prompt. Check yours before calibrating:
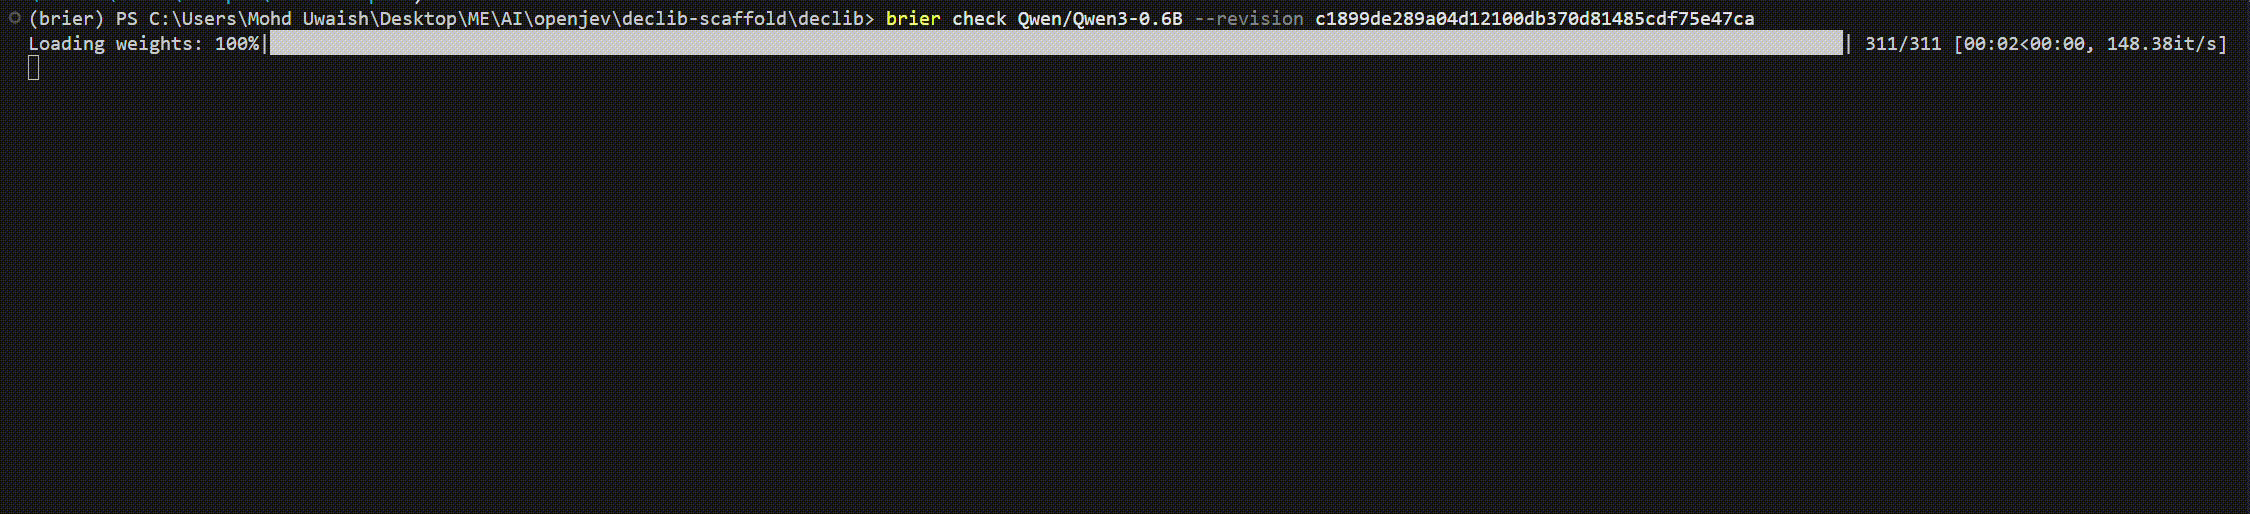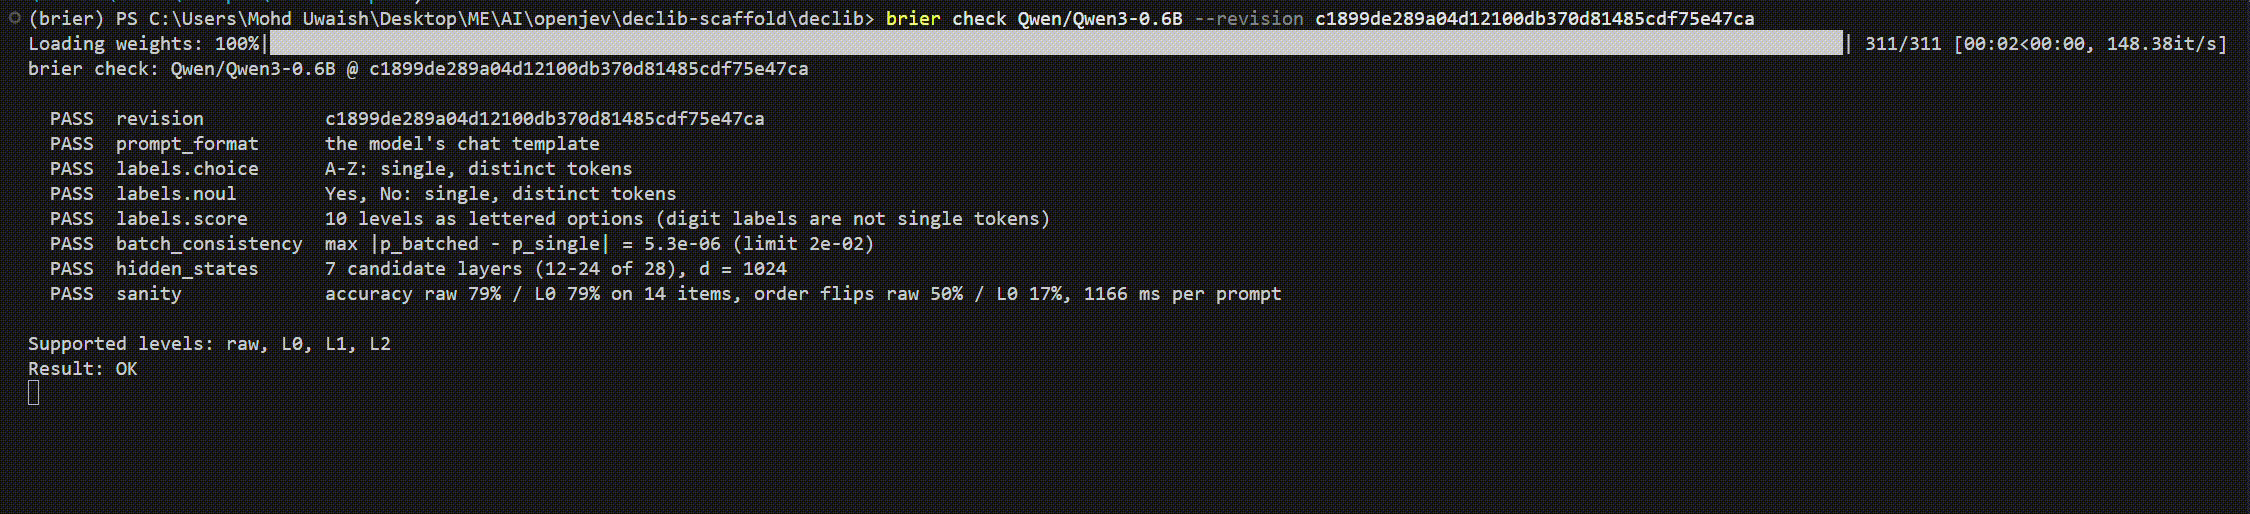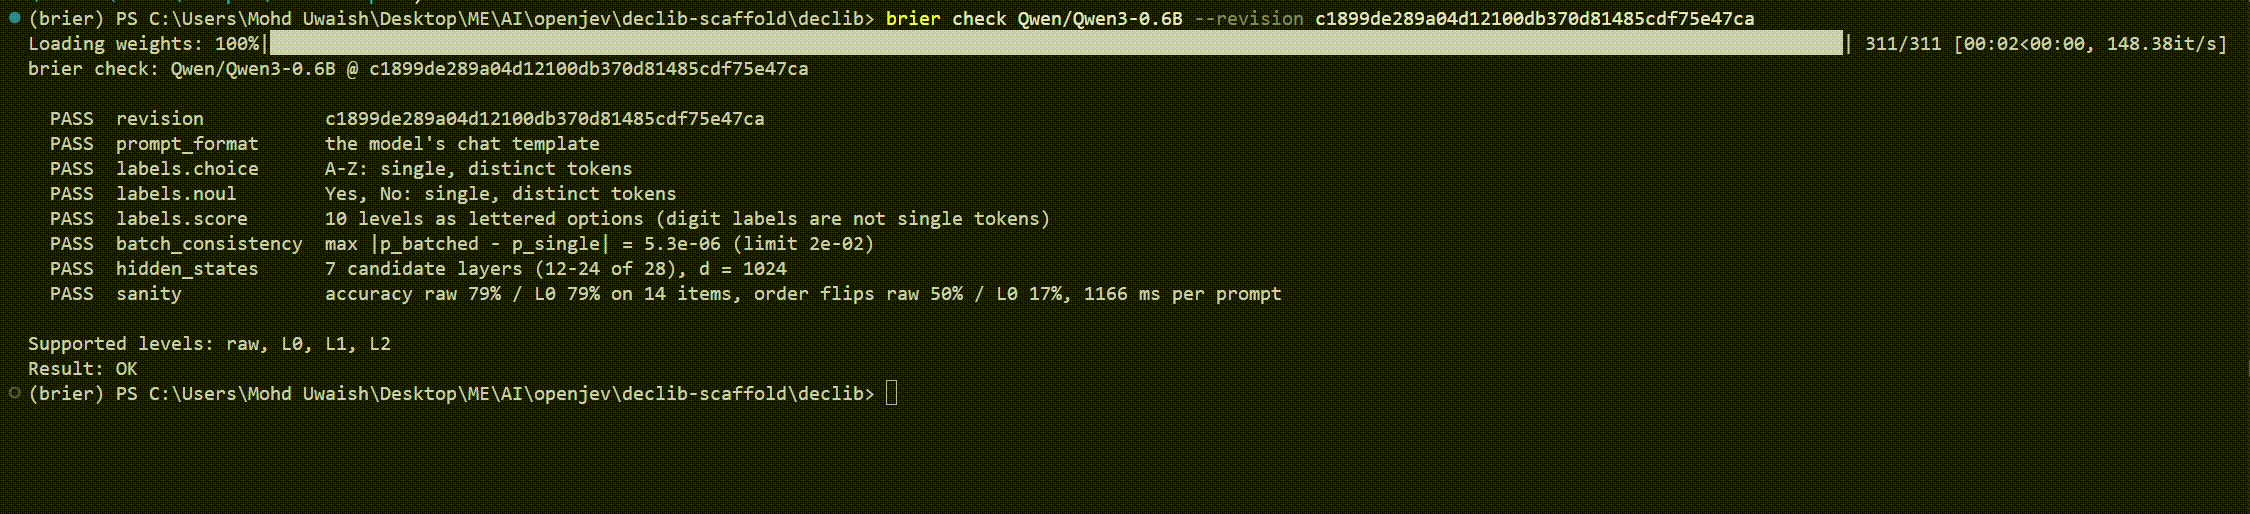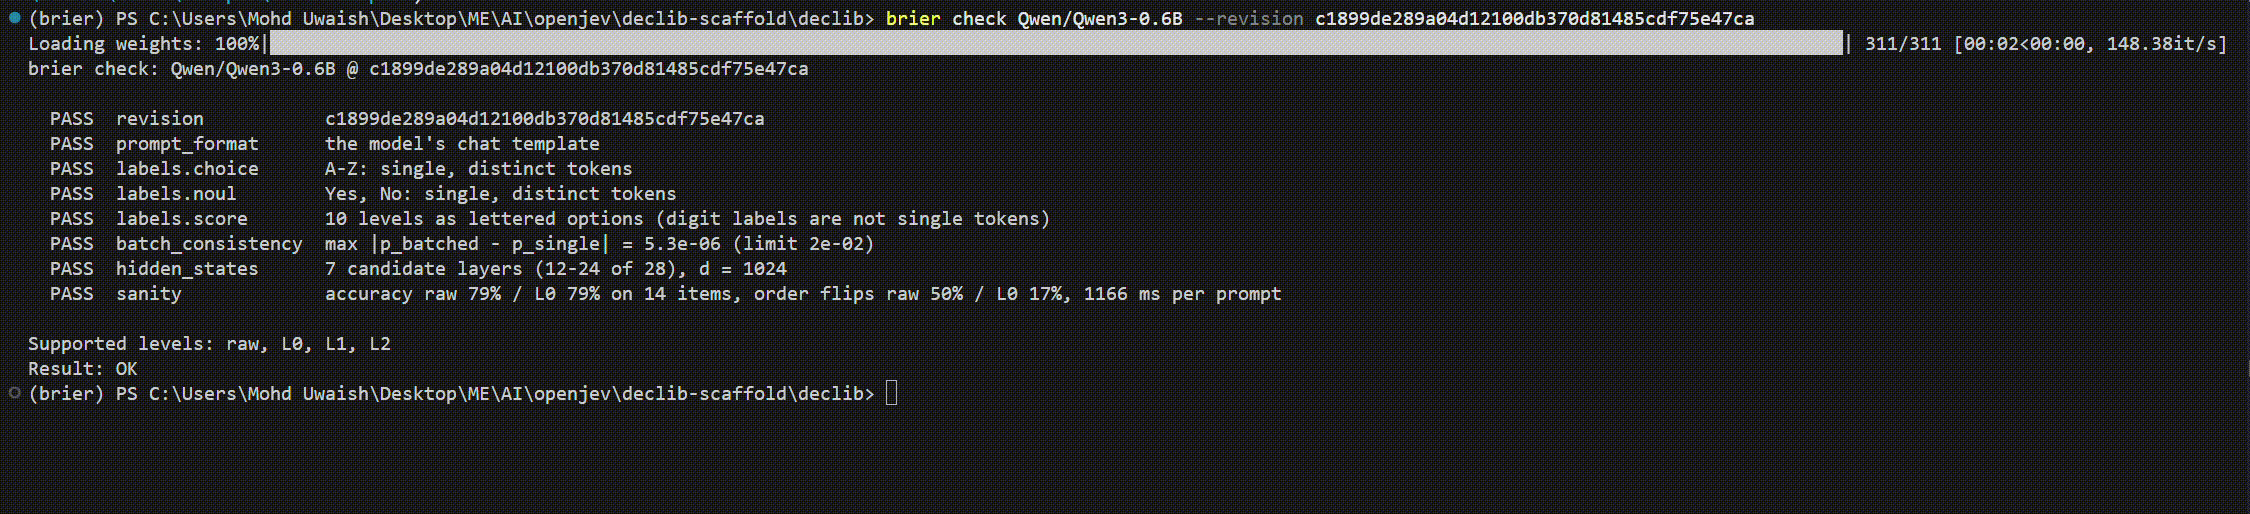
The same output as text:
$ brier check Qwen/Qwen3-0.6B --revision c1899de289a04d12100db370d81485cdf75e47ca

  PASS  revision           c1899de289a04d12100db370d81485cdf75e47ca
  PASS  prompt_format      the model's chat template
  PASS  labels.choice      A-Z: single, distinct tokens
  PASS  labels.noul        Yes, No: single, distinct tokens
  PASS  labels.score       10 levels as lettered options (digit labels are not single tokens)
  PASS  batch_consistency  max |p_batched - p_single| = 5.3e-06 (limit 2e-02)
  PASS  hidden_states      7 candidate layers (12-24 of 28), d = 1024
  PASS  sanity             accuracy raw 79% / L0 79% on 14 items, order flips raw 50% / L0 17%, ...

Supported levels: raw, L0, L1, L2
Tested so far (15 models): Qwen3, SmolLM2 / SmolLM3, TinyLlama, OLMo-2, Gemma 3, Granite-MoE,
LFM2, DeepSeek-R1-Distill, Falcon3, Phi-4-mini, OLMoE and Mistral, including two mixtures of
experts and two base models. Details and known quirks:
docs/COMPATIBILITY.md.
Documentation
- API reference
SPEC.md: behaviour and limitsMETHODS.md: the maths of every level, with referencesEVALUATION.mdandresults.md: benchmark protocol and resultsrelated_work.md: where the idea and the methods come from
Limitations
- One benchmark task so far (banking20); more tasks are welcome.
L0costs K forward passes for a K-option question; there is no prefix caching yet.- Hugging Face
transformersonly (no vLLM backend yet); models need safetensors weights and the standard decoder layout. - Decisions on untrusted text can be steered by prompt injection (see Security).
Contributing
Contributions are welcome: new models in the compatibility table (run brier check and open a
PR), benchmark tasks, backends and docs. Start with
CONTRIBUTING.md and the
issues labelled good first issue.
Security
Decisions on untrusted text can be manipulated by prompt injection. Don't use them as the only
gate for destructive actions. brier never runs model code (trust_remote_code is never set),
loads weights from safetensors only, and validates calibration files as untrusted input. Report
vulnerabilities privately; see
SECURITY.md and
THREAT_MODEL.md.
Related work
brier follows the idea of TypeSafe AI's Jev and of
AnyJev (Nokia Applied Research): typed
questions answered from next-token probabilities, corrected in levels. It is an independent
implementation, not affiliated with either. The correction methods come from published work
(Zheng et al. 2024; Zhou et al. 2024; Guo et al. 2017; Platt 1999; Ledoit & Wolf 2004).
related_work.md sets
out what brier shares with these projects and where it differs.
License
Apache-2.0
1 maintainer

Metadata
1 maintainer
Release files for brier 0.1.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| brier-0.1.1.tar.gz | 102.2 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| brier-0.1.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 174.8 kB
Release files / brier-0.1.1.tar.gz
| Download URL | brier-0.1.1.tar.gz |
|---|---|
| Size | 102.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
b867fed5d51a30472aabc7662917ac06e74a5d8e0fac79876c9b0acd30b08025
|
|
BLAKE2b-256 checksum How to use checksums |
190794c414f5880ac48b94115a4ac2bb92cab3595ad317a7da24dfd01f7d9e53
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 6, 2026.
Transparency logRelease files / brier-0.1.1-py3-none-any.whl
| Download URL | brier-0.1.1-py3-none-any.whl |
|---|---|
| Size | 72.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
ffe453fe2623151f5b30ac592d7d216e69c7eb344d8537723e06d854d18e9efa
|
|
BLAKE2b-256 checksum How to use checksums |
2a5344fef3812bd2d598288edcc1af9cf2ab81d1b6f8be0658101b4dec6983d6
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 6, 2026.
Transparency log













