
cadence-core


cadence-core is a pretrained neural model for next clinical event prediction from electronic health record (EHR) sequences. Given a patient's longitudinal clinical history, it predicts which of 48 clinical event categories will occur next and how many days until that event.
Key Features
- 5.86M parameter residual MLP — lightweight, fast inference, no GPU required
- Trained on MIMIC-IV v3.1 — 100k patient sequences from a large academic medical center
- Joint prediction — simultaneous 48-class event classification and time-to-event regression
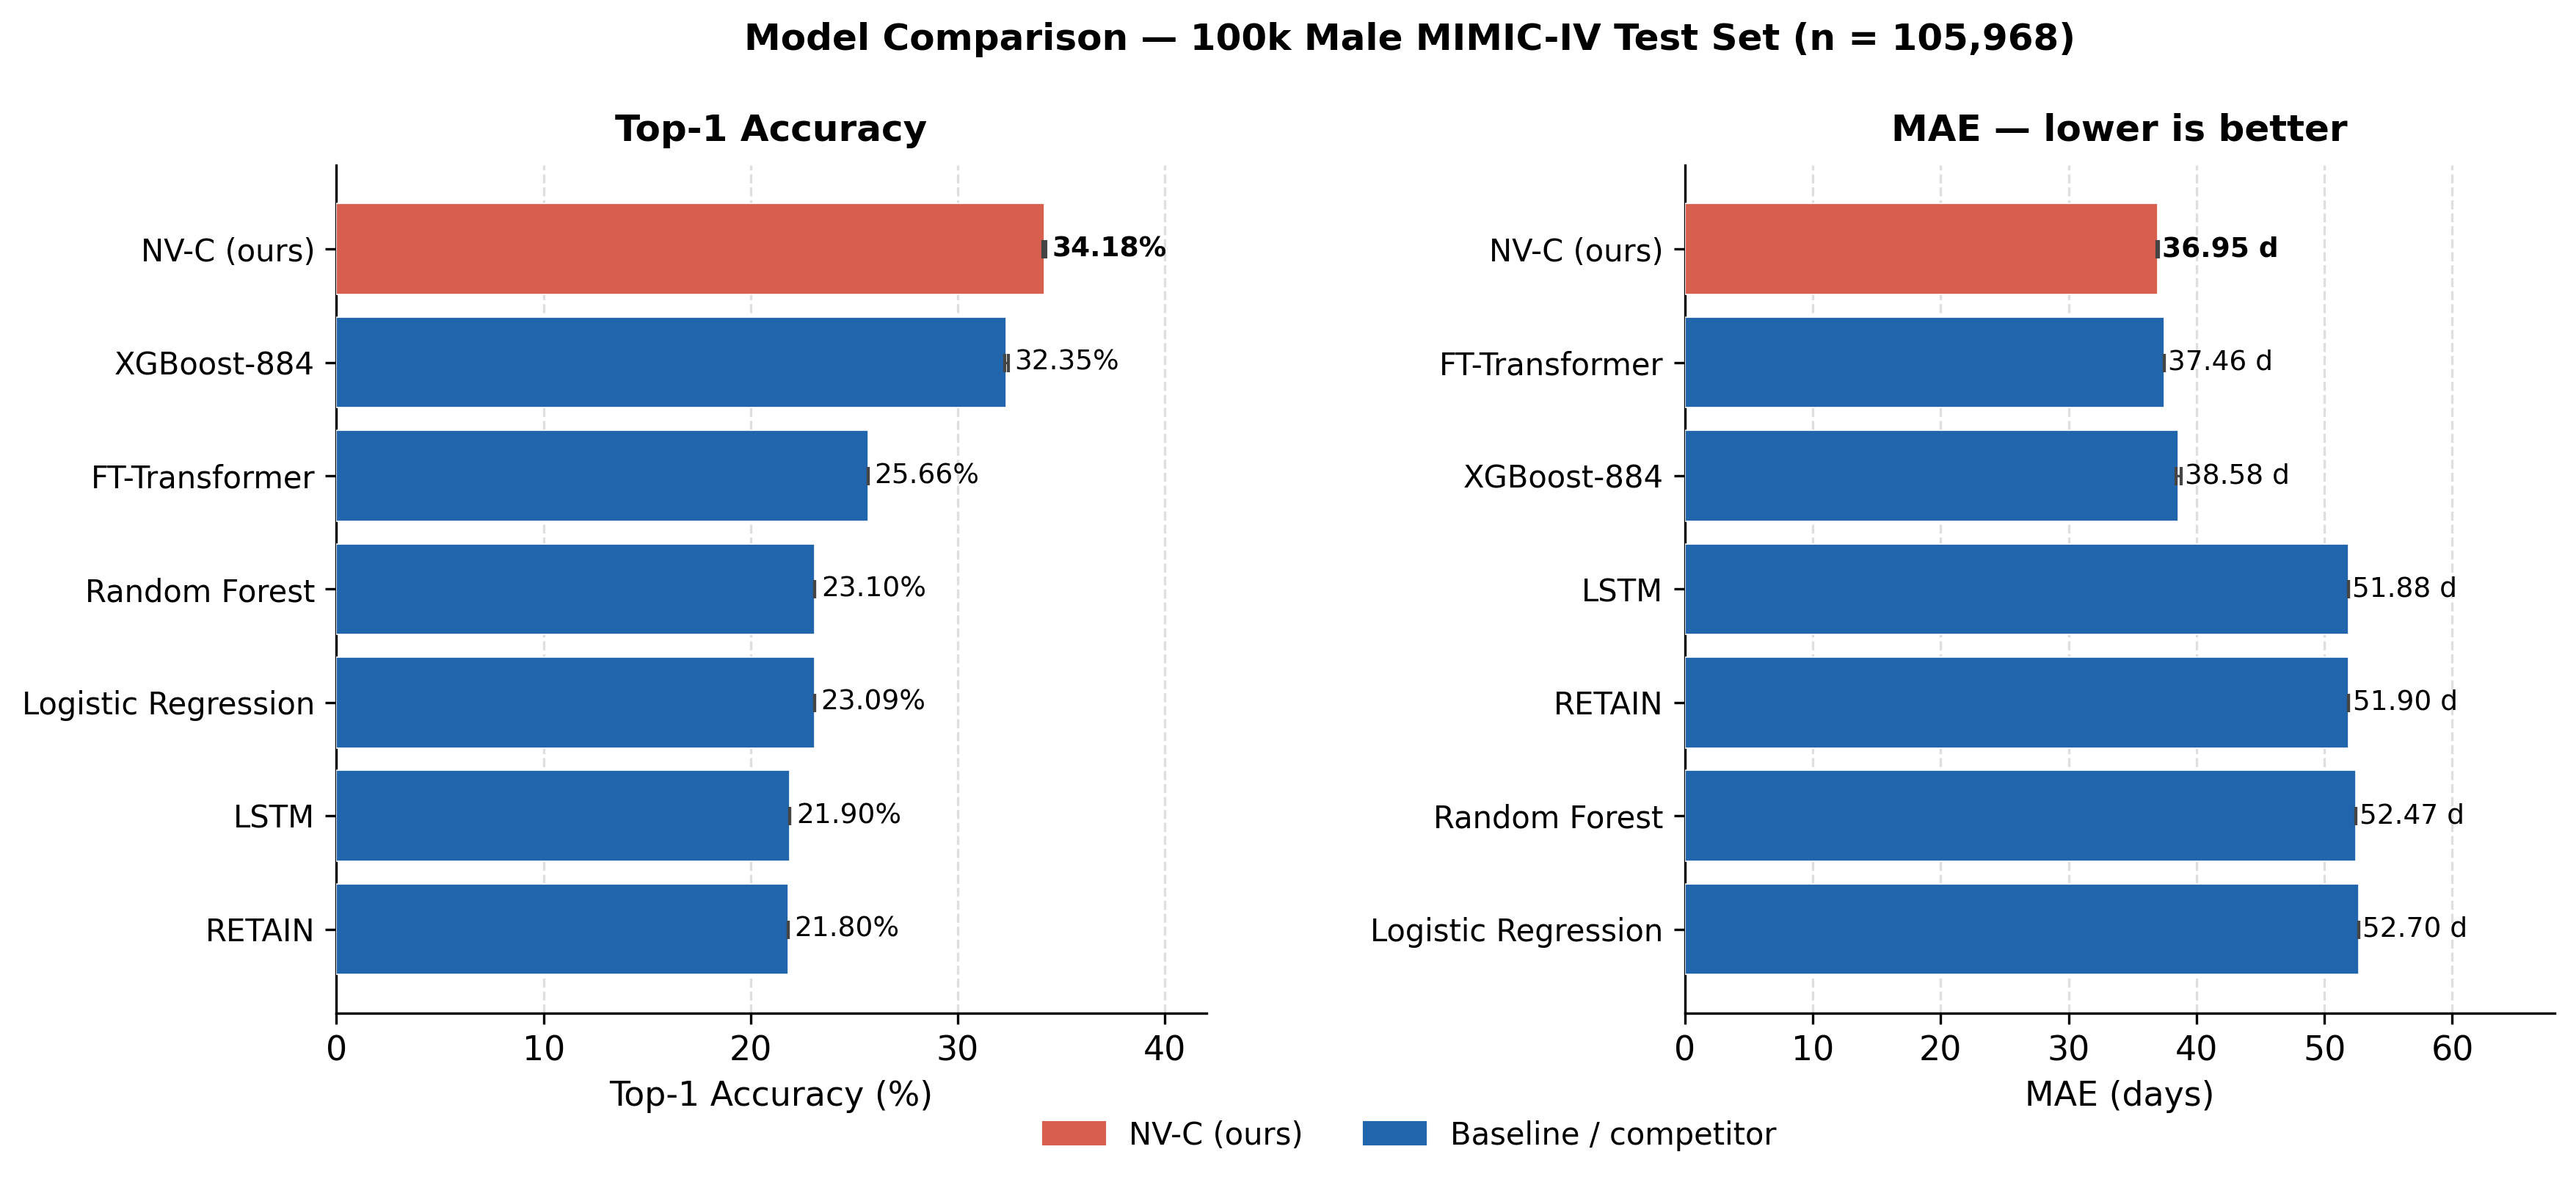
- 34.18% top-1 accuracy, 36.95 days MAE — outperforms XGBoost and all evaluated baselines
- Self-knowledge distillation — improved generalization without external teacher models
- Train on your own data — bring your JSONL sequences and per-event embeddings; no MIMIC required
Installation
pip install cadence-core
Requires Python 3.10+. No GPU needed for inference.
Quick Start
Pretrained weights not distributed. The MIMIC-trained classifier is dataset-specific
(50-cluster space derived from MIMIC text). Transfer to other datasets is not meaningful,
so we ship the architecture and training code rather than weights. Train your own model
on your own data using cadence.train(...).
import cadence

classifier = cadence.train(
    train_jsonl="my_data/train.jsonl",
    val_jsonl="my_data/val.jsonl",
    embeddings_path="my_data/embeddings.npy",
    event_index_path="my_data/event_index.json",
    n_clusters=50,
    out_dir="./runs/my_run",
    n_epochs=30,
)

preds = cadence.predict(
    classifier,
    "my_data/test.jsonl",
    embeddings_path="my_data/embeddings.npy",
    event_index_path="my_data/event_index.json",
)
# preds: [{"patient_id": "...", "top_3_clusters": [...], "top_3_probs": [...], "days_until_next": ...}, ...]
Model Architecture
cadence-core implements the Narrative Velocity Composite (NV-C) framework — a residual MLP that fuses structured clinical features with contextual language embeddings.
| Component | Details |
|---|---|
| Input dimension | 2420 (884 NV features + 768 PubMedBERT mean + 768 PubMedBERT last) |
| Backbone | 3-block MLP with residual skip connections and LayerNorm |
| Classification head | Linear → 48 event-class logits |
| Regression head | Linear → 19-bin discretized time-to-event logits |
| Parameters | 5.86M |
| Training objective | Cross-entropy (classification) + ordinal regression loss (time), with self-KD |
The 884 NV features capture structured clinical signals (labs, vitals, medications, procedures) encoded as narrative velocity trajectories. PubMedBERT embeddings are cluster-semantic embeddings — microsoft/BiomedNLP-BiomedBERT-base-uncased-abstract-fulltext encodings of event-category labels (not raw clinical note text) — frozen at inference. Self-knowledge distillation applied after PubMedBERT cluster-semantic fusion yields a disproportionately large top-1 gain (+0.81 pp), substantially exceeding the gain from self-KD on structured features alone.
Performance
100k Training Tier — Male Cohort (MIMIC-IV v3.1)
Results are 3-seed means with bootstrap 95% CIs. XGBoost falls outside Cadence's CI on both metrics.
| Model | Top-1 Accuracy | MAE (days) |
|---|---|---|
| cadence-core (NV-C) | 34.18% [33.84%, 34.42%] | 36.95 [36.10, 37.68] |
| XGBoost | 32.35% | 38.58 |
| Random Forest | 24.1% | 53.2 |
| Logistic Regression | 21.3% | 58.7 |
| RETAIN (baseline) | 22.8% | 54.1 |
| Majority-class baseline | 9.25% | — |
| Random baseline | 2.08% | — |
Full-Cohort Results (MIMIC-IV v3.1)
At full cohort, cadence-core leads all models on top-1 accuracy. FT-Transformer achieves the best MAE.
| Cohort | Model | Top-1 Accuracy | MAE (days) |
|---|---|---|---|
| Male | cadence-core (NV-C) | 38.04% | 29.39 |
| Male | FT-Transformer | — | 27.82 |
| Female | cadence-core (NV-C) | 35.66% | 39.88 |
| Female | FT-Transformer | — | 37.08 |
External Validation — BWH Dataset (1,120 patients)
External validation on de-identified records from Brigham and Women's Hospital (BWH) — a geographically and demographically distinct population with missing structured features and population shift. BWH events were LLM-extracted and mapped to the MIMIC-IV 48-cluster event schema.
| Model | Top-1 Accuracy |
|---|---|
| RETAIN | 20.98% (best overall) |
| cadence-core (NV-C) | 11.88% (leads structured-feature models) |
Under domain shift with missing structured features, RETAIN achieves the best overall top-1 on BWH. Cadence leads among structured-feature models.
Paper & Citation
Cadence: A Benchmark Evaluation of the Narrative Velocity Framework for Next Clinical Event Prediction in MIMIC-IV Rouhollahi A. and Nezami F.R. — bioRxiv, 2026. doi.org/10.64898/2026.05.06.722409
If you use cadence-core in your research, please cite:
@article{rouhollahi2026cadence,
  title   = {Cadence: A Benchmark Evaluation of the Narrative Velocity Framework for Next Clinical Event Prediction in {MIMIC-IV}},
  author  = {Rouhollahi, Amir and Nezami, Farhad R.},
  journal = {bioRxiv},
  year    = {2026},
  doi     = {10.64898/2026.05.06.722409},
  url     = {https://doi.org/10.64898/2026.05.06.722409}
}
Train on Your Own Data
Starting with v1.1.0, cadence-core ships a complete training pipeline. Provide your own JSONL sequences and per-event embeddings; no MIMIC data is required.
Input format
Each line in your JSONL files is one patient prediction record:
{
  "patient_id": "patient_001",
  "history": [
    {
      "date_iso": "2019-03-15",
      "event_index": 42,
      "cluster_id": 7,
      "days_from_start": 0.0
    },
    {
      "date_iso": "2019-04-01",
      "event_index": 17,
      "cluster_id": 3,
      "days_from_start": 17.0
    }
  ],
  "target": {
    "cluster_id": 12,
    "days_from_prev": 14.0
  }
}
event_index: row index (0-based) into yourembeddings.npyfile.cluster_id: integer in[0, n_clusters-1]representing the event category.days_from_start: days since the first event in this patient's history window.days_from_prev: regression target -- days between the last history event and the target event.
Embeddings
Provide a NumPy array of shape (N_events, emb_dim) -- one row per unique event
in your dataset. Any sentence embedding works: PubMedBERT, BERT, domain-specific
encoders, etc. The emb_dim can be any size (768, 512, 32, ...).
Pair it with an event_index.json file -- a JSON array where element i identifies
the patient and event for row i of embeddings.npy:
[
  {"subject_id": "patient_001", "event_index": 42},
  {"subject_id": "patient_001", "event_index": 17},
  ...
]
Training
The default task='next_event' reproduces the paper's setup. For arbitrary classification, see Custom Labels below.
import cadence

classifier = cadence.train(
    train_jsonl="my_data/train.jsonl",
    val_jsonl="my_data/val.jsonl",
    embeddings_path="my_data/embeddings.npy",
    event_index_path="my_data/event_index.json",
    n_clusters=50,
    out_dir="./runs/my_run",
    n_epochs=30,
)
Inference
preds = cadence.predict(
    classifier,
    "my_data/test.jsonl",
    embeddings_path="my_data/embeddings.npy",
    event_index_path="my_data/event_index.json",
)
# preds is a list of dicts:
# [{"patient_id": "...", "top_3_clusters": [7, 3, 12],
#   "top_3_probs": [0.42, 0.31, 0.18], "days_until_next": 14.2}, ...]
Feature dimensions (public training path)
The public training path uses 5*n_clusters + max_history + 20 + 2*emb_dim input
features. For n_clusters=50, max_history=10, emb_dim=768: 1806 dims. The paper
checkpoint uses 2420 dims (884 base + 768 + 768); the extra 614 base dims require
MIMIC-specific structured/temporal preprocessing pipelines not available publicly.
The public model uses the same Cadence architecture and training schedule (Phase 1
classification + Phase 2 joint cls+reg + SWA + MixUp + ASL + Gaussian soft targets).
Train on Custom Labels (Binary / Multiclass)
Starting with v1.2.0, cadence.train() accepts task="binary" or task="multiclass" so you can train Cadence on arbitrary labels instead of next-event prediction. Add a label_field key to your target objects and pass it along:
import cadence

# Binary classification on JSONL data
# (your target objects include e.g. {"cluster_id": ..., "readmitted_30d": 1})
classifier = cadence.train(
    train_jsonl="train.jsonl",
    val_jsonl="val.jsonl",
    embeddings_path="embeddings.npy",
    event_index_path="event_index.json",
    n_clusters=50,
    n_epochs=30,
    out_dir="./runs/binary_run",
    task="binary",
    label_field="readmitted_30d",
)
preds = cadence.predict(
    classifier,
    "test.jsonl",
    embeddings_path="embeddings.npy",
    event_index_path="event_index.json",
)
# preds: [{"patient_id": "...", "probabilities": 0.83}, ...]

# Multiclass (4 classes) on JSONL data
classifier = cadence.train(
    train_jsonl="train.jsonl",
    val_jsonl="val.jsonl",
    embeddings_path="embeddings.npy",
    event_index_path="event_index.json",
    n_clusters=50,
    n_epochs=30,
    out_dir="./runs/multiclass_run",
    task="multiclass",
    label_field="discharge_category",
    n_classes=4,
)
preds = cadence.predict(
    classifier,
    "test.jsonl",
    embeddings_path="embeddings.npy",
    event_index_path="event_index.json",
)
# preds: [{"patient_id": "...", "probabilities": [0.1, 0.5, 0.3, 0.1]}, ...]
Pre-built feature matrix
If you already have a feature matrix, skip JSONL entirely:
import cadence
import numpy as np

# X_train: (N, D) numpy array, y_train: (N,) integer labels
classifier = cadence.train_classifier(
    X_train, y_train,
    X_val=X_val, y_val=y_val,
    task="binary",
    n_epochs=30,
    out_dir="./runs/features_run",
)
probs = cadence.predict_from_features(classifier, X_test)
# probs: (N,) array of probabilities for binary; (N, K) for multiclass
Recommended for small datasets (n < 5000)
On small datasets Cadence can overfit quickly. Use early stopping, class weighting, and stronger L2 regularization to stabilize training:
classifier = cadence.train_classifier(
    X_train, y_train,
    X_val=X_val, y_val=y_val,
    task="binary",
    n_epochs=200,
    hidden_dims=(128, 64),         # smaller model for small n
    early_stopping_patience=10,    # halt when val plateaus
    early_stopping_metric="val_auroc",
    class_weight="balanced",       # imbalanced clinical labels
    weight_decay=1e-3,             # stronger L2 vs default 1e-4
    lr=1e-3,
)
probs = cadence.predict_from_features(classifier, X_test)
The same kwargs are available on cadence.train() for task="binary" or
task="multiclass" (JSONL path):
classifier = cadence.train(
    train_jsonl="train.jsonl",
    val_jsonl="val.jsonl",
    embeddings_path="embeddings.npy",
    event_index_path="event_index.json",
    n_clusters=50,
    out_dir="./runs/binary_run",
    task="binary",
    label_field="readmitted_30d",
    n_epochs=200,
    early_stopping_patience=10,
    early_stopping_metric="val_auroc",
    class_weight="balanced",
    weight_decay=1e-3,
)
For task="next_event", these kwargs are accepted but ignored (the next-event
head uses its own two-phase training schedule with fixed hyperparameters).
Reproducibility
Data access requires a signed PhysioNet credentialed account for MIMIC-IV:
https://physionet.org/content/mimiciv/3.1/
Once access is granted, follow the preprocessing instructions in src/ to generate the NV feature sequences and PubMedBERT embeddings used for training.
License
This project is released under the MIT License. MIMIC-IV data is subject to its own PhysioNet Credentialed Health Data License.
Contact
Amir Rouhollahi Brigham and Women's Hospital / Harvard Medical School arouhollahi@bwh.harvard.edu GitHub · PyPI
1 maintainer

Metadata
1 maintainer
Release files for cadence-core 1.3.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| cadence_core-1.3.0.tar.gz | 66.6 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| cadence_core-1.3.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 145.7 kB
Release files / cadence_core-1.3.0.tar.gz
| Download URL | cadence_core-1.3.0.tar.gz |
|---|---|
| Size | 66.6 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
7efd7d5af1d4ef6542e6a32c618338dafd1d9f1df3120377109a98c71b04ca13
|
|
BLAKE2b-256 checksum How to use checksums |
64012ff2be62282564711b8d0a740e4ce7f9098344f71b02505f1e3137e94ac4
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.12.13
|
Release files / cadence_core-1.3.0-py3-none-any.whl
| Download URL | cadence_core-1.3.0-py3-none-any.whl |
|---|---|
| Size | 79.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
5e34b105d521e53c8e19ced05013c5bab0b565d6180845df6a8f0909888db808
|
|
BLAKE2b-256 checksum How to use checksums |
e6c36c5b9d5ab8a4d9debd621d1c58269a55c77800fba5039c010b46c5a674aa
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.12.13
|














