

callm
The production toolkit for LLM calls.
Caching, retries, provider fallback, cost tracking, budgets, PII redaction, prompt-injection detection, structured output validation and telemetry — in one decorator, on top of the SDKs you already use. No proxy. No database server. Zero required dependencies.


Documentation · Quickstart · Features · How it works · CLI
import openai
from pydantic import BaseModel
from callm import callm

class Summary(BaseModel):
    title: str
    bullets: list[str]

client = openai.OpenAI()

@callm(cache=True, retry=3, fallback=["anthropic/claude-sonnet-5"], max_cost=0.25,
       block_pii=True, detect_injection=True, output_schema=Summary)
def summarize(text: str) -> Summary:
    return client.chat.completions.create(
        model="gpt-4o", messages=[{"role": "user", "content": text}]
    )
summarize() still calls OpenAI with your code, your client and your API key — but now every
call is cached, retried on rate limits, failed over to Claude if OpenAI is down, refused if it
would cost more than 25¢, stripped of emails and phone numbers before it leaves your process,
scanned for prompt injection, validated into a Summary object, and recorded in a local cost
dashboard.
Why callm
Every team shipping LLM features writes the same production checklist: retry on 429s, cache
repeated prompts, fall back when a provider has an outage, track spend, keep PII out of prompts,
catch injection attempts, and make the model return valid JSON. That usually means stitching
together tenacity, a cache, a PII library, an output-parsing library and a pile of glue code —
or deploying a proxy service.
callm is a library: install it, add a decorator, ship.
- No rewrite. Keep calling
openai,anthropicorgoogle-genaidirectly. callm intercepts the SDK call inside decorated functions and hands you back the SDK's own response type. - No infrastructure. State lives in a local SQLite file (or memory, or Redis if you want a shared cache).
- No required dependencies. The core is standard library only; features that need extra packages are optional extras.
- Sync and async. Same behaviour for
defandasync def, including concurrent tasks.
Before and after
A simplified version of the glue code callm replaces, for one provider and without fallback, budgets or telemetry:
| Without callm | With callm |
|---|---|
import hashlib, json, re
from tenacity import (retry, stop_after_attempt,
    wait_random_exponential, retry_if_exception_type)
import openai
from pydantic import ValidationError

EMAIL = re.compile(r"[\w.+-]+@[\w-]+\.[\w.]+")
_cache = {}
PRICES = {"gpt-4o": (2.50, 10.00)}  # $/1M tokens

@retry(
    retry=retry_if_exception_type(
        (openai.RateLimitError, openai.APIConnectionError,
         openai.InternalServerError)),
    wait=wait_random_exponential(max=30),
    stop=stop_after_attempt(4),
)
def _create(**kwargs):
    return client.chat.completions.create(**kwargs)

def summarize(text: str) -> Summary:
    text = EMAIL.sub("[EMAIL]", text)
    messages = [{"role": "user", "content": text}]
    key = hashlib.sha256(json.dumps(messages).encode()).hexdigest()
    if key in _cache:
        return _cache[key]
    for _ in range(3):
        response = _create(model="gpt-4o", messages=messages)
        usage = response.usage
        inp, out = PRICES["gpt-4o"]
        log_cost((usage.prompt_tokens * inp
                  + usage.completion_tokens * out) / 1e6)
        content = response.choices[0].message.content
        try:
            result = Summary.model_validate_json(content)
            _cache[key] = result
            return result
        except ValidationError as exc:
            messages += [
                {"role": "assistant", "content": content},
                {"role": "user", "content": f"Fix: {exc}"},
            ]
    raise RuntimeError("model never returned a valid Summary")
|
from callm import callm

@callm(cache=True, retry=3, block_pii=True,
       output_schema=Summary)
def summarize(text: str) -> Summary:
    return client.chat.completions.create(
        model="gpt-4o",
        messages=[{"role": "user", "content": text}],
    )
Plus what the hand-written version lacks:
rate-limit reset headers and Gemini RetryInfo, phone/card/SSN/IBAN
masking, persistent cache, provider fallback,
budgets, injection detection, async support,
telemetry and |
Quickstart
Try it without an API key
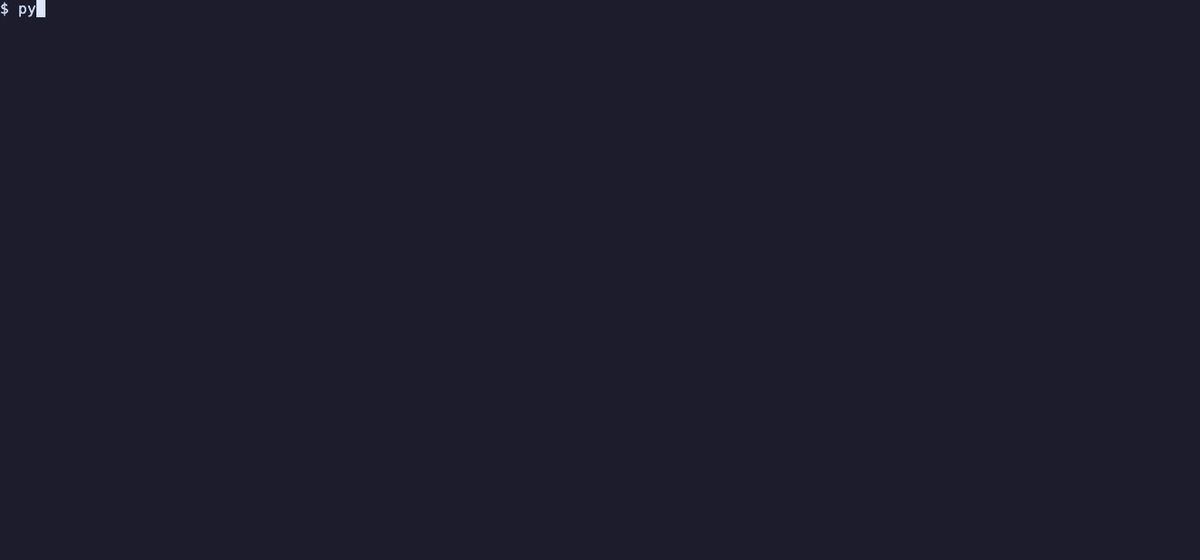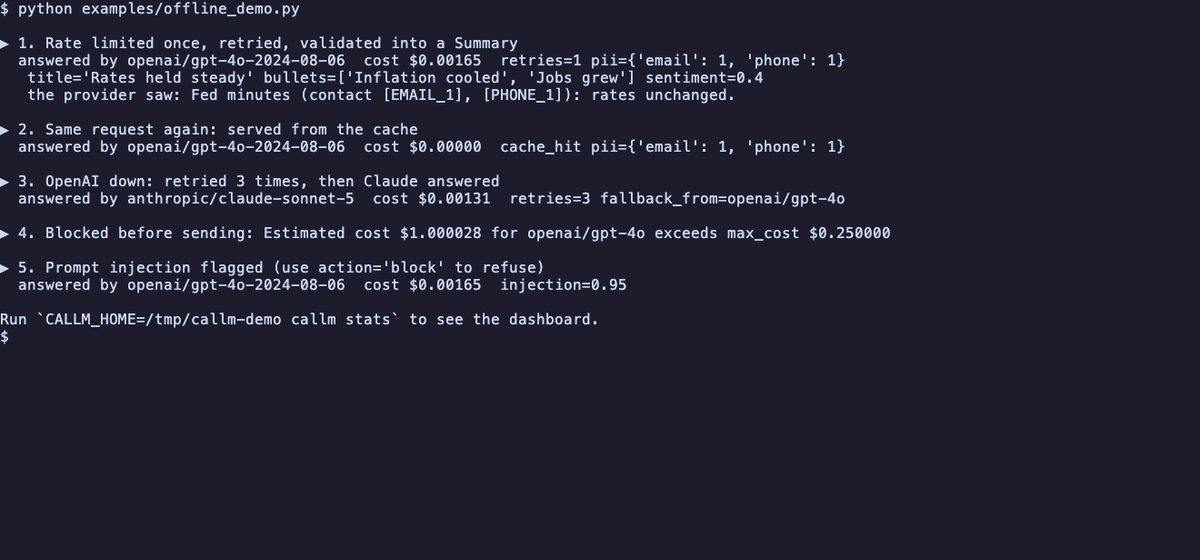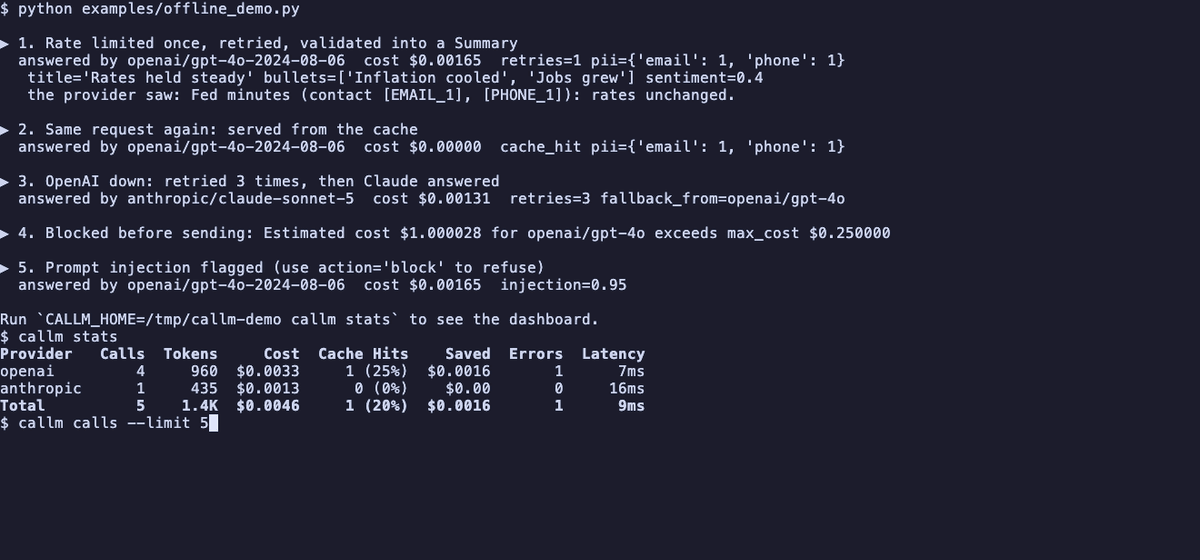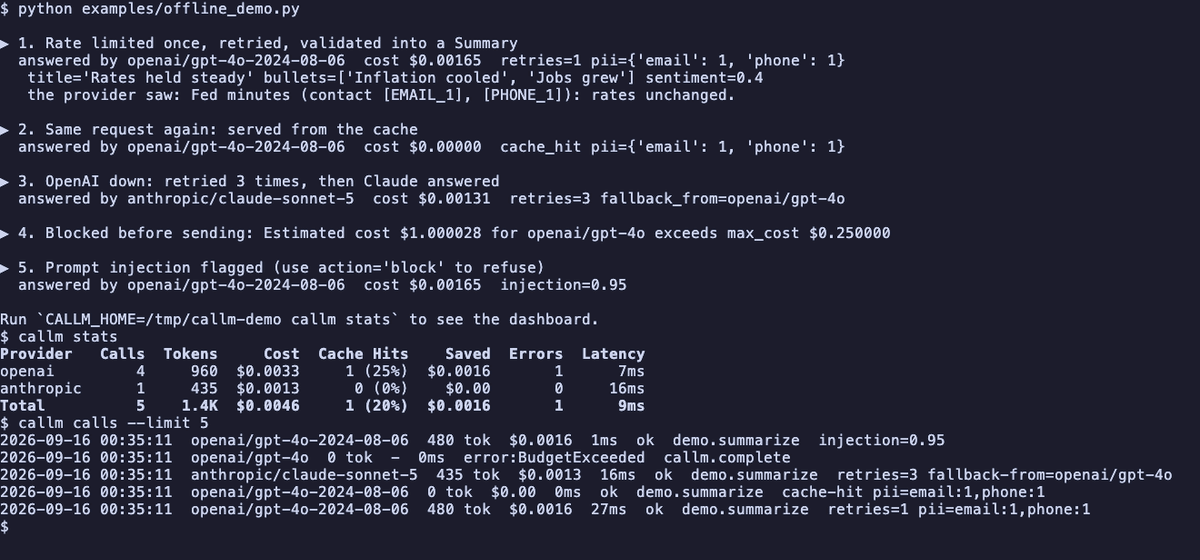
examples/offline_demo.py runs the real OpenAI and Anthropic SDKs against a scripted fake
server and walks through a rate-limit retry, PII masking, schema validation, a cache hit, a
fallback to Claude during an outage, a blocked expensive call and a flagged injection:
pip install "callm-toolkit[openai,anthropic,validation]"
curl -O https://raw.githubusercontent.com/TanbirRamim/callm/main/examples/offline_demo.py
export CALLM_HOME=/tmp/callm-demo      # keep demo data out of ~/.callm
python offline_demo.py
callm stats
(If you cloned the repository, run python examples/offline_demo.py instead.)
With your API key
pip install "callm-toolkit[openai,validation]" # or callm-toolkit[all]
The package is published as callm-toolkit; you import it as callm and the CLI is callm.
import openai
from callm import callm

client = openai.OpenAI()

@callm()  # zero-config: retries + cost tracking
def ask(question: str) -> str:
    response = client.chat.completions.create(
        model="gpt-4o-mini", messages=[{"role": "user", "content": question}]
    )
    return response.choices[0].message.content

print(ask("What is the capital of France?"))
$ callm stats
Provider   Calls   Tokens    Cost   Cache Hits   Saved   Errors   Latency
──────────────────────────────────────────────────────────────────────────
openai         1       31   $0.0000     0 (0%)   $0.00        0     412ms
Features
| Feature | What you get | |
|---|---|---|
| 🔄 | Smart retries | Exponential backoff with full jitter on 408/409/429/5xx/529, timeouts and connection errors. Honours retry-after, retry-after-ms, OpenAI x-ratelimit-reset-*, Anthropic anthropic-ratelimit-*-reset and Gemini RetryInfo. |
| 🗄️ | Response cache | Exact-match by default; opt-in semantic matching with sentence-transformers, OpenAI embeddings or your own embedder. SQLite, memory or Redis. TTLs. Refusals and invalid output are never cached. |
| 🔀 | Provider fallback | Ordered chains across OpenAI, Anthropic, Gemini, Ollama and any OpenAI-compatible endpoint. Requests are translated between providers, and your code still receives the response type of the SDK it called. |
| 💰 | Cost tracking & budgets | Per-call cost from a bundled price table (refreshable with callm pricing update), including prompt-cache read/write pricing. max_cost per call, shared Budgets per function, session or user — enforced before the request is sent. |
| 🛡️ | Input security | PII redaction (emails, phones, SSNs, Luhn-checked cards, IPs, checksum-validated IBANs, optional spaCy names) with stable placeholders. Prompt-injection scoring with a fast heuristic detector and an optional local ML classifier; flag or block. |
| ✅ | Structured output | Pass any Pydantic type as output_schema. Invalid output is re-requested with the validation errors appended, and the function returns the validated object. |
| 📊 | Telemetry | Every call records provider, model, tokens, cost, savings, latency, retries, fallbacks and security flags — never prompt text. callm stats, callm calls, JSON export, on_call hooks and OpenTelemetry spans. |
Examples
Structured output with automatic repair
from pydantic import BaseModel
from callm import callm

class Invoice(BaseModel):
    vendor: str
    total: float
    currency: str

@callm(output_schema=Invoice, validation_retries=2)
def extract(text: str):
    return anthropic_client.messages.create(
        model="claude-sonnet-5", max_tokens=1024,
        messages=[{"role": "user", "content": f"Extract the invoice as JSON:\n{text}"}],
    )

invoice = extract(raw_text)   # -> Invoice(vendor=..., total=..., currency=...)
Fallback across providers
@callm(retry=2, fallback=["anthropic/claude-sonnet-5", "google/gemini-2.5-flash", "ollama/llama3.1"])
def answer(question: str):
    return openai_client.chat.completions.create(
        model="gpt-4o", messages=[{"role": "user", "content": question}]
    )
If OpenAI keeps returning 429/5xx, callm retries, then sends the same conversation to Claude,
then Gemini, then a local model — and answer() still returns an OpenAI ChatCompletion.
Requests that use provider-specific features (tools, images, response formats) only fall back
to models of the same provider, so a fallback never silently changes what you asked for.
Budgets per user
import callm

@callm.callm(max_cost=0.05)
def chat(messages): ...

def handle(user_id: str, messages):
    with callm.budget_for(f"user:{user_id}", limit=2.00):
        return chat(messages)   # raises callm.BudgetExceeded once the user spent $2
Security without a decorator
from callm import shield

with shield(block_pii=True, detect_injection=True) as s:
    # Any supported SDK call inside the block is protected...
    openai_client.chat.completions.create(model="gpt-4o-mini", messages=user_messages)
    # ...and you can make provider-neutral calls directly.
    response = s.complete(provider="anthropic", model="claude-sonnet-5", messages=user_messages)
    print(response.text, response.cost)
Direct, provider-neutral calls
response = callm.complete("gemini/gemini-2.5-flash", "Summarize: ...", max_tokens=200, cache=True)
response.text, response.usage.total_tokens, response.cost, response.raw
Want a complete program to run? examples/ticket_triage.py triages
support tickets with validation, caching, PII masking and a cost report in ~60 lines. More in the
cookbook: a support chatbot, RAG answers with
citations and data extraction.
How it works
your function                         callm middleware stack
─────────────                         ──────────────────────
@callm(...)                    ┌────────────────────────────────────┐
def summarize():   ─────────►  │ 1. Telemetry     cost, latency, tokens
    client.chat.completions    │ 2. Security      injection scan, PII masking
        .create(...)           │ 3. Cache         exact / semantic lookup
                               │ 4. Validator     parse + re-ask on invalid output
                               │ 5. Fallback      next provider when one keeps failing
                               │ 6. Cost guard    max_cost and budgets, before sending
                               │ 7. Retry         backoff honouring retry-after
                               │ 8. Transport ──► the real SDK call
                               └────────────────────────────────────┘
@callmsets a scope (aContextVar) while your function runs.- The official SDK methods (
chat.completions.createand.parse, OpenAI'sresponses.create,messages.create,models.generate_content, sync and async) are instrumented on first use. Outside a callm scope they call straight through, so importing callm never changes other code. - Inside a scope, the SDK call is converted into a provider-neutral request and sent through the middleware chain. Each layer is independent and only enabled when configured.
- The response is converted back into the SDK's native type before it is returned to you.
The middleware is written once as generators and executed by a sync or an async driver, so
def and async def functions behave identically.
Configuration
import callm

callm.configure(
    home="~/.callm",          # SQLite database and price overrides
    storage="sqlite",         # "sqlite" | "memory" | a storage object
    telemetry=True,
    otel=False,               # emit OpenTelemetry spans
    default_retries=2,
    on_call=[print],          # called with every CallRecord
)
| Environment variable | Effect |
|---|---|
CALLM_HOME |
Data directory (default ~/.callm) |
CALLM_STORAGE |
sqlite or memory |
CALLM_TELEMETRY=0 |
Do not persist call records |
CALLM_OTEL=1 |
Export OpenTelemetry spans |
CALLM_DISABLED=1 |
Kill switch: decorated functions run untouched |
Every option of @callm is documented in the API reference.
The callm CLI
$ callm stats --since 7d                 # cost, tokens, cache hits and savings by provider
$ callm stats --by function --json       # machine-readable, per function
$ callm calls --limit 20                 # recent calls with retries, fallbacks, flags
$ callm cache stats | clear
$ callm pricing show claude-sonnet-5     # USD per 1M tokens
$ callm pricing update                   # refresh prices from the LiteLLM price list
$ callm info                             # environment and installed extras
Installation extras
| Extra | Installs | Needed for |
|---|---|---|
openai / anthropic / google |
provider SDKs | calling those providers |
validation |
pydantic>=2 |
output_schema |
cache |
sentence-transformers |
semantic caching with local embeddings |
security |
spacy |
person-name redaction (PIIConfig(ner=True)) |
redis |
redis |
shared cache across hosts |
otel |
opentelemetry-api |
OpenTelemetry spans |
tokens |
tiktoken |
exact OpenAI token estimates for the cost guard |
cli |
rich |
prettier callm stats tables |
all |
everything above |
How callm compares
callm is not the only tool in this space. An honest summary of where each one fits:
| Tool | What it is | Choose it when |
|---|---|---|
| callm | A decorator around your existing OpenAI, Anthropic and Gemini SDK calls: retries, caching, fallback, cost limits, PII masking, injection detection, validation and telemetry, all in-process | You want production hardening without changing how you call the SDKs or running any service |
| LiteLLM | A unified litellm.completion() API for 100+ providers, with a router (retries, fallbacks), caching (including semantic), cost tracking, and a proxy server that adds budgets, virtual keys and guardrails |
You want one API across many providers or a central LLM gateway for a team |
| Instructor | Structured outputs from LLMs with Pydantic models and automatic re-asking, across many providers | Structured extraction is the main problem you need to solve |
| Guardrails AI | A validation framework with a hub of input/output validators (PII, jailbreak detection, and many more) | You need a broad catalogue of validators or custom guard pipelines |
The trade-off: callm covers fewer providers than LiteLLM and fewer validators than Guardrails, in exchange for zero code changes, zero required dependencies and no infrastructure.
Benchmarks
Measured offline with the real OpenAI SDK against a fake server
(method and caveats, reproduce with
python benchmarks/run.py):
- Overhead: +0.06 ms per call with default settings, +0.10 ms with PII masking, injection detection and budgets enabled.
- Cache: 91% lower spend on support/FAQ-style traffic; 2% on prompts that rarely repeat.
- Reliability: with 20% random provider failures, success rises from 79.9% (plain SDK) to
99.4% with
retry=2and 100% with a fallback deployment.
Design decisions and limits
- The cache is exact-match unless you opt into semantic matching. A semantic cache with a
similarity threshold would happily return the answer for "Summarize https://a.example" when
asked about "https://b.example". Use
cache="semantic"(orCacheConfig(semantic=True)) for FAQ-style traffic; semantic matches never cross different system prompts, histories, parameters or schemas. - Injection detection flags by default. Heuristics have false positives, so the default
logs a warning and records the score; use
InjectionConfig(action="block")to refuse. No detector catches every attack — keep treating model output as untrusted. - Budgets use estimates before a call and actual cost after it. Set
max_tokensfor a tight worst-case estimate; without it the cost guard assumes 1,024 output tokens. - Streaming calls get security, retries on connection setup, budgets and telemetry, but are not cached or validated.
- Threads: the callm scope follows
asynciotasks automatically. Work handed to a thread pool needscontextvars.copy_context().run(...), or decorate the function running in the thread. - Prices are a bundled snapshot. Run
callm pricing updateorcallm.set_price(...)for current or negotiated rates.
Contributing
Contributions are welcome. The good first issues are small and scoped, and every pull request gets a review. See CONTRIBUTING.md. The test suite runs entirely offline against the real provider SDKs with mocked HTTP transports:
uv sync
uv run pytest
If callm is useful to you, a star helps other people find it.
License
1 maintainer

Metadata
1 maintainer
Release files for callm-toolkit 0.3.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| callm_toolkit-0.3.0.tar.gz | 131.4 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| callm_toolkit-0.3.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 240.0 kB
Release files / callm_toolkit-0.3.0.tar.gz
| Download URL | callm_toolkit-0.3.0.tar.gz |
|---|---|
| Size | 131.4 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
da35b576593eaf7c7efbcf1e1d16640f533b6a053a55cad31b524b121aa103d1
|
|
BLAKE2b-256 checksum How to use checksums |
58cb390744d697bb5d3f41e28143aa3bba1b9eda6b02847640f080438283f925
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 2, 2026.
Transparency logRelease files / callm_toolkit-0.3.0-py3-none-any.whl
| Download URL | callm_toolkit-0.3.0-py3-none-any.whl |
|---|---|
| Size | 108.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
e96ed1402d3704428c2abf6bf5b7e3a9ad542a25c359c2b6503b08ed1c5b3bde
|
|
BLAKE2b-256 checksum How to use checksums |
e985acd1efb9524a9b8fe196f457141a1ca7262ebabd6f94870ff15936b78914
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 2, 2026.
Transparency log













