
Cartage
Declarative data migrations. Describe sources, destinations and pipelines in YAML, put custom logic in plain Python, run locally to test, and generate thin Airflow DAGs, Dagster jobs or Prefect flows for production.
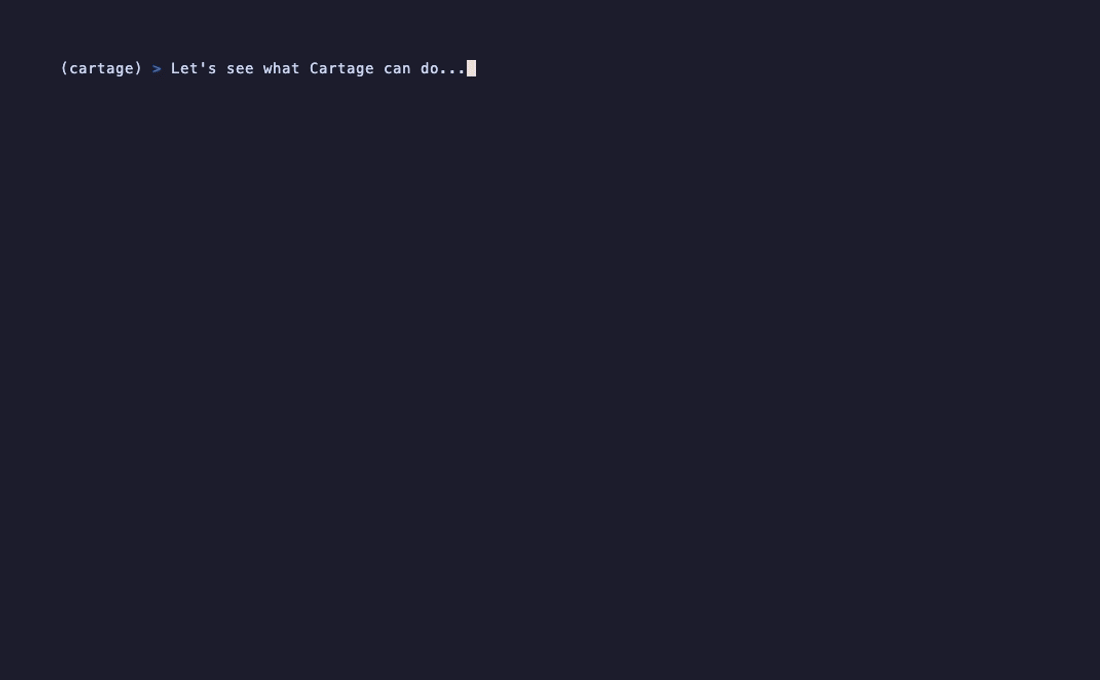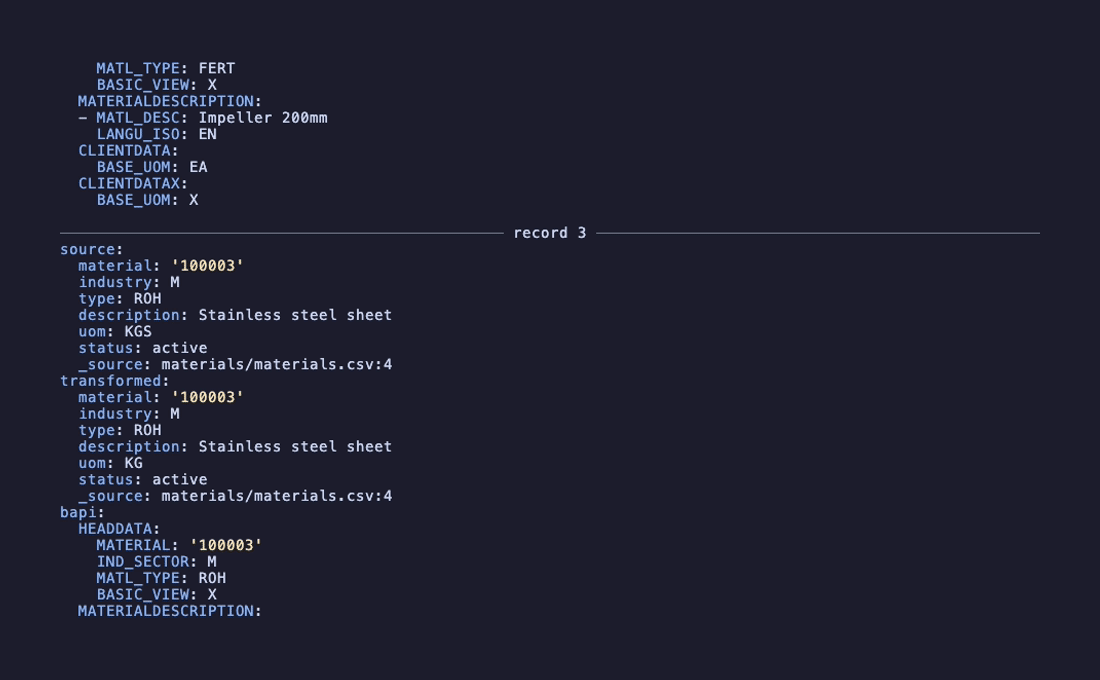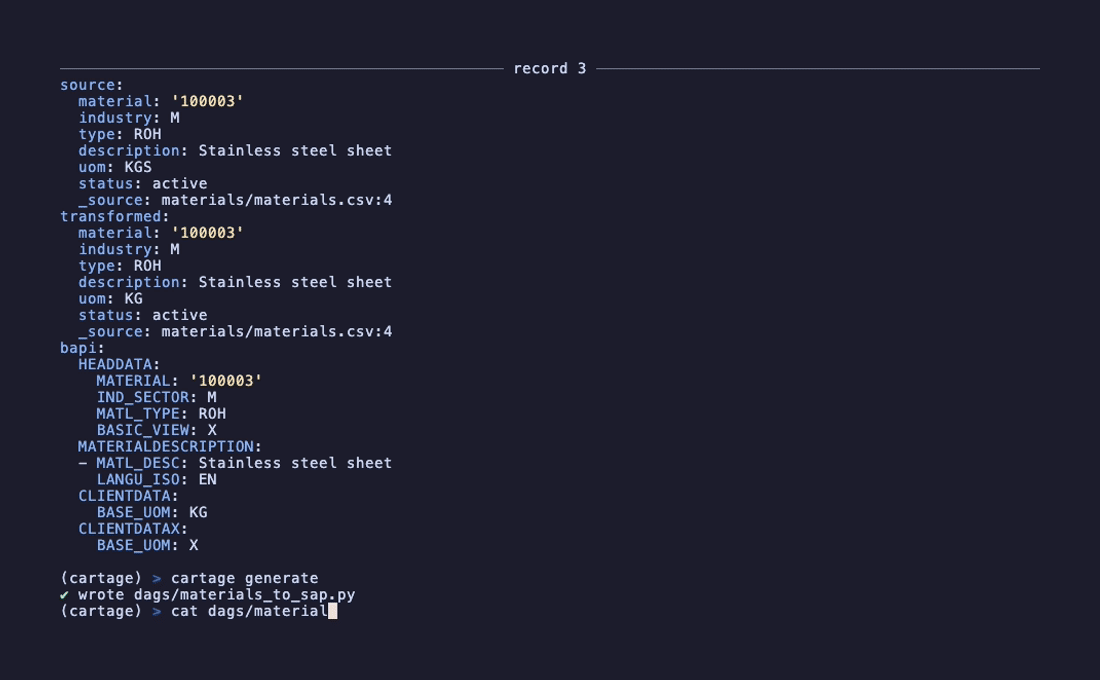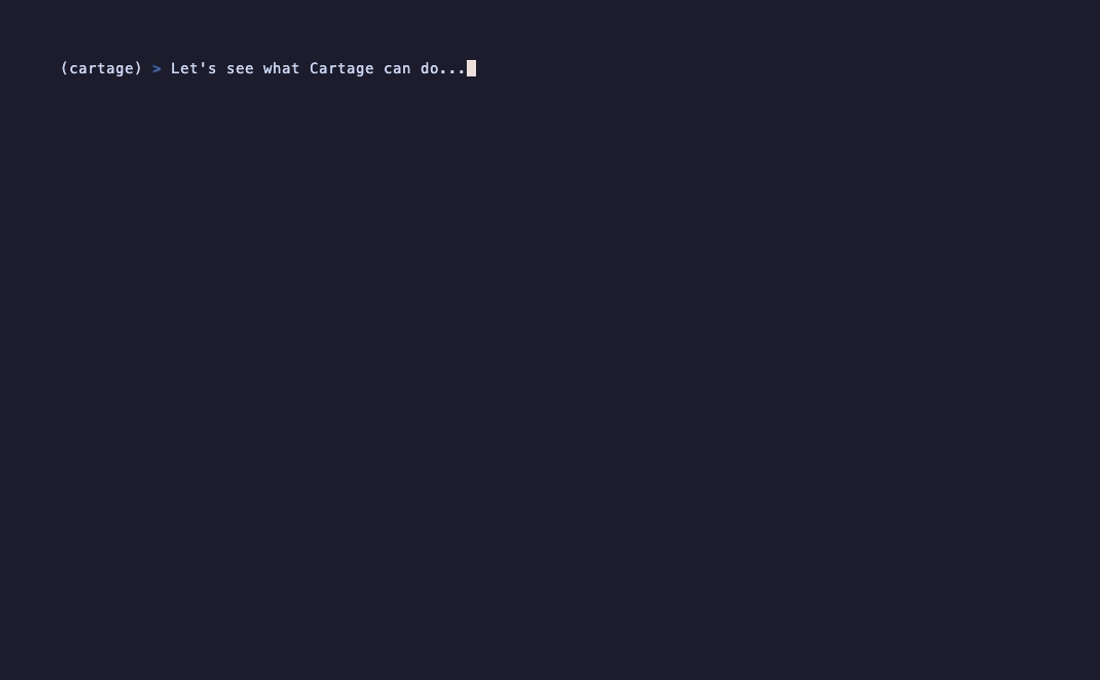
- Sources: local CSV folders, S3, and any dlt source.
- Destinations: SAP via BAPIs (ships a mock SAP; the RFC transport is planned) and any dlt destination (filesystem/S3, DuckDB, Postgres, Snowflake, BigQuery, ...), loaded natively by dlt, and local files (JSON, JSON Lines, XML, CSV). One pipeline can write to several destinations.
- Engines:
python(a plain loop) anddlt. - Orchestrators: Airflow, Dagster and Prefect. Generated code only calls
cartage run, so local and production run the same code.
Quickstart
pip install "cartage[dlt]"
cartage init demo && cd demo
cartage validate
cartage plan materials        # dry run: records before/after transforms and the BAPI payloads
cartage run materials         # reads 20 rows, filters 2, sends 18: 16 load, 2 fail on purpose (exit 1)
cartage run materials --advance-state
cartage run materials         # incremental: nothing new to load
cartage generate              # dags/materials_to_sap.py
cartage generate -t dagster   # orchestration/dagster/<pipeline>.py, for pipelines with schedule.dagster
cartage generate -t prefect   # orchestration/prefect/<pipeline>.py, for pipelines with schedule.prefect
Split-screen demo: run cartage sap mock in one terminal, set url: http://localhost:8765 on sap_erp.dev
in connections.yaml, and run the pipeline in another terminal.
Install
Cartage needs Python 3.11.4 or newer. The core install runs the python engine over CSV folders; extras add the rest.
| Install | Adds |
|---|---|
pip install cartage |
CLI, filesystem source, SAP destination, python engine, all generators |
pip install "cartage[dlt]" |
dlt engine, dlt sources and destinations |
pip install "cartage[s3]" |
S3 source and S3 state store |
pip install "cartage[all]" |
dlt, s3 and airflow |
pip install "dlt[snowflake]" |
the driver for a dlt destination or source (postgres, bigquery, ...) |
Generating Airflow, Dagster or Prefect files needs nothing extra; the orchestrator itself runs them.
Commands
| Command | Does |
|---|---|
cartage init <dir> |
create a demo project (CSV → transforms → mock SAP) |
cartage validate [pipelines...] |
check YAML, connections, secrets, transforms and mappings; moves no data |
cartage plan <pipeline> [-n 3] |
dry run: files to process, each record before/after transforms (or why it was dropped), payloads |
cartage run <pipeline> |
run it; --env, --engine, --full-refresh, --advance-state, --json |
cartage generate [-t airflow|dagster|prefect] |
write orchestrator files; --check, --output, --show-context <pipeline> |
cartage connections list|test <name> |
list connections (secrets as references) or check one |
cartage state show|reset <pipeline> |
inspect or delete incremental state |
cartage plugins |
list installed sources, destinations, engines and orchestrators |
cartage sap mock [--port 8765] |
run a mock SAP server that validates BAPI calls |
Global options go before the command: -C/--project-dir, -v/--verbose, --debug (tracebacks), --no-color.
Project layout
| Path | Purpose |
|---|---|
cartage.yaml |
environments, default engine, state location, orchestrator settings |
connections.yaml |
named connections with settings per environment — secrets only as references |
pipelines/*.yaml |
source → transforms → destination(s) (+ schedule) |
transforms/*.py |
map / filter / batch functions referenced as module:function |
templates/airflow/dag.py.j2 |
optional DAG template override ({% extends "cartage/airflow_dag.py.j2" %}) |
templates/<target>/... |
optional Dagster/Prefect overrides (dagster.py.j2, prefect.py.j2) |
.cartage/ |
git-ignored: secrets.yaml, state/, rejects/ |
YAML configuration
Cartage uses three YAML layers: cartage.yaml sets project-wide defaults, connections.yaml defines named services
per environment, and each pipelines/*.yaml file describes one flow from a source to one or more destinations.
cartage.yaml
project: inventory
environments: [dev, prd]
default_env: dev

defaults:
  engine: dlt # or python

state:
  dev: { path: .cartage/state }

orchestrators:
  airflow:
    dags_dir: dags
    default_args: { owner: data-team, retries: 1 }
The default_env must be listed in environments. A pipeline can override the default engine with its own engine.
State settings are optional; when omitted, Cartage stores local state under .cartage/state.
connections.yaml
Connections have a type and an envs map. Put service-specific settings under the environment where they apply;
pipelines refer to the connection by name. Keep credentials out of the file and use secret or environment references.
connections:
  local_files:
    type: filesystem
    envs:
      dev: { path: ./data }

  sap_erp:
    type: sap
    envs:
      dev: { transport: mock, client: "100" }
      prd:
        transport: rfc
        ashost: sap.example.com
        sysnr: "00"
        client: "100"
        user: "${secret:sap.user}"
        passwd: "${secret:sap.passwd}"
${secret:key} resolves from CARTAGE_SECRET__<KEY> (dots become double underscores and names are uppercased),
then .cartage/secrets.yaml. ${env:NAME} reads an environment variable directly. See Secrets for details.
pipelines/*.yaml
Each pipeline names a source connection, applies an ordered list of transforms, and writes to a destination (or a
list of destinations, see Multiple destinations). A step
must have exactly one of map, filter, or batch; each reference uses the module:function format.
name: materials_to_sap
source:
  connection: local_files
  format: csv
  path: materials/*.csv
  incremental: true

transforms:
  - map: transforms.materials:normalize_uom
  - filter: transforms.materials:is_active
  - batch: transforms.materials:dedupe
    with: { key: material }

destination:
  connection: sap_erp
  bapi: BAPI_MATERIAL_SAVEDATA
  mapping:
    material: HEADDATA.MATERIAL
    description: MATERIALDESCRIPTION[].MATL_DESC
    uom: CLIENTDATA.BASE_UOM
  constants:
    MATERIALDESCRIPTION[].LANGU_ISO: EN
  commit: per_record

schedule:
  airflow:
    schedule: "0 3 * * *"
    tags: [sap, materials]
Source and destination fields other than connection are adapter options. Transform functions live in your transforms/
package; with passes keyword arguments to the function, and on_error: fail stops the run on that step's first
error instead of rejecting the record. The optional schedule.airflow, schedule.dagster and schedule.prefect
blocks control generation with cartage generate (see Orchestrators). Run cartage validate after
editing YAML to check the project and references.
Sources
| Source | Connection settings | Pipeline options |
|---|---|---|
filesystem |
path |
path (glob), format: csv, incremental, batch_size |
s3 |
bucket, prefix, region, endpoint_url, access keys |
path (glob), format: csv, incremental, batch_size |
dlt |
none: use type: dlt on the source |
ref (module:function), with, incremental, batch_size |
File sources with incremental: true skip files already processed. A dlt source's ref returns a dlt source or
resource; incremental: { cursor: updated_at, initial: "2024-01-01" } adds a dlt cursor and needs engine: dlt.
Other keys go to dlt.sources.incremental: lag (re-read a window before the last value, e.g. for late updates),
end_value, primary_key, row_order, last_value_func, on_cursor_value_missing, range_start, range_end.
SAP destination
bapi names the BAPI, mapping maps record fields to BAPI parameters (HEADDATA.MATERIAL, TABLE[].FIELD) and
constants sets fixed values. commit is per_record (default), per_batch or none. cartage validate checks
mapped parameters and fields against the bundled BAPI metadata; the mock SAP also rejects values that are too long,
not allowed, or missing when required, as SAP would.
File destination
type: file writes each run to one local file, in json (an array), jsonl (default), xml or csv. It works with
both engines and needs no extra dependencies. cartage plan shows each record as it will be written.
connections:
  exports:
    type: file
    envs:
      dev: { path: ./output }       # folder, relative to the project
destinations:
  - { connection: exports, format: json }                                 # output/<pipeline>.json
  - { connection: exports, name: as_xml, format: xml, root: materials, record: material }
  - { connection: exports, name: as_csv, format: csv, file: "materials_{date}.csv" }
file is the name inside the folder ({pipeline}, {date} as YYYYMMDD UTC, {ext}; default {pipeline}.{ext}).
The file is written to <file>.partial and moved into place only when the run succeeds, so a failed run never leaves
a half-written file and the previous one stays. Nested values become nested elements in XML (lists as <item>) and
JSON text in CSV; XML names that start with a digit get a leading _. A CSV's columns come from its first record;
records with other columns are rejected. Records that fail transforms go to rejects as usual, and the file holds the
rest.
dlt destinations
Any dlt destination (filesystem/S3, DuckDB, Postgres,
Snowflake, BigQuery, ...) is a type: dlt connection. destination names a dlt.destinations factory, or a project
module:function returning one; the other settings are passed to it. Install the driver extra too, e.g.
pip install "cartage[dlt]" "dlt[snowflake]". dlt destinations need engine: dlt.
connections:
  warehouse:
    type: dlt
    envs:
      dev: { destination: filesystem, bucket_url: "file:///tmp/warehouse" }
      prd:
        destination: snowflake
        credentials: "${secret:snowflake.connection_string}"
        naming: sql_ci_v1                              # connection-level default
destination:
  connection: warehouse
  dataset_name: raw                 # default: the pipeline name
  table_name: materials             # default: the source resource name
  write_disposition: merge          # append | replace | merge; unset: the source resource's hint, else append
  primary_key: material             # merge key: here, or the source resource's own hints
  columns: { price: { data_type: decimal, precision: 18, scale: 4 } }
  loader_file_format: parquet
  naming: direct                    # dlt naming convention, or a project module (e.g. naming.upper)
  dlt_config:                       # any dlt config key, applied to this run only
    data_writer.buffer_max_items: 100000
    extract.max_parallel_items: 15
  after_load:                       # called as f(pipeline, **with) after a successful load
    - { ref: utils.snowflake:enable_change_tracking, with: { tables: [materials] } }
The dlt engine loads straight into the destination: bulk loads, staging and merge are dlt's, run once per run.
Without transforms, source batches reach dlt untouched, so Arrow/pandas batches (e.g. sql_database with the
pyarrow backend, ConnectorX) stay columnar. Hints the source resource sets itself (write_disposition,
primary_key, columns, ...) are kept unless the destination sets them. after_load hooks get the dlt pipeline, so
they can run SQL with pipeline.sql_client() (grants, tags, change tracking); if one fails the data stays loaded, the
run exits with code 3 and state is not saved. dlt fails whole load jobs, not single records: a failed load stops the
run and state is not saved. Database-specific extraction (casts for Oracle LOBs and NUMBERs, MSSQL datetime2, Postgres
enums and timestamptz, time zones) belongs in your dlt source factory, not in Cartage.
Example: an incremental table copy from a database into Snowflake, kept columnar end to end.
# sources/erp.py
from dlt.sources.sql_database import sql_table

def materials(credentials: str, schema: str):
    return sql_table(credentials=credentials, schema=schema, table="materials", backend="pyarrow")
name: erp_materials
source:
  type: dlt
  ref: sources.erp:materials
  with: { credentials: "${secret:erp.url}", schema: ERP }
  incremental: { cursor: updated_at, initial: "2024-01-01" }
destination:
  connection: warehouse
  dataset_name: raw_erp
  write_disposition: merge
  primary_key: material
engine: dlt
Multiple destinations
Use destinations: instead of destination:. Each entry is its own run, in order, with its own state, rejects and
dlt pipeline (<pipeline>__<name>; name defaults to the connection and tells apart destinations that share
one), so a failed destination retries without reloading the others. The source is
read once per destination; to read it once, land it in filesystem/S3 first and load from there.
destinations:
  - { connection: warehouse, table_name: materials, write_disposition: merge, primary_key: material }
  - { connection: sap_erp, bapi: BAPI_MATERIAL_SAVEDATA, mapping: { ... } }
Orchestrators
cartage generate --target airflow|dagster|prefect writes one file per pipeline that has a schedule.<target> block.
Each file only runs cartage --project-dir <project> run <pipeline> --env <env>, so deploy the Cartage project (with
transforms/) next to it. Settings merge: built-in defaults ← orchestrators.<target> in cartage.yaml ← the
pipeline's schedule.<target> (dicts merge by key). Add --check in CI to fail on stale files.
schedule:
  airflow: { schedule: "0 3 * * *", tags: [sap] }
  dagster: { schedule: "0 3 * * *", tags: { team: data }, timezone: Europe/Brussels }
  prefect: { schedule: "0 3 * * *", tags: [sap], retries: 2 }
| Target | Output (default) | Settings | Environment at run time |
|---|---|---|---|
| airflow | dags/<dag_id>.py |
dags_dir, schedule, tags, default_args, operator, operator_args, task_env, image, ... |
Airflow var cartage_env |
| dagster | orchestration/dagster/<name>.py |
out_dir, name, schedule, timezone, tags, env, command, project_dir |
CARTAGE_ENV env var |
| prefect | orchestration/prefect/<name>.py |
out_dir, name, schedule, retries, tags, env, command, project_dir |
CARTAGE_ENV env var |
- Dagster: each file defines a job, its schedule, and
defs = dg.Definitions(...). Load it withdagster dev -f orchestration/dagster/<name>.py(repeat-fper pipeline), or merge thedefsobjects. - Prefect: each file defines the
cartage_runflow.python orchestration/prefect/<name>.pyserves it on the schedule, or pointprefect deployatorchestration/prefect/<name>.py:cartage_run. envdefaults toprd;command(defaultcartage) may include a launcher, e.g.uv run cartage.- Airflow:
task_envadds environment variables to the task (e.g.UV_CACHE_DIR).operatorcan be anyBashOperator-compatible class, e.g.operators.datacoves.bash:DatacovesBashOperator. A project template (templates/airflow/dag.py.j2,{% extends "cartage/airflow_dag.py.j2" %}) can override the blocksheader,imports,default_args,schedule,dag,taskandextra, e.g.{% block schedule %}my_utils.set_schedule({{ super() }}){% endblock %}.
Airflow connections
In Airflow, credentials usually live in Airflow connections. Cartage reads them with ${airflow:...} references, so
nothing has to copy them into variables by hand and they never appear in YAML or in the generated DAG.
1. Reference connection fields in connections.yaml, in the environment the DAGs run (the cartage_env Airflow
variable, prd by default):
warehouse:
  type: dlt
  envs:
    dev: { destination: snowflake, destination_name: datacoves_snowflake }   # ~/.dlt/secrets.toml locally
    prd:
      destination: snowflake
      credentials:
        host: "${airflow:main_load_keypair.extra.account}"
        username: "${airflow:main_load_keypair.login}"
        private_key: "${airflow:main_load_keypair.extra.private_key_content}"   # PEM, as stored
        warehouse: "${airflow:main_load_keypair.extra.warehouse}"
        role: "${airflow:main_load_keypair.extra.role}"
| Reference | Airflow connection field |
|---|---|
${airflow:<conn_id>.login} |
Login (also password, host, schema, port) |
${airflow:<conn_id>.extra.<key>} |
a key of the Extra JSON; nest with dots (extra.auth.token) |
2. Generate the DAGs. cartage generate collects every ${airflow:...} used by the pipeline (its source,
destinations, state store and options, in every environment) and passes them to the task as environment variables
whose values are Airflow templates:
BashOperator(
    task_id="cartage_run",
    bash_command="cartage --project-dir ... run pipelines/loans.yaml --env {{ var.value.get('cartage_env', 'prd') }}",
    env={"CARTAGE_AIRFLOW__MAIN_LOAD_KEYPAIR__LOGIN": "{{ conn.get('main_load_keypair').login or '' }}", ...},
    append_env=True,
)
3. Airflow fills them in when the task runs, from wherever it keeps connections (metadata database, a secrets
backend such as Vault or AWS Secrets Manager, or AIRFLOW_CONN_<ID> variables), and masks passwords in the task log.
4. cartage run resolves each reference from its CARTAGE_AIRFLOW__<CONN_ID>__<FIELD> variable (dots and dashes
become __ and _). Values are never printed.
Notes:
- Rerun
cartage generatewhen references change;cartage generate --checkin CI catches stale DAGs. - A field that is empty in the connection resolves to
"". A missingextrakey fails the task when Airflow renders it (Airflow'sStrictUndefined), naming the key. - Outside Airflow,
cartage run/validatestop at the first${airflow:...}with a hint naming the variable. Use another environment locally (${secret:...},${env:...}or the driver's own config), or export the variable. - To test a DAG without a real connection, define one inline:
AIRFLOW_CONN_MAIN_LOAD_KEYPAIR='{"conn_type": "snowflake", "login": "...", "extra": {...}}' airflow dags test <dag_id>. - Dagster and Prefect pass secrets to tasks as environment variables; read them with
${env:...}.
Batches
batchtransforms see one source batch at a time (default 100 rows,batch_sizesource option), never across files.commit: per_batchcommits each batch the engine hands to the destination (the dlt engine re-chunks at 100).- dlt destinations are not fed in batches: dlt extracts, normalizes and loads the whole run. Size its files and
buffers with
dlt_config(e.g.data_writer.buffer_max_items,data_writer.file_max_items).
Secrets
${secret:sap.passwd} reads CARTAGE_SECRET__SAP__PASSWD, then .cartage/secrets.yaml. ${env:VAR} reads an
environment variable. Resolved values are never printed.
${airflow:<conn_id>.<field>} reads a field of an Airflow connection inside DAGs from cartage generate; see
Airflow connections.
State and rejects
Incremental state is saved only when a run has no record errors (or with --advance-state). Rejected records
go to .cartage/rejects/<pipeline>/<run_id>.jsonl. cartage state show|reset <pipeline> inspects or clears state.
With several destinations, each destination is its own run named <pipeline>__<name>: state, rejects and the
dlt pipeline are kept per destination, and state show|reset covers all of them. cartage run goes through the
destinations in order and stops at the first fatal error; destinations that already finished keep their state, so a
rerun only retries the rest. With --json, run prints one result line per destination and plan prints a list.
Cartage's state store is the source of truth for dlt state: dlt's restore-from-destination is disabled, so
--full-refresh really starts from scratch.
Exit codes
0 ok · 1 record errors · 2 configuration error · 3 fatal run error (connection, transport, failed dlt load,
on_error: fail).
Advanced: database extraction tuning
Cartage has no database drivers of its own: a dlt source's ref is your Python, so ConnectorX, sql_table,
SQLAlchemy, Oracle or Teradata clients, and every per-database fix are plain code in your project. Cartage calls the
function with with: (secrets resolved), adds incremental:, and hands what it yields to dlt. Keep tuning helpers in a
project package (e.g. utils/) and use them from source functions. Where each kind of tuning goes:
| Need | Where in Cartage |
|---|---|
| Driver and backend (ConnectorX, pyarrow, pandas, SQLAlchemy) | the source function |
| SQL casts per database (timestamps, LOBs, decimals, enums) | the source function builds the SELECT |
| Per-batch type fixes (epoch ms, ints → float, rounding) | resource.add_map(...) in the source function |
| Row-count / truncation checks | a generator wrapper in the source function |
| Credentials | with: + ${secret:...} |
| dlt performance and load settings | dlt_config: on the destination |
Identifier casing (direct, upper, lower, keep quotes) |
naming: on the destination |
| Column types, nullability | columns: on the destination, or hints in the source |
pipelines_dir, bucket URL, write disposition, file format |
Cartage state, the connection, destination options |
Driver, casts and fallback
The source function picks the driver and can fall back when a type isn't supported, then build its query from
metadata-driven casts (for example a build_select_with_casts-style helper that reads ALL_TAB_COLUMNS or
INFORMATION_SCHEMA):
# sources/erp.py
from urllib.parse import quote_plus

import connectorx as cx
import dlt

from utils.data_types import build_select  # your helper, e.g. adapted from build_select_with_casts


@dlt.resource(name="materials", max_table_nesting=0)
def materials(db: str, user: str, password: str, dsn: str, table: str, conversions: dict | None = None,
              updated_at=dlt.sources.incremental("UPDATED_AT")):
    conn = f"{db}://{quote_plus(user)}:{quote_plus(password)}@{dsn}"
    where = f" WHERE UPDATED_AT >= '{updated_at.start_value}'" if updated_at.start_value else ""
    query = f"SELECT {build_select(conn, table, conversions or {})} FROM {table}{where}"
    try:
        yield from cx.read_sql(conn, query, return_type="arrow_stream", batch_size=10_000)
    except BaseException:  # Arrow stream lacks some types (e.g. Oracle NCLOB): fall back to a DataFrame
        yield cx.read_sql(conn, query)
source:
  type: dlt
  ref: sources.erp:materials
  with:
    db: oracle
    user: "${secret:erp.user}"
    password: "${secret:erp.password}"
    dsn: "${secret:erp.dsn}"
    table: ERP.MATERIALS
    conversions: { CREATED_ON: timestamp, NOTES: lob_text }
  incremental: { cursor: UPDATED_AT, initial: "2024-01-01" }
Cartage's incremental: binds to the function's dlt.sources.incremental argument, so start_value is the stored
cursor: put it in the WHERE to read only new rows. dlt's sql_table(..., backend="connectorx" | "pyarrow" | "sqlalchemy") does that pushdown for you, and takes query_adapter_callback (extra filters or suffixes),
table_adapter_callback (e.g. remove_nullability_adapter) and chunk_size. Pass with: values such as backend
or connector: sqlalchemy to switch drivers per pipeline when ConnectorX can't read a table.
Per-batch type normalization
Attach Arrow, pandas or row transforms with add_map. They run inside dlt on every batch, before normalization, and
keep batches columnar:
from utils.data_types import normalize_types  # timestamps → epoch ms, decimals/ints → float64, rounding

def orders(...):
    return sql_table(credentials=..., table="ORDERS", backend="pyarrow").add_map(normalize_types)
Prefer add_map in the source over Cartage transforms for bulk copies: Cartage transforms see row dicts, so Arrow
batches are converted to rows first.
Row-count checks
ConnectorX can silently return fewer rows (dropped batches, timeouts). Count what you yield and raise at the end; the run then fails with exit code 3 before anything is loaded, and no state is saved:
def checked(batches, expected: int, tolerance: int = 10):
    n = 0
    for batch in batches:
        n += len(batch)  # Arrow tables, DataFrames and lists all have len()
        yield batch
    if n < expected - tolerance:
        raise RuntimeError(f"extracted {n} rows, source had {expected}: try connector: sqlalchemy")

@dlt.resource(name="materials")
def materials(conn: str, table: str):
    expected = int(cx.read_sql(conn, f"SELECT COUNT(*) FROM {table}").iloc[0, 0])
    yield from checked(cx.read_sql(conn, f"SELECT * FROM {table}", return_type="arrow_stream"), expected)
dlt settings and naming
dlt_config: takes any dlt config key (as in dlt.config[...]), on the connection as a default or on the pipeline
destination as an override, applied only while that run executes:
destination:
  connection: lake
  loader_file_format: parquet
  write_disposition: replace
  naming: utils.sql_upper             # a module with a NamingConvention class, as dlt's schema.naming expects
  columns: { AMOUNT: { data_type: double, nullable: true } }
  dlt_config:
    sources.data_writer.file_max_items: 1000000
    sources.data_writer.file_max_bytes: 100000000
    data_writer.buffer_max_items: 100000
    extract.max_parallel_items: 15
    normalize.data_writer.disable_compression: false
    load.truncate_staging_dataset: true
naming takes dlt's built-ins (direct, snake_case, sql_cs_v1, sql_ci_v1) or a project module, so naming
classes such as upper, lower or keep-quotes variants work as they are. Two settings are Cartage's: leave
load.delete_completed_jobs true (the state archive must not keep loaded data) and restore_from_destination false
(Cartage's state store is the source of truth).
Process-wide patches to dlt internals (for example keeping all-null columns) are not run settings: apply them in the source module (at import, or at the start of the source function), knowing they affect every pipeline in that process.
Extending
Adapters are entry points in the groups cartage.sources, cartage.destinations, cartage.engines and
cartage.orchestrators. cartage plugins lists what is installed.
A destination is a record sink (preview + write, like SAP and file) by default. Optional: finish(ok) is called
after the run (to finalize or discard output), and preview_label/preview_syntax name and highlight plan output. To have the dlt engine load into it natively
instead, expose dlt_destination() returning a dlt destination, plus hints (resource hints such as
write_disposition), dataset_name, loader_file_format and dlt_env (env vars applied to the run), as the
built-in dlt destination does.
License
Apache-2.0
1 maintainer

Metadata
1 maintainer
Release files for cartage 0.5.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| cartage-0.5.0.tar.gz | 5.0 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| cartage-0.5.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 5.1 MB
Release files / cartage-0.5.0.tar.gz
| Download URL | cartage-0.5.0.tar.gz |
|---|---|
| Size | 5.0 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
f72479d224cd20849fb2b5a6512cd94c7660dd42d3ff6aa9200674f680990dd8
|
|
BLAKE2b-256 checksum How to use checksums |
b97929cb0126216e0fe495e510326fcaa1fe4348f3d4dfed17c50e7145713d9a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
uv/0.12.21 {"installer":{"name":"uv","version":"0.12.21","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":true}
|
Release files / cartage-0.5.0-py3-none-any.whl
| Download URL | cartage-0.5.0-py3-none-any.whl |
|---|---|
| Size | 70.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
cf9726ebfb89018d9320f97c33e54d57a234891a929a61c294d0a563a5bc5173
|
|
BLAKE2b-256 checksum How to use checksums |
3d5bb4ce5434210b72acf636ec1ec1cf9b9180e44a45eb374215ef00d874ee1c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
uv/0.12.21 {"installer":{"name":"uv","version":"0.12.21","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":true}
|














