
Agent tools you declare instead of implement.
Documentation · Quickstart · Packs · Write a pack · Request a pack



Charter
You define the schema, the model fills in the args, and Charter does the plumbing: the request, the auth, the wire format. The same declaration decides what the model can see and send. No glue code.
A library, not a service. Runs in your process. No proxy, no per-call pricing, no telemetry.
Installation
pip install charter-ai
549 tools across fifteen APIs ship with
it, on two dependencies: pydantic>=2.9,<3 and httpx>=0.27,<1. Packs never add more.
The upper bounds are so a fresh install cannot silently resolve to pydantic 3.0 the day
it ships.
Call a tool that ships
Every pack is already declared. Point one at a credential and invoke it:
from charter.auth import EnvTokenProvider
from charter.packs import gmail

gmail.configure(EnvTokenProvider("GOOGLE_ACCESS_TOKEN"))

await gmail.messages_list.ainvoke({"q": "is:unread", "maxResults": 5})
A tool is four markers and a URL
Path, Query, Body, Format. That is the core, and there is no abstraction
underneath it. You read the API's reference page and write down what it says, field by
field, in the dumbest possible way, on a pydantic model of your own:
from typing import Annotated

from pydantic import BaseModel

from charter import Path, Query, oauth_tool_factory
from charter.auth import EnvTokenProvider

class ListMessages(BaseModel):
    user_id: Annotated[str, Path()] = "me"
    q: Annotated[str, Query()]
    max_results: Annotated[int, Query()] = 10

gmail = oauth_tool_factory(
    pack="mygmail",
    base_url="https://gmail.googleapis.com/",
    provider="google",
    credential_provider=EnvTokenProvider("GOOGLE_ACCESS_TOKEN"),
    query_case="camel",
)

list_messages = gmail(
    name="list_messages",
    description="Search the mailbox and return matching messages.",
    method="GET",
    url_template="gmail/v1/users/{user_id}/messages",
    args_schema=ListMessages,
)

await list_messages.ainvoke({"q": "is:unread", "max_results": 5})
Ordinary pydantic, ordinary types. Path() interpolates into the URL template,
Query() becomes a query parameter, and query_case="camel" spells max_results the
way Gmail wants it on the wire.
Body and Format are the other two, and Format is where a wire format the model
should never construct is declared once:
from typing import Annotated

from pydantic import BaseModel

from charter import Body, EmailContent, Format

class SendEmail(BaseModel):
    raw: Annotated[EmailContent, Body(envelop=True), Format("rfc822_base64")]
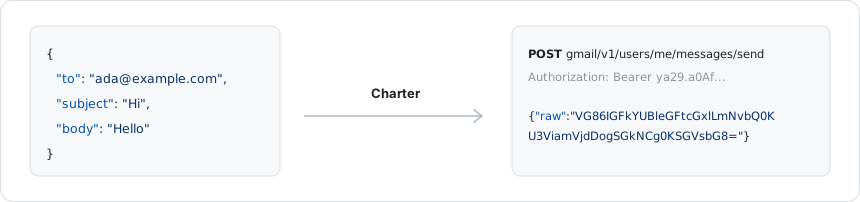
The model fills in to, subject and body. Everything between that
and the request Gmail accepts is declared rather than written.
The model never touches a wire format. Not MIME headers, not base64 padding, not a
GraphQL document. Every format handled by hand is a library, a spec, and a thing that
drifts when the API moves. Here Format("rfc822_base64") is the whole of it: it builds
the RFC 2822 document and encodes it base64url, and Body(envelop=True) puts it under
raw. No email builder, no Google SDK, nothing added to the two dependencies.
What that replaces.
There is no drift between the declaration and the vendor either, because it mirrors Gmail's own reference page line for line, which is why a reviewer can check one against the other and a coding agent can write one.
What no glue code buys
There is no per-endpoint code in Charter, generated or hidden. So when a tool call fails it was the model's arguments, or it was the API. It was never the tool's logic, because there is no tool logic. With that variable held still, you can finally tell a better model from a worse one, and a better prompt from a worse one. Bad arguments do not reach the API either: they fail validation locally, with an error written for the model, so it fixes them next turn.
Two campaigns, on 15 and 16 September 2026, against live accounts over real API calls, with no mocks and no recorded fixtures. Two arms over the same tasks, models, prompts and credentials, differing only in the tool surface: Charter's packs against one generic HTTP tool per provider, where the model supplies the method, path, query and body itself. That raw arm is the glue people write first, and its endpoint list is derived from the pack's own tools so nobody hand-picked what it could reach. Full methodology.
| Across 534 measured runs | raw HTTP tool | Charter |
|---|---|---|
| malformed GraphQL documents | 32 | 0 |
| calls to endpoints never declared | 10 | 0 |
| base64 the API rejected | 4 | 0 |
Auth, end to end, without an OAuth library
Declare the server, pick a strategy, done. An env key, a token you already hold, a full
authorization-code client with refresh and rotation, or one credential per end user:
same seam either way, and no OAuth library. You never install google-auth or a
vendor SDK. Single-flighted refresh, rotation and renewal timing are handled, and you
will not think about them again.
gmail.configure(EnvTokenProvider(...)) above was the simplest of those. The hardest is
the same one line: SubjectProvider resolves a different credential per end user, per
call, through an authorization-code client you configure once, with refresh and rotation
handled.
Getting the grant has it end to end.
You do not have to know the server's details.
discover() reads them from
RFC 8414 metadata, which is why an enterprise IdP nobody has heard of needs no special
support. You do not have to know which scopes to ask for either.
scopes_for() computes them from the
tools you hand out:
from charter.auth import scopes_for
from charter.packs import gmail

scopes_for([gmail.messages_list])    # ['https://www.googleapis.com/auth/gmail.modify']
scopes_for([gmail.threads_delete])   # ['https://mail.google.com/']
Policy that lives on the declaration
pin fixes a value the model can neither see nor set. Not a prompt instruction,
not a check afterwards: absent from the schema it fills in, present in the one the
runtime executes, indistinguishable on the wire from a value you passed by hand. A
customer id, a region, a year, a sandbox flag. One line where otherwise it is plumbing:
from charter import format_egress_map
from charter.packs import gdrive

search_documents = gdrive.files_list.derived(
    name="search_documents",
    pin={"q": "mimeType='application/vnd.google-apps.document'"},
)

print(format_egress_map([search_documents]))
search_documents  (GET drive/v3/files)
  visible to the model (10):
    + page_size
    + page_token
    ...
  withheld (5):
    - q  [pinned] = "mimeType='application/vnd.google-apps.document'"
Mode makes one tool behave several ways. The string is arbitrary, so one
schema covers whatever you need it to:
- Versioning:
Mode("v1"),Mode("v2") - A/B testing:
Mode("A"),Mode("B"),Mode("A, B") - Plan tiers:
Mode("pro"),Mode("max") - Regional rules:
Mode("uk"),Mode("fr"),Mode("us"),Mode("eu") - Read vs write:
Mode("read"),Mode("write")
ToolSession(tools, mode=plan_of(user)) puts a label in force across every tool it
holds, replacing a TOOLSETS = {"free": [...], "pro": [...]} dict and the code that
chooses between its entries. The label sits beside the one each tool was declared with
rather than replacing it, so a pack's own create/update split survives and you do
not have to read a pack to predict what keying it to a tier will do. static_body,
static_query and static_headers do the same at the factory, for a constant every
tool in a pack must send and the model must never see.
Tune the surface before you tune the prompt
Linear's IssueFilter carries every condition the API accepts, which renders as 187KB of
schema. To address that, a projection does two things with one edit:
- Scope. It narrows what the tool can do.
- Context. It narrows how much of the context window the tool occupies. A schema is in the prompt on every turn, before the model has read the task, so it is part of what the model decides with.
We hit this on Linear, running the benchmark. The fix was to cut the filter down to the conditions a triage agent actually uses. Thirty generations per cell, temperature 0, one task:
| the filter the model was given | bytes | glm-5p3-flash | deepseek-v4p1 | nemotron-lightning |
|---|---|---|---|---|
| removed entirely | 1,131 | 0/30 | 0/30 | 0/30 |
| the full mirror | 187,655 | 22/30 | 400 ×30 | 400 ×30 |
| curated | 15,531 | 28/30 | 30/30 | 4/30 |
Deleting the filter is the first row: a list tool that cannot narrow a list, so all three
models page the whole team 250 issues at a time. A prompt does not reach this either. The
same model used the filter 21/21 times when the schema was accidentally flat and 0/40
after — the capability was never missing, the shape was. The 400s are the extreme case,
and the end of this section.
Steps 1 and 2. by_cost=True prices a level instead of naming it, each path really pruned
and the schema regenerated, so the number is what cutting it will do:
from charter import schema_tokens
from charter.packs import linear

schema_tokens(linear.issues_list_full)            # 46913
linear.issues_list_full.paths()                   # ['variables']
linear.issues_list_full.paths(under="variables")
# ['first', 'after', 'filter', 'order_by', 'include_archived']

linear.issues_list_full.paths(under="variables", by_cost=True)
# [PathCost(path='filter',   tokens=46631),
#  PathCost(path='order_by', tokens=57),
#  PathCost(path='first',    tokens=50), ...]
One field of five is 46,631 of the 46,913, and nothing about its name said so.
Step 3 is the only one with judgement in it, and the question is about the job rather than the schema: which conditions does this agent narrow a list by? For triage, the issue's own fields plus one level into the four relations that identify work. That is the curated row above:
from charter import schema_tokens
from charter.packs import linear

F = "variables.filter."

issues_list_triage = linear.issues_list_full.derived(
    name="issues_list_triage",
    keep={
        F + "id", F + "number", F + "title", F + "priority",
        F + "due_date", F + "created_at", F + "updated_at", F + "completed_at",
        F + "state.type", F + "state.name",
        F + "assignee.email", F + "assignee.name",
        F + "team.key", F + "team.name",
        F + "labels.name",
    },
)

schema_tokens(issues_list_triage)    # 3458, i.e. 13,832 bytes
Write the full dotted path: keep={"labels"} matches more than 200 paths on this schema
and raises rather than guessing. And name team.key, not team — keeping a relation
keeps its whole subtree, which drags the cycle back in and lands you at 46,313 tokens,
larger than what you started with.
The same edit is a permission. A Google documents scope does all 33 kinds of edit
as one indivisible grant, and keep says "may edit text, may not delete content" about
it:
from charter import schema_tokens
from charter.packs import gdocs

edit_text = gdocs.documents_batch_update.derived(
    name="documents_edit_text",
    keep={"insert_text", "delete_content_range", "replace_all_text"},
)

edit_text.paths(under="body.requests")
# ['replace_all_text', 'insert_text', 'delete_content_range']  — 33 down to 3
schema_tokens(edit_text)    # 1750, from 8183
A projection can only ever remove, which is what makes the saving and the restriction one line of code, and what makes it safe to hand to whoever owns the deployment rather than the pack.
At the extreme, a schema is not expensive, it is refused. IssueFilter refers back to
itself, and on a schema that does:
The long version covers the $defs arithmetic, what flattening clients do to
a cycle, and why deferral is the other half of this lever rather than a substitute.
Control what comes back
A schema says what goes out. A response handler says how much of what comes back the model ever sees, and one Gmail call can otherwise end a conversation on its own: a base64 body, a dozen response-only fields, a block tree, avatar URLs eight to a user.
Across the same 534 runs the Charter arm handed the model roughly a quarter of the bytes the raw arm did, 7,382 against 36,383 per run in one campaign and 10,581 against 39,785 in the other. In the second it had pulled more off the wire, not less. It forwarded less, by the packs' own handlers, with nothing configured.
Print the boundary
A property enforced by construction is only auditable if something prints it. Two do, both generated from the declarations the runtime executes, so neither can drift:
egress_map()answers what a security review actually asks. Snapshot it in CI and a change to what the model can see becomes a reviewable diff on a pull request.format_conflicts()prints the rules an API keeps in prose. Google Calendar'ssyncTokenrefuses eight other parameters; that is a property of the schema here, checked on every call.
When a 200 is not a success
Slack answers a rejected request with 200 OK and {"ok": false}. Every GraphQL API
returns 200 with an errors array. Linear returns success: false, Shopify returns
userErrors. Every signal a runtime normally trusts says the write happened, and your
agent tells the user the message sent.
from charter import Envelope

Envelope(errors_field=("errors", "data.*.userErrors"))
One line on the factory, enforced on every call including calls by tools added next year. The full measured record covers both campaigns, including where task success was a wash and the one template that goes the other way.
The rest of the vocabulary
Gloss tells the model what the API's own description leaves out, without replacing
it, which is where a Stripe field that needs a hint gets one. ConflictsWith declares
which parameters an endpoint refuses together. Then
Case, KeyCase, WireName, TransportOverride, partial_of and Pagination.
Coverage
| Pack | Import | Tools | Auth | The awkward part |
|---|---|---|---|---|
| Gmail | charter.packs.gmail |
23 | OAuth bearer | Mail goes out as base64url RFC 2822 and comes back parsed |
| Google Calendar | charter.packs.gcalendar |
13 | OAuth bearer | camelCase in the query, snake_case in the body |
| Google Sheets | charter.packs.gsheets |
17 | OAuth bearer | Cells are protobuf JSON, not plain values |
| Google Docs | charter.packs.gdocs |
3 | OAuth bearer | One batch request, thirty-three alternative edit types |
| Google Drive | charter.packs.gdrive |
25 | OAuth bearer | PATCH takes a subset of the create body |
| Google Forms | charter.packs.gforms |
6 | OAuth bearer | One resource, different fields on create and update |
| Slack | charter.packs.slack |
18 | OAuth bearer | Rejected writes answer HTTP 200 |
| GitHub | charter.packs.github |
139 | OAuth bearer | Three constant headers, one of them a pinned API version |
| Stripe | charter.packs.stripe |
59 | API key | Form-encoded, bracketed query, DELETE with a body |
| Linear | charter.packs.linear |
128 | API key | GraphQL, with the cursor nested inside the response |
| Shopify | charter.packs.shopify |
22 | API key | No fixed host, and every price is a nested MoneyBag |
| Notion | charter.packs.notion |
35 | OAuth bearer | 100 blocks and two levels of children per write |
| Firecrawl | charter.packs.firecrawl |
43 | API key | camelCase wire, and some failures answer HTTP 200 |
| Granola | charter.packs.granola |
9 | API key | Four kinds of actor in one discriminated union |
| Tavily | charter.packs.tavily |
9 | API key | Research is asynchronous: create, then poll |
Every pack has its LLM schema built, its egress map checked against that schema, and its OpenAI function definition validated in the suite.
What Charter is not
Three shapes sit near this one, and none of them is it:
- an orchestrator (LangChain, LangGraph, Google ADK) sits on top of the tool execution layer. It doesn't deal with the underlying request, and isn't designed to;
- a catalogue (Zapier, Composio, Arcade) runs the call for you, remotely, priced per call, and sells on catalogue size. Here you write the pack;
- a protocol (MCP) governs what the model sees and structurally cannot reach the API side, because it never talks to the upstream API.
Charter compiles to MCP and adapts to each of the others. None of them is a library you run yourself that decides what goes out.
Conformance
A declaration can be wrong in a way no per-tool test notices: the call returns 200, the
suite stays green, and the filter you declared was silently discarded on the way out. So
nineteen properties that must hold for every pack are checked separately, without
knowing anything about any particular API, and each one also runs against a pack broken
on purpose in the specific way the bug it guards against broke it. Most were written
after a bug rather than before one: four packs added in a single week produced six, five
of them silent, including a factory-level Pagination that labelled twenty-two retrieve
and write endpoints with a cursor parameter they do not accept. Conformance has the
list.
What none of it tells you is whether a schema still matches the vendor's live API. Catching that drift needs their published spec.
What this can't express
Charter describes one request, and declarative has edges.
Pagination loops, multi-call compositions and retry policies are out of scope by design,
because that is orchestration and it belongs in your agent. Multipart upload, request
signing, header-based pagination markers, dynamic GraphQL selection sets and streaming
are not supported yet. A schema cannot change mid conversation, because it was
serialised into a prompt the model is still reading; a surface that has to change means
a new session. And Mode is schema visibility, not authorization: it decides what a
tool exposes, never who may call it.
Docs
| Start | Quickstart · Installation · Why Charter |
| Packs | Overview · Write one with a coding agent |
| The boundary | Egress control · Mode system · Quick reference |
| The wire | Wire contract · Envelopes · Transforms · Key case |
| Credentials | Getting the grant · Authorization servers · API keys |
| Running it | What a call cost · Adapters and MCP · Errors |
| Guarantees | Conformance · Measured results · Limitations |
| Reference | API reference · AGENTS.md |
Development
uv venv
uv pip install -e ".[dev,langchain,mcp]"
uv run pytest
uv run ruff check src tests examples
uv run pyright --pythonpath .venv/bin/python src
License
Apache 2.0. See LICENSE and NOTICE.
Charter is built by R28.
1 maintainer

Release files for charter-ai 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| charter_ai-0.1.0.tar.gz | 1.0 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| charter_ai-0.1.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.8 MB
Release files / charter_ai-0.1.0.tar.gz
| Download URL | charter_ai-0.1.0.tar.gz |
|---|---|
| Size | 1.0 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
001bda6619b6c84846bf7e4388e29ac64c02169c49f51ac2473af1aa370a168c
|
|
BLAKE2b-256 checksum How to use checksums |
965bed34f04a6737b64ca8bd4be6bf693f312fc752a21ca897bc1647c7bf5d09
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 25, 2026.
Transparency logRelease files / charter_ai-0.1.0-py3-none-any.whl
| Download URL | charter_ai-0.1.0-py3-none-any.whl |
|---|---|
| Size | 804.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
879300caea64de9bb410d92e712687753d50e6ee636cf149ec146b806234752f
|
|
BLAKE2b-256 checksum How to use checksums |
bf3616abbe6d1598a86e662ae0985df6718f0e297e7932730bbd7f62379d9e9f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 25, 2026.
Transparency log












