
CJE: Causal Judge Evaluation
Is the new model, prompt, or agent version better than the current one, and by how much?
CJE answers that from an LLM-judge evaluation without taking the judge at its word. It calibrates the judge against ground-truth labels (human ratings, expert reviews, or observed outcomes) on a random sample of responses, so you label a slice instead of everything.
You get each policy's mean on the label scale and the paired differences between policies, with confidence intervals that include the calibration's uncertainty, plus a plain statement of which claims your data cannot support yet.


Use CJE from your AI agent
Paste this into your coding agent, filling in the brackets:
Install cje-eval in a Python 3.10-3.13 environment: pip install -U "cje-eval>=0.9.2" pandas
(on Python 3.9 a bare `pip install cje-eval` silently installs the legacy 0.5 line).
Run `cje skill` and follow it; when it points to reference.md, run `cje skill --reference`.
If `cje` is unavailable, curl the raw files from
https://raw.githubusercontent.com/cimo-labs/cje/main/skills/cje/ (SKILL.md, reference.md)
rather than a summarizing web fetcher.
Data: [path to the eval export]
Question: [e.g. is candidate better than production on support prompts, and by how much?]
How the labels were chosen: [e.g. 50 random responses per policy rated by our QA team /
escalated tickets only / not sure]
CJE assumes the labels are a random sample. Hand-picked labels (complaints, failures, "interesting" cases) can reverse a comparison without any warning, so the last line is the one to get right. The agent reports each policy's estimate with its CI, the paired differences, and which conclusions are not yet supported, for example a policy with no labels of its own. To install the skill natively, see skills/cje.
What you need
- Each policy's responses to a shared set of prompts. A policy is a model, system prompt, or agent version. Reuse the same
prompt_idacross policies: responses that share it are paired, and treated as one cluster for uncertainty. - One
judge_scoreper response from one fixed LLM judge, with the same rubric for every policy, on any bounded scale (0–1, 0–100, Likert). - Ground-truth labels (
oracle_label) on a randomly sampled subset of responses, on any bounded scale; estimates come back on the label scale. Aim for 20 or more random labels per policy you compare; calibration needs at least 4 labeled prompts and 10 is the practical minimum. Never hand-pick which responses get labeled.
No labels yet? Label a random slice first; sampling at random within judge-score strata covers the score range. Without labels, or with labels on fewer than 4 prompts, CJE returns only the raw judge mean, marked naive_direct / UNCALIBRATED and gate-FLAGGED. To size a budget before collecting, see how many labels a judge saves.
Your own data
import csv
from collections import defaultdict
from cje import analyze_dataset

draws = defaultdict(list)
with open("evals.csv") as f:  # prompt_id, variant, judge_score, human_rating (blank = unlabeled)
    for row in csv.DictReader(f):
        draws[row["variant"]].append({
            "prompt_id": row["prompt_id"],
            "judge_score": float(row["judge_score"]),
            "oracle_label": float(row["human_rating"]) if (row["human_rating"] or "").strip() else None,
        })
results = analyze_dataset(fresh_draws_data=dict(draws))
print(results.summary())
From pandas, df.groupby("variant") into lists of dicts works the same way; a NaN label means unlabeled. Where to put labels across policies, unequal sampling rates (label_design="known_propensity") and more recipes: reference.md: Your own data.
What it estimates
Each estimate targets the policy's mean label over the population your prompts were sampled from, on the label scale. It assumes (1) the labels are a probability sample of the responses they describe, (2) the judge and rubric stay fixed, and (3) for a policy without labels of its own, the reused calibration has zero mean error on its responses (transport). CJE cannot check (1) or (2); it reports (3) as NOT_CHECKED until a held-out audit grades it. Default intervals are analytic, clustered by prompt_id, and include the uncertainty of fitting the calibration on finite labels; bootstrap intervals are opt-in. How calibration, inference and the audits work, and why there is no importance weighting: Methods.
60 seconds
pip install -U "cje-eval>=0.9.2" # Python 3.10–3.13
Each record is one judged response, {"prompt_id", "judge_score", "oracle_label" (optional)}; the API calls these records fresh draws.
from cje import analyze_dataset

# Synthetic data: two policies, production vs candidate, each answered the same
# 20 prompts. A separate fixed judge model scored all 40 responses; human
# raters labeled 10 of production's (None = not labeled).
judge_scores = {
    "production": [0.62, 0.68, 0.72, 0.76, 0.79, 0.83, 0.85, 0.88, 0.91, 0.95,
                0.64, 0.69, 0.73, 0.77, 0.80, 0.84, 0.87, 0.89, 0.92, 0.94],
    "candidate": [0.70, 0.74, 0.75, 0.78, 0.81, 0.83, 0.86, 0.90, 0.93, 0.94,
                0.72, 0.76, 0.79, 0.80, 0.84, 0.85, 0.88, 0.89, 0.91, 0.95],
}
human_labels = [0.55, 0.60, 0.70, 0.74, 0.75, 0.80, 0.90, 0.92, 0.88, 0.97,
                None, None, None, None, None, None, None, None, None, None]

draws = {
    "production": [
        {"prompt_id": f"q{i:02d}", "judge_score": s, "oracle_label": y}
        for i, (s, y) in enumerate(zip(judge_scores["production"], human_labels))
    ],
    "candidate": [
        {"prompt_id": f"q{i:02d}", "judge_score": s}
        for i, s in enumerate(judge_scores["candidate"])
    ],
}
results = analyze_dataset(fresh_draws_data=draws)

# Estimates, then the paired test of candidate vs production on the shared
# prompts (decide from that, not by comparing the two intervals by eye).
print(results.summary())
CJE Estimation Results (method: calibrated_direct)
  candidate   0.824  95% CI [0.766, 0.882]  [borrowed calibration]
  production  0.786  95% CI [0.696, 0.876]
candidate: no labels of its own; its estimate and every difference involving it assume production's calibration transfers, which the CI and p-value do not cover (the true difference can have either sign). Label >=20 random responses of candidate, or audit transport on a held-out random sample of their responses (size it with plan_transport_audits).
Best by point estimate: candidate (point estimate, not a test)
Limitations: borrowed calibration (residual transport NOT_CHECKED)
Paired differences (p unadjusted):
  candidate - production: +0.038  95% CI [-0.027, +0.102]  p=0.22  [borrowed calibration: candidate]
No reliable winner: every paired CI includes 0 (not evidence that they are equal)
Status: warning
Read the paired difference, not the two intervals: its CI includes 0 (p = 0.22), so these 20 synthetic prompts do not show that candidate is better, and Best by point estimate only ranks point estimates. [borrowed calibration] marks candidate: it has no labels of its own, so it uses production's calibration (analyze_dataset also logs a WARNING). Its interval covers prompt sampling and calibration-fit error but not the chance that the calibration is off for candidate's responses, which is why it is narrower than production's. A paired CI that excluded 0 would not settle this comparison either; the summary would say No decision-ready winner. Labeling a random slice of candidate's own responses removes that reliance, and a held-out transport audit grades it. For the same test as a dict, use results.compare_policies("candidate", "production") (difference is the first minus the second; conditional_on_transport is True here).
→ Colab tutorial on Chatbot Arena prompts (GPT-5 labels stand in for human ratings) · API reference
Guardrails: claims CJE refuses to make
Every estimate ships with its limitations attached: a REFUSE-LEVEL badge when a policy's judge scores fall outside the labeled range, an opt-in held-out transport audit for reused calibration (PASS, FAIL, INCONCLUSIVE, NOT_GRADED, or NOT_CHECKED without probes), and a best_policy() that never silently crowns a gate-flagged policy. What each state means and how to clear it: diagnostics README.
Is CJE the right tool?
| Your situation | Use |
|---|---|
| Compare policies scored by an LLM judge, with random ground-truth labels | CJE |
| Estimate a new model or prompt before shipping it (ahead of, not instead of, an A/B test) | CJE on its responses to prompts sampled from real traffic, labeled offline. It measures offline quality, not online effects |
| Evaluate many policies without labeling each | CJE: labels pool across policies; audit that reuse with held-out probes. With only a few policies, label a random slice of each (your own data) |
| One sample, want a CI on its mean | calibrated_mean_ci (array API) |
| No ground-truth labels yet | Label a random slice first |
| Predict how a specific response will score | Per-item prediction (e.g. conformal methods) |
| Reweight another policy's logged responses (importance sampling or doubly robust OPE) | The frozen cje-eval==0.3.* line (why) |
The array API
calibrated_mean_ci is the bottom layer: a ppi_py-style primitive that takes NumPy arrays for one sample (judge scores on any bounded scale; labels in [0, 1] on an equal-probability random slice, NaN elsewhere) and returns a calibrated mean and confidence interval. It has no weights argument, so use analyze_dataset for stratified labels and for comparing policies. Signature, inference and calibrator reuse →
Evidence
- HealthBench Consensus (29,511 response–criterion records, physician grades). In a custom confidence-augmented regrade, judges were overconfident by 24.5 (gpt-4o-mini) and 13.0 (Claude Haiku 4.5) percentage points against strict positive physician majority. In one seeded retrospective replay that exposed 5% of the aggregate labels, calibrated estimates were within 1.4–2.1 points of the full aggregate endpoint; this was not prospective annotation or repeated-split validation. Audit →
- Chatbot Arena (4,961 prompts, 5 policies; GPT-5 ratings stand in for human labels, so this is a model-reference study, not human validation). With 5% of the base policy's responses labeled, policy pairs were ranked correctly 99% of the time in the headline configuration (92% averaged across configurations at the
analyze_datasetdefault, 94% with a response-length covariate). The arXiv v3 cost model puts this at 14× lower total cost (oracle labels plus judge calls) than labeling every response: 8.8× for one policy, 14× when one calibration is reused for all five, assuming it transfers to the others; it does not for the deliberately unhelpful policy, which the transport audit flags. Nominal 95% intervals on raw judge means covered the reference mean 0% of the time; CJE's default intervals covered about 95% (93.9% Direct, 95.6% with the covariate, across 25 sample-size and label-fraction settings × 50 seeds) in a corrected rerun. Paper →
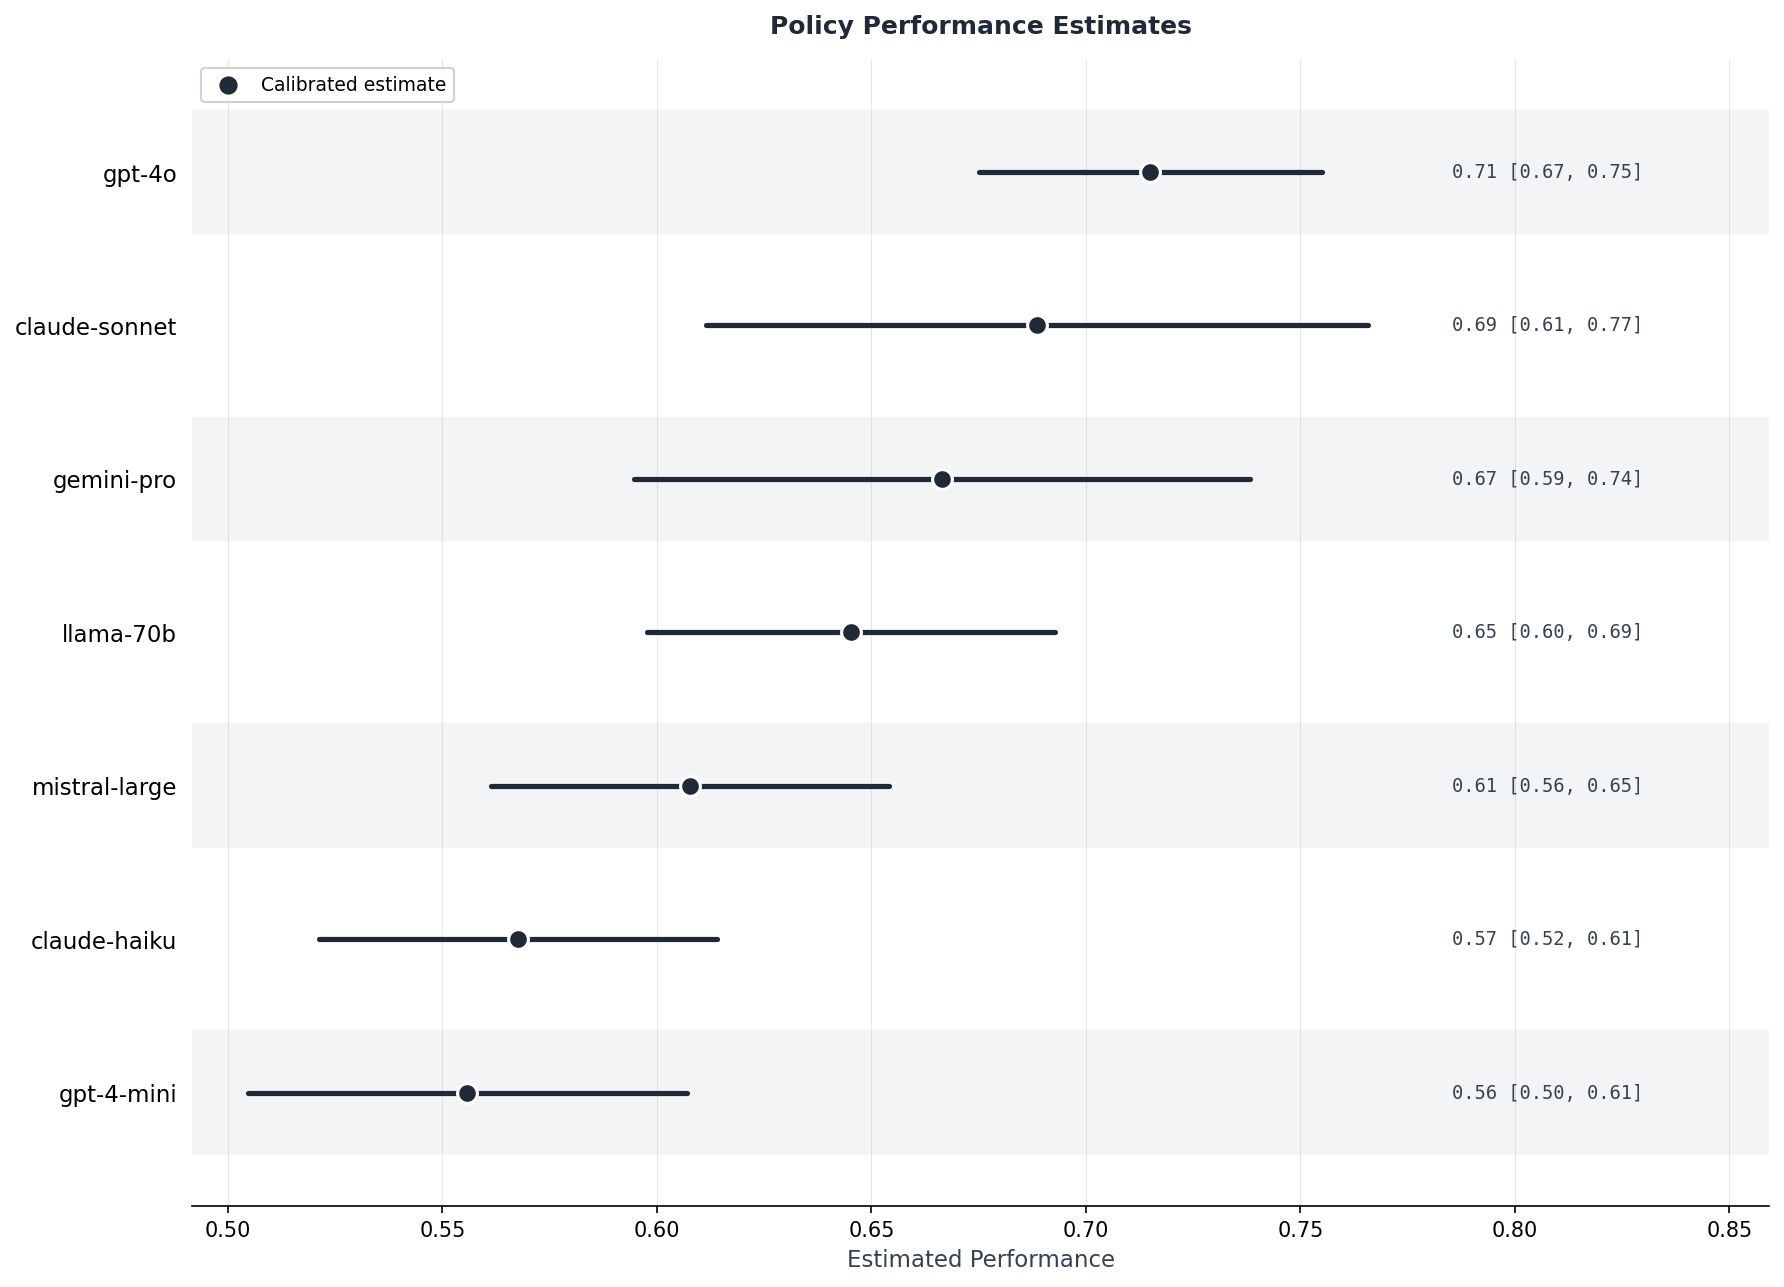
The Chatbot Arena sample in
examples/arena_sample (GPT-5 labels stand in for human ratings). The calibration is fit on base-policy labels; diamonds are mean labels on 50 held-out responses per policy (for base, on its own labels). The calibration overstates the deliberately unhelpful policy, and its transport audit fails. Made by scripts/make_readme_forest_plot.py.
Full numbers and caveats: Methods: validation.
Documentation
- Agent skill:
cje skill, or skills/cje: the procedure and hard rules for coding agents. - API reference:
analyze_dataset(),EstimationResult, thecjeCLI. - Guides: how many labels a judge saves · planning a transport audit · from audit to correction · operational playbook · migrating from 0.5.x
- Notebooks: tutorial · planning a label budget (from judge quality and per-call costs, no data needed)
- Module deep dives: calibration · diagnostics · estimators and methods · data formats
- Bridges: Langfuse experiments (keeps response identity and label provenance) · Promptfoo, TruLens, LangSmith, OpenCompass
- Videos: CJE in 3 minutes · technical walkthrough
- Paper: arXiv 2512.11150
- Upgrading: read the CHANGELOG first; two-stage calibrators saved before 0.8.0 need refitting from retained inputs.
- Development:
git clone https://github.com/cimo-labs/cje.git && cd cje && poetry install && make test
Citation
If you use CJE in your research, please cite:
@misc{landesberg2025causaljudgeevaluationcalibrated,
  title={Causal Judge Evaluation: Calibrated Surrogate Metrics for LLM Systems},
  author={Eddie Landesberg and Manjari Narayan},
  year={2025},
  eprint={2512.11150},
  archivePrefix={arXiv},
  primaryClass={stat.ME},
  url={https://arxiv.org/abs/2512.11150},
}
License
MIT. See LICENSE for details.
1 maintainer

Metadata
1 maintainer
Release files for cje-eval 0.9.4
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| cje_eval-0.9.4.tar.gz | 283.3 kB | With provenance | Details for cje_eval-0.9.4.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| cje_eval-0.9.4-py3-none-any.whl | Python 3 | none | any | Details for cje_eval-0.9.4-py3-none-any.whl |
Total release size: 588.7 kB
Release files / cje_eval-0.9.4.tar.gz
| Download URL | cje_eval-0.9.4.tar.gz |
|---|---|
| Size | 283.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
7d6c7d1d150456a0e17feb1d1f785f44d94c89acc06ede6391f7de5fb1459e31
|
|
BLAKE2b-256 checksum How to use checksums |
aa2036851bce5593778520e791aacfa0fecc1652c8e437d21610f7e63c616a6d
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 3, 2026.
Transparency logRelease files / cje_eval-0.9.4-py3-none-any.whl
| Download URL | cje_eval-0.9.4-py3-none-any.whl |
|---|---|
| Size | 305.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
662e6d28c6e11f588a9a4bad7d63fec0c37857187c8641bd739cbb7e90136868
|
|
BLAKE2b-256 checksum How to use checksums |
918db8fda63785dcdfe224fc3469661f227139301c055e7761e3f28d224b6be3
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 3, 2026.
Transparency logSecurity for cje-eval 0.9.4
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
Both files in this release have been uploaded with provenance metadata.
Attestation for cje_eval-0.9.4.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 3, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














