
ckpt-chaos


Crash-consistency testing for ML training checkpoints.
ckpt-chaos kills a training job at every file boundary of a checkpoint save, resumes it, and tells you what came back: a clean resume, a crash that needs manual cleanup, a silent resume with different weights, or lost work. It works on your own unmodified training script (any framework, or none), needs only the Python standard library for that, and exits non-zero on a failure so it can gate CI.
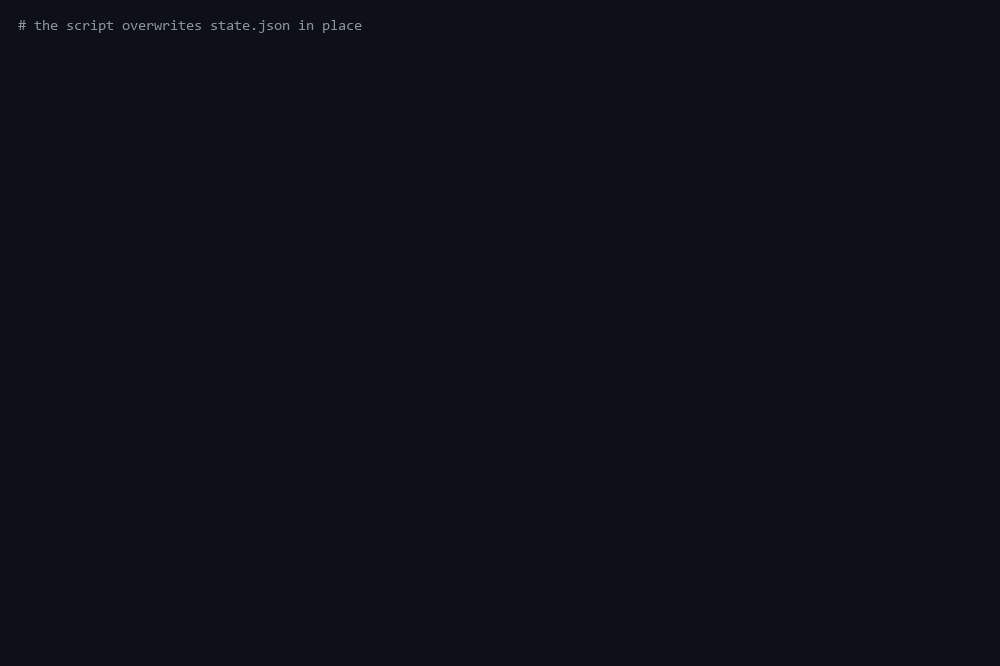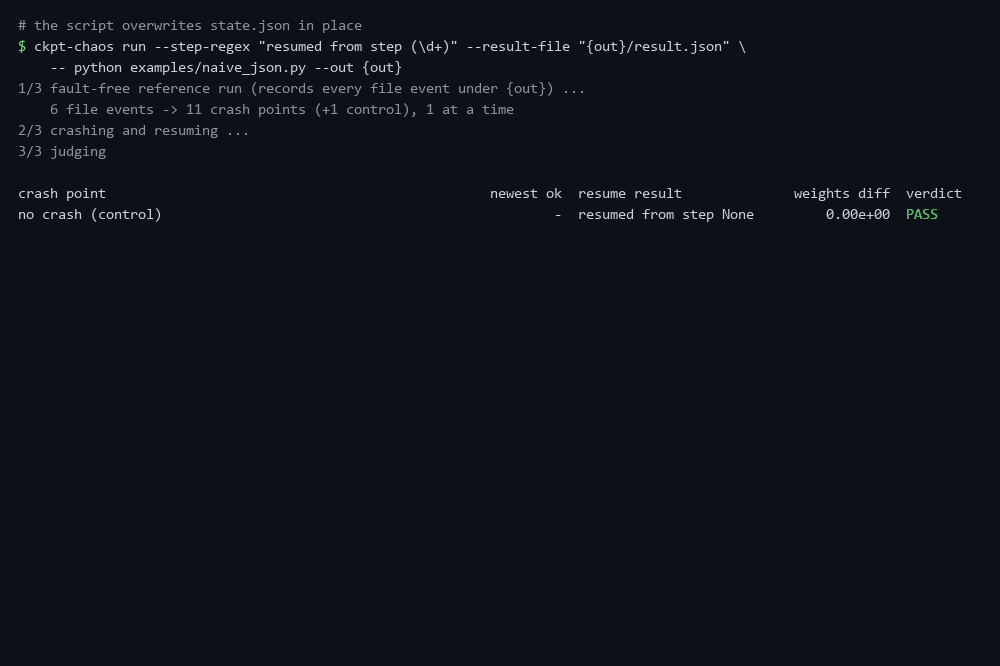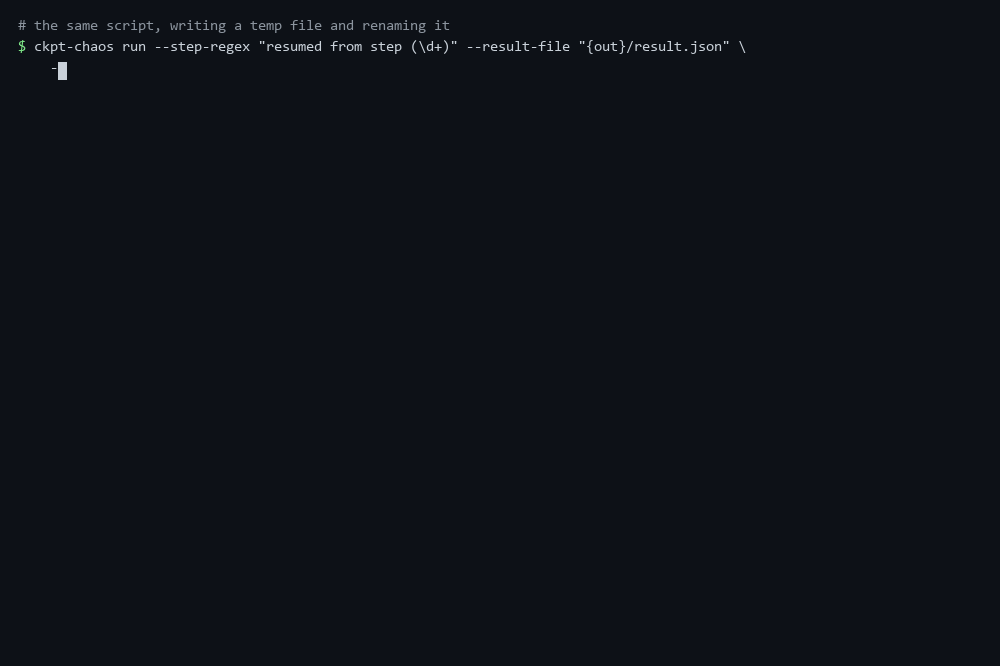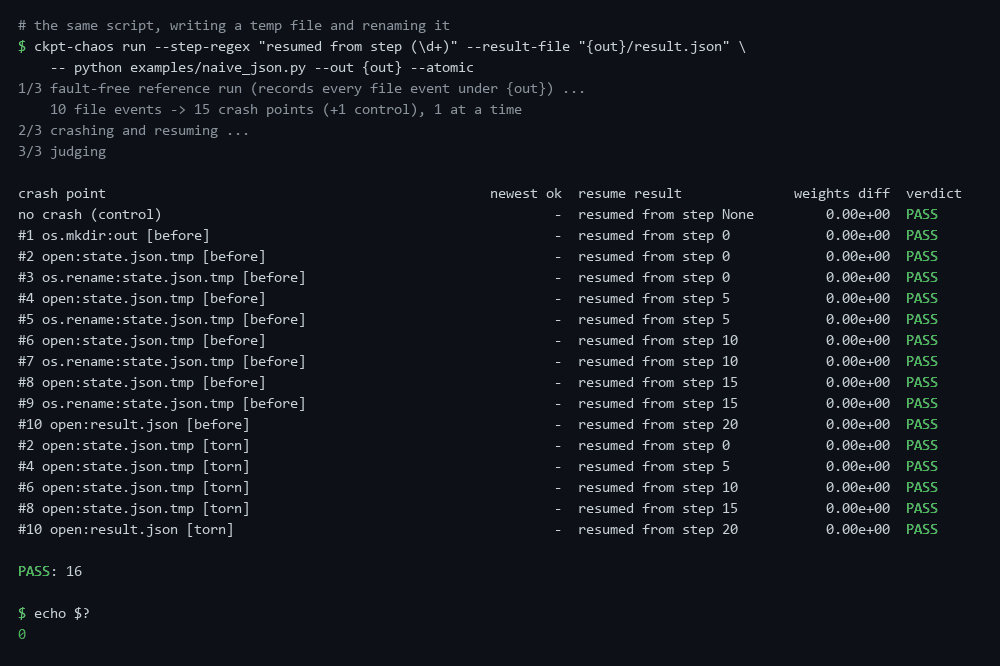
A real run: the output was recorded and the waiting time shortened. The script that overwrites its checkpoint in place fails 4 kill points and exits 1; the same script writing a temp file and renaming it passes all 16 and exits 0. How the GIF is made.
Why
Most training stacks treat "checkpoint-N/ exists" as "checkpoint N is complete". A kill in the middle of
a save leaves a folder that looks valid and is not.
- Hugging Face: #35525 (open) asks for a fallback to the previous checkpoint when the latest is broken.
- Hugging Face merged an atomic temp-directory save (#35580), it broke multi-GPU DDP saves (#36076), and it was reverted (#36112).
- Lightning: #21431 (open), corrupt checkpoint saves.
It builds on the single-node, single-filesystem study Crash-Consistent Checkpointing for AI Training on macOS/APFS, whose stated limits (one filesystem, one node, a synthetic workload) are this tool's starting points.
Try it on your own script
pip install ckpt-chaos

# put {out} where your command takes its output / checkpoint directory
ckpt-chaos run --step-regex "resumed from step (\d+)" --result-file "{out}/final.pt" \
    -- python train.py --output_dir {out}
It runs your command once fault-free to record every file it creates, renames or removes under {out},
then kills a fresh copy at each of those events (and, for files written by torch.save, safetensors or
Python's open(), a second copy with the file cut in half). Each time it runs your resume command
(--resume-cmd, default: the same command) and compares what came back with the fault-free run.
It only ever writes inside {out} directories it creates itself, and exits 1 on HARD_FAIL,
SILENT_DIVERGENCE or a failing control (--fail-on changes that).
Two ordinary scripts are included, with no changes to either:
| Command | Result |
|---|---|
ckpt-chaos run ... -- python examples/naive_torch.py --out {out} (saves with torch.save over the old file) |
6 HARD_FAIL, 10 PASS, exit 1: a torn write at any checkpoint destroys the only copy |
ckpt-chaos run ... -- python examples/naive_torch.py --out {out} --atomic (temp file + os.replace) |
22 / 22 PASS, exit 0 |
examples/naive_json.py, no torch, JSON checkpoints |
same split; covered by tests/test_byo.py |
Options worth knowing: --result-cmd (compare with a tolerance), --max-points (sample long runs),
--jobs (keep 1 on a shared GPU), --timeout. If two fault-free runs of your command already differ
(unseeded training), the report says so, because divergence verdicts mean nothing then.
Without --checkpoint-glob, run mode cannot tell which checkpoints were complete, so it does not report
LOST_WORK or the "newest ok" column.
Resume contract: did it use the checkpoint that was there?
ckpt-chaos run --checkpoint-glob "{out}/ckpt-*" --step-regex "resumed from step (\d+)" \
    --result-file "{out}/final.pt" --fail-on HARD_FAIL,SILENT_DIVERGENCE,LOST_WORK \
    -- python train.py --output_dir {out}
The fault-free run records what each matching checkpoint is made of (its files and their sizes; the step is
the last number in its name). After each crash, a checkpoint that matches its fault-free twin is complete,
and the resume must start from the newest one. Starting from an older step, or from scratch, is
LOST_WORK, even when nothing raises and the final result is identical. That is the shape of verl #7952,
where the async save never writes its marker and the resume silently starts over.
examples/rotating_json.py --bug reproduces it: 11 of 16 points are LOST_WORK ("newest ok 20, resumed
from step 0"), every one with exit code 0 from the job itself.
--step-regexis required, and a resume that prints no step counts as step 0 (the run warns when the regex never matches).--ckpt-ignore-sizecompares names only, for checkpoints whose size varies between runs. It cannot see torn files.- Checkpoints the fault-free run deletes itself (keep-last-N rotation) are not tracked: keep all of them for this test.
LOST_WORKis reported but does not fail the run unless you add it to--fail-on.- Checked so far on the stdlib examples only, not yet on a real framework's resume.
Turn a failure into an issue
ckpt-chaos repro ckpt-chaos-runs/<timestamp>     # writes repro/<verdict>-<step>-<mode>/ for up to 3 failing points
cp ckpt-chaos-runs/<timestamp>/repro/lost_work-004-before/repro.py .   # from your project root
python repro.py
Each folder has a repro.py that rebuilds the failure on its own (fault-free run, kill at the same file event, resume,
verdict; repeated 3 times) and an ISSUE.md draft with the expected and observed behaviour, versions, and the end of the
resume output with local paths removed. Paste the output of repro.py into the draft before filing. The script imports
ckpt-chaos internals, so run it with the same ckpt-chaos version as the run (the draft pins it).
Use it in CI (GitHub Action)
- uses: actions/checkout@v4
- uses: actions/setup-python@v5
  with: { python-version: "3.12" }
- run: pip install -r requirements.txt      # your training dependencies
- uses: rkb32/ckpt-chaos@v0.1.3
  with:
    command: python train.py --output_dir {out}
    checkpoint-glob: "{out}/ckpt-*"
    step-regex: 'resumed from step (\d+)'
    result-file: "{out}/final.pt"
    fail-on: HARD_FAIL,SILENT_DIVERGENCE,LOST_WORK
The job fails if any crash point breaks the resume, and the run page gets a summary: verdict counts, a table
of the failing crash points (with the newest complete checkpoint and the step the resume actually used), the
full table in a collapsible block, and the command to reproduce it locally. The inputs are the run options
(resume-command, result-cmd, max-points, jobs, timeout, ckpt-ignore-size); package picks the pip
requirement and python-version runs setup-python for you. Each crash point's result.json and event log are
uploaded as an artifact (upload-results: false turns that off; set artifact-name when you use a matrix, since
artifact names must be unique per run). Outside Actions, ckpt-chaos run --summary FILE appends the same Markdown.
On a CI machine your training command runs once per crash point, so use a small config (a few steps, a tiny
model) and max-points to bound the time. The action writes only inside its own work directory under runner.temp.
The built-in targets
ckpt-chaos bench hf_trainer                       # HF Trainer, single process (needs torch, transformers, accelerate)
ckpt-chaos bench hf_trainer --ranks 2             # two gloo ranks
ckpt-chaos bench lightning_trainer --ranks 2      # needs lightning
ckpt-chaos bench loop_ddp --ranks 2 --strategy tmp_rename --flake 25   # repeat the fault-free job, count failures
ckpt-chaos judge runs/<dir>                       # re-apply the verdict rules to a finished run
Tests: python -m unittest discover tests.
How it works
- A dry run counts the file events of one checkpoint save (
inject.py): CPython audit events for open/rename/remove/mkdir, plus wrappers for the native writerstorch.saveand safetensors, which raise no audit events. - For every event, one run dies there (
before: the file never appears). For native writers a second run dies with the filetorn(cut to half its size). With several ranks, every rank is a crash candidate. - The job is resumed with the library's own auto-resume, and the final weights are compared with an uninterrupted run of the same schedule.
invariants.pyturns each outcome into a verdict.
| Verdict | Meaning |
|---|---|
PASS |
resumed, weights identical to the uninterrupted run |
HARD_FAIL |
resume raised; the job is down until someone cleans up |
SILENT_DIVERGENCE |
resumed, but weights differ or ranks disagree |
LOST_WORK |
resumed correctly from an older checkpoint than necessary |
Results
Setup: transformers 5.18.0 (tiny GPT-2, resume_from_checkpoint=True) and Lightning 2.6.6 (tiny MLP,
fit(ckpt_path="last")), torch 2.14.1 (CPU), Windows/NTFS. The job is killed while the step-10 checkpoint is
being saved (the step-5 checkpoint already exists).
| Setup | Runs | PASS | HARD_FAIL | SILENT_DIVERGENCE | LOST_WORK |
|---|---|---|---|---|---|
| HF Trainer 5.18.0, 1 process | 19 | 2 | 17 | 0 | 0 |
| HF Trainer 5.18.0, 2 gloo ranks | 22 | 1 | 19 | 2 | 0 |
| Lightning 2.6.6, 1 process | 5 | 3 | 0 | 0 | 2 |
| Lightning 2.6.6, 2 gloo ranks | 5 | 3 | 0 | 0 | 2 |
Each run is one crash point; the control run has no crash and a clean one counts as a PASS.
- An intact resume is bit-identical to an uninterrupted run (max weight diff 0.0), with 1 and with 2 ranks, so any difference below is caused by the crash.
- The 17 + 19 hard failures are one root cause, not 36 bugs. Auto-resume picks the highest-numbered
checkpoint-Nfolder without checking that it is complete, andtrainer_state.jsonis written last, so a kill at any earlier point leaves a folder that makes the resume raise (FileNotFoundError,ValueError,SafetensorError) until someone deletes it by hand. This is the behaviour behind #35525. - Multi-rank only: divergence without an error. If rank 1 dies before writing
rng_state_1.pth, rank 0 finishes the checkpoint andtrainer_state.json. The resume then succeeds from that folder and ends with weights 1.65e-4 away from the uninterrupted run. The model and optimizer are intact; exact reproducibility is lost. A single process cannot produce this state. This is documented behaviour, not a hidden one: Hugging Face logs "Didn't find an RNG file for process 1 ... reproducibility is not guaranteed", but at INFO level, so it is invisible at the default log level (and the harness runs withTRANSFORMERS_VERBOSITY=error). It is reported here because nothing stops the job or says so by default. - Lightning is atomic per file, and the matrix shows it.
_atomic_savewrites each checkpoint to a temp file in the system temp directory inside an fsspec transaction, then renames it into place, so no crash point leaves a broken checkpoint, with 1 or 2 ranks. The two LOST_WORK rows are a crash between installingck-step=10.ckptand updatinglast.ckpt:ckpt_path="last"then resumes from step 5 although a complete step-10 checkpoint exists. That redoes 5 steps and corrupts nothing. Because the temp file lives outside the watched folder, torn writes cannot reach it and are not exercised. - One crash point is clean with a single process (HF): dying before the folder exists. With 2 ranks even that fails, because the surviving rank creates the folder (this depends on the few seconds the survivors run on, see Limits).
Save protocols compared
loop_ddp is a small hand-written DDP loop with three ways of installing a checkpoint, run with 2 gloo
ranks. It shows the harness can say PASS, and that it can find a protocol that is broken only sometimes.
| Strategy | What it does | Crash matrix | Fault-free repeat (--flake 25) |
|---|---|---|---|
direct |
write straight into checkpoint-N/, state file last |
1 PASS, 11 HARD_FAIL | not run |
tmp_rename_rank0 |
write checkpoint-N.tmp/, barrier, rank 0 renames, barrier |
13 / 13 PASS | 0 / 25 failed |
tmp_rename |
write checkpoint-N.tmp/, barrier, every rank renames |
13 PASS, 1 HARD_FAIL | 2 / 25 failed |
tmp_renameis the shape of the temp-directory fix Hugging Face merged and reverted (#35580 / #36076): every rank tries to move the same shared directory. Here the loser getsFileNotFoundErroroncheckpoint-N.tmp -> checkpoint-N. It passed 23 of 25 fault-free runs and its control row passed, so a single run would have missed it. That is why--flake Nexists.- The failing crash-matrix row for
tmp_renameis not a recovery failure: rank 1 lost the same race during a later save after the resume. It is reported honestly as what happened, with a cause unrelated to the injected crash. - Not claimed: that Hugging Face's code failed in exactly this way. #36076 was reported on Linux with a different error ("Directory not empty"); the Windows race gives the same class of failure, not the same bug.
Reproduce the Hugging Face results
pip install torch transformers accelerate
ckpt-chaos bench hf_trainer                  # 1 process: 17 HARD_FAIL, 1 PASS (plus a passing control)
ckpt-chaos bench hf_trainer --ranks 2        # 2 ranks: 19 HARD_FAIL, 2 SILENT_DIVERGENCE
# the same, but get_last_checkpoint skips a folder whose trainer_state.json is missing or unparseable:
CKPT_CHAOS_PATCH=skip_incomplete ckpt-chaos bench hf_trainer             # 1 process: 19 of 19 PASS
CKPT_CHAOS_PATCH=skip_incomplete ckpt-chaos bench hf_trainer --ranks 2   # 19 PASS, 2 SILENT_DIVERGENCE, 1 HARD_FAIL
To test any other change to a library without touching the installed copy, copy its package to a folder,
edit the copy, and run with CKPT_CHAOS_PREPEND_PYTHONPATH=<that folder>. That is how the open pull request
#39599 (continue resuming when trainer_state.json
is missing) was tested: the same single-process matrix gave 9 HARD_FAIL, 8 SILENT_DIVERGENCE and 2 PASS,
because the resumed run restarts at step 0 on the weights of the incomplete folder.
Filesystem roundtrip (no crash involved)
ckpt-chaos roundtrip --dir DIR --n 200 --writer torch|lightning saves a checkpoint, loads it straight back,
and repeats, for reports like Lightning #21431
(a save that is sometimes unreadable right after writing, in Docker on Windows/WSL). With the included
Dockerfile on Docker Desktop for Windows, 8 MB checkpoints, one file overwritten each time:
| Filesystem | torch.save, 200 saves |
Lightning save_checkpoint, 100 saves |
|---|---|---|
| container overlayfs | 0 unreadable | 0 unreadable |
| Docker volume (ext4 in the VM) | 0 | 0 |
| bind mount of a Windows folder | 0 | 0 |
| tmpfs (control) | 0 | 0 |
The Windows host itself (NTFS) gave 0 of 100 (torch) and 0 of 40 (Lightning). #21431 did not reproduce. The reporter's model size, versions and hardware differ from mine, so this does not show the report is wrong; it shows these four setups do not trigger it.
Limits
- Crashes are emulated by killing the process (
os._exit) at a file event. That is not power loss: data the OS had not flushed is not lost, and writes are not reordered. Real power-loss testing needs kernel level injection or hardware. - Torn writes cover
torch.save, safetensors and Python'sopen()(inrunmode). Writers that call C code directly, such as h5py (Keras.h5) or tensorstore (Orbax), are only crashed before or after, not torn. - The
benchtargets tear onlytorch.saveand safetensors, so their matrices keep the numbers above. - After one rank dies, the others run on for a few seconds before they are stopped, which is realistic but timing dependent.
- Tested so far: transformers 5.18.0 and Lightning 2.6.6 on Windows/NTFS with CPU gloo ranks. The
hand-written loop also only on Windows. The crash matrices are single runs per crash point; only the
fault-free runs have been repeated (
--flake).
Roadmap
See ROADMAP.md: the features ranked by the evidence behind them (what developers actually report in GitHub issues and papers), what is done, and what is not verified.
1 maintainer

Metadata
1 maintainer
Release files for ckpt-chaos 0.1.4
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| ckpt_chaos-0.1.4.tar.gz | 57.3 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| ckpt_chaos-0.1.4-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 108.4 kB
Release files / ckpt_chaos-0.1.4.tar.gz
| Download URL | ckpt_chaos-0.1.4.tar.gz |
|---|---|
| Size | 57.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
08451e2add60fb7a91412e6e784509c866d6a0c900dbda9f842c4bb28622aa03
|
|
BLAKE2b-256 checksum How to use checksums |
4ec9450308f31410032ae2d250139c1f6bb1928bb1ba2365a5d533c62dcb0d6b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 11, 2026.
Transparency logRelease files / ckpt_chaos-0.1.4-py3-none-any.whl
| Download URL | ckpt_chaos-0.1.4-py3-none-any.whl |
|---|---|
| Size | 51.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
cf8a0448bf017146211cc408f76944d7349b7b2aff7306c1dd5082f272c024fd
|
|
BLAKE2b-256 checksum How to use checksums |
98263b12042c5a9db0eb45c6ff4dfe8884ef464c5d7bb4c67cec316cfa7acd60
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 11, 2026.
Transparency log













