
claude-context-cost


How much each source (your CLAUDE.md, rules, skills, memory, tool results)
costs in the context of a Claude Code session, counted from the API usage
recorded in its transcript, not estimated from characters. For Claude Code
users who want to know what fills their context.
Try it in a minute:
pip install claude-context-cost
claude-context-cost --example
Or try it in the browser: choose one of your transcripts, or run the synthetic example. The library runs in the page (Pyodide); your file is never uploaded.
Reads only the transcripts under
~/.claude/projectson your machine. Nothing is sent anywhere. The numbers are tokens, not dollars.
The usual shortcut, characters ÷ 4, counts 40 to 45% too few tokens (−45% in the author's sessions, mostly in Portuguese; −40% in one in English). Here the sources of every response add up exactly to the token total the API recorded, checked in 457 transcripts.
Also: --budget
fails a pull request or a commit that makes a CLAUDE.md, a rule or an
import grow over the limit you set, and
--versions
shows which git commit of each CLAUDE.md, rule and memory file a session
loaded.
Install
pip install claude-context-cost
Python 3.11 or newer, no dependencies. To install a tagged version straight from GitHub instead:
pip install "git+https://github.com/peterwkdev-creator/claude-context-cost@v1.6.3"
Usage
claude-context-cost --example
claude-context-cost ~/.claude/projects/<project-folder>/<session-id>.jsonl
The newest .jsonl in a project's folder is its latest session (on Windows,
~ is %USERPROFILE%). A subagent has its own transcript,
<session-id>/subagents/agent-<id>.jsonl.
Pass a project's folder instead of a file to sum its sessions and their
subagents: the costliest sources first, then one line per session. Pass
~/.claude/projects itself to sum every project. Tools and your own
~/.claude/... files add up across projects; a project's CLAUDE.md and
rules stay apart, marked with the project.
--steps shows what entered before each response, --all lists every
source, --json is for scripts (for a folder too). On the synthetic example
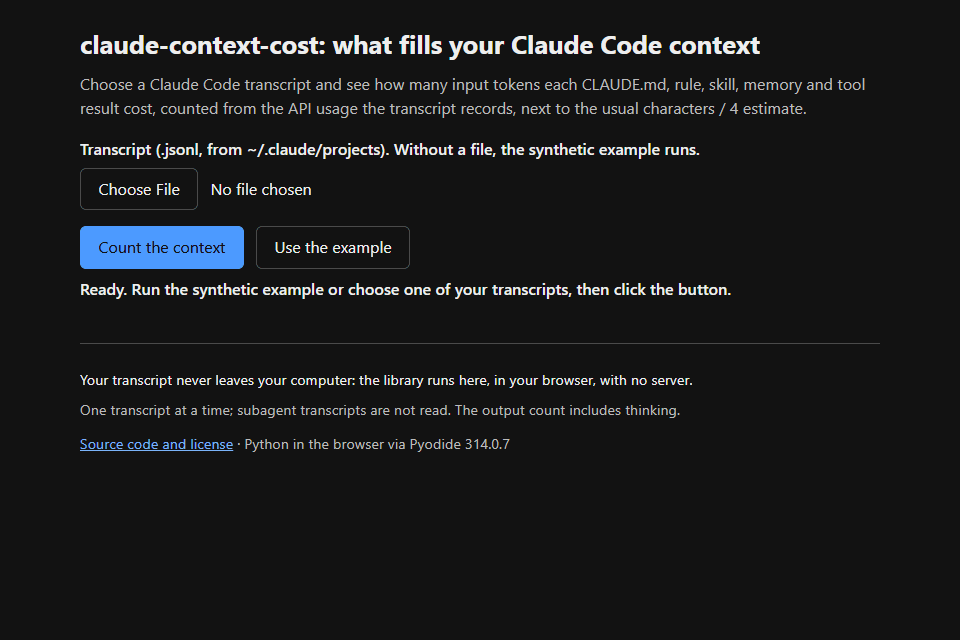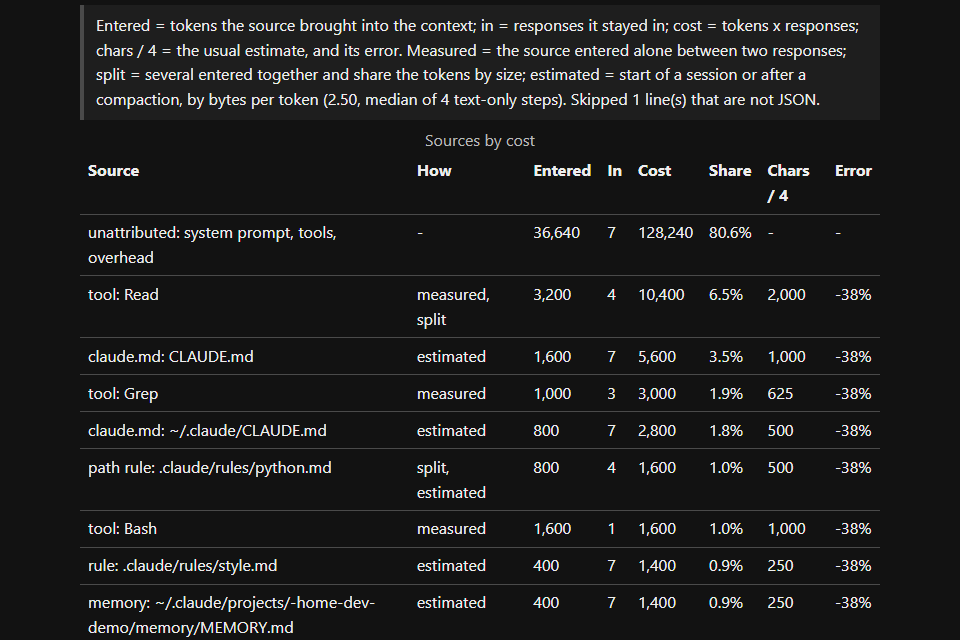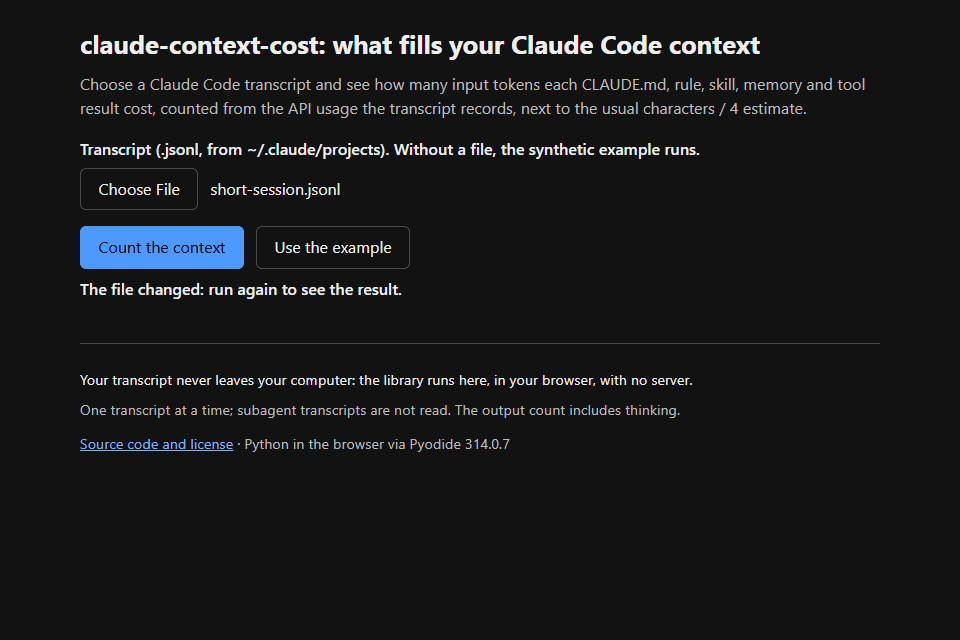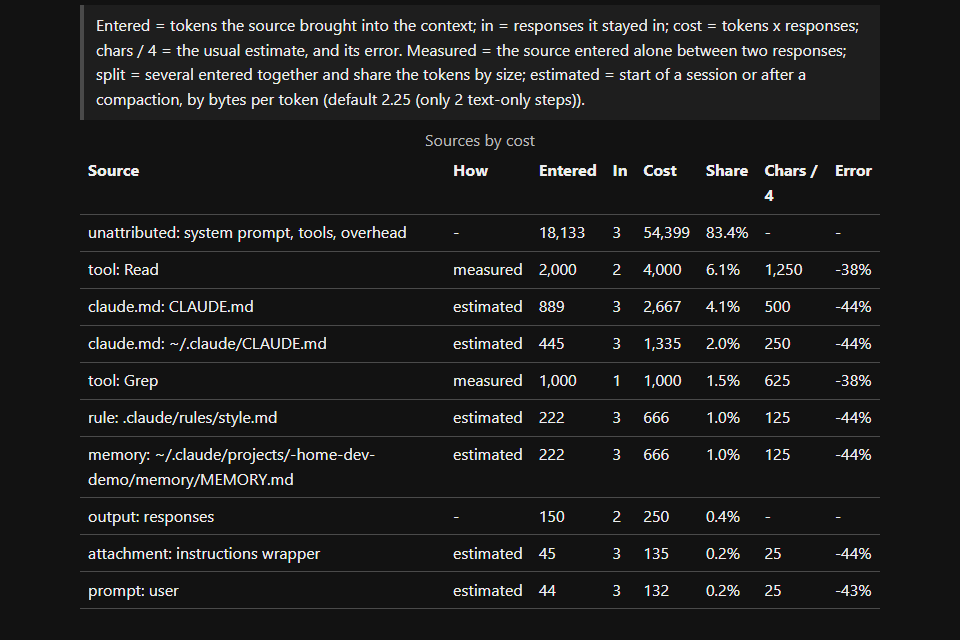
shipped with the package (some rows left out):
        cost  share   entered    in    chars/4  error  how                  source
     128,240  80.6%    36,640     7          -      -  -                    unattributed: system prompt, tools, overhead
      10,400   6.5%     3,200     4      2,000   -38%  measured, split      tool: Read
       5,600   3.5%     1,600     7      1,000   -38%  estimated            claude.md: CLAUDE.md
       ...
       1,600   1.0%       800     4        500   -38%  split, estimated     path rule: .claude/rules/python.md
- cost: tokens × the responses the source stayed in context, until a compaction removed it. This is what you pay for over the session. share: its part of all the input tokens.
- entered: the tokens it brought in; in: the responses it stayed in (for a folder, the transcripts it was in).
- chars/4 and error: what the usual estimate would say, beside it;
-38%means it would count 38% too few. - how:
measured(alone between two responses, so the usage gives its exact tokens),split(shared with others, in proportion to bytes) orestimated(at the start or after a compaction); rarelyunknown(no text to weigh, as an image) orshrank(the context got smaller); see What it counts. - source, by kind:
claude.md,rule(always loaded),path rule(a rule withpaths:, loaded on demand),memory,skill,tool(its results),prompt(your messages),output(Claude's earlier answers, which the next request sends back),summary(a compaction's summary),attachment(the text Claude Code wraps around them) andunattributed(Claude Code's own system prompt and tool definitions: not from your files, usually the largest row; fewer MCP servers make it smaller).
From Python:
from claude_context_cost import analyze, example_path

report = analyze(example_path())  # or the path of any .jsonl transcript
print(report.total)  # 159160: input tokens summed over the 7 responses
read = report.sources[("tool", "Read")]
print(read.entered, read.responses, read.cost)  # 3200 4 10400
print(read.estimate_div4)  # 2000.0: characters / 4 for the same text
summarize(folder) returns the same sum as a folder on the command line:
.sources maps (kind, name, project) to the totals, with project set only
for a project's own files.
Which version a session loaded
A transcript keeps the text of every CLAUDE.md, rule and memory file as it
was loaded, and the counts above use that text. --versions finds it in git:
claude-context-cost --versions ~/.claude/projects/<project-folder>/<session-id>.jsonl
CLAUDE.md, rules and memory as this session loaded them: their git version, and today's file

   tokens  loads  version                         today           file
      337      1  no git                          same            claude.md: ~/.claude/CLAUDE.md
      871      1  1c3456f 2026-10-05              +289 tokens     claude.md: CLAUDE.md
      248      1  not committed                   same            rule: .claude/rules/style.md
      160      1  5c41635 2026-10-08 (later)      same            rule: .claude/rules/tests.md
      680      2  e8e382b 2026-10-01              not found       path rule: .claude/rules/api.md

tokens: of one load; loads: how many times the session loaded this text
version: the commit with exactly this text; (later): committed only after it was loaded
  not committed: no commit has this text; no git: the file is not in a git repository
today: the file on disk now, as Claude Code would load it: same, +N or -N tokens (grew or shrank since), changed, or not found
- tokens are of one load; loads is how many times the session loaded
that same text (again after each compaction, for example). The main table's
enteredadds up every load. - version is the newest commit made before the load whose file, as
Claude Code loads it (frontmatter and HTML comments removed), is exactly
the loaded text (line endings aside). If the text was committed only
afterwards, it is the first such commit, marked
(later). - today compares the file on disk now:
+289 tokensmeans it grew by that much since the session loaded it. - Git is only read (
git log,git cat-file), never written.--jsonadds the list under"versions"(the top-level"version"is the tool's own); from Python,loaded_versions(transcript).
Context budget in CI
There is no transcript in CI, so --budget measures the repository itself:
every CLAUDE.md, rule and @import Claude Code would load from it, as
Claude Code loads them (frontmatter and HTML comment blocks removed), held to
the limits you declare. It exits with 1 when a limit is exceeded, so a pull
request that bloats the context fails.
# context-budget.toml, at the root of the repository
startup = 3000                  # everything loaded when a session starts

[limits]                        # per file; a file is held to every pattern that matches it
"CLAUDE.md" = 2000
".claude/rules/*.md" = 1500     # * stays in one folder, **/ is any number of folders
"**/CLAUDE.md" = 2000
claude-context-cost --budget context-budget.toml
It measures the current folder; give another after the budget file
(--budget context-budget.toml path/to/repo). A relative path to the budget
file starts from the current folder, not from the repository.
context budget of my-repo: 5 instruction files, 2.25 bytes per token (default)

   tokens     limit  loaded     file
      622     1,500  start-up   rule: .claude/rules/style.md
    1,705     2,000  start-up   claude.md: CLAUDE.md
    1,066         -  start-up   claude.md: docs/architecture.md (imported by CLAUDE.md)
    1,813     1,500  on demand  path rule: .claude/rules/api.md  OVER
      427     2,000  on demand  claude.md: web/CLAUDE.md
    3,393     3,000  start-up total  OVER

not counted, as not in the repository: your ~/.claude/CLAUDE.md, memory and any CLAUDE.md above it

over budget: 2 limits exceeded
  path rule: .claude/rules/api.md: 1,813 tokens > 1,500 (limit ".claude/rules/*.md")
  start-up total: 3,393 tokens > 3,000 (limit startup)
- Start-up:
CLAUDE.md,.claude/CLAUDE.md,CLAUDE.local.md, rules in.claude/rules/withoutpaths:, and what they import. On demand: rules withpaths:and theCLAUDE.mdof a subfolder, with their imports. Hidden folders andnode_modulesare skipped. Your own~/.claude/CLAUDE.md, your memory (MEMORY.md) and anyCLAUDE.mdabove the repository are not in it, so they are not counted, though a session loads them too. - In a git hook,
--quietprints only the verdict and the limits exceeded:within budget, or theover budgetlines. - Tokens are bytes / a ratio: 2.25 bytes per token by default, or
bytes_per_token = ...in the budget. Running the tool on one of your transcripts prints the ratio measured in it. - Patterns: only
*,?and**/are special;[and]are plain characters. Quote a pattern with a dot, as above: TOML readsCLAUDE.md = 1as a nested key. - An invalid budget exits with 2, never passes: a typo in a key, a limit that is not a positive integer, a pattern that matches no file (it would leave a file without its limit), a missing budget file, or a wrong command line. An import that resolves outside the repository is listed, not counted.
In a GitHub Actions workflow:
- uses: actions/setup-python@v7
  with:
    python-version: "3.x"
- run: pip install claude-context-cost==1.6.3
- run: claude-context-cost --budget context-budget.toml
--json gives the same result for scripts; from Python,
check_budget(repository, budget_file) returns it, and raises BudgetError
for an invalid budget.
Why
claude-devtools already shows
the context by source. Read in its code at commit 1486f20 (the latest on
2026-10-10):
- Each source's tokens are characters / 4 (
src/main/utils/tokenizer.ts); only the turn total comes from theusage. - Rules in
.claude/rules/are listed as global sources without reading theirpaths:, so a rule that never loaded still counts. Issue #224, open since 2026-07-17. CLAUDE.mdand rules are read from disk today, not as they were during the session. On the author's machine (2026-10-11), only 290 of the 2,863 distinct texts loaded were still the same on disk.
This tool fixes all three: it counts from the usage and from the text the
transcript kept, and --versions finds that text in git.
What it counts
- One response per
message.id. A response is written over several lines with the sameusage; it counts once. - Context =
input_tokens+cache_read_input_tokens+cache_creation_input_tokens. - What entered between two responses is the context growth minus the previous response's output. When a single source entered, its tokens are measured. When several did, the growth is split by their size.
- At the start of the session and after each compaction the context
jumps at once: each source is estimated with the bytes-per-token ratio
measured in the same transcript (median over the responses after which
only text entered; 2.25 when
it has fewer than 3), and the rest is unattributed (system prompt,
tool definitions). So every response adds up to its
usage. - Rules with
paths:count only from the response where Claude Code loaded them (nested_memory), never before. - Only what Claude Code rendered into the context counts; bookkeeping lines in the transcript do not.
- A compaction removes everything; messages it keeps count as "kept by compaction", not as new responses.
How it is tested
- A synthetic transcript with known values (
tests/fixtures/build_example.py) where every source's tokens are worked out by hand: each one comes out exact, every response adds up to itsusage, apaths:rule that never loaded counts 0, a response written over several lines counts once. - The budget is tested on synthetic repositories (
tests/test_budget.py): what loads at start-up and on demand, imports, rendering, limits, invalid budgets.--versionsis tested on synthetic git repositories (tests/test_versions.py): a commit before and after the load, a text that comes back, a deleted file, a file outside git. python tests/mutate.pybreaks each of those rules in a copy of the code (51 mutants: 24 in the budget, 10 in--versions); the tests catch all 51.- On the author's machine (2026-10-10): 75 session transcripts and 382
subagent transcripts, 91,347 responses, 0 where the sources differ from the
usage, 0 where the response count differs from an independent count, and the sum over every project takes every transcript. For the budget (2026-10-11): the files found are the ones Claude Code loaded in 257 of 257 start-ups and 252 of 252 on-demand loads, with the same bytes in 268 of 268 files (loads whose files changed afterwards are left out). The ratio was measured in 50 of the 73 sessions with responses, median 2.22 bytes per token. For--versions(2026-10-11): of 2,863 distinct texts loaded, 811 were in a git repository and the commit was found for 798; the other 13 were never committed. Every one of the 212 texts that are the same today and inHEADgot its commit. Run it on yours withCLAUDE_CONTEXT_COST_CORPUS=1 python -m unittest tests.test_corpus -v(it prints only counts).
Limits
- Split and estimated tokens are not measured. The
howcolumn says which is which. Many steps bring a tool result together with a small reminder, so splitting is common. - Output includes thinking. Thinking may leave the context later, so the previous output can be overcounted; the remainder then shows as negative unattributed tokens (191 of 91,347 responses).
- A session's total does not include its subagents; the sum of its project's folder does.
- English was measured in one session (2026-10-10): 8 file reads, a license, release notes, two READMEs, three Python modules and a git log; median −40%, from −29% to −47%. The other numbers come from one person's sessions, mostly in Portuguese.
- The budget counts bytes, not the tokenizer: its tokens are as good as
the ratio. And it counts every
@importthat resolves to a file: on the author's machine Claude Code loaded 32 of 35 such imports, with no rule found for the other 3, so the budget may count more than loads, never less. --versionsfinds only the exact text. A commit that differs by one character is not it; the file is thennot committed. It needsgiton thePATH, and it reads only.mdfiles.- The transcript format is not documented and changes between versions.
Compatibility
Transcripts of Claude Code 2.1 (the synthetic fixture follows 2.1.293). Python 3.11 to 3.14, tested on Linux and Windows.
Versions follow Semantic Versioning: the names in
claude_context_cost.__all__ and the keys of --json change incompatibly only
in a new major version. The transcript format is Claude Code's and changes
without notice; when it does, a fix keeps the API and ships as a minor or
patch version.
Contributing
See CONTRIBUTING.md. Never paste a real transcript in an issue or pull request: it holds paths, file contents and sometimes secrets. Report a security problem privately, as in SECURITY.md.
License
1 maintainer

Metadata
1 maintainer
Release files for claude-context-cost 1.6.3
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| claude_context_cost-1.6.3.tar.gz | 56.1 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| claude_context_cost-1.6.3-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 88.5 kB
Release files / claude_context_cost-1.6.3.tar.gz
| Download URL | claude_context_cost-1.6.3.tar.gz |
|---|---|
| Size | 56.1 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
ff6a5a00f903721f941c3dadb5a82ab56c9617209fba5a6618c794bc1e61631f
|
|
BLAKE2b-256 checksum How to use checksums |
e43411cccf5bea34428530eabc031e9bd8cd0259a58ad98f2014aa016c2f44bc
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 11, 2026.
Transparency logRelease files / claude_context_cost-1.6.3-py3-none-any.whl
| Download URL | claude_context_cost-1.6.3-py3-none-any.whl |
|---|---|
| Size | 32.5 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
2a3021f9739f1840c5bfa51c8b167bf272fdaa0fb389effb5e9a93779c2edf61
|
|
BLAKE2b-256 checksum How to use checksums |
22a3cec4a1dbeff5f60472d6e23ddcac24f83a2f5d281b3e76b37a9c2363688f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 11, 2026.
Transparency log













