
clausius — measure the model as you run it

Benchmarks measure models; clausius measures the model as you run it — at your quantization, your cap, your thinking setting, on your prompts — with paired statistics and the truncation rate beside every number. Today that is two verbs: compare tells you whether a change broke the model, on your own prompts, with no labels, and exits non-zero so it drops into CI without glue; plan tells you how to run a model from measured cells.
Install
pip install "clausius[mlx]"        # capture + compare (Apple Silicon)
pip install clausius               # compare and analysis only — pure numpy, runs anywhere
Run it
Take 60 prompts of your own — production traffic is ideal, no labels needed — or the 60 in examples/prompts.jsonl. Capture the configuration you trust, capture the one you changed, compare:
clausius capture --model ./gemma-26b-a4b-4bit --prompts examples/prompts.jsonl --out ref.json  --max-tokens 1536
clausius capture --model ./gemma-26b-a4b-2bit --prompts examples/prompts.jsonl --out cand.json --max-tokens 1536
clausius compare ref.json cand.json --show 3
REGRESSION  (max d_z = +5.922, threshold 0.3, one-sided)
  compared 20 paired items, dropped 5 truncated
  all signals: max +5.92  p90 +11.64  mean +10.43  mean_top10 +9.00  first +2.80  gen_len +10.55
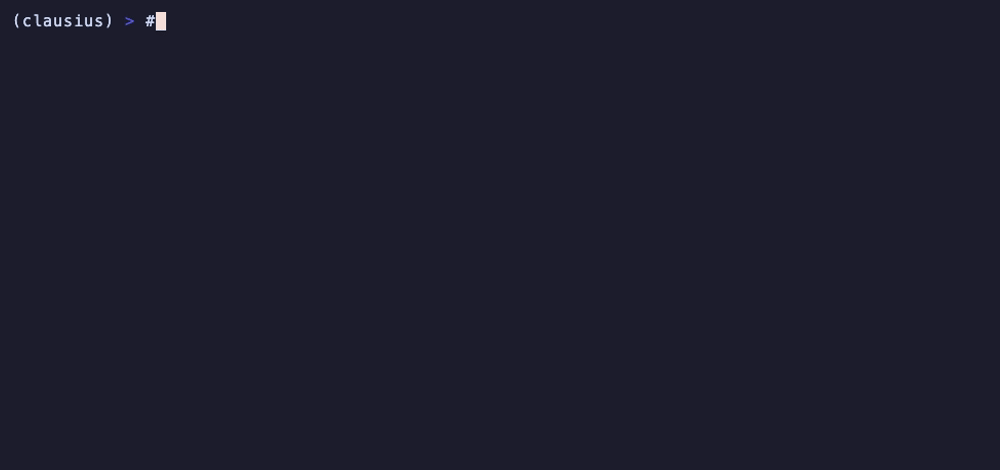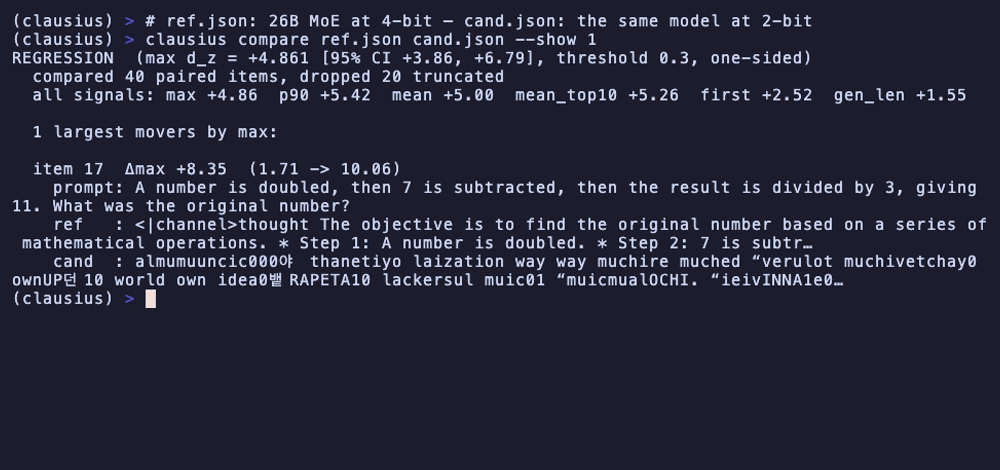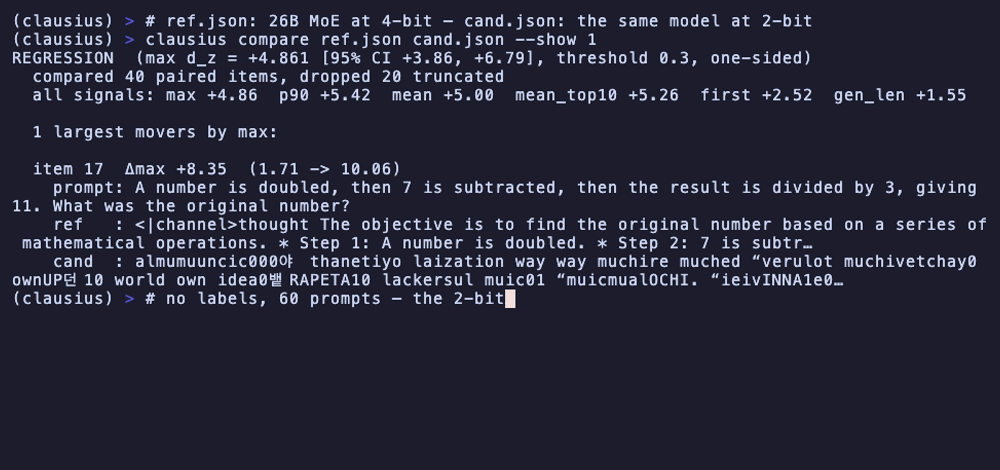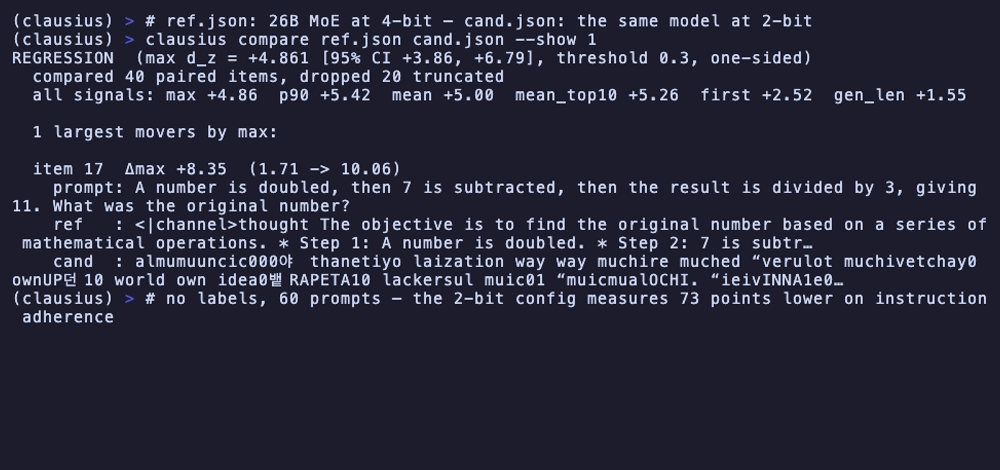
That is a real run on 25 unlabeled prompts. The two checkpoints differ only in quantization; the 2-bit one independently measures 73 points lower on instruction adherence. --show 3 prints the items whose entropy moved most, with the text both configurations produced — the verdict says something broke, this says what.
First time? Try it in 30 minutes: three public checkpoints, five commands, measured output included. Then read USAGE.md: choosing prompts, setting the token cap, reading d_z and its interval, calibrating your own null, running it as a CI gate.
What the verdict means
- The signal is the change in the model's predictive entropy over its own answers, paired prompt by prompt between the two captures (
d_z). - The defaults are measured, not chosen: the 0.3 threshold comes from 13 configurations known to be harmless; the one-sided test from a construction that fools a two-sided one; the truncation filter from an effect that doubles once applied.
src/clausius/core.pystates each one and MEASUREMENTS has the evidence. - It is more sensitive than labels on the damage it was validated against: a −2.2pp quantization regression was flagged on 60 unlabeled prompts where a paired test on gold labels needed n=878 (F14).
- It is a regression check, not a score: it needs a reference capture and cannot rate a configuration in isolation.
Limits
- Sensitivity is the weaker half. Specificity is 13/13; a −5.7pp configuration is missed at any threshold that preserves that record.
- Confidence-increasing damage would be invisible to a one-sided detector. Three mechanisms were built to produce it and none did, but it is not excluded.
d_zis ordinal, not proportional: 3-bit loses 25× more accuracy than 4-bit and reads 2× thed_z. "Something moved, and roughly how hard" is supportable; "you lost k points" is not.- The threshold is calibrated on one stack (MLX, Apple Silicon). On another framework, device, or quantizer, measure your own null first — USAGE.md has the recipe.
- Local and self-hosted models only: hosted APIs expose no logprobs, or truncated ones, which is a different quantity.
Capture targets Apple Silicon via MLX in this release. An experimental PyTorch backend exists and is deliberately unshipped: it has been measured on mps and cpu, never calibrated on cuda or the CUDA-native quantizers, and shipping an uncalibrated threshold would contradict what this package claims about its defaults. It is archived at the tag archive/torch-backend rather than kept as a live branch, and will be revisited if a user needs it or a contribution calls for it; the bar it must clear is recorded in the research notes.
Receipts
The numbers behind the defaults, measured on consumer hardware (M5 Max, 128 GB) across five model families, with negatives kept: eight controlled failures and seven corrections to the record. Headline rows:
| result | where | |
|---|---|---|
| Label-free detection works | validated against five unrelated damage mechanisms whose true damage was measured independently; benign controls stay clean (a 3.3× memory reduction changes ~25% of generations textually and moves no signal) | F8 |
| More sensitive than labels | the −2.2pp regression: 60 unlabeled prompts, where labels needed n=878 | F14 |
| Short benchmarks understate damage ~14× | factual QA loses 1.5pp where structured generation loses 18–21pp under the same quantization | F11 |
| Offload beats downsizing | an offloaded 35B at 3.40 GB scores 0.9447 on gsm8k against a natively-fitting 4B at 3.91 GB scoring 0.8426; the whole cost is latency | F3–F6 |
Everything else — the quantization ladder and frontier chart, the claim taxonomy, what did not work, the seven corrections, prior art — is in MEASUREMENTS. The corpus and the research code that produced these results live in a separate research repository; MEASUREMENTS records each result with its n and its interval.
Ask how to run a model
clausius plan answers "thinking on or off, at what cap, and what does it cost" from measured cells — never from estimates. Each row is one configuration actually run: accuracy with a 95% interval, seconds per item, and the share of items that hit the output cap. One pick per task by a fixed rule (highest accuracy among rows that truncated at most half their items; ties go to the cheaper row). A row that truncated more than half is reported as cap-bound, because its accuracy is partly the cap's.
clausius plan                          # models on the card
clausius plan --model qwen3.5-35b-a3b --task aime-2024-25
  aime-2024-25
    strategy                        cap    n  accuracy           95% CI  s/item  trunc
    greedy                         2048   60     0.200   [0.118, 0.318]      19   0.80  cap-bound
    greedy                         8192   60     0.550   [0.425, 0.669]      47   0.67  cap-bound
    thinking                      16384   60     0.400   [0.286, 0.526]     121   0.62  cap-bound
    thinking                      32768   60     0.550   [0.425, 0.669]     204   0.47  ◀ pick
The card currently holds 37 rows across four Qwen models on gsm8k, MATH-500 L5, GPQA-Diamond, AIME, IFEval, BFCL, and LiveCodeBench, all measured on one machine (M5 Max, 128 GB) at 4-bit; the rows and their sources are in the packaged data/cards.json (--json prints them). Rows are added as cells are measured, never interpolated.
Where this is going
v0.2 adds report cards — the benchmarks official model cards report, re-measured at the configurations people actually deploy — and makes every measurement a module on one statistical core, so later measurements (agent trajectories, stopping behavior) arrive as rows on the same card rather than as new tools.
Sibling. boyle runs the model you want at the memory pressure you specify — budgeted MoE inference with speed forecasts before you download. Its predict cites this repository's measured accuracy.
Named for Rudolf Clausius, who coined the word entropy in 1865. Entropy is the signal this tool reads.
Repository layout
| path | what | needs |
|---|---|---|
src/clausius/ |
the tool — capture, compare, plan, CLI; data/cards.json is the measured card |
numpy; mlx-lm only to capture |
src/clausius/measure/ |
the measurement engine: run a strategy over items against any OpenAI-compatible endpoint, one JSONL record per item with resume, paired statistics (exact McNemar, Wilson intervals), manifests → card rows | stdlib |
tests/ |
80 tests, none load a model; CI installs the built wheel | numpy |
USAGE.md |
the operating manual | — |
docs/measurements.md |
the measured basis for the tool's defaults and claims | — |
1 maintainer

Metadata
1 maintainer
Release files for clausius 0.1.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| clausius-0.1.2.tar.gz | 42.8 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| clausius-0.1.2-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 82.2 kB
Release files / clausius-0.1.2.tar.gz
| Download URL | clausius-0.1.2.tar.gz |
|---|---|
| Size | 42.8 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
f2fb31465091d07f6c382241cf6ad69efc35dd5563cc7129556ac139bd7f9ac7
|
|
BLAKE2b-256 checksum How to use checksums |
adb0fb25f8c3eefe5633e7c3d128755a6a1b98fb20abab50c04e51c474d6a576
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 14, 2026.
Transparency logRelease files / clausius-0.1.2-py3-none-any.whl
| Download URL | clausius-0.1.2-py3-none-any.whl |
|---|---|
| Size | 39.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
18c738f5e7c08a457a724b9c4f5b68e78c38e9f2d2c75f2e41888e33941a466d
|
|
BLAKE2b-256 checksum How to use checksums |
519ad549b8dbef734b3f9be58d0374c1f4344ae09997619bc81a9ccbe1c0013a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 14, 2026.
Transparency log












