
CleanFrame
The reproducible data-cleaning engine for Python.
AI writes the cleaning recipe once. The recipe runs forever — deterministic, diffable, reviewable.
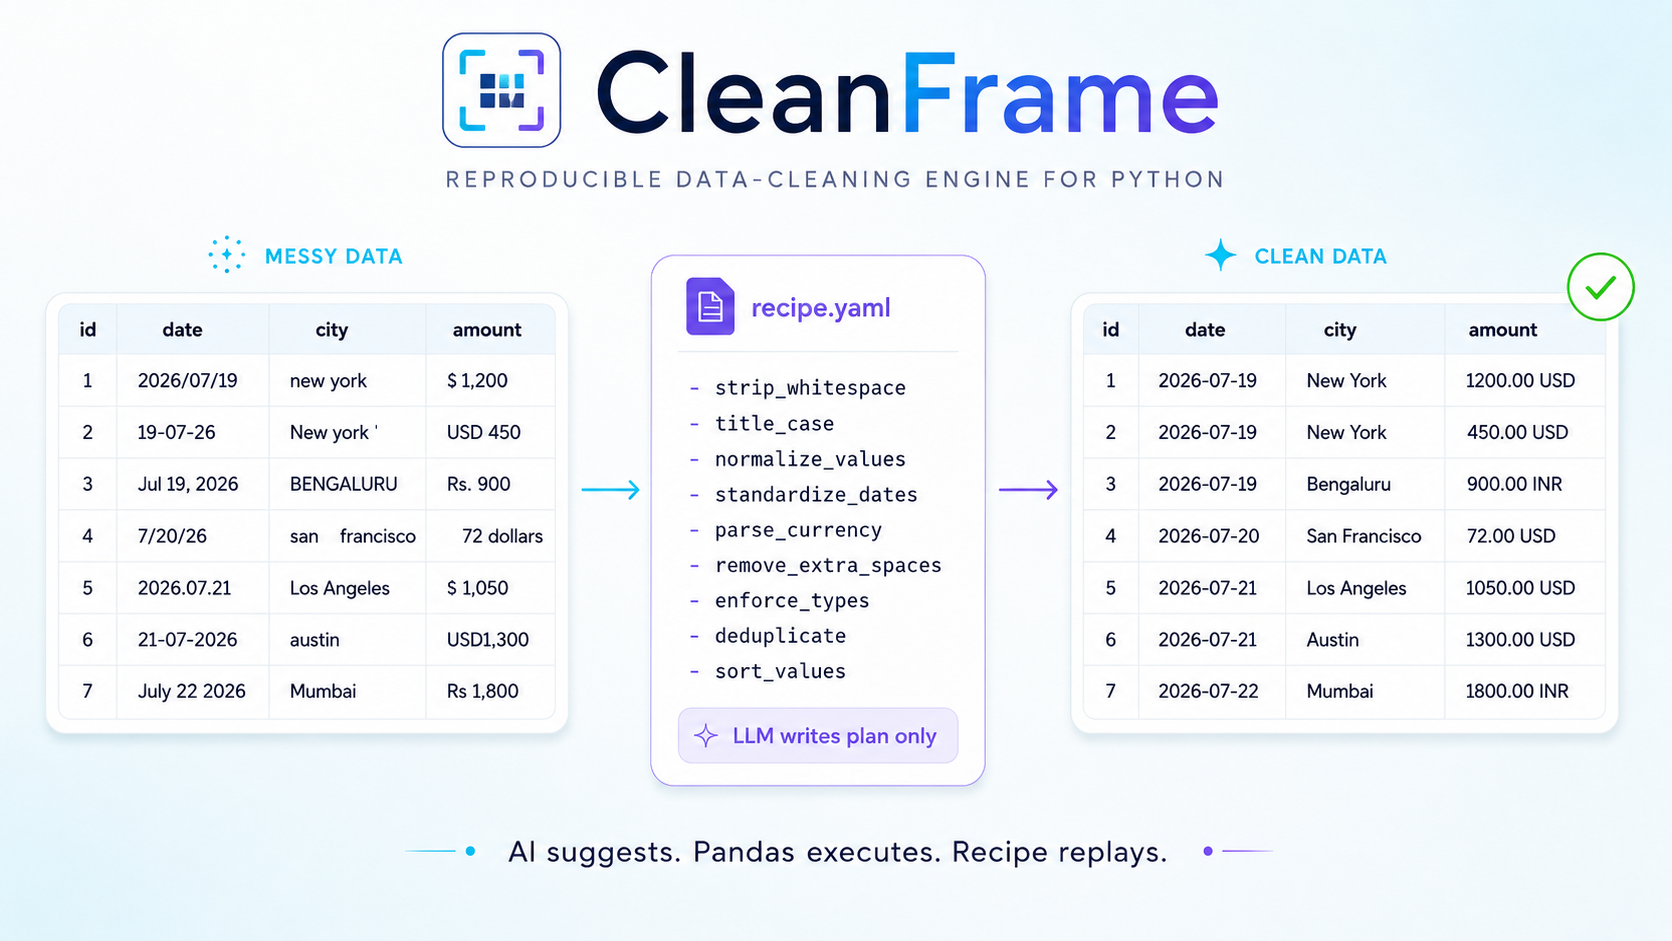




Every team has that file. The vendor spreadsheet that arrives monthly with dates in three formats. The CRM export where Bengaluru, Bangalore, and BLR are three different cities. The finance sheet with ₹1,20,000 in a column typed as text.
You clean it by hand. Next month, it arrives broken in a new way, and you clean it again.
CleanFrame ends that loop. It profiles your data, detects issues, proposes a cleanup plan (with an LLM's help — or without one), executes it with pure pandas, and saves the whole thing as a recipe: a versionable YAML file that replays on every future file with zero AI calls, and alerts you when the incoming schema drifts.
AI suggests. Pandas executes. Rules validate. You approve. Everything is reproducible.
Documentation
| Wiki (full docs) | Getting started, API, recipe/schema specs, production guide |
| docs/ | Same guides in-repo |
| CONTRIBUTING.md | Invariants + how to add detectors/ops |
| SECURITY.md | Vulnerability reporting |
| CHANGELOG.md | Release notes |
Why not just use an LLM agent on my dataframe?
Because you can't ship "the model probably fixed it" to production. Chat-with-your-data tools are great for exploration and say so themselves — they are not built for pipelines. CleanFrame is built on one rule:
The LLM never touches your data. It only writes the plan.
The plan compiles to deterministic pandas operations. Same input → same output, every time. Every changed cell is tracked. Every step is reviewable, reversible, and exportable as plain Python you can read.
30-second demo
No API key needed for this:
pip install cleanframe-engine
cleanframe report examples/messy_customers.csv
You get an HTML report: detected issues, quality score, column-by-column diagnosis. Then fix it:
import pandas as pd
import cleanframe as cf

df = pd.read_csv("examples/messy_customers.csv")

result = cf.clean(
    df,
    target_schema="examples/customer.schema.yaml",  # or: cf.infer_schema(df)
    llm="anthropic/claude-sonnet-4-6",              # optional — omit for rules-only
    mode="review",                                  # review | auto | strict
)

result.diff.show()                # cell-level before/after, git-diff style
result.recipe.save("customer.recipe.yaml")   # ← the durable artifact
result.code.save("clean_customers.py")       # plain pandas, no cleanframe dependency
clean_df = result.dataframe
result.quarantine                 # rows validation held back, with reasons — never deleted
The sample file has one genuinely invalid email, so the demo quarantines that row and cleans the other five.
Next month, the file comes back. No LLM, no tokens, no variance:
cleanframe apply new_customers.csv --recipe customer.recipe.yaml --out clean.csv
If the new file's schema drifted (a renamed column, a new currency format), CleanFrame stops and tells you instead of silently corrupting data:
⚠ Schema drift detected in new_customers.csv
  • Column "Amt (INR)" is new — 94% match to recipe column "amount_inr"
  • 312 value(s) in "signup_date" match no allowed date format (new: 'Jan 5, 26')
  • 40 of 312 numeric value(s) in "Amount" do not fit the recipe's number format
    (decimal '.', thousands ','; new: '€1.200,50')
  Run `cleanframe suggest new_customers.csv --recipe <recipe.yaml> --update` to review a patch.
Bring your own API key (or no key at all)
CleanFrame is LLM-optional and provider-agnostic.
| Mode | What runs | Data leaves your machine? |
|---|---|---|
| Rules-only (default) | Deterministic detectors + heuristics | Never |
| Metadata | LLM sees column names, dtypes, and value patterns (regex sketches) — never raw values | Only metadata |
| Sample | LLM sees a small shuffled sample of values. Emails, phones and long strings are redacted; other short values (names, cities) are sent verbatim. Passing llm_exposure="sample" is the opt-in — there is no separate approval step |
Sample values, per the redaction above |
| Replay | Saved recipes | Never — recipes need no LLM |
- Keys come from environment variables (
ANTHROPIC_API_KEY,OPENAI_API_KEY,OPENROUTER_API_KEY,GROQ_API_KEY, …). CleanFrame never stores or logs them, and each provider reads only its own variable —OPENAI_API_KEYis never sent to another provider. - Any provider that speaks OpenAI Chat Completions works out of the box —
Anthropic (native), OpenAI, OpenRouter, Groq, Together, Fireworks, DeepSeek,
Mistral, Google Gemini, xAI, Perplexity, Cohere, plus local Ollama / LM Studio
or any custom
OPENAI_BASE_URL. Spec format:provider/model(e.g.openrouter/anthropic/claude-sonnet-4,groq/llama-3.3-70b-versatile). - Cost cap:
cf.clean(..., max_tokens_budget=50_000)is checked before each call (against an estimate) and again against the usage the provider reports — leave headroom, since a call that overshoots has already been billed. - Fully offline / air-gapped operation is a supported first-class mode, not a degraded one.
What it cleans
| Problem | Example |
|---|---|
| Invisible characters | zero-width spaces, BOMs, non-breaking spaces and decomposed accents (café typed two ways) → one normalised form |
| Column name chaos | Cust Name, customer_name, CustomerName → customer_name |
| Date formats | 12/01/24, 1 Jan 2024, 2024-01-01 → ISO dates |
| Currency & numbers | ₹1,20,000, $1,200, -$5, (1,200), 1.234,56, 1200 INR → typed floats (+ a currency column); a value whose grouping is invalid or ambiguous becomes a counted, warned null, never a guess |
| Category variants | Bengaluru / bengaluru / BENGALURU and typos (Banglore) → one canonical value; abbreviations such as BLR need a seed map or an LLM |
| Emails & phones | validation, normalization, 00/+ international prefixes, optional default country code |
| Duplicates | exact duplicates are dropped (tracked in the diff); fuzzy near-duplicates and key collisions are reported with keep/drop proposals for you to act on |
| Missing values | detected and explained; strategies proposed, never silently applied |
| Units | 5kg, 5000 g, 5 KG → normalized |
| Schema mapping | messy file → your target schema, with confidence scores |
| Outliers | flagged with evidence — detected, never auto-"fixed" |
Production-ready defaults
CleanFrame is built for pipelines, not just demos:
- Plan once, replay forever — commit recipes; fail on schema drift
- Multi-sheet workbooks — clean every Excel tab into one reviewable recipe; write-back refuses to overwrite the source in place
- Out-of-core streaming — replay row-independent recipes over larger-than-RAM CSVs at chunk-bounded memory
- Format auto-detection — encoding (utf-8 → cp1252) and delimiter sniffed at read time, pinned into the recipe for replay
- Bounded memory — detector sampling (50k values) + capped cell-diff detail (100k); the diff snapshots the op-touched columns (peak is the frame plus those columns — about 2× when most columns are cleaned; use streaming for files that do not fit)
- Safe CSV exports — spreadsheet formula injection escaped by default
- Regex guards — oversized / nested-quantifier patterns rejected
- Visible degradation — missing columns, unparseable values and LLM fallbacks warn instead of failing silently
- Quarantine, don't delete — validation failures are held with reasons
- Verbatim reads —
text=Truekeeps leading zeros, literalNAand1e5exactly as the file has them; otherwise CleanFrame warns about what pandas' type inference changed on read - Never overwrites its input — writing output over the source file takes an explicit
--overwrite, and every write lands via a temporary file - Scriptable exits — distinct exit codes for usage errors, data errors, drift stops and validation failures;
--jsonprints one machine-readable summary on stdout - Number-format drift — a file whose numbers stop fitting the recipe (
€1.200,50against a.-decimal recipe) stops the replay instead of yielding1.2005 - Strict recipes — unknown ops/params, duplicate keys and bad regexes fail at load; plain YAML keys like
yes,010or12:30stay column names - Generated code = executor — exported pandas embeds the executor's own parsers, and property-based tests check they agree
- Plugins that travel — custom ops/detectors load from entry points,
--pluginorCLEANFRAME_PLUGINS, and can opt in to code export and streaming
See the Production Guide.
The recipe: your durable artifact
# customer.recipe.yaml — generated by CleanFrame, edited by you, owned by git
version: 1
# source_fingerprint: {...}   ← stamped automatically; drives drift detection
columns:
  "Customer Name":
    rename_to: customer_name
    ops: [strip_whitespace, title_case]
  "Signup Date":
    rename_to: signup_date
    parse_date: {dayfirst: true, allowed: ["%d/%m/%Y", "%d-%m-%Y", "%Y-%m-%d"]}
  "Amount":
    rename_to: amount_inr
    ops: [{remove_symbols: ["₹", ","]}, {cast: float}]
  "City":
    rename_to: city
    normalize_values: {Bengaluru: Bangalore, BLR: Bangalore, Bombay: Mumbai}
  "Email":
    rename_to: email
    ops: [strip_whitespace, normalize_email]
validate:
  - {column: email, check: valid_email, on_fail: quarantine}
  - {column: amount_inr, check: ">= 0", on_fail: quarantine}
A worked example ships in examples/ (messy_customers.csv,
customer.schema.yaml, customer.recipe.yaml).
Recipes are reviewed in PRs like code, replayed in CI/Airflow/dbt, and exported as
plain pandas via result.code — CleanFrame plays with your validation stack,
not against it.
How it compares
| CleanFrame | PandasAI | Great Expectations / pandera | YData Profiling | OpenRefine | Flatfile / OneSchema | |
|---|---|---|---|---|---|---|
| Fixes data (not just reports) | ✅ | ⚠️ ad-hoc | ❌ validates only | ❌ profiles only | ✅ | ✅ |
| Deterministic & reproducible | ✅ recipes | ❌ | ✅ | ✅ | ⚠️ manual | ⚠️ |
| Production pipelines | ✅ | ❌ (exploration tool) | ✅ | ⚠️ | ❌ GUI | ✅ |
| Python-native library + CLI | ✅ | ✅ | ✅ | ✅ | ❌ | ❌ JS widget / SaaS |
| Works with zero LLM / offline | ✅ | ❌ | ✅ | ✅ | ✅ | ⚠️ |
| Cell-level diff & lineage | ✅ | ❌ | ❌ | ❌ | ⚠️ | ⚠️ |
| Schema-drift alerts on re-import | ✅ | ❌ | ⚠️ | ❌ | ❌ | ✅ ($6k+/yr) |
| Free & open source | ✅ Apache-2.0 | ✅ | ✅ | ✅ | ✅ | ❌ |
Use PandasAI to explore. Use pandera/GX to guard. Use CleanFrame to fix — repeatably.
Architecture
CSV / Excel / DataFrame
   │
   ▼
Profiler ─→ Issue Detectors ─→ Planner ──────────→ Recipe (YAML)
             (deterministic)    (rules, or            │
                                LLM-assisted)         ▼
                                              Executor (pure pandas)
                                                      │
                                                      ▼
                                        Validator · Cell-diff · HTML report
Detectors and ops are plugins — write your own in ~30 lines:
@cf.register_op("normalize_iban", streamable=True,
                codegen=lambda p, col: [f"df[{col!r}] = df[{col!r}].str.replace(' ', '').str.upper()"])
def normalize_iban(series: pd.Series) -> pd.Series:
    return series.str.replace(" ", "").str.upper()

@cf.detector("iban")
def detect_iban(series: pd.Series) -> cf.Issues: ...   # propose cf.Op("normalize_iban")
Package it under the cleanframe.plugins entry-point group and cleanframe apply in CI
finds it — see the plugin guide.
Install
pip install cleanframe-engine
pip install "cleanframe-engine[excel]"      # Excel
pip install "cleanframe-engine[parquet]"    # Parquet
pip install "cleanframe-engine[llm]"        # Anthropic + OpenAI SDKs
pip install "cleanframe-engine[all]"

# straight from git
pip install "cleanframe-engine @ git+https://github.com/inboxpraveen/Cleanframe"
Python 3.10+. The distribution is cleanframe-engine; the import package is
cleanframe (import cleanframe as cf), and the CLI is cleanframe (or
python -m cleanframe).
Roadmap
- Profiler, core detectors (dates, currency, categories, dedup, nulls, schema mapping)
- Recipe format v1 + replay + drift detection
- HTML reports, cell-level diff
- Production safety guards (sampling, CSV sanitisation, regex limits, diff caps)
- Multi-sheet Excel workbooks (clean every tab, safe write-back)
- Selective ingestion (sheet / columns / rows)
- Out-of-core streaming replay (larger-than-RAM CSVs)
- Read-time format auto-correction (encoding + delimiter)
- Plugin discovery; custom ops that export and stream
-
--jsonrun summaries, library logging, property-based invariant tests -
MessyData-100public benchmark + leaderboard - pandera / GX / dbt exporters
- Polars backend
- Recipe registry for teams
Contributing
The detector plugin system exists so the community owns the long tail of messy-data weirdness. Good first issues are tagged good-first-detector. See CONTRIBUTING.md.
Sponsoring
CleanFrame is free, Apache-2.0, and will stay that way for individuals — no feature is paywalled for a person with a laptop and a messy CSV. If it saves your team recurring hours, sponsorship funds detector coverage, the benchmark, and long-term maintenance.
Profile it once. Recipe it forever.
1 maintainer

Metadata
1 maintainer
Release files for cleanframe-engine 0.4.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| cleanframe_engine-0.4.0.tar.gz | 270.5 kB | With provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| cleanframe_engine-0.4.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 459.1 kB
Release files / cleanframe_engine-0.4.0.tar.gz
| Download URL | cleanframe_engine-0.4.0.tar.gz |
|---|---|
| Size | 270.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
ab7b3423bfbb63729228260e2fb40fe0cd477df692b3ef04873de096c13d0de7
|
|
BLAKE2b-256 checksum How to use checksums |
f876c2707b613f0de79ad6ebcf5a1a04776f6ceae61d96eb2e4945af00ef7119
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 18, 2026.
Transparency logRelease files / cleanframe_engine-0.4.0-py3-none-any.whl
| Download URL | cleanframe_engine-0.4.0-py3-none-any.whl |
|---|---|
| Size | 188.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
a0846164ed00a3f50ad9fc0fe610cb8c269f7a6741e00d7d58eb7051ab2d82fc
|
|
BLAKE2b-256 checksum How to use checksums |
ec79c6e5d8e21efa6e1d625be8d0344c640949ec7ad23daa1eaafbf4e5321c5e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 18, 2026.
Transparency logSecurity for cleanframe-engine 0.4.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for cleanframe_engine-0.4.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 18, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.














