
clinops 🏥
Clinical ML Pipeline Toolkit — production-grade data loading, preprocessing, and time-series feature engineering for healthcare AI research.




Docs: https://clinops.readthedocs.io/ | PyPI: https://pypi.org/project/clinops/
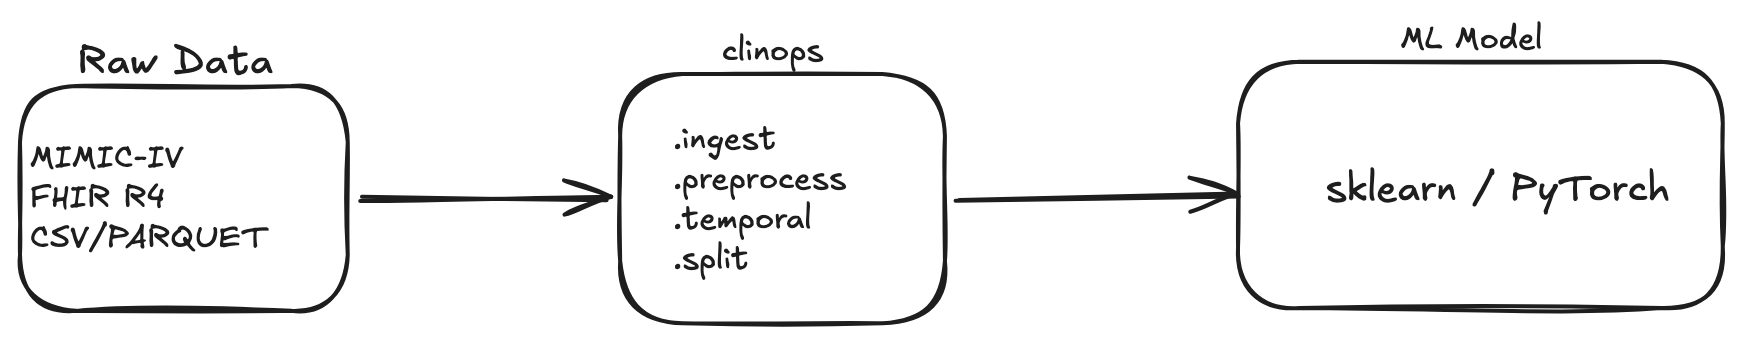
Every healthcare AI project starts with the same two weeks of plumbing: loading
MIMIC-IV tables without hitting memory limits, clipping physiologically impossible
values before they corrupt your model, normalizing glucose from mmol/L to mg/dL
across sites, building time-series windows that handle clinical missingness correctly,
and splitting data without leaking patients across folds. clinops packages those
hard-won patterns into a single, well-tested library so your first notebook is actual
science.
Built from production experience in clinical and genomic data engineering across multi-cloud environments.
Modules
| Module | What it does |
|---|---|
clinops.ingest |
Loaders for MIMIC-IV, MIMIC-III, eICU-CRD, FHIR R4, and flat CSV/Parquet with schema validation. Includes MimicTableLoader (pre-built MIMIC schemas) and EicuTableLoader (offset-based multi-centre ICU feature/label/sequence builder). |
clinops.temporal |
Sliding/tumbling windows, gap-aware imputation, lag features, cohort alignment |
clinops.preprocess |
Outlier clipping with physiological bounds, unit normalization (mg/dL ↔ mmol/L etc.), ICD-9→10 mapping |
clinops.split |
Temporal, patient-level, and stratified patient train/test splitting |
clinops.monitor |
Distribution drift detection (PSI, KS) and data quality checks (null rates, schema and dtype drift, row count anomalies) |
clinops.orchestrate |
Pipeline artifact storage on GCS/S3 and AWS Step Functions pipeline definition and execution (optional gcp/aws extras) |
See the user guide for full walkthroughs of clinops.monitor and clinops.orchestrate.
How clinops relates to other tools
clinops is a data preparation library: it turns raw clinical tables into clean, leakage-safe DataFrames. It does not train models, and it is meant to be used alongside modelling libraries rather than instead of them.
| clinops | PyHealth | scikit-learn | |
|---|---|---|---|
| Main purpose | Clinical data preparation on pandas DataFrames | End-to-end deep learning for healthcare (PyTorch) | General-purpose ML |
| Dataset loaders | MIMIC-III, MIMIC-IV, eICU-CRD, FHIR R4, flat CSV/Parquet | MIMIC-III, MIMIC-IV, eICU, OMOP, FHIR, and more | None |
| Patient-level splits | PatientSplitter, StratifiedPatientSplitter, GroupedPatientSplitter |
split_by_patient |
GroupShuffleSplit, GroupKFold, StratifiedGroupKFold |
| Timestamp cutoff split | TemporalSplitter |
No | No (TimeSeriesSplit splits by row position) |
| Physiological range clipping | ClinicalOutlierClipper |
No | No |
| Lab unit normalization | UnitNormalizer (30 conversions) |
No | No |
| ICD-9 to ICD-10 mapping | ICDMapper |
medcode.CrossMap |
No |
| Drift and data quality monitoring | clinops.monitor |
No | No |
| Models and training | No | Yes | Yes |
When to choose which:
- PyHealth is the better fit if you want a full deep learning pipeline: predefined clinical tasks, PyTorch models, and a trainer. It overlaps with clinops on dataset loading, patient-level splitting, and ICD code mapping. Use clinops when you need a pandas-native preparation step that PyHealth does not cover (unit normalization, physiological clipping, timestamp cutoff splits, drift monitoring), or when you are training classical models and do not want a PyTorch dependency.
- scikit-learn's group splitters already keep each patient's records
together, and
StratifiedGroupKFoldalso balances the outcome. For k-fold cross-validation, use them directly. clinops splitters produce a single train/test (or train/val/test) split as DataFrames with a summary of sizes and outcome rates, and add the timestamp cutoff split that scikit-learn lacks.
Using clinops with scikit-learn: clinops handles the clinical cleaning and windowing, and scikit-learn handles patient-grouped cross-validation and the model.
from sklearn.ensemble import RandomForestClassifier
from sklearn.impute import SimpleImputer
from sklearn.model_selection import StratifiedGroupKFold, cross_val_score
from sklearn.pipeline import make_pipeline

from clinops.preprocess import ClinicalOutlierClipper, UnitNormalizer
from clinops.temporal import TemporalWindower

# 1. clinops: clinical cleaning that generic tools don't know about
df = UnitNormalizer(column_unit_map={"glucose": "glucose_unit"}).transform(df)
df = ClinicalOutlierClipper(action="null").fit_transform(df)

# 2. clinops: per-patient time windows -> one feature row per window
windows = TemporalWindower(window_hours=24, step_hours=6).fit_transform(
    df, id_col="subject_id", time_col="charttime", feature_cols=["heart_rate", "glucose"]
)
windows["label"] = windows["subject_id"].map(outcomes)

# 3. scikit-learn: patient-grouped, outcome-stratified cross-validation.
#    Imputation sits inside the pipeline so it is fit on each training fold only.
model = make_pipeline(SimpleImputer(strategy="median"), RandomForestClassifier(random_state=0))
cv = StratifiedGroupKFold(n_splits=5, shuffle=True, random_state=0)
scores = cross_val_score(
    model, windows[["heart_rate", "glucose"]], windows["label"],
    groups=windows["subject_id"], cv=cv, scoring="roc_auc",
)
Comparison based on PyHealth and scikit-learn 1.8 as of October 2026. If something here is out of date, please open an issue.
Quickstart
pip install clinops
clinops.ingest
MimicTableLoader — pre-built schemas, no manual ColumnSpec required
MimicTableLoader wraps MimicLoader and exposes the five MIMIC-IV tables
researchers use in every project with fully validated schemas out of the box.
No ColumnSpec definitions, no schema boilerplate.
from clinops.ingest import MimicTableLoader

tbl = MimicTableLoader("/data/mimic-iv-2.2")

# ICU vitals — charttime parsed as datetime automatically
charts = tbl.chartevents(subject_ids=[10000032, 10000980])

# Lab results — reference range columns dropped by default (sparse in most exports)
labs = tbl.labevents(subject_ids=[10000032], with_ref_range=True)

# Hospital admissions with mortality flag
adm = tbl.admissions(subject_ids=[10000032])

# ICD-9/10 diagnoses — primary_only keeps only seq_num == 1
dx = tbl.diagnoses_icd(subject_ids=[10000032], primary_only=True)

# ICU stays — with_los_band adds <1d / 1-3d / 3-7d / >7d column
stays = tbl.icustays(subject_ids=[10000032], with_los_band=True)
Audit a new MIMIC download without loading full tables into memory:
tbl.summary()
#        table  rows_sampled  columns  null_rate_pct
#  chartevents         10000       23           8.41
#    labevents         10000       12           4.17
#   admissions         10000       15           6.02
# diagnoses_icd        10000        5           0.00
#     icustays         10000        8           2.31
MimicLoader — full control
For advanced filtering and chunk-based loading of large tables, use MimicLoader
directly:
from clinops.ingest import MimicLoader

loader = MimicLoader("/data/mimic-iv-2.2")

charts = loader.chartevents(
    subject_ids=[10000032, 10000980],
    start_time="2150-01-01",
    end_time="2150-01-10",
)
labs  = loader.labevents(subject_ids=[10000032, 10000980])
stays = loader.icustays(subject_ids=[10000032, 10000980])
Load eICU-CRD (multi-centre external validation)
eICU stores time as integer minute offsets from ICU admission, ages over 89
as the string "> 89", and labs in long free-text format across 208 hospitals.
EicuTableLoader normalises all of that into the same canonical feature matrix
the MIMIC pipeline produces — so cross-site validation is a few lines:
from clinops.ingest import EicuTableLoader
from clinops.split import GroupedPatientSplitter

loader = EicuTableLoader("/data/eicu-crd")

# 22-feature hourly sequences (7 vitals, 9 labs, 3 derived, 3 treatment) +
# 5 physiology-only organ-deterioration labels — with a programmatic leakage
# guard that refuses to emit label-defining variables as features.
X, y = loader.build_sequences(observation_hours=24, prediction_hours=6)

# Patient-grouped 70/15/15 split: uniquepid (patient) ≠ patientunitstayid (stay),
# so all stays for one patient stay in the same fold (no leakage).
meta = loader.build_cohort()[["uniquepid", "patientunitstayid", "unittype"]]
split = GroupedPatientSplitter(
    group_col="uniquepid", stay_col="patientunitstayid",
    val_size=0.15, test_size=0.15, random_state=42,
).split(meta)
Large tables (vitalPeriodic, nurseCharting, lab, …) are read in chunks, so
the 6–11 GB files never have to fit in memory.
Load FHIR R4 resources
from clinops.ingest import FHIRLoader

loader   = FHIRLoader("/data/fhir_export")
obs      = loader.observations(category="vital-signs")
patients = loader.patients()
Validate any flat clinical export
from clinops.ingest import FlatFileLoader, ClinicalSchema, ColumnSpec

schema = ClinicalSchema(
    name="vitals",
    columns=[
        ColumnSpec("subject_id", nullable=False),
        ColumnSpec("heart_rate", min_value=0,  max_value=300),
        ColumnSpec("spo2",       min_value=50, max_value=100),
    ]
)
df = FlatFileLoader("vitals.csv", schema=schema).load()
clinops.preprocess
Clip physiologically impossible values
Standard statistical outlier methods (z-score, IQR) are wrong for clinical data —
a heart rate of 180 in a patient with SVT is clinically meaningful and should not
be removed. ClinicalOutlierClipper uses published physiological bounds to remove
values that are impossible regardless of patient state.
from clinops.preprocess import ClinicalOutlierClipper

clipper = ClinicalOutlierClipper(action="clip")  # or "null" or "flag"
clean_df = clipper.fit_transform(vitals_df)

print(clipper.report())
#    column  low_outliers  high_outliers  pct_outliers  bound_low  bound_high
#  heart_rate             0              3         0.012          0         300
#        spo2             1              0         0.004         50         100
Built-in bounds cover 20 vitals and labs (heart_rate, spo2, sbp, glucose,
creatinine, ph, wbc, and more). Add site-specific ranges with add_bounds().
Normalize units across sites
Multi-site studies routinely mix mg/dL and mmol/L for the same lab, or °F and °C
for temperature. UnitNormalizer detects non-standard units via a companion unit
column and converts in-place.
from clinops.preprocess import UnitNormalizer

# df has a "glucose" column and a "glucose_unit" column (mixed "mg/dL" / "mmol/L")
normalizer = UnitNormalizer(column_unit_map={"glucose": "glucose_unit"})
df = normalizer.transform(df)
# All glucose values now in mg/dL; glucose_unit column updated

print(normalizer.report())
#   column from_unit to_unit  n_converted
#  glucose    mmol/L   mg/dL          142
30 registered conversions covering glucose, creatinine, bilirubin, haemoglobin, calcium, temperature, weight, and height.
Harmonize ICD-9 and ICD-10 codes
MIMIC-III uses ICD-9, MIMIC-IV mixes both versions, and many real-world datasets
span the October 2015 transition. ICDMapper converts ICD-9-CM codes to ICD-10-CM
and adds chapter-level groupings for ML features.
from clinops.preprocess import ICDMapper

mapper = ICDMapper()

# Map a mixed-version DataFrame to ICD-10 in-place
df = mapper.harmonize(df, code_col="icd_code", version_col="icd_version")

# Add chapter-level grouping (e.g. "Diseases of the circulatory system")
df["chapter"] = mapper.chapter_series(df["icd_code"])

# Map a single code
mapper.map_code("4280")   # → "I509"
Ships with ~60 curated high-frequency mappings. Load the full CMS GEM file
(~72,000 mappings) with ICDMapper.from_gem_file(path).
clinops.temporal
Build temporal feature windows
from clinops.temporal import TemporalWindower, ImputationStrategy

windower = TemporalWindower(
    window_hours=24,
    step_hours=6,
    imputation=ImputationStrategy.FORWARD_FILL,
    min_observations=3,
)

windows = windower.fit_transform(
    df=charts,
    id_col="subject_id",
    time_col="charttime",
    feature_cols=["heart_rate", "spo2", "resp_rate", "map"],
)
# → DataFrame: subject_id | window_start | window_end | heart_rate | spo2 | ...
Long-format input (MIMIC native itemid × valuenum)
windows = windower.fit_transform(
    df=charts,
    id_col="subject_id",
    time_col="charttime",
    item_col="itemid",    # auto-pivots to wide format
    value_col="valuenum",
)
Add lag and rolling features
from clinops.temporal import LagFeatureBuilder

enriched = LagFeatureBuilder(
    lags=[1, 2, 4],
    rolling_windows=[4, 8],
    id_col="subject_id",
).fit_transform(windows)
# Adds: heart_rate_lag1, heart_rate_roll4_mean, heart_rate_roll4_std, ...
Align a cohort to an anchor event (e.g. ICU admission)
from clinops.temporal import CohortAligner

aligned = CohortAligner(
    anchor_col="intime",
    max_hours_before=0,
    max_hours_after=48,
).align(events_df=charts, anchor_df=stays)
# → filtered to 48h post-admission, with hours_from_anchor column
Imputation strategies
Clinical data has unique missingness patterns that standard ML windowing gets wrong.
clinops provides strategies tuned for clinical context:
| Strategy | Best for |
|---|---|
FORWARD_FILL |
Slowly-changing vitals — carry last observation forward |
BACKWARD_FILL |
Values recorded with lag |
LINEAR |
Continuous signals with regular sampling |
MEAN / MEDIAN |
Fit on training set, apply to test (no leakage) |
INDICATOR |
Adds {col}_missing binary column — lets model learn from missingness |
NONE |
Leave NaN in place |
from clinops.temporal import Imputer, ImputationStrategy

imputer = Imputer(ImputationStrategy.MEAN, per_patient=True, id_col="subject_id")
imputer.fit(train_windows)
test_windows = imputer.transform(test_windows)
clinops.split
Standard sklearn.train_test_split is wrong for clinical ML: it leaks future
observations into training, and splits patients across folds so the model
memorises patient-specific patterns rather than generalising.
Temporal split — no future leakage
from clinops.split import TemporalSplitter

result = TemporalSplitter(cutoff="2155-01-01", time_col="charttime").split(df)
# or auto-compute cutoff from the data:
result = TemporalSplitter(train_frac=0.8, time_col="charttime").split(df)

print(result.summary())
# Train: 38,400 rows (80.0%)
# Test:   9,600 rows (20.0%)
# cutoff: 2155-01-01 00:00:00
Patient-level split — no leakage across admissions
from clinops.split import PatientSplitter

result = PatientSplitter(id_col="subject_id", test_size=0.2).split(df)

# Guaranteed: no patient appears in both splits
assert not set(result.train["subject_id"]) & set(result.test["subject_id"])
Stratified patient split — preserves outcome rate
Critical for imbalanced clinical endpoints (in-hospital mortality is typically 5–15%). Stratifies on a binary outcome while respecting patient boundaries.
from clinops.split import StratifiedPatientSplitter

result = StratifiedPatientSplitter(
    id_col="subject_id",
    outcome_col="hospital_expire_flag",
    test_size=0.2,
).split(df)

print(result.summary())
# Train: 32,000 rows (80.0%)
# Test:   8,000 rows (20.0%)
# population_outcome_rate: 0.0821
# train_outcome_rate:      0.0819
# test_outcome_rate:       0.0826
Installation
Requires Python 3.12+.
pip install clinops           # core
pip install clinops[fhir]     # adds FHIR R4 loader
pip install clinops[gcp]      # adds GCS storage for clinops.orchestrate
pip install clinops[aws]      # adds S3 storage and Step Functions for clinops.orchestrate
pip install -e ".[dev]"       # development
Supported sources
| Source | Format |
|---|---|
| MIMIC-IV v2.0–v2.2 | CSV, CSV.GZ, Parquet |
| MIMIC-III v1.4 | CSV, CSV.GZ, Parquet |
| eICU-CRD v2.0 | CSV, CSV.GZ, Parquet |
| FHIR R4 | JSON Bundle, NDJSON |
| Flat files | CSV, CSV.GZ, Parquet |
Generative AI usage disclosure
This library was developed with assistance from Claude (Anthropic) as an AI pair-programming tool. Specifically, Claude was used for:
- Generating test cases — unit test drafts for edge cases (e.g., empty DataFrames, single-patient cohorts, missing unit columns), all reviewed and validated against real expected outputs
- Drafting docstrings — inline documentation for public methods, reviewed and corrected for accuracy by the author
- Iterating on error messages — improving the clarity of
ValueErrorandlogger.warningmessages
All generated code was reviewed, tested, and validated by the author prior to release.
Contributing
See CONTRIBUTING.md. Run pytest tests/ -v and
ruff check clinops/ before opening a PR.
Citation
@software{kasaraneni2026clinops,
  author  = {Kasaraneni, Chaitanya},
  title   = {clinops: Clinical ML Pipeline Toolkit},
  year    = {2026},
  url     = {https://github.com/chaitanyakasaraneni/clinops},
  version = {0.6.0}
}
A companion JOSS paper is in preparation.
License
Apache 2.0 — see LICENSE.
1 maintainer

Metadata
1 maintainer
Release files for clinops 0.6.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| clinops-0.6.0.tar.gz | 311.9 kB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| clinops-0.6.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 404.1 kB
Release files / clinops-0.6.0.tar.gz
| Download URL | clinops-0.6.0.tar.gz |
|---|---|
| Size | 311.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
db98bae6ab37290a0933237703c0cd0c0b6eb5f21bed8ece8a4975bbe39db17a
|
|
BLAKE2b-256 checksum How to use checksums |
7b6eea61e874ea8d9459c05a1e87bdec9338f79d74fa8dfc64242eddbd8c6b89
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Release files / clinops-0.6.0-py3-none-any.whl
| Download URL | clinops-0.6.0-py3-none-any.whl |
|---|---|
| Size | 92.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
093382e4be0f1acd1725e6d8bbf4c49e64e8bf7b806c669e192e8b0334ce566a
|
|
BLAKE2b-256 checksum How to use checksums |
01db86146e2b4d4cb67f64f9891ba5b3727d4299100ffe3620e1a6eca94e2ed6
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Security for clinops 0.6.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.














