
Codebase Brain MCP


An MCP server that gives AI assistants a cited, searchable memory of a
codebase, including its history. Point it at a local folder or a public git URL. Claude, Cursor or any MCP client
can then answer questions about the code with exact path:start-end citations.
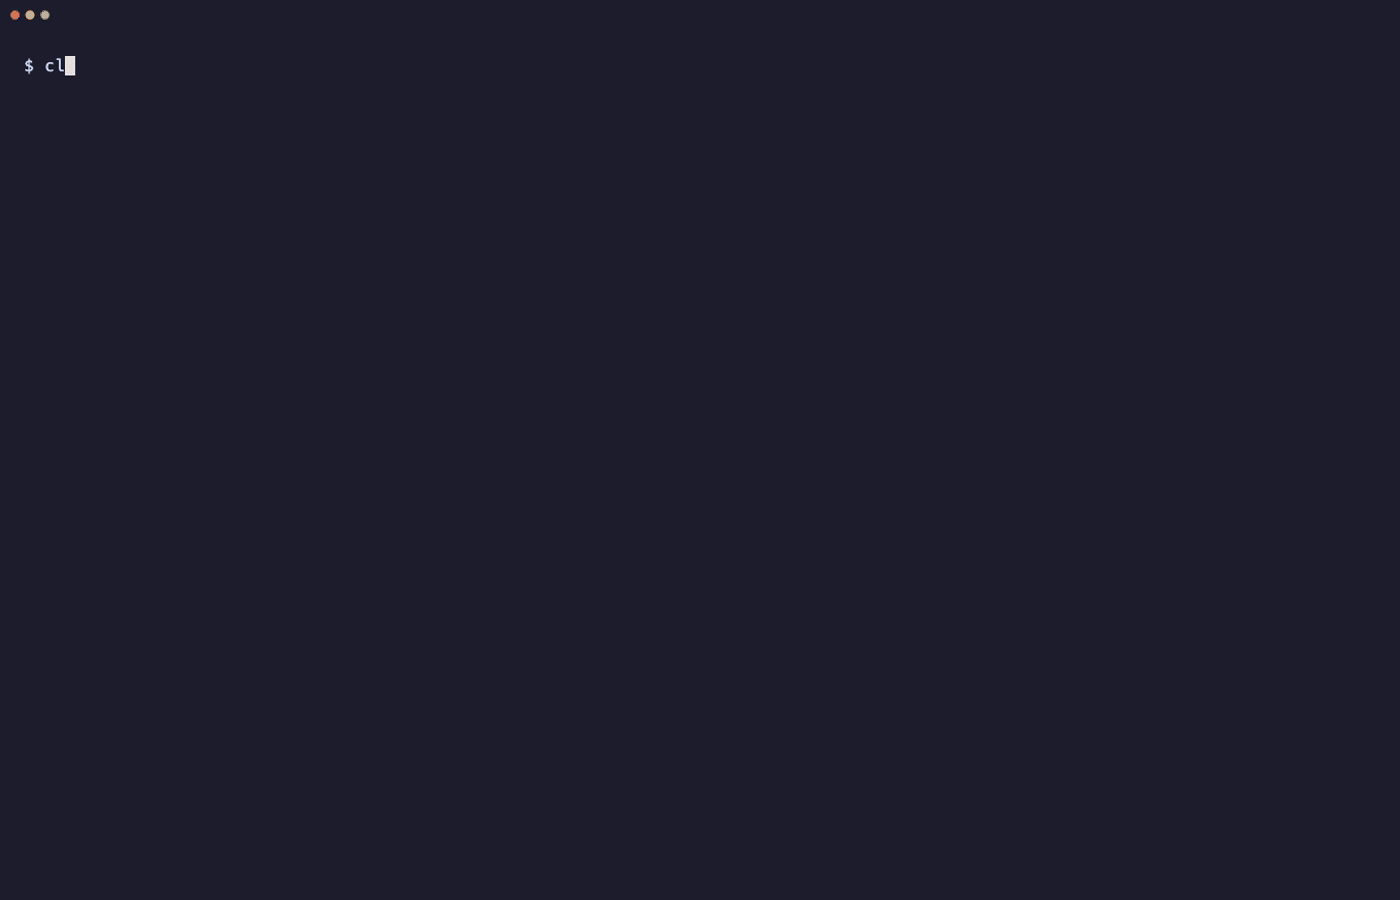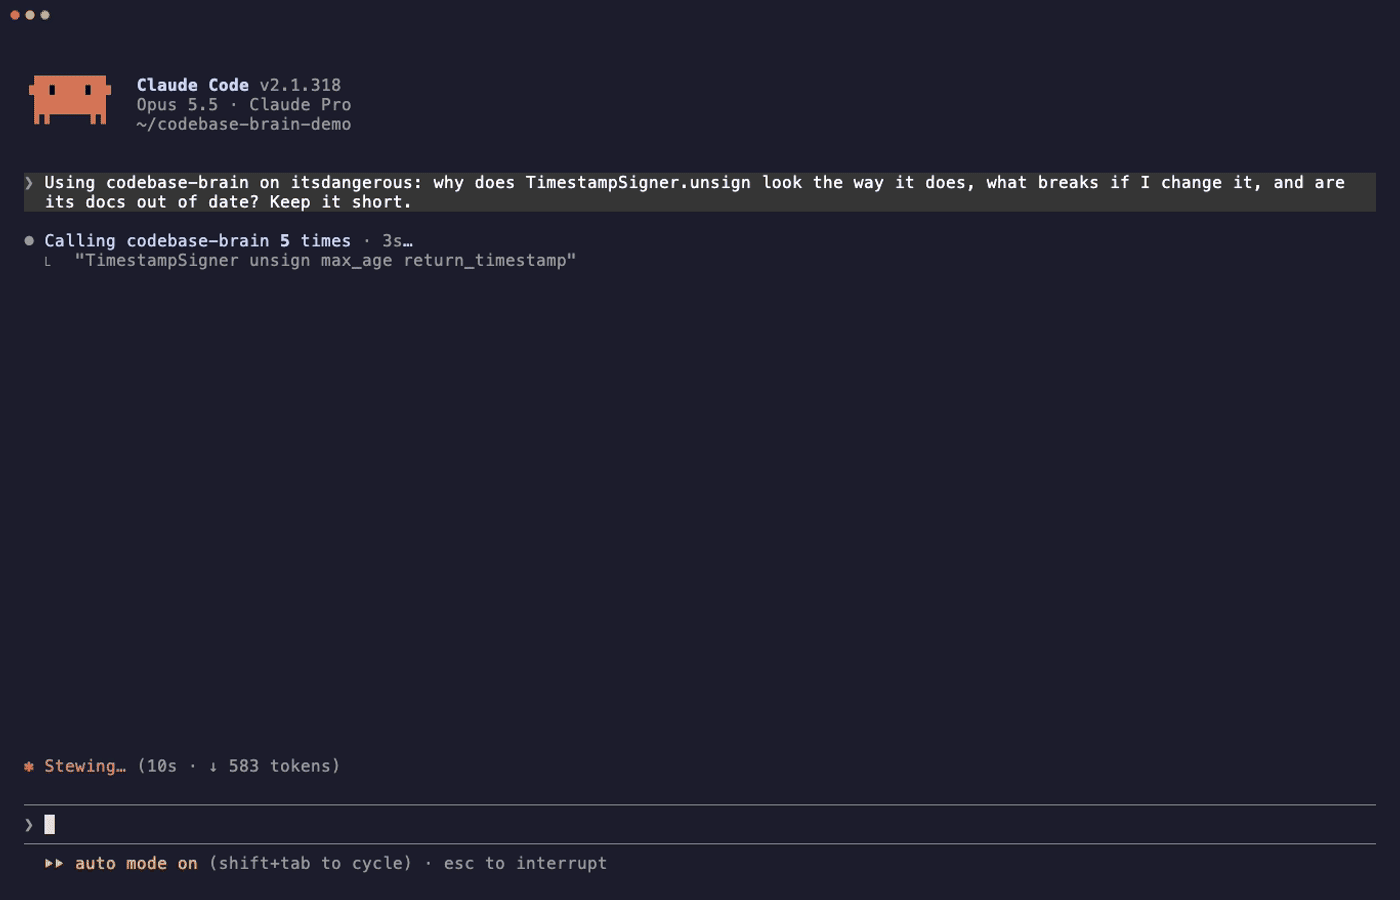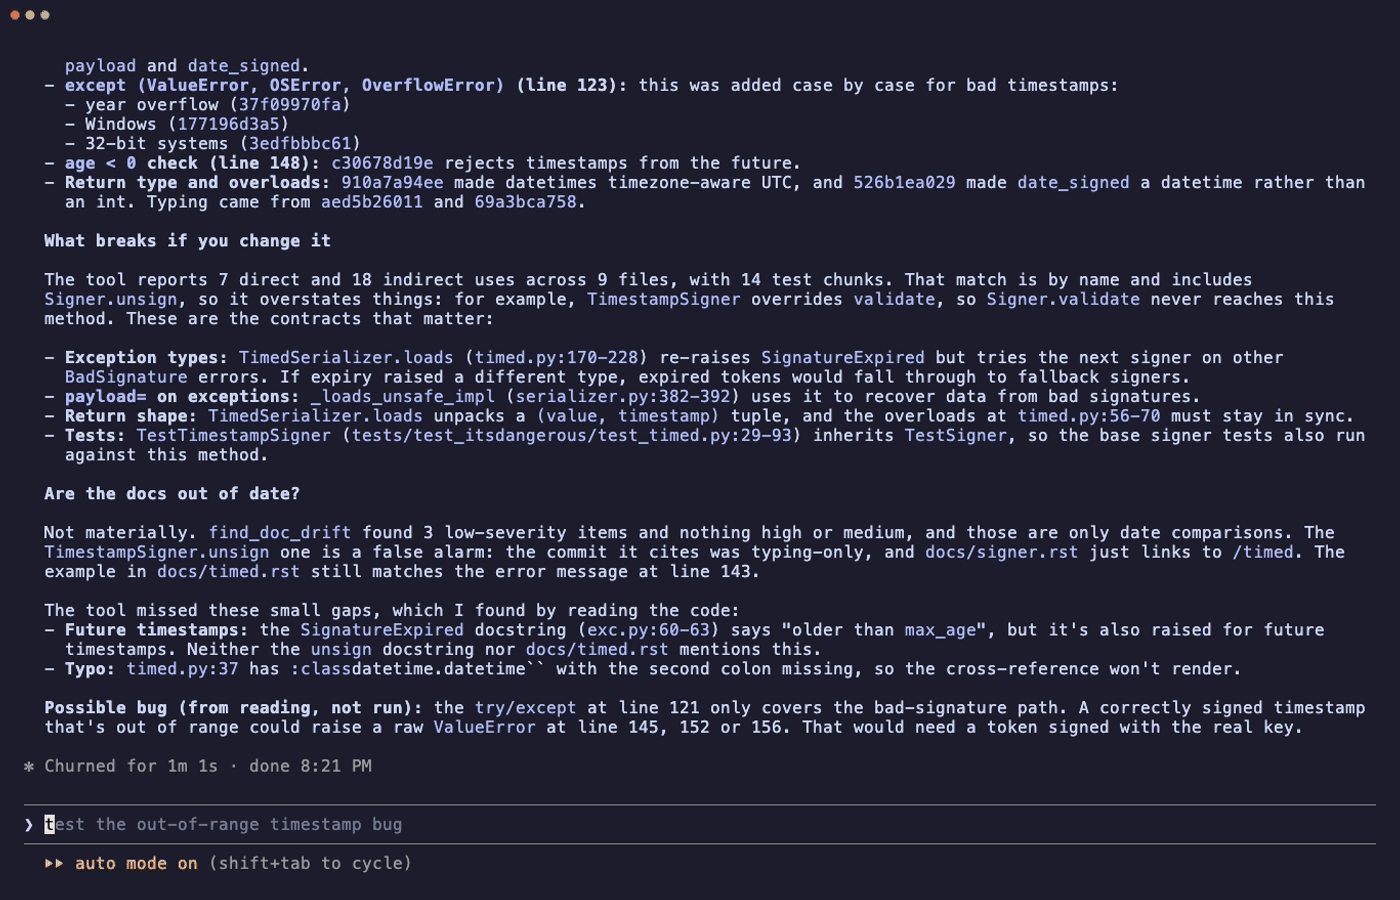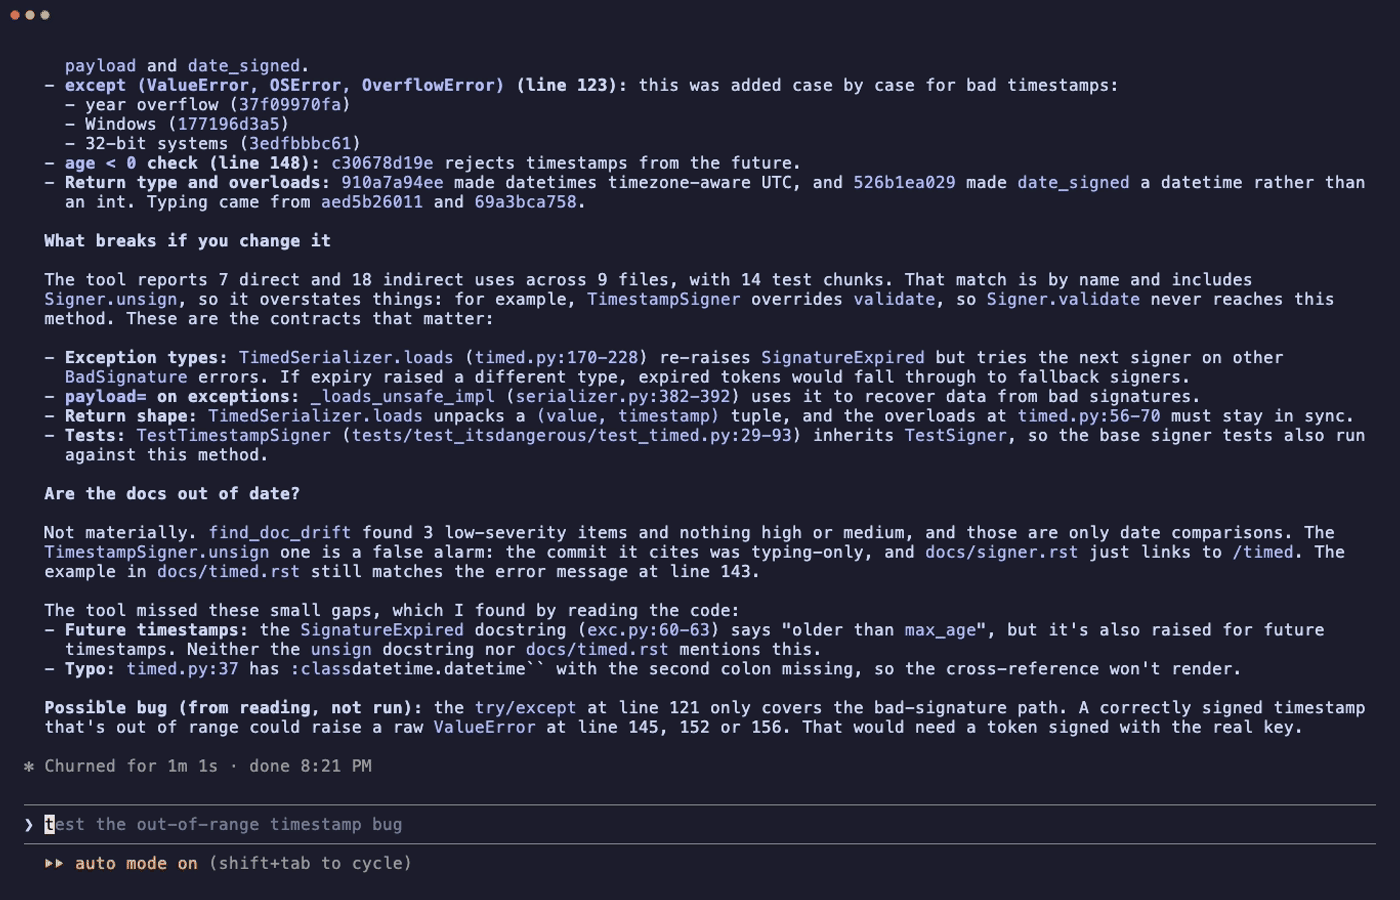
Claude Code asks why TimestampSigner.unsign looks the way it does, what breaks if it changes, and whether its
docs are current. Codebase Brain answers with commits, callers, tests and doc findings, all cited. (Waiting time
sped up.)
The problem
AI coding assistants are good at writing new code but struggle to understand code that already exists:
- They can't see the whole project. A real codebase has thousands of files. The assistant reads a few and guesses the rest, so it misses the function that matters or invents one that doesn't exist.
- You can't check their answers. "Expiry is handled in the auth module" is no use if you can't see where. Without file and line references, you have to trust the answer or re-read the code yourself.
- They don't know why code is the way it is. The code shows what it does. The reasons ("we added this check because it crashed on Windows") live in git history and pull requests, which assistants never read. So they "clean up" code that exists for a reason and bring old bugs back.
- They don't know what a change will break, or whether the documentation still matches the code.
- Many tools send your code to someone else's server to make it searchable.
What Codebase Brain gives you
A plug-in for any AI assistant that turns a codebase into something it can actually look things up in:
- Answers with proof. Every result points to the exact file and lines, and the assistant can open them.
- Search that understands code. It finds code whether you type the exact name (
calculate_invoice_total) or describe it in plain words ("how are invoices totalled?"). - The story behind the code. For any function, it shows every change made to it, who made it, why (from the commit message and pull request), and what the change was.
- What breaks if you change something. Everything that uses a function, directly or indirectly, and the tests that cover it.
- Out-of-date docs, found automatically. Documentation that mentions functions, files or settings that no longer exist, or shows examples that would no longer work.
- Private by design. Everything runs on your machine. No API keys, and your code never leaves your computer.
Why it's different (technical)
- Code-aware chunking. Python is split by function, class and method using the real syntax tree, Markdown by
heading. Each chunk knows its symbol (
TimestampSigner.unsign) and exact lines, so citations point at real code. - Hybrid retrieval. SQLite FTS5 BM25 (with
camelCase/snake_caseidentifier splitting) plus local embeddings, merged with reciprocal-rank fusion. Exact names and fuzzy questions both work. - Local and free. Embeddings run on your machine (
fastembed, ONNX). No API keys, and no code leaves your computer. - Incremental. Re-indexing only re-embeds files whose content changed. On a 42-file repo, a re-index with no changes takes about 2 seconds.
- History-aware.
explain_historyfollows a function's lines back through git (git log -L), shows who wrote the current lines, and links the pull requests behind each change. So agents can answer "why is it built this way?", not just "what does it do?". - Impact analysis.
impact_of_changelists everything that uses a function, directly and transitively, plus the tests that exercise it, before an agent changes anything. - Doc-drift detection.
find_doc_driftchecks Markdown and reStructuredText docs against the code. It finds files, functions, settings and flags that don't exist; examples passing parameters a function doesn't take; imports that would fail; and sections last edited long before the code they describe changed. Each finding cites the doc section and suggests a fix ("Was it renamed tocheckout_total?"). - Agent-friendly output. Structured tool results, read-only tool annotations, progress notifications while indexing, and clear error messages the model can act on.
Tools
| Tool | What it does |
|---|---|
index_repo(source, name?) |
Index a local path or an https:// git URL (shallow clone). Reports progress. |
ask_codebase(question, repo?, k?) |
The most relevant code and docs as cited sources, plus related commits, with instructions to answer only from them. |
search(query, repo?, k?, path_prefix?, kinds?) |
Raw hybrid search, filterable by path and chunk kind. |
explain_history(symbol? | path, start_line?, end_line?, repo?) |
Every commit that changed a function or line range, newest first, with the relevant diff, current authorship, and PR titles and descriptions (GitHub). |
search_history(query, repo?, k?) |
Find commits by what their messages say. |
impact_of_change(symbol, path?, depth?, repo?) |
Direct and indirect users of a function or class, and the tests involved. |
find_doc_drift(path_prefix?, check_history?, repo?) |
Documentation that no longer matches the code, by severity (high, medium, low). |
read_lines(path, start, end, repo?) |
Open the exact lines behind a citation. Refuses paths outside the repo. |
list_repos() |
What's indexed, at which commit, and in which languages. |
Also included: the resource brain://repos, and the prompt answer_with_citations.
Install
Codebase Brain runs on your own machine, so there's no server or account, and it's free. With uv:
# Claude Code
claude mcp add codebase-brain -- uvx codebase-brain-mcp

# Any MCP client (Claude Desktop, Cursor, ...): add this server to its config
{ "command": "uvx", "args": ["codebase-brain-mcp"] }
Quick start
uv sync
uv run codebase-brain index https://github.com/pallets/itsdangerous
uv run codebase-brain search "how is the signature timestamp checked for expiry"
0.0313  src/itsdangerous/timed.py:72-158  method TimestampSigner.unsign
0.0311  docs/timed.rst:1-28  code
0.0301  src/itsdangerous/timed.py:170-228  class TimedSerializer
Ask why it looks like that. explain_history(symbol="TimestampSigner.unsign") returns its line-by-line history:
src/itsdangerous/timed.py:72-158
  3edfbbbc 2022-03-24 handle OverflowError in timed unsign on 32-bit systems
  177196d3 2022-03-09 catch OSError on Windows
  37f09970 2022-03-08 catching year overflow ValueError
  c30678d1 2019-05-31 don't allow timestamps from the future
  910a7a94 2020-04-17 datetimes are timezone-aware utc
  ...
Use it from Claude Code
claude mcp add codebase-brain -- uv run --directory /path/to/codebase-brain-mcp codebase-brain
Run it as a remote server (Streamable HTTP)
export CODEBASE_BRAIN_TOKEN="$(python -c 'import secrets; print(secrets.token_urlsafe(32))')"
uv run codebase-brain serve --transport streamable-http --host 0.0.0.0 --port 8765
Clients connect to http://<host>:8765/mcp with Authorization: Bearer <token>. GET /healthz is open for load
balancers. Remote mode is locked down by default:
- No token, no public port. The server refuses to listen beyond localhost without a token of at least 24 characters. Tokens are compared in constant time.
- Remote clients can't read the server's disk. Only public
https://git URLs can be indexed, not local paths, unless you setCODEBASE_BRAIN_ALLOW_LOCAL_PATHS=1. - Big repos are refused above
CODEBASE_BRAIN_MAX_FILES(default 20,000), and every git command has a timeout. - DNS-rebinding protection is on for localhost, and for any hosts listed in
CODEBASE_BRAIN_ALLOWED_HOSTS.
Docker
docker build -t codebase-brain-mcp .
docker run -p 8765:8765 -e CODEBASE_BRAIN_TOKEN="$CODEBASE_BRAIN_TOKEN" -v brain-data:/data codebase-brain-mcp
The image runs as a non-root user and includes the embedding model, so it starts fast and needs no download at
runtime. It has a health check, and keeps indexes in the /data volume. Indexing uses about 1.2 GB of memory, so
give the container 2 GB.
Configuration
| Variable | Default | |
|---|---|---|
CODEBASE_BRAIN_HOME |
~/.codebase-brain |
Indexes and clones |
CODEBASE_BRAIN_EMBEDDER |
fastembed |
hash gives an offline, deterministic embedder (used in tests) |
CODEBASE_BRAIN_EMBED_MODEL |
BAAI/bge-small-en-v1.5 |
Any fastembed text model |
CODEBASE_BRAIN_MAX_FILE_BYTES |
512000 |
Larger files are skipped |
GITHUB_TOKEN |
unset | Optional. Raises GitHub's API rate limit for PR lookups |
CODEBASE_BRAIN_FETCH_PRS |
1 |
Set to 0 to never call the GitHub API |
CODEBASE_BRAIN_TOKEN |
unset | Bearer token for HTTP mode (required unless bound to localhost) |
CODEBASE_BRAIN_ALLOWED_HOSTS |
unset | Comma-separated Host values to accept (DNS-rebinding protection) |
CODEBASE_BRAIN_ALLOW_LOCAL_PATHS |
1 (stdio) / 0 (HTTP) |
Whether index_repo may read local directories |
CODEBASE_BRAIN_MAX_FILES |
20000 |
Refuse repos with more indexable files |
PORT |
8765 |
HTTP port (platforms such as Cloud Run set this) |
Doc drift, tested honestly
On a well-maintained project (itsdangerous), find_doc_drift reports no false alarms. It only reports three
"worth a look" sections whose docs date from 2020 while the code they describe changed in 2024–2025. On docs with
planted mistakes, it catches every one: a moved file, a renamed function (with the right suggestion), an unknown
setting and flag, a keyword argument the function doesn't take, and an import that would fail. Changelogs are skipped,
because they're supposed to mention removed things.
Evaluation
Does search actually put the right code in front of the model? codebase-brain eval answers that with a benchmark.
The benchmark has 32 questions about pallets/itsdangerous, pinned to
commit 672971d, each with the code or docs a good answer must come from. The questions are in
evals/datasets/itsdangerous.toml. They were written by reading the code
before any results were measured, and haven't been changed since.
| Mode | Hit@1 | Hit@3 | Hit@5 | Hit@10 | MRR@10 (95% CI) | nDCG@10 | p50 latency |
|---|---|---|---|---|---|---|---|
| hybrid (default) | 56% | 88% | 88% | 91% | 0.697 (0.56–0.82) | 0.735 | 5 ms |
| keyword only (BM25) | 56% | 75% | 78% | 84% | 0.667 (0.52–0.80) | 0.699 | <1 ms |
| vector only (bge-small) | 56% | 72% | 75% | 94% | 0.658 (0.51–0.80) | 0.701 | 4 ms |
| Hit@5 by question type | describes behaviour (14) | about the docs (7) | names the code (11) |
|---|---|---|---|
| hybrid | 71% | 100% | 100% |
| keyword only | 64% | 71% | 100% |
| vector only | 57% | 71% | 100% |
What this shows:
- Hybrid finds a right answer in the top 3 for 88% of questions, against 75% and 72% for either method alone. The gain comes from questions written in plain words and questions about the docs. When the question names the code, every mode finds it.
- It's honest about uncertainty. With 32 questions, the confidence intervals for MRR overlap, so hybrid is better on this set but not yet proven in general. Per question, hybrid beats keyword-only on 8 questions and loses on 4.
- It has known misses. Four questions describing behaviour in very different words from the code don't reach
the top 5. They're listed in
evals/results/itsdangerous.mdand are the next thing to improve. A larger, held-out question set will come first, so any tuning isn't fitted to these 32.
Reproduce it (the first run downloads the repo and the embedding model):
uv run codebase-brain eval evals/datasets/itsdangerous.toml --out evals/results
How it's measured:
- Hit@k: a relevant result is in the top k.
- MRR: 1 / rank of the first relevant result.
- nDCG@10: each target is credited once, so duplicate chunks don't inflate the score.
- Confidence intervals: 95% bootstrap over questions, seeded.
- Relevance: a result is relevant if it's in the target file and, when the target names a symbol, is that symbol or one of its methods.
- Dataset rot: the harness fails if a target no longer exists at the pinned commit.
How it works
source ─► resolve (local dir / shallow https clone) ─► list files (.gitignore-aware, skips binaries and lockfiles)
       ─► chunk (ast / headings / line windows) ─► embed (fastembed) ─► SQLite: chunks + vectors + FTS5
query  ─► BM25 top 50 ┐
       ─► vector top 50 ┴─► reciprocal-rank fusion ─► filters ─► cited sources
Security
- Clones are blobless (
--filter=blob:none): full history, with file contents fetched only when needed. - Commit authors are shown by name only; email addresses are never stored or returned.
- Only
https://clone URLs are accepted. Git runs withGIT_ALLOW_PROTOCOL=https:fileand no terminal prompts. read_linesresolves paths and refuses anything outside the indexed repository.- Repo names are validated, so they can't escape the index directory.
- All query tools are marked read-only.
- In HTTP mode: a required bearer token (constant-time check), git URLs only, repo size limits, DNS-rebinding protection, and a non-root container.
Development
uv run pytest           # 54 tests, offline (hash embedder, temporary git repos, in-process MCP client)
uv run ruff check .     # lint
uv run ruff format .    # format
uv run pyright          # types
Roadmap
- Git history and PR discussions:
explain_history,search_history - Symbol references and transitive dependents:
impact_of_change -
find_doc_drift: Markdown and reStructuredText, signatures, imports, settings, flags, staleness - tree-sitter chunking for more languages
- Retrieval evals with confidence intervals (
codebase-brain eval) - Larger held-out eval set, then retrieval tuning (reranking, query expansion)
- Streamable HTTP with bearer-token auth, Docker image
- Hosted demo, PyPI package, MCP Registry listing
- OpenTelemetry tracing
1 maintainer

Metadata
1 maintainer
Release files for codebase-brain-mcp 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| codebase_brain_mcp-0.1.0.tar.gz | 44.6 kB | With provenance | Details for codebase_brain_mcp-0.1.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| codebase_brain_mcp-0.1.0-py3-none-any.whl | Python 3 | none | any | Details for codebase_brain_mcp-0.1.0-py3-none-any.whl |
Total release size: 94.7 kB
Release files / codebase_brain_mcp-0.1.0.tar.gz
| Download URL | codebase_brain_mcp-0.1.0.tar.gz |
|---|---|
| Size | 44.6 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
04fd92ed4c3a0dfb35e26f13010bfb3190b755c29e6c3b1cc2dd19d9230296be
|
|
BLAKE2b-256 checksum How to use checksums |
7b5c84c63061fda40b6b731ac9e3279eccf846ff5f8642f73908a107face76f1
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.12.8
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 6, 2026.
Transparency logRelease files / codebase_brain_mcp-0.1.0-py3-none-any.whl
| Download URL | codebase_brain_mcp-0.1.0-py3-none-any.whl |
|---|---|
| Size | 50.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
b8f29f9efbaff1f48292df5e5ca61cc90df362930791c2c49f9cc650f895560e
|
|
BLAKE2b-256 checksum How to use checksums |
babcfbc0955544486879a407f89f5d738526a18c6585dc528644bf14acd787ac
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.12.8
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 6, 2026.
Transparency logSecurity for codebase-brain-mcp 0.1.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
Both files in this release have been uploaded with provenance metadata.
Attestation for codebase_brain_mcp-0.1.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 6, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














