
ComicFury Scraper
A powerful command-line tool to scrape and download comics from ComicFury.com, creating neatly organized CBZ files for offline reading.
Features
- Scrape comic chapters and pages from ComicFury.com
- Multi-threaded downloading for improved performance
- Automatic CBZ file creation with proper ordering
- Simple command-line interface with multiple options
- Support for both URL and comic ID input methods
- Configurable output directories
- Use existing JSON files for faster downloads without re-scraping
Installation
Prerequisites
- Python 3.9 or higher
- Internet connection
Dependencies
- requests
- beautifulsoup4
- argparse
- concurrent.futures (standard library)
Installing
Method 1: From python code
- Clone this repository or download the source code:
git clone https://github.com/yourusername/ComicsInfiniteScroll.git
cd ComicsInfiniteScroll
- Install the required dependencies:
pip install -r requirements.txt
cd src
- To use you have to execute following command in terminal:
python cli.py
Method 2: From github releases
-
Download the executable at the release page
-
To use you have to execute following command in terminal:
comicfuryscraper.exe
Method 3: From pip install
- Install pip package
pip install comicfuryscraper
- To use you have to execute following command in terminal:
comicfuryscraper
Usage
Basic Usage
Get the comic ID from the profile page
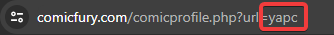
Then execute (depending on how you installed it):
python cli.py -i COMIC_ID -d
OR
comicfuryscraper.exe -i COMIC_ID -d
OR
comicfuryscraper -i COMIC_ID -d
Command Line Arguments
| Argument | Description |
|---|---|
-u, --url |
URL of the webpage to scrape |
-i, --id |
ID of the comic to scrape (alternative to URL) |
-t, --max-threads |
Maximum number of threads to use (default: 4) |
-d, --download |
Download the comic and create CBZ files |
-o, --output |
Output directory for downloaded files |
-v, --verbose |
Enable verbose output |
-j, --json |
Path to a JSON file with chapter data (skips scraping) |
Examples
- Scrape comic information without downloading:
python cli.py -i yourcomicid
This will generate a yourcomicid-chapters.json file with all chapters and pages information.
- Download a comic using its ID and save to a specific folder:
python cli.py -i yourcomicid -d -o "My Comics/ComicName"
- Download a comic using its URL with verbose output:
python cli.py -u "https://comicfury.com/comicprofile.php?url=yourcomicid" -d -v
- Increase download speed by using more threads:
python cli.py -i yourcomicid -d -t 8
- Use a previously generated JSON file to download without scraping:
python cli.py -j yourcomicid-chapters.json -d
- Download a comic using an existing JSON file and save to a specific directory:
python cli.py -j yourcomicid-chapters.json -d -o "My Comics/ComicName"
How It Works
- The scraper first checks if a JSON file with chapter data exists
- If specified with
-jflag, it uses that file - Otherwise, it looks for a default file named
[comic-id]-chapters.json
- If specified with
- If no JSON file is found, it scrapes all chapters from the comic's archive page
- For each chapter, it finds all pages and their image URLs
- When downloading, it creates a temporary directory for each chapter
- Images are downloaded with proper ordering (001.jpg, 002.jpg, etc.)
- A CBZ file is created for each chapter with numbered prefixes for proper ordering
- Temporary directories are cleaned up automatically
Output
Downloaded comics are saved as CBZ files in the specified output directory (or a directory named after the comic ID by default). Files are named with numerical prefixes to ensure proper ordering, for example:
01_Chapter_Name.cbz
02_Another_Chapter.cbz
etc...
Limitations
- Only works on Comic With Infinite Scroll if comic has infinite scroll disabled, please use ComicFury-Scrape

License
Contributing
Contributions, issues, and feature requests are welcome!
1 maintainer

Metadata
1 maintainer
Release files for comicfuryscraper 1.0.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| comicfuryscraper-1.0.1.tar.gz | 8.0 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| comicfuryscraper-1.0.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 16.9 kB
Release files / comicfuryscraper-1.0.1.tar.gz
| Download URL | comicfuryscraper-1.0.1.tar.gz |
|---|---|
| Size | 8.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
240d002726f9d32c51f710e462c4574e6c8cdf0f8e22f439d6991aaf8add1e7b
|
|
BLAKE2b-256 checksum How to use checksums |
973728a6ec7a964aaa65e44b26754d5939721ed3d79ccc1672101ba7b08f6fa1
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.1.0 CPython/3.12.9
|
Release files / comicfuryscraper-1.0.1-py3-none-any.whl
| Download URL | comicfuryscraper-1.0.1-py3-none-any.whl |
|---|---|
| Size | 8.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
1349f5803de8156ebb5b7e907e252678d7758fac0a91e13ba5219fd3759cb2b1
|
|
BLAKE2b-256 checksum How to use checksums |
03b2ff30b8071ebaafcfb19e8fd5e476ad6d9c9bbe0aaeca27c926dc6290afb6
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.1.0 CPython/3.12.9
|














