
Concise Concepts
When wanting to apply NER to concise concepts, it is really easy to come up with examples, but pretty difficult to train an entire pipeline. Concise Concepts uses few-shot NER based on word embedding similarity to get you going with easy! Now with entity scoring!


Usage
This library defines matching patterns based on the most similar words found in each group, which are used to fill a spaCy EntityRuler. To better understand the rule definition, I recommend playing around with the spaCy Rule-based Matcher Explorer.
Tutorials
-
TechVizTheDataScienceGuy created a nice tutorial on how to use it.
The section Matching Pattern Rules expands on the construction, analysis and customization of these matching patterns.
Install
pip install concise-concepts
Quickstart
Take a look at the configuration section for more info.
Spacy Pipeline Component
Note that, custom embedding models are passed via model_path.
import spacy
from spacy import displacy

import concise_concepts

data = {
    "fruit": ["apple", "pear", "orange"],
    "vegetable": ["broccoli", "spinach", "tomato"],
    "meat": ['beef', 'pork', 'turkey', 'duck']
}

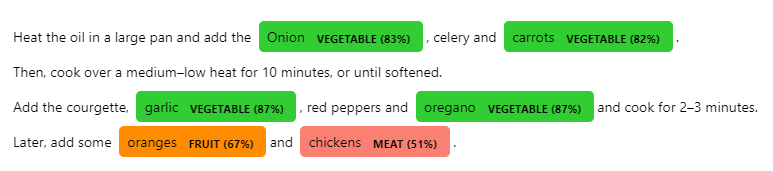
text = """
    Heat the oil in a large pan and add the Onion, celery and carrots.
    Then, cook over a medium–low heat for 10 minutes, or until softened.
    Add the courgette, garlic, red peppers and oregano and cook for 2–3 minutes.
    Later, add some oranges and chickens. """

nlp = spacy.load("en_core_web_md", disable=["ner"])

nlp.add_pipe(
    "concise_concepts",
    config={
        "data": data,
        "ent_score": True,  # Entity Scoring section
        "verbose": True,
        "exclude_pos": ["VERB", "AUX"],
        "exclude_dep": ["DOBJ", "PCOMP"],
        "include_compound_words": False,
        "json_path": "./fruitful_patterns.json",
        "topn": (100,500,300)
    },
)
doc = nlp(text)

options = {
    "colors": {"fruit": "darkorange", "vegetable": "limegreen", "meat": "salmon"},
    "ents": ["fruit", "vegetable", "meat"],
}

ents = doc.ents
for ent in ents:
    new_label = f"{ent.label_} ({ent._.ent_score:.0%})"
    options["colors"][new_label] = options["colors"].get(ent.label_.lower(), None)
    options["ents"].append(new_label)
    ent.label_ = new_label
doc.ents = ents

displacy.render(doc, style="ent", options=options)
Standalone
This might be useful when iterating over few_shot training data when not wanting to reload larger models continuously.
Note that, custom embedding models are passed via model.
import gensim
import spacy

from concise_concepts import Conceptualizer

model = gensim.downloader.load("fasttext-wiki-news-subwords-300")
nlp = spacy.load("en_core_web_sm")
data = {
    "disease": ["cancer", "diabetes", "heart disease", "influenza", "pneumonia"],
    "symptom": ["headache", "fever", "cough", "nausea", "vomiting", "diarrhea"],
}
conceptualizer = Conceptualizer(nlp, data, model)
conceptualizer.nlp("I have a headache and a fever.").ents

data = {
    "disease": ["cancer", "diabetes"],
    "symptom": ["headache", "fever"],
}
conceptualizer = Conceptualizer(nlp, data, model)
conceptualizer.nlp("I have a headache and a fever.").ents
Configuration
Matching Pattern Rules
A general introduction about the usage of matching patterns in the usage section.
Customizing Matching Pattern Rules
Even though the baseline parameters provide a decent result, the construction of these matching rules can be customized via the config passed to the spaCy pipeline.
exclude_pos: A list of POS tags to be excluded from the rule-based match.exclude_dep: A list of dependencies to be excluded from the rule-based match.include_compound_words: If True, it will include compound words in the entity. For example, if the entity is "New York", it will also include "New York City" as an entity.case_sensitive: Whether to match the case of the words in the text.
Analyze Matching Pattern Rules
To motivate actually looking at the data and support interpretability, the matching patterns that have been generated are stored as ./main_patterns.json. This behavior can be changed by using the json_path variable via the config passed to the spaCy pipeline.
Fuzzy matching using spaczz
fuzzy: A boolean value that determines whether to use fuzzy matching
data = {
    "fruit": ["apple", "pear", "orange"],
    "vegetable": ["broccoli", "spinach", "tomato"],
    "meat": ["beef", "pork", "fish", "lamb"]
}

nlp.add_pipe("concise_concepts", config={"data": data, "fuzzy": True})
Most Similar Word Expansion
topn: Use a specific number of words to expand over.
data = {
    "fruit": ["apple", "pear", "orange"],
    "vegetable": ["broccoli", "spinach", "tomato"],
    "meat": ["beef", "pork", "fish", "lamb"]
}

topn = [50, 50, 150]

assert len(topn) == len

nlp.add_pipe("concise_concepts", config={"data": data, "topn": topn})
Entity Scoring
ent_score: Use embedding based word similarity to score entities against their groups
import spacy
import concise_concepts

data = {
    "ORG": ["Google", "Apple", "Amazon"],
    "GPE": ["Netherlands", "France", "China"],
}

text = """Sony was founded in Japan."""

nlp = spacy.load("en_core_web_lg")
nlp.add_pipe("concise_concepts", config={"data": data, "ent_score": True, "case_sensitive": True})
doc = nlp(text)

print([(ent.text, ent.label_, ent._.ent_score) for ent in doc.ents])
# output
#
# [('Sony', 'ORG', 0.5207586), ('Japan', 'GPE', 0.7371268)]
Custom Embedding Models
model_path: Use customsense2vec.Sense2Vec,gensim.Word2vecgensim.FastText, orgensim.KeyedVectors, or a pretrained model from gensim library or a custom model path. For using asense2vec.Sense2Vectake a look here.model: within standalone usage, it is possible to pass these models directly.
data = {
    "fruit": ["apple", "pear", "orange"],
    "vegetable": ["broccoli", "spinach", "tomato"],
    "meat": ["beef", "pork", "fish", "lamb"]
}

# model from https://radimrehurek.com/gensim/downloader.html or path to local file
model_path = "glove-wiki-gigaword-300"

nlp.add_pipe("concise_concepts", config={"data": data, "model_path": model_path})
2 maintainers


Metadata
2 maintainers
Release files for concise-concepts 0.8.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| concise-concepts-0.8.1.tar.gz | 16.2 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| concise_concepts-0.8.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 31.8 kB
Release files / concise-concepts-0.8.1.tar.gz
| Download URL | concise-concepts-0.8.1.tar.gz |
|---|---|
| Size | 16.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
ada3d42efb94f58cc9dd0a12de81a5034a91bb030681ca641730ae5d9179fdae
|
|
BLAKE2b-256 checksum How to use checksums |
3b5351e162b39416ede8847622343aac98c537822011c657e1ec63130dcfcbc4
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
poetry/1.2.1 CPython/3.10.11 Darwin/22.5.0
|
Release files / concise_concepts-0.8.1-py3-none-any.whl
| Download URL | concise_concepts-0.8.1-py3-none-any.whl |
|---|---|
| Size | 15.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
42fa5704b44c278da70258f689d92305e07cf4a40d0f7c7c54891eaac0d729bc
|
|
BLAKE2b-256 checksum How to use checksums |
4def3e226225eebbec7923b76e353baae875a29e9892f98681c25aacc0840596
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
poetry/1.2.1 CPython/3.10.11 Darwin/22.5.0
|














