
convene



convene runs the Claude Code you are already logged into as a local inference layer for Python: named experts with cached system prompts, multi-turn sessions, bounded concurrency, and a ledger of what every call cost.
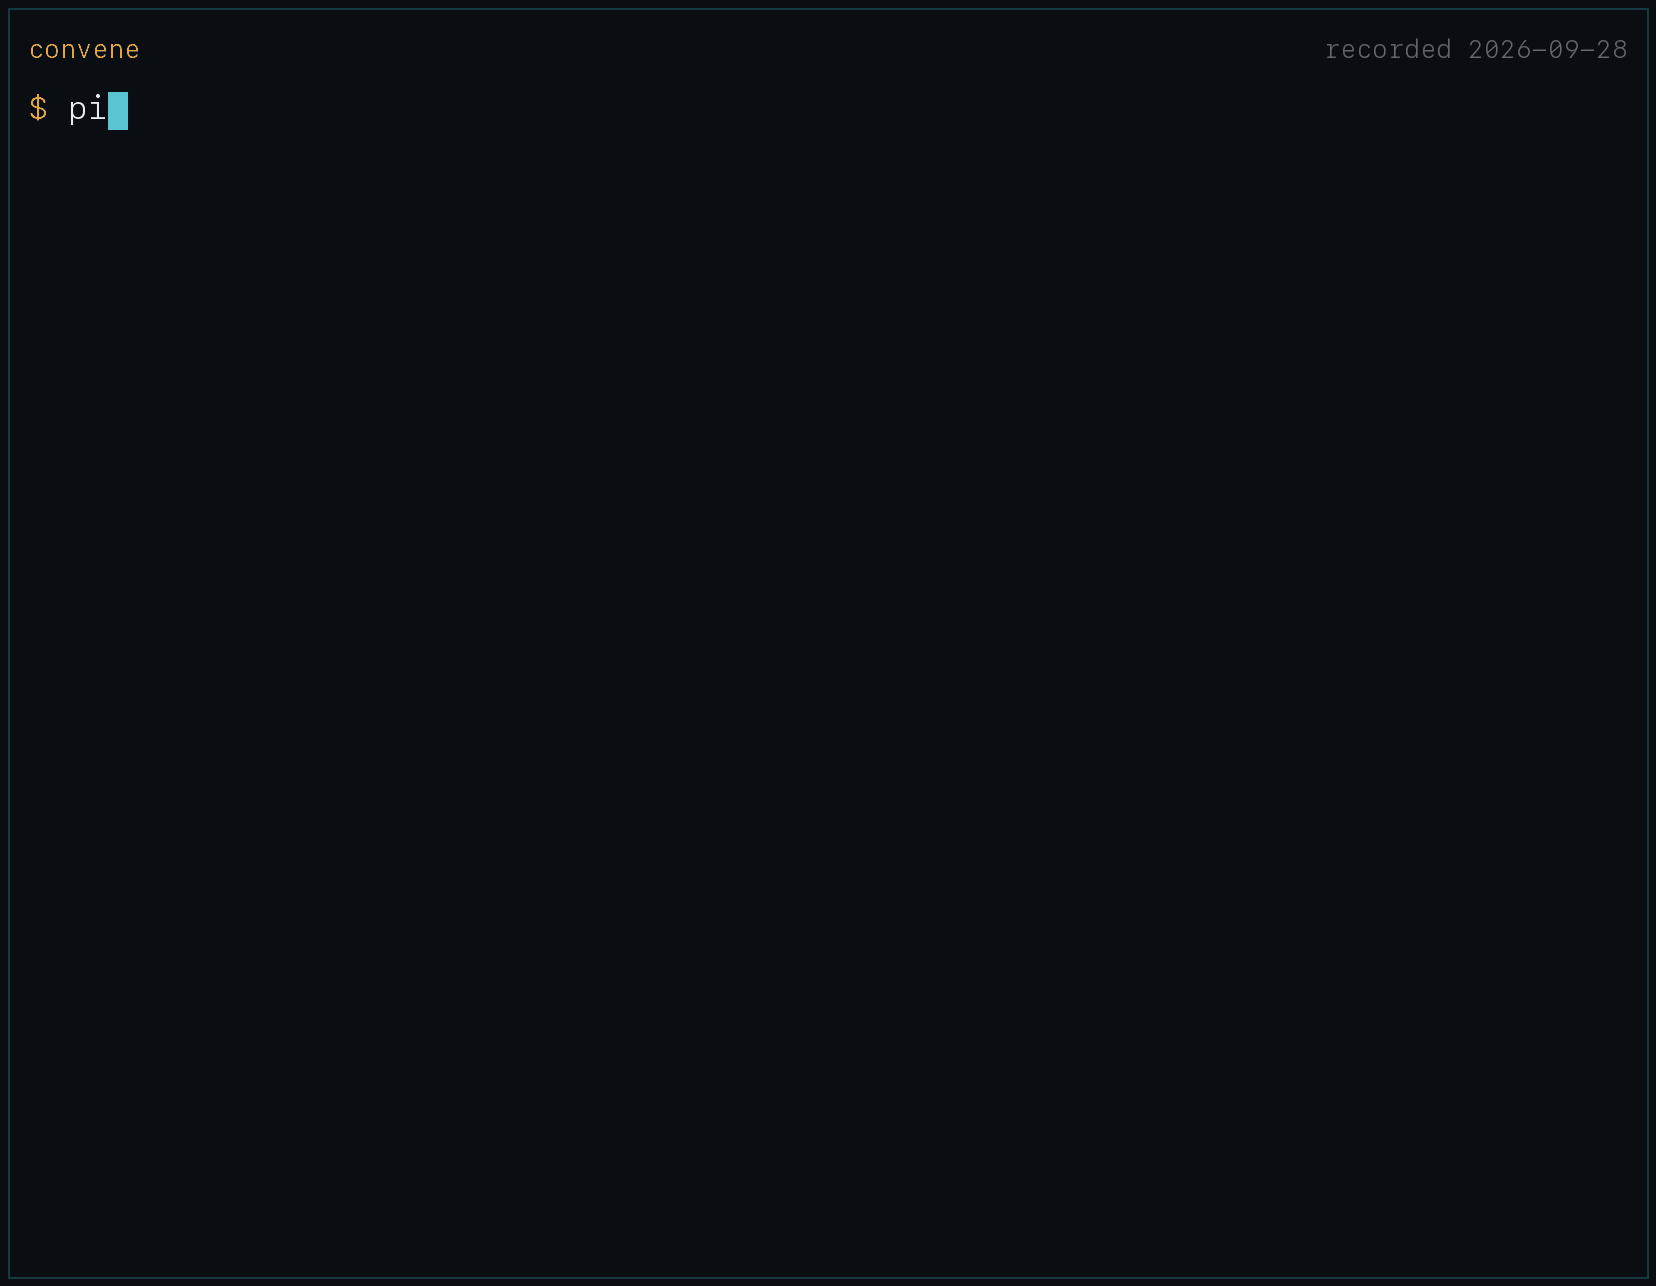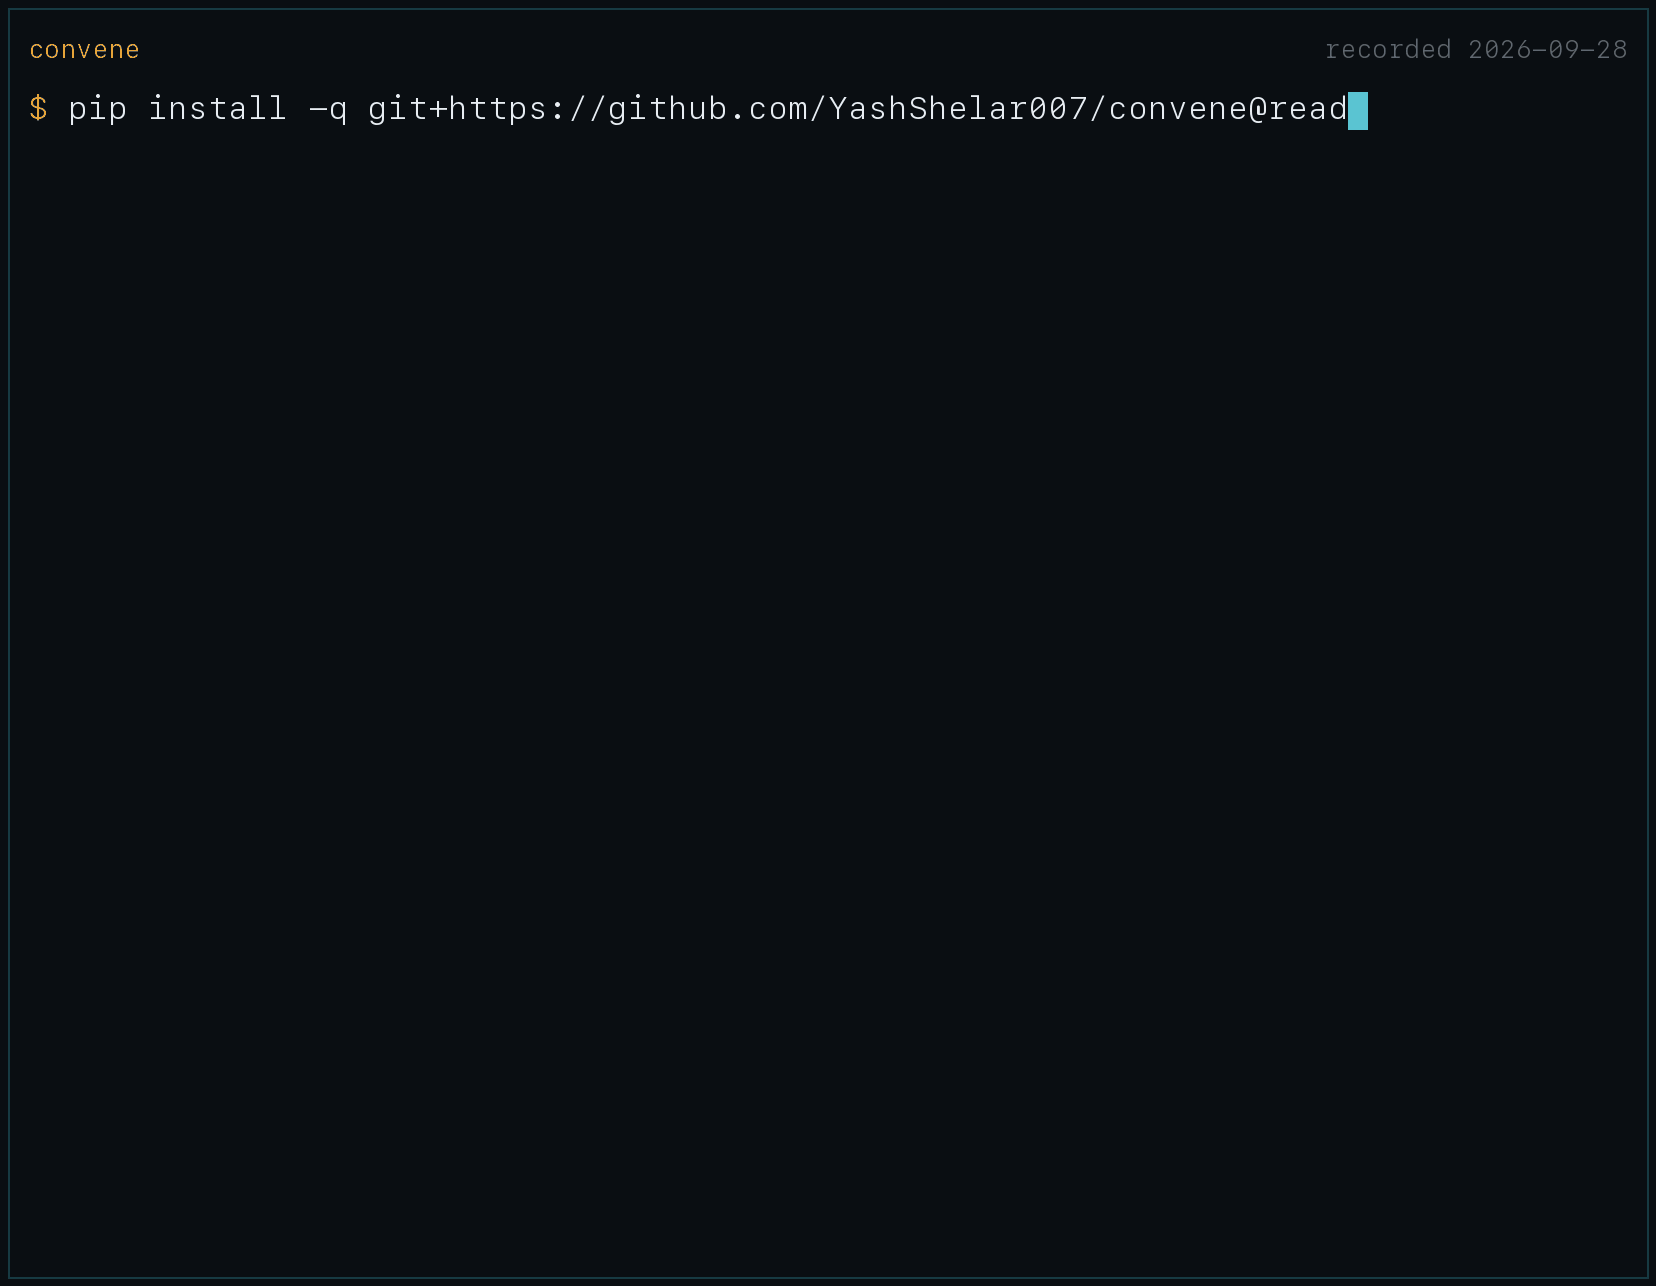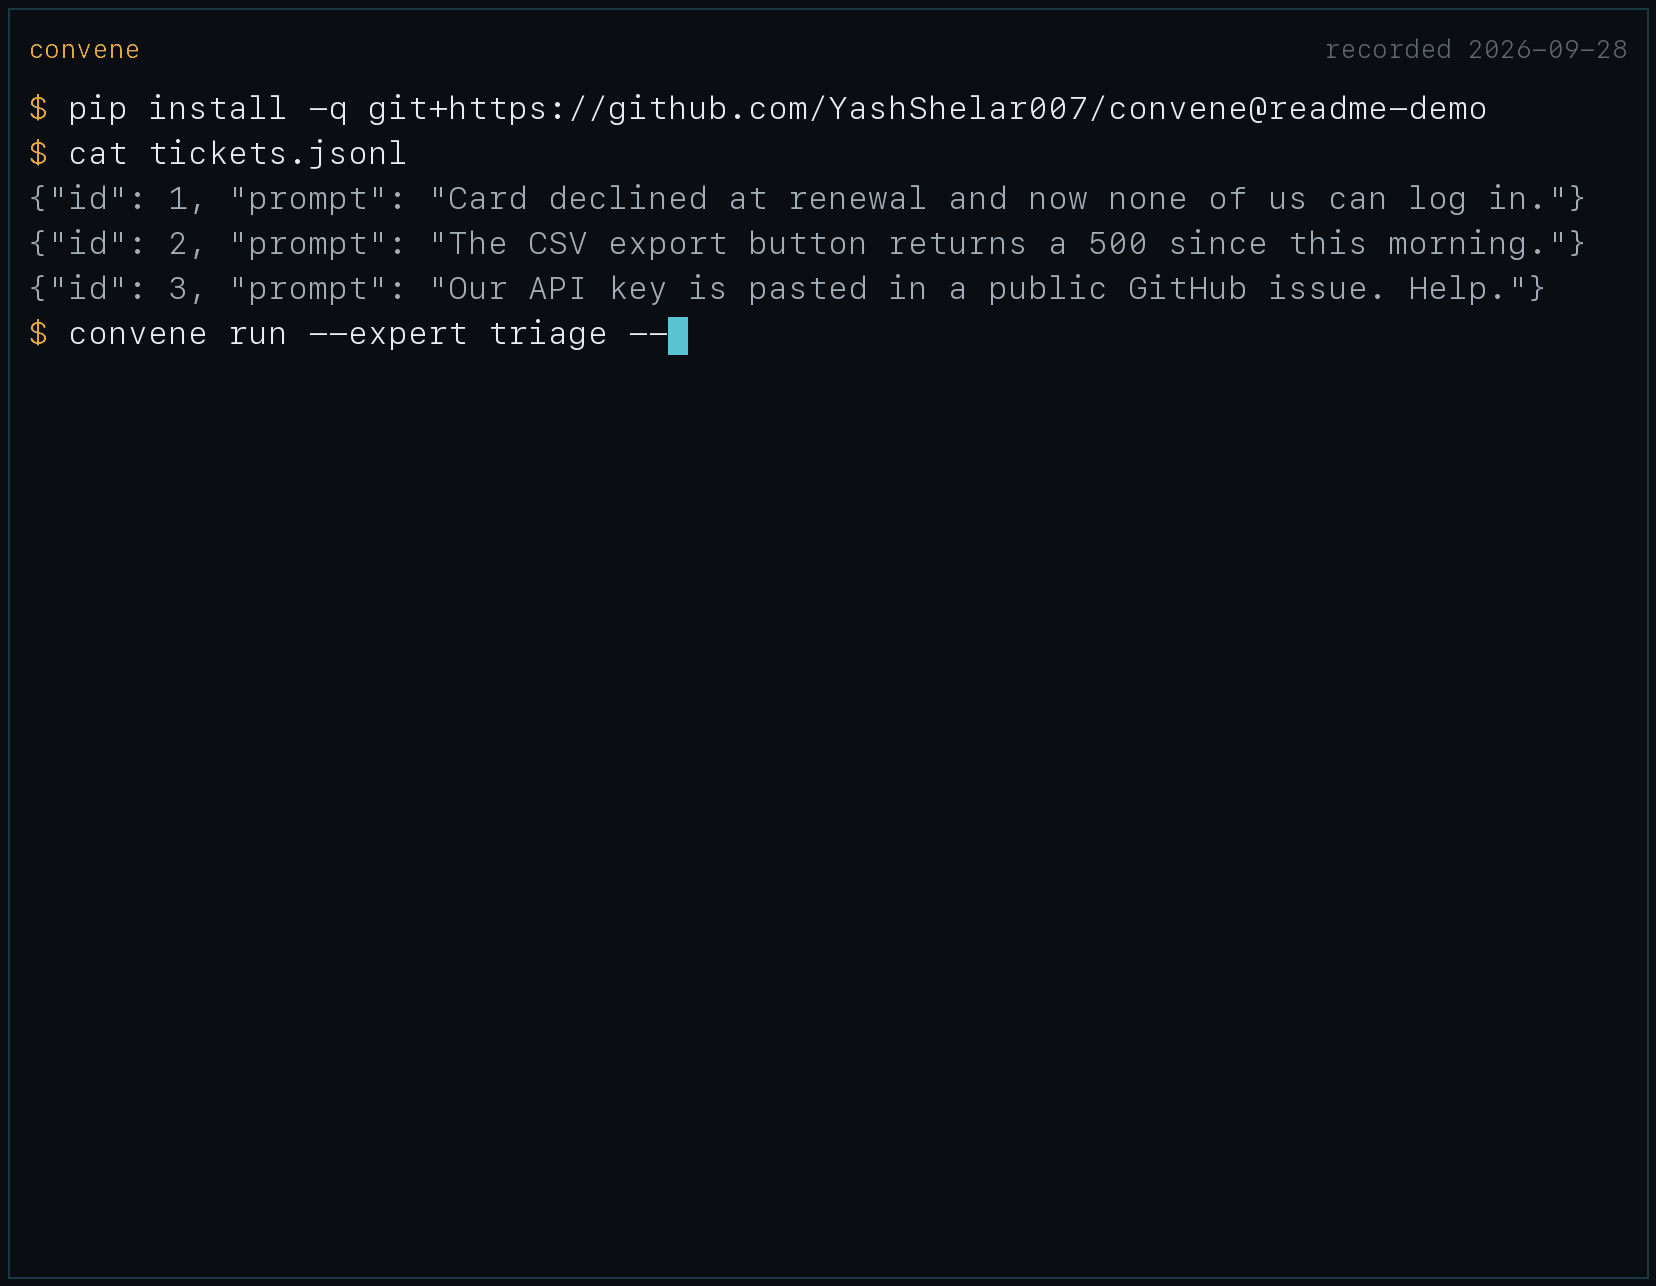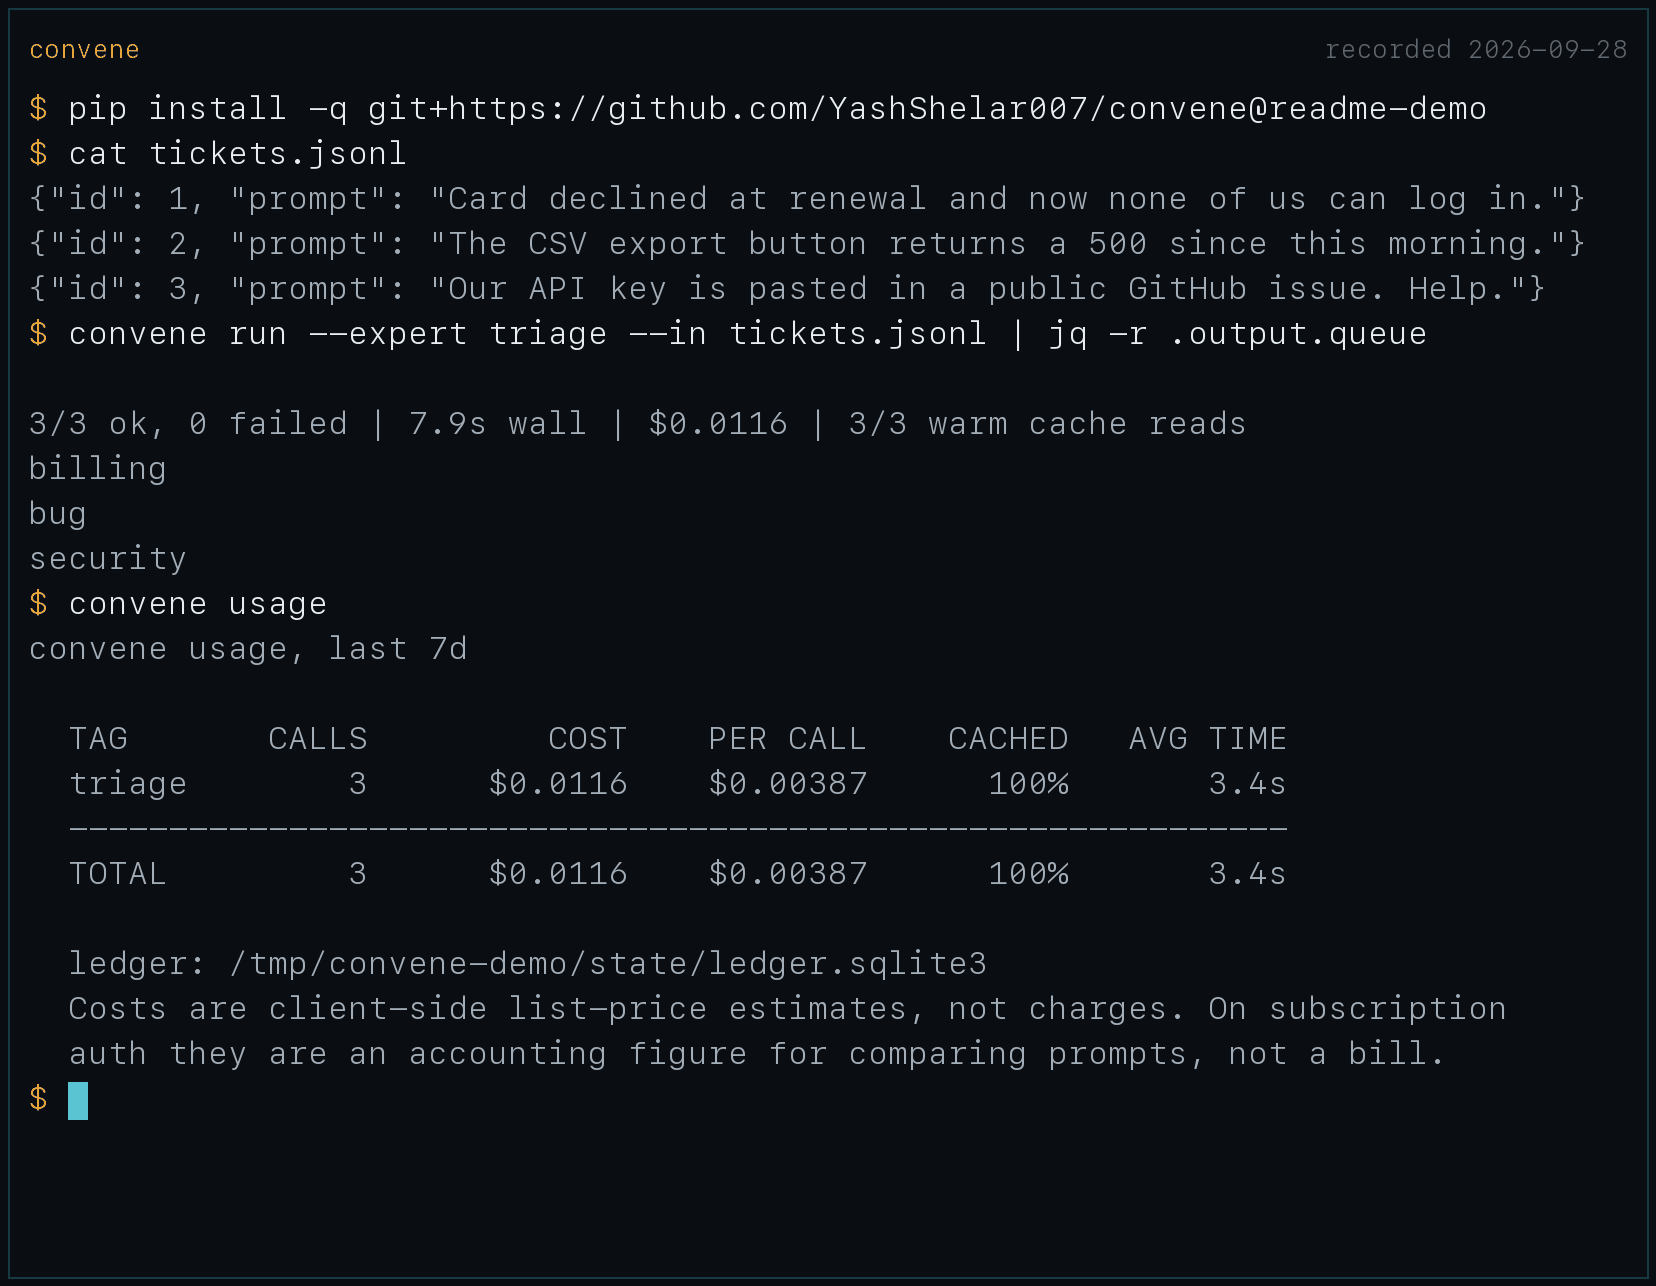
Three real calls against Claude Code 2.1.273, recorded 2026-09-28 from source ahead of the next PyPI release. All three read a warm cache because an earlier take had created it minutes before. Pauses longer than 1.5s are cut to 1.5s; every time and cost on screen is what convene printed. MP4, raw recording, re-record it.
Install
pip install convene
Python 3.11+, zero dependencies. The one requirement is a Claude Code install you have already logged into.
Quickstart
The demo above, on your machine:
convene doctor    # which account pays, confirmed with one live call
curl -sO https://raw.githubusercontent.com/YashShelar007/convene/develop/examples/experts.toml
echo '{"id": 1, "prompt": "Card declined at renewal and now none of us can log in."}' > tickets.jsonl
convene run --expert triage --in tickets.jsonl
convene usage
Or from Python:
from convene import ask, ask_json

ask("Name the capital of France in one word.")
# 'Paris'

ask_json("Extract: Ada Lovelace, born 1815.", {
    "type": "object",
    "properties": {"name": {"type": "string"}, "born": {"type": "integer"}},
    "required": ["name", "born"],
    "additionalProperties": False,
})
# {'name': 'Ada Lovelace', 'born': 1815}
Why this exists
claude -p is already a capable inference endpoint once you strip the coding
agent off it. What it lacks is everything around the call: a name for a
configuration you reuse, conversations that outlive the process, a concurrency
limit taken from measurement rather than folklore, and a check on which account
is about to be billed. convene is that layer, in the standard library, with
every number below re-runnable on your own machine.
Measured, not assumed
Claude Code 2.1.237 on macOS 15 (arm64), subscription auth on a Max plan,
claude-sonnet-5 at effort=low, first published 2026-08-27. Samples are
small and each one says so. Tables and raw figures are in
FINDINGS.md;
convene bench re-runs the cache and concurrency numbers.
| Claim | Result | Method |
|---|---|---|
| The prompt cache survives process death | 9.5x cheaper warm: $0.00281 against $0.02670 | Same 4.4k-token system prompt, three separate processes about 30s apart, n=1 per row |
| Concurrency goes well past "about 5" | ~10x throughput, 0 rate-limit errors at a burst of 20 | Identical trivial calls, one burst each at 1, 5, 10 and 20; 20 is the largest tried, not a ceiling |
A hot process beats --resume for multi-turn |
4.3x cheaper: $0.00342 against $0.01485 | One three-turn conversation each way, n=1 |
| The lockdown flags matter | a plain claude -p cost 88x more |
Identical one-word prompt, n=1; re-check with convene doctor --lockdown |
-p uses your subscription; --bare does not |
~150 calls, all succeeded | No API key in the environment for any of them |
License and releases
MIT. Every version is a GitHub release and its release notes are the changelog.
Scope, and a word about terms
This runs the first-party claude binary on your machine, under your own
interactive login. It is not a proxy, it exposes no network endpoint, and it
never extracts or replays your credentials. Those three properties are
deliberate and this project intends to keep them.
They matter because Anthropic's Consumer Terms §3 restricts
…access[ing] the Services through automated or non-human means, whether through a bot, script, or otherwise
with the carve-out "except when you are accessing our Services via an
Anthropic API Key or where we otherwise explicitly permit it." Claude Code's
headless mode is squarely inside that carve-out: Anthropic
ships and documents it, and states
plainly that non-bare -p uses your subscription login.
What is not inside it is turning a subscription into an API for other software. Between January and April 2026 Anthropic blocked exactly that: OpenClaw, OpenCode, Cline, Aider and the OpenAI-compatible proxies. The common factor in every tool that got cut off was exposing the subscription as an endpoint to other programs.
So convene will not grow an HTTP server, an OpenAI-compatible shim, or a credential-forwarding mode, and pull requests adding them will be declined. This is a scope decision, not legal advice; read the terms yourself and decide what you are comfortable with. The test is the carve-out, not locality.
What this measured that the folklore gets wrong
Every number is reproducible with convene bench; the full tables, with
sample sizes and build versions, are in FINDINGS.md.
1. claude -p uses your subscription. --bare is the one that doesn't.
The widely repeated claim that -p "bypasses OAuth and requires an API key" is
false, and Anthropic's own docs say so: it is --bare that
"doesn't use your subscription login." convene therefore never passes
--bare, despite it being the faster and officially recommended flag for
scripts.
2. Prompt caching works, and is worth ~9.5x. The same 4.4k-token system prompt across three separate processes:
cache_creation |
cache_read |
cost | |
|---|---|---|---|
| cold | 4434 | 0 | $0.02670 |
| warm | 243 | 4191 | $0.00281 |
The cache is server-side and survives process death. This inverts the usual advice: a long, stable system prompt is the cheap option. It is the whole reason experts exist here.
3. Concurrency goes much further than "about 5." One burst per row, no retries:
| n | wall | errors |
|---|---|---|
| 1 | 6.3s | 0 |
| 5 | 6.8s | 0 |
| 10 | 9.9s | 0 |
| 20 | 12.1s | 0 |
~10x the throughput of serial calls, zero rate-limit errors. 20 is the largest burst tested, not a discovered ceiling. The default here is 12.
4. Multi-turn works, two ways. --session-id/--resume gives durable
conversations that outlive the process; --input-format stream-json gives a
hot process that holds one open. On a three-turn conversation the hot process
was 4.3x cheaper, because resume re-establishes context every turn.
Experts
An expert bundles everything that makes a call a kind of call, behind a name.
# experts.toml
[triage]
description   = "Sorts inbound support mail into a queue, with a confidence score"
model         = "claude-sonnet-5"
effort        = "low"
system_prompt = '''
You are a support triage specialist. You read one inbound customer message
and assign it to exactly one queue.
...the full rubric, worked examples, and edge cases...
'''

[triage.json_schema]
type = "object"
required = ["queue", "confidence", "rationale"]
additionalProperties = false
# ...
from convene import load_experts, ask_expert

load_experts("experts.toml")
r = ask_expert("triage", ticket_text)
r.structured_output   # {'queue': 'security', 'confidence': 0.98, ...}
Because of finding 2, the registry pushes you toward long prompts. Put the whole rubric in the system prompt and only the per-item data in the user prompt: you get better output and a smaller bill from the same change.
Two ways to get that wrong, both checked:
convene experts lint
- A prompt too short to cache: every call pays full price.
- A prompt interpolated per call (
{},%s): changing the prefix misses the cache every single time. Per-call data belongs in the user prompt.
Running one over a batch
convene run --expert triage --in tickets.jsonl --out results.jsonl
Bounded concurrency, resumable (a rerun skips ids already in --out), and it
warms the cache with one serial call before releasing the rest, so the batch
pays to create the cache entry once instead of once per call.
5/5 ok, 0 failed | 14.9s wall | $0.0322 | 4/5 warm cache reads
Asking several at once
from convene import consult

await consult(["security", "performance", "style"], diff_text)
# {'security': Result(...), 'performance': Result(...), 'style': Result(...)}
A failing expert returns its exception rather than sinking the panel. The useful thing about asking five specialists is usually the four who answered.
Sessions
Two kinds, because they fail differently.
from convene import Session, LiveSession

# Durable: on disk, resumable from another process, another day, another cwd.
s = Session(system_prompt=RUBRIC)
s.ask("Here is the first document.")
print(s.id)                          # save this
later = Session.resume(saved_id, system_prompt=RUBRIC)

# Hot: one long-lived process. No per-turn startup, 4.3x cheaper, dies with
# the process.
with LiveSession(system_prompt=RUBRIC) as live:
    live.ask("First document.")
    live.ask("Now compare it to the second.")
For many concurrent conversations, SessionPool keeps n hot processes and
hands them out:
async with SessionPool(size=4, system_prompt=RUBRIC) as pool:
    async with pool.acquire() as session:
        turn = await session.ask("...")
A pooled session keeps its history between checkouts. That is the point when
you want shared accumulated context, and a bug when you don't. Pass
reset_between=True for a fresh process per checkout.
Cost gotcha. The two paths report
total_cost_usddifferently: per call for durable sessions, cumulative for live ones. Summing the raw field across a live session triple-counts.Turn.cost_usdis always the incremental figure; the raw one stays onturn.result.cost_usd.
Spend
Every call is recorded to a SQLite ledger at ~/.convene/ledger.sqlite3.
Prompts and responses are never stored. It is for accounting, not
transcripts, so it stays safe to hand to someone who should not see your data.
convene usage --since 7d
  TAG           CALLS         COST    PER CALL    CACHED   AVG TIME
  badprompt         8      $0.1600    $0.02000        0%       0.0s
  goodprompt        6      $0.0240    $0.00400      100%       0.0s
  ----------------------------------------------------------------
  TOTAL            14      $0.1840    $0.01314       43%       0.0s

  note: 'badprompt' read a warm cache on only 0% of 8 calls. Its system prompt
  is likely too short, unstable, or interpolated per call. `convene experts
  lint` will say which.
The CACHED column is the one to act on. Those two experts differ 5x in
cost per call for the same reason finding 2 describes, and the note tells you
which lever to pull. --by day groups by date instead; --verbose lists
recent calls.
Ceilings
A budget stops a runaway loop before it spends, rather than reporting it afterwards. No code needed:
export CONVENE_BUDGET_USD=5          # with CONVENE_BUDGET_WINDOW=1d by default
convene run --expert triage --in tickets.jsonl --budget-usd 2
or in Python, optionally scoped to one expert:
from convene import Budget, add_budget

add_budget(Budget(5.00, "1d"))                    # everything
add_budget(Budget(1.00, "12h", tag="triage"))     # just this expert
Once a ceiling is reached, the next call raises BudgetError before the
subprocess is spawned, and a batch halts with one message rather than marking
every remaining row failed.
What a budget is not. It is checked against spend already recorded, so it is a guard rail, not a fence. With 12 calls in flight the ceiling can be crossed by up to 12 calls' worth before the next check sees it, and a single expensive call is not bounded by it at all; use
max_budget_usdon the call for that, which the CLI enforces server-side. Set a budget below what would actually hurt.
Set CONVENE_LEDGER=0 to record nothing.
Which account am I billing?
The expensive failure mode is silent: an ANTHROPIC_API_KEY in the environment
outranks your subscription login, and the call succeeds identically while
billing API credits. claude-code#37686
reports $1,800 in two days from exactly this.
Two defences. convene strips ANTHROPIC_API_KEY and ANTHROPIC_AUTH_TOKEN
from the subprocess environment on every subscription call, and:
convene doctor
  [ok  ] claude binary  2.1.237 (Claude Code)
  [ok  ] api key        no ANTHROPIC_API_KEY / ANTHROPIC_AUTH_TOKEN in the environment
  [ok  ] account        you@example.com (max, via claude.ai)
  [ok  ] state dir      ~/.convene
  [ok  ] live probe     claude-sonnet-5 answered in 3.4s (in=282 out=4 cost=$0.00091)
In code, at the top of any batch job:
from convene import assert_account
assert_account("you@example.com")   # raises on wrong account, or an API key takeover
The live probe is not decoration. Anthropic's docs say --bare "will become
the default for -p in a future release", and bare mode never reads OAuth. If
that lands, this whole approach stops working, and the probe finds out with a real
call rather than guessing from a version string.
Auth modes
| Mode | Uses | Setup | Billed to |
|---|---|---|---|
LOGIN (default) |
the claude /login you already did |
none | your subscription |
SANDBOX_TOKEN |
its own long-lived token, isolated HOME |
convene setup-token |
your subscription |
API_KEY |
ANTHROPIC_API_KEY |
set the variable | API credits |
API_KEY works but is never selected implicitly: you have to name it.
What you don't get
convene is not a drop-in for the Messages API. Check here before promising a caller a feature.
| model choice | yes | aliases and full ids both resolve |
| system prompt | yes | replaces the agent prompt entirely |
| reasoning depth | yes | effort="low".."max", the lever instead of a token budget |
| JSON schema output | yes | enforced server-side, auto-retries bad JSON |
| per-call spend cap | yes | max_budget_usd, enforced server-side |
| rolling spend ceiling | yes | Budget, checked before the call is made |
| usage accounting | yes | SQLite ledger, convene usage |
| usage + cost reporting | yes | a list-price estimate, not a charge |
| multi-turn | yes | Session and LiveSession |
| prompt caching | automatic | no breakpoint control, but see finding 2 |
| model fallback | yes | fallback_model |
| images | conditional | file on disk, and allow tools="Read" for that call |
| streaming | not wired | the CLI supports it; this does not expose it yet |
max_tokens |
no | no such flag. Constrain via the prompt |
temperature / top_p |
no | also rejected by the Opus 5 / Sonnet 5 API |
stop_sequences |
no | |
| token counting endpoint | no | |
| Batch API (50% off) | no |
Latency is 3 to 9s per call. If you need sub-second responses, max_tokens
control, or the Batch API, use the anthropic SDK with an API key, and say so
plainly rather than working around it here.
Prior art
This is a well-trodden idea and this repo is not the first crack at it. If a different shape suits you better:
| Project | Shape | Notes |
|---|---|---|
| Claude Agent SDK | first-party | Python and TypeScript. The supported path for agentic work. Start here unless you specifically want inference-shaped calls |
| RichardAtCT/claude-code-openai-wrapper | OpenAI-compatible server | What convene deliberately is not; see Scope above |
| dtzp555-max/ocp | OpenAI-compatible server | LAN auth, per-key quotas, response cache |
The difference convene is going for is not features, it is verified claims:
every number in FINDINGS.md carries its sample size and the
build it came from, and convene bench re-runs them on your machine.
Gotchas
- Auth failure returns
subtype: "success"and exit code 0.is_erroris the only reliable signal. Handled; don't "simplify" that check. - Never drop the lockdown flags. A plain
claude -pcosts ~88x more; verify on your own machine withconvene doctor --lockdown. - Never add
--bare. It forces API-key auth and never reads OAuth. - stdout is pure JSON; warnings go to stderr. Don't merge the streams.
result_textvsstructured_output. With a schema, readstructured_output, which is already a parsed dict.- A long session is a growing prompt. Input tokens climb every turn.
Migrating from claude_cli.py
This project began as a single file called claude_cli.py. That module still
exists as a shim, so from claude_cli import ask, ask_json, run_claude_cli_sync
keeps working, with a DeprecationWarning. It will be removed in 1.0.
| old | new |
|---|---|
run_claude_cli_sync(system_prompt=…, user_prompt=…, …) |
run_sync(Call(…)) |
run_claude_cli(...) |
await run(Call(…)) |
ClaudeCLIError |
ConveneError (still exported under the old name) |
ClaudeResult |
Result |
r.result_text, r.total_cost_usd |
r.text, r.cost_usd (old names still work) |
sandbox_ready() |
ready() |
./setup.sh |
convene setup-token |
State moved from ./data and ./logs to ~/.convene, overridable with
CONVENE_HOME.
Contributing
The most valuable contribution is usually a measurement, not a patch. See CONTRIBUTING.md for the standard every empirical claim has to meet, and ROADMAP.md for what is planned and what is deliberately out of scope.
MIT.
1 maintainer

Metadata
1 maintainer
Release files for convene 0.2.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| convene-0.2.1.tar.gz | 69.0 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| convene-0.2.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 122.0 kB
Release files / convene-0.2.1.tar.gz
| Download URL | convene-0.2.1.tar.gz |
|---|---|
| Size | 69.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
82150a3907afa9bb998fdbd7156c827dae1691236d9960f40cf8c06e663d7708
|
|
BLAKE2b-256 checksum How to use checksums |
92426e68690d883bb80030e8cd166e5294471ddcbddb478ee3a99774275550e0
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 30, 2026.
Transparency logRelease files / convene-0.2.1-py3-none-any.whl
| Download URL | convene-0.2.1-py3-none-any.whl |
|---|---|
| Size | 53.0 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
750e8f6a1eca643c72caaa12d593c6a6ca35f2d81afc2bdf7d4c53cba78b9229
|
|
BLAKE2b-256 checksum How to use checksums |
f5e30fab5466f8d30b452ce32d207fa3cd16516ffc5dd7ab98a48d457f2fd618
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 30, 2026.
Transparency log













