
cost-risk-toolkit
A Python library and command line tool for defense cost estimating. Point it at your own production history, units and cost for each lot, and it fits a learning curve, tells you which lots it misses, forecasts the next buy with prediction intervals, and writes down every assumption it made along the way. It also carries a full synthetic CSDR/SRDR pipeline, parametric CERs, and correlated Monte Carlo risk analysis.
Want a window instead of a terminal? The desktop lot cost model lives in
its own repository, lot-cost-model.
It is a tkinter tool over the same three models: paste analogy lots and
estimate lots from Excel, fit LC, Rate and LC+Rate, roll several WBS elements
into one programme, and write the Excel workbook. Since its 3.0.0 it is a front
end onto this library rather than a second copy of it: the fit, the roll-up, the
risk and the workbooks all come from cost_core, and the window refuses to
start without it.
Fit a curve to your own lot data in one command:
ce-core fit-lots --csv mylots.csv --dollar-year 2026 --out results/
lot,units,cost
LRIP 1,22,96800000
LRIP 2,18,70200000
FRP 1,25,90000000
Two columns is the whole input. Jump to the details, including the four things that quietly ruin a lot fit and how the tool checks for each one.
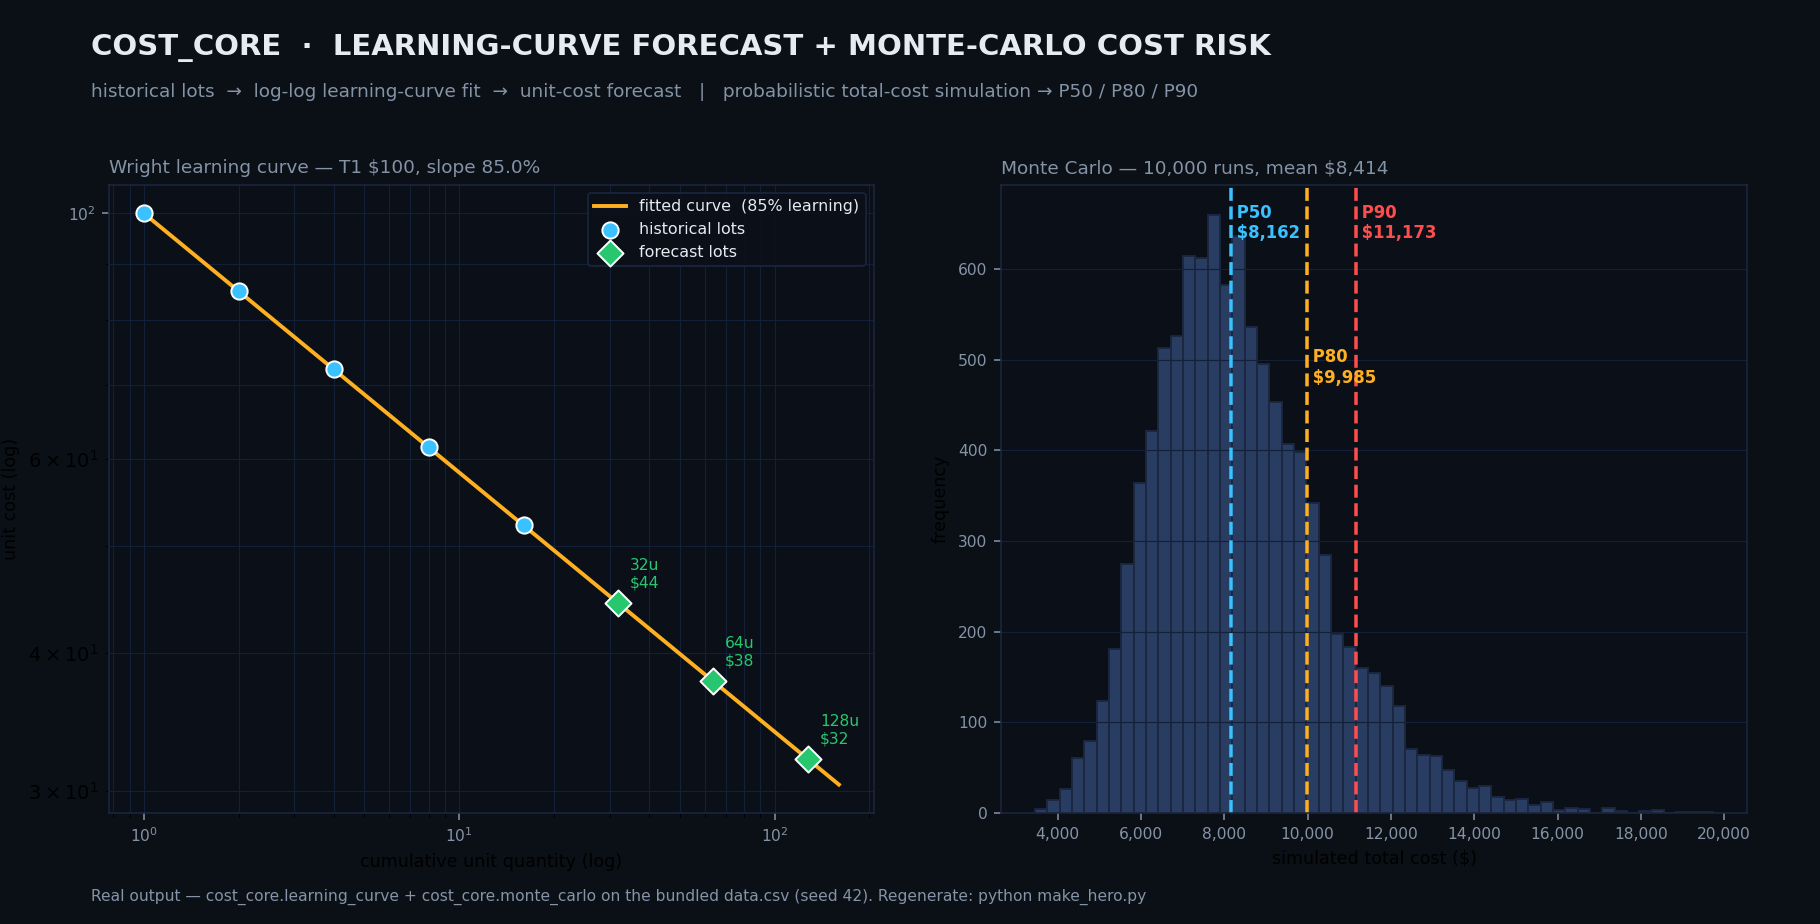
Real output. cost_core fits an 85% Wright learning curve and forecasts future
lots (left), then runs a 10,000 iteration Monte Carlo total cost simulation with
P50/P80/P90 thresholds (right). Regenerate with python make_hero.py, which
reads a local data.csv that isn't committed, since .gitignore excludes
*.csv.
No real or proprietary data is committed to this repository. You supply your own for
fit-lots, and nothing you pass in gets stored here. Everything the repo ships with, and everything the test suite runs on, comes from a seeded generator producing invented programs in the shape of CADE submissions.
What it does
| Module | Purpose |
|---|---|
cost_core.lotmodel |
The lot cost engine. Analogy lots in, estimate lots out. Fits LC / Rate / LC+Rate, selects on significance with an AICc tiebreak, and layers refits, influence, prediction intervals and buy risk on top. Carried over from the desktop tool in lot-cost-model, which runs on this code from its 3.0.0 rather than a copy of it |
cost_core.program |
WBS roll-up. Several elements, fitted, factor or amount, priced against one lot schedule and correlated into a programme estimate |
cost_core.lots |
Your own data. Units and cost per lot, in CSV or Excel. Runs the same three model engine, then layers the statistics on top |
cost_core.synth |
Seeded synthetic CSDR/SRDR generator: DD 1921, DD 1921-1, DD 1921-2, Cost and Hour Report (FlexFile), Quantity Data Report, SRDR (DD 2630), with realistic pathologies to clean |
cost_core.ingest |
ETL to one normalized long table: WBS crosswalk, base year normalization, resubmission dedup, loud validation gates, row level provenance |
cost_core.fitting |
Shared estimator: OLS, MUPE and ZMPE, with delta method prediction and confidence intervals |
cost_core.learning_curve |
Wright (cumulative average) and Crawford (unit) theories, rate breaks, prediction intervals |
cost_core.cer |
Parametric CERs, log log and linear, with leverage and influence diagnostics, extrapolation warnings, small sample guardrails |
cost_core.monte_carlo |
Correlated WBS level risk: Gaussian copula or Iman Conover, PSD repair, discrete risks, tornado, convergence |
cost_core.reporting |
S curve, tornado, cost improvement curve, CER diagnostics, and the assumptions log |
Installation
Python 3.9 or higher. The distribution name is cost-core and the import name
is cost_core. Nothing is published yet, so install from a clone:
python -m venv .venv && .venv/Scripts/activate && pip install -e ".[plots]"
That pulls in pandas, numpy, scipy and openpyxl, plus matplotlib for the
[plots] extra. Excel input and the workbooks the lot engine writes both need
openpyxl, so it's installed by default rather than as an extra. matplotlib is
the other way round: it draws the charts and nothing else, so installing without
the extra gives you the whole engine, the CERs, the risk simulation and the Excel
workbooks, and anything that draws a PNG tells you to add [plots] when you
reach it.
numpy and scipy also carry an upper bound, numpy<2.5 and scipy<1.18. That is
about reproducing numbers, not about running: above those versions the library
imports and works, but it stops reproducing the figures this release pins. Both
land the unbiased MUPE and ZMPE refits in a slightly different place, which moves
golden leaves by up to 8e-9 and 4.5e-8 relative against a 1e-9 tolerance, and
scipy 1.18 also changes the simulated draws, which the frozen-draw tests hash.
Both are seen on Windows, where the goldens were captured. Elsewhere those refit
leaves carry a measured allowance for the machine's own last bits and the hashes
are not checked, so a bound has to be measured on Windows. Raising a bound means
rebaselining the goldens and the frozen draws against the new stack and writing
down what moved, the same process every other rebaseline here went through.
CHANGELOG.md carries the measurements.
Quick start
With your own data
ce-core fit-lots --csv mylots.csv --dollar-year 2026 --forecast "30,40" --out results/
Costs come back in the units they went in, because the fit is scale free and
this command converts nothing. Headings that read ($K) are the engine's own
column names, carried over from the desktop tool whose input column is
AUC ($K), and the S-curve formats the same numbers as dollars, so read both
as "cost" in your file's units unless that file really is in thousands.
Prints the fitted slope and first unit cost, the standard error and CV, an
interval on the slope, and a per lot percentage error showing which lots the
curve misses. With --out it also writes those tables as CSV and an
ASSUMPTIONS.md; the one chart this command draws is the buy S-curve, and that
needs --simulate. See
Fitting a curve to your own lot data.
With generated data, to see the whole pipeline
Generate synthetic submissions, ingest and normalize them, fit a learning curve and a CER, simulate with correlation, then write charts, tables and an assumptions log:
ce-core full-run --out artifacts/ --seed 7
That writes:
artifacts/
  ASSUMPTIONS.md              the written assumptions and provenance log
  charts/                     s_curve, tornado, learning_curve,
                              cer_diagnostics, summary_table  (PNG, 200 dpi)
  tables/                     every table behind those charts, as CSV
  artifacts/source_reports/   the six synthetic submissions
  artifacts/wbs_crosswalk.csv the persisted name crosswalk
  artifacts/inflation_index.csv
The same seed reproduces the run exactly.
The lot cost engine
The lot cost engine is cost_core.lotmodel, the code the desktop tool runs
on. Historical analogy
lots (fiscal year, quantity, unit cost) are the history; estimate lots
(fiscal year, quantity, complexity factor) are the buy being priced.
from cost_core.lotmodel import run_lot_cost_model, generate_analyst_summary, enrich_run

projections, ctx = run_lot_cost_model(analogy_df, estimate_df)
summary = generate_analyst_summary(ctx, {"Program": "TEST"})
extras = enrich_run(ctx, projections, summary)
Three models get fitted to the analogy lots, and every estimate lot is priced under all three, so the projections carry the models the tool didn't pick right alongside the one it did:
LC        ln(cost) = ln(T1) + b*ln(lot midpoint)
Rate      ln(cost) = ln(T1) + c*ln(lot quantity)
LC+Rate   both terms together
Selection goes to LC+Rate when its rate coefficient is significant, to Rate when the rate slope is significant and beats LC by more than the AICc tie threshold, and to LC otherwise. Where AICc disagrees with the significance gate, the summary says so instead of hiding it. Because the lot midpoint depends on the slope you're fitting, the fit iterates to a fixed point. That's the Goal Seek the original workbook did by hand.
What the statistics layer adds
The estimate itself is untouched by any of this. A golden master test fails if a
single coefficient moves. What enrich_run reports is how much confidence
those numbers can carry.
Retransformation bias. The fit is OLS on ln(cost), then exponentiated back.
That estimates the median and understates the mean by exp(s²/2). MUPE and
ZMPE refit the same regressors under a proportional error loss and drive the
mean percentage error to zero, so the bias gets measured on your data instead of
argued about.
Influence. Six analogy lots is a normal sample here, and at that size one lot can set the slope while every summary statistic still looks healthy. Leverage and Cook's distance name it. On the reference programme in the tests, analogy lot 1 carries leverage 0.77 and Cook's D 4.00.
Prediction intervals on every projected lot. For a new lot, carrying the residual scatter, with a t multiplier because sigma is estimated rather than known.
Buy risk. A distribution over the total of the estimate lots with P50/P80/P90 and where the point estimate falls on it. Residuals across lots are correlated at 0.30 by default, for the same reason WBS elements are.
enrich_run returns the four tables (Fit_Methods, Influence,
Prediction_Intervals, Buy_Risk) as frames. The desktop tool writes the risk
ones into its workbook after the original three sheets, so an analyst who wants
only the original three still gets exactly those.
Fitting a curve to your own lot data
The simplest way in. Two columns, one row per lot:
lot,units,cost
LRIP 1,22,96800000
LRIP 2,18,70200000
FRP 1,25,90000000
FRP 2,30,100500000
ce-core fit-lots --csv mylots.csv --dollar-year 2026 --forecast "30,40" --out results/
The lot column is optional. Common header spellings (Qty, Quantity,
Total Cost, Amount, and so on) are recognized automatically, and anything
unusual you name with --units-col / --cost-col. Currency formatting like
$1,200,000 parses fine. .xlsx works out of the box.
Everything else is derived. Lot 1 is units 1 to 22, lot 2 is units 23 to 40, and
so on by running total. That's what turns a flat list of lots into positions on a
curve. You get the fitted slope and first unit cost, standard error and CV, an
interval on the slope, a per lot percentage error showing which lots the curve
misses, prediction intervals on forecast lots, and an ASSUMPTIONS.md.
Re-using the curve on another program
The fit is also an estimating relationship you can lift and apply somewhere else.
The equation gets printed and written to equation.csv. The four lots above
select LC+Rate, so theirs carries both terms:
Unit Cost = 7,424,501.70 * midpoint^(-0.108355) * qty^(-0.093348)
Where only the learning term survives the significance gate the qty factor is
absent. Drop FRP 2 from that sample and the remaining three lots select LC,
printing Unit Cost = 5,586,219.86 * midpoint^(-0.108548). The priced lots carry
whichever terms the equation does. There's a test for exactly that, because for a
while they didn't.
--price-lots applies the selected model to any buy profile from unit 1,
producing the learning curve table an analyst would build by hand:
ce-core fit-lots --csv mylots.csv --dollar-year 2026 --price-lots "10,15,20,25,30" --out results/
The lot_midpoint column is the algebraic midpoint, meaning the unit whose
cost equals the lot average. Most tools approximate it, because they only have an
approximate lot average to work from. Here the lot average is exact, so the
midpoint gets solved for directly. There's a test asserting the cost at the
midpoint equals the lot average, which is its definition.
This is the analogy use case: price a program with no cost history of its own using the slope from one that does. Whether that's valid is a judgement, not a result. The slope carries across only if the two programs are comparable in product, process, rate and contractor. Nothing in the data can confirm that, so the assumptions log records it as an untested assumption and notes that the extra error it introduces isn't in any interval reported.
Forecasting the next buy, with risk
--forecast prices future lots continuing from the last unit built, with
prediction intervals. --simulate then Monte Carlos them:
ce-core fit-lots --csv mylots.csv --dollar-year 2026 --forecast "30,40" --simulate 50000 --out results/
Unlike the WBS level simulator, this needs no elicited distributions. The uncertainty is measured from the program's own history. Two sources get propagated: parameter uncertainty in the fitted slope and T1, which dominates on a short series, and lot to lot scatter, which is what makes the answer a prediction about a real lot. Residuals across future lots are correlated at 0.30 by default for the same reason WBS elements are. Consecutive lots share a workforce and a schedule, and treating them as independent understates the spread of the whole buy.
It does not include schedule risk, requirement changes, or rate changes the history never saw. That's a narrower claim than a full risk model, and the log says so.
How it fits
Three candidate models against the lot midpoint, one selected:
LC        ln(unit cost) = ln(T1) + b*ln(lot midpoint)
Rate      ln(unit cost) = ln(T1) + c*ln(lot quantity)
LC+Rate   both terms together
This engine came across from the desktop tool in lot-cost-model, which since its 3.0.0 imports it rather than keeping a copy, so the two are the same code by import rather than by descent. All three models get fitted and all three price every lot, so the alternatives stay on the record. Because the midpoint depends on the slope you're fitting, the fit iterates to a fixed point.
Four things that quietly ruin a lot fit
The tool checks all four, because each one leaves a fit that looks perfectly healthy while the slope is several points wrong.
Nonrecurring cost in the totals. Nonrecurring is front loaded, so including it
makes early lots look expensive and the curve reads steeper than the production
process really is. That overstates future savings. --cost-basis has to be
declared, and total warns.
Escalation left in "constant" dollars. --dollar-year is required. No
index gets applied, but constant dollars are constant relative to a year, and an
output nobody can place in a year can't be escalated or compared. The tool checks
whether cumulative average cost ever rises, which can't happen on a learning
curve, and it also tests the log log residuals for a bend.
Be careful about what that second check can actually do. Fitted against the lot midpoint it's a poor escalation detector: the fitted slope moves with the escalation, the midpoint moves with the slope, and the trend gets absorbed instead of being left in the residuals. It catches a rate break, a design change or a production gap, not moderate escalation. The level check needs roughly 10% a year before it bites. Below that, moderate escalation and genuinely slower learning can't be told apart without a fiscal year attached to each lot, and the log says exactly that. There's a parametrized test at 2%, 4% and 6% asserting the miss, so the limit is documented rather than discovered later.
Lots that don't start at unit 1. If the program has a prior buy the curve has
already learned through, --first-unit shifts the series. Otherwise the fitted
first unit cost describes a unit nobody built.
Too few lots. Degrees of freedom are lots minus 2. Two lots interpolate exactly and are refused. Three gives one degree of freedom and an interval too wide to support a decision. Five is the practical floor. The tool fits below that but says so loudly.
Usage guide
Full run
ce-core full-run --out artifacts/ --seed 7 --iters 50000 --theory crawford --method mupe --correlation 0.30
--clean generates data with no reporting pathologies, which is how the tests
show that the pipeline recovers the generating truth exactly.
Fit a learning curve
Takes a CSV with program, lot, unit_quantity and unit_cost columns.
ce-core fit-curve --csv your_history.csv --out model_params.json
Forecast future lots
ce-core forecast --model model_params.json --quantities "32,64,128" --out forecast.csv
Run a Monte Carlo simulation
In PowerShell, wrap the JSON arguments in single quotes.
ce-core simulate --n-iter 10000 --unit-cost-dist '{"type": "lognormal", "mean": 5.0, "sigma": 0.2}' --quantity-dist '{"type": "triangular", "left": 40, "mode": 50, "right": 75}' --out sim_results.csv
As a library
from cost_core.synth import generate_program
from cost_core.ingest import normalize_program
from cost_core.learning_curve import Theory, fit_from_progress_report

program = generate_program(seed=7)
data = normalize_program(program)                    # raises if a gate fails
curve = fit_from_progress_report(
    data.learning_curve_input(), theory=Theory.CRAWFORD, method="mupe"
)
curve.forecast_lots([[109, 132]], level=0.80, kind="prediction")
Methodological choices
Why MUPE and ZMPE, not just OLS
The standard cost fit is ordinary least squares in log space, followed by
exponentiating back to dollars. That retransformation is biased. If the log space
errors are normal with variance s², then
E[y | x] = f(x) · exp(s² / 2)
so the retransformed value estimates the median and understates the mean
by a factor of exp(s²/2). On a 30% CV relationship that's roughly a 4 to 5%
understatement baked into the estimate before any risk analysis even starts, and
it runs in the direction that makes a program look cheaper.
Two unbiased alternatives are provided, and both drive the mean percentage error to exactly zero:
MUPE (minimum unbiased percentage error) minimizes Σ (y - f)² / f_prev² by
iteratively reweighted least squares. At its fixed point, the normal equation for
a multiplicative scale parameter collapses to Σ (y - f)/f = 0.
ZMPE (zero percentage bias minimum percentage error) minimizes
Σ ((y - f)/f)² subject to Σ (y - f)/f = 0. Same zero bias property, but
imposed as a constraint rather than emerging from the algebra, and it gives a
different slope.
retransformation_bias() measures the bias three ways: the theoretical
exp(s²/2), Duan's nonparametric smearing estimate, and the observed shift
against MUPE and ZMPE. So the correction gets quantified instead of asserted.
Prediction intervals, not confidence intervals
These aren't interchangeable, and the confusion always runs the same direction.
A confidence interval covers the mean response at a point, meaning where the fitted line is. It shrinks toward zero as the sample grows.
A prediction interval covers a single new observation, meaning where the next actual program will land. It carries the residual scatter as well as the parameter uncertainty.
The variance relationship is exact:
Var_prediction = Var_confidence + σ²
That extra σ² is the spread of programs about the line, and no amount of
additional data removes it. A cost estimate forecasts one new program, so the
prediction interval is the correct one. CER.predict() takes kind explicitly
and defaults to "prediction".
Why correlation matters
Sampling WBS elements independently is the spreadsheet default and close to the worst assumption available. Elements on one program share a workforce, a management chain, a supply base and a schedule. When one runs late they mostly all run late. The variance of a sum is
Var(Σ Xᵢ) = Σ Var(Xᵢ) + 2 · Σ_{i<j} ρᵢⱼ · sdᵢ · sdⱼ
so for k equally variable elements at a common ρ, ignoring correlation
understates the variance of the total by exactly 1 + ρ(k-1). Ten elements at
ρ = 0.3 is a factor of 3.7 in variance, close to a doubling of the standard
deviation, and it lands on the upper tail, which is where the P80 lives.
Because independence is so rarely right, RiskModel applies a non zero default
correlation when none is supplied, and warns that it did so. A default is an
assumption, and an unstated assumption is the failure this documentation exists
to prevent. correlation_impact() reports the measured and the closed form
inflation side by side, so the claim doesn't rest on the simulation alone.
Standard error and CV, not R²
R² measures how tightly points hug the fitted line, which a wrong model can do
perfectly well. In tests/test_learning_curve.py, data generated under Crawford
unit theory and fitted as a Wright curve returns R² of about 0.996 with a
demonstrably wrong forecast. Standard error is in dollars and CV is a proportion.
Both are arguable. R² is reported, but last.
Projections have to satisfy the equation
The original desktop tool priced its Rate lots on the lot midpoint, which isn't
the variable that model regresses on, and priced LC+Rate without the rate factor
at all. So it printed an equation and then printed lot costs that didn't satisfy
it. On example_lots.csv that overstates a back cast of the fitted lots by 36%
against a known total, while the residual columns from the same run showed the
model tracking those lots to about 1%. One run, two formulas.
Dropping the term isn't a modeling choice you could defend. It evaluates the fit at a lot quantity of one unit while keeping the learning position of the real lot, and because the rate exponent is negative it only ever biases upward.
The corrected behavior is the default. LegacyRateOmission reproduces the old
numbers for anyone who has to match a legacy workbook, and the command line has
--legacy-rate-omission for it, which prints a warning when you use it. Passing
the old setting name raises instead of being ignored, because a caller who asked
for legacy behavior and quietly got something else is worse off than one who
gets an error.
The guard is a test that retypes the printed equation and evaluates it against the printed projections, for all three models. That test is why this is a paragraph about a fix rather than a known issue.
Wright and Crawford are different theories
Wright's cumulative average form says the average cost of the first x units
follows T1·x^b. Crawford's unit form says the cost of unit x does. Which one
applies is a property of the production process, not a modeling preference.
fit_curve() makes the caller choose and compare_theories() reports both,
because the same data under the two gives materially different forecasts.
Mapping to the GAO Cost Estimating and Assessment Guide
Every run emits an ASSUMPTIONS.md organized around the four characteristics of
a reliable estimate.
| Characteristic | How this library addresses it |
|---|---|
| Comprehensive | All six report shapes ingested. Recurring and nonrecurring cost, five functional categories and discrete risks all modeled. The WBS crosswalk surfaces unmatched elements rather than dropping them |
| Well-documented | Row level provenance from every output number back to its source submission. The crosswalk and inflation index are persisted artifacts, not inline logic. The assumptions log separates what was measured from what was assumed, and counts the assumptions |
| Accurate | Validation gates reconcile row counts and dollar totals within and across reports, and fail the run when they disagree. Retransformation bias is measured and corrected. Estimating methods are compared rather than assumed |
| Credible | Prediction intervals on every forecast. Leverage and influence diagnostics on the CER. Extrapolation flagged, including hidden extrapolation. The correlation assumption's effect quantified against independence. P80 convergence checked |
Project structure
cost_core/
  fitting.py          shared OLS / MUPE / ZMPE estimator and intervals
  lots.py             your own lot data: units and cost per lot
  cli.py              the ce-core command line interface
  lotmodel/           the lot cost engine: LC / Rate / LC+Rate on lot midpoints, summary, enrichment
  program/            WBS roll-up of several elements into one programme
  learning_curve.py   Wright and Crawford theories, rate breaks
  monte_carlo.py      correlated risk simulation
  data_io.py          CSV and SQLite loading
  synth/              synthetic CSDR/SRDR generator
  ingest/             crosswalk, inflation, normalization pipeline
  cer/                parametric CERs and diagnostics
  reporting/          charts, assumptions log, the Excel workbooks, end to end run
tests/                property tests, see below
Tests
pip install -e ".[plots]" pytest
pytest tests/ -q
requirements.txt also exists, but it holds the exact versions this repo
develops against, and four of the five will not install on 3.9, three of them
not on 3.10. It is the pinned development set, not the way to set up a checkout
on an older interpreter. Install the package and let the version range in
pyproject.toml resolve.
759 tests, run on Python 3.9, 3.10, 3.11, 3.12, 3.13 and 3.14 on every push, which is the whole supported range; four of them, the frozen-draw hashes, run on Windows only. They assert mathematics against closed form answers rather than against recorded output, with one deliberate exception: tests/goldens pins what the lot engine produced on 6 September 2026, so a refactor that moves a number has to say so. The strongest ones:
Our OLS is the textbook OLS. The generic estimator reproduces
scipy.stats.linregress and the normal equations to machine precision, and the
delta method prediction interval reduces algebraically to
s·√(1 + 1/n + (x₀-x̄)²/Sxx).
MUPE and ZMPE drive the mean percentage error to exactly zero. That's what their names mean, and it's asserted to 1e-9. ZMPE's sum of squared percentage errors is also proven to be no larger than MUPE's, which is a theorem, not a tuning outcome.
Cook's distance is checked against an actual leave one out refit. The closed form is exact, so the test drops each program, refits, and confirms the formula reproduces the movement in the fitted surface.
Variance inflation is exactly 1 + ρ(k-1). Asserted across element counts
and correlations, and confirmed against simulation.
Tornado variance shares sum to exactly one, because the covariance
decomposition Var(T) = Σ Cov(Xᵢ, T) is an identity when T is the sum.
A messy program normalizes back to the generating truth to the cent. Name drift, mixed then year and base year dollars, resubmitted periods and a mid program quantity change are all reversible by construction, so the pipeline that reverses them has no excuse for landing anywhere else.
Learning curve identities are definitional. Doubling quantity multiplies the right quantity by the slope under each theory. Wright's unit costs telescope back to its cumulative total. Crawford's lot cost is the exact sum of its units.
Simulations are seed deterministic. A P80 that moves between runs isn't a number you can put in front of anyone.
Limits get tested, not just capabilities. There's a parametrized test asserting that both escalation checks stay silent at 2%, 4% and 6% a year under a midpoint fit, while the fitted slope drifts several points off the truth. A second test confirms the level check does catch 15%. Documenting where a diagnostic stops working matters more than showing where it works.
The projections satisfy the equation the tool prints. Retyped by hand for all three models and evaluated against the projected costs, to the cent the column is rounded to. Flipping the legacy switch back on fails five of these, which is how I know they'd have caught the original defect.
Bad input is refused, not absorbed. Zero degrees of freedom, a missing base year, two lots, fractional units, unmatched WBS names, non positive costs in a log fit, a correlation matrix that isn't symmetric, a rate break beyond the data, an unknown interval kind, an index asked for a year it doesn't cover. Each one raises instead of producing a plausible looking number.
1 maintainer

Release files for cost-core 1.0.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| cost_core-1.0.1.tar.gz | 1.5 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| cost_core-1.0.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.8 MB
Release files / cost_core-1.0.1.tar.gz
| Download URL | cost_core-1.0.1.tar.gz |
|---|---|
| Size | 1.5 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
f83e51178194f8cd12887f68ca0e31a1be4c9d2cd5c711f52f9bd254f1585925
|
|
BLAKE2b-256 checksum How to use checksums |
46535473ffa62f888db80071b3adf6535441122ff9f543de0e058ce33f35a3b9
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 19, 2026.
Transparency logRelease files / cost_core-1.0.1-py3-none-any.whl
| Download URL | cost_core-1.0.1-py3-none-any.whl |
|---|---|
| Size | 206.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
d791cf94e1d05e7306cf354253a3d4dd2d46be3c65f8a4f56018f21a52ed3d6c
|
|
BLAKE2b-256 checksum How to use checksums |
39042b08330c72bed01762e1a557fd5a84b10c67df9403cb216b60ea013a7e90
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 19, 2026.
Transparency log












