
crewlore


Your coding agents keep relearning what your team already figured out.
crewlorecompiles agent sessions and agent-authored pull requests into a citable, plaintext team-knowledge layer that lives in your git repo. It records what the team adopted and what it tried and declined. Local-first.
pipx install crewlore
Validated on
pydantic/pydantic-ai(17.3k ⭐) · 3 sessions · 18 claims · 100% fidelity · see receipts →
Quickstart
Two ways in, depending on where your team's knowledge currently lives.
You already use a coding agent. Point lore at the transcripts it writes to disk:
cd my-repo
lore init                      # create .lore/ in your repo
lore watch                     # automatic: read agent transcripts, scrub secrets,
                               #   compile to claims, prune — on an interval
lore query "billing webhook"   # ask the knowledge layer anything, anytime
You have a repo but no sessions yet. Compile its pull-request threads instead. Coding agents now write much of the reasoning in PR bodies and reviews — the intent, the alternatives weighed, the constraint hit — so a repo you have never run an agent in already has a knowledge layer waiting:
cd my-repo
lore init
lore import-prs owner/repo     # uses your existing `gh auth`; agent-authored PRs by default
lore query "billing webhook"
Either way, commit .lore/knowledge and .lore/claims and your teammates inherit it on the next git pull. Engineers keep working in whatever agent they use; lore watch keeps the layer fresh in the background.
Trouble installing?
If pipx fails with Broken Python installation, platform.mac_ver() returned an empty value, your default Python is a broken install (sometimes seen with very recent Homebrew Python builds). This is about the interpreter pipx uses, not the package — pin a known-working one:
pipx install --python python3.13 crewlore
To make pipx default to Python 3.13 going forward: export PIPX_DEFAULT_PYTHON=$(which python3.13).
Try it in 30 seconds — no API key
git clone https://github.com/srijansk/crewlore.git
cd crewlore && uv run python scripts/demo.py
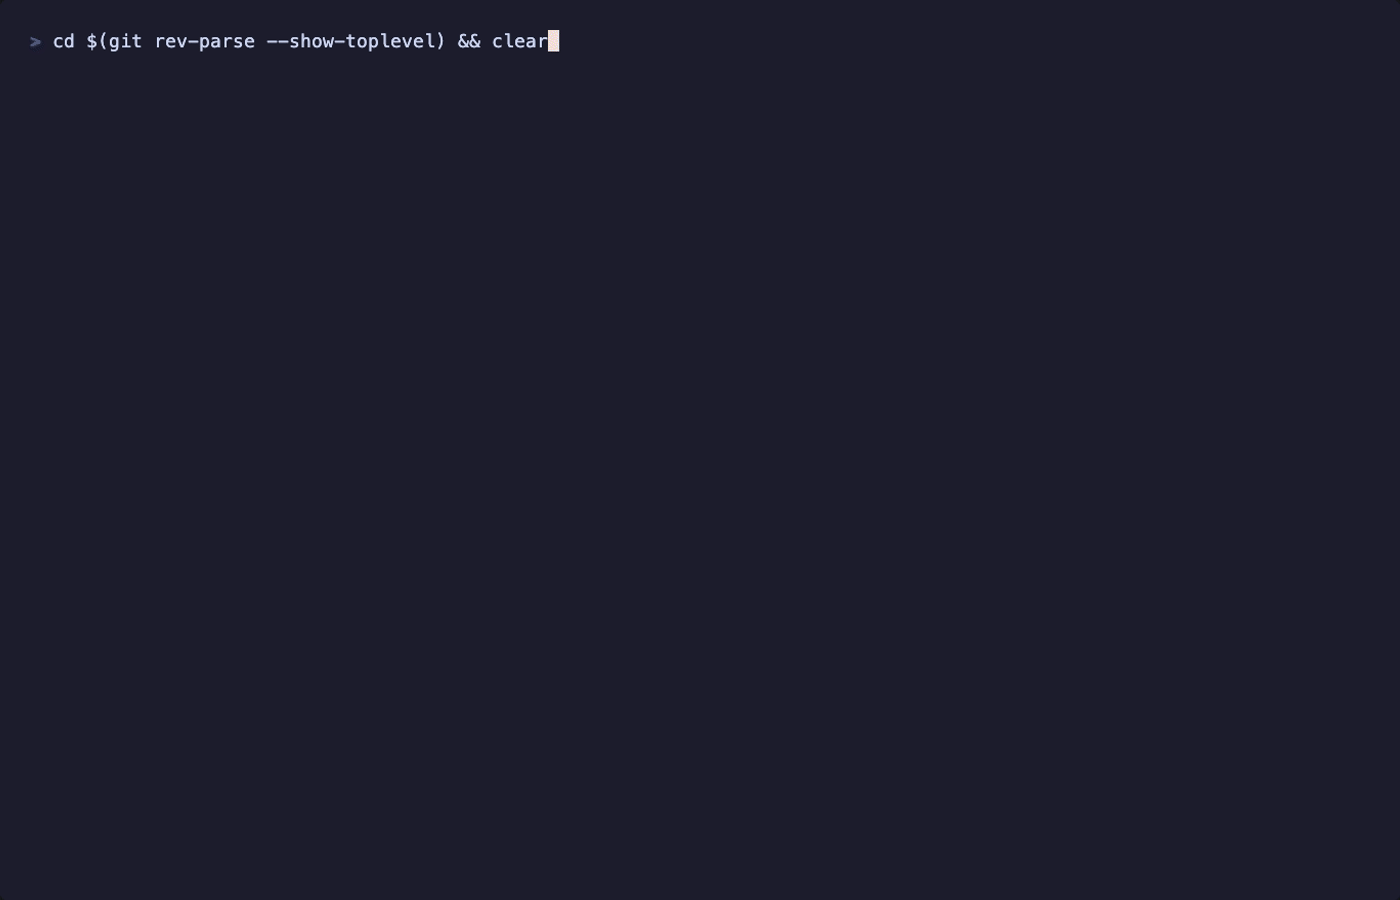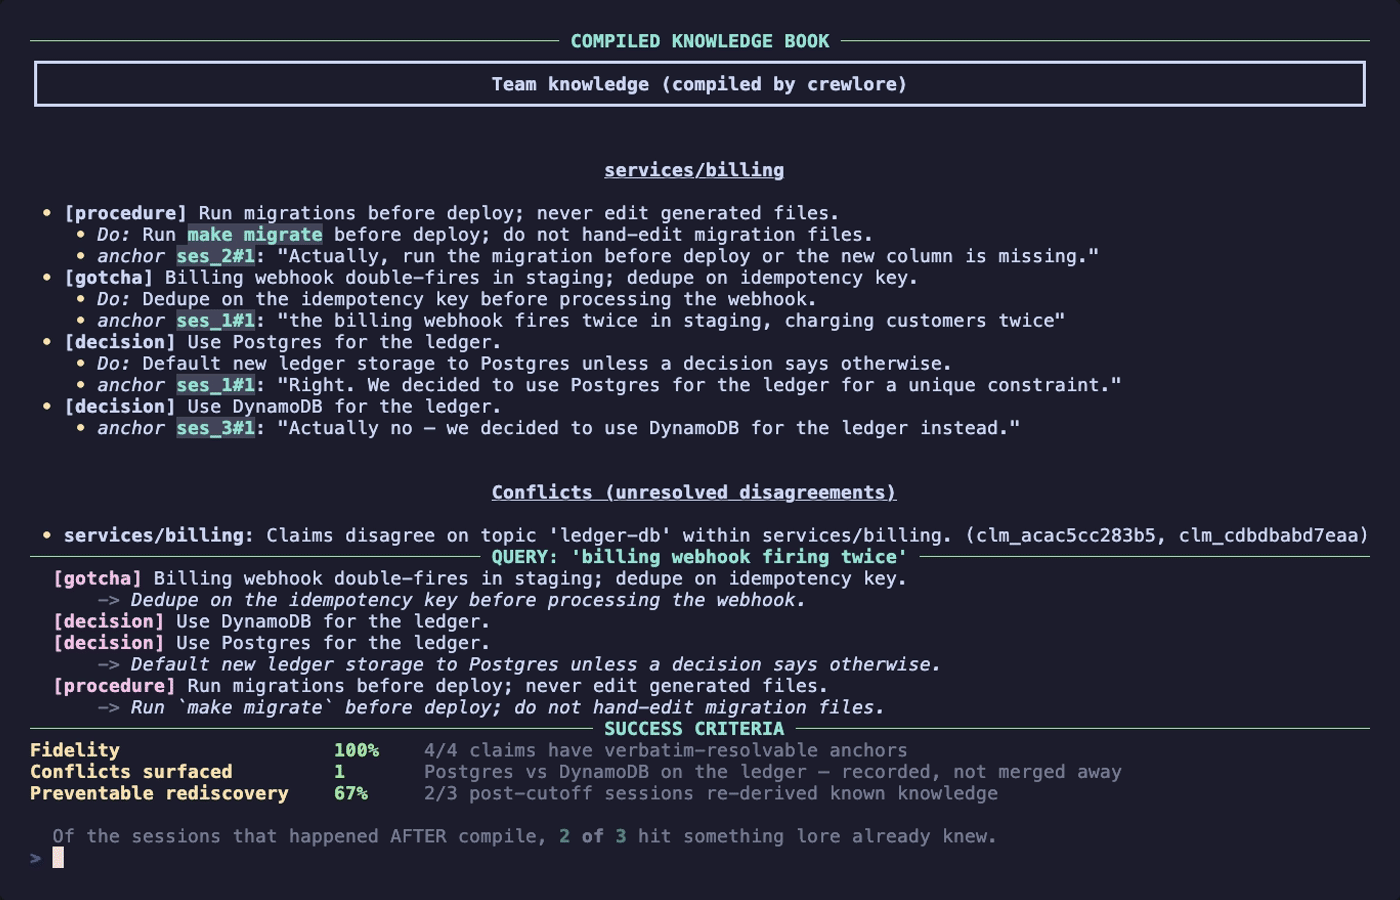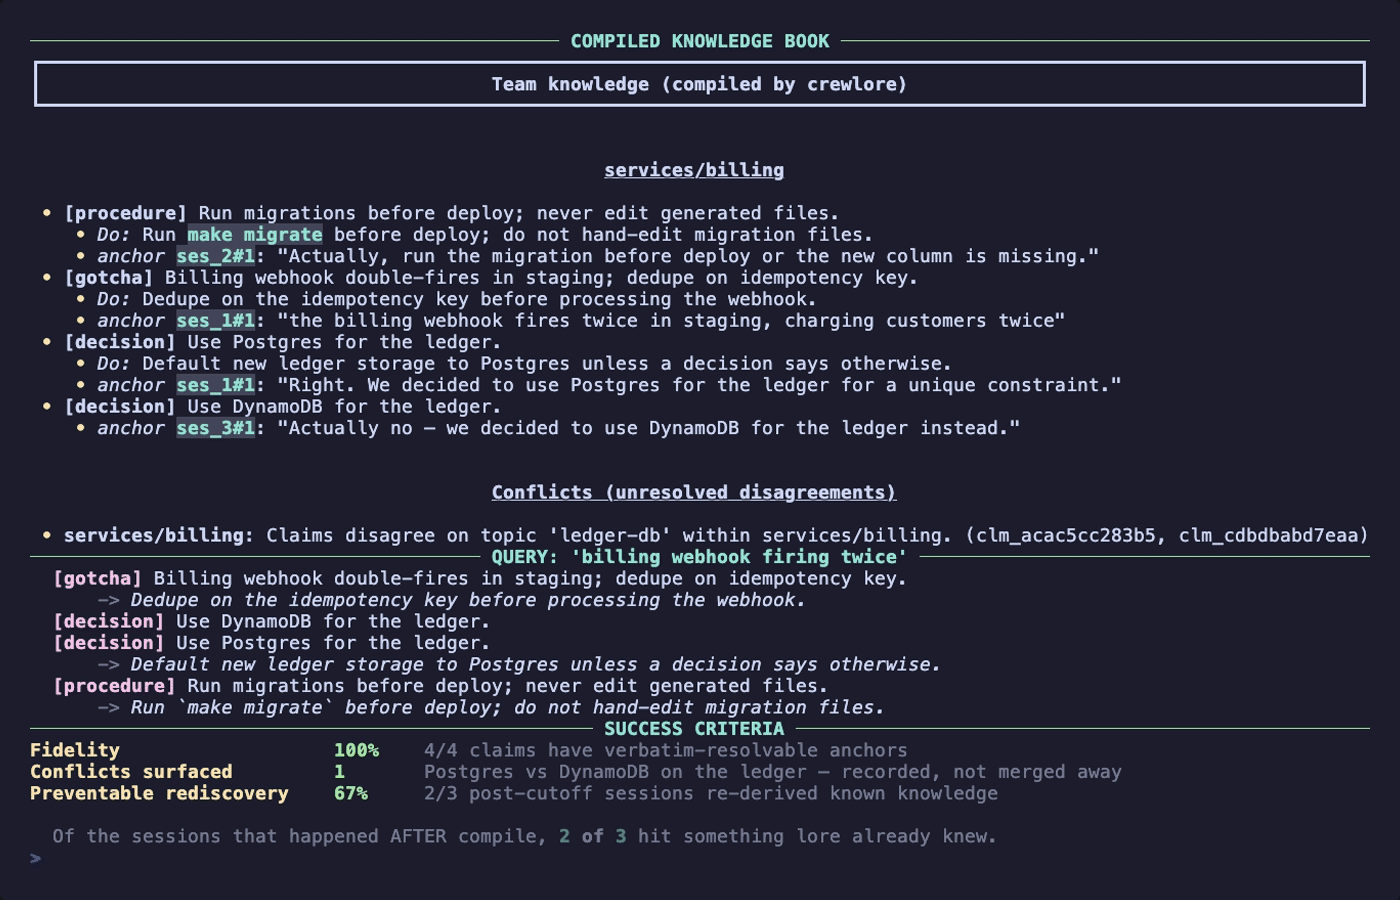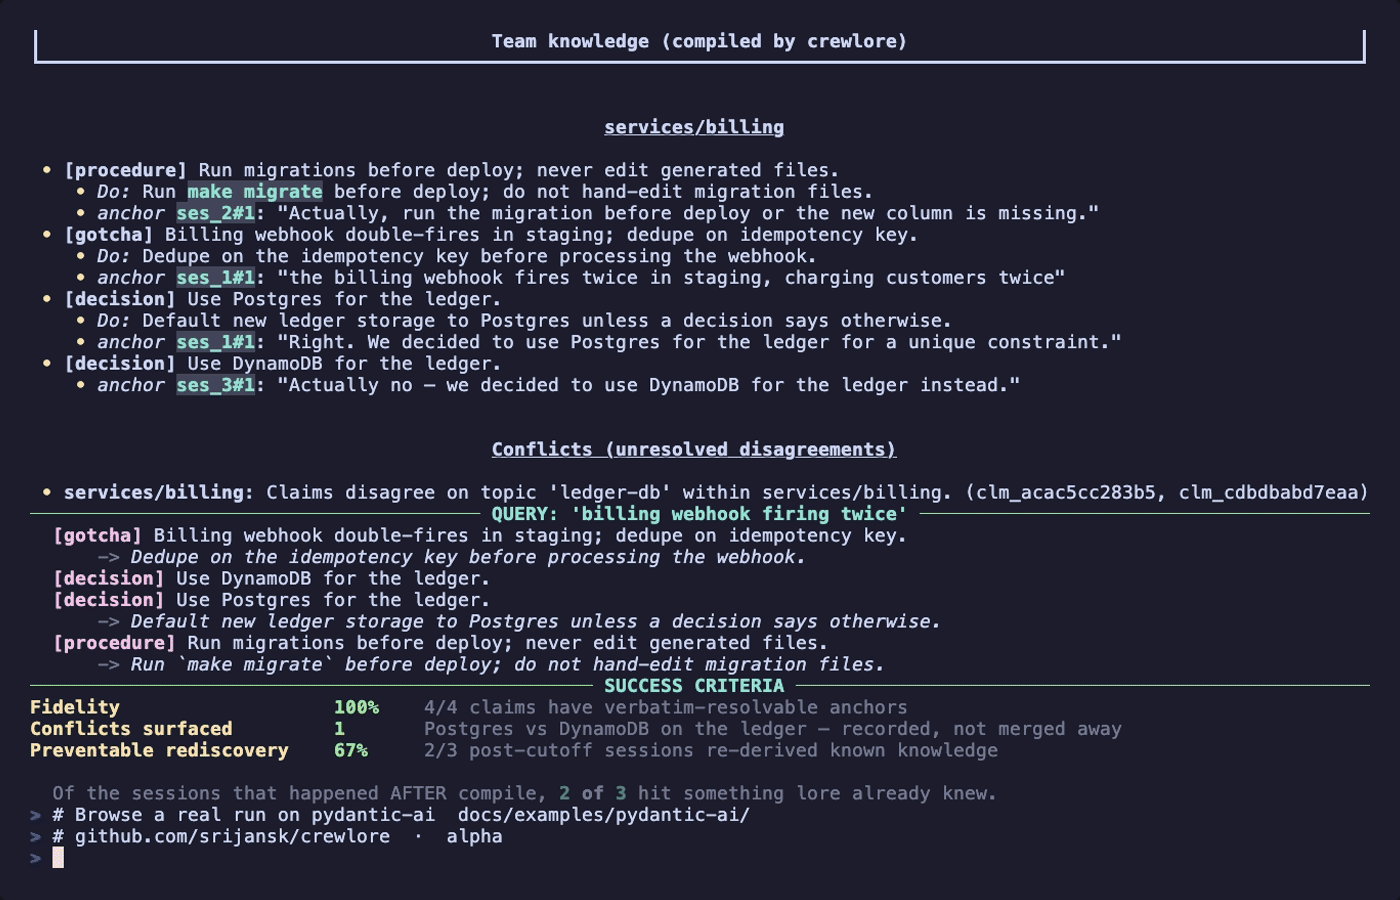
The demo runs the full loop on bundled public-safe sessions and prints what it found:
See it run on a real codebase: pydantic-ai (17.3k ⭐)
docs/examples/pydantic-ai/ is a committed snapshot of crewlore compiled on the public pydantic/pydantic-ai repo — 3 Claude Code sessions on real issues, no synthetic data.
- 18 claims compiled across 9 scope groupings (UI adapters, decorator introspection, durable-execution threat modeling, toolsets, tests, version policy)
- 100% fidelity under the explicit canonical-form contract — every anchor's quote canonically resolves to a substring of its source session. (Fidelity certifies the citation is real, not that the model's statement is fully entailed by it — that's what human/PR review of the book is for.)
- 0 conflicts because the three sessions covered disjoint scopes — the conflict detector wasn't given anything to flag
- Receipts: the rendered
book.md, the rawclaims.jsonl, and fullprovenance.md(session ids, commit hashes, compile cost, scrub redactions, five real-data bugs the capture surfaced and we fixed before publishing)
What you get
Raw, messy sessions go in. Out comes a structured, citable compiled claim — every one carrying its kind, its scope, the action it implies for future work, and a verbatim anchor back to the moment it was discovered:
[gotcha]· services/billingBilling webhook handler lacks an idempotency check, causing duplicate charges when Stripe retries webhooks.
Do — dedupe on the Stripe idempotency key before processing.
anchor — "the handler has no idempotency check, so when Stripe retries a webhook the charge is processed again."
A human can verify it (the anchor points back to the exact session line); an agent can trust it (the citation is real, not hallucinated).
Declined work is recorded as declined. When a session or pull request shows an approach was tried and not adopted, the claim says so, and its action says what to do instead:
[decision · not adopted]· services/billingStoring the Stripe idempotency key in Redis was proposed and rejected in review because the check has to run inside the database transaction.
Instead — keep the key in the same transaction as the charge.
anchor — "Don't put the key in Redis. Must be inside the transaction."
This matters more than it looks. A memory schema that can only say "X" turns "we tried X and declined it" into a confident assertion of X — fluent, correctly cited, and wrong about the world. Every crewlore claim carries an adoption field and the extractor is instructed to use it; the study behind that decision is in the repo.
Claims roll up into a knowledge book at .lore/knowledge/README.md, grouped by area and committed to your repo alongside your code:
# Team knowledge (compiled by crewlore)

## services/billing

- **[gotcha]** Billing webhook handler lacks an idempotency check; dedupe on the Stripe key.
  - *Do:* Dedupe on the Stripe idempotency key before processing.
  - _anchor_ `services/billing/webhook.py:88`: "the handler has no idempotency check, so when Stripe retries a webhook the charge is processed again."
- **[decision · not adopted]** Storing the idempotency key in Redis was proposed and rejected in review.
  - *Instead:* Keep the key in the same transaction as the charge.
  - _anchor_ `pr_acme__billing__42#event-6`: "Don't put the key in Redis. Must be inside the transaction."

## deployment

- **[procedure]** Run migrations before deploy to prevent missing columns.
  - *Do:* Run `make migrate` before every deploy.
How it works
flowchart LR
    S["coding-agent<br/>sessions"] --> I
    P["agent-authored<br/>pull requests"] --> I["ingest + scrub<br/>(→ one session format,<br/>secrets redacted)"]
    I --> C["compile<br/>(→ claims with verbatim<br/>anchors + adoption)"]
    C --> R["<b>.lore/</b> in your repo<br/>(knowledge book + claims,<br/>plaintext, git-versioned)"]
    R --> SV["serve<br/>(files + MCP query)"]
    SV --> N["next agent session<br/>inherits the knowledge"]

    SV -. "usage signal" .-> AL["actuation loop<br/>(decay · reinforce · retire)"]
    AL -. "lifecycle update" .-> R

    classDef engine fill:#4a5d9e,stroke:#1a2c4d,color:#fff,stroke-width:2px
    classDef artifact fill:#2d6a4f,stroke:#1b4332,color:#fff,stroke-width:2px
    class C engine
    class R artifact
lore watchruns ingest → compile → prune automatically, on an interval.lore import-prsruns the same pipeline over a repository's pull-request threads.
- Ingest + scrub — two capture sources feed one session format. Transcripts: the coding agent's existing on-disk session files. Pull requests: fetched through the
ghCLI, one PR thread per session, with merge/close and approve/request-changes carried as real outcome events and inline review comments already anchored to apath:line. Both are scrubbed of a curated set of secret patterns (Anthropic / OpenAI / genericsk-*API keys, AWS keys, GitHub classic + fine-grained PATs, Google API keys, Slack tokens, HuggingFace tokens, JWTs, connection-string passwords, private-key blocks, andpassword=…assignment shapes) before anything is stored or sent to a model. The pattern set is documented indocs/scrub.md. - Compile — extracts atomic claims with an adoption status, deduplicates them, records disagreements instead of silently overwriting, scores authority by how often a claim recurs, and drops any claim whose citation doesn't resolve verbatim. An anchor's
refis derived from where the quote actually resolved — apath:linewhen the source carries one, otherwise<session>#event-<n>— never copied from the model, so every anchor is somewhere a reader can go. - Serve — writes a human- and agent-readable knowledge book to
.lore/knowledge/, and exposes a query tool (including an optional MCP server) so any agent can pull the relevant slice on demand. - Actuation loop — every retrieval is recorded, and that usage drives a lifecycle: unused claims decay and archive, contradicted claims are retired, useful claims are reinforced. The store stays small and fresh instead of growing into a pile nobody reads.
The intelligence is in compile; ingest and serve are deliberately thin, so supporting another coding agent or another source is a small adapter, not a rewrite. To be precise about the word "compile": extraction is an LLM step (the only non-deterministic part), wrapped in deterministic stages — verbatim-anchor verification, anchor-ref derivation, content-addressed dedup, conflict recording, and authority scoring. "Compile" means the repeatable session → claims transform, not that an LLM is absent.
How it differs
- vs. hosted memory (Letta, mem0) — their store lives in someone else's cloud and you can't
git logit;crewlore's lives in your repo as plaintext. - vs. per-IDE memory (Cursor rules, Claude memory, Continue, Cody) — tied to one developer, one IDE;
crewloreis a team artifact, committed and reviewed like code. - vs. hand-curated
CLAUDE.md/.cursorrules— humans write those by hand and they go stale;crewlorecompiles + reinforces from real sessions and retires what stops being used. - vs. RAG over a vector DB — RAG retrieves document chunks;
crewlorecompiles atomic, citable claims with verbatim anchors and an adoption status, so a human or agent can verify the cited source in seconds and can tell a decision from a rejected alternative. (Retrieval today is deterministic lexical overlap, not embeddings — simpler and dependency-free; semantic ranking is on the roadmap.)
Why this exists
Knowledge discovered inside an agent session is private by default and lost by default. It lives in one developer's transcript, so the next engineer — and every future agent run — re-reads the same files, re-learns the same gotcha, and re-makes a decision the team already made. There's no shared layer that both humans and agents read from, so decisions drift and bugs resurface.
crewlore makes that knowledge a first-class, versioned artifact in the place your team already trusts: your git repo.
What it is: a compiler that turns sessions and pull requests into accurate, deduplicated, conflict-aware, provenance-carrying team knowledge, served back to any agent.
What it isn't: a hosted service, a vector database, or a personal-memory layer for a single IDE. There's no account, no cloud, and no proprietary store — the compiled knowledge is plaintext you own.
Your data stays yours
- Local-first. Capture, compile, and serve all run on infrastructure you control. Point the compiler at your own model provider or a local OpenAI-compatible model (Ollama, LM Studio, vLLM) via
provider: local— nothing routes through anycrewlore-operated service, because there is none. - Plaintext, in your repo. The knowledge layer is human-readable Markdown and JSONL under
.lore/, versioned by git.git log .lore/is your audit trail. - Secrets never travel. Scrubbing — of both message content and tool-call arguments — happens at ingest, before storage or any model call. It's a high-precision pattern set (a floor, not a DLP guarantee; see
docs/scrub.md), and raw session captures are git-ignored by default regardless. - No tokens to store. Pull-request import goes through the
ghCLI you already authenticated;crewlorenever sees or stores a GitHub token.
CLI
| Command | What it does |
|---|---|
lore init |
Create the .lore/ layout in your repo. |
lore watch |
Automatically ingest → compile → prune on an interval (--once for cron/CI). |
lore compile |
Run a single ingest-and-compile pass manually (--rebuild to re-extract everything). |
lore import-prs OWNER/REPO |
Compile a GitHub repository's pull-request threads into knowledge. Agent-authored PRs by default; --all-authors for every PR; --limit N to scan more. Needs the gh CLI. |
lore query "<task>" |
Retrieve the claims most relevant to a task (records usage). |
lore status |
Show claim/conflict counts and how much of the layer is actually being used. |
lore serve --mcp |
Start an MCP server exposing query-time retrieval to any MCP-speaking agent (Claude Desktop, Cursor, …). Requires pip install 'crewlore[serve]'. See docs/mcp.md for wiring snippets. |
Configuration
.lore/config.yaml:
model:
  provider: anthropic          # anthropic | openai | local
  name: claude-sonnet-4-6
  # For provider: local — point at any OpenAI-compatible endpoint you run:
  # base_url: http://localhost:11434/v1   # e.g. Ollama, LM Studio, vLLM
capture:
  transcripts: ~/.claude/projects
compile:
  cadence: auto                # `lore watch` interval below
  watch_interval_seconds: 300
Bring your own key (ANTHROPIC_API_KEY / OPENAI_API_KEY); crewlore never ships keys anywhere. The default Anthropic provider works out of the box. For OpenAI or a local OpenAI-compatible model, add the SDK: pipx inject crewlore openai (or pip install 'crewlore[openai]'). With provider: local nothing leaves your machine at all — the compile call hits your own endpoint. A rejected key stops the run with a clear error instead of reporting a successful compile of nothing.
Research
Product decisions here are measured, and the measurements live in the repo. studies/ holds each study's code and reproduction recipe. The first, studies/palm/, asks what a memory system stores when it compiles work a team declined — using agent-authored pull requests that were closed without merging, with merged controls — and is the reason every claim now carries an adoption field. If crewlore is useful in your research, CITATION.cff has the citation.
Roadmap & limitations
- Stable today: capture from Claude Code transcripts and GitHub pull-request threads, secret scrubbing, the compile pipeline (verbatim-anchor fidelity gate, anchor-ref derivation, adoption status, conflict recording), retrieval, the actuation loop, and the
.lore/plaintext format. - In flight: cross-session conflict alignment — real disagreements are surfaced today, but reliably aligning claims about the same question across independently-compiled sessions is an active area of work.
- Planned: an explicit human approve-before-serve gate (secret scrubbing is already automated), transcript adapters for Cursor / Codex / Copilot, embedding-based retrieval, and a real-time capture hook.
Contributing
Issues, discussions, and PRs welcome. New here? Start a discussion — adding a capture adapter for another coding agent is the most valuable first contribution and is intentionally small (the Claude Code and GitHub PR adapters are the two worked examples). See CONTRIBUTING.md for local setup and the dev loop.
Tests are fully deterministic — no real API calls during pytest.
License
MIT — see LICENSE.
1 maintainer

Release files for crewlore 0.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| crewlore-0.2.0.tar.gz | 89.5 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| crewlore-0.2.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 141.7 kB
Release files / crewlore-0.2.0.tar.gz
| Download URL | crewlore-0.2.0.tar.gz |
|---|---|
| Size | 89.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
99c3998168fbcc4dc465873a1b273a4441d426dcab7329f56beb21e455a6ee61
|
|
BLAKE2b-256 checksum How to use checksums |
22b9bef94ec6c32095345c7c43517d0a9dfc2d569003df0a5f18ea96cca4eff4
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 24, 2026.
Transparency logRelease files / crewlore-0.2.0-py3-none-any.whl
| Download URL | crewlore-0.2.0-py3-none-any.whl |
|---|---|
| Size | 52.3 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
337bb0bbad0d8dceaf2ff49623fddf096a51c84641f8eeb2284aee1e24579e1b
|
|
BLAKE2b-256 checksum How to use checksums |
e763de2c94403ed3144ede1d7cd273b65c90104d7d653c245db50df6bb9095c7
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 24, 2026.
Transparency log













