

CRISPR-Correct
CRISPR-Correct (Python package crispr-ambiguous-mapping) was developed by the Pinello Lab as an easy-to-use Python package for performing guide-RNA mapping from raw FASTQs against a guide-library DataFrame. Specifically, CRISPR-Correct handles imperfect mapping — either from self-editing by SpRY-based base-editors or sequencing errors — by mapping observed protospacer sequences to the guide RNA with the closest Hamming distance. It cannot handle indels in the protospacer (for that, consider the Pinello Lab tool CRISPR BEAN). If you aren't expecting self-editing or sequencing error, this tool still works but CRISPR SURF may be faster.
CRISPR-Correct also handles guide-RNA sensor / surrogate constructs, UMIs, and single-cell sample barcodes (see Figure 1). Mapping is performed on each protospacer / surrogate / barcode permutation and the editing outcomes at the protospacer and surrogate are characterized. You provide regex strings or positional specifications for extracting each component from the read.
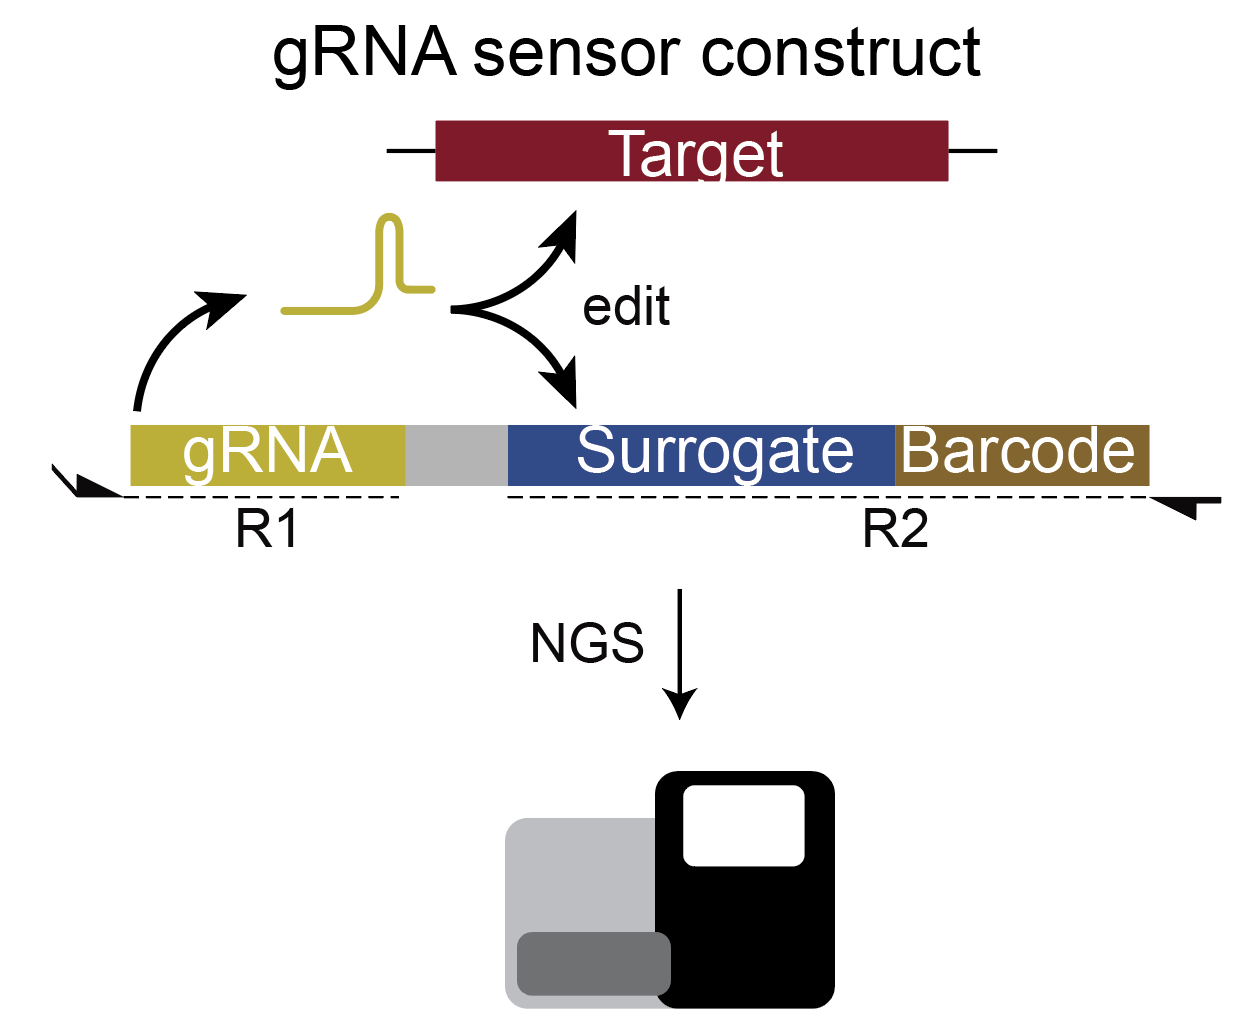
Figure 1. Schematic of a guide-RNA sensor construct. Typically, the expressed guide RNA edits both the endogenous target site and the surrogate target site. A short barcode distinguishes between similar protospacer / surrogate sequences in the guide-RNA library. Paired-end sequencing is performed to capture the protospacer (R1) and the surrogate + barcode (R2).
If you are mapping many large samples that would take too long on a personal computer, CRISPR-Correct can also run on the Broad Institute's Terra Platform. The workflow file is at the Terra Firecloud repository.
What's new in 0.2.0
- High-level
api— a small, stage-aligned interface that most users should start from:map_fastq→count→alleles, plus durablesave/load. AParsingConfigdataclass bundles the ~50 parsing/threshold options into one IDE-friendly object, and aMatchTierstring-enum gives type-safe tier names. Importable either ascrispr_ambiguous_mappingor via the forward-looking aliasimport crispr_correct as cc. - Slim results by default —
retain_inference_results=Falseis now the default, so the returned object holds just the counts + QC + config. Result pickles shrink ~15× (≈ −93% at simulation scale). Passretain_inference_results=Trueonly when you need allele/mutation post-processing. - Flat-arg command-line interface — a
crispr-correctconsole script withmap/count/save/load/allelessubcommands; everyParsingConfigfield maps 1:1 to a--flag(no YAML, no config file). - Cross-language durable serialization —
save/loadround-trip the count series, QC summary, andCountInputthrough a parquet + JSON directory readable from Python / R / Julia. - Much faster + leaner — the counter-series build went from ~21,317 s to ~53 s (~400×) on the AVITI 100k-read profile; end-to-end benchmarks improved −36–43% wall time and −33–57% peak RSS (cumulative Phase 1–5).
Migrating from 0.0.x? Several keyword arguments were renamed for clarity —
contains_surrogate/contains_barcode/contains_umi→contains_guide_surrogate/contains_guide_barcode/contains_guide_umi, and (earlier)barcode_*/umi_*→guide_barcode_*/guide_umi_*. See../USAGE.md §6for the full rename table andCHANGELOG.mdfor the accumulated 0.0.236 → 0.2.0 changes (new API surface, CLI, parquet save/load, memory + performance deltas).
Installation
pip install crispr-ambiguous-mapping
Development install (for contributing):
git clone https://github.com/pinellolab/CRISPR-Correct.git
cd CRISPR-Correct/crispr-ambiguous-mapping
pip install -e .
Python constraint: >=3.8, <3.12.
System requirements
Any OS that can run a supported Python version. Multi-core CPU recommended (the inference step parallelizes via multiprocessing.Pool); sufficient RAM for in-memory Counter of unique observed sequences; SSD recommended for large FASTQ I/O. pandarallel, biopython, pysam, anndata, click (CLI), and pyarrow (parquet save/load) are pulled in as dependencies.
Prepare inputs
The three inputs are:
- Demultiplexed R1 (and R2) FASTQ(s). See the tip below if your reads arrive with in-read indices that need extra demultiplexing.
- Guide library TSV with columns
protospacer(required),surrogate(optional),barcode(optional). Lengths may differ per column but must be uniform within a column. - Parsing specifications that tell the tool where each component lives within each read (or the FASTQ header).
Tip: if indices need to be parsed out of the read before demultiplexing (i.e. in-read indices), use UMItools and BBMap demuxbyname. A Terra Firecloud method runs both.
Guide library TSV (example)
protospacer            surrogate                         barcode
TGTCGTGAGGTAGCTACGAC   CAGCAATGTCGTGAGGTAGCTACGACTTGTCA  GCTC
AGTCGTAGCTACCTCACGAC   ATGACAAGTCGTAGCTACCTCACGACATTGCT  GTTG
CCTAGTGGTTATTCGATGTC   AGGTTACCTAGTGGTTATTCGATGTCTCAGAA  CGAA
...
Header regexes (example)
Suppose UMI-tools put the sample barcode + UMI into the FASTQ header:
@lh00134:140:225VLGLT3:7:1101:1028:1080_ANGC_GGCA 1:N:0:GAAATAAG+ACGTCCTG
- Guide barcode regex:
r"_([^_ ]+)[\s+]"capturesGGCA - UMI regex (8 bp UMI variant):
r":([^+:]{8})(.{2})\+"capturesGAAATAAG - UMI regex (6 bp UMI variant):
r":([^+:]{6})(.{2})\+"
Hamming thresholds
For a 20 bp protospacer, 32 bp surrogate, and 4 bp barcode, these defaults work well across published CRISPR-Correct runs:
PROTOSPACER_HAMMING_THRESHOLD = 7
SURROGATE_HAMMING_THRESHOLD   = 10
BARCODE_HAMMING_THRESHOLD     = 2
These are guidelines for a canonical base-editor editing window. As long as numbers are not too low (which would discard true edits) or too high (which would bring in random reads), they don't need fine tuning.
Running the guide mapping
High-level API (recommended)
The quickest way in is the api module — map_fastq runs the mapping, count pulls out the per-tier count container, and alleles does allele post-processing. It's exposed at the top level of both crispr_ambiguous_mapping and the forward-looking alias crispr_correct:
import crispr_correct as cc          # equivalently: import crispr_ambiguous_mapping as cam
import pandas as pd

lib = pd.read_table("guide_library.tsv")

# Bundle the parsing/threshold options into one IDE-friendly object...
cfg = cc.ParsingConfig(
    protospacer_start_position=0, protospacer_length=20, is_protospacer_r1=True,
    revcomp_protospacer=False, protospacer_hamming_threshold_strict=7,
    cores=8,
)

result = cc.map_fastq(lib, ["sample_R1.fastq.gz"], config=cfg)   # extra keyword **overrides also accepted
counts = cc.count(result)                                        # the per-tier count-Series container

# MatchTier is a str-enum of the six tiers (str-equal to the underlying name)
series = getattr(counts, cc.MatchTier.PM).ambiguous_accepted_umi_collapsed_counterseries
series.head()
map_fastq(library, fastq_r1_fns, fastq_r2_fns=None, *, config=ParsingConfig(...), **overrides)— thin wrapper over the full entry point below. Pass options viaconfig=and/or as direct keyword**overrides.ParsingConfig— dataclass bundling the ~50 per-component parsing + threshold fields (same names as the full function below; all default toNoneexceptretain_inference_results=Falseandcores=1).MatchTier—strenum with membersPM,PM_SM,PM_BM,PM_SM_BM,PM_MISMATCH_SM,PM_MISMATCH_SM_BM. Because it subclassesstr,cc.MatchTier.PM_SM_BM == "protospacer_match_surrogate_match_barcode_match"andstr(tier)returns the underlying tier name (handy forgetattr).count(result)— returnsresult.all_match_set_whitelist_reporter_counter_series_results.alleles(result, tier, *, contains_guide_surrogate, contains_guide_barcode, contains_guide_umi)— allele extraction for a tier; raises a clearValueErrorif the result is slim (run withretain_inference_results=Truefirst).save(result, directory)/load(directory)— durable parquet + JSON serialization (see Saving + reloading below).
Full parameter reference (fine-grained entry point)
from crispr_ambiguous_mapping.mapping import get_whitelist_reporter_counts_from_fastq
map_fastq is a wrapper over this function; call it directly when you want every knob in one signature. It accepts a guide-library DataFrame, one or more R1 FASTQ paths, optional R2 FASTQ paths, a per-component parsing spec (regex or left/right flanks or fixed start/end positions), location flags (R1 body / R2 body / FASTQ header), reverse-complement flags, per-component Hamming thresholds, and parallelism controls:
def get_whitelist_reporter_counts_from_fastq(
    whitelist_guide_reporter_df,
    fastq_r1_fns,                      # list of R1 FASTQ paths
    fastq_r2_fns=None,                 # optional list of R2 FASTQ paths

    # Parsing -- per component, ONE of: regex, left+right flank, start+end position
    protospacer_pattern_regex=None,
    surrogate_pattern_regex=None,
    guide_barcode_pattern_regex=None,
    guide_umi_pattern_regex=None,
    sample_barcode_pattern_regex=None,

    protospacer_left_flank=None,       protospacer_right_flank=None,
    protospacer_start_position=None,   protospacer_end_position=None,
    protospacer_length=None,

    surrogate_left_flank=None,         surrogate_right_flank=None,
    surrogate_start_position=None,     surrogate_end_position=None,
    surrogate_length=None,

    guide_barcode_left_flank=None,     guide_barcode_right_flank=None,
    guide_barcode_start_position=None, guide_barcode_end_position=None,
    guide_barcode_length=None,

    guide_umi_left_flank=None,         guide_umi_right_flank=None,
    guide_umi_start_position=None,     guide_umi_end_position=None,
    guide_umi_length=None,

    sample_barcode_left_flank=None,    sample_barcode_right_flank=None,
    sample_barcode_start_position=None, sample_barcode_end_position=None,
    sample_barcode_length=None,

    # Location flags -- where does each component live?
    is_protospacer_r1=None,    is_surrogate_r1=None,
    is_guide_barcode_r1=None,  is_guide_umi_r1=None,   is_sample_barcode_r1=None,

    is_protospacer_header=None,   is_surrogate_header=None,
    is_guide_barcode_header=None, is_guide_umi_header=None, is_sample_barcode_header=None,

    # Reverse complement (usually True for any component read off R2)
    revcomp_protospacer=None,    revcomp_surrogate=None,
    revcomp_guide_barcode=None,  revcomp_guide_umi=None,   revcomp_sample_barcode=None,

    # Hamming thresholds (pass-through to the internal Hamming matcher)
    surrogate_hamming_threshold_strict=None,
    guide_barcode_hamming_threshold_strict=None,
    protospacer_hamming_threshold_strict=None,

    # Output control -- NEW
    retain_inference_results=False,    # see "Slim vs full output" below

    # Internal
    store_intermediates=False,
    cores=1,
) -> WhitelistReporterCountsResult
Parameter naming conventions:
fastq_r1_fns/fastq_r2_fns— always lists, even with one file. This is the current multi-sample-support API.guide_barcode_*,guide_umi_*,sample_barcode_*— prefix distinguishes a guide's library-encoded barcode/UMI from a per-read (single-cell) sample barcode.is_<comp>_r1=Trueextracts from R1 body;is_<comp>_header=Trueextracts from the R1 FASTQ header. If both areFalse/Noneandfastq_r2_fnsis provided, the component is extracted from R2.
Slim vs full output
By default the returned object holds the count Series + QC summary + input config — a lean object that pickles in ~150 KB on typical runs.
If you need allele/mutation post-processing (get_matchset_alleleseries, get_mutation_profile, helper_get_observed_values_given_whitelist_value), pass retain_inference_results=True. The result then also carries the full per-observation inference dict (observed_guide_reporter_umi_counts_inferred), which can be several GB on 45 M-read runs.
If you call a post-processing function on a slim result you get a clear error:
ValueError: get_matchset_alleleseries requires `observed_guide_reporter_umi_counts_inferred`
but the result object was built with `retain_inference_results=False` (the default).
Re-run the mapping call with `retain_inference_results=True` to enable
allele / mutation post-processing.
Example -- full triplet with UMI in header
import crispr_ambiguous_mapping as cam
import pandas as pd

whitelist_guide_reporter_df = pd.read_table("guide_library.tsv")

result = cam.mapping.get_whitelist_reporter_counts_from_fastq(
    whitelist_guide_reporter_df=whitelist_guide_reporter_df,
    fastq_r1_fns=["sample_R1.fastq.gz"],
    fastq_r2_fns=["sample_R2.fastq.gz"],

    # Protospacer: first 20 bp of R1
    protospacer_start_position=0, protospacer_length=20,
    is_protospacer_r1=True, revcomp_protospacer=False,

    # Surrogate: first 32 bp of R2 (reverse-complemented)
    surrogate_start_position=0, surrogate_length=32,
    is_surrogate_r1=False, revcomp_surrogate=True,

    # Guide barcode: parsed from R1 header via regex
    guide_barcode_pattern_regex=r"_([^_ ]+)[\s+]",
    is_guide_barcode_header=True, revcomp_guide_barcode=True,

    # UMI: parsed from R1 header via regex
    guide_umi_pattern_regex=r":([^+:]{8})(.{2})\+",
    is_guide_umi_header=True, revcomp_guide_umi=False,

    # Thresholds
    protospacer_hamming_threshold_strict=7,
    surrogate_hamming_threshold_strict=10,
    guide_barcode_hamming_threshold_strict=2,

    cores=8,

    # If you want to run allele / mutation post-processing on this result,
    # uncomment the next line. Default is False (slim result).
    # retain_inference_results=True,
)
Accessing counts
The main output lives at:
result.all_match_set_whitelist_reporter_counter_series_results
which has one attribute per match tier — protospacer_match, protospacer_match_surrogate_match, protospacer_match_barcode_match, protospacer_match_surrogate_match_barcode_match, and two mismatch tiers — each with nine pd.Series counters (3 ambiguity strategies × 3 UMI modes).
# Example: UMI-collapsed, ambiguous-accepted full-triplet counts
series = (
    result.all_match_set_whitelist_reporter_counter_series_results
          .protospacer_match_surrogate_match_barcode_match
          .ambiguous_accepted_umi_collapsed_counterseries
)
series.head()
QC summary:
result.quality_control_result.protospacer_match.num_non_error_umi_noncollapsed_counts
result.quality_control_result.protospacer_match.num_total_umi_noncollapsed_counts
Post-processing (allele + mutation profiles)
When retain_inference_results=True, you can further analyze per-allele observations:
match_set = cam.processing.get_matchset_alleleseries(
    result.observed_guide_reporter_umi_counts_inferred,
    "protospacer_match_surrogate_match_barcode_match",
    contains_guide_surrogate=result.count_input.contains_guide_surrogate,
    contains_guide_barcode=result.count_input.contains_guide_barcode,
    contains_guide_umi=result.count_input.contains_guide_umi,
)

mutations = cam.processing.get_mutation_profile(
    match_set,
    whitelist_reporter_df=result.count_input.whitelist_guide_reporter_df,
    contains_guide_surrogate=result.count_input.contains_guide_surrogate,
    contains_guide_barcode=result.count_input.contains_guide_barcode,
)

linked = cam.processing.tally_linked_mutation_count_per_sequence(
    mutations,
    contains_guide_surrogate=result.count_input.contains_guide_surrogate,
    contains_guide_barcode=result.count_input.contains_guide_barcode,
    count_attribute_name="ambiguous_accepted_umi_noncollapsed_mutations",
)

cam.visualization.plot_mutation_count_histogram(
    linked.protospacer_total_mutation_counter,
    filename="protospacer_mut_hist.png",
)
Saving + reloading
Standard Python pickling works. With the slim default (retain_inference_results=False), pickle sizes are much smaller:
import pickle

with open("result.pkl", "wb") as f:
    pickle.dump(result, f, protocol=pickle.HIGHEST_PROTOCOL)
Intermediate save utilities (e.g. cam.utility.save_or_load_pickle) remain available.
Command-line interface (v0.2.0)
The package registers a crispr-correct console script with two subcommands. All flags mirror the Python ParsingConfig fields 1:1 (field names with _ → -) — no config file, no YAML.
# Map
crispr-correct map \
    --r1 R1.fq.gz \
    --r2 R2.fq.gz \
    --library library.tsv \
    --out result.pickle \
    --protospacer-start-position 0 --protospacer-length 20 \
    --is-protospacer-r1 --no-revcomp-protospacer \
    --protospacer-hamming-threshold-strict 7 \
    --surrogate-start-position 0 --surrogate-length 32 \
    --no-is-surrogate-r1 --revcomp-surrogate \
    --surrogate-hamming-threshold-strict 10 \
    --guide-barcode-pattern-regex '_([^_ ]+)[\s+]' \
    --is-guide-barcode-header --revcomp-guide-barcode \
    --guide-barcode-hamming-threshold-strict 2 \
    --retain-inference-results \
    --cores 4

# Emit one tier's count Series as TSV
crispr-correct count \
    --in result.pickle \
    --out counts.tsv \
    --tier protospacer_match_surrogate_match_barcode_match \
    --strategy ambiguous_accepted_umi_noncollapsed_counterseries
Repeat --r1 / --r2 for multi-file input. Boolean flags use --flag/--no-flag convention. Run crispr-correct map --help for the full flag list.
Save/load — parquet + JSON (cross-language durable)
# Convert a pickle into a parquet directory (portable across Python/R/Julia)
crispr-correct save --in result.pickle --out-dir result/
# Inspect in pandas:
#   pd.read_parquet("result/counts_protospacer_match_surrogate_match_barcode_match.parquet")

# Reconstruct a pickle from the directory
crispr-correct load --in-dir result/ --out result.pickle
Save/load via Python:
import crispr_ambiguous_mapping as cam
cam.save(result, "result/")      # writes parquet + manifest.json + qc.json + count_input.json
result2 = cam.load("result/")    # reconstructs the result (without the inference dict)
The per-observation inference dict (observed_guide_reporter_umi_counts_inferred) is not round-tripped through parquet — pickle it if you need it.
Post-processing — alleles subcommand
crispr-correct alleles \
    --in result.pickle \
    --tier protospacer_match_surrogate_match_barcode_match \
    --ambiguity accepted --umi-strategy noncollapsed \
    --out alleles.parquet
Requires the source pickle to have been produced with --retain-inference-results; otherwise emits a clear error pointing at the flag.
Testing
A GitHub Actions workflow (.github/workflows/ci.yml) runs the smoke tests plus the 135-mode simulation regression on every push/PR (fast subset on push, full matrix on PR), against checked-in tests/fixtures/ so no external data is needed.
This repository ships with a test suite under ../tests/ (one directory up from the package). Three layers of coverage:
tests/test_sccrispr_cell_barcode.py— pytest regression against a real scCRISPR FASTQ pair with an auto-baselined golden pickle. Runs in ~75 s.tests/simulation/— ground-truth simulated data where every read's source guide, edits, UMI, and recombination state are known; compares all 135 combinations of (parsing mode × tier × ambiguity × UMI-strategy) to expected counts. Runs in ~90 s.tests/benchmarks/— real HbF sample data withbench_results.jsonltracking wall time and peak RSS across optimization iterations.
Run everything:
cd CRISPR-Correct-Folder
ENV=/data/pinello/SHARED_SOFTWARE/envs/bfb12_envs/bb_crisprcorrect_LOCAL   # or your editable-install env
"$ENV/bin/pytest" tests/ -v
"$ENV/bin/jupyter" nbconvert --to notebook --execute --inplace tests/simulation/test_local.ipynb
Supporting documentation
One level up from the package source, in CRISPR-Correct-Folder/:
ARCHITECTURE.md— module map, pipeline stages, data models, Hamming / ambiguity algorithm.USAGE.md— recipes (protospacer-only / full-triplet+UMI / single-cell with sample_barcode), parameter cheat sheet, common pitfalls.BRANCHES.md— per-branch status (master, multi-sample-support, perf/counter-series-fix, perf/roadmap-phase1, …) and merge path.EXAMPLES.md— pointers to the in-tree production projects that use the package.IMPROVEMENTS.md— roadmap of tactical + architectural improvements across correctness, memory, performance, usability, DX.
1 maintainer

Metadata
1 maintainer
Release files for crispr-ambiguous-mapping 0.2.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| crispr_ambiguous_mapping-0.2.2.tar.gz | 78.8 kB | Without provenance | Details for crispr_ambiguous_mapping-0.2.2.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| crispr_ambiguous_mapping-0.2.2-py3-none-any.whl | Python 3 | none | any | Details for crispr_ambiguous_mapping-0.2.2-py3-none-any.whl |
Total release size: 163.4 kB
Release files / crispr_ambiguous_mapping-0.2.2.tar.gz
| Download URL | crispr_ambiguous_mapping-0.2.2.tar.gz |
|---|---|
| Size | 78.8 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
e4c32a602aa1c2b1e4922486290111205fc8d0973d3d598712f1a55f80f27b9e
|
|
BLAKE2b-256 checksum How to use checksums |
52ae4435e5b09f42ac5f8593662faa2a7155abfaceaaad4b97e3ab977369703d
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
poetry/2.4.1 CPython/3.12.10 Linux/5.4.0-204-generic
|
Release files / crispr_ambiguous_mapping-0.2.2-py3-none-any.whl
| Download URL | crispr_ambiguous_mapping-0.2.2-py3-none-any.whl |
|---|---|
| Size | 84.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
699342985ca9537e7bcddaf63122d01511d0e17afc5d7323c2955cc8f096ef06
|
|
BLAKE2b-256 checksum How to use checksums |
114d8d00bfa6720e1eb9ef047485e3248281e4ac68e6062a60559c2e6f690c6e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
poetry/2.4.1 CPython/3.12.10 Linux/5.4.0-204-generic
|
Security for crispr-ambiguous-mapping 0.2.2
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














