
Extract Croissant metadata, including the 20 Responsible AI fields, from the paper that introduces an ML dataset.

Code, benchmark and systems of CroissantMiner: Automated Extraction and Validation of Croissant Metadata for ML Datasets (NeurIPS 2026, Evaluations and Datasets Track). Paper: arXiv link follows.
News
- 1 Oct 2026: on PyPI (
pip install croissantminer), with--merge-intoto add the fields to a dataset's Croissant file on Hugging Face, a guide for NeurIPS dataset submissions and a leaderboard open to new systems. - 30 Sep 2026:
croissantminer extract, one command from a paper to a Croissant file. - 28 Sep 2026: code, dataset and demo released.
- 24 Sep 2026: accepted at NeurIPS 2026 (Evaluations and Datasets Track).
Documenting a dataset in the Croissant format, including its Responsible AI (RAI) fields, takes time, and venues such as the NeurIPS Evaluations and Datasets Track ask for it. CroissantMiner reads the paper that introduces a dataset and drafts all 30 fields of the Croissant 1.1 schema: 10 core fields (name, license, creators and others) and 20 RAI fields (how the data was collected and annotated, known biases, limitations, intended uses and others). You check the draft and publish it.
- For dataset authors: one command turns a paper into a Croissant file that passes the MLCommons validator.
- For researchers: a benchmark of 602 dataset papers with human gold annotations for 102 of them, the outputs and scores of 24 extraction systems, and a leaderboard that scores new ones with the paper's scorer.
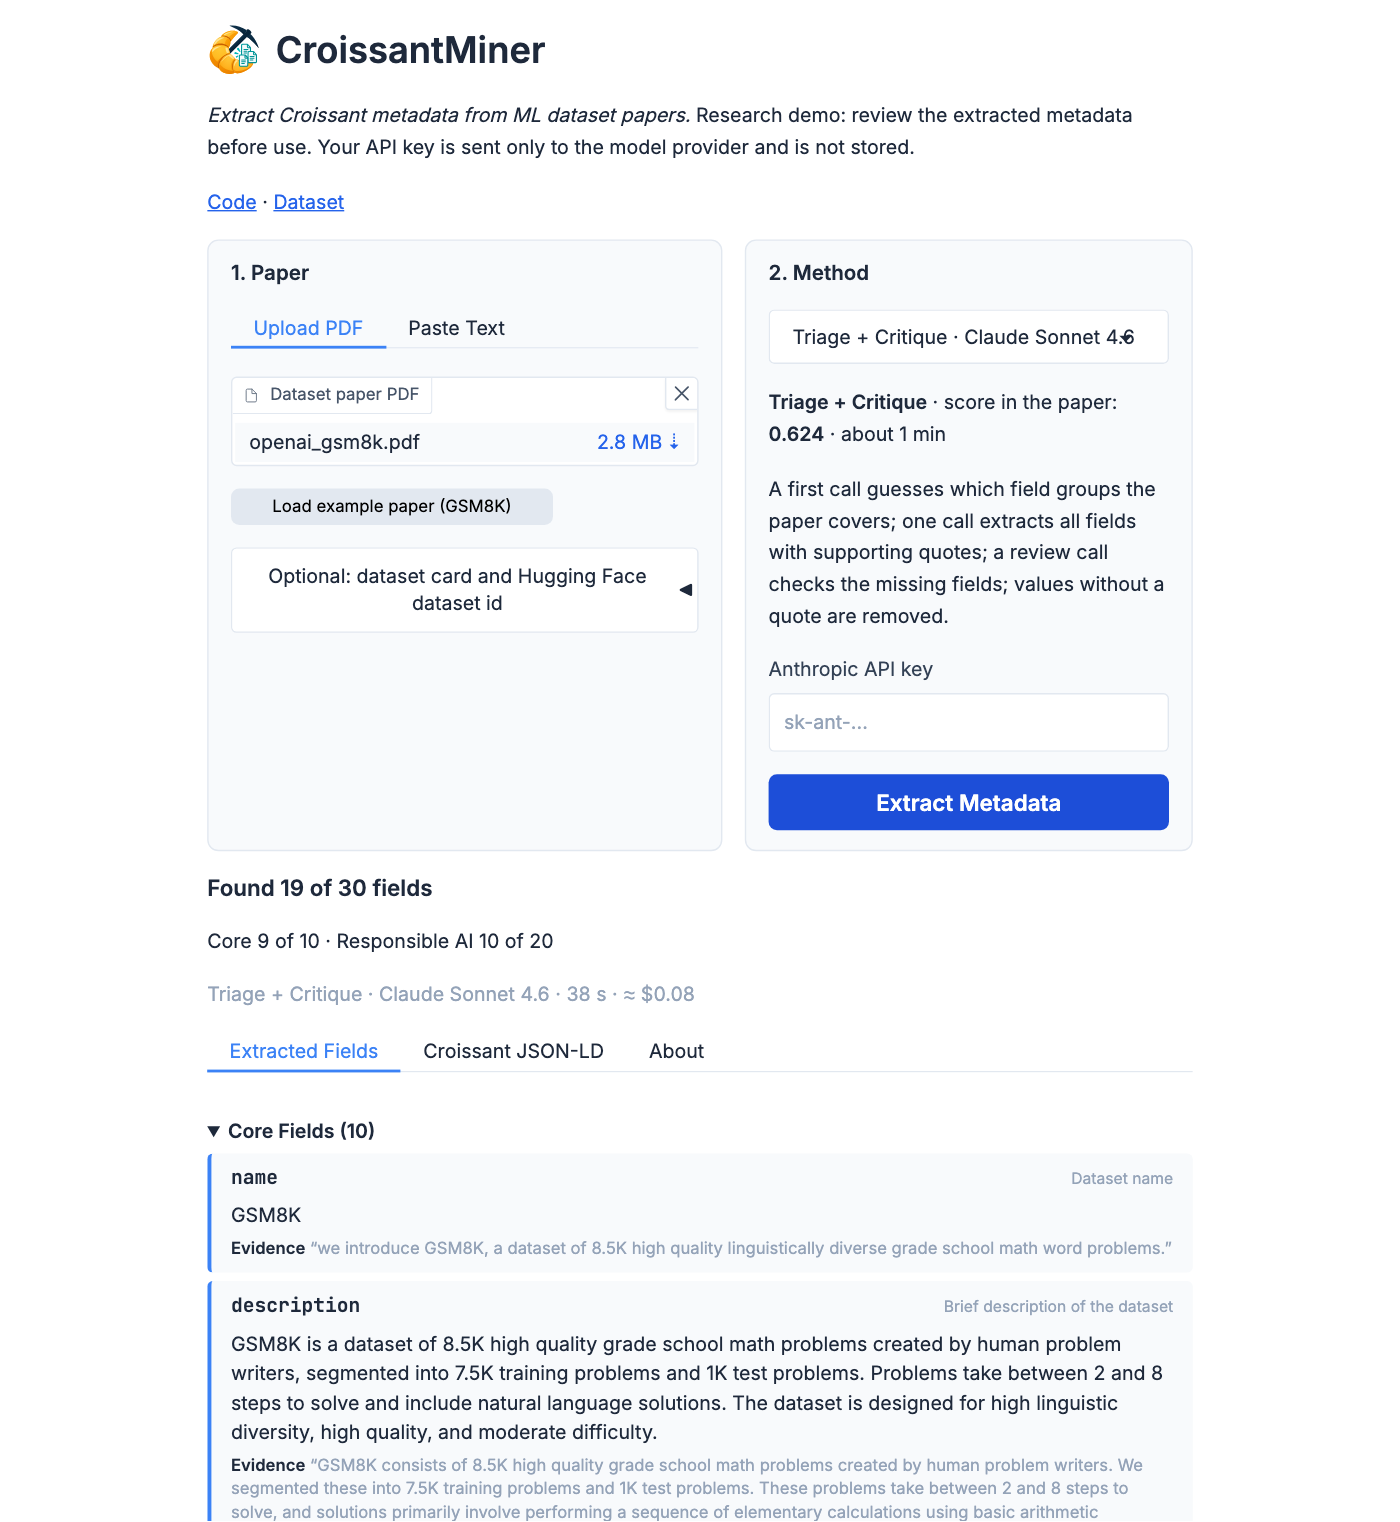
Try it in your browser
The demo runs the six systems below on a PDF you upload. It needs your own Anthropic or OpenAI API key, which is sent only to that provider and not stored.
Quick start
Python 3.10 to 3.13.
pip install "croissantminer[validate]"   # the extraction tool and the Croissant validator
export ANTHROPIC_API_KEY=...              # or put it in a .env file in the folder you run from
croissantminer extract paper.pdf
Extracting with Single-pass · Claude Sonnet 4.6 (usually about 30 s)...
Found 22 of 30 fields (core 9 of 10, Responsible AI 13 of 20) with single-pass in 35 s, about $0.06.
Not found: license, rai:dataCollectionMissingData, rai:dataCollectionTimeframe, ...
Wrote:  paper.croissant.json (Croissant 1.1)
Check:  passes the mlcroissant validator (2 recommended properties missing)
These are drafts by a language model: check each value against the paper before publishing.
Example output for GSM8K (--hf-id openai/gsm8k), shortened
{
  "@context": {
    "@language": "en",
    "@vocab": "https://schema.org/",
    "sc": "https://schema.org/",
    "cr": "http://mlcommons.org/croissant/",
    "rai": "http://mlcommons.org/croissant/RAI/",
    "dct": "http://purl.org/dc/terms/",
    "conformsTo": "dct:conformsTo"
  },
  "@type": "sc:Dataset",
  "conformsTo": "http://mlcommons.org/croissant/1.1",
  "@id": "https://huggingface.co/datasets/openai/gsm8k",
  "name": "GSM8K",
  "url": "https://github.com/openai/grade-school-math",
  "publisher": {"@type": "Organization", "name": "OpenAI"},
  "datePublished": "2021-11-18",
  "rai:dataCollection": "Problems were initially collected by hiring freelance ...",
  "rai:dataCollectionType": "Manual Human Curator, Others",
  "rai:dataAnnotationPlatform": "Upwork (upwork.com) for initial collection; Surge AI ...",
  "rai:dataBiases": "Seed questions used to assist contractors were automatically ...",
  // and description, inLanguage, cr:citeAs, creator, cr:isLiveDataset and 9 more rai: fields
}
| Option | What it does |
|---|---|
-o my_dataset.json |
choose the output file |
--method react |
use another system (list them with croissantminer methods) |
--hf-id org/name |
give the dataset's Hugging Face id, so the agentic systems can check its license and URL |
--card README.md |
read the dataset card together with the paper |
--fields values.json |
also save the extracted values with their supporting quotes |
--merge-into org/name |
add the fields to the dataset's Croissant file on Hugging Face (see Using the file) |
croissantminer validate my_dataset.json checks any Croissant file with the MLCommons validator.
From Python:
from croissantminer import extract

result = extract("paper.pdf")            # method="single-pass" by default
print(result.summary())                  # Found 22 of 30 fields (core 9 of 10, Responsible AI 13 of 20)
result.fields["rai:dataCollection"]      # one extracted value
result.croissant                         # the Croissant 1.1 file as a dict
To change the code, install from a clone instead: git clone https://github.com/berkearda/croissantminer, then
pip install -e ".[validate]" in that folder.
Which method to choose
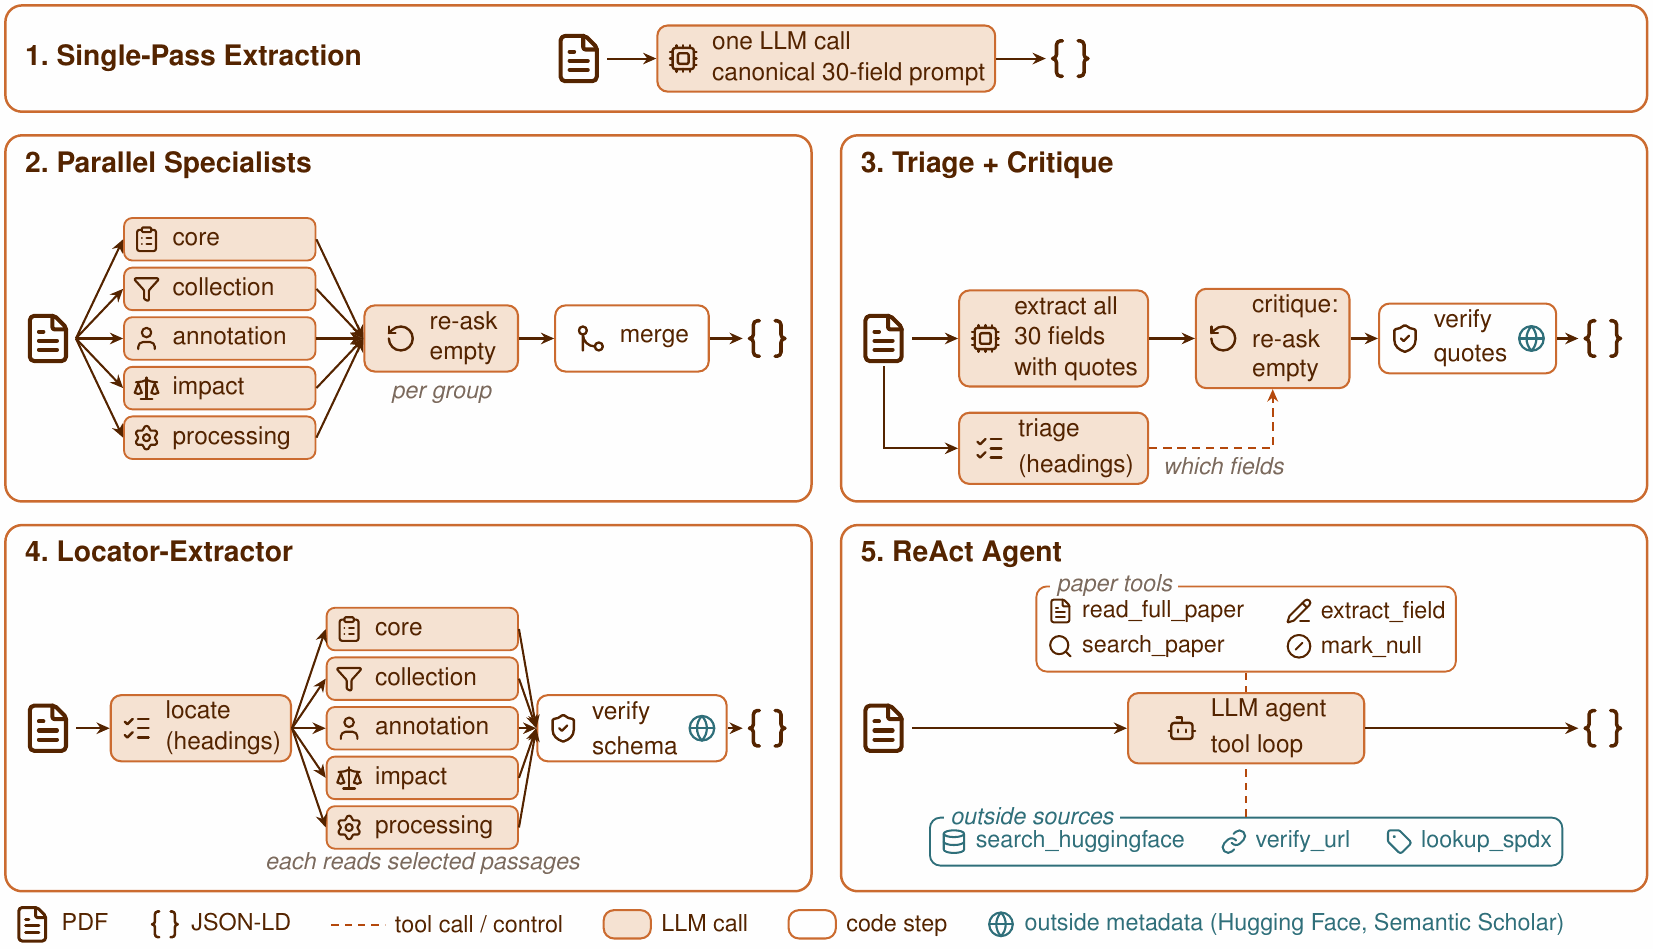
The five system designs, from the paper. Single-pass reads the whole paper in one model call; the four agentic systems split the work into steps.
All six methods are systems from the paper, with the same code and settings. Score: the composite over the 30 fields on the 88 test papers (see Results). Time and cost: one run on the 22-page GSM8K paper.
| Method | Model | Score | Time | Cost | API key |
|---|---|---|---|---|---|
single-pass (default) |
Claude Sonnet 4.6 | 0.709 | 35 s | $0.06 | ANTHROPIC_API_KEY |
single-pass-gpt |
GPT-5.4 | 0.665 | about 30 s | not measured | OPENAI_API_KEY |
react |
Claude Sonnet 4.6 | 0.652 | 80 s | $0.17 | ANTHROPIC_API_KEY |
parallel-specialists |
Claude Sonnet 4.6 | 0.647 | 15 s | $0.42 | ANTHROPIC_API_KEY |
triage-critique |
Claude Sonnet 4.6 | 0.624 | 35 s | $0.08 | ANTHROPIC_API_KEY |
locator-extractor |
Claude Sonnet 4.6 | 0.566 | 40 s | $0.09 | ANTHROPIC_API_KEY |
Start with single-pass: it is the most accurate and among the cheapest. triage-critique and
locator-extractor return a supporting quote for most values (--fields), which makes checking faster, and
react gives a reason for each field it leaves empty.
Using the file
The file describes the dataset: the core fields and the Responsible AI fields the paper supports. It does not list
the data files and their columns (Croissant's distribution and recordSet), which a data host generates from the
files themselves. Hosts such as Hugging Face, Kaggle and OpenML publish such a file for their datasets, but without
the Responsible AI fields. CroissantMiner adds its fields to the host's file:
croissantminer extract paper.pdf --merge-into org/name     # extract, then merge into the file Hugging Face generates
croissantminer merge org/name paper.croissant.json         # merge a file you already extracted
croissantminer merge host_croissant.json paper.croissant.json   # any host's file, by path or URL
The merged file keeps everything the host wrote (name, URL, license, files and columns) and adds the Responsible AI
fields and any core field the host lacks; a value the host already has is never replaced. On GSM8K, the merged file
kept Hugging Face's 3 data files and 4 record sets, gained 12 Responsible AI fields and passed the validator. A
private or gated Hugging Face dataset needs HF_TOKEN.
Submitting a dataset to NeurIPS? The step-by-step guide covers the Croissant file the Evaluations and Datasets Track requires, including the three Responsible AI items you add yourself.
Before you publish the file
- Check every value against the paper. The fields are drafts. Typical mistakes are a value the paper does not state, a detail from a related dataset, or, for an anonymous submission, the page header taken as the publisher.
- Empty fields are left out of the Croissant file, never filled with placeholders. Add what you know.
- The validator checks the format, not the content. A file that passes can still contain wrong values.
- Your paper is sent to the model provider (Anthropic or OpenAI) under your API key and their terms.
- API keys are read from the environment or a
.envfile, never from the command line, so they do not end up in your shell history.
The benchmark
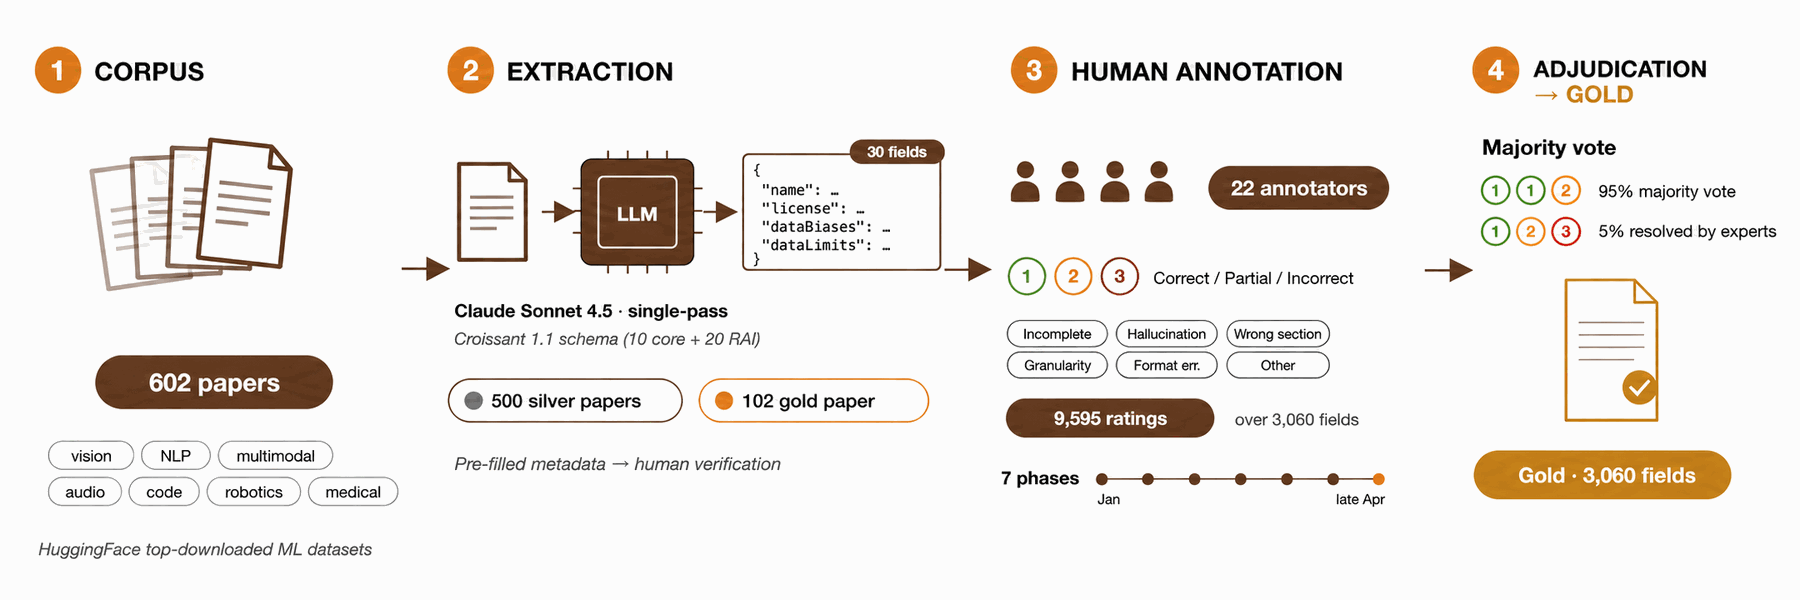
How the benchmark was built, from the paper: 602 dataset papers, drafts of all 30 fields by Claude Sonnet 4.5, 9,595 ratings by 22 annotators, and a majority vote or an expert decision for each of the 3,060 gold cells.
- Papers: 602 dataset papers. 102 have human-validated gold annotations (3,060 cells, 22 annotators) and 500 have LLM-generated silver annotations. The 102 gold papers are split into 14 development and 88 test papers.
- Systems: single-pass extraction and four agentic architectures (ReAct, Parallel Specialists, Triage + Critique, Locator-Extractor), each with several LLM backbones.
- Evaluation: rule-based scoring for the 10 core fields, an LLM judge (GLM-5) for the 20 RAI fields, and tests that check the scorer against the numbers in the paper.
- Data: the annotations, system outputs and judge verdicts are on
Hugging Face and in
data/(seedata/README.md).
Results
Test split (88 papers). Core averages the 10 core fields, RAI the 20 RAI fields, and Composite weights all 30 fields equally; 95% confidence intervals come from 2,000 bootstrap samples over papers. The gold annotations were first drafted by Claude Sonnet 4.5 and then checked and corrected by annotators, so Anthropic-family systems are marked with *. Claude Sonnet 4.5 itself is shown for reference and not ranked.
| System | Architecture | Core | RAI | Composite [95% CI] |
|---|---|---|---|---|
| Claude Sonnet 4.6* | Single-pass | 0.752 | 0.687 | 0.709 [0.688, 0.729] |
| Claude Opus 4.7* | Single-pass | 0.676 | 0.711 | 0.699 [0.665, 0.732] |
| GPT-5.4 | Single-pass | 0.653 | 0.671 | 0.665 [0.648, 0.692] |
| Qwen 3.6 35B-A3B | Single-pass | 0.698 | 0.601 | 0.634 [0.615, 0.654] |
| GLM-5.1 | Single-pass | 0.675 | 0.599 | 0.625 [0.604, 0.645] |
| Gemini 2.5 Flash | Single-pass | 0.615 | 0.616 | 0.616 [0.592, 0.639] |
| GPT-5.4 Mini | Single-pass | 0.561 | 0.614 | 0.596 [0.573, 0.620] |
| Gemini 3.1 Pro Preview | Single-pass | 0.577 | 0.596 | 0.590 [0.571, 0.609] |
| DeepSeek V3.2 | Single-pass | 0.617 | 0.555 | 0.575 [0.547, 0.604] |
| Mistral Small 4 | Single-pass | 0.616 | 0.482 | 0.527 [0.510, 0.544] |
| Llama 4 Scout 17B | Single-pass | 0.506 | 0.334 | 0.391 [0.374, 0.409] |
| ReAct (Sonnet 4.6)* | ReAct | 0.734 | 0.610 | 0.652 [0.626, 0.687] |
| ReAct (GPT-5.4) | ReAct | 0.688 | 0.603 | 0.631 [0.601, 0.663] |
| ReAct (Gemini 3.1 Pro) | ReAct | 0.723 | 0.511 | 0.582 [0.556, 0.605] |
| Parallel Specialists (Sonnet 4.6)* | Parallel Specialists | 0.699 | 0.621 | 0.647 [0.626, 0.667] |
| Parallel Specialists (GPT-5.4) | Parallel Specialists | 0.627 | 0.570 | 0.589 [0.572, 0.611] |
| Parallel Specialists (Gemini 3.1 Pro) | Parallel Specialists | 0.607 | 0.505 | 0.539 [0.518, 0.559] |
| Triage + Critique (Sonnet 4.6)* | Triage + Critique | 0.675 | 0.599 | 0.624 [0.606, 0.653] |
| Triage + Critique (GPT-5.4) | Triage + Critique | 0.592 | 0.540 | 0.557 [0.537, 0.585] |
| Triage + Critique (Gemini 3.1 Pro) | Triage + Critique | 0.513 | 0.397 | 0.436 [0.415, 0.457] |
| Locator-Extractor (Sonnet 4.6)* | Locator-Extractor | 0.643 | 0.528 | 0.566 [0.543, 0.592] |
| Locator-Extractor (GPT-5.4) | Locator-Extractor | 0.523 | 0.492 | 0.502 [0.481, 0.528] |
| Locator-Extractor (Gemini 3.1 Pro + GPT-5.4 Mini) | Locator-Extractor | 0.560 | 0.436 | 0.478 [0.456, 0.502] |
| Locator-Extractor (Gemini 3.1 Pro) | Locator-Extractor | 0.500 | 0.422 | 0.448 [0.423, 0.471] |
| Claude Sonnet 4.5* (reference) | Single-pass | 0.903 | 0.840 | 0.861 [0.830, 0.893] |
Reproducing the paper
Installation
The paper's environment uses Python 3.10 or 3.11 and the pinned versions in requirements.txt:
git clone https://github.com/berkearda/croissantminer
cd croissantminer
pip install -r requirements.txt
pip install -e .
API keys are only needed to run the systems or the judge. Copy .env.example to .env and fill in the keys for
the providers you use.
Checking the numbers
No API keys and no cost: the scores are recomputed from the stored system outputs
(data/extractions/), judge verdicts (data/judged/) and gold annotations
(data/annotations/gold.parquet), which are included in this repository.
- Check Table 2 and the per-field tables in the appendix against the published numbers:
make reproduce - Print Table 2 (Core, RAI and Composite with 95% confidence intervals, grouped as in the paper):
make table2 - Run the pairwise significance tests (paired bootstrap, Wilcoxon and McNemar with BH-FDR correction):
make significance
Running the systems and the scoring rules
docs/reproducing.md explains how to re-run each system on the benchmark (this needs API keys and the benchmark PDFs) and gives the exact scoring rules: rule-based scores for the 10 core fields, the GLM-5 judge for the 20 RAI fields, and how empty values are scored.
Tests
make test
About 120 tests, about 10 seconds, no API keys. They cover the scoring rules, the handling of model output, the command line and the Croissant output, and the check that Table 2 and Tables 5 and 6 are reproduced exactly. GitHub Actions runs them on every push, and the tool's tests on Python 3.10 to 3.13.
Extending CroissantMiner
- A new method or model for the tool: methods are registered in
croissantminer/methods.py(METHODSandrun), model backbones incroissantminer/systems/helpers.py(MODELS), and the Croissant file is built incroissantminer/croissant.py. - A new system on the benchmark:
make evaluate OUTPUTS=folder NAME=namescores it with the paper's scorer and judge model; the leaderboard explains the format and how to add your entry. - A wrong extraction, a bug or an idea: open an issue or a discussion.
Repository layout
| Path | Contents |
|---|---|
croissantminer/ |
Package: command line and Python API (cli.py, api.py), the six methods (methods.py) and the systems' code (systems/), the Croissant file (croissant.py), the extraction prompt, PDF reading and the ReAct agent |
scripts/ |
Benchmark runs of the systems, the judge, tables and figures (guide in scripts/README.md) |
evaluation/ |
Field metrics and system registry used by the scorer |
data/ |
Gold annotations, judge verdicts and system outputs |
silver/ |
Selection and extraction of the 500 silver papers |
tests/ |
Tests and the published numbers they check against |
hf_space/ |
The Hugging Face Space demo |
docs/ |
Reproduction guide (reproducing.md), README figures and the ReAct agent's prompts |
legacy/ |
Early prototype and experiments from before the paper, kept for reference and not maintained |
The scripts that read the named annotation sheets are not included, to protect the annotators'
privacy; data/annotations/gold.parquet and data/annotations/iaa.parquet are their output.
Comments that cite decisions.md or task numbers (T-###) refer to our
internal project log, which is not included.
Community
Questions and ideas go to Discussions, bugs and wrong extractions to issues. Please read CONTRIBUTING.md before opening a pull request. Everyone taking part follows the code of conduct; security problems are reported as described in SECURITY.md. Changes are listed in CHANGELOG.md.
Citation
@inproceedings{arda2026croissantminer,
  title     = {CroissantMiner: Automated Extraction and Validation of Croissant Metadata for ML Datasets},
  author    = {Arda, Berke and Yavuz, Ahmetcan and Gerry, Paul and Lobentanzer, Sebastian and
               Sarwar, Nobin and Giner-Miguelez, Joan and Chen, Kongtao and Zhang, Luyao and
               Sachan, Mrinmaya and Akhtar, Mubashara},
  booktitle = {Advances in Neural Information Processing Systems (Evaluations and Datasets Track)},
  year      = {2026}
}
License
Code: MIT (see LICENSE). Annotations: CC BY 4.0 (see the dataset card). The papers remain under their
authors' licenses.
1 maintainer

Metadata
1 maintainer
Release files for croissantminer 0.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| croissantminer-0.2.0.tar.gz | 168.2 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| croissantminer-0.2.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 342.9 kB
Release files / croissantminer-0.2.0.tar.gz
| Download URL | croissantminer-0.2.0.tar.gz |
|---|---|
| Size | 168.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
e204c9946301aefc39986a969f15fa2eaac846409840f9d81da42404a3ca353b
|
|
BLAKE2b-256 checksum How to use checksums |
e8a1267c99386b2fc07a0be79c8fb417ac63e813c21a96dba61fab38e84ac0e1
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 1, 2026.
Transparency logRelease files / croissantminer-0.2.0-py3-none-any.whl
| Download URL | croissantminer-0.2.0-py3-none-any.whl |
|---|---|
| Size | 174.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
49792c216aac20ebbadaca7c0847550782c70ed26e0a9303dc83258acb63a52e
|
|
BLAKE2b-256 checksum How to use checksums |
f0371038caeee1a2d10026da6d1952fa07c7f51cb3f80815f5cc740d139ad9d6
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 1, 2026.
Transparency log












