
Crosslingual Coreference
Coreference is amazing but the data required for training a model is very scarce. In our case, the available training for non-English languages also proved to be poorly annotated. Crosslingual Coreference, therefore, uses the assumption a trained model with English data and cross-lingual embeddings should work for languages with similar sentence structures.


Install
pip install crosslingual-coreference
Quickstart
from crosslingual_coreference import Predictor

text = (
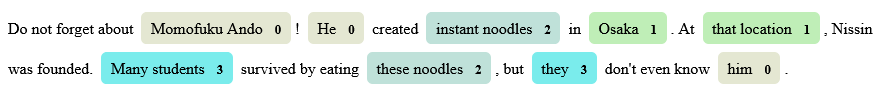
    "Do not forget about Momofuku Ando! He created instant noodles in Osaka. At"
    " that location, Nissin was founded. Many students survived by eating these"
    " noodles, but they don't even know him."
)

# choose minilm for speed/memory and info_xlm for accuracy
predictor = Predictor(
    language="en_core_web_sm", device=-1, model_name="minilm"
)

print(predictor.predict(text)["resolved_text"])
print(predictor.pipe([text])[0]["resolved_text"])
# Note you can also get 'cluster_heads' and 'clusters'
# Output
#
# Do not forget about Momofuku Ando!
# Momofuku Ando created instant noodles in Osaka.
# At Osaka, Nissin was founded.
# Many students survived by eating instant noodles,
# but Many students don't even know Momofuku Ando.
Models
As of now, there are two models available "spanbert", "info_xlm", "xlm_roberta", "minilm", which scored 83, 77, 74 and 74 on OntoNotes Release 5.0 English data, respectively.
- The "minilm" model is the best quality speed trade-off for both mult-lingual and english texts.
- The "info_xlm" model produces the best quality for multi-lingual texts.
- The AllenNLP "spanbert" model produces the best quality for english texts.
Chunking/batching to resolve memory OOM errors
from crosslingual_coreference import Predictor

predictor = Predictor(
    language="en_core_web_sm",
    device=0,
    model_name="minilm",
    chunk_size=2500,
    chunk_overlap=2,
)
Use spaCy pipeline
import spacy

text = (
    "Do not forget about Momofuku Ando! He created instant noodles in Osaka. At"
    " that location, Nissin was founded. Many students survived by eating these"
    " noodles, but they don't even know him."
)


nlp = spacy.load("en_core_web_sm")
nlp.add_pipe(
    "xx_coref", config={"chunk_size": 2500, "chunk_overlap": 2, "device": 0}
)

doc = nlp(text)
print(doc._.coref_clusters)
# Output
#
# [[[4, 5], [7, 7], [27, 27], [36, 36]],
# [[12, 12], [15, 16]],
# [[9, 10], [27, 28]],
# [[22, 23], [31, 31]]]
print(doc._.resolved_text)
# Output
#
# Do not forget about Momofuku Ando!
# Momofuku Ando created instant noodles in Osaka.
# At Osaka, Nissin was founded.
# Many students survived by eating instant noodles,
# but Many students don't even know Momofuku Ando.
print(doc._.cluster_heads)
# Output
#
# {Momofuku Ando: [5, 6],
# instant noodles: [11, 12],
# Osaka: [14, 14],
# Nissin: [21, 21],
# Many students: [26, 27]}
Visualize spacy pipeline
This only works with spacy >= 3.3.
import spacy
from spacy.tokens import Span
from spacy import displacy

text = (
    "Do not forget about Momofuku Ando! He created instant noodles in Osaka. At"
    " that location, Nissin was founded. Many students survived by eating these"
    " noodles, but they don't even know him."
)

nlp = spacy.load("nl_core_news_sm")
nlp.add_pipe("xx_coref", config={"model_name": "minilm"})
doc = nlp(text)
spans = []
for idx, cluster in enumerate(doc._.coref_clusters):
    for span in cluster:
        spans.append(
            Span(doc, span[0], span[1]+1, str(idx).upper())
        )

doc.spans["custom"] = spans

displacy.render(doc, style="span", options={"spans_key": "custom"})
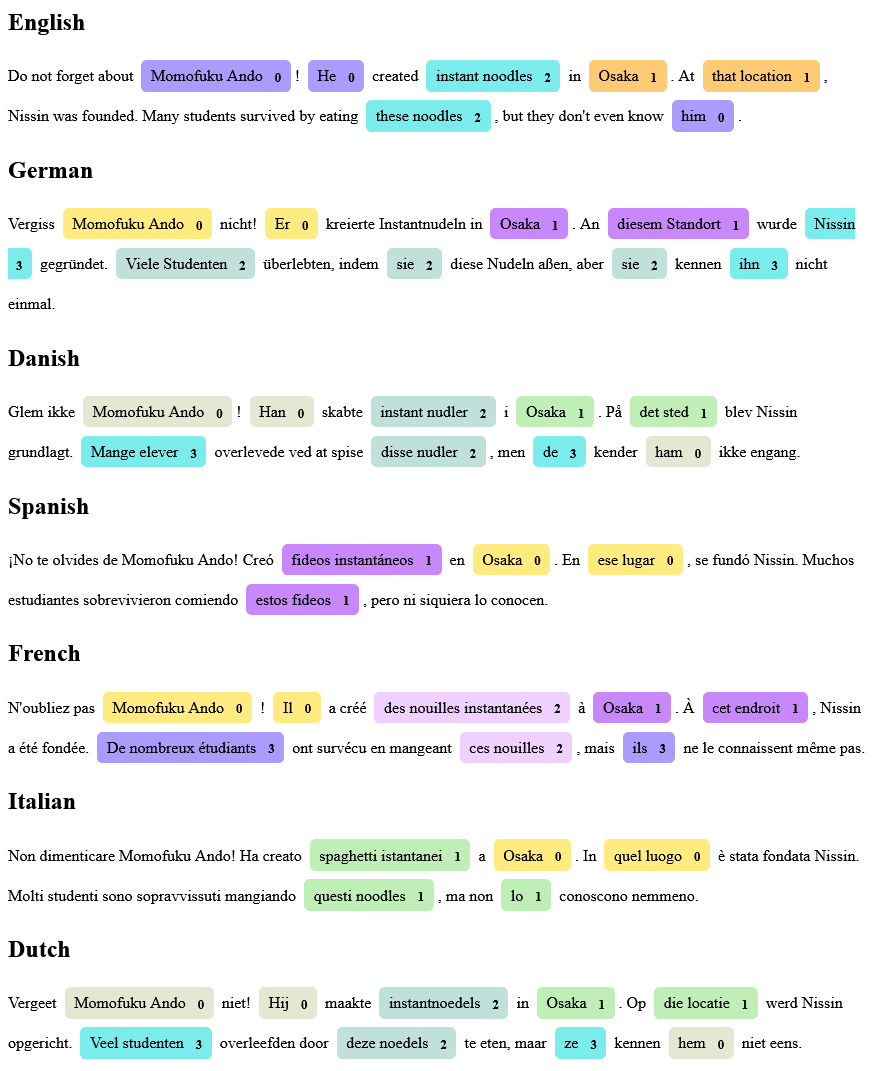
More Examples
2 maintainers


Metadata
2 maintainers
Release files for crosslingual-coreference 0.3.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| crosslingual-coreference-0.3.1.tar.gz | 11.7 kB | Without provenance | Details for crosslingual-coreference-0.3.1.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| crosslingual_coreference-0.3.1-py3-none-any.whl | Python 3 | none | any | Details for crosslingual_coreference-0.3.1-py3-none-any.whl |
Total release size: 24.5 kB
Release files / crosslingual-coreference-0.3.1.tar.gz
| Download URL | crosslingual-coreference-0.3.1.tar.gz |
|---|---|
| Size | 11.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
cbd46de0afedf75d3315c39e9fecb851112e29cb7d8b3d85fdb7eb39ac63c25e
|
|
BLAKE2b-256 checksum How to use checksums |
81a07dca701ec4ad2eef0df1de5d5952dbae2c4c86ade79fb9a4e23bd36dd1d4
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
poetry/1.2.1 CPython/3.10.11 Darwin/22.5.0
|
Release files / crosslingual_coreference-0.3.1-py3-none-any.whl
| Download URL | crosslingual_coreference-0.3.1-py3-none-any.whl |
|---|---|
| Size | 12.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
bd44ec22b2a1a02eb03203d04c4c92d819e2ac929baa2b825f21de7106beeedd
|
|
BLAKE2b-256 checksum How to use checksums |
2b8de4ad53fd3a0f805658a140bd8e0affee4436a05831141660dc2a4103fcda
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
poetry/1.2.1 CPython/3.10.11 Darwin/22.5.0
|
Security for crosslingual-coreference 0.3.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














