
ctxprune
Cut big tool outputs, logs and documents in half before your LLM reads them, without mangling IDs. A 140M-parameter model deletes the least useful words; everything it keeps is passed on byte for byte. Runs on CPU in about 0.1 s per 500 tokens. Apache-2.0.
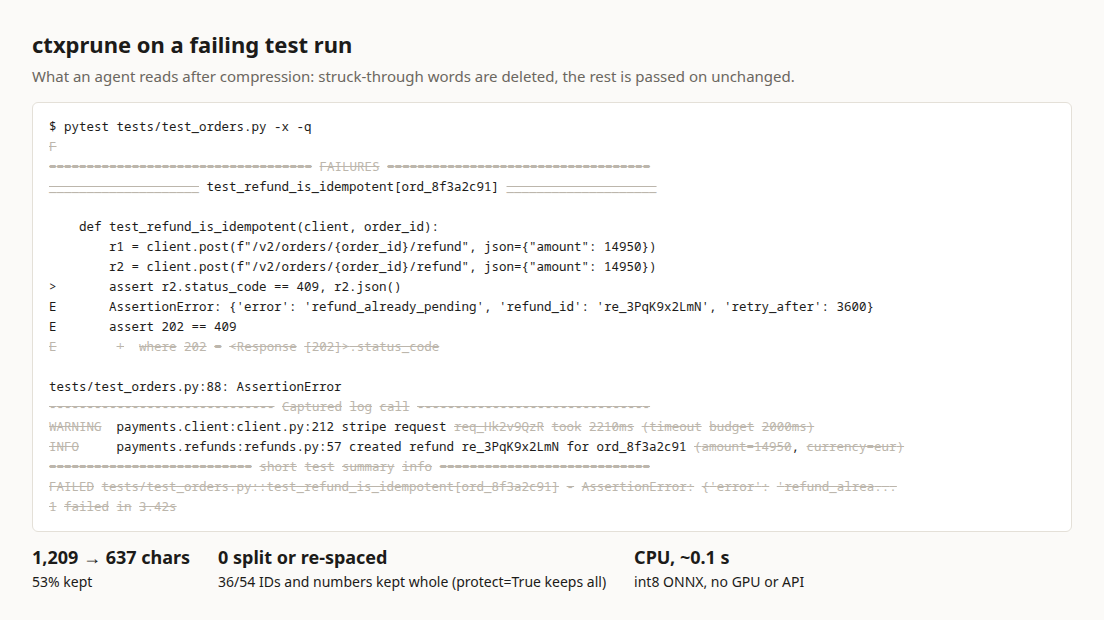
At 50% of tokens kept, a reader LLM answers 51.5% of SQuAD v2 + HotpotQA questions exactly from ctxprune's output vs 36.5% from headroom's Kompress-v2 (400 questions, 95% CI of the gap +10.5 to +19.5; the reader there is Qwen3.8-27B, which also labeled ctxprune's training data, so this may flatter ctxprune), and 68.8% vs 53.4% for LLMLingua-2-large on our agent-text set with an independent reader (DeepSeek V4 Flash). Try it in your browser (nothing is uploaded).
Quick start
pip install ctxprune
ctxprune build.log --keep 0.5          # or: some_command | ctxprune --keep 0.33 --protect
import ctxprune
short = ctxprune.prune(tool_output, keep=0.5)    # protect=True never drops IDs, numbers or paths
Which one do I use?
| You want to... | Use | |
|---|---|---|
| Shrink big Bash/MCP outputs inside Claude Code | ctxprune install claude-code |
or the plugin: /plugin install ctxprune --marketplace riceharvest/ctxprune |
| Compress a file or a pipe from the shell | ctxprune FILE --keep 0.5 |
--protect, --stats, reads stdin |
| Call it from Python | ctxprune.prune(text, keep=0.5) |
Compressor for batching and options |
| Call it from another language / avoid the model load | ctxprune serve |
POST localhost:8719/compress {"text": ...} |
| Compress retrieved documents in LangChain | CtxpruneDocumentCompressor |
see below |
| Compress retrieved nodes in LlamaIndex | CtxpruneNodePostprocessor |
see below |
| Use it inside LLMLingua | PromptCompressor(model_name="darioooooo0o/ctxprune-small", use_llmlingua2=True) |
needs LLMLingua#261 |
| Run the raw model (ONNX / transformers / transformers.js) | model card | label 1 = keep |
Agents setting this up for a user: see AGENTS.md.
Claude Code
pip install ctxprune && ctxprune install claude-code # undo: ctxprune uninstall claude-code
This adds a PostToolUse hook. Bash and MCP outputs over 6,000 characters are compressed to about half before
Claude reads them, with identifiers, numbers and paths always kept. Claude gets a one-line note saying so, and the
full output is saved under ~/.cache/ctxprune/outputs/ so it can grep the original if a detail is missing.
Commands that print files Claude may edit (cat, head, sed -n, git diff/show) and the Read/Grep tools are
never touched, and a command containing CTXPRUNE_OFF=1 is passed through. If anything fails, Claude gets the
original output. Settings: CTXPRUNE_RATE (0.5), CTXPRUNE_MIN_CHARS (6000). Each compressed call loads the model
(~2 s); run ctxprune serve in the background and the hook uses it instead.
As a plugin, without touching settings files (needs ctxprune on PATH, or uv so it can run via uvx):
/plugin install ctxprune --marketplace riceharvest/ctxprune. The plugin does not pre-download the model, so the
first large outputs pass through uncompressed while it downloads (~180 MB); run ctxprune serve once, or
python -c "import ctxprune; ctxprune.prune('x')", to fetch it up front.
Saved originals in ~/.cache/ctxprune/outputs/ are raw tool output (which can include secrets) and are never
deleted automatically; clear them with rm -rf ~/.cache/ctxprune/outputs.
LangChain and LlamaIndex
from ctxprune.integrations import CtxpruneDocumentCompressor    # LangChain
retriever = ContextualCompressionRetriever(base_compressor=CtxpruneDocumentCompressor(rate=0.5),
                                           base_retriever=base_retriever)

from ctxprune.integrations import CtxpruneNodePostprocessor     # LlamaIndex
engine = index.as_query_engine(node_postprocessors=[CtxpruneNodePostprocessor(rate=0.5)])
How good is it, honestly
- Compression loses information. On our agent set, QA accuracy goes from 91.8% uncompressed to 68.8% at 50% kept. Use it where the token savings are worth that, e.g. long logs, test output, search results, retrieved docs.
- Weak spots: source code (the teacher rarely deleted code, so the model keeps most of it) and non-English web prose, where LLMLingua-2-large still does better.
- Our 378-question set is from our own training distribution, and the neutral SQuAD/HotpotQA comparison used our labeling teacher as the reader; neither is a fully independent benchmark. Per-source tables and caveats: model card.
By @imdariotoo.
Reproducing the model
Why: LLMLingua-2 (Microsoft, Mar 2024) was trained only on meeting transcripts under CC BY-NC-SA labels. On agent tool outputs it loses or mangles about half of all identifiers (UUIDs, IPs, paths, versions) and breaks JSON.
Pipeline
| step | script | where | notes |
|---|---|---|---|
| corpus | scripts/build_corpus.py |
CPU, ~2 min | ranged parquet reads from 8 permissive sources; split per repo/server/site |
| labels | scripts/label.py |
teacher LLM (scripts/teacher_up.sh) |
deletion-only compression, LCS-aligned to atoms; cached |
| train | scripts/train.py |
any torch device (we used an Intel Arc Pro B70) or CPU | token classifier, label 1 = keep (LLMLingua-2 convention) |
| quick eval | scripts/eval_quick.py |
CPU | identifiers lost, JSON validity, char ratio vs LLMLingua-2 |
| QA eval | scripts/eval_qa.py questions/answer |
teacher LLM | can a reader still answer from the compressed text |
scripts/run_v1.sh runs corpus and labels; scripts/after_label.sh runs everything after them.
Data sources (all permissive)
SWE-smith trajectories (MIT), SWE-rebench OpenHands trajectories (CC BY 4.0), Toucan-1.5M MCP tool calls (Apache-2.0), github-code-clean filtered to MIT/Apache/BSD/ISC files, FineWeb-Edu and FineWeb-2 (ODC-BY), oasst2 (Apache-2.0). Every chunk records its dataset, license and source reference. Teacher: Qwen3.8-27B GPTQ (Apache-2.0 outputs).
Training more after an eval
Nothing has to be redone:
- More data, same mix. Rerun
build_corpus.pyinto the same directory with a larger--total. Sampling is deterministic, and dataset revisions are pinned inchunks/revisions.json, so every source file becomes a superset of the old one. To weight a domain up, add--mix toucan_mcp=0.3. - Label only the new chunks. Rerun
label.py. The teacher cache is keyed by (prompt version, model, text), so old chunks come back from disk. - Continue training from the previous model:
train.py --data <dir> --init-from runs/v1-mmbert-small/final --out runs/v2-...(or--resumeto continue an interrupted run from its checkpoint).--dataaccepts several directories, to mix label sets. - Re-run evals. Question and answer caches mean only new contexts cost LLM calls.
Changing the teacher prompt bumps PROMPT_VERSION in ctxprune/teacher.py, which
invalidates the cache on purpose.
Tests
uv run pytest: atom round-trips, identifier atoms, CJK handling, LCS
alignment, chunk budgets, split stability and cache resume.
1 maintainer

Metadata
1 maintainer
Release files for ctxprune 0.2.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| ctxprune-0.2.1.tar.gz | 34.6 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| ctxprune-0.2.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 70.8 kB
Release files / ctxprune-0.2.1.tar.gz
| Download URL | ctxprune-0.2.1.tar.gz |
|---|---|
| Size | 34.6 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
2535374ea6a21e49d1f8954577c07d4375ff678cdf4f419c84daf3ac3db167db
|
|
BLAKE2b-256 checksum How to use checksums |
b73d3248245a6fa6c5080854ca995d39e5f621799e8eea67dcb05ad61c66f72c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 12, 2026.
Transparency logRelease files / ctxprune-0.2.1-py3-none-any.whl
| Download URL | ctxprune-0.2.1-py3-none-any.whl |
|---|---|
| Size | 36.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
ca7e5406becedab00dc3acde84faaa295451c9a8369580ab85e3fd391525dc18
|
|
BLAKE2b-256 checksum How to use checksums |
7d53c824bcf984fe2da97760f8e96c50197a46660fd80433adfa535a687a1a78
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 12, 2026.
Transparency log













