



cusvna (CUDA Self-Validated Numerical Analysis) is a header-only C++17 library for CUDA providing
computations with guaranteed error bounds. It implements affine arithmetic
(AA), a model that keeps track of the correlations between quantities and therefore yields much tighter
bounds than interval arithmetic on long computations. Two models are available: full affine arithmetic
(cusvna::AA) and the cheaper fixed-size AF1 forms (cusvna::AF1), see AF1 forms.
- Rigorous: the exact real result of a computation always lies within the computed bounds, including floating point rounding errors.
- GPU friendly: no dynamic allocation, affine forms live in registers. Works in
__device__code compiled with nvcc or at runtime with NVRTC, and in host code compiled with nvcc. - Complete: arithmetic, all usual elementary functions of the CUDA math API, signed distance
helpers (
min,max,hypot,smooth_min, ...) and rigorous predicates, infloatanddouble.
Typical applications are robust root isolation and subdivision schemes (quadtrees, octrees), ray tracing of implicit surfaces and level sets, and any numerical method that must not miss a solution. A Vulkan and Slang port of the AF1 forms is available as vusvna, see vusvna.
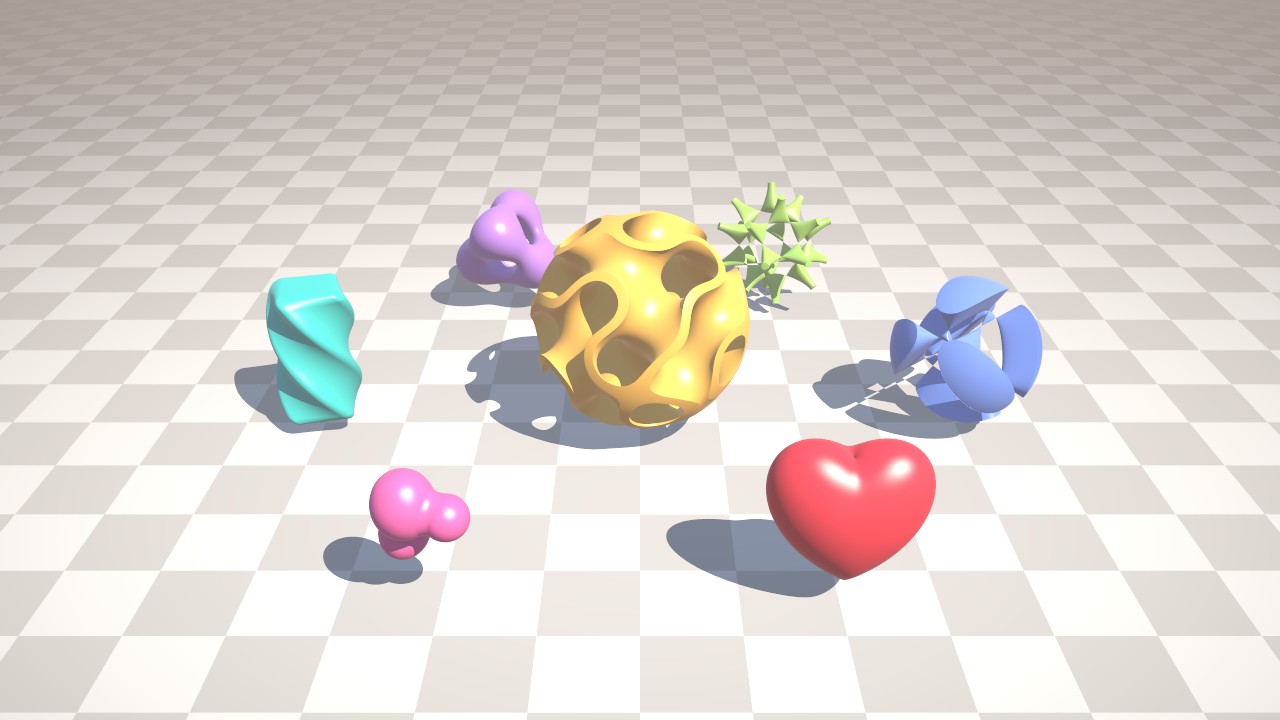
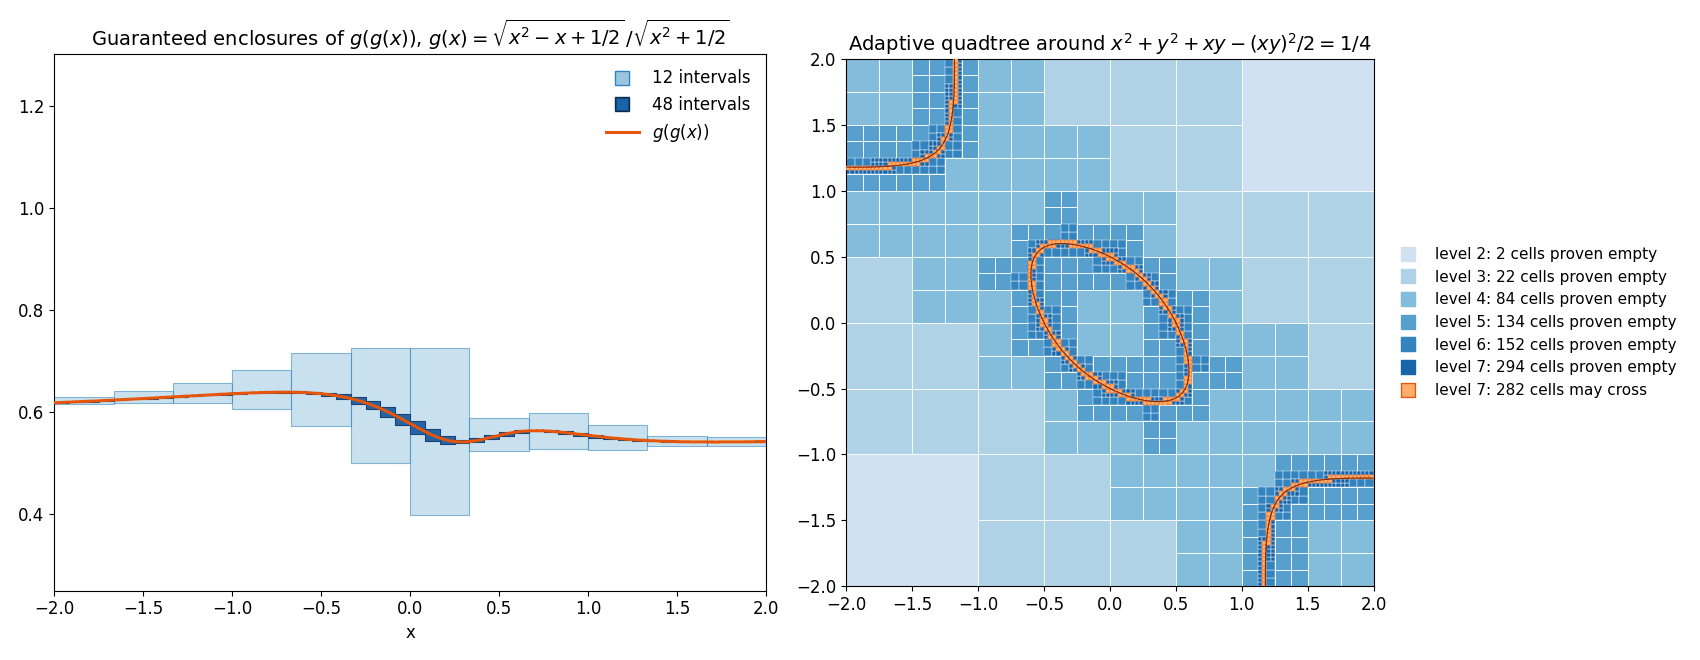
Left: guaranteed enclosures of a function on 12 and 48 intervals. Right: adaptive quadtree around an implicit curve, cells proven empty are discarded at each level. Computed on the GPU with cusvna::AA<float> (1D) and cusvna::AF1<float,2> (2D).
Getting started
The examples compile their CUDA kernels at runtime with CuPy (NVRTC) and only need an
NVIDIA GPU, the CUDA toolkit and Python. The ray tracing examples (04_raytracing.py and 05_levelset.py)
also need the OptiX 7.4 SDK for
python-optix.
git clone --recursive https://github.com/keckj/cusvna.git
cd cusvna
python3 -m venv .venv
source .venv/bin/activate
python3 -m pip install -r examples/requirements.txt
python3 examples/02_quadtree.py   # adaptive quadtree around a 2D curve
python3 examples/05_levelset.py   # interactive ray tracing of animated level sets (needs OptiX)
See Examples for the other scripts, Installation to use cusvna in your own kernels and Tests to check it on your GPU.
Example
#include <cusvna/aa.cuh>

using Interval = cusvna::Interval<float>;
using AA = cusvna::AA<float>;

/* returns false only if the unit circle certainly does not cross the box X x Y */
__device__ bool may_contain_root(const Interval& X, const Interval& Y) {
    const auto x = AA::from_interval<0>(X);   /* input noise symbols are numbered by the user */
    const auto y = AA::from_interval<1>(Y);
    const auto f = sqr(x) + sqr(y) - 1.0f;    /* f(x, y) is guaranteed to lie in f.interval() */
    return possibly_zero(f);
}
Functions are found by argument dependent lookup, so the same templated code can be evaluated on floating
point numbers and on affine forms. Replacing cusvna::AA<float> by cusvna::AF1<float, 2> (from
<cusvna/af1.cuh>) evaluates the same code with AF1 forms.
Installation
cusvna is header-only: add the root of this repository to your include paths and include <cusvna/aa.cuh>
and/or <cusvna/af1.cuh>.
The headers are also available as a Python package, for instance to compile kernels at runtime with NVRTC:
python3 -m pip install cusvna
python3 -m cusvna --include   # include directory to pass as -I to nvcc or NVRTC
import cusvna
options = ("--std=c++17", f"-I{cusvna.get_include()}")  # plus the CUDA include directory
Requirements:
- CUDA 11 or newer (the library uses
cuda::stdfrom libcu++, shipped with the CUDA toolkit), - C++17 (
nvcc -std=c++17,nvrtc --std=c++17), - no fast math, even with
CUSVNA_IGNORE_ROUNDING, see Guarantees and Rounding modes.
With NVRTC (for instance through CuPy), pass the CUDA include directory and the root of this repository
as include paths, see examples/utils.py.
Affine arithmetic in cusvna
An affine form represents an unknown real quantity as
x = b + x_1 e_1 + ... + x_N e_N + err e_err, e_i, e_err unknown in [-1, 1]
The noise symbols e_i are shared between forms and carry correlations: x - x is exactly zero, while
interval arithmetic would return [-2r, 2r]. Nonlinear operations approximate their result by an affine
function of their input and attach the approximation error to a new noise symbol. The error term
err accumulates rounding errors and is independent from everything else.
In cusvna, noise symbols are identified at compile time by types: cusvna::AA<T, Is...> stores exactly
sizeof...(Is) coefficients and the type of the result of an operation is computed at compile time from
the types of its operands.
- Input symbols are created by
AA::from_interval<K>(interval), whereKidentifies the input. Two forms created with the sameKrepresent the same quantity. The macronew_aa_from_interval(interval)uses a uniqueKfor each line of code (not available with NVRTC). - Since the types of the symbols created by nonlinear operations only depend on the types of the operands, each of them also carries a 64-bit runtime tag: a hash of the content of the operands. Symbols with equal tags represent the same quantity, symbols with different tags are merged conservatively.
AF1 forms
cusvna::AF1<T, N> implements the AF1 model of Messine: a form has exactly N input noise symbols and a
single error term,
x = b + x_1 e_1 + ... + x_N e_N + err e_err
Affine operations are exact up to rounding as in AA, but nonlinear operations (products of forms, elementary
functions) add their approximation error to err instead of creating a new noise symbol. Forms have a
constant size of N + 2 scalars and need no symbol types, tags or merges, which makes them cheaper. The
price is that correlations between results of nonlinear operations are lost: on x = [0.1, 0.3],
sin(x) - sin(x) has a radius of 1e-3 (twice the approximation error of sin) with AF1, and 2e-8
(rounding errors only) with AA.
- Input symbols are created by
AF1::from_interval<K>(interval)with0 <= K < N(checked at compile time), orAF1::variable(k, interval)with a runtime index.AF1::constant(interval)encloses an interval without any symbol. - All the operations listed below are available with the same names and the same guarantees, forms of different models cannot be mixed.
AF1 is a good default when nonlinear subexpressions are not reused, which is the case of most signed distance functions. AA is tighter when the results of nonlinear operations appear several times in an expression. See Performance.
Supported operations
| Operations | Notes |
|---|---|
+, -, *, / between forms and with scalars |
|
reciprocal(x) |
min-range approximation, entire if 0 belongs to x |
sqrt(x), exp(x), log(x) |
Chebyshev approximations |
sqr(x), pow(x, int n) |
sqr(x) is tighter than x*x |
pow(x, T y) |
for x >= 0 (x > 0 if y < 0) |
pow(x, y), pow(c, y) with an affine exponent |
exp(y*log(x)), for x > 0 |
rsqrt(x), cbrt(x), rcbrt(x) |
|
exp2(x), exp10(x), expm1(x), log2(x), log10(x), log1p(x) |
|
sin(x), cos(x), tan(x), cot(x) |
entire if a pole belongs to x |
sinpi(x), cospi(x) |
sin(pi*x) and cos(pi*x) without rounding pi*x, exact at integers and half-integers |
atan(x), asin(x), acos(x), atan2(y, x) |
atan2 returns [-pi, pi] when the input box meets the branch cut y = 0, x <= 0 |
sinh(x), cosh(x), tanh(x), asinh(x), acosh(x), atanh(x) |
|
erf(x), erfc(x), normcdf(x) |
|
tgamma(x), lgamma(x) |
for x > 0 only (entire otherwise) |
abs(x), positive_part(x) |
positive_part(x) = max(x, 0) |
min(x, y), max(x, y), fmin, fmax, clamp(x, lo, hi) |
min(x, y) + max(x, y) cancels to x + y |
hypot(x, y), hypot(x, y, z), norm3d, rhypot, rnorm3d |
|
fma(x, y, z), lerp(a, b, t), smoothstep(e0, e1, x) |
|
smooth_min(a, b, k), smooth_max(a, b, k) |
polynomial smooth minimum of distances |
floor, ceil, trunc, round, rint, fract, modf(x, &ip) |
exact when no discontinuity is crossed, else the range of the result |
fmod(x, y), remainder(x, y) |
y may be a scalar or a form, exact and correlated with x and y when the integer quotient is known |
remquo(x, y, &quo_lo, &quo_hi) |
returns the range of the whole integer quotient rint(x/y) (not only its low bits as in C), quo_lo == quo_hi when it is known |
certainly_lt, certainly_le, certainly_gt, certainly_ge, possibly_zero |
rigorous predicates |
x.interval(), x.sign(), x.radius(), x.is_entire() |
conversions back to intervals |
hull, intersect, contains, subset, is_empty |
on cusvna::Interval |
These cover all the operations of libaffa, which is used as a reference
in the tests (inv is reciprocal, cotan is cot and half_plane is positive_part).
Guarantees
For any operation, the exact real result of the computation belongs to the range of the computed form,
including rounding errors. In particular x.interval(), x.sign() and the predicates are rigorous.
Bounds are never NaN.
- Rounding: bounds are rounded outward, with the directed rounding instructions of the hardware in device code and with emulated directed rounding in host code, and the rounding errors of affine operations are accumulated in the error term, see Rounding modes.
- Nonlinear functions: the residual
f(x) - alpha*xis bounded with outward rounding by splitting the input range into pieces wherefis convex or concave. The results of math library functions are assumed to be within twice the maximum error documented in the CUDA math API (seecusvna/approx.cuh).tgammaandlgammaare restricted to positive inputs where this assumption holds; CUDA does not bound the relative error oflgammafor negative inputs close to its zeros. - Domains: if an input range is not entirely inside the domain of a function, the result is entire
(its interval is
[-inf, inf]), except forsqrt,pow(x, T y),acosh,asinandacoswhich are evaluated on the part of their input inside their domain when it is not empty. Overflows produce entire forms. Entire forms propagate through all operations, except through bounded functions such assin.
These guarantees hold under the following assumptions:
- IEEE-754 binary32 (
float) or binary64 (double) arithmetic in round-to-nearest mode, - no fast math: do not compile with
--use_fast_math(nvcc, nvrtc) or-ffast-math(host),-ftz=true,-prec-div=falseor-prec-sqrt=false, - host code must not contract floating point operations into fused multiply-adds (
-ffp-contract=off, which is the default of gcc with-std=c++17). Device code uses non-contractible intrinsics, - hash collisions (AA only): a collision between the runtime tags of two different values would wrongly
correlate them. For non-adversarial inputs the probability is about
2^-64per comparison of two generated symbols of the same type.
Rounding modes
The rounding errors are handled in one of three ways, selected at compile time:
| Mode | Selected by | Rigorous | Speed on GPUs | Use |
|---|---|---|---|---|
| native | default in device code | yes | reference | GPU code |
| emulated | host code, or CUSVNA_EMULATED_ROUNDING in device code |
yes | 2 to 6 times slower | host code, tests |
| ignore | CUSVNA_IGNORE_ROUNDING |
no | up to 2.5 times faster | visualization |
- native: device code uses the directed rounding instructions of the hardware (
__fadd_ru,__dmul_rd, ...), which are exact and as fast as round-to-nearest ones. The rounding errors of affine operations are computed exactly (TwoSum, fused multiply-add residuals) and accumulated in the error term, and the results of math library functions are enclosed by twice their documented maximum error. - emulated: host code has no directed rounding instructions, so everything runs in the default
round-to-nearest mode and outward rounding is emulated with error-free transformations (TwoSum, TwoProd):
they detect exact operations and the sign of the rounding errors, and inexact bounds are moved outward by
at least one ulp. This is the only mode of host code. Defining
CUSVNA_EMULATED_ROUNDINGselects it in device code too, which gives the same results as host code but is only useful for testing. - ignore: when
CUSVNA_IGNORE_ROUNDINGis defined, cusvna ignores all floating point rounding errors: directed operations become round-to-nearest operations, the error terms of affine operations are not computed, the results of math library functions are taken as exact, and operations may be contracted into fused multiply-adds. Approximation errors of nonlinear functions are still bounded. The results are no longer rigorous: enclosures may miss the exact result by a few ulps, and deep subdivisions may discard cells that contain zeros. This mode is meant for visualization.
The examples select the mode with --rounding native|emulated|ignore, --fast being a shortcut for
--rounding ignore. See Performance for the timings of the three modes.
Fast math is strictly discouraged, even with CUSVNA_IGNORE_ROUNDING. Its approximate math functions
(__sinf, __expf, ...) are far less accurate than the CUDA math library and break the enclosures: with
--use_fast_math, 05_levelset.py misses most surfaces and runs 5 times slower because interval marching
cannot conclude.
Examples
The examples directory contains Python scripts that compile CUDA kernels at runtime with CuPy (NVRTC):
| Script | Description |
|---|---|
00_1d.py |
enclosures of a 1D function on refined subdivisions |
01_2d.py |
sign classification of a 2D function on refined grids |
02_quadtree.py |
adaptive quadtree refinement around the zero level set of a 2D function |
03_octtree.py |
adaptive octree refinement around an implicit surface, meshed with marching cubes |
04_raytracing.py |
ray tracing of implicit surfaces with OptiX |
05_levelset.py |
interactive OptiX viewer of level sets |
With the virtual environment of Getting started activated:
python3 examples/02_quadtree.py                       # AF1 forms
python3 examples/02_quadtree.py aa                    # AA forms
python3 examples/02_quadtree.py --rounding emulated   # AF1 forms, emulated rounding
python3 examples/02_quadtree.py --fast                # AF1 forms, rounding errors ignored
02_quadtree.py to 05_levelset.py take an optional af1 (default) or aa argument selecting the affine
forms, and a --rounding option selecting the rounding mode (--fast for
--rounding ignore). The examples never use fast math. The OptiX examples require the OptiX SDK and the
python-optix submodule.
05_levelset.py opens a window, or renders offscreen with --output image.png (see --help for the time,
mode, method, samples and size). 05_levelset.py --benchmark times the rendering offscreen at 1 spp over the
animation, with the same protocol as the level set example of vusvna. The level sets are found by marching
along the rays with affine forms of the ray parameter, either by a sign test on the interval of the function
or with a root window that skips the parts of the ray where the affine form proves that there is no root.
The shapes cast shadows and are antialiased by accumulating jittered samples while the scene is paused.
| Key | Action |
|---|---|
ENTER |
rendering mode: shaded, normals, marching steps |
M |
marching method: sign test, root window |
A |
samples per pixel |
SPACE |
pause the animation (images accumulate while paused) |
+/-, UP/DOWN |
animation speed |
| left / right mouse button, wheel | orbit, look around, zoom |
Q, ESC |
quit |
Performance
Time of the evaluations on an RTX 5090 (float) in the three rounding modes, for AF1 and
AA forms. 05_levelset.py is timed with --benchmark (1024x768, 1 sample per pixel, root window marching,
median over the animation).
| Benchmark | AF1 native | AF1 emulated | AF1 ignore | AA native | AA emulated | AA ignore |
|---|---|---|---|---|---|---|
02_quadtree.py, level 22 |
0.24 ms | 0.58 ms | 0.12 ms | 0.29 ms | 0.64 ms | 0.12 ms |
02_quadtree.py, level 25 |
2.4 ms | 6.3 ms | 0.70 ms | 2.9 ms | 7.0 ms | 0.74 ms |
03_octtree.py, level 11 (20M active cells) |
1.7 ms | 9.4 ms | 0.70 ms | 4.2 ms | 12 ms | 3.2 ms |
03_octtree.py, level 12 (81M active cells) |
7.0 ms | 37 ms | 2.8 ms | 17 ms | 48 ms | 13 ms |
05_levelset.py, shaded |
7.2 ms | 22 ms | 6.3 ms | 8.3 ms | 24 ms | 6.9 ms |
05_levelset.py, marching steps |
4.4 ms | 13.3 ms | 3.7 ms | 5.1 ms | 14.6 ms | 4.2 ms |
Both models produce the same numbers of active cells up to a few cells and the same images. Marching with the sign test instead of the root window is about 1.5 times slower.
Ignoring rounding errors keeps fewer cells in the quadtree (8.4M instead of 9.5M at level 22, 57M instead
of 126M at level 25): in single precision, the rounding errors of deep levels are larger than the cells.
The octree keeps 0.02% fewer cells and the images of 05_levelset.py are the same.
vusvna
vusvna is a port of cusvna to Vulkan, as a Slang module usable in any shader stage, with the same examples run by slangpy. It is a partial port:
- it only provides the AF1 forms (Slang generics cannot express the symbol types of
cusvna::AA), - it works in single precision only,
- Vulkan has no directed rounding and the driver may fuse operations, so vusvna bounds rounding errors with
the standard model of floating point arithmetic instead of exact error terms;
VUSVNA_IGNORE_ROUNDINGignores them asCUSVNA_IGNORE_ROUNDINGdoes, - some functions are missing (
asin,acos, the hyperbolic functions,erf,tgamma, ...).
The two libraries give the same images and nearly the same cells. On the same RTX 5090, with the same scenes and benchmark protocol:
| Benchmark | vusvna | cusvna AF1 | cusvna AA | vusvna, ignore | cusvna AF1, ignore | cusvna AA, ignore |
|---|---|---|---|---|---|---|
03_octtree.py, level 11 |
1.0 ms | 1.7 ms | 4.2 ms | 0.69 ms | 0.70 ms | 3.2 ms |
03_octtree.py, level 12 |
4.2 ms | 7.0 ms | 17 ms | 3.0 ms | 2.8 ms | 13 ms |
05_levelset.py, shaded |
2.2 ms | 7.2 ms | 8.3 ms | 1.6 ms | 6.3 ms | 6.9 ms |
05_levelset.py, marching steps |
1.5 ms | 4.4 ms | 5.1 ms | 1.1 ms | 3.7 ms | 4.2 ms |
Tests
The tests compare cusvna against libaffa, which must be cloned in ext/libaffa
(git submodule update --init ext/libaffa), and check the soundness of all operations against extended
precision evaluations, for AA and AF1 forms, in float and double, in host code (emulated rounding) and in
device code (hardware rounding and CUDA math library).
cmake -S . -B build -DCMAKE_BUILD_TYPE=Release && cmake --build build && ctest --test-dir build
Add -DCMAKE_CUDA_COMPILER=/usr/local/cuda/bin/nvcc if nvcc is not in your PATH.
Defects found in libaffa
The following libaffa functions do not return enclosures, they have been fixed in cusvna:
| Function | Input | libaffa | Exact range |
|---|---|---|---|
exp |
[0, 1] |
[0.682, 2.612] |
[1, 2.718] |
sin |
[-4.41, 1.21] |
[-0.951, 0.996] |
[-1, 0.955] |
abs |
[-1, 1] |
[-0.5, 0.5] |
[0, 1] |
In addition, exp only uses the tangent intercept instead of the mean of the secant and tangent
intercepts, sin estimates its approximation error from 8 samples, atanh is not implemented (no return
value) and no operation accounts for rounding errors.
License
cusvna is released under the MIT License.
1 maintainer

Metadata
1 maintainer
Release files for cusvna 1.0.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| cusvna-1.0.2.tar.gz | 52.5 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| cusvna-1.0.2-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 99.2 kB
Release files / cusvna-1.0.2.tar.gz
| Download URL | cusvna-1.0.2.tar.gz |
|---|---|
| Size | 52.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
3500f16d7d4ab1bdd11fe4f46335378cb8912260a80717c779d76ce45cb612dc
|
|
BLAKE2b-256 checksum How to use checksums |
e8b682ad3bfed59e2090ec6c5e417b90da0a6a3d1e1984b50c56698531806e13
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.10.12
|
Release files / cusvna-1.0.2-py3-none-any.whl
| Download URL | cusvna-1.0.2-py3-none-any.whl |
|---|---|
| Size | 46.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
f0706af101d93b5e76c7829bc3e9b6d060df3077f2ba34b4184490f23b256a8c
|
|
BLAKE2b-256 checksum How to use checksums |
177c08869b162fc5f8e22b802b61eb8a6d4ddbc5206bda1ec5c3439582ae48e8
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.10.12
|














