
DataJig
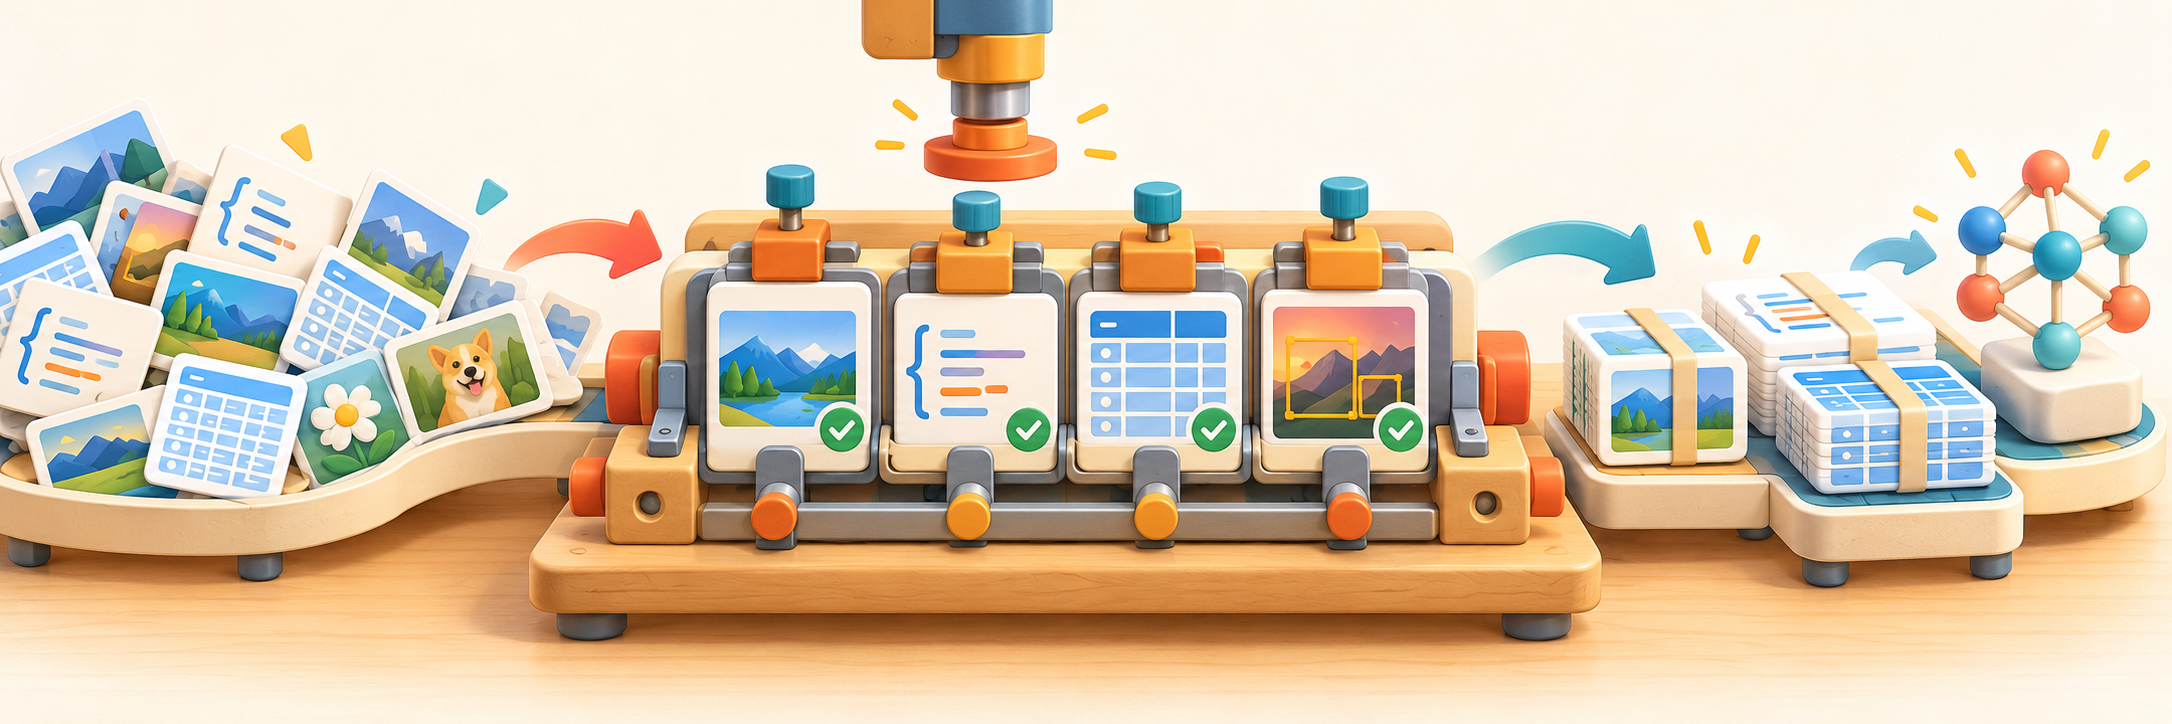
The agent-native data supply chain from raw datasets to verified training input.
Import, prepare, review, version, export, and verify—without losing identity between steps.



Chinese README · PyPI · Architecture · Roadmap · Contributing · Security · Changelog
DataJig turns raw upstream bytes and an agent's dataset edit into a traceable training-data transaction:
pin source → import → prepare → review → seal → export → consume → receipt
                 └──────────── content-addressed evidence chain ────────────┘
It is not another Git, DVC, or Oxen replacement. DataJig sits above storage and processing tools to control the moment an agent changes data—and to hand training code identity-pinned, integrity-checked records. Every task, candidate, review, accepted revision, subset, and training bundle receives a deterministic identity. Stale evidence and out-of-scope mutations fail closed.
Version
0.5.1· local-first · Rust-native core · CSV, Parquet, JSONL, and ImageFolder
Why DataJig
Agents are good at editing data, but a successful script run does not answer:
- Which exact dataset bytes did the agent review?
- Did another process change the files after that review?
- Was the edit limited to the declared task?
- Why was this revision accepted?
- Which records and shard bytes entered training?
DataJig answers those questions with a small machine-readable workflow. Full artifacts stay on disk; stdout stays bounded for an agent context window.
Quickstart
Install the stable wheel. It already contains the Rust core:
python -m pip install datajig
datajig capabilities
Run the complete workflow once without preparing any input files:
datajig tutorial ./datajig-tutorial
The command requires a new destination and creates a tiny keyed JSONL dataset,
an immutable workspace, one reviewed and sealed agent change, and a verified
training bundle. Its bounded JSON response contains every resulting identity
and the exact export-info verification action.
Discovery responses expose a deterministic agent_contract_id covering the
command catalog and input artifact schemas. Pin it in Agent or CI integrations
when an unreviewed protocol change must fail closed; generated Agent Skills
record the same identity.
Install that contract into any Git worktree with one command:
datajig repository-install --root .
datajig repository-check --root .
This creates a version-matched Agent Skill, a SHA-pinned GitHub Actions workflow,
an executable pre-commit hook, and .datajig-repository.json as the final
content-addressed commit point. The lock binds the exact DataJig version, Agent
contract, managed bytes, enabled components, and repository-relative workspace
states. Installation is idempotent and crash-recoverable; it refuses unknown or
locally modified targets, conflicting core.hooksPath values, symlinks, hard
links, and upgrades that silently remove a component or state binding.
repository-check is read-only. It fails on protocol or file drift and verifies
that every bound workspace still matches a clean dataset HEAD. In a fresh CI
clone, use --ci to skip only the clone-local core.hooksPath assertion; all
content and workspace checks remain active. Optional components can be omitted
at first install with --no-hook or --no-github-actions. Add repeatable
--state .datajig bindings when those workspace directories are materialized
in every environment that runs the generated check, including CI; DataJig does
not upload or restore ignored workspace state implicitly.
Start with the same privacy-safe command for JSONL, CSV, or flat Parquet:
datajig inspect data/papers.jsonl --id-field paper_id
datajig inspect data/papers.csv --id-field paper_id
datajig inspect data/papers.parquet --id-field paper_id
inspect reports schema, row and missing-value counts, stable source identity,
and ID health without printing cell values or raw IDs. For CSV and Parquet it
also returns an editable preparation recipe template and a prepare-plan next
action. For JSONL it recommends workspace initialization when the file is ready.
CSV and flat Parquet are native inspection and deterministic preparation inputs. The task-scoped transactional workspace currently operates on keyed JSONL, so tabular sources are prepared into JSONL before change control. XLSX and direct database/Hive/Spark connectors are not native adapters yet.
Compare two keyed JSONL revisions without creating a workspace:
datajig record-diff baseline/papers.jsonl data/papers.jsonl \
  --id-field paper_id
record-diff aligns records by ID and distinguishes added, removed, modified,
and moved records.
For ImageFolder datasets, generate a self-contained review:
datajig compare baseline/ candidate/ \
  --output review.html \
  --json review.json
Import an immutable Hugging Face dataset
Resolve a dataset branch or tag once, inspect the selected repository files, then authorize that exact plan:
mkdir -p raw artifacts

datajig hf-import-plan lhoestq/demo1 \
  --revision main \
  --include 'data/*.csv' \
  --output raw/demo1 \
  --plan artifacts/demo1.hf-plan.json

# Copy plan_id from the bounded JSON response after reviewing the plan.
datajig hf-import-apply artifacts/demo1.hf-plan.json \
  --accept-plan hfplan_...

datajig artifact-schema prepare-recipe
Planning resolves main to a 40-character commit and records the exact file
set and sizes. Apply downloads only that commit, verifies every selected file,
and writes local BLAKE3 identities to datajig.hf-import.json before atomically
publishing the directory. An existing output is accepted only when its receipt
and every file still match, so retries are idempotent without overwriting data.
Public, private, and gated repositories use standard Hugging Face token and
endpoint configuration. This first adapter imports files from dataset
repositories; it does not interpret Dataset Viewer configurations or generated
splits. The verified receipt can be passed directly to prepare-plan, so an
agent does not need an untracked concatenation script between import and
workspace initialization.
Save a schema-1 recipe whose source selects the imported shards:
{
  "namespace": "datajig",
  "kind": "prepare",
  "schema_version": 1,
  "source": {
    "format": "csv",
    "include": ["data/*.csv"],
    "ignore": ["data/test*"]
  },
  "output": {"format": "jsonl"},
  "id_field": "id",
  "steps": []
}
Then bind the import identity, selected shard bytes, recipe, and predicted output into one accepted plan:
datajig prepare-plan raw/demo1/datajig.hf-import.json \
  --recipe recipes/demo1.prepare.json \
  --output data/demo1.jsonl \
  --plan artifacts/demo1.prepare.plan.json

datajig prepare-apply artifacts/demo1.prepare.plan.json \
  --accept-plan prep_...

datajig init data/demo1.jsonl --id-field id
The sections below document the identity chain, failure boundaries, and current product scope directly in the public project overview.
Prepare tabular data
Turn one CSV, flat Parquet, or JSONL file—or ordered same-format shards from a verified import receipt—into deterministic keyed JSONL with an ordered recipe:
{
  "namespace": "datajig",
  "kind": "prepare",
  "schema_version": 1,
  "source": {"format": "csv"},
  "output": {"format": "jsonl"},
  "id_field": "paper_id",
  "steps": [
    {"op": "trim", "fields": ["paper", "score"]},
    {"op": "replace", "field": "score", "from": "N/A", "to": null},
    {"op": "fill_missing", "field": "score", "value": "0"},
    {"op": "filter", "field": "status", "predicate": "eq", "value": "active"},
    {"op": "rename", "from": "paper", "to": "title"},
    {"op": "cast", "field": "score", "type": "number"},
    {"op": "select", "fields": ["paper_id", "title", "score"]},
    {"op": "dedupe", "by": ["paper_id"], "keep": "first"}
  ]
}
For Parquet, use the same recipe and operations with a typed source:
"source": {"format": "parquet"}
For JSONL objects, select the JSONL source format:
"source": {"format": "jsonl"}
Parquet preparation streams compressed files in the Rust core. It accepts flat null, boolean, integer, finite floating-point, UTF-8, decimal, date, and millisecond/microsecond time and timestamp columns. Binary, nested/list/map, and nanosecond time columns fail closed instead of being silently coerced. A 256 MiB uncompressed row-group budget rejects compressed inputs that could cause unsafe decode spikes.
Plan first, then authorize the exact predicted result:
datajig prepare-plan data/papers.csv \
  --recipe recipes/papers.prepare.json \
  --output data/papers.jsonl \
  --plan artifacts/papers.prepare.plan.json

datajig prepare-apply artifacts/papers.prepare.plan.json \
  --accept-plan prep_...
The plan binds direct source bytes or the immutable hfimport_... receipt,
selected shard paths and bytes, recipe, canonical paths, output row counts, and
the predicted JSONL hash. Shards run in canonical path order with global row,
dedupe, and ID state. Apply re-executes the recipe and publishes only if every
identity still matches. Outputs and provenance receipts use crash-recoverable
transaction semantics, never overwrite existing files, and are safe to retry.
Recipe v1 supports ordered filter, select, rename, cast, trim, case,
replace, fill_missing, drop_missing, and dedupe steps. Missing means
JSON null or an empty string; trim first when whitespace-only cells should be
treated as missing. drop_missing supports any and all modes.
Protect an agent edit
Initialize a keyed JSONL file, then declare why the agent is changing it:
datajig init data/papers.jsonl --id-field paper_id

datajig changeset-begin \
  --intent "Normalize paper metadata" \
  --task-id research-42
After the agent edits the file, freeze and review the exact candidate:
datajig changeset-stage --change chg_...
datajig check
When exactly one declaration and staged candidate match the current dataset,
adapter, and HEAD, check, plan, status, and seal resolve that context
automatically. DataJig refuses to guess when the workspace is empty or
ambiguous. Explicit IDs and aliases remain available when choosing among
multiple candidates:
datajig check --change @active --changeset @latest
Workspace workflow commands return JSON with a decision and populated
next_actions. Follow those actions to inspect findings, restage a fix, or seal
the accepted revision. A failed check immediately returns both the deterministic
remediation-plan command and a bounded findings query as argv arrays; it never
guesses a domain value or silently applies a patch:
datajig plan
datajig findings .datajig/latest.review.json --offset 0 --limit 50

datajig seal \
  --accept-report review_... \
  --message "Accept normalized metadata"
Before sealing, DataJig rechecks the live dataset, staged candidate, task anchor, and review identity. If any of them changed, the operation is rejected.
Every new keyed-JSONL revision also retains its exact original bytes. Recover a reachable historical revision without changing the tracked dataset or HEAD:
datajig log
datajig materialize rev_... --output recovered/papers.jsonl
Materialization rehashes the stored blob, creates the output atomically, and never replaces differing content. An exact retry succeeds idempotently. Legacy revisions created before byte retention remain visible but cannot be invented from metadata, so DataJig fails explicitly when their content is unavailable.
Add a quality gate
Pin a JSON policy when the workspace is created:
{
  "namespace": "datajig",
  "schema_version": 1,
  "adapter": "jsonl",
  "mode": "changed_only",
  "fields": {
    "status": {
      "required": true,
      "types": ["string"],
      "enum": ["draft", "published"]
    },
    "score": {"types": ["number"], "minimum": 0, "maximum": 1},
    "doi": {"types": ["string"], "pattern": "^10\\.", "unique": true}
  }
}
datajig init data/papers.jsonl \
  --id-field paper_id \
  --policy data/papers.policy.json
changed_only blocks new violations introduced by added or modified records.
full requires the entire candidate to pass. Policies support required fields,
nullability, JSON types, typed enums, numeric ranges, regex patterns, and scalar
uniqueness.
Preview, apply, and undo a repair
When a quality check fails, an agent can turn a finding directly into a guarded scalar repair. DataJig fills in the report, candidate, pseudonymous record, and record-hash bindings from fresh evidence:
datajig patch-draft .datajig/latest.review.json fnd_... \
  --change chg_... \
  --changeset changeset_... \
  --after-json 0.9 \
  --output repair.json

datajig patch-preview repair.json .datajig/latest.review.json \
  --change chg_... \
  --changeset changeset_...

datajig patch-apply repair.json .datajig/latest.review.json \
  --change chg_... \
  --changeset changeset_... \
  --accept-patch patch_...
Use --remove instead of --after-json to remove an optional invalid field.
If a finding covers multiple records, first run locate and pass one sampled
rid_... with --record. Both commands return the next fully bound action.
DataJig rechecks the live source and returns a deterministic patch_... ID plus
the predicted record hash. patch-apply requires that exact ID as explicit
consent, atomically rewrites only the intended physical line, and prepares the
replacement changeset. It never prints the raw record ID, before value, or after
value. Follow the returned next_actions to check the new candidate.
Every successful apply returns an opaque undo_... handle. Until another edit
or HEAD transition changes its anchors, the exact original line can be restored:
datajig patch-undo undo_...
The one-line preimage is stored under .datajig/private with private
permissions; immutable apply and undo receipts contain identities only. Apply and undo are
retry-safe and recover interrupted transactions. A workspace lock coordinates
DataJig writers, while an exact pre-commit fingerprint rejects edits from other
processes. As on any portable filesystem, unrelated software that ignores the
lock cannot be given a universal compare-and-swap guarantee.
Export verified training data
Export a clean, sealed JSONL revision into deterministic splits and shards:
datajig export \
  --output artifacts/papers-v1 \
  --seed research-42 \
  --split train=9000 \
  --split validation=1000

datajig export-info artifacts/papers-v1/datajig.bundle.json --verify
Split weights are integer basis points: repeat --split NAME=WEIGHT, use a
positive weight, and make all weights total exactly 10000. This contract and
the complete example are visible in export --help and capabilities.
Invalid arguments return structured remediation and executable next_actions
instead of requiring an agent to infer the syntax by trial and error.
--max-shard-records accepts values from 1; the final shard may contain fewer
records. --max-shard-bytes is a soft target from 1 byte: when one valid
record is larger than the target, that record occupies a shard by itself. The
independent 16 MiB JSONL line safety limit is unchanged.
Reproduce a training bundle from any reachable retained revision—even when the working file has changed, moved, or been deleted:
datajig log --state .datajig
datajig export \
  --state .datajig \
  --revision rev_... \
  --output artifacts/papers-rev \
  --split train=9000 \
  --split validation=1000
DataJig verifies the immutable stored bytes before evaluating a view or writing shards. It never substitutes the current working file for a requested revision. Older revisions created before content retention fail explicitly instead of silently exporting different data.
The bundle manifest binds the dataset, sealed revision, record state, split
recipe, shard sizes, and BLAKE3 hashes into one bundle_... identity. The output
is standard JSONL, so training code does not need a DataJig runtime.
Bundle publication never overwrites an existing target. If the destination
filesystem cannot provide atomic no-replace directory publication, DataJig
fails before exposing a partial bundle and recommends exporting on a compatible
local filesystem (for example /tmp) before moving the verified result.
You can also pin a reproducible cohort before spending training compute:
{
  "namespace": "datajig",
  "kind": "subset_view",
  "schema_version": 1,
  "where": [{"field": "status", "op": "eq", "value": "published"}]
}
datajig view-check --recipe recipes/published.json
datajig export \
  --view recipes/published.json \
  --output artifacts/published-v1 \
  --split train=9000 \
  --split validation=1000
Load verified training records
Open a bundle with identities supplied by your experiment or CI policy. Rust verifies the manifest, every shard, record identity, split assignment, ordering, and optional subset view before Python receives a consumer plan:
from datajig import open_bundle

bundle = open_bundle(
    "artifacts/papers-v1/datajig.bundle.json",
    expected_bundle_id="bundle_...",
    expected_revision_id="rev_...",
    require_assurance="quality_policy",
)

for record in bundle.iter_records("train"):
    train(record)
Each shard is rehashed into a private spool before its first record is yielded, closing the gap between verification and consumption. Optional adapters add no implicit shuffle, transform, or cache:
from datajig.integrations.torch import iterable_dataset

dataset = iterable_dataset(bundle, split="train")
# torch.utils.data.DataLoader(dataset, batch_size=32)
The Hugging Face equivalent is
datajig.integrations.huggingface.iterable_dataset. Install torch or
datasets separately only when using those adapters.
Prove what crossed the training boundary
When a run needs durable lineage, create a plan for one exact bundle split and name the external training run:
datajig consume-plan artifacts/papers-v1/datajig.bundle.json \
  --split train \
  --consumer pytorch \
  --run-id research-42-run-001 \
  --output runs/research-42-run-001 \
  --plan artifacts/research-42-run-001.consume.json
Review the response, then pass its exact consume_... ID to training:
from datajig import open_consumption
from datajig.integrations.torch import iterable_dataset

run = open_consumption(
    "artifacts/research-42-run-001.consume.json",
    accept_plan="consume_...",
)
dataset = iterable_dataset(run)
Plans naming python use run.iter_records() directly; plans naming PyTorch or
Hugging Face must use that adapter so the recorded boundary cannot be bypassed.
The last worker to exhaust the verified split atomically publishes
datajig.consumed.json. Its consumed_... identity proves that every verified
record crossed the named DataJig adapter boundary at least once. Early stop,
exceptions, changed shards, or forged run state produce no receipt. This is not
proof of training success, gradient use, post-adapter ordering, or exactly-once
delivery.
ImageFolder review
For image classification datasets, DataJig can identify:
- added, removed, renamed, relabeled, and split-moved samples;
- exact and perceptual duplicates across train/validation/test;
- corrupt or unsupported media;
- label, split, format, size, aspect-ratio, and channel drift.
The human-facing compare command produces HTML and JSON. Native inventory and
review commands expose the same workflow as bounded agent-facing artifacts.
Built for agents
datajig capabilities
datajig describe
datajig describe check
datajig artifact-schema
datajig artifact-schema prepare-recipe
datajig artifact-schema subset-view
datajig artifact-schema training-consumption-plan
datajig artifact-schema training-consumption-receipt
datajig agent-skill --output .agents/skills/datajig/SKILL.md
- Discoverable: versioned command and artifact contracts expose inputs, effects, limits, schemas, canonical examples, platforms, outputs, and exits.
- Bounded: summaries and finding pages have hard limits; full evidence stays in artifacts.
- Addressable: stable
chg_...,changeset_...,fnd_...,review_...,hfplan_...,hfimport_...,prep_...,patch_...,apply_...,undo_...,revert_...,rev_...,view_...,bundle_...,consume_..., andconsumed_...IDs connect every step. - Recoverable: commands return explicit decisions and next actions instead of relying on prose or hidden state.
- Race-aware: live bytes are revalidated before review evidence can advance the workspace HEAD.
Supported today
| Workflow | Status |
|---|---|
| Revision-pinned Hugging Face dataset-repository import | Available on Linux and macOS |
| Keyed JSONL inspection and record diff | Available |
| Privacy-safe CSV/Parquet inspection and recipe scaffold | Available |
| Deterministic CSV/flat Parquet cleaning with plan/apply provenance | Available on Linux and macOS |
| Task-scoped JSONL workspace and quality policy | Available on Linux and macOS |
| Evidence-bound JSONL patch draft, preview, atomic apply, and exact undo | Available on Linux and macOS |
| Sealed subset views and verified training export | Available on Linux and macOS |
| Verified Python, PyTorch, and Hugging Face consumption | Available |
| ImageFolder semantic review and HTML report | Available |
| Universal directory snapshots | Available |
| Runnable end-to-end tutorial | Available on Linux and macOS |
| Linux x86_64/aarch64 and macOS x86_64/arm64 wheels | Published |
| Windows through WSL | Supported using the Linux wheel |
| Native Windows workspace writes | Not yet supported |
| S3/GCS/Azure, Oxen, and DVC source adapters | Planned |
| Automatic model-training orchestration | Out of scope |
DataJig is experimental. Artifact schemas and CLI contracts are versioned, but
the project has not reached a stable 1.0 compatibility promise.
Python API
Python exposes human-facing ImageFolder comparison and verified training-bundle consumption:
from datajig import compare, open_bundle

report = compare("baseline/", "candidate/", workers=4)
print(report.policy.status)

bundle = open_bundle(
    "artifacts/papers-v1/datajig.bundle.json",
    expected_bundle_id="bundle_...",
    expected_revision_id="rev_...",
)
print(bundle.bundle_id, bundle.splits)
Without an expected bundle or revision ID, open_bundle still checks internal
integrity but does not establish that the bundle is the one your experiment or
CI policy intended. Pin at least one trusted identity for training inputs.
The authoritative agent workspace, identity, review, and export paths run in Rust. Python is the packaging and integration layer, not an algorithm fallback.
Develop from source
git clone https://github.com/liukejun7/DataJig.git
cd DataJig
cargo build --locked --manifest-path rust/Cargo.toml
python -m pip install -e '.[dev]'
export DATAJIG_NATIVE="$PWD/rust/target/debug/datajig-core"
datajig capabilities
Requirements: Python 3.11+ and Rust 1.85+.
Current direction
DataJig is becoming the default control layer between an agent and its data:
- Arrow batch execution, joins, dataset-wide numeric transforms, and multi-record patch sets;
- XLSX and database snapshot adapters, followed by Spark/Hive manifests;
- revision adapters for S3/GCS/Azure, Oxen, DVC, and additional dataset hubs;
- native Windows filesystem semantics and wheels.
The goal is simple: an agent should always know what it changed, prove what it reviewed, recover safely, and hand training code a verified input.
1 maintainer

Metadata
1 maintainer
Release files for datajig 0.5.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Built distributions (wheels)
| File | Reset | |||
|---|---|---|---|---|
| datajig-0.5.1-py3-none-manylinux2014_x86_64.manylinux_2_17_x86_64.whl | Python 3 | none | Linux glibc 2.17+ x86-64 | Details |
| datajig-0.5.1-py3-none-manylinux2014_aarch64.manylinux_2_17_aarch64.whl | Python 3 | none | Linux glibc 2.17+ ARM64 | Details |
| datajig-0.5.1-py3-none-macosx_11_0_arm64.whl | Python 3 | none | macOS 11.0+ ARM64 | Details |
| datajig-0.5.1-py3-none-macosx_10_12_x86_64.whl | Python 3 | none | macOS 10.12+ x86-64 | Details |
Total release size: 25.3 MB
Release files / datajig-0.5.1-py3-none-manylinux2014_x86_64.manylinux_2_17_x86_64.whl
| Download URL | datajig-0.5.1-py3-none-manylinux2014_x86_64.manylinux_2_17_x86_64.whl |
|---|---|
| Size | 6.7 MB |
| Tags | Linux glibc 2.17+ x86-64 Python 3 |
|
SHA-256 checksum How to use checksums |
4ef137d205b71ed60e0d2c01e0399da0dd24f0f20f895473ccd01dcdd7946d62
|
|
BLAKE2b-256 checksum How to use checksums |
2c7fafda0e469098e37c4db715edc8f1bc4484b69762548405ead72d00fbb0c8
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 6, 2026.
Transparency logRelease files / datajig-0.5.1-py3-none-manylinux2014_aarch64.manylinux_2_17_aarch64.whl
| Download URL | datajig-0.5.1-py3-none-manylinux2014_aarch64.manylinux_2_17_aarch64.whl |
|---|---|
| Size | 6.4 MB |
| Tags | Linux glibc 2.17+ ARM64 Python 3 |
|
SHA-256 checksum How to use checksums |
a3e66013cc4c973e8f9cb3d0069672d576d74a1171786f70bae3f30c158a63a5
|
|
BLAKE2b-256 checksum How to use checksums |
cc428863cf54d74c6e174df97eb055d73a5eb15d538b979abf025a4a260de5a9
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 6, 2026.
Transparency logRelease files / datajig-0.5.1-py3-none-macosx_11_0_arm64.whl
| Download URL | datajig-0.5.1-py3-none-macosx_11_0_arm64.whl |
|---|---|
| Size | 5.9 MB |
| Tags | Python 3 macOS 11.0+ ARM64 |
|
SHA-256 checksum How to use checksums |
13a21c964c38d2462cc47f8548dff3761cf846c4f1bd71f1977949ebc3c9e1f0
|
|
BLAKE2b-256 checksum How to use checksums |
eacff23254cc0a42d5d531042ef578353ad125d4ddf131edaf68f686d637d66c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 6, 2026.
Transparency logRelease files / datajig-0.5.1-py3-none-macosx_10_12_x86_64.whl
| Download URL | datajig-0.5.1-py3-none-macosx_10_12_x86_64.whl |
|---|---|
| Size | 6.3 MB |
| Tags | Python 3 macOS 10.12+ x86-64 |
|
SHA-256 checksum How to use checksums |
6e07d9b5584083663d7102bed5ac8a8e57332ccfc57506e734c46e24754fb5c1
|
|
BLAKE2b-256 checksum How to use checksums |
8001f4c56b6a265395386a3f8ed40f028712b6502e236e6f67a5514cc18ebbea
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 6, 2026.
Transparency log













