
Theoretically-Efficient and Practical Parallel DBSCAN
Overview
This repository hosts fast parallel DBSCAN clustering code for low dimensional Euclidean space. The code automatically uses the available threads on a parallel shared-memory machine to speedup DBSCAN clustering. It stems from a paper presented in SIGMOD'20: Theoretically Efficient and Practical Parallel DBSCAN.
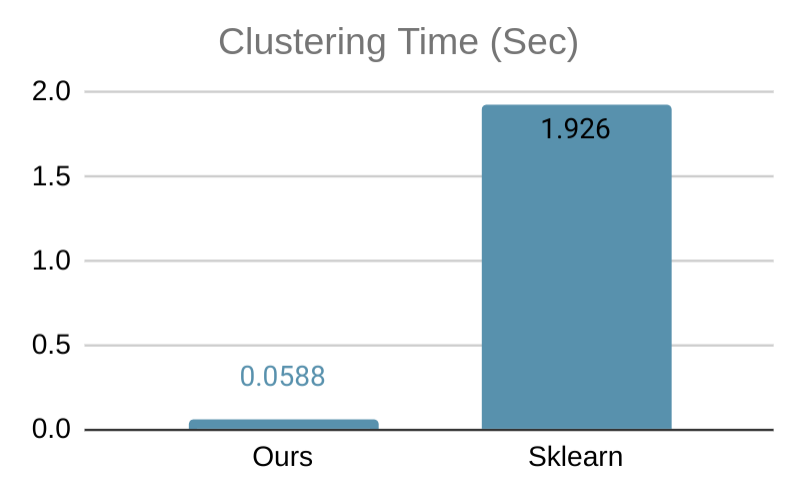
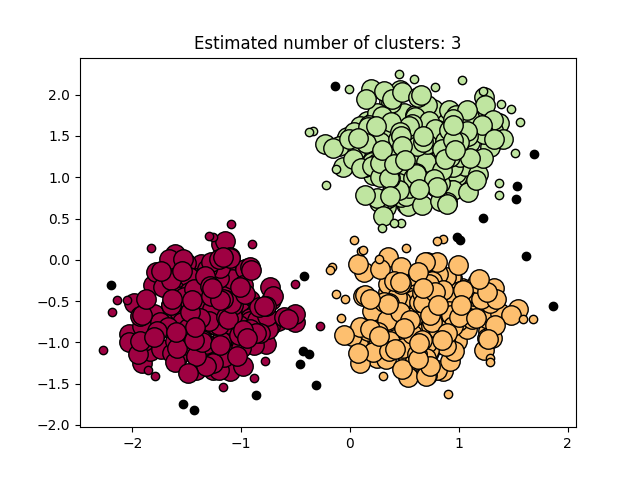
Our software on 1 thread is on par with all serial state-of-the-art DBSCAN packages, and provides additional speedup via multi-threading. Below, we show a simple benchmark comparing our code with the DBSCAN implementation of Sklearn, tested on a 6-core computer with 2-way hyperthreading using a 2-dimensional data set with 50000 data points, where both implementation uses all available threads. Our implementation is more than 32x faster. We also show a visualization of the clustering result on a smaller data set.
Data sets with dimensionality 2 - 20 are supported by default, which can be modified by modifying DBSCAN_MIN_DIMS and DBSCAN_MAX_DIMS in the source code.
Tutorial
Option 1: Use the Python binding
There are two ways to install it:
- Install it using PyPI:
pip3 install --user dbscan(you can find the wheels here). - To build from scratch for testing:
pip3 install -e .from the project root directory.
An example for using the Python module is provided in example.py. It generates the clustering example above.
Python API
from dbscan import DBSCAN
labels, core_samples_mask = DBSCAN(X, eps=0.3, min_samples=10)
Input
X: A 2-D Numpy array containing the input data points. The first dimension ofXis the number of data pointsn, and the second dimension is the data set dimensionality (the maximum supported dimensionality is 20).eps: The epsilon parameter (default 0.5).min_samples: The minPts parameter (default 5).
Output
labels: A lengthnNumpy array (dtype=np.int32) containing cluster IDs of the data points, in the same ordering as the input data. Noise points are given a pseudo-ID of-1.core_samples_mask: A lengthnNumpy array (dtype=np.bool) masking the core points, in the same ordering as the input data.
We provide a complete example below that generates a toy data set, computes the DBSCAN clustering, and visualizes the result as shown in the plot above.
import numpy as np
from sklearn.datasets import make_blobs
from sklearn.preprocessing import StandardScaler

# #############################################################################
# Generate sample data
centers = [[1, 1], [-1, -1], [1, -1]]
X, labels_true = make_blobs(n_samples=750, centers=centers, cluster_std=0.4,
                            random_state=0)
X = StandardScaler().fit_transform(X)

# #############################################################################
# Compute DBSCAN

# direct call of the C API:
from dbscan import DBSCAN
labels, core_samples_mask = DBSCAN(X, eps=0.3, min_samples=10)

# OR calling our sklearn API:
# from dbscan import sklDBSCAN as DBSCAN
# db = DBSCAN(eps=0.3, min_samples=10).fit(X)
# core_samples_mask = np.zeros_like(db.labels_, dtype=bool)
# core_samples_mask[db.core_sample_indices_] = True
# labels = db.labels_

# #############################################################################
# Plot result
import matplotlib.pyplot as plt

n_clusters_ = len(set(labels)) - (1 if -1 in labels else 0)
n_noise_ = list(labels).count(-1)
# Black removed and is used for noise instead.
unique_labels = set(labels)
colors = [plt.cm.Spectral(each)
          for each in np.linspace(0, 1, len(unique_labels))]
for k, col in zip(unique_labels, colors):
    if k == -1:
        # Black used for noise.
        col = [0, 0, 0, 1]
    class_member_mask = (labels == k)
    xy = X[class_member_mask & core_samples_mask]
    plt.plot(xy[:, 0], xy[:, 1], 'o', markerfacecolor=tuple(col),
             markeredgecolor='k', markersize=14)
    xy = X[class_member_mask & ~core_samples_mask]
    plt.plot(xy[:, 0], xy[:, 1], 'o', markerfacecolor=tuple(col),
             markeredgecolor='k', markersize=6)
plt.title('Estimated number of clusters: %d' % n_clusters_)
plt.show()
Option 2: Use the binary executable
Compile and run the program:
mkdir build
cd build
cmake ..
cd executable
make -j # this will take a while
./dbscan -eps 0.1 -minpts 10 -o clusters.txt <data-file>
The <data-file> can be any CSV-like point data file, where each line contains a data point -- see an example here. The data file can be either with or without header. The cluster output clusters.txt will contain a cluster ID on each line (other than the first-line header), giving a cluster assignment in the same ordering as the input file. A noise point will have a cluster ID of -1.
Option 3: Include directly in your own C++ program
Create your own caller header and source file by instantiating the DBSCAN template function in "dbscan/algo.h".
dbscan.h:
template<int dim>
int DBSCAN(int n, double* PF, double epsilon, int minPts, bool* coreFlagOut, int* coreFlag, int* cluster);

// equivalent to
// int DBSCAN(intT n, floatT PF[n][dim], double epsilon, intT minPts, bool coreFlagOut[n], intT coreFlag[n], intT cluster[n])
// if C++ syntax was a little more flexible

template<>
int DBSCAN<3>(int n, double* PF, double epsilon, int minPts, bool* coreFlagOut, int* coreFlag, int* cluster);
dbscan.cpp:
#include "dbscan/algo.h"
#include "dbscan.h"
Calling the instantiated function:
int n = ...; // number of data points
double data[n][3] = ...; // data points
int labels[n]; // label ids get saved here
bool core_samples[n]; // a flag determining whether or not the sample is a core sample is saved here
{
  int ignore[n];
  DBSCAN<3>(n, (void*)data, 70, 100, core_samples, ignore, labels);
}
Doing this will only compile the function for the number of dimensions that you want, which saves on compilation time.
You can also include the "dbscan/capi.h" and define your own DBSCAN_MIN_DIMS and DBSCAN_MAX_DIMS macros the same way the Python extension uses it. The function exported has the following signature.
extern "C" int DBSCAN(int dim, int n, double* PF, double epsilon, int minPts, bool* coreFlag, int* cluster);
Right now, the only two files that are guaranteed to remain in the C/C++ API are "dbscan/algo.h" and "dbscan/capi.h" and the functions named DBSCAN within.
Citation
If you use our work in a publication, we would appreciate citations:
@inproceedings{wang2020theoretically,
  author = {Wang, Yiqiu and Gu, Yan and Shun, Julian},
  title = {Theoretically-Efficient and Practical Parallel DBSCAN},
  year = {2020},
  isbn = {9781450367356},
  publisher = {Association for Computing Machinery},
  address = {New York, NY, USA},
  url = {https://doi.org/10.1145/3318464.3380582},
  doi = {10.1145/3318464.3380582},
  booktitle = {Proceedings of the 2020 ACM SIGMOD International Conference on Management of Data},
  pages = {2555–2571},
  numpages = {17},
  keywords = {parallel algorithms, spatial clustering, DBScan},
  location = {Portland, OR, USA},
  series = {SIGMOD ’20}
}
2 maintainers


Metadata
2 maintainers
Release files for dbscan 1.0.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| dbscan-1.0.0.tar.gz | 168.9 kB | Without provenance | Details for dbscan-1.0.0.tar.gz |
Built distributions (wheels)
| File | Actions Reset | |||
|---|---|---|---|---|
| dbscan-1.0.0-cp39-abi3-manylinux_2_17_x86_64.manylinux2014_x86_64.whl | CPython 3.9 | abi3 | Linux glibc 2.17+ x86-64 | Details for dbscan-1.0.0-cp39-abi3-manylinux_2_17_x86_64.manylinux2014_x86_64.whl |
| dbscan-1.0.0-cp39-abi3-manylinux_2_17_aarch64.manylinux2014_aarch64.whl | CPython 3.9 | abi3 | Linux glibc 2.17+ ARM64 | Details for dbscan-1.0.0-cp39-abi3-manylinux_2_17_aarch64.manylinux2014_aarch64.whl |
| dbscan-1.0.0-cp39-abi3-macosx_11_0_arm64.whl | CPython 3.9 | abi3 | macOS 11.0+ ARM64 | Details for dbscan-1.0.0-cp39-abi3-macosx_11_0_arm64.whl |
| dbscan-1.0.0-cp39-abi3-macosx_10_9_x86_64.whl | CPython 3.9 | abi3 | macOS 10.9+ x86-64 | Details for dbscan-1.0.0-cp39-abi3-macosx_10_9_x86_64.whl |
Total release size: 22.2 MB
Release files / dbscan-1.0.0.tar.gz
| Download URL | dbscan-1.0.0.tar.gz |
|---|---|
| Size | 168.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
8ea6c8b72b8ff98d12422a3b9d7c56c3feac5390ab18b4be5e37042124ada1ce
|
|
BLAKE2b-256 checksum How to use checksums |
ec2530582913c170d4b606e791c8b6182b832a29777ca760c436da6ff546d164
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.1.0 CPython/3.9.23
|
Release files / dbscan-1.0.0-cp39-abi3-manylinux_2_17_x86_64.manylinux2014_x86_64.whl
| Download URL | dbscan-1.0.0-cp39-abi3-manylinux_2_17_x86_64.manylinux2014_x86_64.whl |
|---|---|
| Size | 10.0 MB |
| Tags | CPython 3.9 Linux glibc 2.17+ x86-64 abi3 |
|
SHA-256 checksum How to use checksums |
e9a87909cc5814ea865ecb05bd2c363a48ca070b4d5feb794f70b049ca902cd6
|
|
BLAKE2b-256 checksum How to use checksums |
b1e7160c3324565254aaf6ebf88e78c90b5de675024795dff2f68b522d755e43
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.1.0 CPython/3.9.23
|
Release files / dbscan-1.0.0-cp39-abi3-manylinux_2_17_aarch64.manylinux2014_aarch64.whl
| Download URL | dbscan-1.0.0-cp39-abi3-manylinux_2_17_aarch64.manylinux2014_aarch64.whl |
|---|---|
| Size | 9.5 MB |
| Tags | CPython 3.9 Linux glibc 2.17+ ARM64 abi3 |
|
SHA-256 checksum How to use checksums |
535377c21f0c7e49ad03aeb8e93b4bb6654a294e01cb41a648116cee947ad31c
|
|
BLAKE2b-256 checksum How to use checksums |
5b31b75be9bdff24f9d8fa58959391de5557d27b48554010d42bbb9efa0af40a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.1.0 CPython/3.9.23
|
Release files / dbscan-1.0.0-cp39-abi3-macosx_11_0_arm64.whl
| Download URL | dbscan-1.0.0-cp39-abi3-macosx_11_0_arm64.whl |
|---|---|
| Size | 1.3 MB |
| Tags | CPython 3.9 abi3 macOS 11.0+ ARM64 |
|
SHA-256 checksum How to use checksums |
e0c602ff948c4fd8a0a0c0d01dd4cb847cc4d5d206b961fa98582b29de858e9d
|
|
BLAKE2b-256 checksum How to use checksums |
2206a9ad2dcb2a23db045f5bc8570a6ec1bef6bf4333035dc9fe0168593acb7a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.1.0 CPython/3.9.23
|
Release files / dbscan-1.0.0-cp39-abi3-macosx_10_9_x86_64.whl
| Download URL | dbscan-1.0.0-cp39-abi3-macosx_10_9_x86_64.whl |
|---|---|
| Size | 1.2 MB |
| Tags | CPython 3.9 abi3 macOS 10.9+ x86-64 |
|
SHA-256 checksum How to use checksums |
9208c13159de06007047a7120334d96c52dc9a11d8f979dd5439327c400ff50d
|
|
BLAKE2b-256 checksum How to use checksums |
43952480b873982729f53fcc635c9a3b9af3037af9ffafbbfe5e0660db61f7fb
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.1.0 CPython/3.9.23
|
Security for dbscan 1.0.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














