
DecimalAI Python SDK
Catch what your next agent change will break — a structural regression check against your recorded traces, built on manifest-aware versioning of your agent's tools, prompts, models, and skills. The open source SDK for DecimalAI.



Docs · Registry · Leaderboard · Changelog
Installation
pip install decimalai
# or
uv pip install decimalai
Requires Python 3.10+ (pip won't install current releases on older Pythons).
The core install is deliberately thin (tracing, CLI, manifests, skills). Framework and provider adapters ship as extras — install the one matching your stack:
pip install "decimalai[langchain]"       # LangChain (add [langgraph] for LangGraph)
pip install "decimalai[openai-agents]"   # OpenAI Agents SDK
pip install "decimalai[all]"             # everything
Available extras: [langchain], [langgraph], [openai], [openai-agents], [llamaindex], [claude-agent-sdk], [pydantic-ai], [adk], [evals], [all].
See it in 2 minutes
The regression demo seeds a reference agent (v1 → v2 + a trace corpus) into your workspace and runs the exact pipeline a real PR check runs. It needs a free API key — that's the only setup:
export DECIMAL_API_KEY="dai_sk_..."   # free key from app.decimal.ai/settings
decimalai demo regression             # → impact report: what your next change would break
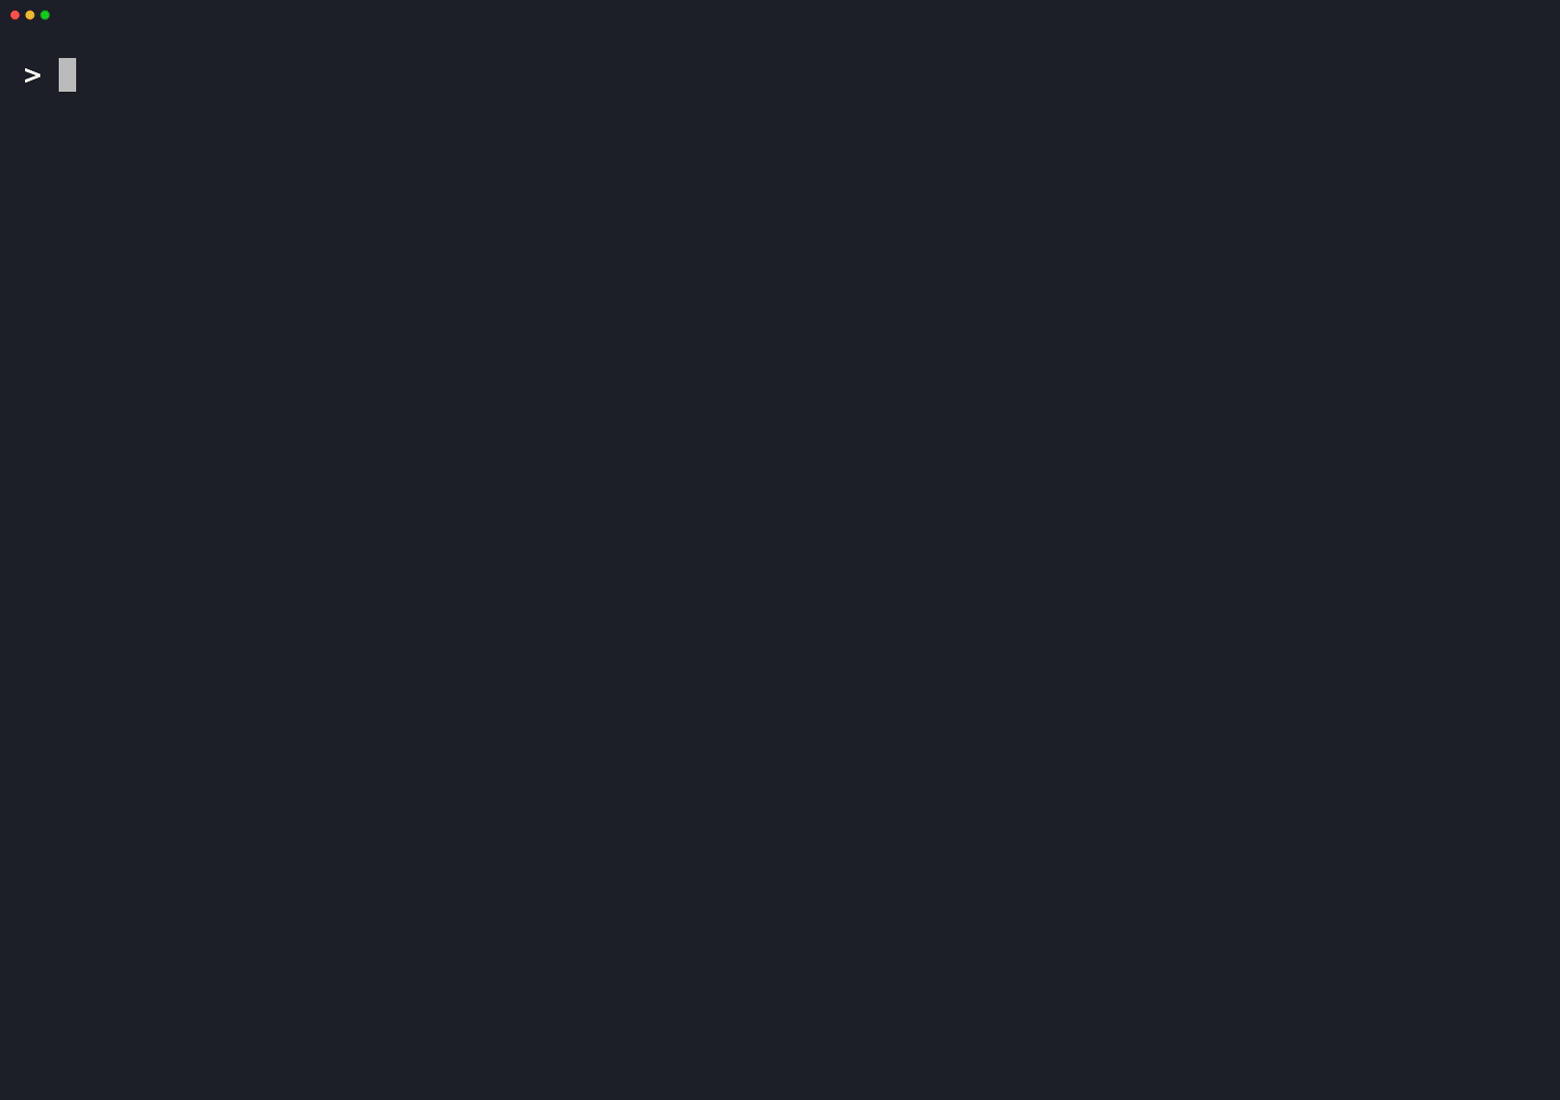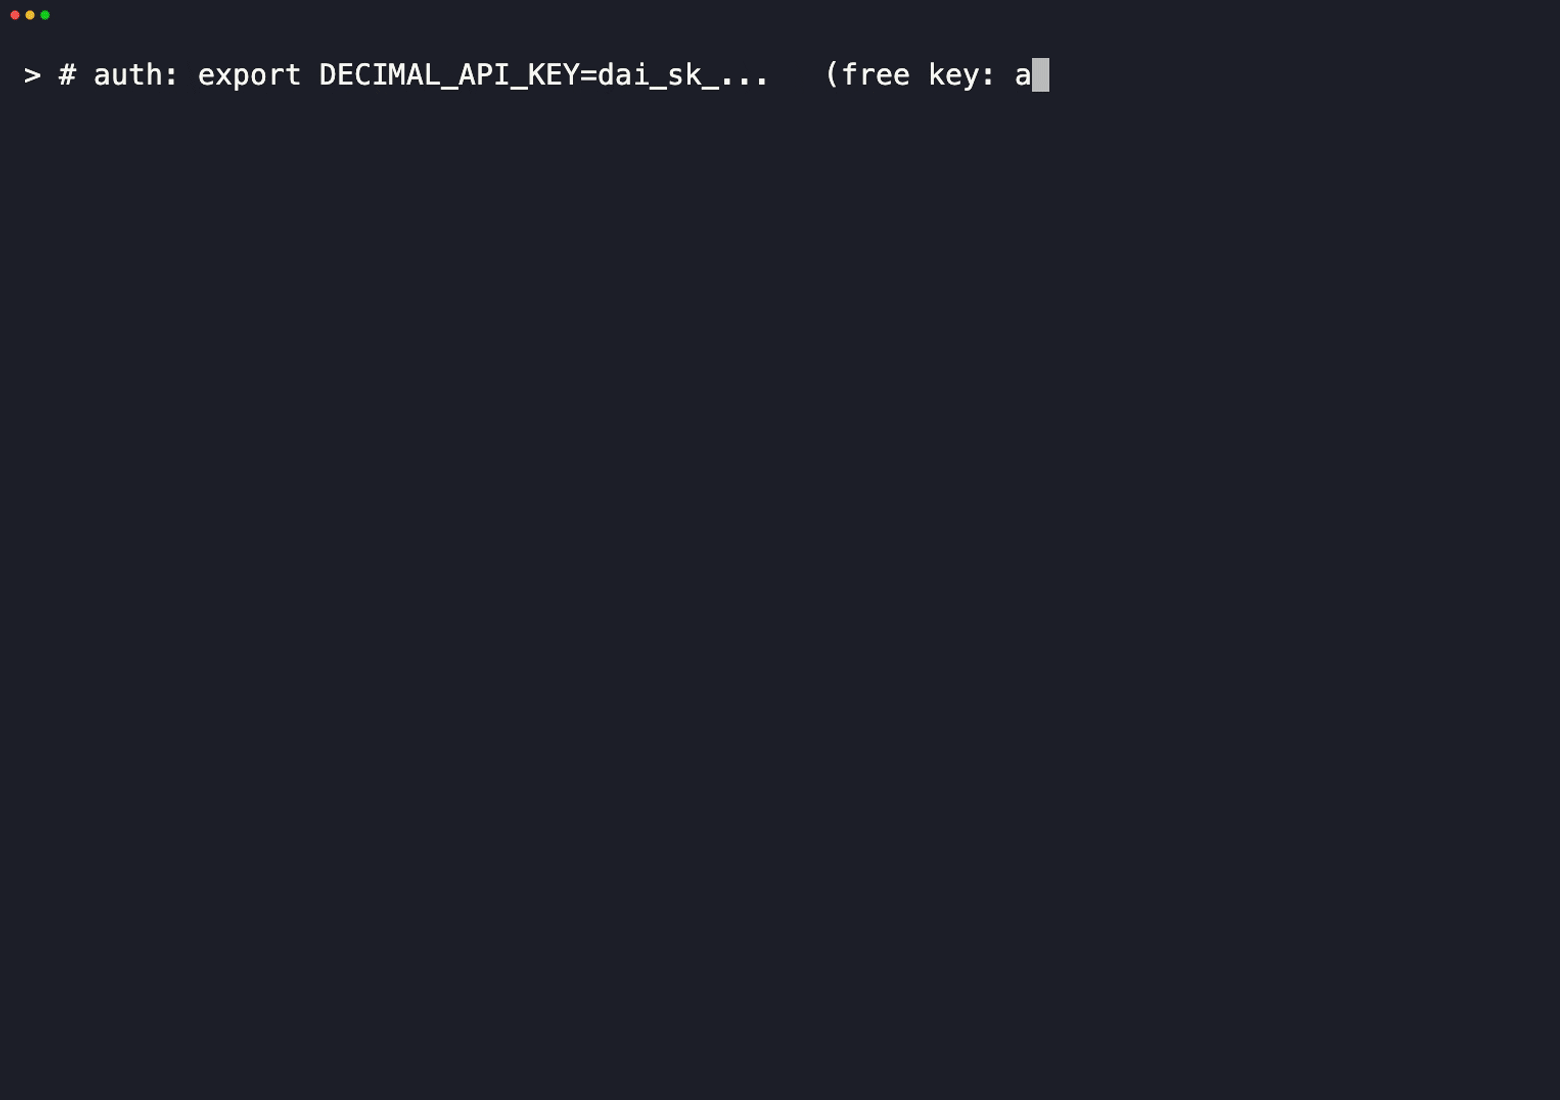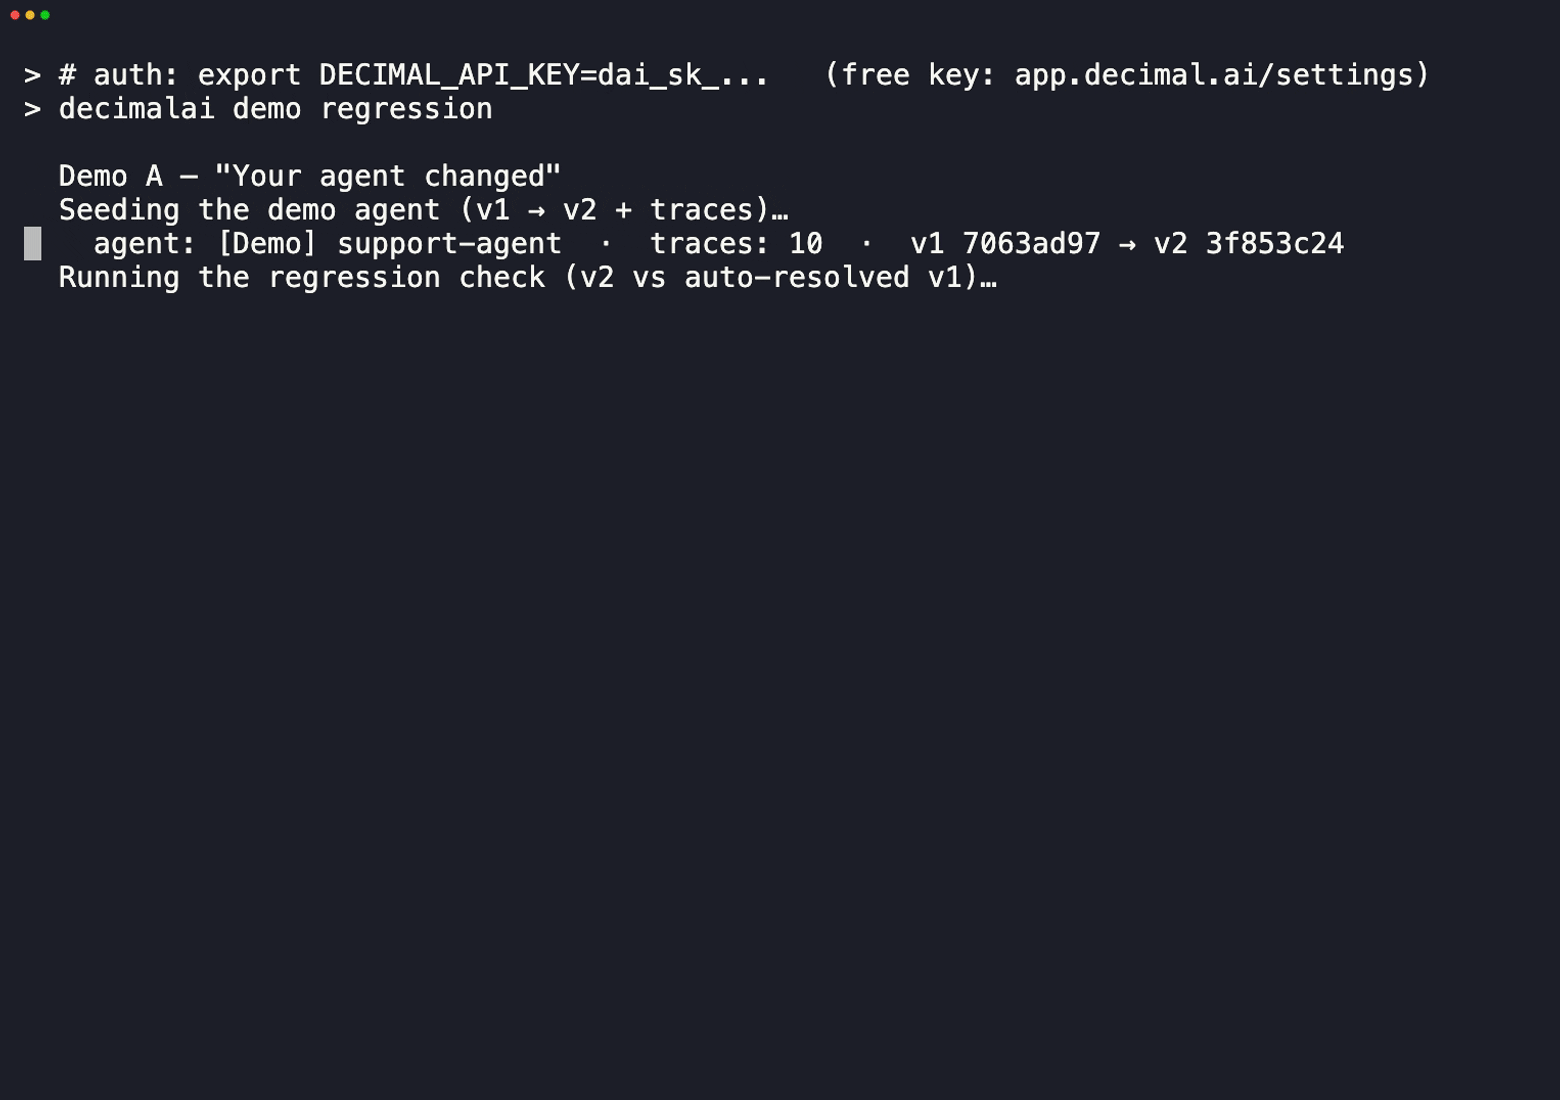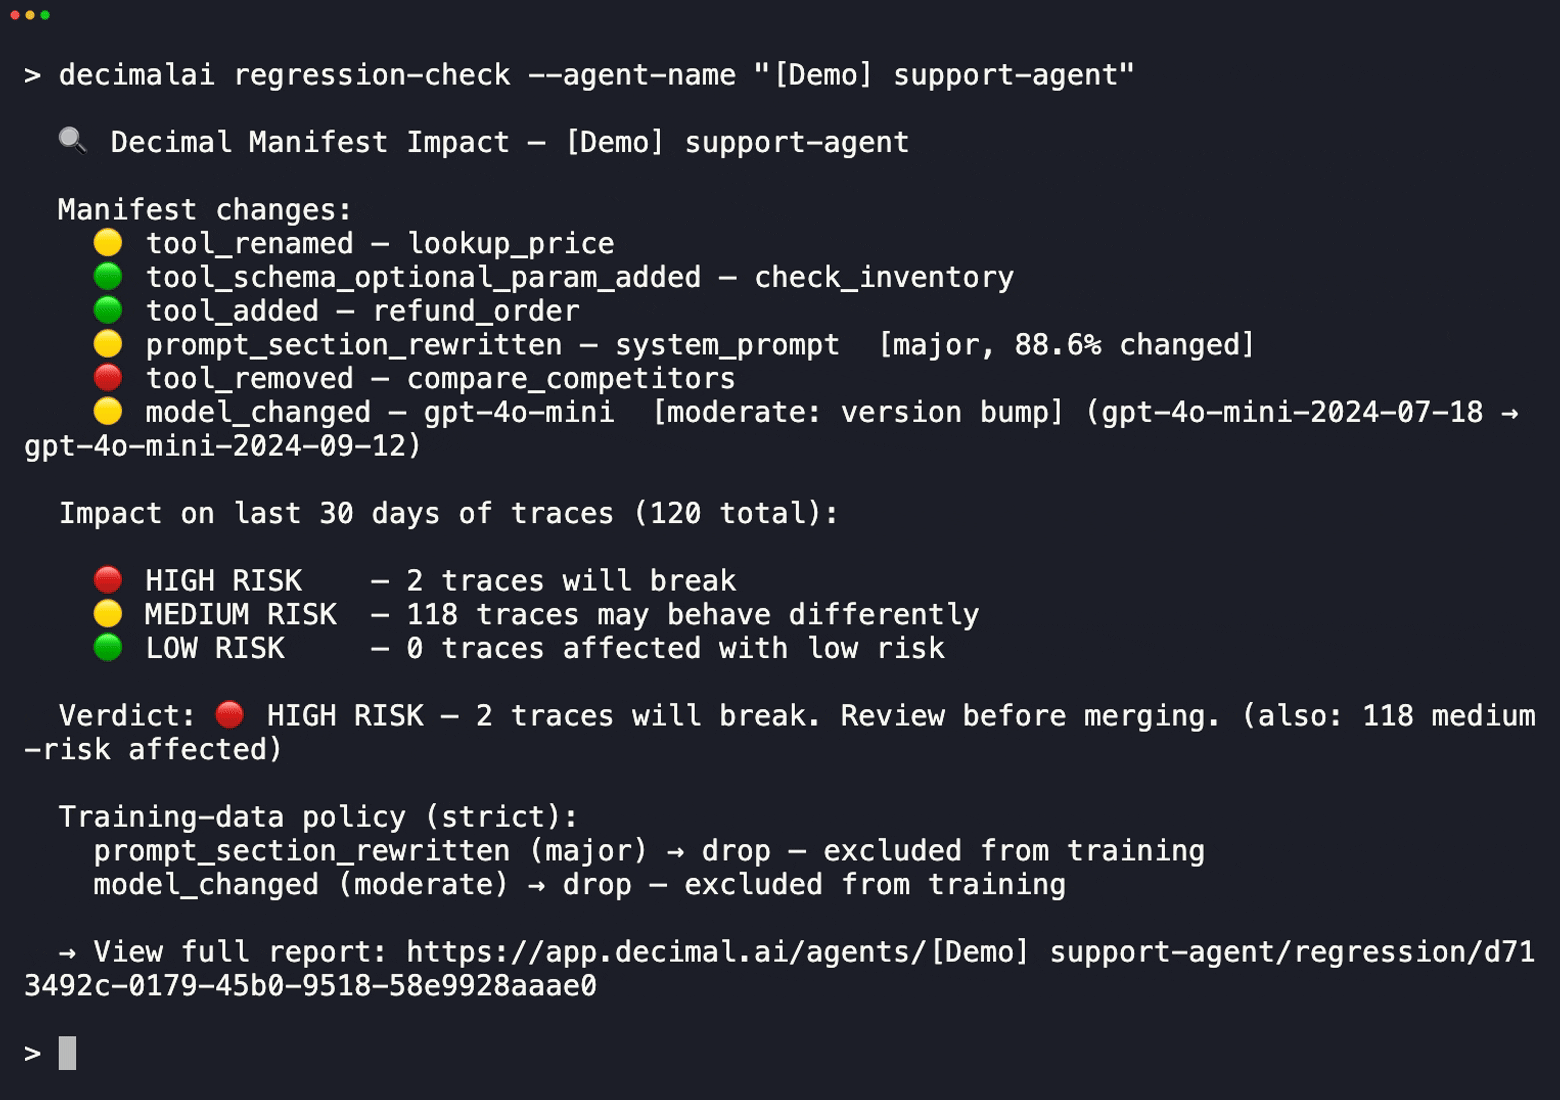
The impact report it produces looks like this — captured with the SDK's decimalai regression-check against the seeded reference agent, trimmed:
  🔍 Agent Regression Check — [Demo] support-agent

  Manifest changes:
    🟡 tool_renamed — lookup_price
    🟢 tool_added — refund_order
    🟡 prompt_section_rewritten — system_prompt  [major, 88.6% changed]
    🔴 model_changed — gpt-4o-mini  (gpt-4o-mini-2024-07 → gpt-4o-mini-2024-09)
    🔴 tool_removed — compare_competitors

  Training-data policy (default):
    prompt_section_rewritten (major) → replay — need re-running first
    model_changed (major) → drop — excluded from training
Everything above comes from a seeded reference agent — illustrative, run it yourself. On your own instrumented agent, each change is additionally checked against your recorded traces — a high/medium/low blast radius per trace, not just the structural diff. The API key is needed because the demo seeds data into a workspace on the platform; decimalai demo reset removes it all.
No key at all? Two things work without one:
decimalai skills pull <slug>— fetch any published SKILL.md to disk, no account.- The
agentversionmanifest flow (below) — diff and gate agent manifests fully locally.
There's a second demo for the registry side:
decimalai demo skills # → tour the registry: security-scanned skills, benchmarkable with an open A/B spec
Browsing without an account? Explore the public skill registry — no signup required.
Quick Start
LangChain / LangGraph — Zero-Code Tracing
import decimalai

decimalai.init(langchain=True)  # That's it — chains, graphs and agents auto-traced

# Use LangChain as normal — nothing else changes
from langchain_openai import ChatOpenAI
from langchain_core.prompts import ChatPromptTemplate

chain = ChatPromptTemplate.from_template("Tell me about {topic}") | ChatOpenAI(model="gpt-4o")
result = chain.invoke({"topic": "otters"})  # ← one trace, sent when the chain completes
A trace is sent when a chain, agent, or graph run completes. A bare llm.invoke("Hello!")
with no surrounding chain never reaches that boundary, so it sends nothing — wrap the call, or
see manual tracing for the per-call
handler.
OpenAI Agents SDK
import decimalai

decimalai.init(openai_agents=True)
Any Framework — Manual Tracing
import decimalai

decimalai.init()

@decimalai.trace(agent_name="my-agent")
def run_agent(query):
    msgs = [{"role": "user", "content": query}]
    resp = openai.chat.completions.create(model="gpt-4o", messages=msgs)
    decimalai.log_llm_call(
        model="gpt-4o",
        input=msgs,
        output={"content": resp.choices[0].message.content},
    )
    return resp.choices[0].message.content
Environment Variable Setup (No Code Changes)
export DECIMAL_API_KEY=dai_sk_...
export DECIMAL_AUTO_TRACE=langchain   # or "openai-agents"
# Just run your app — tracing activates on import
python app.py
What It Does
- Auto-tracing — Captures LLM calls, tool calls, and agent steps with zero code changes
- Agent versioning — Auto-detects tool schemas, prompts, models, and graph topology
- Change detection — Detects when your agent configuration drifts
- Inline evals — Run eval functions on every trace with
@decimalai.evals.eval - Built-in deterministic scores —
completion,has_output,tool_compliance,latency,token_efficiency, attached by the LangChain adapter only:decimalai.langchain.instrument(...), disabled withinstrument(..., builtin_evals=False). No other adapter attaches them today. These run in your process, not server-side — bare HTTPPOST /tracesdoes not auto-score. - Batch evals — Run evals offline across historical traces
- Dataset pull — One-liner to download versioned training data:
decimalai.pull_dataset("ds_abc", "./data.jsonl") - HuggingFace Hub — Push datasets to HF Hub for instant Axolotl/Unsloth/TRL compatibility
- Fine-tuning — Launch fine-tuning jobs on OpenAI, Together.AI, or Gemini from the platform
- Skills management — Auto-discover SKILL.md files, sync to platform, install from registry
- OTel compatible — Export spans to any OpenTelemetry backend
How it fits together
The SDK is the client for the hosted platform and the reference implementation of two open specs — everything it captures is portable by design:
flowchart LR
  A[your agent code] --> SDK["decimalai SDK<br/>traces + manifests"]
  SDK --> API["DecimalAI platform<br/>registry + SkillScore"]
  SDK -.->|implements| AV[agentversion spec]
  SDK -.->|implements| SE[skillevaluation spec]
  RC["regression-check<br/>CI action"] --> API
agentversion— the open manifest spec (versioning, diffing, compatibility)skillevaluation— the open A/B spec for measuring a skill's liftregression-check— the GitHub Action that runs the per-PR structural check
How does DecimalAI compare?
DecimalAI is not a tracing or eval-case platform — it's the structural layer that runs alongside one. LangSmith, Braintrust, and promptfoo watch your agent's outputs; DecimalAI versions its structure (tools + prompts + models + skills) and diffs every change against your recorded production traffic. Keep your eval tool; add the manifest layer under it.
| Capability | DecimalAI | LangSmith | Braintrust | promptfoo |
|---|---|---|---|---|
| Structural regression check against production traces — no eval cases to write | ✅ per-PR impact report (regression-check) | ❌ needs datasets; online evals score outputs | ❌ needs datasets; online scoring rates outputs | ❌ needs test cases you write |
| Whole-agent version manifest, diffable with an open spec | ✅ agentversion — tools + prompts + models + skills | Prompts only (Prompt Hub commits) | Prompts only (versioned prompts + experiments) | ❌ config versioning via your own git |
| Open A/B spec to measure a skill's lift — re-runnable by anyone | ✅ skillevaluation | ❌ | ❌ | ❌ |
| Skills registry with pre-publish security scanning | ✅ deterministic scan blocks unsafe skills before publish | ❌ | ❌ | ❌ |
| Output-quality evals: datasets, LLM-as-judge, playgrounds | ❌ by design — keep your eval tool alongside | ✅ | ✅ | ✅ |
| Adversarial red-teaming of your own app | ❌ | ❌ | ❌ | ✅ |
| Fully open source, runs 100% locally | Partial — SDK, Action, and specs are MIT / Apache-2.0; the platform is hosted | ❌ self-host is Enterprise-only | ❌ self-host is Enterprise-only | ✅ |
The regression demo (decimalai demo regression) runs the real pipeline on a seeded reference agent — its numbers are illustrative; run it yourself, then instrument your own agent for real ones. Competitor capabilities checked against each tool's public docs, August 2026.
Skills
DecimalAI auto-discovers your existing SKILL.md files and provides observability — tracking which skills activate, how effective they are, and how they change over time.
Auto-Discovery (Bring Your Own Skills)
If you already have SKILL.md files (from npx skills add, your team's repo, or hand-written), the SDK discovers them automatically:
import decimalai
decimalai.init(api_key="dai_sk_...")

from decimalai.openai_agents import instrument
instrument()  # Scans .claude/skills/, .agents/skills/, etc. → syncs to dashboard
Supports 32 agent runtimes: Claude Code, Cursor, Copilot, Windsurf, Continue, and more.
Registry Search & Install
Find community skills and install them in one call:
from decimalai.skill_router import SkillRouter
router = SkillRouter(api_key="dai_sk_...")

# Search the public registry
results = router.search("code review security")

# Install a skill — a LINK into your workspace, tracking the author's updates
router.use("pdf")

# Write the files to disk, for runtimes that load SKILL.md themselves
router.export("pdf", agents=["claude-code", "cursor"])

# Take an editable copy, only if you intend to change it
router.fork("pdf")
Status & Update
# Check sync status between local files and platform
status = router.status()
# → {"synced": [...], "modified_locally": [...], "untracked": [...]}

# Pull upstream updates
router.update_skills()
Skill Delivery at Runtime (enable_skill_loader)
Discovery and sync (above) get skills into the platform. To get them into your agent's context at runtime, enable the skill loader on your adapter's instrument():
import decimalai
decimalai.init()

from decimalai.openai_agents import instrument  # or .langchain / .anthropic / .pydantic_ai
instrument(enable_skill_loader=True)
With the loader on, the router adds a ranked menu of relevant skills to the prompt (one short row per skill: name + when to use it). A menu row alone is only an offer — the skill's actual content (its body) reaches the model through one of three delivery mechanisms:
- Body injection —
decimalai.init(inject_skill_body=...)(orDECIMALAI_INJECT_SKILL_BODY=0/1) injects the top-routed skill's full body into the prompt, trimmed to a token budget. The flag is tri-state, not opt-in: left unset it defaults on for the adapters where injection is the only body channel (langchain,anthropic,adk— none of them register aload_skilltool) and off foropenai_agentsandpydantic_ai, which fetch on demand rather than double-deliver (turn theload_skilltool off and injection takes over there too). An explicitTrue/Falsealways wins. Pydantic AI also builds its prompt in full-menu mode (no query available), so bodies arrive viaload_skillthere. load_skilltool — on adapters that own their tool loop, aload_skilltool registers automatically whenever the loader is enabled, so the model can fetch any offered skill's body mid-turn. On by default; kill switch:decimalai.init(load_skill_tool=False)orDECIMALAI_LOAD_SKILL_TOOL=0. It is not aninstrument()parameter on these adapters.- Export to disk — for runtimes that natively load skills from files (Claude Code, Cursor, ...), write them out with
router.export(...)ordecimalai skills exportand let the runtime deliver them. Export takes no copy and needs no fork; you can export a skill you only linked.
Delivery support differs per adapter — the asymmetry is structural (load_skill needs a tool loop the adapter controls):
| Adapter | Menu + body injection | load_skill tool |
Notes |
|---|---|---|---|
decimalai.openai_agents |
✅ | ✅ | tool auto-registers with the loader |
decimalai.pydantic_ai |
✅ menu / ❌ body injection | ✅ | full-menu mode (no query at prompt-build time) — bodies arrive via load_skill |
decimalai.langchain |
✅ | ❌ injection-only | enable_load_skill_tool accepted but dormant (warns) |
decimalai.adk |
✅ | ❌ injection-only | bodies appended to system_instruction; enable_load_skill_tool accepted but dormant (warns) |
decimalai.anthropic |
✅ | ❌ injection-only | patches a single messages.create() — no loop to route a tool result back |
decimalai.claude_agent_sdk |
❌ disk-only | ❌ | tracing-only adapter; Claude Code loads skills itself from .claude/skills/ |
generic (@decimalai.trace) |
❌ disk-only | ❌ | no prompt-assembly hook; use disk install |
Honest-measurement note: menu-only (loader on, no body injection, no load_skill tool) means the model sees that a skill exists but never its content. Usage from that channel counts as offered, not activated — don't expect activation stats from prompt-injection-only setups.
Other Ways to Use Skills (No SDK)
Every published skill is reachable without installing anything:
- Web copy-paste — open any skill's scorecard page on app.decimal.ai/skills, hit Copy SKILL.md, and paste it into your repo.
- Raw URLs —
https://app.decimal.ai/s/<slug>/SKILL.mdserves the raw markdown (version-pinned:/s/<slug>@<version>/SKILL.md);https://app.decimal.ai/s/<slug>.jsonserves machine-readable metadata (lift summary, benchmark models, trust/safety bands);https://app.decimal.ai/llms.txtindexes the registry for agents. - CLI pull (no account) —
decimalai skills pull <slug>writes just the file to disk; no fork, no signup. (decimalai skills install <slug>forks + syncs if you do have a key.) - MCP server — search and read skills from any MCP client (
pip install decimalai-mcp).
See the full SDK Skills Reference for all methods.
Datasets & Training
Pull Training Data
import decimalai
decimalai.init()

# Pull the latest version to a local file
result = decimalai.pull_dataset("ds_abc123", "./training_data.jsonl")
print(f"Wrote {result['row_count']} rows")

# Pull a specific version
result = decimalai.pull_dataset("ds_abc123", "./data.jsonl", version="v2")
Push to HuggingFace Hub
# Push to HF Hub — instantly loadable by Axolotl, Unsloth, TRL
result = decimalai.push_to_hub("ds_abc123", "my-org/support-agent-sft")

# Now usable everywhere:
# from datasets import load_dataset
# ds = load_dataset("my-org/support-agent-sft")
Load as HuggingFace Dataset (In-Memory)
# Skip files — load directly into your training script
ds = decimalai.load_hf_dataset("ds_abc123")
# → Dataset({features: ['messages'], num_rows: 500})
CLI
# Pull latest version
decimalai datasets pull ds_abc123 -o ./training_data.jsonl

# Pull specific version as Parquet
decimalai datasets pull ds_abc123 -o ./data.parquet --version v2

# Push to HuggingFace Hub
decimalai datasets push-to-hub ds_abc123 my-org/support-agent-sft
Fine-Tuning Providers
| Provider | Models | Setup |
|---|---|---|
| OpenAI | GPT-4o, GPT-4.1-mini | Dashboard or API |
| Together.AI | Llama 4, Qwen 3, DeepSeek R1, Mistral | Dashboard or API |
| Gemini | Gemini 2.5 Flash/Pro | Dashboard or API |
Supported Frameworks
| Framework | Status | Setup |
|---|---|---|
| LangChain / LangGraph | ✅ | init(langchain=True) |
| OpenAI Agents SDK | ✅ | init(openai_agents=True) |
| Google ADK | ✅ (native) | init(adk=True) |
| Anthropic Claude Agent SDK | ✅ (native) | init(claude_agent_sdk=True) |
| Pydantic AI | ✅ | from decimalai.pydantic_ai import instrument (no init() flag) |
| LlamaIndex | ✅ | init(llamaindex=True) |
| CrewAI | ✅ | init(crewai=True) |
| Generic (any framework) | ✅ | @decimalai.trace() |
| OpenTelemetry | ✅ | init(otel=True) |
Tracing a direct LLM SDK with no agent framework? Use the provider flags: init(openai=True), init(anthropic=True), or init(google=True).
Examples
See the examples/ directory for runnable notebooks with Open in Colab badges:
| Notebook | Description | Colab |
|---|---|---|
| Quickstart | Full version-aware loop — no LLM key needed |  |
| LangChain | Instrument a LangChain agent | |
| OpenAI Agents | Instrument an OpenAI Agents app | |
| Evaluations | Run built-in evaluators on traces | |
| Datasets | Build SFT training datasets | |
| Pull & Push | Pull datasets locally, push to HuggingFace Hub | — |
| Version-Aware Loop | Detect manifest changes and impact | |
Open standard: agentversion
The manifests this SDK captures are agentversion manifests — the open spec for agent versioning, diffing, and compatibility decisions that DecimalAI is built on. export_manifest hands a captured manifest to the OSS tooling, so you can diff and gate it in CI with no platform account:
import decimalai
from decimalai.schema.manifest import extract_from_config
from agentversion.diff import diff_manifests              # pip install agentversion
from agentversion.compatibility import classify_compatibility

snap = extract_from_config(agent_name="support-agent", prompts={...}, models={...})
manifest = decimalai.export_manifest(snap)                # → an agentversion manifest dict
print(classify_compatibility(diff_manifests(last_prod, manifest)).recommended_decision)
You can reproduce the platform's diffs and verdicts entirely outside DecimalAI — the SDK is the convenience layer over the open standard.
FAQ
How is this different from LangSmith / Braintrust / Weave?
They watch your agent's outputs — traces, eval scores, feedback. DecimalAI watches its structure: a versioned manifest of tools + prompts + models + skills, diffed against your recorded traffic. Tracing answers "what happened," evals answer "how well," this answers "is this data still usable now that the agent changed?" It's not either/or — DecimalAI runs alongside them, and we recommend keeping your tracing tool.
Isn't the regression check just a linter?
A linter checks code against static rules someone wrote. This checks an agent change against your actual production history: for each recorded trace, did it depend on a surface this change touches? There's no ruleset to write or maintain — your traffic is the ruleset. The output isn't "style violation," it's "these conversations will break and this slice of your training set is now stale."
Are the demo's numbers real? Whose traffic is that?
The demo runs on a seeded reference agent built for the demo — not a customer's traffic. The pipeline is the real one; the numbers are illustrative, and we say so everywhere they appear. When you run the check on your own instrumented agent, it's your traffic in your workspace.
Is the "lift" number on a skill real? Can I reproduce it?
The measurement spec is open: same task set run in two arms (with the skill injected vs. without), same model, conformance-graded, with a minimum case count, a never-hurt check, and a negative control. pip install skillevaluation and re-run any published number. The honest state today: effectiveness figures on the site are labeled "illustrative — run it yourself" until a skill's full benchmark run lands — no skill is claimed as measured unless its number was actually produced by that spec.
What data leaves my machine? Do you run my agent?
DecimalAI never runs your agent and never holds your LLM API keys. The SDK sends traces to your workspace; the PR check is a read query over your own trace store — zero LLM calls. The optional mode=real call-replay uses your key, on your opt-in, for same-provider swaps only. Everything the SDK sends is visible in your dashboard and exportable.
Do I need an account?
For the regression check and tracing, yes — a free API key (traces have to live somewhere). Without any account you can still: browse the registry, pull any published skill with decimalai skills pull <slug>, and diff agent manifests fully locally with agentversion.
Can I self-host? Why isn't the whole platform open source?
The measurement layer is open on purpose: skillevaluation (the A/B eval spec + runner) and agentversion (the manifest spec) are on PyPI, and this SDK and the GitHub Action are MIT. Every number published is checkable without trusting us. The hosted platform — the trace store, the registry, the scanning pipeline — is not open source; charging for hosting is how a solo-founder project survives. Worst case, you lose a vendor, not your history: the specs are open and your traces are exportable.
Why should I trust the security scanner?
Don't trust it — test it. The first-tier scan is deterministic and findings are shown in full; we planted a skill with a hidden reverse shell against our own registry and it was blocked with 2 critical findings, no human in the loop. And the honest part: a scan is a floor, not a guarantee — which is why there's an intent-review tier on top, an appeal path for authors, and no "0 false positives" claim anywhere.
Development
pip install -e ".[dev]"
python -m pytest tests/ -q --ignore=tests/test_langchain_compat.py
ruff check decimalai/ --select I,E,W,F --ignore E501,E402,F821,F841
git grep -nE 'decimal[-_]ai'   # must find nothing — the package is 'decimalai', no separator
Run these before opening a PR. CI runs the same commands, plus the LangChain compatibility matrix in tests/test_langchain_compat.py. See AGENTS.md if you're pointing an AI coding agent at this repo.
Documentation
Full docs at docs.decimal.ai
License
MIT — see LICENSE for details.
Docs · Registry · SDK · Specs: agentversion · skillevaluation · regression-check
1 maintainer

Metadata
1 maintainer
Release files for decimalai 0.13.7
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| decimalai-0.13.7.tar.gz | 1.3 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| decimalai-0.13.7-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.8 MB
Release files / decimalai-0.13.7.tar.gz
| Download URL | decimalai-0.13.7.tar.gz |
|---|---|
| Size | 1.3 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
351c7de5bffe61b886123c8a56f6bda903f2601d71a012824a957442f7562077
|
|
BLAKE2b-256 checksum How to use checksums |
a32bccf85b0b37cb87192374c9aca27a404eeec5836738748084e0fea89b8daa
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 24, 2026.
Transparency logRelease files / decimalai-0.13.7-py3-none-any.whl
| Download URL | decimalai-0.13.7-py3-none-any.whl |
|---|---|
| Size | 489.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
921912b71e0b2df73b60f46f03bd60e3a75b09f4a398f34c7441cafd0d5c333b
|
|
BLAKE2b-256 checksum How to use checksums |
9ba626022f6774b27717731a45c51ee3a8af4228d8e74cf8e15ed98396c18ad0
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 24, 2026.
Transparency log













