
🧲 DELT
Zero-shot and Few-shot Multimodal Classification with Label Tuning
A toolkit for zero-shot, label tuning, and distillation with dual encoders.



👋 DELT
Applications where embeddings serve as persistent representations—such as semantic search, recommendation, document ranking, and RAG—benefit from efficient zero-shot classification based on similarities between input and label embeddings, enabling personalized retrieval. However, adapting these representations to evolving user preferences typically requires retraining the underlying encoder. Label tuning offers an efficient alternative by adapting only the label embeddings, enabling the reuse of precomputed embeddings. delt allows you to operationalize label tuning in embedding-based applications, supporting:
- 🚀 Perform zero-shot classification without training data.
- 🎯 Fine-tune classifiers using only a few labeled examples through label tuning.
- 🌍 Work across text, images, audio, and video using a unified API.
- ⚡ Train in seconds by optimizing only lightweight label embeddings.
- 💻 Run inference efficiently on CPU once embeddings are available.
- 🤖 Distill powerful LLMs and multimodal models into compact, production-ready classifiers.
Whether you have zero, ten, or millions annotated samples, delt provides a simple pipeline that scales with your data.
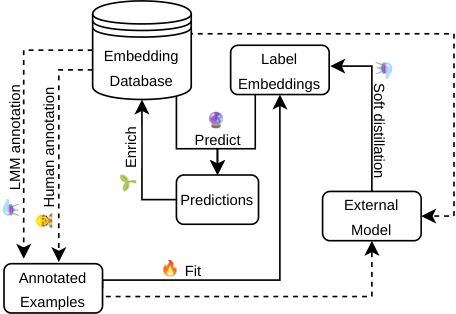
Figure 1. DELT diagram.
✨ How it works
delt is built around dual-encoder embedding models, supporting zero-shot classification and finetuning through label tuning.
If you have no annotated data, delt performs zero-shot classification directly using pretrained embedding models, that is: no optimization, no gradient updates, no training loop, simply define your labels and start predicting.
When a labeled dataset is available (few data or a large volume), delt optimizes the label embeddings through label tuning while keeping the encoder frozen. This offers embedding reusability, dramatically fewer trainable parameters, faster training, smaller deployment artifacts, and competitive accuracy, making it especially suitable for embedding-based applications where embeddings are precomputed—such as retrieval-augmented generation (RAG) systems, visualization tools, and semantic search pipelines. The idea is simple and was originally proposed in (Müller Thomas, et al., 2022) and has been here extended for multimodal dual encoders:
Given a sentence like
"I love this movie."
and the label
"positive"
delt finetunes label embeddings computed from pretrained embedding models such that
❄️embedding("I love this movie")❄️ ≈ 🔥embedding("This review is positive")🔥
where ❄️ and 🔥 refer to frozen and trainable parameters. Unlike traditional training methods, the encoder remains frozen while only the label representations are optimized. In practice, the trainable component contains only (number_of_labels × embedding_dimension) parameters, making label tuning remarkably efficient while preserving the knowledge of the original embedding model.
When human-annotated data is unavailable and zero-shot methods do not deliver sufficient performance, delt provides distillation as an alternative. It supports both soft distillation, where label embeddings are fine-tuned to match the probability distribution produced by more powerful but computationally expensive models, and hard distillation, where label embeddings are fine-tuned to reproduce the labels predicted by models that do not provide class probabilities (e.g., LLMs and LMMs).
This approach enables knowledge from highly capable models to be compressed into a relatively small set of parameters, making it practical to deploy their capabilities in large-scale applications where running an LLM or LMM on every example would be prohibitively expensive. You can just select a random set of your million documents, annotate it with an LLM, train a model with delt, and predict all the remaining data with your brand new model in a more efficient way.
🚀 Supported modalities
delt provides ready-to-use encoders for every modality. However, you're also free to use precomputed embeddings instead.
| Modality | Provided encoders |
|---|---|
| 🈳 Text | Sentence Transformers |
| 🖼 Image | CLIP, SigLIP, SigLIP2 |
| 🔊 Audio | CLAP, GLAP |
| 🎥 Video | X-CLIP |
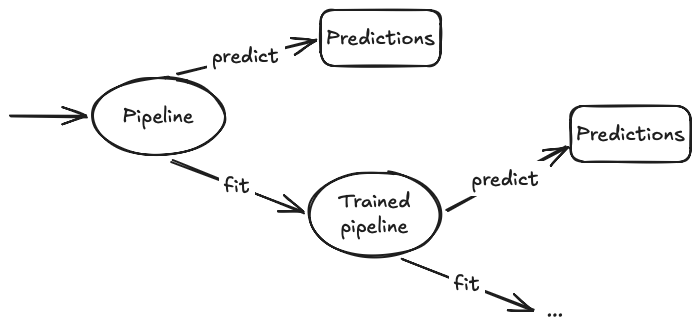
Every modality follows exactly the same workflow, so learning one modality means learning them all:
Figure 2. A pipeline in delt works in the same way for every modality.
📦 Installation
You can install delt using either uv or pip:
uv add deltpy
or
pip install deltpy
For some cases such as hard distillation with LLMs, you will need environment variables depending on the LLM you use (through LiteLLM):
OPENAI_API_KEY=<KEY>
GEMINI_API_KEY=<KEY>
🚀 Pipeline example
The API is intentionally minimal. For examples of how to use delt for every modality, take a look to the pipeline examples folder.
from delt import TextPipeline

# Set your data and configure the encoder
texts = ["I'm happy", "I'm sad", "You're strong", "I hate you."]
label_verbalizations = {
    "positive": "really positive",
    "negative": "really negative",
}
truths = [0, 1, 0, 1]
prompt_template = "This text is {}"
encoder_class = "sentence-transformer"
encoder_name = "sentence-transformers/all-MiniLM-L6-v2"

# Instantiate the pipeline
pipeline = TextPipeline(
    encoder_name, encoder_class, label_verbalizations, prompt_template
)

# Zero-shot prediction
preds = pipeline.predict(texts, batch_size=8)

# Label-tuning training
training_output = pipeline.fit(texts, truths)

# Prediction after training
preds = pipeline.predict(texts, batch_size=8)
The same design applies to images, audio, and video.
⚡ Label tuning example
If you already have precomputed embeddings and annotations, you can use the EmbeddingPipeline to train label embeddings and perform inference.
import torch
from delt import EmbeddingPipeline

# Define your input embeddings
input_embeddings = torch.vstack(
    [torch.randn(100, 16), torch.randn(100, 16) + 2]
)

# Define your label embeddings
label_embeddings = torch.vstack([torch.randn(1, 16), torch.randn(1, 16) + 2])

# Define your truth labels
truths = [0] * 100 + [1] * 100

# Instantiate the pipeline
pipeline = EmbeddingPipeline(label_embeddings)

# Zero-shot prediction
preds = pipeline.predict(input_embeddings, batch_size=8)

# Label-tuning training
training_output = pipeline.fit(input_embeddings, truths)

# Prediction after training
preds = pipeline.predict(input_embeddings, batch_size=8)
🧪 Distillation example
Instead of manually annotating thousands of examples, a stronger model can act as a teacher, while delt learns a lightweight student.
Both soft and hard distillation are supported by delt. You can take a look to the soft distillation and hard distillation folders to see how it works. Here we show an example to distill gpt-5.4-nano into label embeddings for a sentiment analysis task:
from delt.pipelines import TextPipeline
from delt.teachers import LLMTextTeacher

# Define your input data and label set
texts = ["I hate you", "I love you"]
label_set = ["positive", "negative"]

# Instante the teacher model
teacher = LLMTextTeacher(
    "gpt-5.4-nano",
    {"temperature": 0},
    "Classify the following texts into positive or negative for a sentiment analysis task.",
)

# Generate the labels (`predict`) or probs (`predict_proba`)
truths = teacher.predict(texts, label_set)

# Create the label verbalizations (same order as the label set)
label_verbalizations = {
    "positive": "really positive",
    "negative": "really negative",
}

# Set the encoder
prompt_template = "This text is {}"
encoder_class = "sentence-transformer"
encoder_name = "sentence-transformers/all-MiniLM-L6-v2"

# Instantiate the pipeline
pipeline = TextPipeline(
    encoder_name, encoder_class, label_verbalizations, prompt_template
)

# Zero-shot prediction
preds = pipeline.predict(texts, batch_size=8)

# Label-tuning to train the student model
training_output = pipeline.fit(texts, truths)

# Prediction after training
preds = pipeline.predict(texts, batch_size=8)
🖥 User Interface
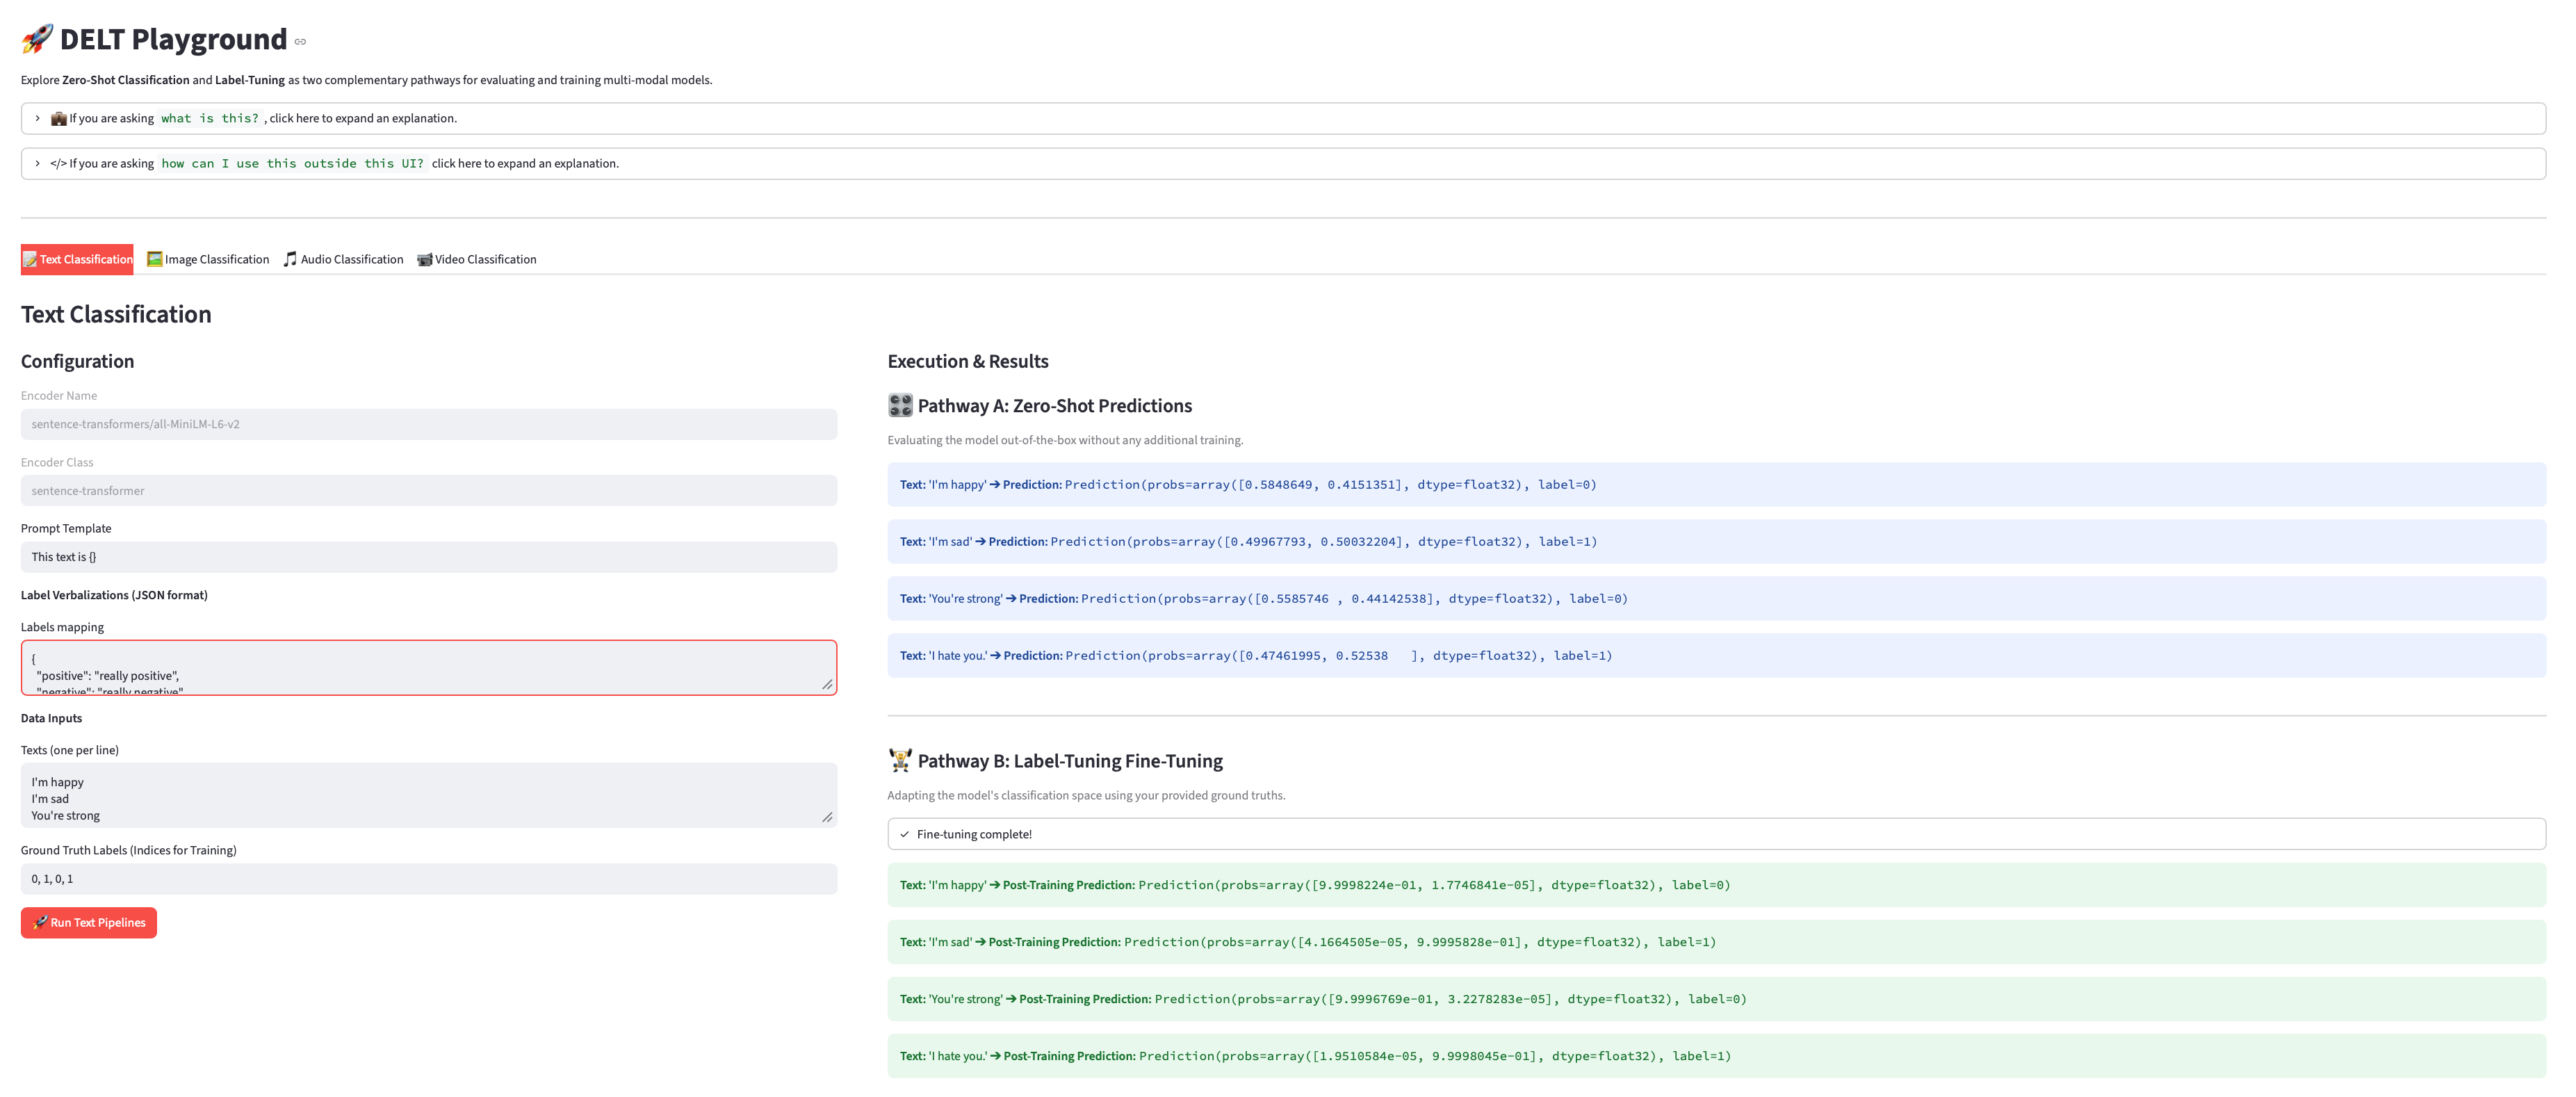
delt ships with a lightweight Streamlit application for experimentation.
uv run streamlit run src/delt/ui/app.py
Figure 3. delt playground.
📚 How to cite
delt extends the label tuning strategy, introduced in (Müller Thomas, et al., 2022), for multimodal dual encoders. If delt contributes to your research, please consider citing the original paper and this repository:
@inproceedings{muller-etal-2022-shot,
    title = "Few-Shot Learning with {S}iamese Networks and Label Tuning",
    author = {M{\"u}ller, Thomas  and
      P{\'e}rez-Torr{\'o}, Guillermo  and
      Franco-Salvador, Marc},
    editor = "Muresan, Smaranda  and
      Nakov, Preslav  and
      Villavicencio, Aline",
    booktitle = "Proceedings of the 60th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers)",
    month = may,
    year = "2022",
    address = "Dublin, Ireland",
    publisher = "Association for Computational Linguistics",
    doi = "10.18653/v1/2022.acl-long.584",
    pages = "8532--8545",
}

@software{delt,
  author       = {González, José Ángel and Aymo, Mahmoud and Bane, Fred},
  title        = {DELT: A Python Library for Multimodal Label Tuning},
  year         = {2026},
  publisher    = {GitHub},
  url          = {https://github.com/jogonba2/delt},
  version      = {main}
}
🤝 Contributing
Contributions are always welcome. Please make sure to:
- Install the development dependencies
- Format your code before submitting as
./dev-tools/format.sh - Lint your code before submitting as
./dev-tools/lint.sh - Run the test suite as
./dev-tools/test.sh - Follow the project's coding standards
- Open discussions for larger feature proposals
1 maintainer

Release files for deltpy 1.5.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| deltpy-1.5.2.tar.gz | 48.7 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| deltpy-1.5.2-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 114.0 kB
Release files / deltpy-1.5.2.tar.gz
| Download URL | deltpy-1.5.2.tar.gz |
|---|---|
| Size | 48.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
624364a8a07c24708fc761794b6d4adb4767a0d4ffc1b356025bb8fae9fe54be
|
|
BLAKE2b-256 checksum How to use checksums |
629b30868456f2a8f6b10b665b5bae915205ecc4a95620a1f57314f72da22e43
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 14, 2026.
Transparency logRelease files / deltpy-1.5.2-py3-none-any.whl
| Download URL | deltpy-1.5.2-py3-none-any.whl |
|---|---|
| Size | 65.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
328b64965644d81263373ba9f9b9d28e27bfb964eba54504f0960178bf4f3a44
|
|
BLAKE2b-256 checksum How to use checksums |
f961c8d701007bdb095c8f72b89a0ed84aacfc1fa38c91232e662f76958fa03f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 14, 2026.
Transparency log













