
D-FINE-seg
Real-Time Object Detection, Instance and Semantic Segmentation
Quick Start • Usage • Export • Inference • Benchmarks • Video Tutorial • Colab


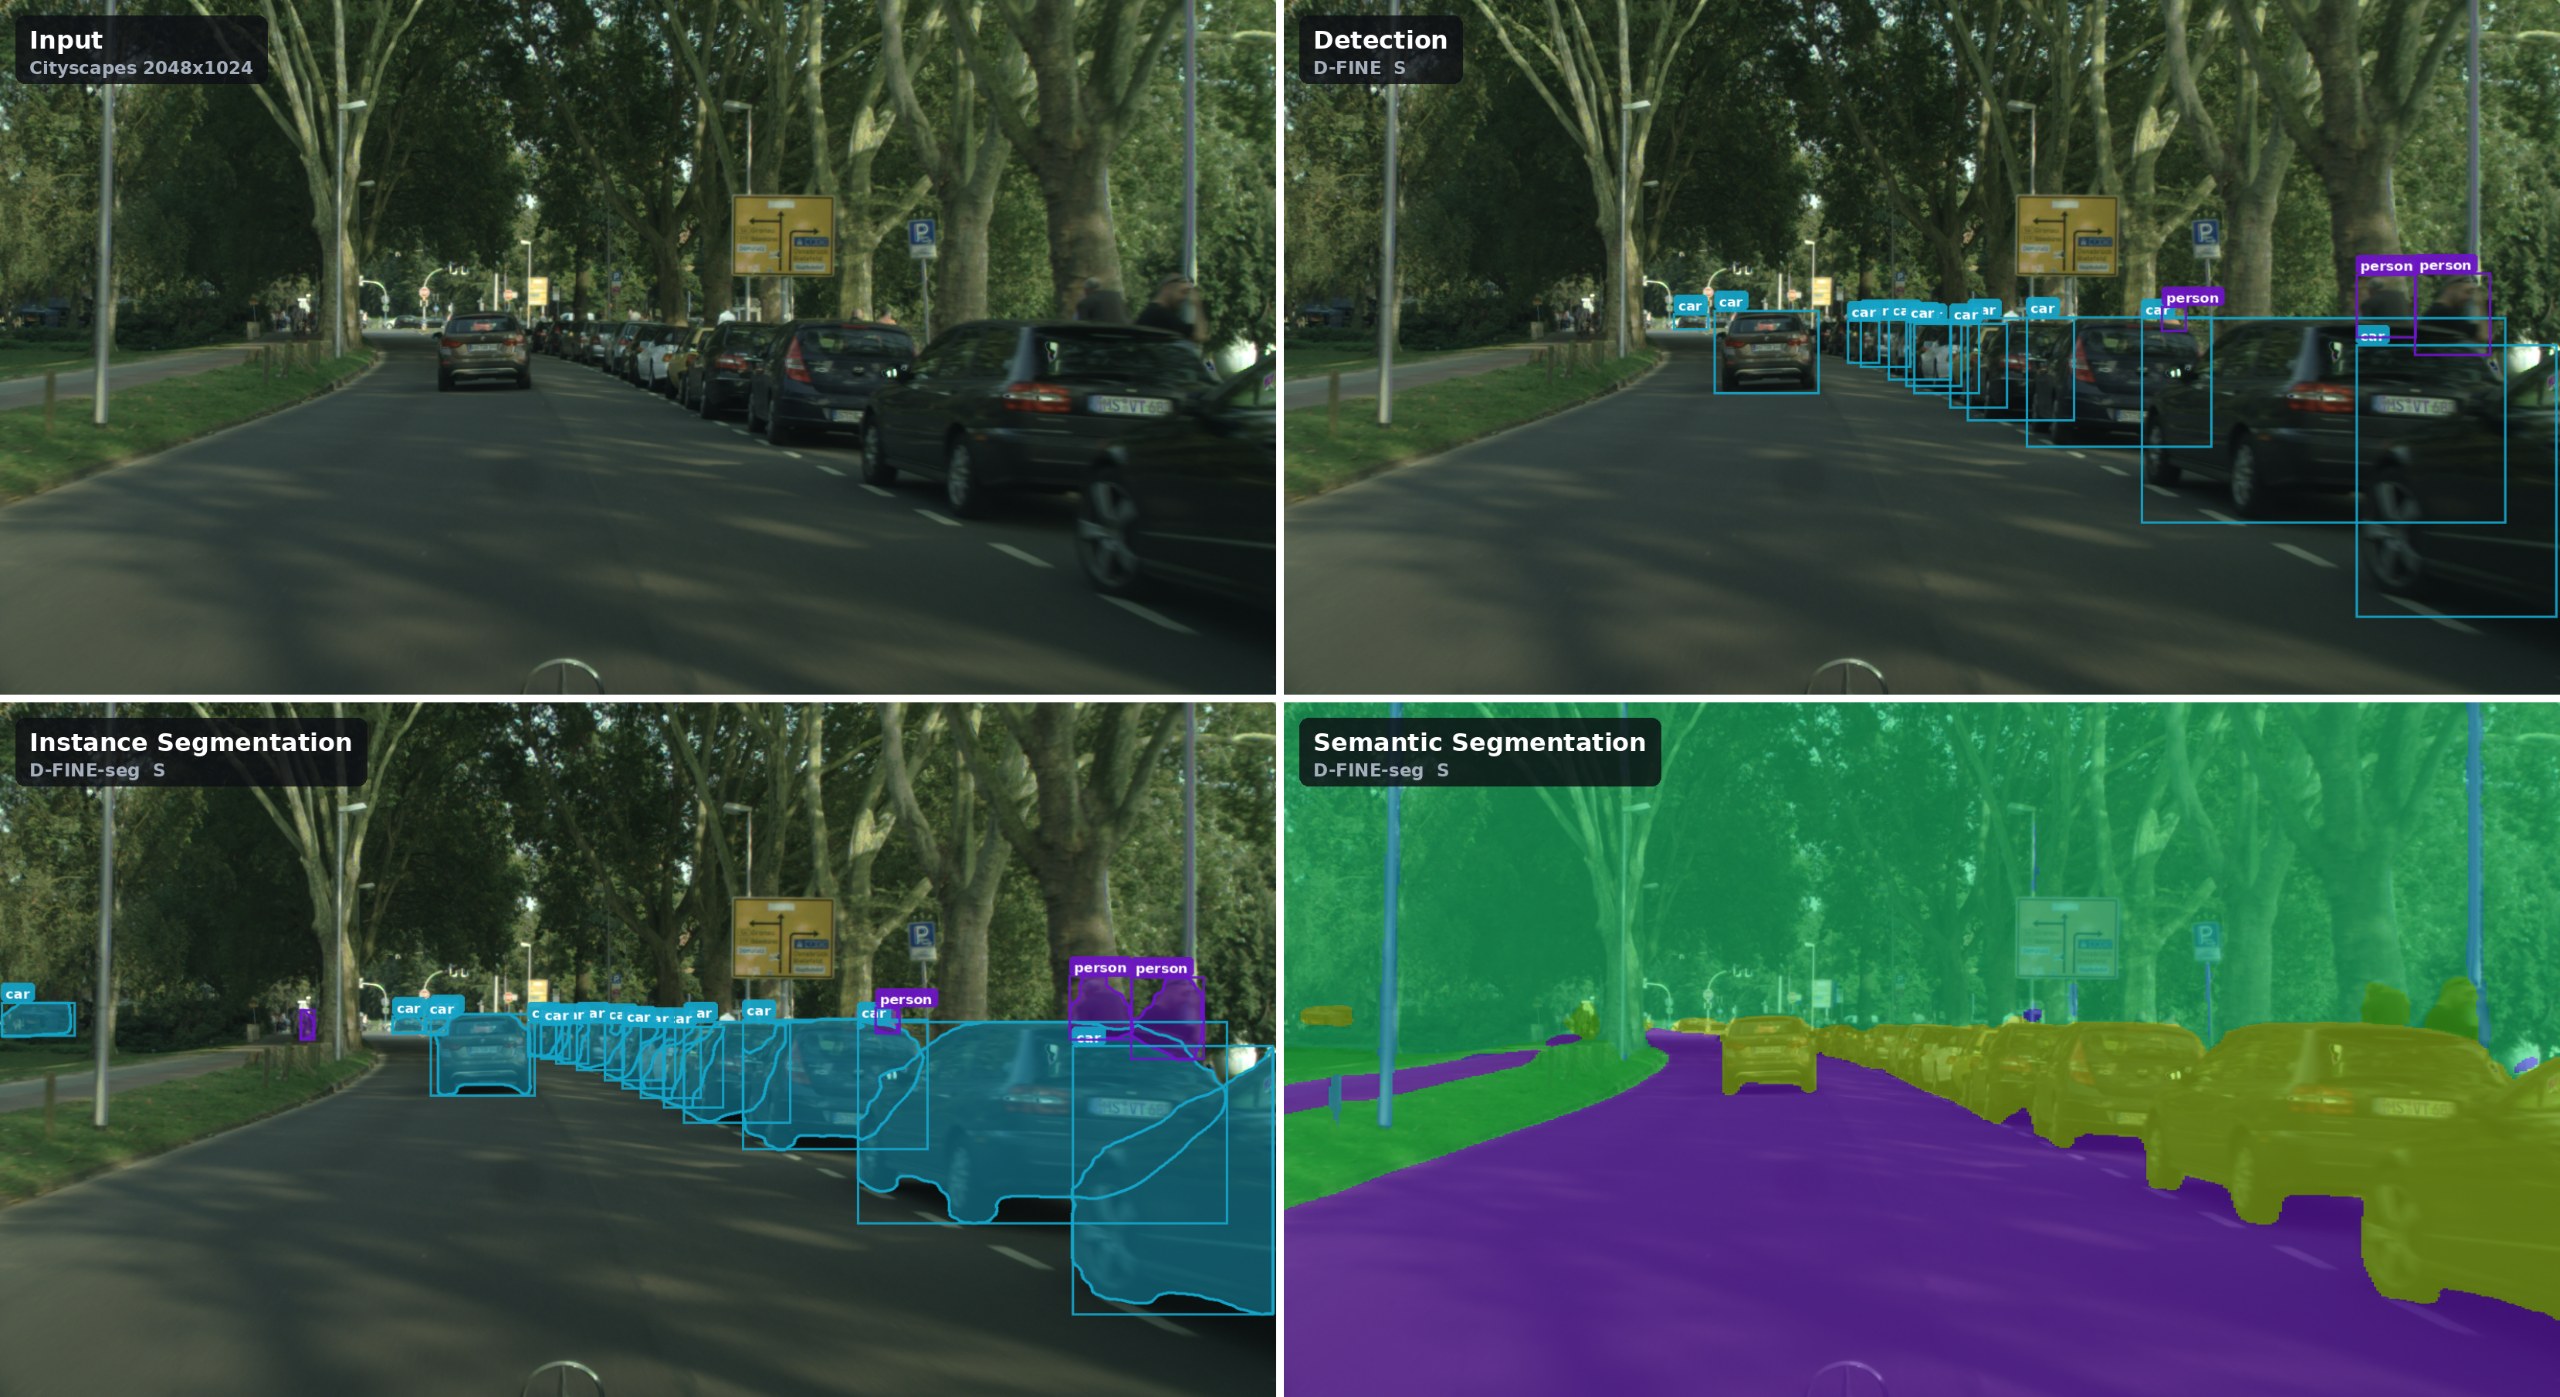
D-FINE-seg is a framework for real-time object detection, instance segmentation, and semantic segmentation - one codebase, one config flag (task: detect | segment | sem_seg), five model sizes (N -> X).
- End-to-end workflow - dataset prep -> training (DDP, EMA, AMP, mosaic) -> export (ONNX, TensorRT, OpenVINO, CoreML, LiteRT) -> benchmarked multi-backend inference
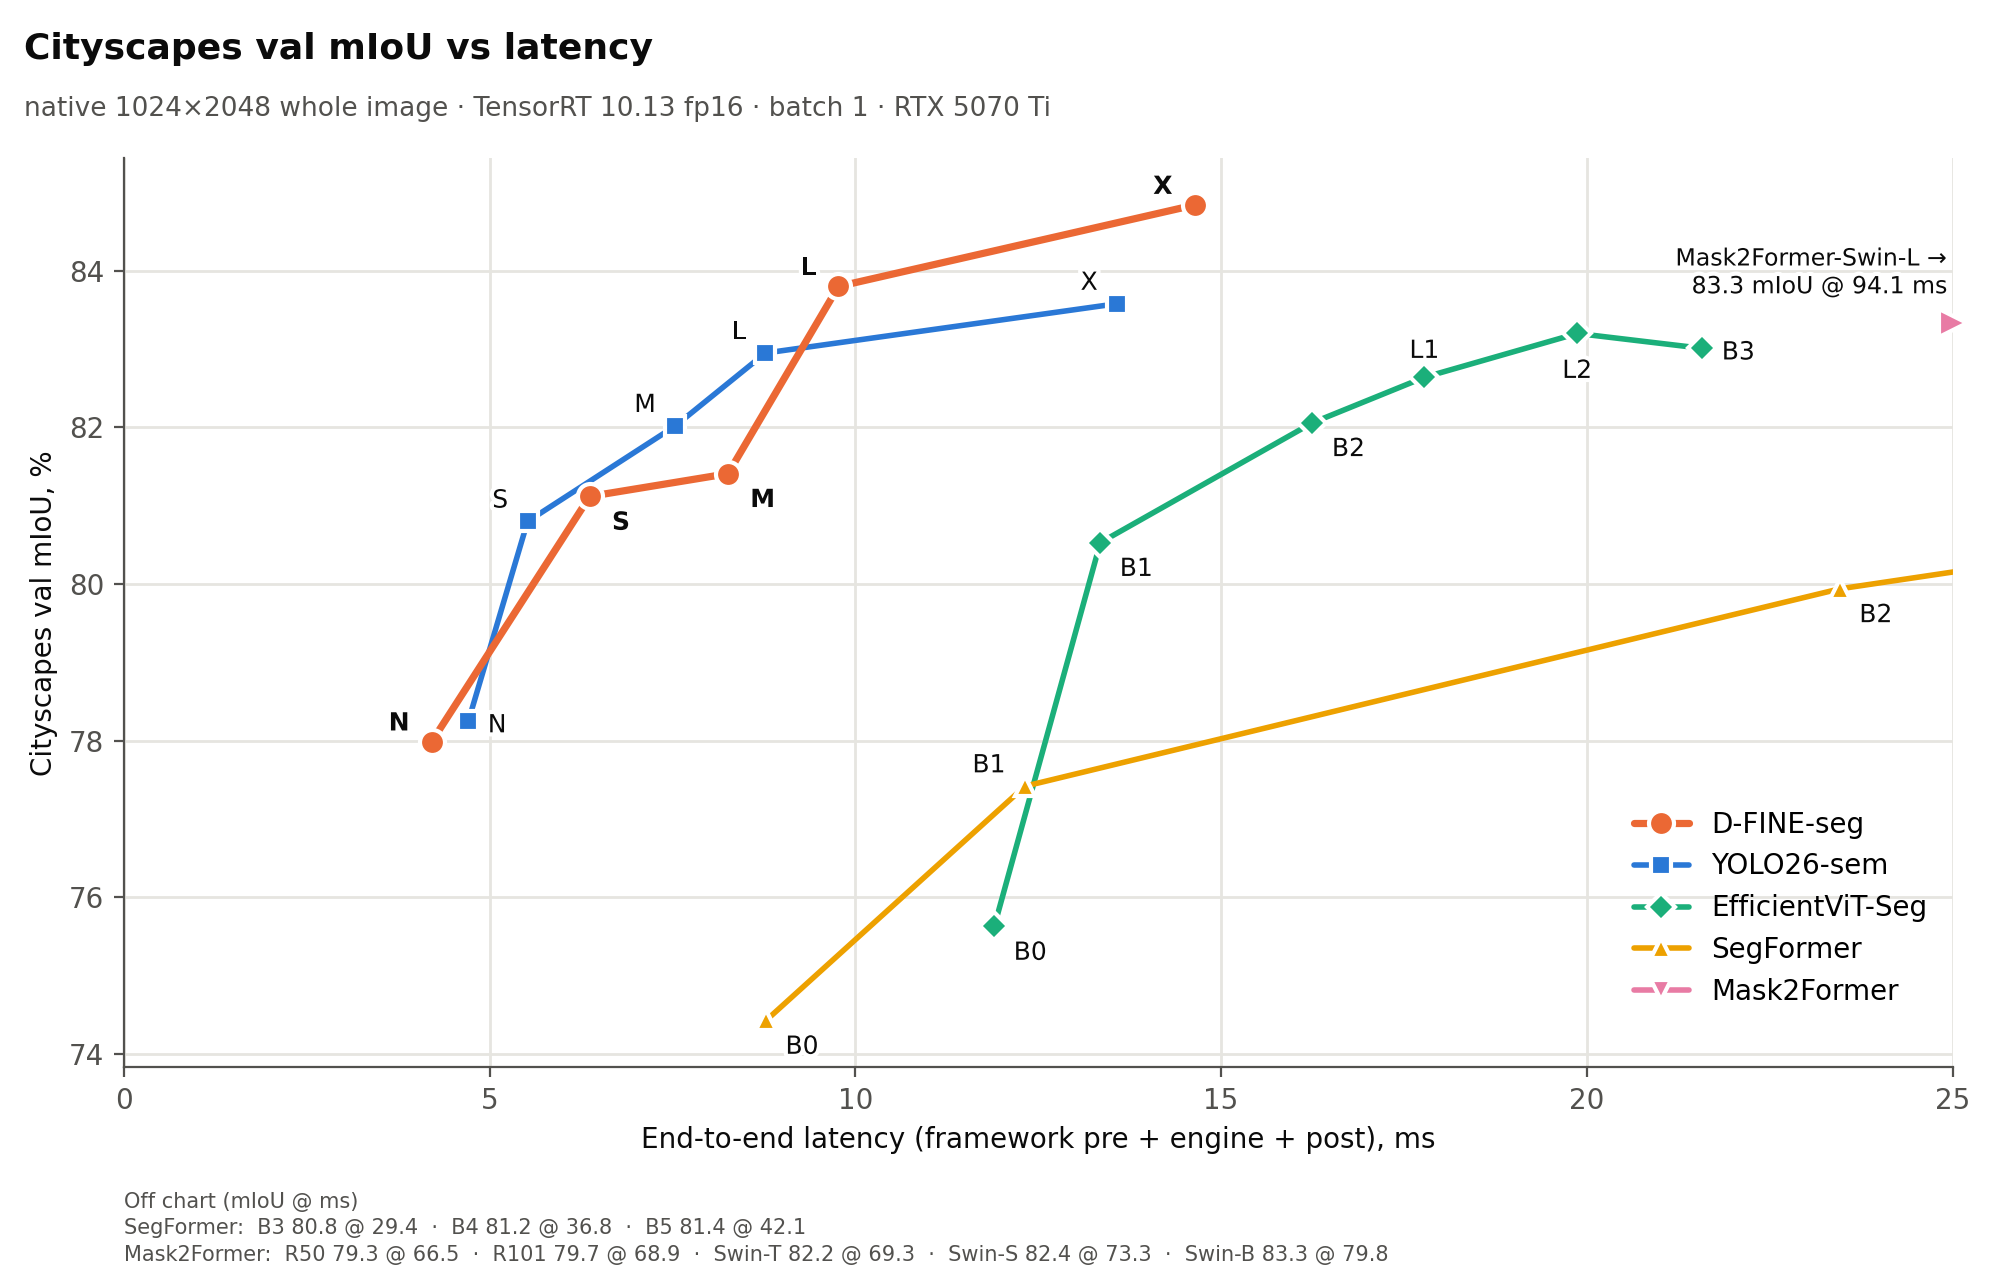
- Accuracy - Cityscapes semantic segmentation at native 1024x2048: D-FINE-X reaches 84.84 mIoU at 14.6 ms end-to-end, the highest of 28 models - +1.26 mIoU over YOLO26-x, and +1.5 mIoU over Mask2Former Swin-L with 6.4x lower latency and a quarter of the params - and D-FINE-L matches or beats YOLO26-x on every axis; also beats YOLO26 and RF-DETR on 640 Cityscapes detection & instance-seg F1, and YOLO26 on TACO and VisDrone (TensorRT FP16, end-to-end protocol)
- Paper - D-FINE-seg: Object Detection and Instance Segmentation Framework with Multi-Backend Deployment
- Not a fork: the detection core follows the D-FINE paper; segmentation heads, training, export and inference are implemented from scratch.
One frame, three tasks, one config flag:
Highlights
- Instance segmentation head (
task: segment) - lightweight mask head on top of D-FINE's HybridEncoder PAN outputs: stride 8/16/32 features fused to 1/4 resolution, then a dot-product between per-query mask embeddings (3-layer MLP) and the shared mask features yields per-instance masks - Semantic segmentation head (
task: sem_seg) - reuses the pretrained instance-seg mask fuser on full-frame features, followed by a small conv neck and 1x1 classifier: no queries, no NMS - Mask-aware training - box-cropped BCE + Dice mask losses (instance seg) and CE + multi-class soft Dice with
ignore_index(semantic seg), mask supervision inside contrastive denoising, and Dice + sigmoid-focal mask costs in the Hungarian matcher - all train-time only, zero inference cost - Pretrained weights for every task - detection on COCO (plain and Objects365-pretrained), COCO instance segmentation, Cityscapes semantic segmentation
- Multi-channel inputs - train on RGB + thermal / depth / NIR stacks (4-channel
.npy), not just RGB - Modern training stack - Muon optimizer, DDP, EMA, mosaic + affine augs, knowledge distillation, OneCycle, early stopping, rare-class sampling (LVIS repeat-factor), WandB, auto-batch size.
- Beyond the model - ByteTrack tracking, SAM3 auto-labeling, Gradio demo, INT8 quantization (OpenVINO / CoreML / LiteRT)
Quick Start
Installation
pip install dfine-seg           # inference + training
pip install 'dfine-seg[all]'    # + every export backend, SAM3, Gradio demo
Pretrained weights auto-download from Hugging Face on first use: detection on COCO (dfine_{n,s,m,l,x}_coco.pt, and dfine_{n,s,m,l,x}_obj2coco.pt - Objects365 pretraining, then COCO), COCO instance segmentation (dfine_seg_{n,s,m,l,x}_coco.pt), Cityscapes semantic segmentation (dfine_sem_{n,s,m,l,x}_cityscapes.pt).
Extras, if you need them (backends are large and platform-specific)
| Install | Adds | For |
|---|---|---|
pip install dfine-seg |
torch, torchvision, opencv, hydra, wandb, albumentations, … | inference + training |
pip install 'dfine-seg[export]' |
onnx, onnxruntime, openvino, nncf, coremltools | dfine export |
pip install 'dfine-seg[trt]' |
tensorrt (Linux) | TensorRT engines - build on the target GPU |
pip install 'dfine-seg[label]' |
transformers | SAM3 auto-labeling |
pip install 'dfine-seg[demo]' |
gradio | the Gradio UI |
pip install 'dfine-seg[all]' |
everything above | full setup |
Two-line predict:
from dfine_seg import load_model, read_image, Visualizer

model = load_model("s")                              # COCO detection, weights auto-downloaded
model = load_model("s", task="segment")              # COCO instance segmentation
model = load_model("x", task="sem_seg")              # Cityscapes semantic segmentation
model = load_model("output/models/exp/model.pt")     # your checkpoint - size/task/classes/input size auto-detected, supports: .pt | .engine | .onnx | .xml

img = read_image("path/to/image.jpg")
out = model(img)[0]
print(out["boxes"], out["scores"], [model.names[int(i)] for i in out["labels"]])

drawn = Visualizer(model)(img, out)                  # annotated BGR copy - boxes, masks or a sem_seg overlay
load_model returns the same wrapper you would construct by hand (dfine_seg/infer/) - it resolves the weights and picks the backend. Extra keyword arguments pass straight through (load_model("s", conf_thresh=0.3)), output tensors stay on the device the model ran on, and those wrapper files remain self-contained enough to copy into your own app. Visualizer reads the class count and names off the model it is given, then draws whatever that model returned - boxes, instance masks or a dense label map - so one call covers every task (BGR uint8 in, BGR uint8 out).
To train from a pip install, materialize a config and go:
dfine init          # writes ./config.yaml - edit train.root and train.label_to_name
dfine split
dfine train         # Hydra overrides work: dfine train model_name=m train.epochs=100
From source (contributors)
git clone https://github.com/ArgoHA/D-FINE-seg.git
cd D-FINE-seg
uv sync
Prepare Your Data
Two annotation formats are supported: YOLO (default) and COCO JSON. Semantic segmentation uses PNG masks instead (see below).
YOLO format (default)
data/dataset/
├── images/    # all images: .jpg, .png, etc. (.npy for multi-channel - see below)
└── labels/    # all labels: one .txt per image (same filename stem)
Detection labels: class_id xc yc w h (normalized)
Segmentation labels: class_id x1 y1 x2 y2 ... xN yN (normalized polygon coordinates)
Input types & channel order: 3-channel .jpg/.png (BGR, read via cv2.imread), 3-channel .npy (RGB, read via np.load), or 4-channel .npy (RGB+extras, e.g. RGB+thermal).
Semantic segmentation masks (task: sem_seg)
data/dataset/
├── images/    # same as YOLO layout
└── labels/    # one single-channel uint8 .png per image (same stem), pixel value = class id
Every pixel gets a class from label_to_name (background included). Pixels with value train.sem_seg.ignore_index (default 255) are excluded from loss and metrics and during inference 255 is the "background" or "ignored" class. dfine split works unchanged; keep_ratio: True is supported (letterbox pad is filled with ignore_index, so pad pixels don't supervise); coco_dataset: True is not supported for this task.
Released Cityscapes weights load with load_model("x", task="sem_seg") - names and input size come from the checkpoint. They are also a strong init for your own driving/outdoor data: point train.pretrained_model_path at one with a different label_to_name and the class heads re-initialize while the rest keeps the Cityscapes training (N from COCO detection weights, S/M/L/X from obj2coco). A model fine-tuned from them is still derived from Cityscapes and inherits its non-commercial terms (see License) - for commercial use, start from the COCO / obj2coco weights instead. Benchmark numbers and the full 28-model comparison: cityscapes-benchmark.
Multi-channel inputs (RGB + thermal / depth / NIR / …)
Set train.in_channels: 4 (3 or 4 supported) to train on RGB + one extra modality (thermal / depth / NIR). Stacks are .npy uint8 HWC arrays in images/ (RGB in planes 0-2, extras after) with YOLO labels as usual; a mismatched channel count is skipped with a warning. See dfine_seg/etl/m3fd_to_yolo.py for a ready-made RGB+thermal converter.
COCO JSON format
Place standard COCO JSON annotation files alongside your images folder. Splits are detected automatically by filename:
data/dataset/
├── images/       # all images
├── train.json    # COCO-format annotations for train split
├── val.json      # COCO-format annotations for val split
└── test.json     # (optional) COCO-format annotations for test split
Enable COCO mode by setting coco_dataset: True in your config (see below). No CSV split generation step is needed - the splits are read directly from the JSON files.
If you only have a single coco.json, run dfine split to produce train.json / val.json (and test.json when the ratios leave room) from it. It splits by image using the same split: ratios, seed and ignore_negatives as the YOLO path, keeps each image's annotations with it, and copies categories / info / licenses into every output.
Configure
Edit config.yaml - key settings:
task: detect  # detect | segment | sem_seg
exp_name: my_exp  # experiment name (used in output paths)
model_name: s  # n / s / m / l / x

train:
  root: /path/to/project  # project root, will be used for outputs
  data_path: /path/to/dataset  # folder with images/ and labels/ (YOLO) or *.json files (COCO)
  coco_dataset: False  # set True to use COCO JSON annotations (train.json / val.json / test.json)
  label_to_name:
    0: class_a
    1: class_b
  epochs: 75
  batch_size: 8
  img_size: [640, 640]  # (h, w)
Usage
| Command | What it does |
|---|---|
dfine init |
write config.yaml from the packaged template (--task, --model, -d, --force) |
dfine split |
create train/val CSV splits (test split if configured) |
dfine train |
train the model |
dfine export |
export to ONNX, TensorRT, OpenVINO, CoreML (+ LiteRT when named) |
dfine bench |
benchmark all exported models on the val set |
dfine infer |
run on test folder, save visualizations + YOLO txt predictions |
dfine check-errors |
compare predictions against GT, save only mismatches (FP/FN) |
dfine test-batching |
find optimal batch size for your GPU |
dfine ov-int8 |
INT8 accuracy-aware quantization for OpenVINO (can take hours) |
dfine trt-int8 |
TensorRT INT8 calibration |
dfine main |
train -> export -> bench in sequence (same as the bare make target) |
dfine demo |
launch the Gradio UI (needs pip install 'dfine-seg[demo]') |
dfine predict |
run a model on an image or folder, no config needed |
dfine hw_bench |
measure Torch inference throughput on this device (cuda/mps/cpu); --batch to saturate a GPU |
dfine version |
print the installed version |
Notes:
- Most commands read
config.yamland work off your trained run; exceptions —init(writes the config),predict,hw_bench,demo,version(no config needed). Every command's flags, defaults and examples:dfine <command> -h. - YOLO format:
dfine trainrequirestrain.csvandval.csvintrain.data_path(generated bydfine split). - COCO format: set
coco_dataset: True-train.jsonandval.jsonare loaded directly;dfine splitis only needed if you have a singlecoco.jsonto split. dfine inferruns Torch inference ontrain.path_to_test_dataand writes totrain.infer_path.infer/export/benchauto-pick the latest<exp_name>_<date>run undertrain.path_to_save.
Every dfine command also has a make alias (make train == dfine train), and any config key can be overridden inline:
dfine train exp_name=my_exp model_name=m train.epochs=100
Enable DDP (multi-GPU) by setting train.ddp.enabled: True and train.ddp.n_gpus: N in config. Then just run dfine train - it auto-launches with torchrun.
Training Features
| Feature | Description |
|---|---|
| Muon optimizer | Optional Newton–Schulz optimizer for encoder/decoder attention+MLP matrices |
| DDP | Multi-GPU distributed training with SyncBatchNorm |
| AMP | Automatic mixed precision (~40% less VRAM, ~15% faster) |
| EMA | Exponential moving average of weights |
| Gradient accumulation | Effective batch size = batch_size x b_accum_steps |
| Knowledge distillation | Set train.kd.teacher to a trained teacher's model.pt (same classes and channels). The frozen teacher adds its predictions to the student's loss. Start with a teacher one size up and 40% bigger input size. |
| Automatic batch size | train.batch_size: -1 probes a full training step (incl. the KD teacher) and targets ~70% of VRAM |
| Gradient clipping | Configurable max norm |
| Mosaic augmentation | 4-image mosaic with affine transforms (recommended for detection) |
| Albumentations | Rotation, flip, blur, noise, gamma, grayscale, coarse dropout, multiscale |
| OneCycleLR scheduler | Separate learning rates for backbone and head |
| Early stopping | Configurable patience |
| WandB integration | Automatic experiment tracking |
| Optimal threshold search | Auto-finds best confidence threshold after training |
| Background warm-up | Ignore background-only images for N initial epochs |
| Autoresearch loop | Research/execute loop for agents (semantic segmentation on Cityscapes), see experiments/program.md |
Export
| Format | Half Precision | Notes |
|---|---|---|
| ONNX | - | With optional fused postprocessor |
| TensorRT | FP16 | Must be exported on the target GPU. Static input shape only |
| OpenVINO | FP16, INT8 | Single export for FP32 or FP16 (pick during inference) and separate INT8 quantization script |
| CoreML | FP16, INT8 | Cross-platform export, inference on macOS / iOS. FP32 and INT8 exported by default |
| LiteRT | INT8 | On-device TFLite (mobile / edge). FP32 and INT8 exported by default |
Tip: FP16 is the best latency/accuracy trade-off for GPU (TensorRT) and CPU (OpenVINO). For Apple Silicon (CoreML), FP32 is faster.
Warning: run TensorRT engines at batch 1. On TRT 10.13.3.9 a batched engine does not compute batch elements independently - feeding four identical images through a single
execute_async_v3call returns four different results (score spread up to 0.20, and different labels), so a detection's score depends on what it happened to be batched with. Batch 1 is exact, and reproduces in raw TensorRT for FP16 and FP32 and for every optimization-profile shape, while torch and ONNX Runtime stay identical across slots (NVIDIA/TensorRT#4813).
After export, a parity self-check (export.parity, on by default) runs each backend on a shared input and writes one cosine per backend - over the sorted top-K detection scores vs torch - to parity.csv next to the weights.
For task: sem_seg every backend gets the same fused-argmax graph: a single int32 sem_seg output [B, H, W] (label map at input resolution, no detection postprocessor), and parity compares per-pixel argmax agreement instead of score cosine.
Inference
Backends
Six inference backends in dfine_seg/infer/:
| Backend | Format | Devices |
|---|---|---|
| Torch | .pt |
CUDA, MPS, CPU |
| TensorRT | .engine |
CUDA |
| OpenVINO | .xml |
CPU, iGPU |
| ONNX Runtime | .onnx |
CUDA, CPU |
| CoreML | .mlpackage |
macOS (GPU), iOS |
| LiteRT | .tflite |
CPU, mobile / edge (Android) |
Output contract: detection / instance segmentation wrappers return labels, boxes, scores (+ masks [N, H, W] for segment); sem_seg wrappers return a single sem_seg [H, W] label map at original image resolution. For sem_seg, dfine infer writes palette overlays + GT-style grayscale PNG label maps (crops and tracking are box-based and skipped).
Also provided:
Bytetrack- simple implementation of object trackerSAM3- text-promptable zero-shot segmentation for auto-labeling (multi-class: repeat--promptor pass"car, person")
Multi-Object Tracking
A simplified ByteTrack (Zhang et al., ECCV 2022) is included for persistent object tracking across video frames - uses constant-velocity motion prediction with EMA-smoothed velocity instead of a Kalman filter, blends IoU with centroid distance in the match cost, and does per-class matching by default.
Gradio Demo
dfine demo # == make demo (pip: pip install 'dfine-seg[demo]')
A web UI for running inference on uploaded images and videos (or a webcam snapshot). It starts on COCO detection s - no setup. The Model panel then swaps in any other model at runtime: a size preset, or a path/upload of your own .pt / .onnx / .engine / .xml, with a box for the class names. detect, segment and sem_seg checkpoints all render, and SAM3 is selectable as a second backend for text-promptable segmentation (prompts are comma- or newline-separated - each one becomes a class).
It serves on 0.0.0.0:7860 (LAN-reachable) and prints a warning on startup: the Model panel loads any path the browser sends, so anyone who can reach the port can load files off this machine. dfine demo --host 127.0.0.1 restores local-only.
Benchmarks
Semantic segmentation - Cityscapes at native 1024x2048
28 models from 5 families: the five D-FINE-seg sizes trained by us and 23 official Cityscapes checkpoints (YOLO26-sem, EfficientViT-Seg, SegFormer, Mask2Former), none of them retrained. Input is the whole 1024x2048 frame in one forward pass; each model runs its own framework's shipped pre- and postprocessing and is scored by one validator on the 500 val images. TensorRT fp16, batch 1, RTX 5070 Ti. e2e ms includes each framework's CPU pre- and postprocessing; engine ms is pure TensorRT execute. Full table, per-class IoU, protocol and every known asymmetry: cityscapes-benchmark.
| model | params (M) | mIoU | pixel acc | engine ms | e2e ms |
|---|---|---|---|---|---|
| D-FINE-N | 3.36 | 77.99 | 96.03 | 3.02 | 4.21 |
| D-FINE-S | 7.99 | 81.12 | 96.47 | 5.38 | 6.37 |
| D-FINE-M | 15.95 | 81.41 | 96.55 | 7.42 | 8.26 |
| D-FINE-L | 24.97 | 83.80 | 96.93 | 8.98 | 9.77 |
| D-FINE-X | 56.3 | 84.84 | 97.10 | 14.18 | 14.64 |
| YOLO26x-sem | 40.13 | 83.58 | 96.79 | 10.37 | 13.58 |
| EfficientViT-L2 | 52.61 | 83.20 | 96.87 | 9.56 | 19.87 |
| Mask2Former-Swin-L | 215.46 | 83.33 | 96.91 | 64.51 | 94.07 |
| SegFormer-B5 | 84.61 | 81.41 | 96.62 | 38.81 | 42.12 |
- D-FINE-X vs Mask2Former-Swin-L (the most accurate Mask2Former checkpoint): +1.51 mIoU, 4.5x lower engine latency, 6.4x lower end-to-end latency, about a quarter of the parameters. X has the highest mIoU and pixel accuracy of the 28 models.
- D-FINE-L vs YOLO26x-sem (the most accurate YOLO26-sem checkpoint): +0.22 mIoU, +0.14 pixel acc, 13% lower engine latency, 28% lower end-to-end latency, 38% fewer parameters. One training seed and a small margin, so read it as "matches or beats".
Cityscapes - vs YOLO26 and RF-DETR (fine-tuning)
500 Cityscapes val images at original 2048x1024, TensorRT 10.13 FP16, batch 1, RTX 5070 Ti - same protocol and latency columns as above, with confidence thresholds tuned per framework to maximize F1. Full protocol: cityscapes-benchmark.
Detection
| model | params (M) | input | conf | F1 | precision | recall | IoU | e2e ms | engine ms |
|---|---|---|---|---|---|---|---|---|---|
| D-FINE-seg S | 10.29 | 640x640 | 0.5 | 0.703 | 0.817 | 0.617 | 0.446 | 2.0 | 1.38 |
| YOLO26-M | 21.79 | 640x640 | 0.25 | 0.691 | 0.792 | 0.613 | 0.432 | 3.03 | 1.59 |
| RF-DETR-medium | 33.39 | 576x576 | 0.35 | 0.673 | 0.769 | 0.599 | 0.409 | 10.2 | 1.45 |
Instance segmentation
| model | params (M) | input | conf | F1 | precision | recall | IoU | e2e ms | engine ms |
|---|---|---|---|---|---|---|---|---|---|
| D-FINE-seg S | 11.87 | 640x640 | 0.5 | 0.661 | 0.748 | 0.592 | 0.375 | 3.09 | 1.9 |
| YOLO26-M | 26.98 | 640x640 | 0.25 | 0.599 | 0.688 | 0.53 | 0.312 | 5.32 | 2.05 |
| RF-DETR-seg-medium | 35.4 | 432x432 | 0.35 | 0.62 | 0.789 | 0.51 | 0.346 | 16.81 | 1.77 |
The 640 semantic segmentation comparison is superseded by the native-resolution results above. Metric definitions, the VisDrone and TACO benchmarks, COCO-style APs and the export-format comparisons: docs/benchmarks.md
Outputs
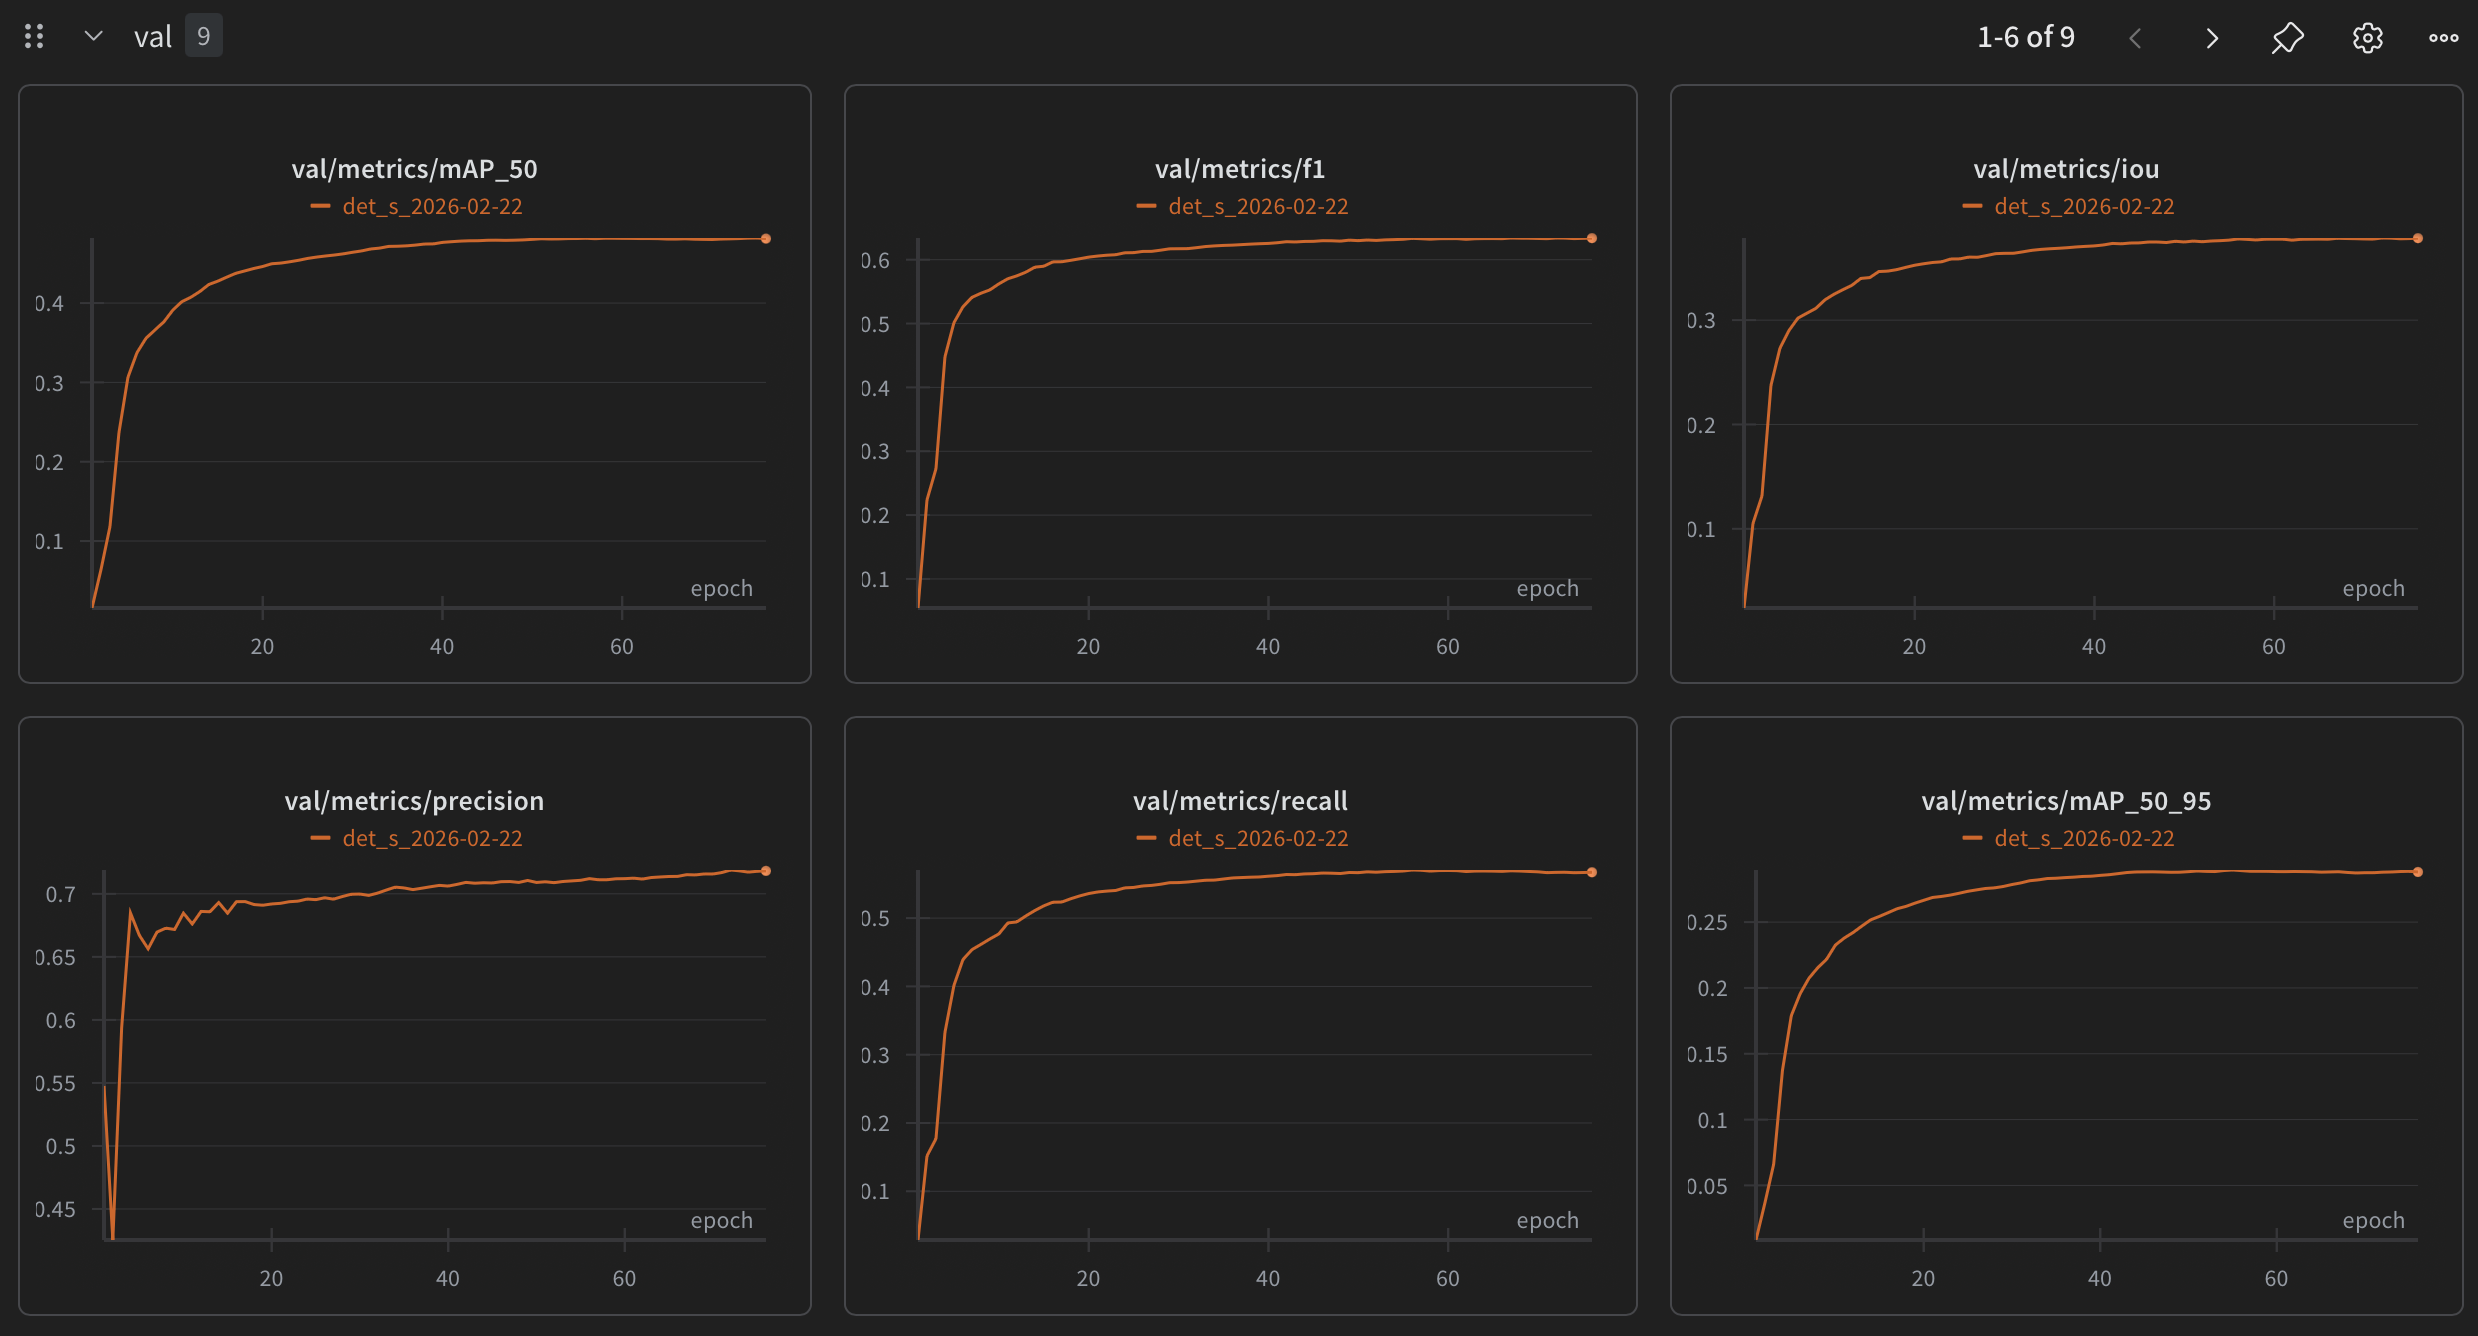
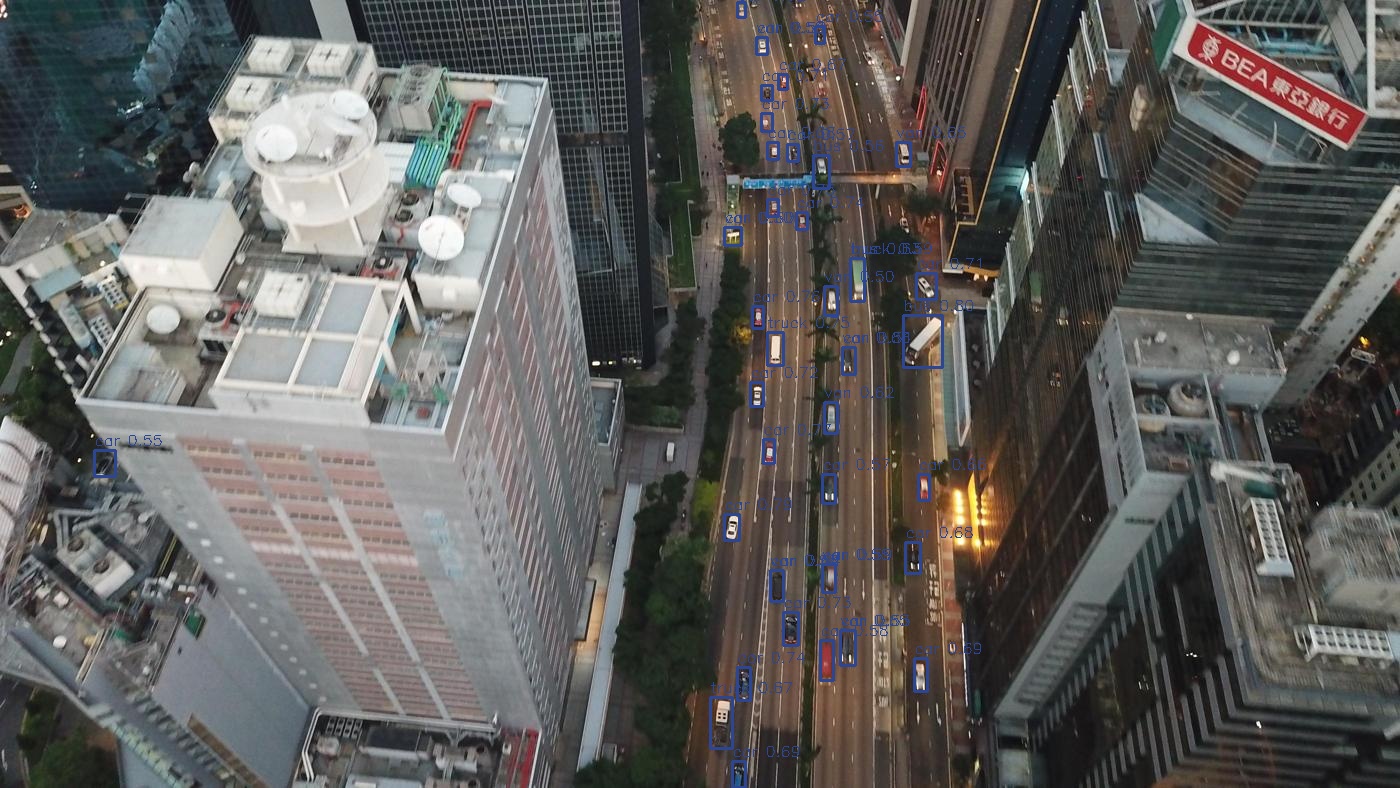
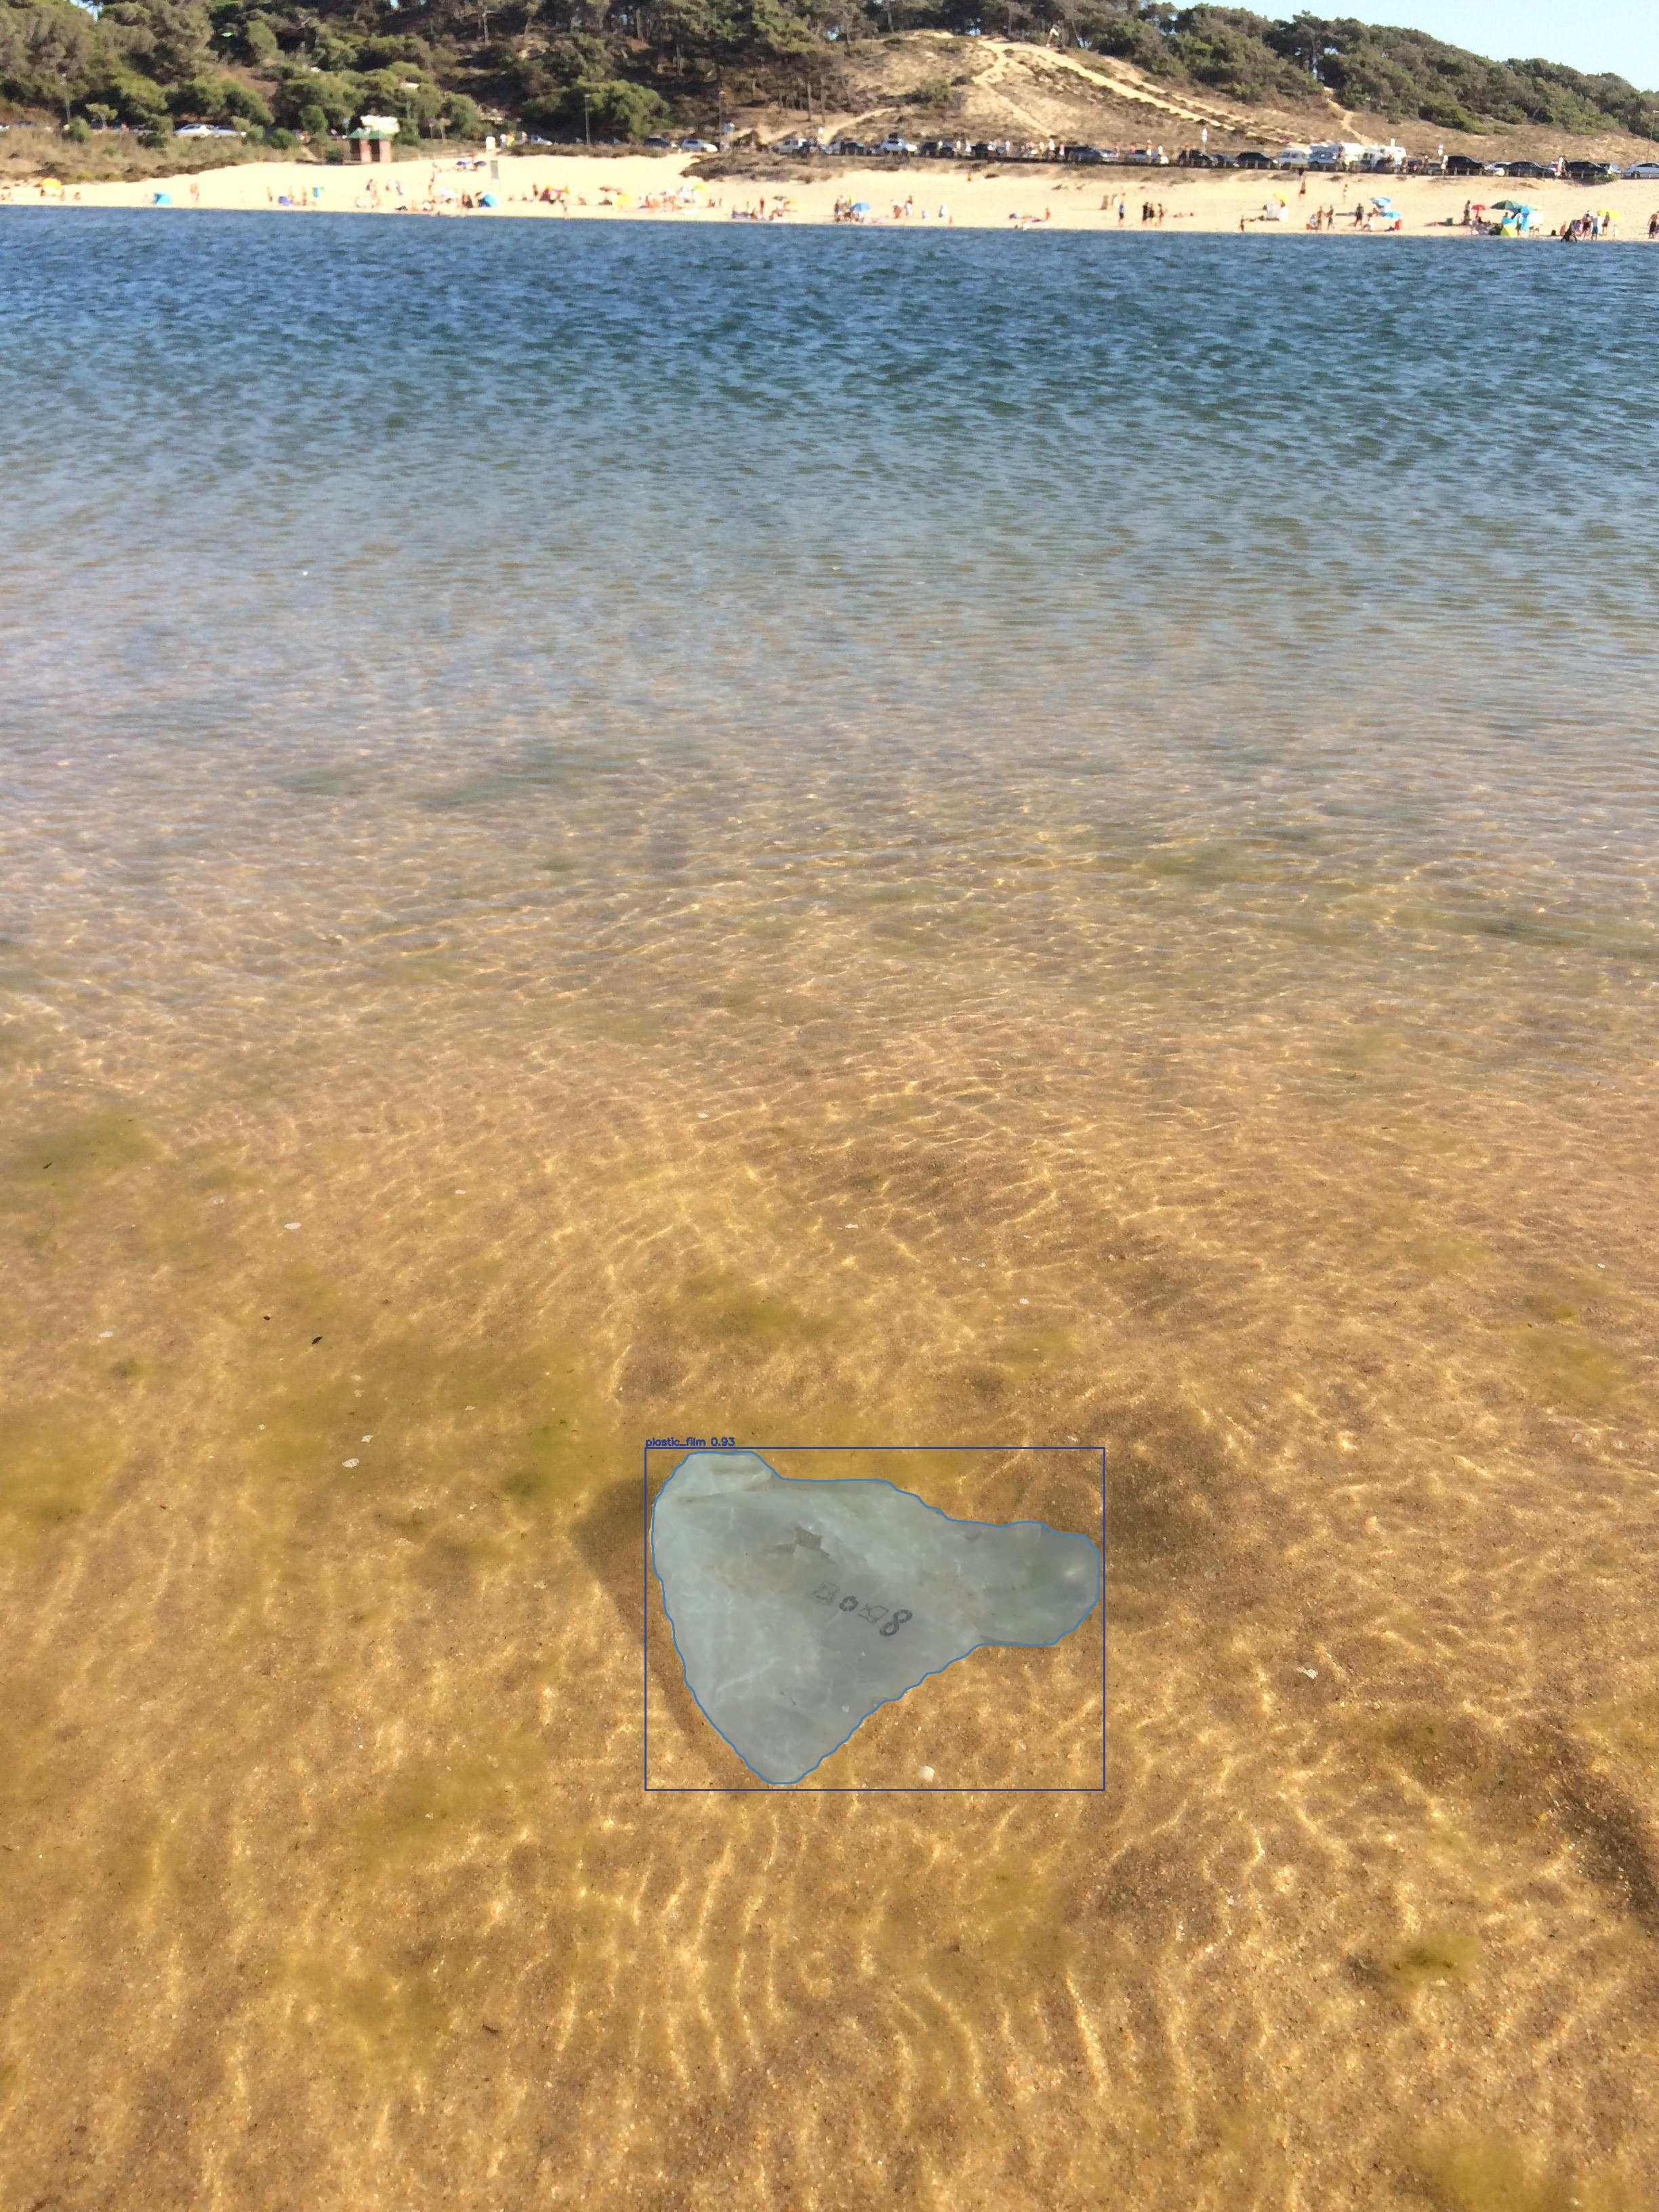
| Output | Location | Description |
|---|---|---|
| Models + logs | output/models/{exp_name}_{date}/ |
Weights, training metrics, confusion matrix, F1 vs threshold plots, per-class metrics, bench metrics, calculated optimal threshold |
| Debug images | output/debug_images/ |
Preprocessed training images (with augmentations) |
| Eval predictions | output/eval_preds/ |
Val set predictions with GT (green) and preds (blue) |
| Bench images | output/bench_imgs/ |
Predictions from all exported models |
| Infer | output/infer/ |
Visualizations + YOLO txt annotations (sem_seg: overlays + PNG label maps) |
| Check errors | output/check_errors/ |
FP and FN only - for finding mislabeled samples |
Result examples
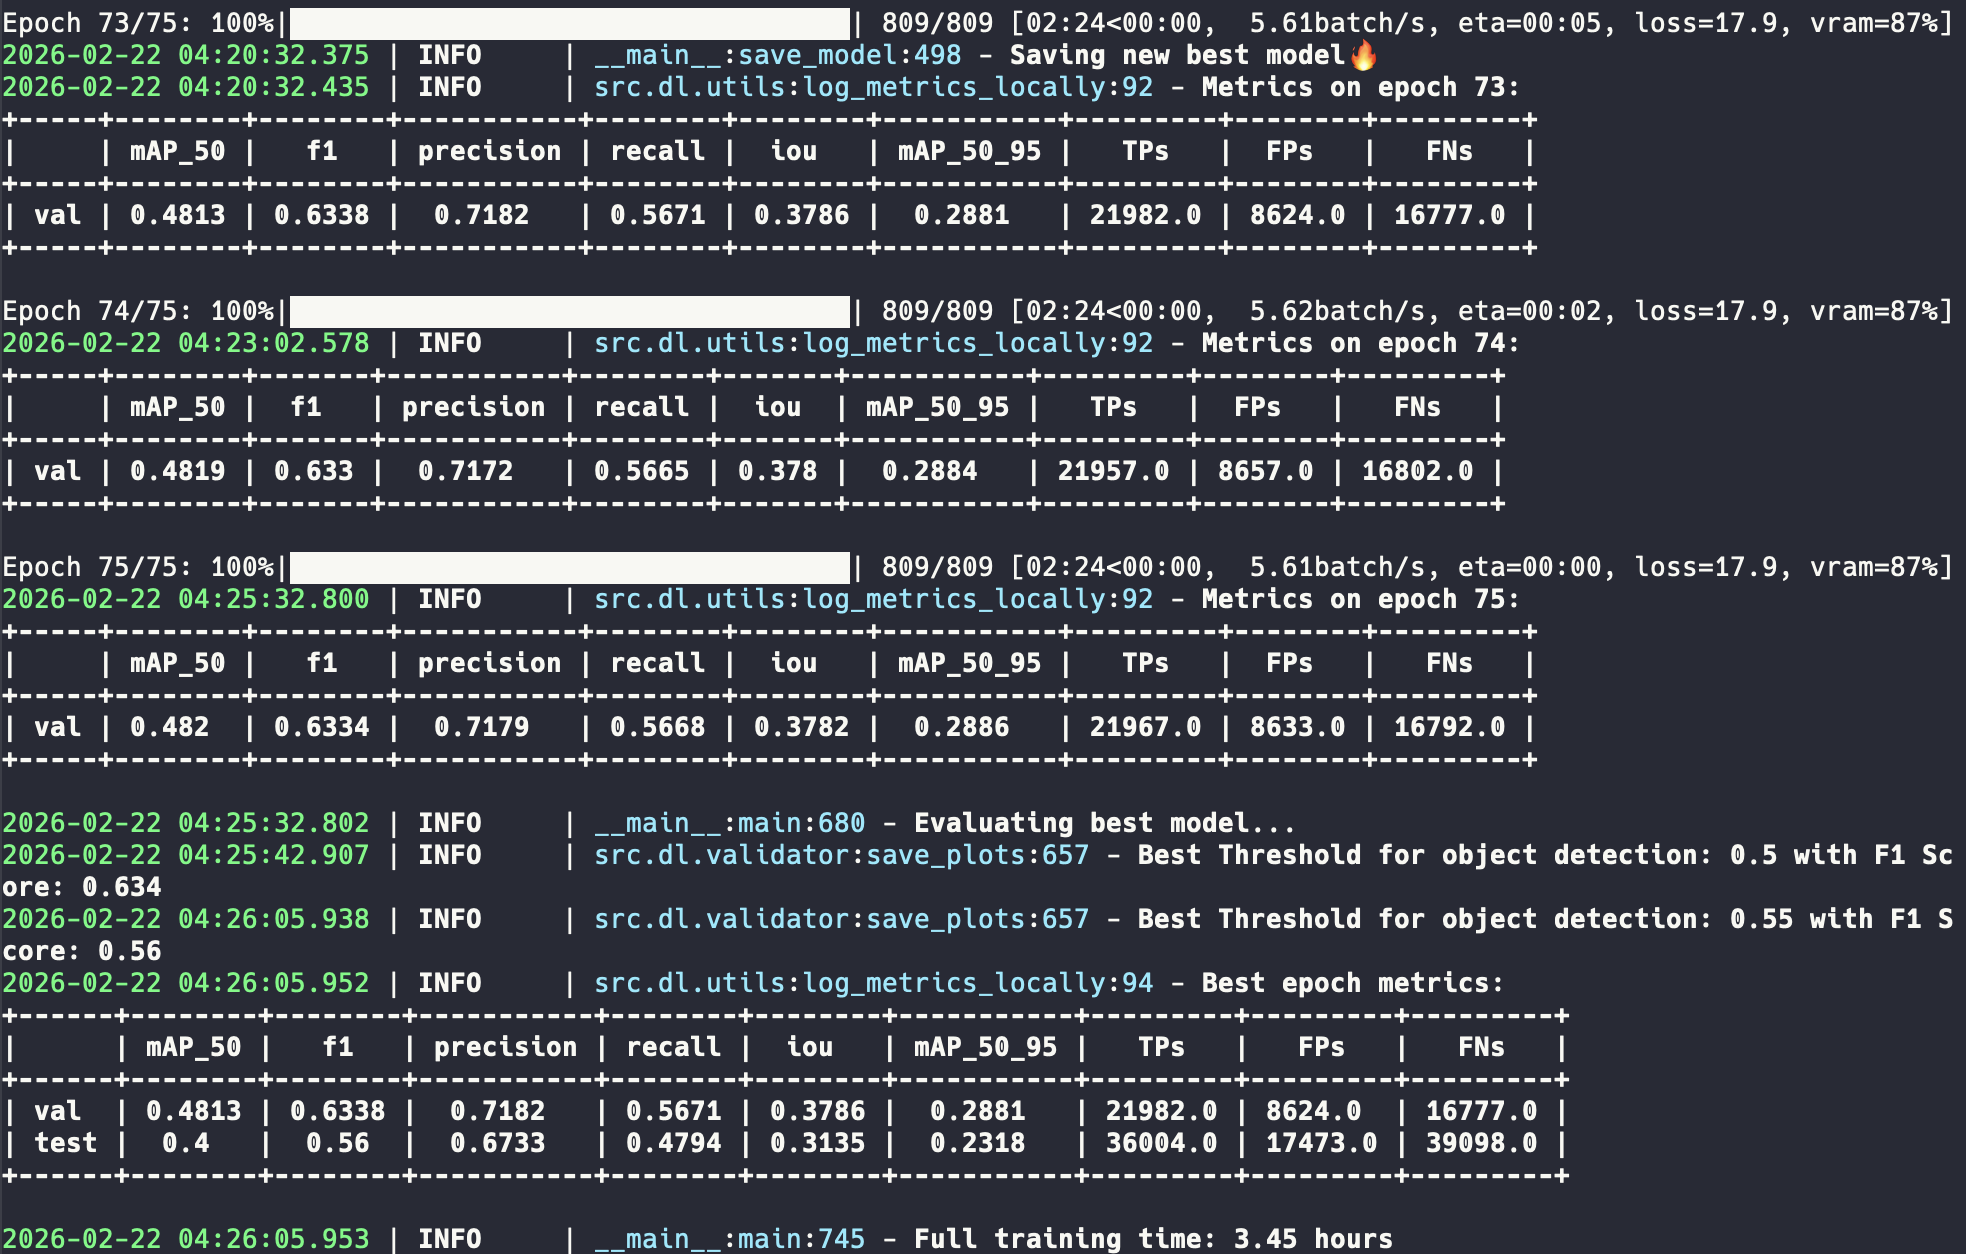
Training
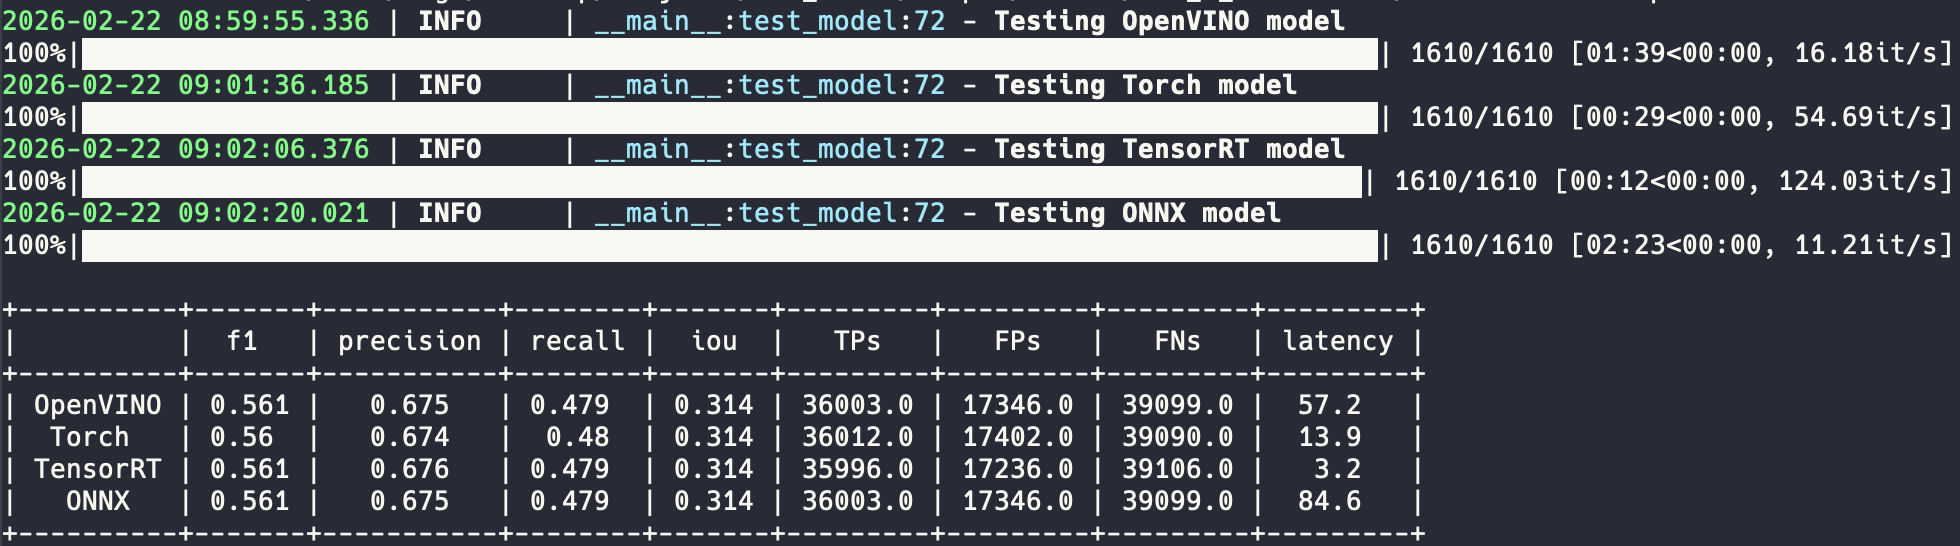
Benchmarking
WandB dashboard
Inference
Citation
If you use D-FINE-seg in your research, please cite:
@article{saakyan2026dfineseg,
  title={D-FINE-seg: Object Detection and Instance Segmentation Framework with multi-backend deployment},
  author={Saakyan Argo and Solntsev Dmitry},
  eprint={2602.23043},
  journal={arXiv preprint arXiv:2602.23043},
  year={2026}
}
And the original D-FINE paper:
@misc{peng2024dfine,
      title={D-FINE: Redefine Regression Task in DETRs as Fine-grained Distribution Refinement},
      author={Yansong Peng and Hebei Li and Peixi Wu and Yueyi Zhang and Xiaoyan Sun and Feng Wu},
      year={2024},
      eprint={2410.13842},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}
If you use the Cityscapes-trained semantic-segmentation weights, also cite the Cityscapes dataset:
@inproceedings{Cordts2016Cityscapes,
  title={The Cityscapes Dataset for Semantic Urban Scene Understanding},
  author={Cordts, Marius and Omran, Mohamed and Ramos, Sebastian and Rehfeld, Timo and Enzweiler, Markus and Benenson, Rodrigo and Franke, Uwe and Roth, Stefan and Schiele, Bernt},
  booktitle={Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR)},
  year={2016}
}
License
The code is licensed under the Apache 2.0 License.
The released Cityscapes semantic-segmentation weights (dfine_sem_{n,s,m,l,x}_cityscapes.pt) are derivative works of the Cityscapes dataset and inherit its terms of use: they may be distributed for non-commercial purposes such as academic research, teaching, scientific publications, or personal experimentation, but not for commercial gain. Train on your own data and the resulting model is yours to ship commercially - the code stays Apache-2.0 (no AGPL).
Acknowledgement
The detection core is based on the D-FINE paper and architecture. The mask head design follows the Mask DINO paradigm. Thank you to both teams for their excellent work.
Benchmarks in this project use the Cityscapes, VisDrone and TACO datasets. We thank the authors for making these datasets publicly available.
1 maintainer

Metadata
1 maintainer
Release files for dfine-seg 0.6.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| dfine_seg-0.6.1.tar.gz | 819.4 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| dfine_seg-0.6.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.1 MB
Release files / dfine_seg-0.6.1.tar.gz
| Download URL | dfine_seg-0.6.1.tar.gz |
|---|---|
| Size | 819.4 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
a28695a9d3347342673048d009c3a531e2dcb338c09542baab5b69599d6f56dd
|
|
BLAKE2b-256 checksum How to use checksums |
4031d0682e27941fea740634c6e949b23fc094d6f8e94928fec831fafc37d6f6
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 16, 2026.
Transparency logRelease files / dfine_seg-0.6.1-py3-none-any.whl
| Download URL | dfine_seg-0.6.1-py3-none-any.whl |
|---|---|
| Size | 272.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
8a5c492696ba1f5c5c6a369fe1f4778104e06f3da66b2246984a18a08cf35144
|
|
BLAKE2b-256 checksum How to use checksums |
63a87363949bfea0fe9b97906146e098eaad6c277e2f381449f2978b81ca6a08
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 16, 2026.
Transparency log













