
⚡ Diceo
Document in, chunks out.

Fast, accurate, free — pick two. The quick parsers hand your embedder a wall of flat text. The accurate ones take days to get through a corpus. The ones that do both charge per page and want your documents on their servers.
Diceo is 11 MB and gives you all three. One function call, and what comes back is chunks shaped for retrieval rather than a wall of text.
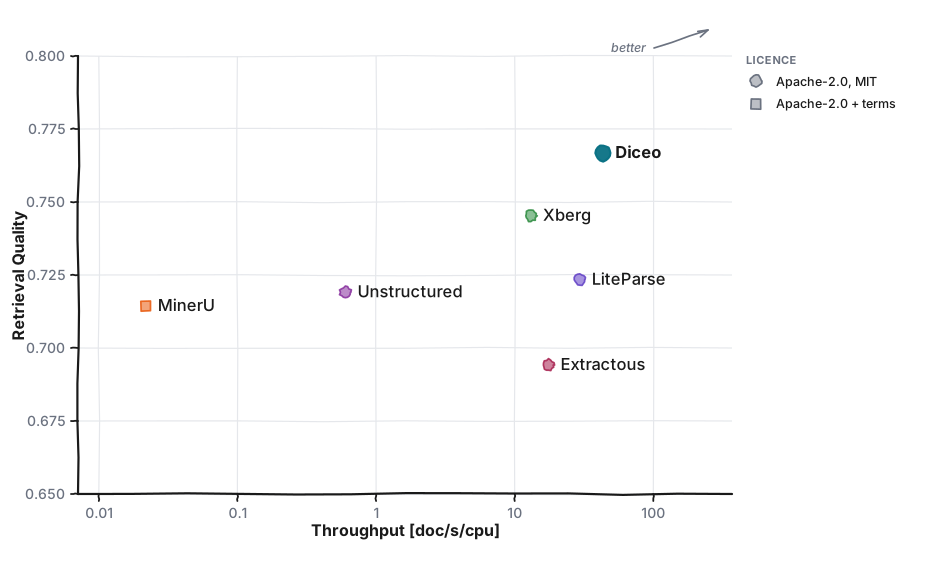
44 held-out PDFs, 776 queries, three chunk sizes. Updated 2026-09-30; comparison CPU costs are carried measurements. Full results · Methodology.
- 🔥 Near the top on speed and retrieval — content-aware chunks, without model inference.
- 🌊 PDF, DOCX, XLSX, CSV and text stream — chunks arrive as the file is read, with bounded PDF windows and incremental table packing.
- 🪶 11 MB installed, two dependencies, 20 ms to import. No GPU, model download or server. It runs in your own process; URL fetching happens only when you pass a URL.
- 📚 Eleven formats, one call, free for commercial use — pdf, docx, xlsx, pptx, xls, xlsb, ods, csv, html, eml, text.
📄 How it works
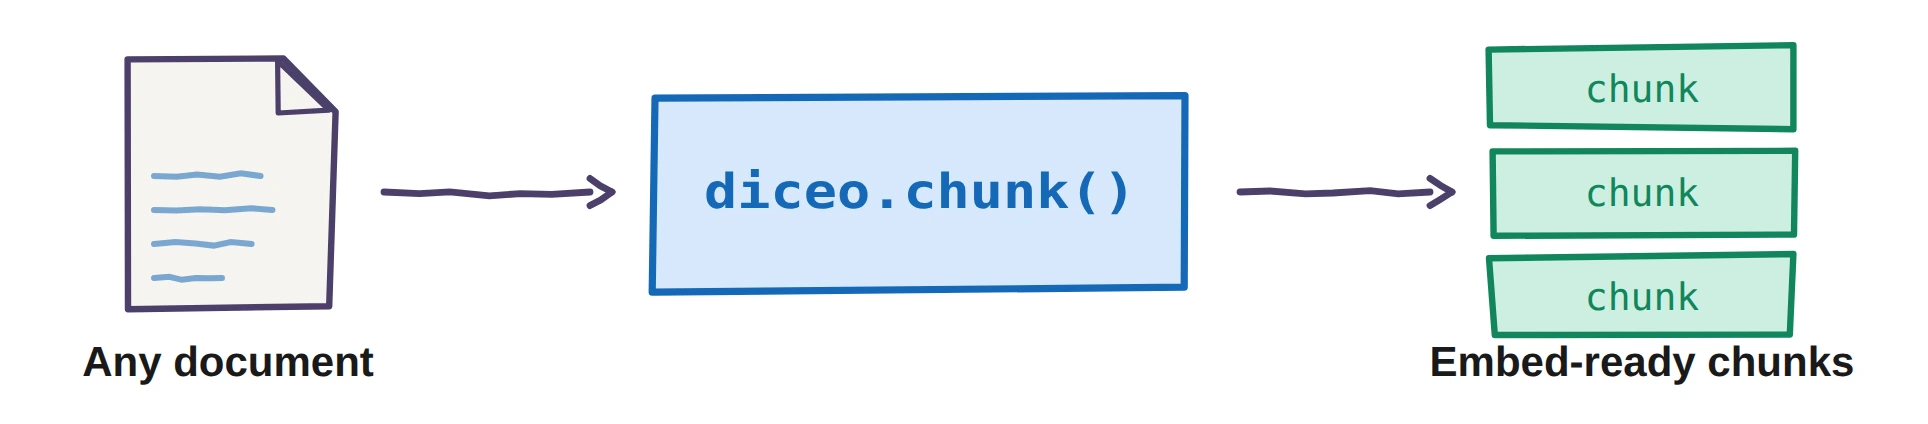
Readers yield blocks straight to the chunker, without an intermediate markdown document or document object. URL downloads spill to disk as needed before extraction.
📦 Install
pip install diceo
Both dependencies ship prebuilt wheels for Linux (glibc and musl), macOS and Windows, on x86-64 and arm64. Nothing compiles at install time.
🚀 Quickstart
>>> import diceo
>>> chunk = next(diceo.chunk("report.docx"))
>>> print(chunk.embed_text)
Quarterly results
Revenue rose to 1200 million in EMEA.
Costs were flat.
>>> chunk.meta
{'index': 0, 'doc_id': 'report', 'title': 'Quarterly results',
 'kinds': ['heading', 'paragraph'], 'char_start': 0, 'char_end': 72}
That is the whole product: embed_text goes to your embedding model, meta to your vector store.
chunk() is a generator — a 1,000-page report starts yielding immediately and never exists in
memory whole. It takes an HTTP(S) URL, a path, bytes, or a seekable binary file, and detects
the format from content:
diceo.chunk("report.pdf")                          # a path
diceo.chunk(response.content, name="report.pdf")   # bytes
diceo.chunk("https://dlmf.nist.gov/1.11")           # URL → clean HTML retrieval chunks
URLs use the same readers and include source_url in metadata. Downloads are bounded by
Limits(download_timeout=..., max_download_bytes=...); JavaScript is not executed.
There is a CLI too:
diceo report.pdf                 # chunks as JSON lines
diceo slides.pptx --diagnostics  # what would be missing from your index
diceo https://dlmf.nist.gov/1.11 --text
🐍 The library
Local, not a service: no server and nothing uploaded. Seven names to learn, plus the
exceptions below, and chunk is the only one most people need.
| name | what it gives you |
|---|---|
chunk(source, **opts) |
the chunks, as a generator |
extract(source, **opts) |
the blocks, before they are packed into chunks |
to_text(blocks) |
those blocks as markdown-ish text, for your own chunker |
sniff(source) |
the format it detects — "pdf", "xlsx", … |
Diagnostics() |
what got left out; hand one in, read it after |
Limits(...) |
the knobs — target_chars, max_pages, max_rows |
FORMATS |
the eleven names it accepts |
Every failure reading a document subclasses DiceoError, so one handler is the whole contract:
try:
    for chunk in diceo.chunk(path):
        index(chunk)
except diceo.DiceoError as exc:
    quarantine(path, exc.reason)
We check that by running it: 930 real documents and 565 deliberately broken ones — truncated,
bit-flipped, zip-bombed — no crash, no hang, nothing raised that was not a DiceoError.
Parallelism is yours: cheap import, picklable chunks, no hidden thread pool. Use processes, not threads, for PDFs — PDFium is not thread-safe. Diceo refuses zip bombs before inflating them, but it is a parser, not a sandbox: isolate untrusted input in a worker with limits (SECURITY.md). Chunk boundaries depend on Diceo and its backend versions — record both and plan to re-embed on upgrade until 1.0.
🔦 It tells you what it could not read
With most tools, a scanned PDF or an image-only deck just yields nothing — the document is silently absent from your index. Diceo hands it back as data:
report = diceo.Diagnostics()
chunks = list(diceo.chunk("scanned.pdf", diagnostics=report))

if report.needs_ocr:      # image-dominated pages that yielded almost nothing
    route_to_ocr(path)
if report.lost_data:      # a limit bit, a part was unreadable, an attachment stayed closed
    log.warning(report.as_dict())
Not an OCR. A page with no text layer is flagged, never reconstructed, and no bundled engine or system binary is called — the output does not depend on what happens to be installed on the box.
🙏 Credits
The two dependencies do the heavy lifting, and both are permissively licensed — which is the only reason a wheel this small can read these formats at all.
- pypdfium2, binding Google's PDFium — the engine Chrome renders PDFs with. Two thirds of the cost of reading a PDF here is PDFium's C++, not ours.
- python-calamine, binding Rust's calamine — the native legacy XLS/XLSB/ODS reader. Its row iterator avoids a second full Python grid; XLSX streaming uses Diceo's own XML reader.
Three more permissively-licensed projects were read closely enough that a design idea here traces to them. Diceo contains no code from any of them — nothing copied, ported or adapted, and no copyleft source consulted at any point. CREDITS.md is the longer version.
- Unstructured — deciding that a line is a label from its shape rather than from a list of English words.
- LiteParse — joining wrapped table header lines by walking back from the body, and emitting a tabular region verbatim when its columns will not resolve.
- Xberg — whether the previous line ended in sentence-final punctuation separates a wrapped continuation from a real heading.
Closest published support for the thesis: arXiv 2603.06976 (paragraph-group chunking nearly doubles nDCG@5 over fixed-size) and arXiv 2602.16974 (simple structure-based chunking beats LLM-guided).
☕ Support
Starring the repo, opening an issue when Diceo mishandles a document, or telling someone it exists all help. If it saves you real time: buy me a coffee ☕ — a donation, no tiers, no perks.
Contributions welcome: CONTRIBUTING.md, and docs/principles.md holds the five rules that settle arguments here.
Track fixes, performance checks and follow-up work on the project board.
1 maintainer

Metadata
1 maintainer
Release files for diceo 0.1.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| diceo-0.1.1.tar.gz | 385.2 kB | With provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| diceo-0.1.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 590.8 kB
Release files / diceo-0.1.1.tar.gz
| Download URL | diceo-0.1.1.tar.gz |
|---|---|
| Size | 385.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
30482e3de077d1e072f28bbe859cbe9e668d3b08d2202b479a1cb6560aa8ca51
|
|
BLAKE2b-256 checksum How to use checksums |
753edb34354e6c630784d5ae995bcf8e4b88b539c4cd1e702f3220e5636f1940
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 30, 2026.
Transparency logRelease files / diceo-0.1.1-py3-none-any.whl
| Download URL | diceo-0.1.1-py3-none-any.whl |
|---|---|
| Size | 205.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
9e17ec2f4e23d725ca487202e0e31a439857ba2117170c753d25f96bc10da79e
|
|
BLAKE2b-256 checksum How to use checksums |
67f33f8359481429655f0f20829f6b4639d4dc6183175fc3d75ed18482d01656
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 30, 2026.
Transparency logSecurity for diceo 0.1.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for diceo-0.1.1.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 30, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.














