
Django Explain Errors Middleware
When debug mode is on, this Django middleware sends each unhandled exception to a language model and shows its explanation of what went wrong and how to fix it on Django's debug page, directly under the exception headline. The explanation is also printed to stdout. The middleware works with the OpenAI API out of the box, with Anthropic's Claude models through Anthropic's OpenAI-compatible endpoint, and with any other OpenAI-compatible endpoint (Ollama, LM Studio, Azure, or a corporate gateway) by setting a base URL, so explanations can run entirely on a local model if you prefer not to send code off your machine.
Enabling RAG is strongly recommended. With it, the middleware retrieves the relevant parts of your own project source from a local vector index, so explanations name the actual file and function that failed instead of guessing. In the package's eval harness, RAG-grounded explanations won 35 of 43 blind comparisons, with the gap concentrated in pointing at the right fix location and not inventing details (see "Does RAG actually help?" below). It is off by default because it needs an optional extra and a one-time index build.
The middleware supports both synchronous (WSGI) and asynchronous (ASGI) views. It auto-detects the view chain at startup and routes requests through the matching path, so no extra configuration is required for either server type. Tracebacks are sanitized before leaving the process, and API calls are rate limited.
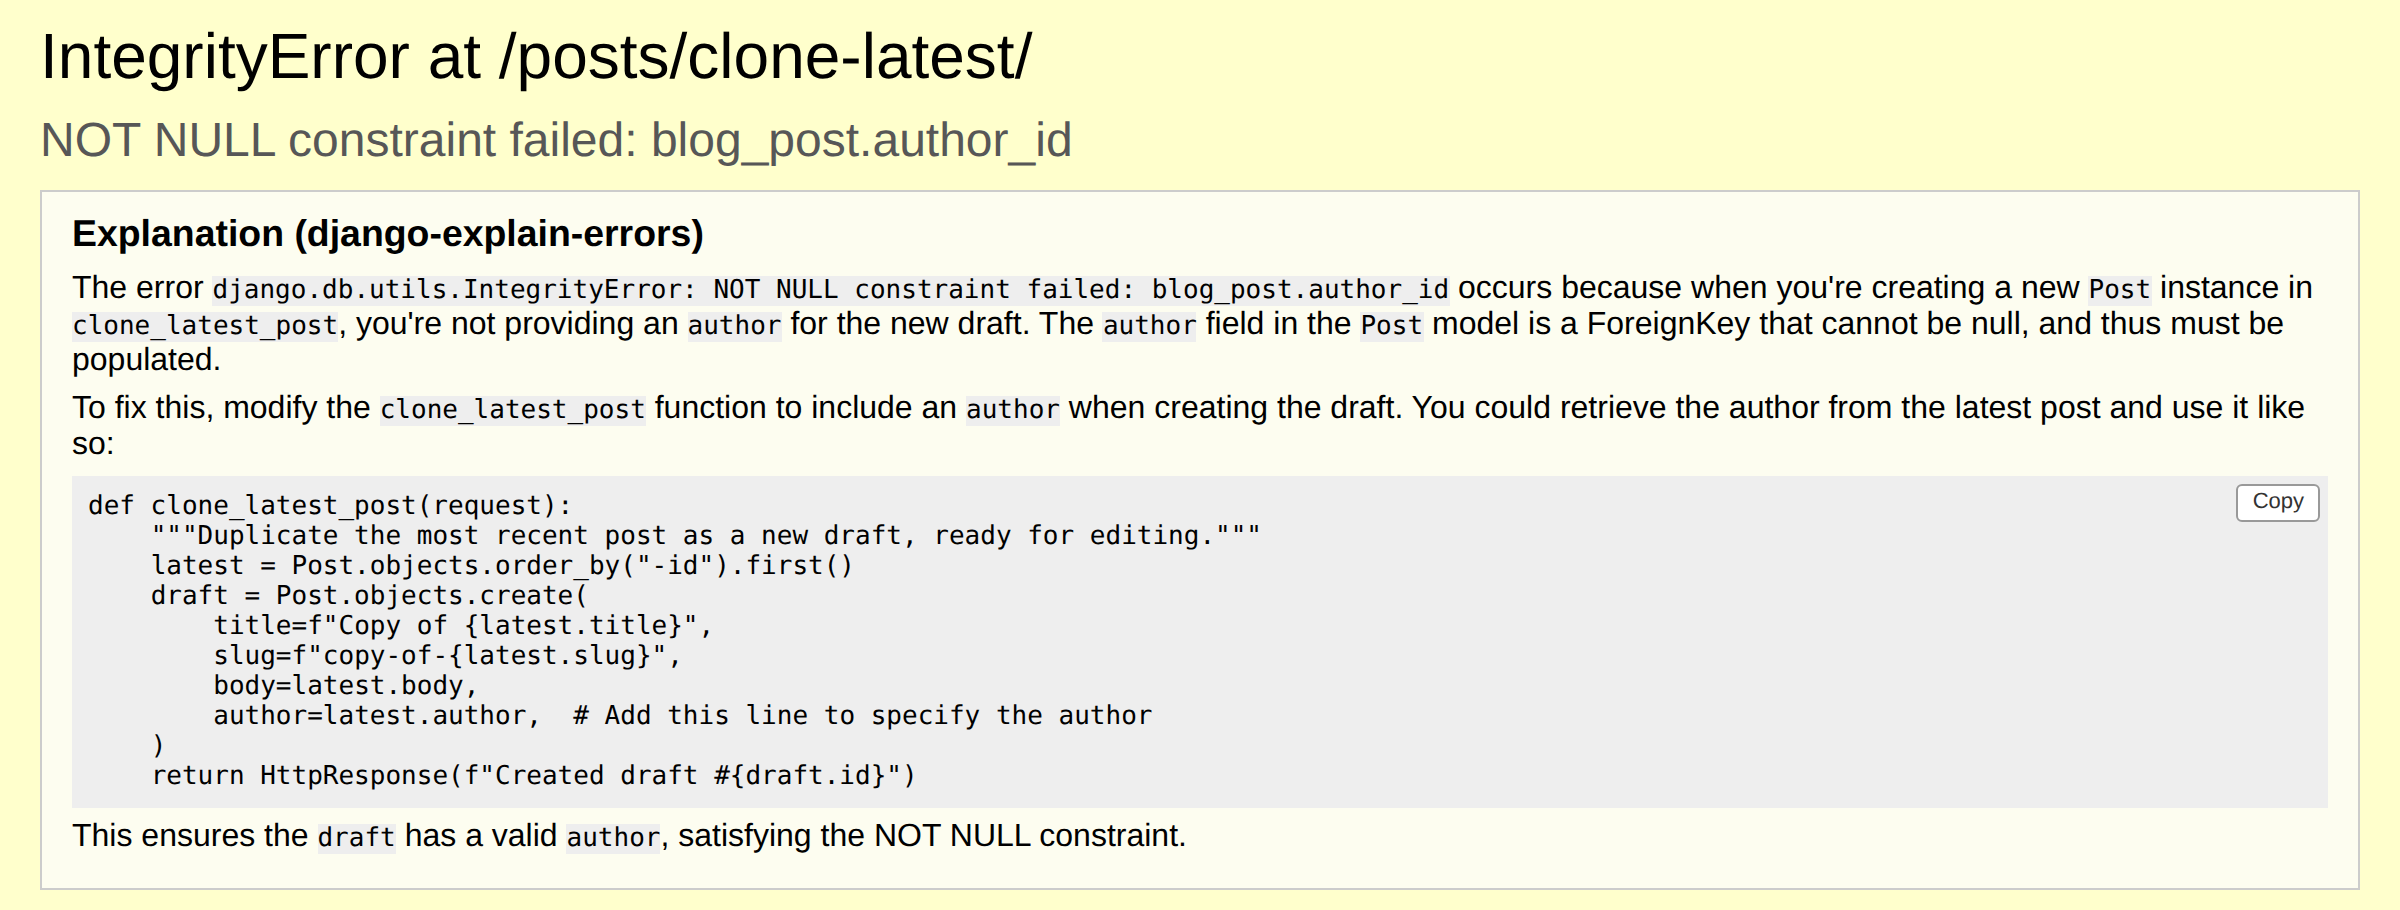
Real gpt-4o-mini output with RAG enabled, recorded by the eval harness
on its missing_fk fixture.
Scope
This package explains errors for a person, not for a coding agent to consume programmatically. The explanation is written for a human reader, on Django's debug page in the browser or in a terminal, and the output format assumes that reader.
If a coding agent is doing the debugging, it does not need this. Agents read tracebacks directly,
and tools that expose live runtime state (debugger-over-MCP servers, mcp-django) serve that case
better. This package is not trying to compete there.
Local development only. It requires DEBUG = True and is inert otherwise.
Features
- Captures Django errors and exceptions
- Shows the explanation on Django's debug page, directly under the
exception headline (
EXPLAIN_ERRORS_INJECT_DEBUG_PAGE, on by default) - Copy button on each code block in the explanation, so a suggested fix copies in one click
- Prints the explanation to stdout, for terminal workflows and logs
(
EXPLAIN_ERRORS_PRINT_STDOUT, on by default) - Optional JSON 500 response instead of the debug page
(
EXPLAIN_ERRORS_PRESERVE_DEBUG_PAGE = False) - Explains errors using OpenAI, Anthropic's Claude models, or any other
OpenAI-compatible endpoint (Ollama, LM Studio, Azure, gateways) via
OPENAI_BASE_URL - Codebase-aware explanations via RAG over a local sqlite-vec index (recommended; see "Codebase-aware explanations" below)
- Explanations in your language via
EXPLAIN_ERRORS_LANGUAGE, with exception names, identifiers, and code kept in English - Redacts secrets, tokens, and emails from tracebacks before sending
- Rate limits API calls with a configurable sliding window
- Works with both sync (WSGI) and async (ASGI) views
- Manages the API key using environment variables
Installation
- Install django-explain-errors by running:
pip install django-explain-errors
-
Add the middleware to your Django project:
-
Open your
settings.pyfile and register the middleware only whenDEBUGis on (see Production Safety below for why):MIDDLEWARE = [ ... ] if DEBUG: MIDDLEWARE.append('explain_errors.middleware.ExplainErrorsMiddleware')
In the default preserve mode,
process_exceptionreturnsNone, so exception handling continues normally no matter where the middleware sits in the list — it no longer needs to be last to avoid pre-empting other packages' error handling. It still needs to sit close enough to the view that unhandled exceptions actually reach it, before any other middleware that might catch and handle them itself. If you setEXPLAIN_ERRORS_PRESERVE_DEBUG_PAGE=False, keep it last: returning a response there still ends exception handling early and pre-empts anything above it in the stack (Debug Toolbar, Sentry, Rollbar — see Compatibility below).
-
-
Set up environment variables:
-
Create a
.envfile in your project's root directory and add your API key. Alternatively, you can set it insettings.py:OPENAI_API_KEY=your_api_key_here
The API key is not required if you set
OPENAI_BASE_URLto a local server such as Ollama, which does not authenticate requests. -
Production Safety
This middleware is intended for local development only. When active, it sends exception tracebacks to the configured LLM provider, which may include source code, file paths, and local variable values. Keep it out of production.
Primary safeguard: register the middleware only when DEBUG is on, or only in your
development settings module:
# settings.py
if DEBUG:
    MIDDLEWARE.append("explain_errors.middleware.ExplainErrorsMiddleware")
See Installation above for where the middleware can sit in MIDDLEWARE.
Secondary safeguard: run Django's deployment checks in CI against your production settings.
This fails the build if DEBUG = True (security.W018):
python manage.py check --deploy --fail-level WARNING
Usage
-
Ensure DEBUG is set to True:
Open your
settings.pyfile and set:DEBUG = True
-
Trigger an error in your Django application:
The middleware captures the error, sends it to the configured model for explanation, prints the explanation to stdout, and adds it as a banner on Django's debug page. By default (
EXPLAIN_ERRORS_PRESERVE_DEBUG_PAGE=True), exception handling then continues normally, so Django (or whatever else is watching, such asrunserver_plusor Sentry, see Compatibility below) renders its usual response. The only change is the banner on Django's own debug page. SetEXPLAIN_ERRORS_INJECT_DEBUG_PAGE = Falseto remove it, orEXPLAIN_ERRORS_PRESERVE_DEBUG_PAGE = Falseto instead get a JSON500response containing the error message and the explanation.In the terminal, the explanation is printed with the model that produced it:
Error explanation (gpt-4o-mini):
 The view raised a ValueError because ...
Async Support
The middleware exposes both sync_capable = True and async_capable = True. At initialization it inspects get_response to decide whether it is part of a sync or async chain:
- Under WSGI (for example
runserverwith sync views), requests flow through the synchronous handler. - Under ASGI (for example with async views), requests are awaited through the async handler. The blocking model API call is offloaded with
asgiref.sync.sync_to_asyncso the event loop is not blocked.
No additional settings are needed. See Installation above for where to place the middleware in MIDDLEWARE.
Debug page injection
When Django renders its debug page for a 500, explain_errors also inserts a banner
containing the explanation directly under the exception headline, in addition to printing
it to stdout.
Controlled by EXPLAIN_ERRORS_INJECT_DEBUG_PAGE, default True. Injection happens only
when all of the following hold:
DEBUGisTrueEXPLAIN_ERRORS_INJECT_DEBUG_PAGEisTrue(the default)EXPLAIN_ERRORS_PRESERVE_DEBUG_PAGEisTrue(the default). WithEXPLAIN_ERRORS_PRESERVE_DEBUG_PAGE=False, the JSON 500 path runs instead and there is no debug page to inject into.- an explanation was actually produced (not throttled, and the API call succeeded)
The banner appears only on the HTML debug page, styled inline (bordered box, light background) so it reads on Django's page. The explanation is HTML-escaped first, then a small Markdown subset (inline code, code blocks, bold, lists) is rendered as HTML. Nothing from the model is ever marked safe.
Each fenced code block gets a "Copy" button that copies the exact code (via
navigator.clipboard on secure contexts such as localhost, or a text-selection fallback
otherwise, for example when runserver is reached by IP over plain HTTP).
Fails open. Any problem building or inserting the banner (a missing request, an unexpected debug page layout, anything else) logs one warning and leaves Django's normal debug page untouched. This code can never turn a working debug page into a broken one.
Custom exception reporters. If your project already sets a custom
DEFAULT_EXCEPTION_REPORTER, or something earlier in the request sets
request.exception_reporter_class, explain_errors leaves it alone and skips injection
(logged at debug level) rather than overriding it.
Upgrading. Turning this on, or upgrading to a version where it defaults on, changes what Django's debug page looks like: a new section appears above the request metadata table. If you rely on the debug page's exact markup (a scraper, a screenshot test), account for this.
Compatibility
How this middleware interacts with other error-handling and debugging tools, in the default
preserve mode and with EXPLAIN_ERRORS_PRESERVE_DEBUG_PAGE=False:
| Package | Preserve mode (default) | EXPLAIN_ERRORS_PRESERVE_DEBUG_PAGE=False |
|---|---|---|
| Django Debug Toolbar | Works — Django renders its debug page (with the explanation banner, unless EXPLAIN_ERRORS_INJECT_DEBUG_PAGE = False), and Debug Toolbar injects into it. |
Broken — the JSON 500 response has no HTML to inject into. |
| Sentry, Rollbar | Work — the exception propagates and Django re-raises it, so got_request_exception fires. |
Broken — returning a response ends exception handling before got_request_exception fires. |
| Django REST Framework | Partial — only exceptions DRF does not already handle itself reach this middleware. | Partial, same reason. |
| Silk and other profiling panels | Timings are inflated by the model API call, since process_exception blocks the request path. |
Same. |
| CORS, GZip, WhiteNoise | No interaction. | No interaction. |
runserver_plus / Werkzeug debugger |
Works — returning None re-raises the original exception, and django-extensions replaces Django's debug-page renderer with one that re-raises instead, so Werkzeug's WSGI wrapper catches it and shows the interactive debugger. |
Broken — the JSON 500 response ends exception handling before it reaches runserver_plus's exception hook, so the Werkzeug debugger never appears. |
Debug Toolbar, Sentry, and Werkzeug were verified empirically, on both Django 4.2 and Django 6.1, in both modes. DRF, Silk, and CORS/GZip/WhiteNoise are reasoned from the mechanism rather than tested.
One additional behavior worth knowing, also verified on both Django versions: when the
explanation call itself fails (a bad key, a timeout, an unreachable endpoint), a
Sentry-instrumented project captures a separate event for that failure. explain_errors
catches the exception internally, so it never becomes an unhandled exception, but Sentry's
httpx integration captures it anyway by instrumenting inside the HTTP client library rather
than relying on got_request_exception. That event is unrelated to whatever error the
developer is actually investigating.
Configuration
| Setting / variable | Required | Description |
|---|---|---|
OPENAI_API_KEY (env or settings) |
Yes, unless OPENAI_BASE_URL points at an endpoint that does not authenticate |
API key used to authenticate with the configured endpoint. Read first from the environment, then from settings. |
DEBUG |
Yes | The middleware is only active when DEBUG=True. When False, requests pass through untouched. |
OPENAI_MODEL |
No | Model used for explanations. Defaults to gpt-4o-mini. |
OPENAI_MAX_TOKENS |
No | Ceiling on tokens generated for the explanation, not a target — the system prompt itself asks for a concise answer. Defaults to 1000; scales up automatically when EXPLAIN_ERRORS_LANGUAGE is set (see below), unless you set this explicitly, which always overrides the scaling. |
OPENAI_TIMEOUT |
No | Request timeout in seconds for model API calls. Defaults to 10. |
OPENAI_MAX_TRACEBACK_CHARS |
No | Total character budget for the traceback sent to the model. Application frames (your own code, as opposed to Django, the standard library, or installed packages) are always kept; library frames fill whatever budget remains, nearest the raise point first, with an ... N library frames omitted ... line where frames are dropped. If the application frames alone exceed the budget, falls back to keeping the last N characters of the raw traceback. Defaults to 3000. |
EXPLAIN_ERRORS_PRESERVE_DEBUG_PAGE |
No | When True (the default), the middleware returns None (after printing the explanation to stdout, unless EXPLAIN_ERRORS_PRINT_STDOUT = False), so exception handling continues normally and Django renders its debug page (with the explanation banner, controlled by EXPLAIN_ERRORS_INJECT_DEBUG_PAGE). Set to False to instead return a JSON 500 response, which ends exception handling early (see Compatibility above). |
EXPLAIN_ERRORS_INJECT_DEBUG_PAGE |
No | When True (the default), also injects the explanation as a banner into Django's debug page, in addition to stdout. Requires EXPLAIN_ERRORS_PRESERVE_DEBUG_PAGE=True (the default); see Debug Page Injection above. |
EXPLAIN_ERRORS_PRINT_STDOUT |
No | When True (the default), prints the explanation to stdout. Set to False to suppress it, for example when EXPLAIN_ERRORS_INJECT_DEBUG_PAGE already shows it in the browser. The failure message (when the model API call itself errors) always prints. For requests where nobody views the debug page (API clients, which get Django's plain-text error response, and fetch/HTMX requests, whose HTML response is never displayed), stdout is the only channel that shows the explanation, so turn this off only in browser-first workflows. |
OPENAI_BASE_URL (env or settings) |
No | Base URL for any OpenAI-compatible API (for example Ollama at http://localhost:11434/v1). When set, a missing API key is replaced with a placeholder since local servers do not require one. |
EXPLAIN_ERRORS_MAX_CALLS |
No | Together with EXPLAIN_ERRORS_WINDOW_SECONDS, caps API spend to at most this many explanations within a rolling window; once the cap is hit, further errors in that window are not sent for explanation until an earlier call ages out. Defaults to 5. |
EXPLAIN_ERRORS_WINDOW_SECONDS |
No | Length in seconds of the rolling window EXPLAIN_ERRORS_MAX_CALLS is measured against. Defaults to 60 (with the defaults, at most 5 explanations per 60-second window). |
EXPLAIN_ERRORS_REDACT_PATTERNS |
No | Extra regex pattern strings (each passed to re.compile) applied to the traceback, appended after the built-in secret/token/email patterns. An invalid pattern is skipped with a warning rather than raising. Defaults to []. |
EXPLAIN_ERRORS_REDACT_DISABLE_DEFAULTS |
No | When True, skips the built-in secret/token/email redaction patterns entirely and redacts only what EXPLAIN_ERRORS_REDACT_PATTERNS specifies. Turning this on removes the default protection against leaking secrets and PII in tracebacks. Defaults to False. |
EXPLAIN_ERRORS_REDACT_REPLACEMENT |
No | Replacement string substituted for anything matched by the redaction patterns. Defaults to "[REDACTED]". |
EXPLAIN_ERRORS_LANGUAGE |
No | Language the explanation prose is written in, as a plain name or code (for example "Spanish" or "es"). Defaults to None, meaning English. Exception names, identifiers, code, file paths, and tracebacks always stay in English regardless of this setting. |
Using local models (Ollama)
Point OPENAI_BASE_URL at any OpenAI-compatible server to run explanations
against a local model instead of the OpenAI API:
OPENAI_BASE_URL = "http://localhost:11434/v1"
OPENAI_MODEL = "llama3.1"
EXPLAIN_ERRORS_RAG_EMBED_MODEL = "nomic-embed-text"
With a local endpoint, no traceback or source code leaves your machine, which matters if you work somewhere that cannot send code to a third-party API.
If you use the RAG layer, rebuild the index after changing the embedding model or provider. Stored vectors are model-specific.
Using Anthropic (Claude) models
Anthropic's Claude models work today through Anthropic's OpenAI-compatible API, with no Anthropic-specific code required:
OPENAI_BASE_URL = "https://api.anthropic.com/v1/"
OPENAI_API_KEY = "your_anthropic_api_key_here"
OPENAI_MODEL = "..."  # see Anthropic's current model list below
OPENAI_MODEL is mandatory here: the default (gpt-4o-mini) doesn't exist on Anthropic's API
and will 404. Use one of the model names from
Anthropic's model overview;
model names are versioned and retired over time, so check that page rather than relying on a
name pinned here.
Anthropic documents this compatibility layer as intended primarily for testing and comparing model capabilities, not as a production integration path. That's an acceptable tradeoff for a development-only middleware, but worth knowing going in.
Reasoning models behind OPENAI_BASE_URL spend part of the token budget on internal reasoning
before producing visible output. At a low OPENAI_MAX_TOKENS, the budget can be used up by
reasoning alone, and the explanation comes back empty. Raise OPENAI_MAX_TOKENS if you see this.
A note on API keys and 401s
explain_errors reads OPENAI_API_KEY (see Configuration above); it does not read
provider-specific variables such as ANTHROPIC_API_KEY. If no key is found and
OPENAI_BASE_URL is set, the client substitutes a placeholder key rather than raising an
error — a convenience for local servers like Ollama or LM Studio, which ignore the key
entirely. Against a real remote endpoint such as Anthropic's, that placeholder is sent as-is
and rejected, so a missing OPENAI_API_KEY shows up as an opaque 401 Unauthorized rather
than a clear configuration error. If you see a 401 with OPENAI_BASE_URL pointed at a remote
provider, check that OPENAI_API_KEY — not a provider-specific variable — is actually set.
Explanation language
By default, explanations are written in English. Set EXPLAIN_ERRORS_LANGUAGE to
read them in another language instead:
EXPLAIN_ERRORS_LANGUAGE = "Spanish" # or the code form, "es"
There is no fixed list of supported languages. EXPLAIN_ERRORS_LANGUAGE accepts
any language the configured model can write, because the setting adds one clause
to the system prompt (see LANGUAGE_CLAUSE_TEMPLATE in
explain_errors/middleware.py), not a translation catalog with its own
maintained language list. How well it works varies by model; see the known
limitation below.
This is independent of Django's own LANGUAGE_CODE, which controls the language your
site serves to its users, not the language you read explanations in. Regardless of
EXPLAIN_ERRORS_LANGUAGE, exception type names, Django and Python identifiers, code,
file paths, and tracebacks are always kept in English, so they stay greppable and
matchable against documentation and search results. Only the explanatory prose is
translated.
Known limitation: small local models behind OPENAI_BASE_URL (see "Using local
models" above) tend to degrade sharply outside English. Output quality with
EXPLAIN_ERRORS_LANGUAGE set does not transfer uniformly across providers — it is
generally solid against OpenAI and Anthropic's APIs, but a small local model that
writes fluent English explanations may produce broken or mixed-language output once
asked to switch languages.
When a language is configured and OPENAI_MAX_TOKENS isn't set explicitly, the
token ceiling defaults to 3,000 instead of 1,000, a flat 3x multiplier applied the
same way regardless of how well or poorly a given language is known to tokenize, so
explanations in languages that use more tokens per word than English aren't cut off
mid-sentence. This is a ceiling, not a target: billing follows tokens actually
generated, so the extra headroom costs nothing if unused. Setting OPENAI_MAX_TOKENS
explicitly always overrides this scaling, at any value, including one lower than the
unscaled 1,000 default. The multiplier itself is deliberately generous rather than
precise: the underlying tokens-per-word figures are estimates, not direct
measurements, and the default model (gpt-4o-mini) uses the o200k_base tokenizer,
which handles non-Latin scripts considerably better than the cl100k_base-era ratios
these estimates lean on.
Codebase-aware explanations (RAG)
By default, explanations are generated from the traceback alone. With the optional RAG (retrieval-augmented generation) layer enabled, the middleware also retrieves the most relevant chunks of your own project's source code from a local vector index and includes them in the prompt, so explanations can reference your actual functions and classes instead of guessing at them.
Recommended for most projects. It is opt-in only because setup takes three steps (install the extra, build the index, enable it), and it adds no dependencies or behavior until you do.
Install the extra
pip install django-explain-errors[rag]
This pulls in sqlite-vec, a single-file, no-server vector store. The core package stays dependency-light if you don't need RAG.
Build the index
Add explain_errors to INSTALLED_APPS (needed for Django to discover the
management command), then run:
python manage.py build_error_index
This walks your project, chunks Python files by top-level function/class (and other text files by fixed-size line windows), embeds each chunk with the configured endpoint's embeddings API, and writes them to a local index file. Re-run it whenever your source changes meaningfully. Indexing is not automatic. Rebuilding is idempotent: it builds into a temp file and atomically replaces the previous index.
Enable it
# settings.py

EXPLAIN_ERRORS_RAG_ENABLED = True
Settings
| Setting | Default | Description |
|---|---|---|
EXPLAIN_ERRORS_RAG_ENABLED |
False |
Master switch for the RAG layer. |
EXPLAIN_ERRORS_RAG_INDEX_PATH |
<BASE_DIR>/.explain_errors_index.db |
Path to the local vector index file. |
EXPLAIN_ERRORS_RAG_TOP_K |
4 |
Number of chunks retrieved and injected into the prompt. |
EXPLAIN_ERRORS_RAG_EMBED_MODEL |
"text-embedding-3-small" |
Embedding model used for indexing and retrieval. Must exist on the configured endpoint. |
EXPLAIN_ERRORS_RAG_INCLUDE |
None (defaults to BASE_DIR) |
List of directories to index. |
EXPLAIN_ERRORS_RAG_EXCLUDE |
migrations, venvs, node_modules, static, media, .git |
Directory names to skip while indexing. |
EXPLAIN_ERRORS_RAG_MAX_PROMPT_CHARS |
6000 |
Combined character budget for the traceback + retrieved source sections of the prompt. |
Every chunk of source code and every retrieval query is passed through the
same sanitize_traceback() redaction used for tracebacks, which strips
patterns that look like secrets, tokens, and emails before anything is sent to the model API or written to the index. It's a pattern-based filter, not a
guarantee: it catches recognizable secret shapes, not arbitrary sensitive
data that doesn't match one.
If RAG is enabled but the index is missing, sqlite-vec isn't installed, or
retrieval fails for any reason, the middleware logs a warning and falls back
to the traceback-only prompt. It never breaks error reporting.
RAG-grounded explanations tend to be longer than traceback-only ones. The default OPENAI_MAX_TOKENS already leaves generous headroom for this, but if you've lowered it, raise it back up when RAG is enabled so explanations are not truncated.
.gitignore
The index file is a local build artifact, not something to commit. Add it
to your project's .gitignore:
.explain_errors_index.db
(Adjust the path if you set EXPLAIN_ERRORS_RAG_INDEX_PATH to something
else.)
Before / after
A real result from the eval harness (missing_fk, one of the fixtures in
evals/fixtures.py): a view creates a new Post without setting the
required author foreign key. The traceback the model actually received
was already truncated to OPENAI_MAX_TRACEBACK_CHARS, so it contains no
application code at all, only Django/SQLite internals:
This example was recorded before 0.7.0, when tracebacks were trimmed to
their last N characters. Since 0.7.0 your application's frames are always
kept, so a traceback-only explanation would now see clone_latest_post
too. The measured results in "Does RAG actually help?" below were run
after that change.
...(truncated)...
  File ".../django/db/models/base.py", line 904, in save
    self.save_base(
  ...
  File ".../django/db/backends/utils.py", line 105, in _execute
    return self.cursor.execute(sql, params)
           ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
  File ".../django/db/backends/sqlite3/base.py", line 359, in execute
    return super().execute(query, params)
           ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
django.db.utils.IntegrityError: NOT NULL constraint failed: blog_post.author_id
Without RAG, traceback only:
The error "django.db.utils.IntegrityError: NOT NULL constraint failed: blog_post.author_id" occurs when you attempt to save a model instance but the
author_idfield does not receive a value, even though it requires one (is defined asNOT NULL).This typically indicates that the
authorfield in yourPostmodel (or similar) is mandatory, but you did not provide anauthorwhen creating or updating the post.To fix this:
Ensure that you are assigning a valid user or author instance to the
authorfield before saving thePostmodel. For example:post.author = some_user_instanceIf you intended for
author_idto be optional, adjust the model definition to allow null values by modifying the field:author = models.ForeignKey(User, on_delete=models.CASCADE, null=True)If the migration is necessary (if you did change the model), run:
python manage.py makemigrations
python manage.py migrate
Make sure that every time you save a
Post, it has a valid author assigned.
With RAG, grounded in the actual function:
The error
django.db.utils.IntegrityError: NOT NULL constraint failed: blog_post.author_idoccurs because when you're creating a newPostinstance inclone_latest_post, you're not providing anauthorfor the new draft. Theauthorfield in thePostmodel is a ForeignKey that cannot be null, and thus must be populated.To fix this, modify the
clone_latest_postfunction to include anauthorwhen creating the draft. You could retrieve the author from the latest post and use it like so:def clone_latest_post(request): """Duplicate the most recent post as a new draft, ready for editing.""" latest = Post.objects.order_by("-id").first() draft = Post.objects.create( title=f"Copy of {latest.title}", slug=f"copy-of-{latest.slug}", body=latest.body, author=latest.author, # Add this line to specify the author ) return HttpResponse(f"Created draft #{draft.id}")This ensures the
drafthas a validauthor, satisfying the NOT NULL constraint.
Does RAG actually help?
To check whether RAG-grounded explanations are actually better, not just
longer, the package ships an eval harness (evals/): fifteen deliberately
broken Django views, each explained twice (once from the traceback alone,
once with RAG enabled) and judged by a separate model, blind to which
explanation is which, against the error's known cause and correct fix
location. Which side the judge sees as "A" is randomized per comparison so
position can't bias the result.
Across three runs (45 judged comparisons, 2 judge failures, 43 scored),
RAG-on won 35, RAG-off 5, and 3 tied. The gap isn't spread evenly across
everything the judge checks. It's concentrated in whether the explanation
names the right file and function, and whether it invents details along
the way: on points_to_fix_location, RAG-on answered yes in 26 of the
group-A comparisons against RAG-off's 13; on no_fabrication, 26 against
17. Without source access, gpt-4o-mini tends to invent a
plausible-sounding function name or parameter rather than say it doesn't
know; given the actual code via RAG, it mostly does not.
Three limitations are worth knowing before trusting this uncritically: RAG
can anchor on the wrong retrieved chunk, as it did in one fixture
(missing_post_key) where the fix got redirected to a retrieved template
instead of the view; the judge is shown the failing function's own
source, which is the same source RAG-on's retriever draws from, so part
of RAG-on's no_fabrication advantage may be judge and generator
overlapping on material RAG-off never sees rather than RAG-on being more
careful; and claim statuses are spot-checked, not exhaustively audited --
a script that flagged 14 of 363 claims on one run, all correct on manual
inspection, is a sample that turned up no false positive, not a proof
that none exists. Full per-fixture results, the judge prompt, and how to
reproduce this (about $1.37 for a --runs 3 pass, most of it judge cost)
are in evals/README.md.
License
This project is licensed under the MIT License. See the LICENSE file for details.
Contributing
Contributions are welcome! Please open an issue or submit a pull request for any improvements or bug fixes.
Acknowledgements
1 maintainer

Release files for django-explain-errors 0.9.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| django_explain_errors-0.9.0.tar.gz | 69.8 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| django_explain_errors-0.9.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 100.5 kB
Release files / django_explain_errors-0.9.0.tar.gz
| Download URL | django_explain_errors-0.9.0.tar.gz |
|---|---|
| Size | 69.8 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
919b8ad9bd68aff0294e89bc5bb4ac2c209712ed5fd8c3440028076d0bc32767
|
|
BLAKE2b-256 checksum How to use checksums |
e19b703d500447ce5caeaa2039357689a8192a621491fcaac16a31775dd2c54f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 26, 2026.
Transparency logRelease files / django_explain_errors-0.9.0-py3-none-any.whl
| Download URL | django_explain_errors-0.9.0-py3-none-any.whl |
|---|---|
| Size | 30.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
624d3449a092cec4d0a972a46c3730b29c962e1e626e41ce49bbd1b1b7f8e2f7
|
|
BLAKE2b-256 checksum How to use checksums |
e7345351f2f0cd49e5449850ac03778837c029dfccb89bc3aa30bedfe47c9bd8
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 26, 2026.
Transparency log













