
driftfdr
English · Русский
English
Drift monitoring for fleets of ML models without a flood of false alarms
With tens or hundreds of models in production, drift detectors (Page-Hinkley, DDM, ADWIN, KS) at their default thresholds produce a stream of false alarms and needless retrains: every detector has an unknown false-alarm rate, and across many models the false alarms add up. driftfdr turns a detector's signal into a calibrated p-value that accounts for autocorrelation in the data, and decides which models to retrain across the whole fleet at once, at a chosen false-alarm level.
error of model 1 ─► detector ─► bootstrap calibration ─► p-value ─┐
error of model 2 ─► detector ─► bootstrap calibration ─► p-value ─┼─► correction for the number of models ─► retrain?
error of model K ─► detector ─► bootstrap calibration ─► p-value ─┘
Why
On real data — four public data sets (INSECTS, Electricity, Airlines, Covertype; 50 models each, rows in their original order) and hourly exchange rates of five currency pairs — the share of false retrains among all alarms:
| data | river Page-Hinkley, defaults | driftfdr |
|---|---|---|
| INSECTS | 50% | 0% |
| Electricity | 56% | 0–8% |
| Covertype | 75% | 15% |
| Airlines | 26% | 0–6% (hourly steps) |
| FX rates, 40 volatility models, 2010–2026 | no alarms at all, no degradation caught | 0–10%, 63–100% of degradations above 30% caught |
On a fixed suite of 100 synthetic scenarios the best driftfdr configuration reaches a detection F1 of 0.88, river's Page-Hinkley at its defaults 0.06: it catches every drift, but 97% of its alarms are false (experiment 21).
Evidently's standard drift test on the error series alarms in 20–78% of windows where the model did not get worse. NannyML's performance monitoring is about as accurate as driftfdr, but its ±3σ threshold is fixed and ignores the number of models; in driftfdr the false-alarm level, the correction for fleet size and the tolerated degradation are explicit. Monitoring is as fast as the river detector itself (about 1 µs per step per model); calibration takes a fraction of a second per model after each retrain (experiment 19). Details and all 24 experiments are in docs/experiments.md.
Installation
pip install driftfdr                 # numpy, scipy, pandas, matplotlib
pip install "driftfdr[prometheus]"   # + an integration: prometheus, mlflow or nannyml
From a clone of the repository: pip install -e ".[dev]" (tests) or pip install -e ".[datasets]"
(river and scikit-learn for the real data sets used in the experiments).
Quick start
At every step the monitor takes the error (or loss) of each model and returns the models that should be retrained:
from driftfdr import CalibrationConfig, MeanShift, StreamingMonitor

monitor = StreamingMonitor(
    model_ids=["pricing", "eta", "demand"],
    detector_factory=lambda: MeanShift(3),     # alarm only if the degradation lasts 3 windows
    procedure="bonferroni",                    # correction for the number of models
    alpha=0.05,                                # false-alarm rate per window across the fleet
    n_ref=300, window=100, horizon=5,          # in steps; a step can be an hour (see bucket_means)
    calibration=CalibrationConfig(tolerance=0.05),  # retrain if the error rose by > 5 points
)

for errors in stream:                          # e.g. {"pricing": 0.21, "eta": 0.35}
    for model_id in monitor.update(errors):
        retrain(model_id)                      # the monitor starts collecting a new reference itself

monitor.save("monitor.npz")                    # the state survives a service restart
monitor = StreamingMonitor.load("monitor.npz", detector_factory=lambda: MeanShift(3))
- If the models' errors move together (shared data source, shared features), set
split_common=True. The detectors then watch each model's deviation from the fleet median, and the median itself is tested separately: its alarm setsmonitor.fleet_alarm("something shared broke"). Without it a common spike produces a burst of simultaneous false alarms (experiment 18). On all four real data sets the models are strongly correlated, andsplit_commonremoves most of that dependence (experiment 20). In this mode every model must report at every step. - To react without waiting for the end of a window, use
detector_factory=ECUSUMwithsequential=True: every model is checked at every step, with the same false-alarm budget per window (Bonferroni). At the same budget this caught drift 26% faster than the windowed PH (exp. 23); a step costs about 7 µs per model instead of 2. - Models may report irregularly or skip steps: each has its own window clock. Models can be added
and removed on the fly (
add_model,remove_model). - With delayed labels, pass a model's error when its label arrives.
- A detector can be taken from river with its settings:
detector_factory=lambda: from_river(drift.PageHinkley(mode="up")). - Full example:
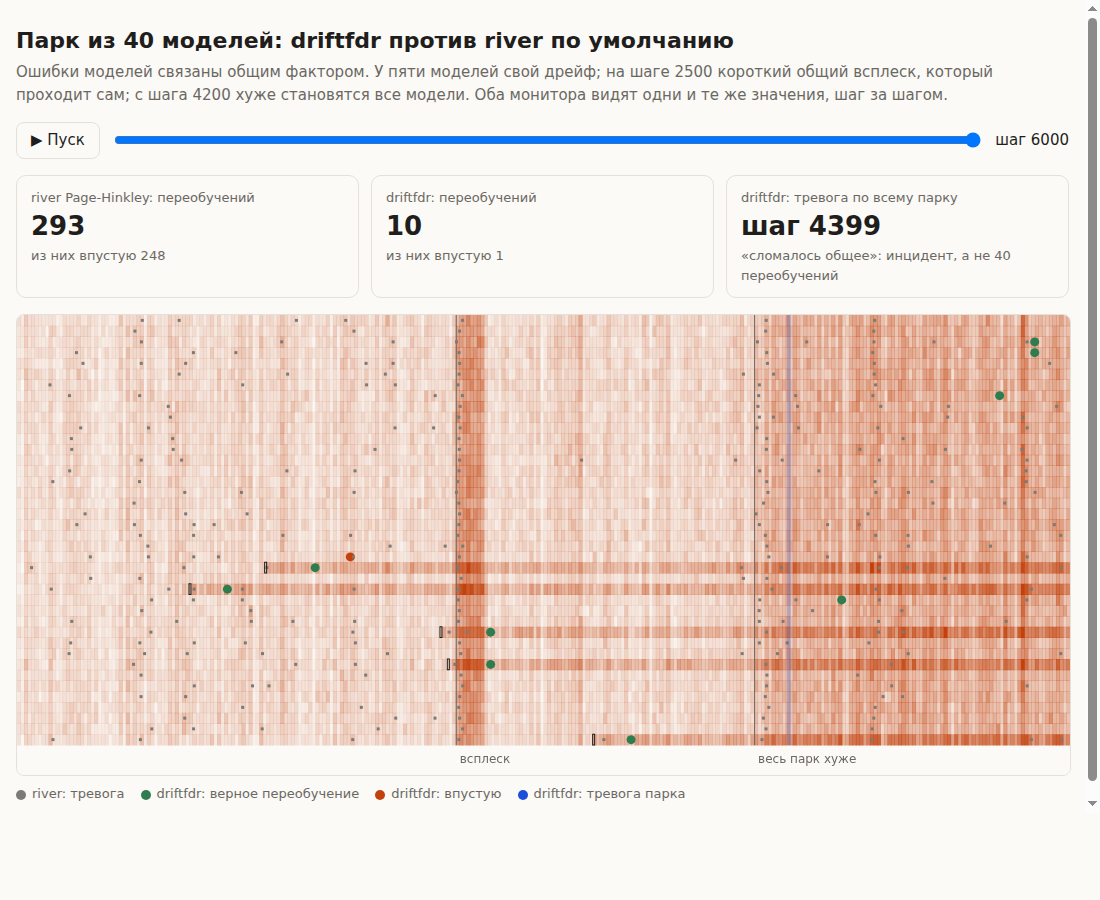
examples/streaming_demo.py. Visual demo:examples/live_demo.py— 40 correlated models, a common spike and a fleet-wide event; river at its defaults retrains 293 times (248 wasted), driftfdr 10 times (1 wasted) plus one fleet alarm. The output, results/demo.html, replays step by step in a browser.
Integrations
Optional adapters in driftfdr.integrations; each needs its own extra and nothing else changes.
| where | what | install |
|---|---|---|
| Prometheus | PrometheusExporter(monitor).serve(8000) publishes p-values, alarms and fleet alarms; alert rules in examples/prometheus/alerts.yml |
driftfdr[prometheus] |
| MLflow | MLflowReporter(monitor, run_id=..., model_versions={id: (name, version)}) logs p-values to a run and tags the registered version of an alarmed model with driftfdr_retrain |
driftfdr[mlflow] |
| NannyML | cbpe_estimated_error(reference, analysis, chunk_size): a label-free error estimate to monitor while labels are delayed; it relies on calibrated probabilities and cannot see changes in p(y|X), and on Electricity it failed (exp. 24): check it against the true error first |
driftfdr[nannyml] |
examples/prometheus_service.py runs the monitor as a small service: it reads errors, exposes
metrics, saves its state on exit and resumes from it. Evidently's drift tests are not wrapped: they
assume independent observations and alarm in 20–78% of the windows where the model did not get
worse (exp. 17), and a multiplicity correction over invalid p-values does not fix that.
Recommended configuration
| what | recommendation | why |
|---|---|---|
| signal | the model's error or loss, not its input features | feature detectors alarm on harmless drift and miss harmful drift (exp. 11) |
| detector | ECUSUM for speed (with a reference of a few hundred points or more, exp. 24), MeanShift(3) for robustness to short spikes; PageHinkley |
at the same false-alarm budget e-CUSUM catches drift 26% faster than PH and MeanShift(3), twice as fast on abrupt shifts (exp. 23); MeanShift(3) ignores one-window spikes (exp. 9, 14) |
| step and window | time units that are multiples of the data's cycle (hour, day) | otherwise a daily cycle looks like drift (exp. 16); bucket_means |
| null hypothesis | tolerance tolerance > 0: "the error rose materially" |
on real data "nothing changed" never holds (exp. 8, 14) |
| tolerance δ | tolerance_from_cost(retrain cost, horizon) |
retraining pays off when a rise δ over the horizon costs more than the retrain itself |
| rule | "bonferroni" or "bh_window"; with split_common=True for correlated models |
Bonferroni holds its level under any correlation (exp. 13), BH is faster when many models drift at once (exp. 4); with split_common the best F1 on the whole benchmark, and the gain grows with correlation (exp. 18, 21) |
| not recommended | ADWIN at strict levels, DDM, LORD/SAFFRON, e-BH | ADWIN's calibrated tail is anti-conservative (exp. 10); DDM is weak; online FDR is slower at an equal number of false alarms (exp. 3, 12); e-BH misses a third of drifts (exp. 13) |
How it works
- The detector as a continuous score. Every detector has one sensitivity parameter, and its binary signal is a threshold on an internal statistic. driftfdr uses that statistic; for Page-Hinkley and DDM it reproduces river exactly.
- Calibration. The null distribution of the statistic is estimated by bootstrap from the reference segment (data right after the model was trained): AR-sieve with parameter uncertainty for continuous signals, block bootstrap for 0/1 errors, a GPD tail for small p-values. A plain bootstrap under autocorrelation gives several times more false alarms than it promises (exp. 1).
- A fleet-level decision. The p-values of all models whose window has ended go through a multiplicity correction; alarmed models are retrained and collect a new reference.
The method: docs/method.md; the relation to the literature:
docs/related_work.md; the reference for every class, method and function:
docs/api.md. Every document except the API reference also has a Russian version
(*.ru.md).
Limitations
- The false-alarm level approximately holds for PH, KS and MeanShift (actual 0.044–0.064 at a nominal 0.05); ADWIN's tail calibration is about three times anti-conservative.
- The results come from synthetic data, four public data sets and hourly FX rates; there has been no validation on production logs, and the models are not actually retrained (an alarm only starts a new reference).
- The corrections' guarantees assume independent p-values; with strongly correlated models Bonferroni is the safer choice.
- On noisy signals (for example, the daily loss of FX volatility models) only material degradations are caught: rises of less than ~15% are indistinguishable from noise (exp. 22).
- The full list is in docs/experiments.md.
Repository layout
src/driftfdr/
  streaming.py     StreamingMonitor (split_common, sequential mode), CalibratedDetector, from_river
  detectors.py     Page-Hinkley, DDM, ADWIN, KS, sliding KS, MeanShift, e-CUSUM; AR whitening
  calibration.py   null distributions, p-values, tail, tolerance δ
  bootstrap.py     block, stationary and AR-sieve bootstrap
  online_fdr.py    Bonferroni, BH, Storey-BH, e-BH per window; BatchBH, LORD++, SAFFRON, LOND, alpha-investing
  preprocess.py    time-bucket means, tolerance from retrain cost, split_common
  monitor.py       batch monitoring of ready-made series (for the experiments)
  metrics.py       FDR, delays, misses, cost of delay, event-level precision / recall / F1
  streams.py       synthetic scenarios with known drift points, the 100-scenario benchmark_suite
  datasets.py      model fleets on INSECTS, Electricity, Airlines, Covertype and hourly FX rates
  integrations/    Prometheus exporter, MLflow reporter, NannyML CBPE signal (optional)
experiments/       24 experiments (exp1…exp24)
results/           tables and figures of the experiments, the demo page
docs/              method, related work, experiment log (English and *.ru.md), API reference (generated: python docs/gen_api.py)
tests/             83 tests (CI on Python 3.10–3.12): agreement with river, bootstrap, calibration, procedures, streaming
examples/          online monitoring, the replayable demo, a Prometheus service with alert rules
Tests and reproduction
pytest                                         # ~15 s
python experiments/exp1_calibration.py --quick # any experiment; without --quick, the full run
The experiments use fixed seeds and pinned settings, so they are reproducible; a full run of each takes from a few minutes to about an hour on 4 cores.
License
Apache License 2.0, see LICENSE and NOTICE. Copyright 2026 Artem Deviatov. The data sets are downloaded by the loaders and keep their own licenses; they are not part of this repository.
Русский
Мониторинг дрейфа для парка ML-моделей без лавины ложных тревог
Когда в эксплуатации десятки и сотни моделей, детекторы дрейфа (Page-Hinkley, DDM, ADWIN, KS) на порогах по умолчанию дают поток ложных тревог и лишних переобучений: у каждого детектора неизвестная доля ложных срабатываний, и при проверке многих моделей они складываются. driftfdr превращает сигнал детектора в откалиброванное p-значение с учётом автокорреляции данных и принимает решение о переобучении по всему парку моделей сразу, с заданным уровнем ложных тревог.
ошибка модели 1 ─► детектор ─► бутстреп-калибровка ─► p-значение ─┐
ошибка модели 2 ─► детектор ─► бутстреп-калибровка ─► p-значение ─┼─► поправка на число моделей ─► переобучить?
ошибка модели K ─► детектор ─► бутстреп-калибровка ─► p-значение ─┘
Зачем
На реальных данных — четыре открытых набора (INSECTS, Electricity, Airlines, Covertype; по 50 моделей, строки в исходном порядке) и часовые курсы пяти валютных пар — доля ложных переобучений среди всех тревог:
| набор | Page-Hinkley river по умолчанию | driftfdr |
|---|---|---|
| INSECTS | 50% | 0% |
| Electricity | 56% | 0–8% |
| Covertype | 75% | 15% |
| Airlines | 26% | 0–6% (шаг — час) |
| Курсы валют, 40 моделей волатильности, 2010–2026 | 0 тревог, не поймано ни одно ухудшение | 0–10%, поймано 63–100% ухудшений больше 30% |
На фиксированном наборе из 100 синтетических сценариев F1 обнаружения у лучшей конфигурации driftfdr 0.88, у Page-Hinkley river по умолчанию 0.06: он ловит все дрейфы, но 97% его тревог ложные (эксп. 21).
Стандартный тест дрейфа Evidently на ряде ошибок тревожит в 20–78% окон, где модель не стала хуже. Мониторинг качества NannyML сопоставим с driftfdr по точности, но его порог ±3σ фиксирован и не зависит от числа моделей; в driftfdr уровень ложных тревог, поправка на размер парка и допустимое ухудшение задаются явно. По скорости мониторинг не медленнее самого детектора river (около 1 мкс на шаг на модель); калибровка занимает доли секунды на модель после каждого переобучения (эксп. 19). Подробности и все 24 эксперимента — в docs/experiments.ru.md.
Установка
pip install driftfdr                 # numpy, scipy, pandas, matplotlib
pip install "driftfdr[prometheus]"   # + интеграция: prometheus, mlflow или nannyml
Из клона репозитория: pip install -e ".[dev]" (тесты) или pip install -e ".[datasets]"
(river и scikit-learn для реальных наборов данных из экспериментов).
Быстрый старт
Монитор принимает на каждом шаге ошибку (или потерю) каждой модели и возвращает модели, которые пора переобучать:
from driftfdr import CalibrationConfig, MeanShift, StreamingMonitor

monitor = StreamingMonitor(
    model_ids=["pricing", "eta", "demand"],
    detector_factory=lambda: MeanShift(3),     # тревога, только если ухудшение держится 3 окна
    procedure="bonferroni",                    # поправка на число моделей
    alpha=0.05,                                # доля ложных тревог на окно по всему парку
    n_ref=300, window=100, horizon=5,          # в шагах; шаг может быть часом (см. bucket_means)
    calibration=CalibrationConfig(tolerance=0.05),  # переобучать, если ошибка выросла > 5 п.п.
)

for errors in stream:                          # например {"pricing": 0.21, "eta": 0.35}
    for model_id in monitor.update(errors):
        retrain(model_id)                      # монитор сам начнёт собирать новый опорный отрезок

monitor.save("monitor.npz")                    # состояние переживает перезапуск сервиса
monitor = StreamingMonitor.load("monitor.npz", detector_factory=lambda: MeanShift(3))
- Если ошибки моделей движутся вместе (общий источник данных, общие признаки), включите
split_common=True. Тогда детекторы смотрят на отклонение каждой модели от медианы по парку, а сама медиана проверяется отдельно: её тревога выставляетmonitor.fleet_alarm(«сломалось что-то общее»). Без этого общий всплеск даёт пачку одновременных ложных тревог (эксп. 18). На всех четырёх реальных наборах модели сильно коррелированы, аsplit_commonснимает большую часть этой зависимости (эксп. 20). В этом режиме каждая модель должна присылать значение на каждом шаге. - Чтобы реагировать, не дожидаясь конца окна, используйте
detector_factory=ECUSUMсsequential=True: каждая модель проверяется на каждом шаге при том же бюджете ложных тревог на окно (Бонферрони). При том же бюджете это ловило дрейф на 26% быстрее оконного PH (эксп. 23); шаг стоит около 7 мкс на модель вместо 2. - Модели могут присылать данные нерегулярно или с пропусками: у каждой свои часы окон.
Модели добавляются и убираются на лету (
add_model,remove_model). - При задержке меток передавайте ошибку модели тогда, когда пришла метка.
- Детектор можно взять из river с его настройками:
detector_factory=lambda: from_river(drift.PageHinkley(mode="up")). - Полный пример —
examples/streaming_demo.py. Наглядная демонстрация —examples/live_demo.py: 40 связанных моделей, общий всплеск и событие во всём парке; river по умолчанию делает 293 переобучения (248 впустую), driftfdr — 10 (1 впустую) и одну тревогу парка. Результат — results/demo.html, открывается в браузере с проигрыванием по шагам.
Интеграции
Опциональные адаптеры в driftfdr.integrations; каждому нужна своя дополнительная зависимость,
основной пакет не меняется.
| куда | что | установка |
|---|---|---|
| Prometheus | PrometheusExporter(monitor).serve(8000) публикует p-значения, тревоги и тревоги парка; правила алертов — examples/prometheus/alerts.yml |
driftfdr[prometheus] |
| MLflow | MLflowReporter(monitor, run_id=..., model_versions={id: (name, version)}) пишет p-значения в run и ставит тег driftfdr_retrain на зарегистрированную версию модели с тревогой |
driftfdr[mlflow] |
| NannyML | cbpe_estimated_error(reference, analysis, chunk_size): оценка ошибки без меток, чтобы мониторить, пока метки задерживаются; опирается на откалиброванные вероятности, изменений p(y|X) не видит, на Electricity не сработала (эксп. 24) — сначала сверьте её с настоящей ошибкой |
driftfdr[nannyml] |
examples/prometheus_service.py запускает монитор как небольшой сервис: читает ошибки, отдаёт
метрики, сохраняет состояние при остановке и продолжает с него. Тесты дрейфа Evidently не
оборачиваются: они предполагают независимые наблюдения и тревожат в 20–78% окон, где модель не
стала хуже (эксп. 17), а поправка на множественность поверх невалидных p-значений этого не исправит.
Рекомендуемая конфигурация
| что | рекомендация | почему |
|---|---|---|
| сигнал | ошибка или потеря модели, не входные признаки | детекторы на признаках тревожат на безвредном дрейфе и не видят вредного (эксп. 11) |
| детектор | ECUSUM для скорости (при опорном отрезке от нескольких сотен точек, эксп. 24), MeanShift(3) для устойчивости к кратким всплескам; PageHinkley |
при том же бюджете ложных тревог e-CUSUM ловит дрейф на 26% быстрее PH и MeanShift(3), на резких сдвигах вдвое (эксп. 23); MeanShift(3) не реагирует на однооконные всплески (эксп. 9, 14) |
| шаг и окно | в единицах времени, кратных циклу данных (час, сутки) | иначе суточный цикл выглядит как дрейф (эксп. 16); bucket_means |
| нулевая гипотеза | допуск tolerance > 0: «ошибка выросла существенно» |
на реальных данных «ничего не изменилось» не бывает (эксп. 8, 14) |
| допуск δ | tolerance_from_cost(цена переобучения, горизонт) |
переобучать выгодно, если рост ошибки δ за горизонт стоит больше самого переобучения |
| правило | "bonferroni" или "bh_window"; при связанных моделях — с split_common=True |
Бонферрони держит уровень при любой корреляции моделей (эксп. 13), BH быстрее при массовых дрейфах (эксп. 4); с split_common лучший F1 на всём бенчмарке, выигрыш растёт с корреляцией (эксп. 18, 21) |
| не рекомендуется | ADWIN при строгих уровнях, DDM, LORD/SAFFRON, e-BH | хвост ADWIN антиконсервативен (эксп. 10); DDM слабый; онлайн-FDR медленнее при равном числе ложных (эксп. 3, 12); e-BH пропускает треть дрейфов (эксп. 13) |
Как это работает
- Детектор как непрерывный скор. У каждого детектора один параметр чувствительности, а бинарный сигнал — это порог на внутренней статистике. Эту статистику и берём; для Page-Hinkley и DDM она воспроизводит river точно.
- Калибровка. Нулевое распределение статистики оценивается бутстрепом из опорного отрезка (данные сразу после обучения модели): AR-sieve с учётом неопределённости параметров для непрерывных сигналов, блочный бутстреп для ошибок 0/1, GPD-хвост для малых p-значений. Обычный бутстреп при автокорреляции даёт в разы больше ложных тревог, чем обещает (эксп. 1).
- Решение по парку. p-значения всех моделей, у которых закончилось окно, проходят через поправку на множественность; модели с тревогой переобучаются и собирают новый опорный отрезок.
Подробное описание — docs/method.ru.md; связь с литературой —
docs/related_work.ru.md; справочник по всем классам, методам и
функциям (только на английском) — docs/api.md. У каждого документа, кроме
справочника API, есть английская версия (без .ru в имени).
Ограничения
- Уровень ложных тревог примерно выдерживается для PH, KS и MeanShift (фактически 0.044–0.064 при номинале 0.05); у ADWIN калибровка хвоста антиконсервативна примерно втрое.
- Выводы получены на синтетике, четырёх открытых наборах данных и часовых курсах валют; проверки на продовых логах не было, и модели не переобучаются по-настоящему (тревога лишь запускает сбор нового опорного отрезка).
- Гарантии поправок выведены для независимых p-значений; при сильно коррелированных моделях надёжнее Бонферрони.
- На шумном сигнале (например, дневная потеря моделей волатильности на курсах валют) ловятся только существенные ухудшения: рост меньше ~15% неотличим от шума (эксп. 22).
- Полный список — в docs/experiments.ru.md.
Структура репозитория
src/driftfdr/
  streaming.py     StreamingMonitor (split_common, последовательный режим), CalibratedDetector, from_river
  detectors.py     Page-Hinkley, DDM, ADWIN, KS, скользящий KS, MeanShift, e-CUSUM; отбеливание AR
  calibration.py   нулевые распределения, p-значения, хвост, допуск δ
  bootstrap.py     блочный, стационарный и AR-sieve бутстреп
  online_fdr.py    Бонферрони, BH, BH Стори, e-BH в окне; BatchBH, LORD++, SAFFRON, LOND, alpha-investing
  preprocess.py    усреднение по временным корзинам, допуск из стоимости переобучения, split_common
  monitor.py       пакетный прогон мониторинга по готовым рядам (для экспериментов)
  metrics.py       FDR, задержки, пропуски, цена задержки, событийные точность / полнота / F1
  streams.py       синтетические сценарии с известными точками дрейфа, бенчмарк benchmark_suite
  datasets.py      парки моделей на INSECTS, Electricity, Airlines, Covertype и часовых курсах валют
  integrations/    экспорт в Prometheus, отчёты в MLflow, сигнал NannyML CBPE (опционально)
experiments/       24 эксперимента (exp1…exp24)
results/           таблицы и графики экспериментов, страница демонстрации
docs/              метод, связанные работы, журнал экспериментов (английский и *.ru.md), справочник API (генерируется: python docs/gen_api.py)
tests/             83 теста (CI на Python 3.10–3.12): совпадение с river, бутстреп, калибровка, процедуры, потоковый режим
examples/          онлайн-мониторинг, демонстрация с проигрыванием, сервис для Prometheus с правилами алертов
Тесты и воспроизведение
pytest                                         # ~15 с
python experiments/exp1_calibration.py --quick # любой эксперимент; без --quick — полный прогон
Эксперименты используют фиксированные сиды и закреплённые настройки, поэтому воспроизводятся; полный прогон каждого занимает от нескольких минут до часа на 4 ядрах.
Лицензия
Apache License 2.0, см. LICENSE и NOTICE. Copyright 2026 Artem Deviatov. Наборы данных скачиваются загрузчиками, остаются под своими лицензиями и в репозиторий не входят.
1 maintainer

Release files for driftfdr 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| driftfdr-0.1.0.tar.gz | 90.1 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| driftfdr-0.1.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 155.7 kB
Release files / driftfdr-0.1.0.tar.gz
| Download URL | driftfdr-0.1.0.tar.gz |
|---|---|
| Size | 90.1 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
fc8d06eee7b613667fc502f7629cf47bdb9ac6098fa5ba717463edece2429a38
|
|
BLAKE2b-256 checksum How to use checksums |
de18c9972dda93f2276f1be9dffe504dcb047ff3b6fb607ff39157586f26ecdc
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 25, 2026.
Transparency logRelease files / driftfdr-0.1.0-py3-none-any.whl
| Download URL | driftfdr-0.1.0-py3-none-any.whl |
|---|---|
| Size | 65.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
debcc2e913c38de011014ea8e3f3ac8b7ef8626b2ca9d34c0d7e777412c880d3
|
|
BLAKE2b-256 checksum How to use checksums |
b8aa941b4b180998c870df506e79b8eac8971dd4cd7ee8db32ee36b04280909b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 25, 2026.
Transparency log












