
ehr2rl


ehr2rl is a Python library for turning MIMIC-IV-style electronic health record
data into datasets ready for offline reinforcement learning research.
Healthcare ML libraries are usually built for supervised prediction, while
offline RL libraries expect a clean state-action-reward dataset that already
exists. ehr2rl fills the gap between those worlds: loading longitudinal EHR
tables, representing patient trajectories, shaping rewards, estimating observed
behavior, and exporting data for tools such as d3rlpy.
Documentation · PyPI · GitHub
Features
- Load and align MIMIC-IV admissions, vitals, and lab tables into patient trajectories.
- Build bounded MIMIC-IV v3.1 cohorts through BigQuery with dry-run billing guards.
- Resolve validated v3.1 itemid maps through named feature presets.
- Construct fluids and vasopressor actions from ICU medication events.
- Construct reward signals, including mortality and SOFA delta, with a swappable reward interface, plus readmission and weighted composite rewards.
- Estimate observed clinician behavior policy from historical data.
- Export training-ready datasets for offline RL with
d3rlpy, including optional provenance sidecars. - Generate synthetic MIMIC-IV-style data for development and testing without credentialed access.
Architecture
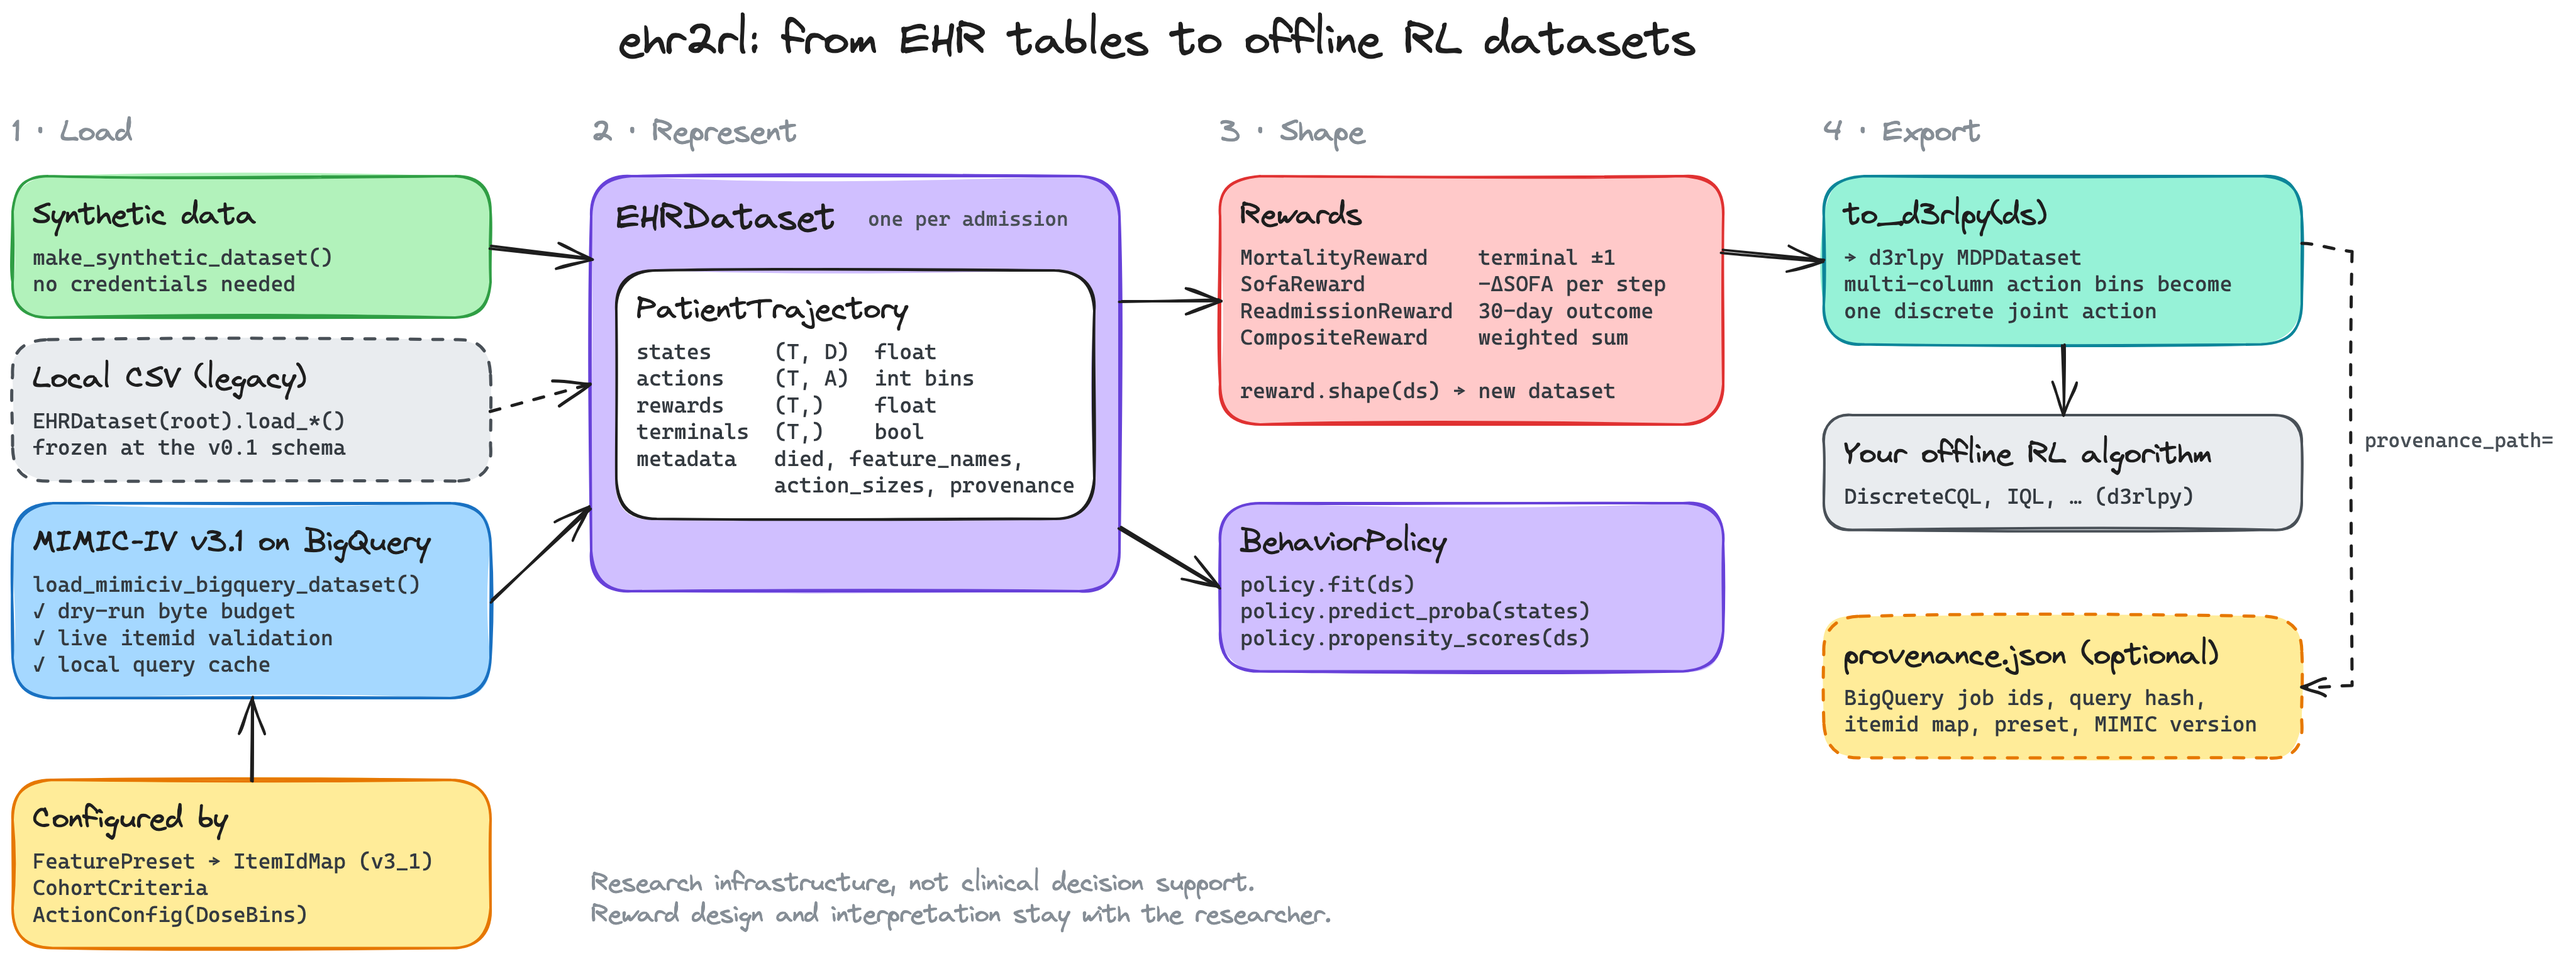
Every source produces the same EHRDataset, a list of PatientTrajectory
objects with aligned per-timestep arrays:
| Field | Shape | Meaning |
|---|---|---|
states |
(T, D) float |
Hourly clinical features; names in metadata["feature_names"] |
actions |
(T, A) |
Treatment per step; medication actions are [vasopressor_bin, fluid_bin] |
rewards |
(T,) float |
Filled in by a reward's shape() |
terminals |
(T,) bool |
True on the last step of the episode |
metadata |
dict | died, feature_names, action_names, action_sizes, provenance, … |
Module map:
| Module | What it does | Main entry points |
|---|---|---|
ehr2rl.bigquery |
Budget-guarded MIMIC-IV v3.1 cohort queries | GuardedBigQueryClient, BigQueryCohort, load_mimiciv_bigquery_dataset |
ehr2rl.data |
Dataset model, itemid maps, feature presets, legacy CSV loading | EHRDataset, PatientTrajectory, load_itemid_map, get_feature_preset |
ehr2rl.actions |
Vasopressor and fluid actions from ICU input events | ActionConfig, DoseBins, build_medication_actions |
ehr2rl.reward |
Swappable reward functions | MortalityReward, SofaReward, ReadmissionReward, CompositeReward |
ehr2rl.policy |
Estimate the observed clinician policy | BehaviorPolicy |
ehr2rl.export |
Training-ready datasets for d3rlpy |
to_d3rlpy |
ehr2rl.provenance |
JSON sidecar describing where a dataset came from | write_provenance, read_provenance |
ehr2rl.testing |
Synthetic MIMIC-IV-style data | make_synthetic_dataset |
See the pipeline concepts page for more detail.
Installation
ehr2rl targets Python 3.10+.
Install the extras for the paths you need:
| Install | Adds | Use it for |
|---|---|---|
pip install ehr2rl |
NumPy, pandas, scikit-learn, SciPy | Synthetic data, rewards, behavior policy |
pip install "ehr2rl[d3rlpy]" |
d3rlpy |
to_d3rlpy export and offline RL training |
pip install "ehr2rl[bigquery]" |
Google Cloud BigQuery client, pyarrow, db-dtypes |
Credentialed MIMIC-IV v3.1 pipelines and smoke tests |
pip install "ehr2rl[all]" |
Both of the above | The full BigQuery-to-d3rlpy example |
Quickstart
Start with synthetic data:
from ehr2rl import make_synthetic_dataset, MortalityReward

ds = make_synthetic_dataset(n_patients=25, trajectory_length=24, seed=7)
ds = MortalityReward().shape(ds)

print(f"Loaded {len(ds)} patient trajectories")
print(f"State shape: {ds.trajectories[0].states.shape}")
Full synthetic-to-d3rlpy round trip:
from ehr2rl import BehaviorPolicy, MortalityReward, make_synthetic_dataset, to_d3rlpy

ds = make_synthetic_dataset(
    n_patients=25,
    trajectory_length=24,
    seed=7,
    include_medication_metadata=True,
)

policy = BehaviorPolicy().fit(ds)
ds = MortalityReward().shape(ds, policy=policy)

# Requires: pip install ehr2rl[d3rlpy]
mdp_dataset = to_d3rlpy(ds)
The synthetic path is the default development path so tests and examples do not require access to MIMIC-IV.
BigQuery MIMIC-IV v3.1 Pipeline
v0.2 makes BigQuery the primary real-data path for MIMIC-IV v3.1. The local CSV loader remains available for backward compatibility and offline work, but it is frozen at its existing demo-schema behavior and does not receive new v3.1 validation, itemid maps, feature presets, or medication action construction.
Every BigQuery query goes through a dry-run estimate before execution and sets
maximum_bytes_billed on the real job as a server-side backstop.
from google.cloud import bigquery

from ehr2rl.actions import ActionConfig, DoseBins
from ehr2rl.bigquery import (
    BigQueryCohort,
    CohortCriteria,
    GuardedBigQueryClient,
    load_mimiciv_bigquery_dataset,
)
from ehr2rl.data.itemid_maps import load_itemid_map
from ehr2rl.data.presets import get_feature_preset

client = GuardedBigQueryClient(
    bigquery.Client(project="YOUR_BILLING_PROJECT_ID"),
    maximum_bytes_billed=25_000_000_000,
    cache_dir=".ehr2rl_cache",
    query_timeout=60,
)

ds = load_mimiciv_bigquery_dataset(
    client=client,
    cohort=BigQueryCohort(CohortCriteria(cohort_size=25)),
    preset=get_feature_preset("vitals_only"),
    itemid_map=load_itemid_map("v3_1"),
    action_config=ActionConfig(
        vasopressor_bins=DoseBins(edges=(0.0, 0.1, 0.3, 0.6)),
        fluid_bins=DoseBins(edges=(0.0, 250.0, 500.0, 1000.0)),
    ),
)
Feature presets reference canonical clinical names rather than raw itemids:
from ehr2rl.data.itemid_maps import load_itemid_map
from ehr2rl.data.presets import get_feature_preset

resolved = get_feature_preset("sepsis3_core").resolve(load_itemid_map("v3_1"))
print(sorted(resolved))
Medication actions are represented as two columns: vasopressor bin and fluid bin. Synthetic datasets can opt into that shape for tests and examples:
from ehr2rl import make_synthetic_dataset

ds = make_synthetic_dataset(include_medication_metadata=True)
print(ds[0].metadata["action_names"])
Exported real datasets can write a JSON provenance sidecar:
from ehr2rl import to_d3rlpy

mdp_dataset = to_d3rlpy(ds, provenance_path="dataset.provenance.json")
Rewards
Each reward implements compute(trajectory) and shape(dataset), and
shape() returns a new dataset with rewards filled in.
| Reward | Signal | Needs in metadata |
|---|---|---|
MortalityReward |
+1 survival or -1 death at the terminal step |
died |
SofaReward |
Per-step SOFA improvement, clipped to [-5, 5] |
sofa_scores |
ReadmissionReward |
+1 / -1 for 30-day readmission at the terminal step; NaN when censored |
readmitted_within_30_days |
CompositeReward |
Weighted sum of other rewards | Whatever its components need |
BigQuery trajectories include died, so MortalityReward works on them
directly. sofa_scores and readmitted_within_30_days must be added by the
researcher. Synthetic trajectories include died and sofa_scores. See
reward semantics.
from ehr2rl import CompositeReward, MortalityReward, SofaReward

reward = CompositeReward([(MortalityReward(), 1.0), (SofaReward(), 0.1)])
ds = reward.shape(ds)
Development Install
pip install -e ".[dev]"
pytest
ruff check .
mypy ehr2rl
To exercise the optional BigQuery and d3rlpy paths in development:
pip install -e ".[dev,all]"
pytest
MIMIC-IV Access
ehr2rl does not ship, mirror, or provide access to MIMIC-IV. Researchers must
obtain any clinical data through the appropriate credentialed channels, such as
PhysioNet, and comply with the applicable data use agreements.
Credentialed users can run a bounded BigQuery smoke test without downloading the dataset. The test is opt-in, applies a per-query bytes-billed cap, and disables BigQuery retries so credential or network failures return quickly.
gcloud auth application-default login
gcloud auth application-default set-quota-project YOUR_BILLING_PROJECT_ID
EHR2RL_RUN_BIGQUERY_SMOKE=1 \
EHR2RL_BIGQUERY_BILLING_PROJECT=YOUR_BILLING_PROJECT_ID \
EHR2RL_BIGQUERY_TIMEOUT_SECONDS=60 \
pytest tests/test_bigquery_smoke.py
The smoke helper uses the MIMIC-IV v3.1 BigQuery datasets exposed as
physionet-data.mimiciv_3_1_hosp and physionet-data.mimiciv_3_1_icu.
Known Limitations
The local CSV loader is retained for backward compatibility and offline/no-GCP development, but v0.2 real-data validation is BigQuery-first.
d3rlpy currently prints a Gym deprecation warning under NumPy 2.x; this is an
upstream issue and does not affect functionality.
Clinical Disclaimer
ehr2rl is research infrastructure. It is not clinical decision support, does
not validate treatment recommendations, and does not define a clinically
authoritative reward function. Reward design and interpretation remain the
responsibility of the researcher.
Roadmap
Future priorities:
- Minari export.
- Standalone pre-flight validation.
- CLI tooling.
- Additional dataset families such as eICU, MIMIC-III, and OMOP-CDM.
Contributing
Issues and pull requests are welcome. For v0.2, the most useful contributions are BigQuery schema checks, validated itemid-map updates, synthetic-data edge cases, documentation fixes, and export compatibility improvements.
If you have access to full MIMIC-IV v3.1 and spot a schema mismatch, opening an issue with the table name and column is especially helpful.
Citation
@software{ehr2rl2026,
  author  = {Bilal Malik},
  title   = {ehr2rl: Bridging MIMIC-IV and Offline Reinforcement Learning},
  year    = {2026},
  version = {0.2.1},
  url     = {https://github.com/pinktownscavenger/ehr2rl}
}
1 maintainer

Metadata
1 maintainer
Release files for ehr2rl 0.2.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| ehr2rl-0.2.1.tar.gz | 49.0 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| ehr2rl-0.2.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 92.7 kB
Release files / ehr2rl-0.2.1.tar.gz
| Download URL | ehr2rl-0.2.1.tar.gz |
|---|---|
| Size | 49.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
6cba9ac72e519e74b4ae14d3b6bc9fdba01d0c0a58910a2d42efc9b3e4ae4371
|
|
BLAKE2b-256 checksum How to use checksums |
22ea2c4e089847a999d2666817327b8983e89c45b6dd01f8a420fa61fc738940
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 14, 2026.
Transparency logRelease files / ehr2rl-0.2.1-py3-none-any.whl
| Download URL | ehr2rl-0.2.1-py3-none-any.whl |
|---|---|
| Size | 43.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
0096211f5f9213ff29be485a6ee0e328bf654cf92004c7aeafc508139b35d813
|
|
BLAKE2b-256 checksum How to use checksums |
49db4114b38d1436895f6cfd957c9316adf094ebef678067ca1f4f6fbe945016
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 14, 2026.
Transparency log













